Binary doc-values updates: what you pass is not always what a document gets. It depends on whether the target document has already been flushed.
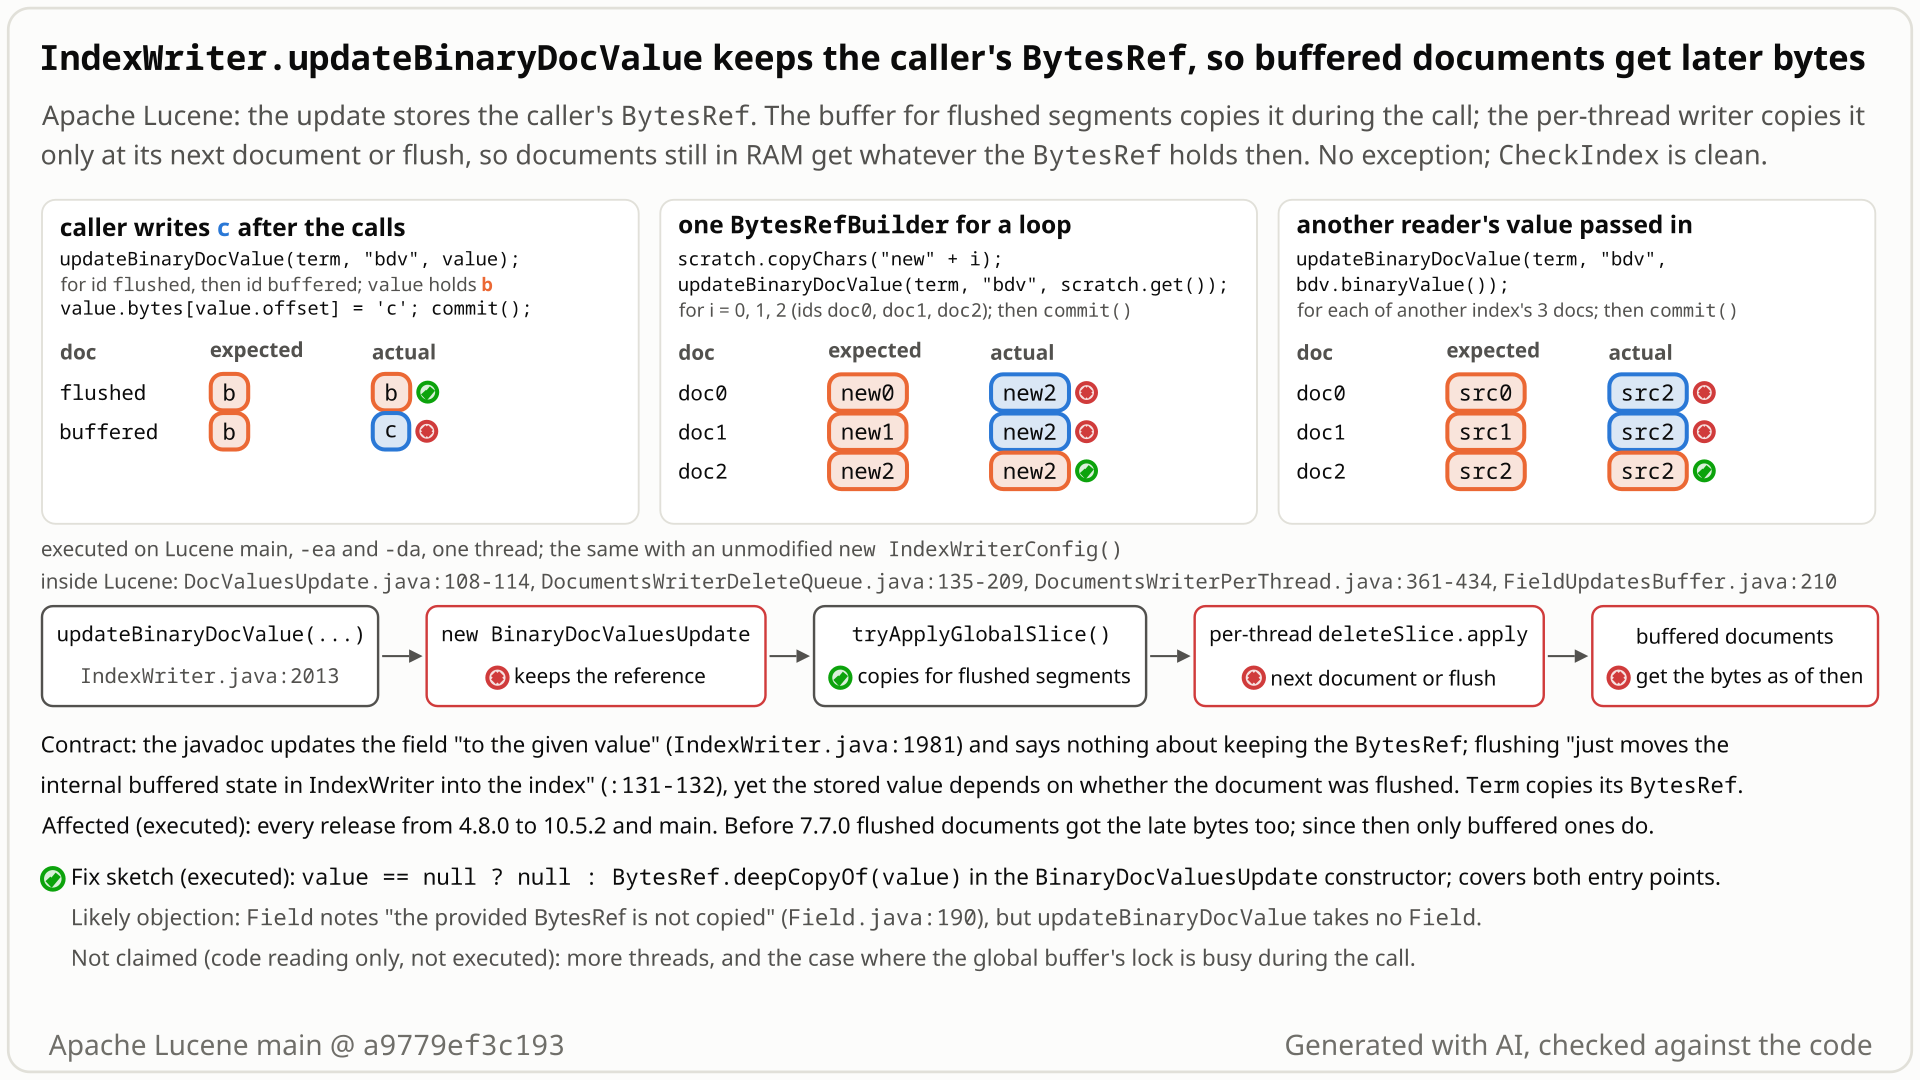
- Index document
flushedwith binary doc valueaand callflush(); index documentbufferedwitha, which stays in the writer's RAM buffer. - Set both to
bwithupdateBinaryDocValue, passing oneBytesRef value = new BytesRef("b"), then reuse thatBytesRef: set its byte tocandcommit(). You expect both documents to readb. - You get
flushed=bbutbuffered=c. The writer kept yourBytesRefand read it for the buffered document only at the flush of the commit. - The same with Lucene's usual idioms: updating doc0, doc1, doc2 to new0, new1, new2 through one
BytesRefBuilderstores new2 three times; copying src0, src1, src2 from another index by passing itsbinaryValue()straight in stores src2 three times, with no change by the caller at all. - No exception,
CheckIndexis clean, and the wrong values are committed. DefaultIndexWriterConfigand codec, one thread; every release from 4.8.0 to 10.5.2 and main.
Applications that call updateBinaryDocValue, or updateDocValues with a BinaryDocValuesField, and then reuse the BytesRef (a BytesRefBuilder scratch, a reused byte[]) or pass a reader's binaryValue() straight in. Default config and codec, one thread, no scale. Only documents added since the last flush or refresh are hit. The API itself is rarely used.
Mechanism, terms and numbers533 words
IndexWriter.updateBinaryDocValue(Term, String, BytesRef), and updateDocValues(Term, Field...) with a BinaryDocValuesField, store the caller's BytesRef object in the queued update without copying it. Documents in flushed segments get the bytes as of the call, because the writer's global buffer copies them inside the call. Documents still buffered in RAM get the bytes that BytesRef holds when the per-thread writer holding them next applies the queued updates: at the end of its next indexing operation, or when it is flushed (commit, refresh). So a caller that reuses its buffer after the call, or passes a reader's BinaryDocValues.binaryValue() straight through, silently commits the wrong value on buffered documents: a loop over one BytesRefBuilder gives every buffered target the last value. Default config and codec, one thread (every run), deterministic, CheckIndex clean; every release since 4.8.0 (2014). Binary doc-values updates are a rarely used API.
- Binary doc-values update:
IndexWriter.updateBinaryDocValue(term, field, value)replaces theBinaryDocValuesvalue of every document that matchesterm, without reindexing the document.updateDocValues(term, fields...)does the same for one or moreFields. BytesRef: a view of a byte array (bytes,offset,length). Lucene reusesBytesRefobjects a lot:BytesRefBuilder.get()returns the same object after everycopyChars, and a doc-values iterator refills one object for every document.- Flushed vs buffered: a document that
IndexWriterhas written to a segment is flushed. A document added since the last flush (commit, refresh, or RAM-triggered flush) is buffered in the RAM buffer of a per-thread writer.
updateBinaryDocValuepasses the caller's object on:new BinaryDocValuesUpdate(term, field, value)(IndexWriter.java:2013).updateDocValues(Term, Field...)does the same withf.binaryValue()(:2113).- The update stores the reference:
this.value = value;(DocValuesUpdate.java:114). - The update is queued in the writer's delete queue (
DocumentsWriterDeleteQueue.java:135-139). During the call only the global buffer reads it (tryApplyGlobalSlice,:198-215, when itstryLocksucceeds; in every executed run the flushed documents got the call-time value, as that gives): that copies the bytes (FieldUpdatesBuffer.java:210,byteValues.append(value), or the constructor at:107-112for a field's first update in that buffer), and the global buffer is what is applied to flushed segments. - The per-thread writer that holds the buffered documents reads the queued update only at the end of its next indexing operation (
DocumentsWriterPerThread.java:361-390) or at flush (:427-439). Until then the queue holds the caller'sBytesRef, so the copy for buffered documents takes whatever bytes it holds then. At flush the global packet (b) is published before the new segment, which gets a later delete generation, so it does not overwrite the new segment's own copy (IndexWriter.java:2969-2990,:6783).
One update with b to a flushed and a buffered document, then the caller writes c: flushed=b, buffered=c. A BytesRefBuilder loop over three buffered documents: new2, new2, new2. A pass-through of another index's binaryValue(): src2, src2, src2. updateDocValues with one reused BinaryDocValuesField: x2, x2. A fresh BytesRef per call: correct. If the writer indexes one more document before the caller changes the bytes, the value is correct too; that document closes the window.
Exposure and likelihood345 words
- Who is hit. Callers of
updateBinaryDocValue, or ofupdateDocValueswith aBinaryDocValuesField, that change or reuse theBytesRefafter the call: oneBytesRefBuilderfor a loop of updates, a reusedbyte[]wrapped in a freshBytesRefper call (it fails the same way), or a reader-ownedBytesRefsuch asBinaryDocValues.binaryValue()passed straight through. Callers whoseBytesRefpoints at bytes they never change afterwards, such as a freshBytesRefover a fresh array per call as Lucene's own tests do, never see it. - Which documents. Targets added since the last flush or refresh that are still in a per-thread writer's RAM buffer, for updates made since that per-thread writer's last indexing operation. Which documents those are depends on flush timing (RAM buffer, refreshes), so the same code can store right values for some documents and wrong ones for others.
- Default, not opt-in. An unmodified
new IndexWriterConfig()and the default codec give the same wrong values for the changed-after-return, loop and pass-through cases (on aByteBuffersDirectoryand anFSDirectory), one thread; deterministic, the same with assertions on and off. The JUnit itself setsNoMergePolicyand turns off flushing by document count. No scale: 1 to 3 documents. - Silent and persistent. No exception; the wrong value is committed,
CheckIndexreports the index clean wherever it was run (the changed-after-return, loop and pass-through cases), and NRT readers see it too. - Reach. Binary doc-values updates are rarely used: no Lucene module calls
updateBinaryDocValueoutside tests, and a read-only code search of three common downstream search servers found it only in one test (code search can miss call sites). - Age. Every release since 4.8.0 (2014). Until 7.6.0 even flushed documents got the late bytes.
- Not claimed (code reading only, not executed). With several indexing threads, each per-thread writer applies the update at its own next indexing operation; the global slice can miss its
tryLock, in which case flushed segments could read late bytes on 7.7.0 and later too; and a binary field passed tosoftUpdateDocument(s)goes into the same kept update, which other per-thread writers apply later.
The test shows that IndexWriter.updateBinaryDocValue keeps the caller's BytesRef, so a buffered document updated through a reused BytesRefBuilder gets the scratch's later bytes instead of the value passed to its call.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import org.apache.lucene.document.BinaryDocValuesField;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.StringField;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;
import org.apache.lucene.util.BytesRefBuilder;

public class TestBinaryDocValuesUpdateReusedBytesRef extends LuceneTestCase {

  public void testReusedBytesRefBuilder() throws Exception {
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter writer = new IndexWriter(dir, new IndexWriterConfig())) {
      for (String id : new String[] {"0", "1"}) {
        Document doc = new Document();
        doc.add(new StringField("id", id, Field.Store.NO));
        doc.add(new BinaryDocValuesField("bdv", new BytesRef("old")));
        writer.addDocument(doc);
      }
      BytesRefBuilder scratch = new BytesRefBuilder();
      scratch.copyChars("new0");
      writer.updateBinaryDocValue(new Term("id", "0"), "bdv", scratch.get());
      scratch.copyChars("new1");
      writer.updateBinaryDocValue(new Term("id", "1"), "bdv", scratch.get());
      writer.commit();
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        BinaryDocValues values = getOnlyLeafReader(reader).getBinaryDocValues("bdv");
        assertTrue(values.advanceExact(0));
        // expected doc 0 to get the value passed with its update; actual: the scratch's later "new1"
        assertEquals("new0", values.binaryValue().utf8ToString());
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-643/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.index.TestBinaryDocValuesUpdateReusedBytesRef
- Expected vs actual
- Expected doc 0 to hold
new0after commit; actual:new1(expected:<new[0]> but was:<new[1]>), with-eaand-da.
More files, environment, full output32 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: expected:<new[0]> but was:<new[1]>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.index.TestBinaryDocValuesUpdateReusedBytesRef.testReusedBytesRefBuilder(TestBinaryDocValuesUpdateReusedBytesRef.java:50)- The javadoc promises "the given value" and never says the
BytesRefis kept;addDocument,tryUpdateDocValueandTermcopy during the call. - One call stores
bin a flushed document andcin a buffered one, yet flushing "just moves the internal buffered state ... into the index". - A reader's
binaryValue()passed straight in, with no caller change, is enough.
The full argument278 words
- The contract. "Updates a document's
BinaryDocValuesforfieldto the givenvalue",@param value"new value for the field" (IndexWriter.java:1981-1995);updateDocValues: "Updates documents' DocValues fields to the given values" (:2060). Neither says theBytesRefis kept after the call. - Flushing must not change the result. The
IndexWriterclass javadoc: "flushing just moves the internal buffered state in IndexWriter into the index" (IndexWriter.java:131-132). Here the stored value depends on whether the target had been flushed. - The writer copies the other
BytesRefs it takes during the call.addDocumentconsumes aBinaryDocValuesField's bytes before returning (a checker's control: one field over a builder changed between calls gives each document its own value);tryUpdateDocValuecopies intoBinaryDocValuesFieldUpdates(IndexWriter.java:1759-1761,BinaryDocValuesFieldUpdates.java:94-98);Term(String, BytesRef): "The provided BytesRef is copied when it is non null" (Term.java:50-55). The update's own code calls the value "a final value" (DocValuesUpdate.java:119). - Precedent. Until 2015
Term(String, BytesRef)carried "WARNING: the provided BytesRef is not copied, but used directly". LUCENE-6821 ("TermQuery's constructors should clone the incoming term", #7879, commit9534904c250) madeTermcopy, because term queries built from sharedBytesRefobjects are "a bit trappy"; mikemccand: "I consider this a bug fix". That trap was even documented; this one is not. - Lucene copies reader-owned values before keeping them. The default bulk implementation in the
BinaryDocValuesjavadoc storesBytesRef.deepCopyOf(binaryValue())(BinaryDocValues.java:43-50). Here the object that keeps the value isIndexWriter's internal update. - Tests and history. Upstream tests allocate a fresh
BytesRefper call (TestBinaryDocValuesUpdates.toBytes,:69-83); no test asserts late-read behaviour. LUCENE-5513 (#6576), which added the API, never discusses copying.
The devil's-advocate check429 words
The case for "intended". Lucene is zero-copy by habit. Field's constructor and setBytesValue say "NOTE: the provided BytesRef is not copied so be sure not to change it until you're done with this field" (Field.java:190-191, 332-333), and in LUCENE-6321 (#7382, won't fix, 2015) rmuir called modifying term bytes after construction "an abuse case". So: do not change a BytesRef you handed to Lucene.
Three more texts a maintainer may cite. The BytesRefBuilder.get() javadoc: "Any update to the content of this builder might invalidate the provided ref and vice-versa" (BytesRefBuilder.java:151-154), against the loop. The 4.9.0 CHANGES entry of LUCENE-5703: "BinaryDocValues API changed to work like TermsEnum and not allocate/copy bytes on each access, you are responsible for cloning if you want to keep data around" (lucene/CHANGES.txt:12171-12173), against the pass-through. And shaie on LUCENE-5189 ("Numeric DocValues Updates", 2013-11-21): "The updates are buffered in their raw form in memory until a flush is needed (e.g. commit(), or NRT-open)."
Why it fails. updateBinaryDocValue(Term, String, BytesRef) takes no Field, and neither it nor BinaryDocValuesField's constructor carries such a note. The NOTE does not say when the writer is "done"; for addDocument it is done when the call returns. The pass-through case changes nothing the caller owns. No reading of the NOTE explains why the stored value depends on whether the target was flushed. The same LUCENE-6321 comment goes on: "But maybe its a good idea to do a little "extra" clone work to make these core queries defensive." The builder javadoc says the ref follows the builder, not how long IndexWriter reads it, and Term(String, BytesRefBuilder) copies (Term.java:63-66). In the pass-through the caller keeps nothing: IndexWriter keeps the reader's object out of the caller's sight, while the BinaryDocValues javadoc's own example clones before keeping. The 2013 comment, from when only numeric updates existed, contrasts updates buffered "raw" (term and value) with their resolved per-document form; it does not say the caller's objects are kept.
Where it partly survives. The reused-Field case (one BinaryDocValuesField whose BytesRef the caller changes between two updateDocValues calls) is close to what the NOTE warns about, so it is the secondary case. The documented reuse idiom, setBytesValue(new BytesRef(...)) per call, is not affected. OpenAI GPT-5.6 reviews rated the "intended" argument moderate and still judged the bug real, and the GPT-5.6 fact check of this doc rated it moderate for the direct API (weaker for the pass-through) and strong for the reused-Field case; the devil's-advocate checker and the adjudication found that it fails for the direct API.
Recommended Copy the value in the BinaryDocValuesUpdate constructor (validated)
Copy once at the boundary: BytesRef.deepCopyOf(value) in the BinaryDocValuesUpdate(Term, String, BytesRef) constructor, which both entry points use (one line). Cost: one array copy per binary update value. With it the repro passes 5/5, and the whole org.apache.lucene.index test package (1,400 tests) and the backward-compatibility update test pass.
BinaryDocValuesUpdate(Term term, String field, BytesRef value) {
  // Copy the caller's bytes, like Term(String, BytesRef) does: documents buffered in RAM get
  // this update only after the IndexWriter call has returned.
  this(term, field, value == null ? null : BytesRef.deepCopyOf(value), BufferedUpdates.MAX_INT);
}
All options and trade-offs3 options · 535 words
Option A was validated in a scratch worktree of main a9779ef3c193 through gradle; options B and C are design alternatives that were not run.
One line in DocValuesUpdate.java: the package-private constructor that both IndexWriter entry points call (IndexWriter.java:2013, :2113) deep-copies a non-null value. prepareForApply keeps using the private constructor, so there is no second copy. This is the remedy upstream chose for Term(String, BytesRef) in LUCENE-6821.
BinaryDocValuesUpdate(Term term, String field, BytesRef value) {
  // Copy the caller's bytes, like Term(String, BytesRef) does: documents buffered in RAM get
  // this update only after the IndexWriter call has returned.
  this(term, field, value == null ? null : BytesRef.deepCopyOf(value), BufferedUpdates.MAX_INT);
}
Trade-offs
- Cost: one array copy per binary update value (an
updateDocValuescall with several binary fields makes one per field), next to the copyFieldUpdatesBufferalready makes for every buffer the update is applied to. - Reach: the constructor is also used, through
buildDocValuesUpdate, bytryUpdateDocValue(IndexWriter.java:1724), which copies the bytes inside the call anyway (:1759-1761), so there the copy is extra but harmless; and bysoftUpdateDocument(s)(:1674,:1947) with a binary field, where it is needed: the calling per-thread writer applies the update inside the call, but other per-thread writers apply the queued node later (code reading, not executed). null: thenullbranch is reached:updateDocValues(term, new BinaryDocValuesField(field, null))resets a value (TestMixedDocValuesUpdates.testResetValue,:628), and that test passes with the fix.- RAM accounting: unchanged.
DocValuesUpdate.sizeInBytes()andvalueSizeInBytes()have had no caller since LUCENE-8590 (b0e6a92ede32) removed the last one.
What the checks validated
- The doc's test: 5/5 pass with assertions on and off (gradle, scratch worktree of main
a9779ef3c193, seed DEADBEEF); stock main fails 4 of 5. TestBinaryDocValuesUpdates,TestNumericDocValuesUpdates,TestSortedNumericDocValuesUpdates,TestMixedDocValuesUpdates,TestIncrementalDocValuesUpdatesand the new test (116 tests with two other methods that match the filter), plusTestDVUpdateBackwardsCompatibilityinbackward-codecs(12): 0 failures, 3 skipped by assumptions, assertions on and off.- The whole
org.apache.lucene.indextest package with assertions on: 1,400 tests, 0 failures (56 skipped). checkGoogleJavaFormat,ecjLintMain,ecjLintTest,forbiddenApisandrenderJavadocfor core pass.- Earlier, the same code change shadowed ahead of main's jars made every checker's own test pass: the finder's 3, the reviewer's 8, the reproducer's 6, the works-as-designed reviewer's 4, the devil's advocate's 5 and (run by the fact check) the audit's 4.
BytesRef.deepCopyOf at IndexWriter.java:2013 and, for the updateDocValues path, at :2113.
Trade-offs
Same effect; keeps BinaryDocValuesUpdate a plain holder, at the price of two sites to keep in sync. It saves no copy over option A: a copy at :2113 runs inside buildDocValuesUpdate, which tryUpdateDocValue and softUpdateDocument(s) share. Not run.
Document on updateBinaryDocValue, updateDocValues and BinaryDocValuesField that the BytesRef must not change after the call.
Trade-offs
No cost, but the honest window (until the per-thread writer holding the target documents next indexes a document or is flushed) is something a caller cannot see or control, so in practice the note says "never reuse it". It keeps the flushed-versus-buffered inconsistency and the reader pass-through trap. Not run.
Downstream relevance: an application that keeps per-document data in binary doc values and updates it through a reused buffer silently stores one document's value on other documents; a read-only code search found no common search server that calls this API outside tests.
Code reading, then a test; no model or proof. The hunt plan for IndexWriter update-value ownership listed the lead, and an AI tool confirmed it with a JUnit that changes the caller's BytesRef after one update reached a flushed and a buffered document.
The method in full210 words
- The lead. The hunt plan for the hunt unit on IndexWriter update-value ownership and doc-values buffers listed it from reading main: a
BinaryDocValuesUpdatekeeps the caller'sBytesRef, and a per-thread writer copies the bytes only at its next document or at flush. Not executed at that point. - The witness. The finder (an AI tool) wrote a differential "mutate after return" JUnit: one update applied to a flushed and to a buffered document, then the caller changes its own
BytesRef. It then classified everyIndexWriterentry point that takes a caller-owned mutable object, by executed probes except for theColumnBatchpath and theQueryobjects of query deletes (code reading). Besides the binary update value, the probes found only the varargs arrays ofdeleteDocumentskept after the call (a sibling candidate); the delete queue also keepsQueryobjects, which were not probed; the other probed arguments are copied or consumed during the call. - Not formal. No model, proof or exhaustive check produced the signal: the unit's bounded-exhaustive harness uses a fresh
BytesRefper call and cannot see it. - Then an independent reproducer, reviews by an independent reviewer from another model family (OpenAI GPT-5.6), a devil's-advocate checker, an adjudication and an audit re-ran it with their own tests (Checks below).
No prior report found (133 automated and 34 manual searches of GitHub, JIRA, four mailing lists, downstream projects and the web, 2026-10-27). Closest: 2014 comments on LUCENE-5189 warning that the Term of updateNumericDocValue is not cloned; Term was made to copy in 2015 (LUCENE-6821).
Searches5 searches
Verdict: new (no report of the same bug found). Not fixed upstream either: upstream main a95c754ee003 (2026-10-26) and branch_10x still store the reference.
Closest items: LUCENE-5189 / #6253, two comments of 2014-03-15 (mkhludnev: "When you call IW.updateNumericDocValue(Term, String, Long) make sure that the term is deeply cloned before. Otherwise, if you modify term or bytes, then the modified version will be applied."; shaie: deleteDocuments(Term) does the same, "the Term isn't cloned internally"). Same class of hazard, but about the Term of a numeric update, a different object with a different fix site; the binary value and the flushed-versus-buffered difference never come up. LUCENE-6821 / #7879 (2015): Term copies, the precedent for the fix. LUCENE-6321 / #7382 (2015, won't fix): "an abuse case", the likely objection. LUCENE-5513 / #6576 (2014): the introduction, no discussion of copying.
Gaps: GitHub search does not index code; the list API returns only the first 400 characters of a mail body.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene) | 2026-10-27 | 48 issue/PR and 6 commit queries in two automated runs, plus 24 manual searches (also Lucene.NET, Solr, other search servers and all of GitHub); 7 issues/PRs read in full with comments and reviews | no report of this defect |
| JIRA archive (LUCENE, SOLR) | 2026-10-27 | 12 automated and 10 manual queries; the full text of 15 issues | closest: LUCENE-5189 comments (Term of a numeric update); LUCENE-6821 (Term copies); LUCENE-6321 (won't fix, 'abuse case') |
| Mailing lists (dev@, java-user@, issues@, commits@) | 2026-10-27 | 40 queries | no report |
| Downstream repositories and the web | 2026-10-27 | 8 downstream queries (three search servers) and 19 web queries | no report |
| Open PRs (apache/lucene) | 2026-10-27 | the file lists of all 409 open PRs; the patches of the 21 that touch the doc-values update files | none changes BytesRef handling |
Introduced with the API in 4.8.0 (LUCENE-5513, 2014); the Field overload since 4.9.0. All 116 releases from 4.8.0 to 10.5.2 and main fail. Until 7.6.0 flushed documents got the late bytes too; LUCENE-8590 (7.7.0) narrowed it to buffered documents.
Versions tested6 rows
Introduced by LUCENE-5513 "Binary DocValues Updates" (JIRA, opened 2014-03-09, migrated as #6576; Subversion era, no pull request), committed by shaie on 2014-03-18 as "LUCENE-5513: add IndexWriter.updateBinaryDocValue": trunk c5263086b4da, branch_4x backport 019b0c879cbc, which 4.8.0 contains. It added BinaryDocValuesUpdate, whose constructor stores the reference. No later commit added a copy; LUCENE-8282 and LUCENE-8298 refactored the class in 2018 and kept the reference. The second entry point, updateDocValues(Term, Field...), came with LUCENE-5680 (de8e86b5d094 / f99a9d7ab049, 2014-05-29, 4.9.0).
Narrowed in 7.7.0 by LUCENE-8590 "Optimize DocValues update datastructures" (2018-12-04, eaf840867fad on branch_7x / b0e6a92ede32 on master): its FieldUpdatesBuffer copies the bytes when the global slice is applied inside the call, so flushed segments became correct; buffered documents stayed wrong.
Every era ran on JDK 25.0.3; the 4.x-6.x programs use RAMDirectory, 7.0 and later a file-system directory. The follow-up notes that neither takes part in when the update bytes are copied.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | 4 of 5 tests fail (gradle and repro harness, assertions on and off): buffered=c, new2 x3, src2 x3, x2 x2 |
| 7.7.0 to 10.5.2 (every release) | affected | flushed b, buffered c; the BytesRefBuilder loop stores new2 new2 new2 |
| 4.8.0 to 7.6.0 (every release) | flushed too | flushed c, buffered c; the loop stores new2 new2 new2 (the Field overload from 4.9.0) |
| 4.7.2 | API absent | the program does not compile: updateBinaryDocValue does not exist |
callers that pass BytesRef.deepCopyOf (control) | not affected | correct values on every era tested, 4.8.0 to main |
| fix option A on main | not affected | the repro 5/5 and the doc-values update suites pass |
An independent reproducer, OpenAI GPT-5.6 reviews (refute and works-as-designed lenses), a devil's-advocate checker, an adjudication and an audit all judged it real and re-ran it, all but the adjudication with tests of their own. The only objection that partly survives covers the reused-Field case.
Checks and verdicts559 words
All checks executed code on main a9779ef3c193, except the GPT-5.6 reviews, which ran on main ea57360912ed (none of the 7 commits in between touches the files involved; a separate run re-ran one review's test on a9779ef3c193).
| Check | Verdict | What it found |
|---|---|---|
| Finder | candidate | 3-test JUnit fails 3/3 with assertions on and off, 60/60 over 20 iterations of one random root seed (tests.iters=20); fails on 10.5.2 and 9.12.3 (JUnit) and 8.11.4, 8.0.0, 7.7.3, 7.0.0 (plain programs). The one-line copy passes it and keeps TestBinaryDocValuesUpdates + TestMixedDocValuesUpdates at 38/0. |
| review, refute lens (OpenAI GPT-5.6, executed) | real, high confidence | Its own 4-test JUnit failed 3 of 4 in every iteration with assertions on and off; the flushed-target control passed; with the fix 8/0 and the upstream suites 38/0. Rated the Field-NOTE argument moderate. |
| Independent reproducer | real | Own public-API JUnit (4 probes, 2 controls): 4/6 fail with assertions on and off, each probe 20/20 over 20 iterations of one root seed (tests.iters=20, assertions off), controls 0/40; 10.5.2 and 9.12.3 reproduce; the fix makes 6/6 pass. |
| Works-as-designed review (OpenAI GPT-5.6, executed) | real, high confidence; intended argument moderate | Its own test fails 2 of 4 on main and 10.5.2; re-run separately on a9779ef3c193: 2 of 4 fail with assertions on and off, 4/4 pass with the fix. |
| Devil's advocate | real | No intended, documented or misuse argument survives for updateBinaryDocValue; only the reused-Field case has a plausible misuse reading. Found the pass-through (src2 x3) and the fresh-BytesRef-over-reused-byte[] variants; its controls (addDocument reuse, setBytesValue idiom, flushed targets) pass; 5/5 with the fix. |
| Adjudication | confirmed, high confidence, not a duplicate | Re-ran the independent reproduction's test with the new seed 1CEB00DA: 4/6 fail with assertions on and off, the same values; controls pass. |
| Credibility audit | keep | A new public-API JUnit fails 2/4 with assertions on and off (changed after return, read through an NRT reader; reader pass-through); the fresh-BytesRef and change-after-next-addDocument controls pass. |
| This doc's runs | reproduced; fix validated | The doc's 5-test JUnit through gradle on a scratch worktree: stock 4/5 fail, with the fix 5/5 pass (assertions on and off); harness: the same 4/5 on main and 10.5.2. |
| Fact check of this doc (independent) | reproduced; 2 text errors, fixed | Re-ran the doc's gradle command in its own clone (4 of 5 fail, assertions on and off, lines identical), fix A (5/5; the update suites 116 tests, 0 failures), the harness on main (two seeds) and 10.5.2, the audit's test with the fix (4/4), and its own default-config probe. Errors: the prior-search count (133, not 124) and a RAM-estimate side effect of the fix that does not exist; both fixed. |
| Fact check of this doc (OpenAI GPT-5.6, read-only) | core finding holds; wording corrected | A reading-only review: 13 factual errors (0 high, 11 medium, 2 low), 7 overclaims and 8 missing caveats, none of which invalidates the main finding; it rated the "intended" case moderate for the direct API and strong for the reused-Field case. Every item was fixed or answered. |
| Diagram check | pass | Every on-screen value, API name and line matched the code and the probe; it also ran the pass-through with an unmodified new IndexWriterConfig() (src2 x3), which backs the summary card's default-config note. Nine minor layout and wording items, none blocking. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 528 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,166 words
- Registry title
- IndexWriter.updateBinaryDocValue and updateDocValues(Term, BinaryDocValuesField) keep the caller's BytesRef without copying it, so documents still buffered in RAM get the bytes that BytesRef holds at the writer's next document or flush instead of the value passed to the call (every release since 4.8.0)
- Area
- index / IndexWriter doc-values updates (BinaryDocValuesUpdate, DocumentsWriterDeleteQueue slices, FieldUpdatesBuffer)
- Priority
- Medium, rank 17: The core IndexWriter binary doc-values update silently commits the wrong value for buffered documents on default config whenever the caller reuses its BytesRef, Lucene's own scratch-buffer idiom, and a one-line copy fixes it.
- Impact class
- silent wrong results
- Impact note
- Hits applications that update binary doc values (updateBinaryDocValue, or updateDocValues with a BinaryDocValuesField) with a BytesRef they reuse or change after the call, or with a reader-owned BytesRef passed straight through, for documents added since the last flush or refresh; default IndexWriterConfig and codec, one thread, deterministic, no scale, the same with -ea and -da [exec]; the API itself is rarely used (no Lucene module calls it outside tests, and a read-only code search found no common downstream server that does).
- Summary
- You call IndexWriter.updateBinaryDocValue(term, field, value), or updateDocValues(term, binaryDocValuesField), and afterwards reuse or change that BytesRef, for example one BytesRefBuilder scratch for a loop of updates or a BinaryDocValues.binaryValue() taken from another reader; each document should get the value it was passed. Documents in flushed segments do, but documents still buffered in RAM get whatever bytes the BytesRef holds when the writer next adds a document or flushes, so a loop over one scratch buffer gives every buffered target the last value. The wrong value is committed silently: no exception, CheckIndex is clean, and the outcome depends on whether the target document had already been flushed.
- Introduced
- c5263086b4da47ae0331678f1ec64dc1e7e3577b on trunk / 019b0c879cbc8d788152dc0693ff2c7d6e88ccda on branch_4x (the backport that 4.8.0 contains), LUCENE-5513 'add IndexWriter.updateBinaryDocValue' (JIRA LUCENE-5513 = apache/lucene#6576; Subversion era, no pull request) [read: git log, tag --contains and blame; exec: 4.7.2 has no such API, 4.8.0 fails]. It added BinaryDocValuesUpdate, whose constructor stores the BytesRef reference, and updateBinaryDocValue, which passes the caller's BytesRef straight in; no later commit added a copy (git log -S deepCopyOf on DocValuesUpdate.java finds none; LUCENE-8282 and LUCENE-8298 refactored the class in 2018 and kept the reference). The second entry point, updateDocValues(Term, Field...), came with LUCENE-5680 (de8e86b5d094227eeca7abf56083ee598687b0e6 on branch_4x / f99a9d7ab0497b88f5a49dbe7b7bbb958756aa1a on trunk) and passes f.binaryValue() into the same constructor. (2014-03-18 (LUCENE-5513); 2014-05-29 (LUCENE-5680, second entry point))
- First affected version
- 4.8.0 [exec: fails, flushed=c buffered=c; 4.7.2, the last release before, cannot compile the program because updateBinaryDocValue does not exist]; 4.9.0 for updateDocValues(Term, Field...) [exec]
- Affected versions
- every release from 4.8.0 through 10.5.2 (the last release before 10.6.0) and main a9779ef3c193; never fixed. [exec] 116 releases (4.8.0-4.10.4 and every 5.x, 6.x, 7.x, 8.x, 9.x and 10.x release) plus main, 117 targets, all fail with era-adapted public-API main() programs; the JUnit fails on 9.12.3, 10.0.0, 10.5.2 and main (-ea and -da), and the independent reproduction reproduced 10.5.2 and 9.12.3 with its own test. How it shows: on 4.8.0-7.6.0 every updated document, flushed or buffered, reads the late bytes; from 7.7.0 on (LUCENE-8590, whose FieldUpdatesBuffer copies the bytes when the global slice is applied inside the call) flushed segments get the value as of the call and only documents still buffered in RAM read late bytes; the reused-buffer loop is wrong on every release. [read] upstream main a95c754ee003 (2026-10-26) and branch_10x still store the reference.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (2026-10-27, the prior-report record: 133 scripted prior-report search queries (66 + 67 in two runs) over GitHub issues/PRs/commits, downstream repositories, four mailing lists, JIRA and the web, plus 24 manual GitHub and 10 manual JIRA searches, the full text of 15 JIRA issues and 7 GitHub issues/PRs, and the file lists of all 409 open PRs; the finder, the intended-behaviour check and the adjudication found nothing either). Not fixed upstream: main a95c754ee003 and branch_10x still store the reference, and none of the 21 open PRs that touch the doc-values update files changes BytesRef handling. Closest prior discussion (a different argument): two comments of 2014-03-15 on LUCENE-5189 / #6253 by mkhludnev and shaie, warning that the Term passed to updateNumericDocValue (and deleteDocuments) is not cloned; LUCENE-6821 / #7879 (2015, Term(String, BytesRef) copies, called 'a bug fix') closed the common route for that Term half and is the precedent for the fix; LUCENE-6321 / #7382 (won't fix) called mutating term bytes after construction 'an abuse case', a likely objection.
- Lucene commit tested
- main
a9779ef3c193(2026-10-26): the doc's JUnit through gradle on a scratch worktree and through the hunt repro harness, assertions on and off; the 10.5.2 release jars; the follow-up's era-adapted public-API programs on all 116 releases from 4.8.0 to 10.5.2 (4.7.2 lacks the API). The checkers' tests ran on maina9779ef3c193orea57360912ed; none of the 7 commits between them touches the files involved.
- Finding record
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:131-132 ('flushing just moves the internal buffered state in IndexWriter into the index'), :1981-2018 (updateBinaryDocValue javadoc 'to the given value'; line 2013 passes the caller's BytesRef) and :2113 (updateDocValues(Term, Field...) passes f.binaryValue())lucene/core/src/java/org/apache/lucene/index/DocValuesUpdate.java:108-121 (BinaryDocValuesUpdate stores the reference; prepareForApply 'it's a final value')lucene/core/src/java/org/apache/lucene/index/DocumentsWriterDeleteQueue.java:135-139, 198-215 (update node queued; only the global slice is applied in the call, under tryLock)lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThread.java:361-389, 427-436 (per-thread slice applied at the next document or at flush)lucene/core/src/java/org/apache/lucene/index/FieldUpdatesBuffer.java:207-211 (first copy of the bytes, byteValues.append)lucene/core/src/java/org/apache/lucene/document/Field.java:190-191, 332-333 (NOTE: the provided BytesRef is not copied)lucene/core/src/java/org/apache/lucene/index/Term.java:50-55 (Term copies its BytesRef)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:1996-2018, 2070-2113 (both entry points pass the caller's BytesRef)lucene/core/src/java/org/apache/lucene/index/DocValuesUpdate.java:108-122 (reference stored; prepareForApply)lucene/core/src/java/org/apache/lucene/index/DocumentsWriterDeleteQueue.java:135-139, 198-215, 500-520 (queued node; global slice under tryLock; node apply)lucene/core/src/java/org/apache/lucene/index/BufferedUpdates.java:146-156 and FieldUpdatesBuffer.java:207-212 (first copy)lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThread.java:361-390, 427-439 (per-thread slice applied at the next document or at flush)lucene/core/src/java/org/apache/lucene/index/FieldUpdatesBuffer.java:107-112 (the constructor copies a field's first update) and IndexWriter.java:2969-2990, 6783 (packet and segment delete generations)
- Who is affected
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:1673-1674, 1946-1947 and DocumentsWriterDeleteQueue.java:154-173 (softUpdateDocument(s) queue the same update node; code reading)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:131-132, 1981-1995, 2060, 1759-1761lucene/core/src/java/org/apache/lucene/index/BinaryDocValuesFieldUpdates.java:94-98; Term.java:44-55; DocValuesUpdate.java:117-122; BinaryDocValues.java:43-50lucene/core/src/java/org/apache/lucene/document/Field.java:187-191, 329-335; BinaryDocValuesField.java:48-58lucene/core/src/test/org/apache/lucene/index/TestBinaryDocValuesUpdates.java:69-83 (fresh BytesRef per call)lucene/core/src/java/org/apache/lucene/util/BytesRefBuilder.java:151-158; Term.java:63-66; lucene/CHANGES.txt:12171-12173 (LUCENE-5703, under Lucene 4.9.0)
- Suggested fix
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:1674, 1724, 1947, 2013, 2113 (constructor callers)lucene/core/src/java/org/apache/lucene/index/DocValuesUpdate.java:108-127 (constructors, prepareForApply, valueSizeInBytes)lucene/core/src/test/org/apache/lucene/index/TestMixedDocValuesUpdates.java:601-628 (testResetValue: null binary value)
- TestBinaryDocValuesUpdateReusedBytesRef.java (JUnit test):
repro/LFV-643/src/org/apache/lucene/index/TestBinaryDocValuesUpdateReusedBytesRef.java(54 lines)
Made in parallel with this doc from the diagram probe's trace (a plain main() on the public API, run on main with assertions on and off and with the fix).
assets/LFV-643/bug.png(528 KB)