A sink replays the tee's recorded token states, but it only has the attributes the tee had when the sink was made.
- A token stream carries each token's data in attributes: the term text, offsets, a keyword flag, a payload. All filters of one chain share one set of attributes, and each filter adds the ones it needs in its constructor.
TeeSinkTokenFilterlets fields share analysis. While the tee is read, it records a snapshot of all attributes for every token; each sink fromnewSinkTokenStream()replays those snapshots later, for example as an unstemmed copy of a stemmed field.- Replaying a snapshot (
restoreState) copies each attribute in it into the same attribute of the sink, so the sink must have every attribute the snapshot holds.
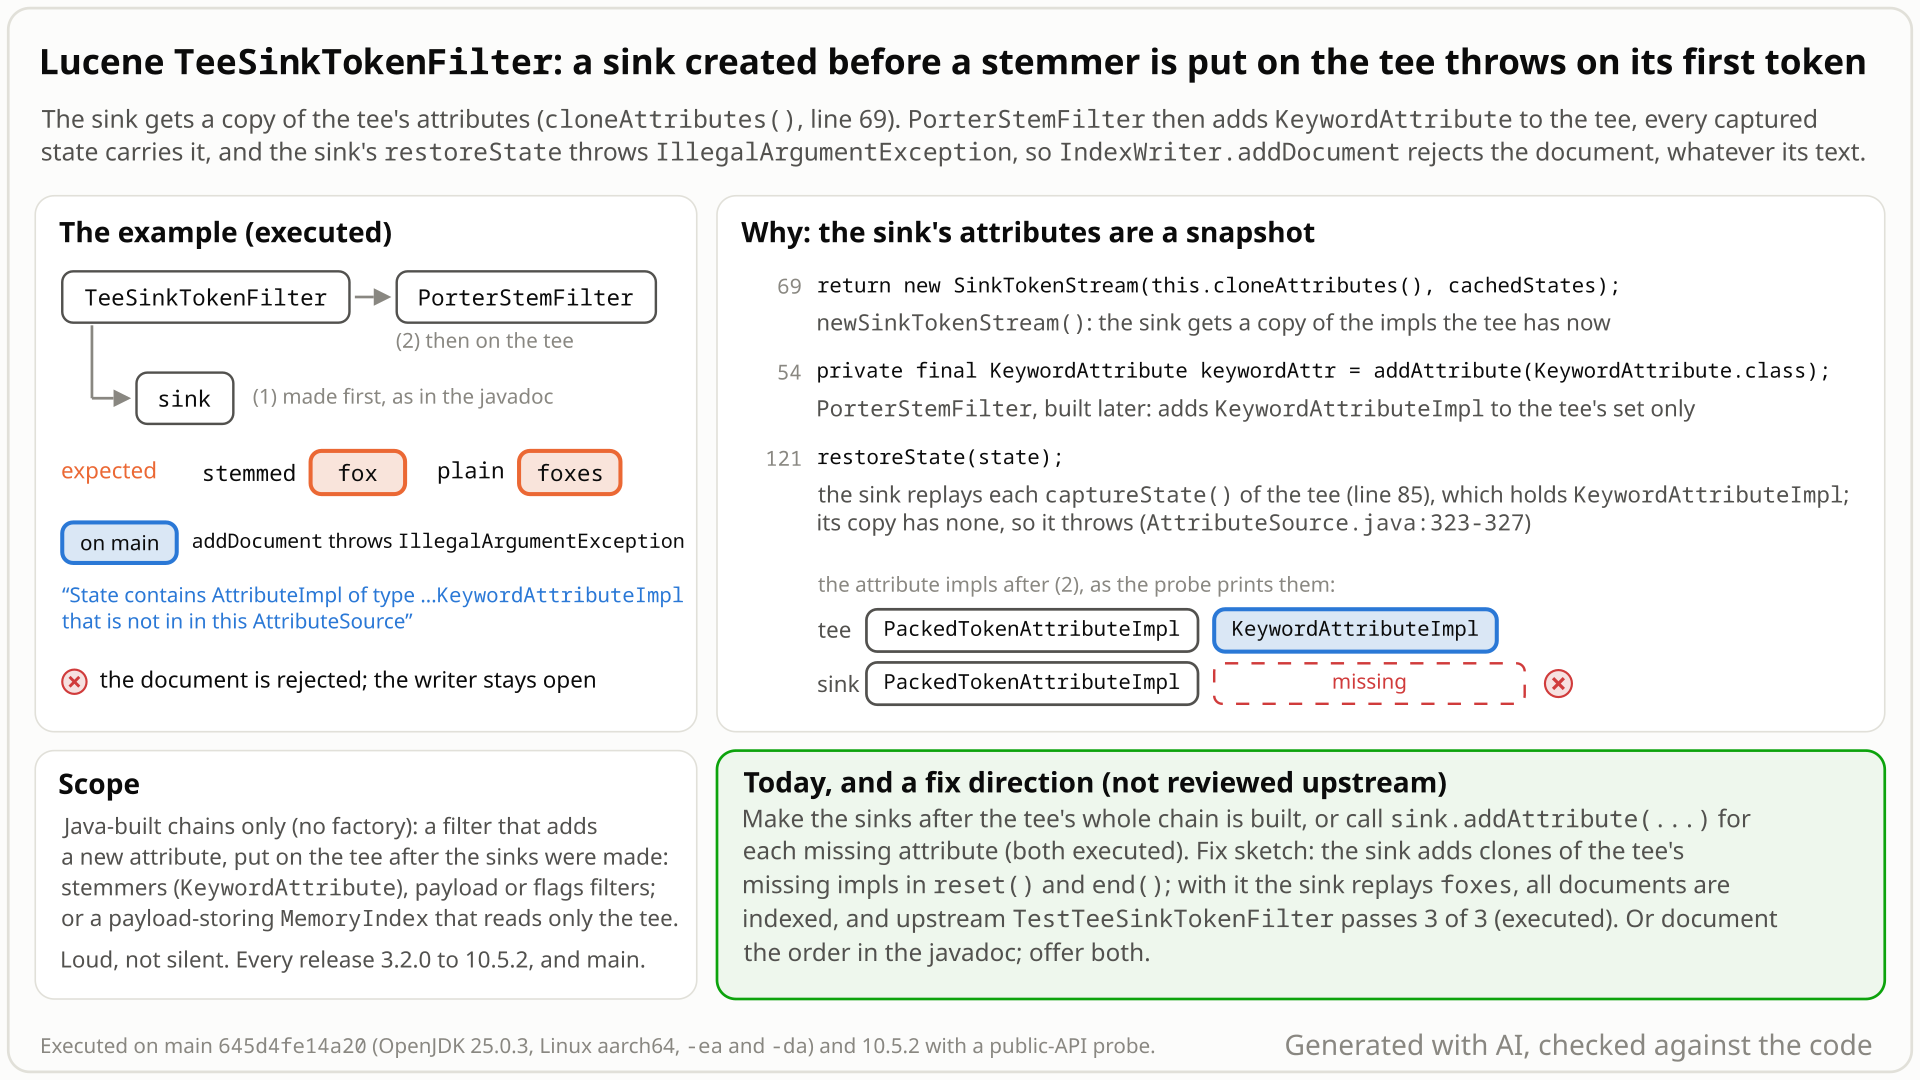
PorterStemFilter adds KeywordAttribute to the tee; every recorded token state carries it, and the sink's replay throws. Select the still to open it at full size. Generated with AI, checked against the code.- Tokenize
foxes, wrap it in aTeeSinkTokenFilter, calltee.newSinkTokenStream(), and only then wrap the tee inPorterStemFilter: sink first, then a filter on the tee, as in the class javadoc. - Read the stemmed stream (it gives
fox), then the sink. You expectfoxes: the sink "receives all tokens consumed by this stream". - Instead the sink's first
incrementToken()throwsIllegalArgumentException: State contains AttributeImpl of type ...KeywordAttributeImpl that is not in in this AttributeSource. WithIndexWriter,addDocumentrejects every document built this way: 5 of 5 texts tried, from an empty value to 2,000 tokens. - Why: the sink got a copy of the tee's attributes when it was made. The stemmer then adds
KeywordAttributeto the tee, every recorded token carries it, and the sink cannot restore an attribute it does not have. - Create the sink after the stemmer and it returns
foxes. The javadoc's ownLowerCaseFilteradds nothing new, so that example works.
Java code that creates a tee's sinks and then puts on the tee a filter that adds a new attribute: a stemmer (KeywordAttribute), a payload or a flags filter. The class has no factory, so analysis configuration cannot reach it. Every document fails at once and loudly; the writer stays open, and creating the sinks last avoids it.
Mechanism, terms and numbers666 words
TeeSinkTokenFilter records the attribute state of every token it passes, and each sink made with newSinkTokenStream() replays those states later, so that several fields can share analysis steps. The sink is built from cloneAttributes(), a copy of the attribute implementations the tee has at that moment. A filter put on the tee afterwards, the order of the class javadoc's example, shares the tee's attributes; when its constructor adds a new one, for example PorterStemFilter adding KeywordAttribute, every state the tee records contains it, the sink does not, and the sink's first restoreState() throws IllegalArgumentException. With IndexWriter, the tee's field first as documented, every document that uses the chain is rejected (5 of 5 texts tried, from an empty value to 2,000 tokens; every recorded state carries the attribute, including the end state that even an empty value has, so the text cannot matter); the exception does not abort the writer and CheckIndex stays clean. Creating the sink after the stemmer, or adding the attribute to the sink by hand, avoids it. The javadoc's own LowerCaseFilter adds no new attribute implementation, so its example works; a narrow split setup fails even with it (a payload-storing MemoryIndex reads the tee while something else reads the sink). The snapshot dates from 2009 (2.9.0); a correct 2011 fix of a stale state cache (LUCENE-3042) exposed it, so every release from 3.2.0 to 10.6.0 and main fails.
newSinkTokenStream()returnsnew SinkTokenStream(this.cloneAttributes(), cachedStates)(TeeSinkTokenFilter.java:68-70).cloneAttributes()clones the attribute implementations present at that moment (AttributeSource.java:424-431); the sink never looks at the tee's attributes again.- A filter wrapped around the tee shares the tee's attribute maps:
TokenFilter(input)callssuper(input)(TokenFilter.java:34-37), andAttributeSource(AttributeSource)"uses the same attributes as the supplied one" (AttributeSource.java:78-85).PorterStemFilteraddsKeywordAttributewhen it is built (PorterStemFilter.java:54), asTokenStreamasks ("the attributes must be added during instantiation",TokenStream.java:64-66). Now the tee has aKeywordAttributeImpl; the sink's copy does not. - The tee records
captureState()for every token (TeeSinkTokenFilter.java:85) and atend()(:95). A state holds every implementation of the shared source (AttributeSource.java:300-303), so it includesKeywordAttributeImpl. SinkTokenStream.incrementToken()andend()callrestoreState(state)(TeeSinkTokenFilter.java:121,:129).restoreStatelooks up each implementation of the state by class in the sink and throwsIllegalArgumentExceptionwhen one is missing (AttributeSource.java:322-327): the first token fails; a value without tokens fails inend().- In
IndexWriterthe exception escapesstream.incrementToken()(IndexingChain.java:1987); analyzer exceptions are non-aborting (comment:1989-1994) and the document is marked deleted (DocumentsWriterPerThread.java:303-306).
| on the tee, after the sink was created | result |
|---|---|
PorterStemFilter, KStemFilter (KeywordAttribute; 49 source files in analysis-common add it) | IllegalArgumentException, KeywordAttributeImpl |
DelimitedPayloadTokenFilter (PayloadAttribute) | IllegalArgumentException, PayloadAttributeImpl |
TypeAsSynonymFilter (FlagsAttribute) | IllegalArgumentException, FlagsAttributeImpl |
LowerCaseFilter, the javadoc's filter | works: the tokenizer already provides CharTermAttribute |
LowerCaseFilter, the tee read by MemoryIndex(storePayloads=true) (it adds PayloadAttribute before reset(), MemoryIndex.java:1006-1008), the sink read by hand | IllegalArgumentException, PayloadAttributeImpl |
the same, both fields read by one MemoryIndex(storePayloads=true) | works: it adds PayloadAttribute to the sink too |
the sink created after the stemmer, or sink.addAttribute(KeywordAttribute.class) | works |
Default tokenizers start with one packed implementation of term, offsets, position increment and length, type and term frequency, so those never trigger it; StopFilter stopped triggering it in 4.9.0 for that reason.
Before LUCENE-3042 (Uwe Schindler, 2011) each filter of a chain kept its own cached state, so the tee's captureState() returned stale states without the late attribute and the sink replayed them without error (for the stemmer this matters only in 3.1.0: in 2.9.x and 3.0.x PorterStemFilter adds no KeywordAttribute yet). LUCENE-3042 correctly made the chain share one cache, which exposed the 2009 snapshot. Swapping only AttributeSource.java flips the result both ways: 3.1.0 with the new file fails 3 of 3 cases, 3.2.0 with the old file passes 3 of 3.
Exposure and likelihood278 words
- Who is hit. Code that builds the chain in Java in the javadoc's order with a filter on the tee that adds an attribute implementation the tee did not have yet. A plausible use is a stemmed field next to an unstemmed copy (
PorterStemFilter,KStemFilter,SnowballFilter, ...); payload (DelimitedPayloadTokenFilter) and flags (TypeAsSynonymFilter) filters do the same. Narrowly also a split setup: aMemoryIndexwithstorePayloads=truereads the tee's field and a consumer that does not addPayloadAttributereads the sink, which fails even withLowerCaseFilter; one suchMemoryIndexfor both fields works. - Default vs opt-in. Opt-in and expert:
TeeSinkTokenFilterhas no factory (TestAllAnalyzersHaveFactoriesexempts it), so analysis configuration files cannot use it; a code search found no use in the major open-source search servers built on Lucene (default branches). - What happens. With the tee's field first (the documented order), every document built with the chain is rejected with
IllegalArgumentException: 5 of 5 texts tried (empty, whitespace only, one token, a sentence, 2,000 tokens), and by the code the text cannot matter. The writer stays open, no tragic exception is recorded, nothing of the rejected document is searchable, later documents index normally, andCheckIndexis clean. - Scale and likelihood. Deterministic from the first document; independent of text and index size. Plausible among the few users of the class: it follows the documented order, but it fails at once and loudly, and the recorded public searches found no report of it since 3.2.0 (2011).
- Workarounds. Create the sinks after the tee's whole chain is built, or call
sink.addAttribute(...)for each attribute the tee's chain adds (KeywordAttribute.classfor stemmers).
One JUnit test, one token, public API only. It fails with assertions on and off and is also the suggested regression test.
package org.apache.lucene.analysis.sinks;

import java.io.StringReader;
import org.apache.lucene.analysis.TokenStream;
import org.apache.lucene.analysis.Tokenizer;
import org.apache.lucene.analysis.core.WhitespaceTokenizer;
import org.apache.lucene.analysis.en.PorterStemFilter;
import org.apache.lucene.analysis.tokenattributes.CharTermAttribute;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestTeeSinkAttributeAddedAfterSink extends LuceneTestCase {

  public void testSinkAfterStemmerOnTee() throws Exception {
    Tokenizer tokenizer = new WhitespaceTokenizer();
    tokenizer.setReader(new StringReader("foxes"));
    TeeSinkTokenFilter tee = new TeeSinkTokenFilter(tokenizer);
    // sink first, then a filter on the tee, as in the class javadoc
    TokenStream sink = tee.newSinkTokenStream();
    TokenStream stemmed = new PorterStemFilter(tee);
    stemmed.reset();
    while (stemmed.incrementToken()) {}
    stemmed.end();
    stemmed.close();

    CharTermAttribute term = sink.getAttribute(CharTermAttribute.class);
    sink.reset();
    try {
      assertTrue(sink.incrementToken());
    } catch (IllegalArgumentException e) {
      throw new AssertionError("expected the sink to replay \"foxes\", but it threw " + e, e);
    }
    assertEquals("foxes", term.toString());
  }
}
cp $REPRO/TestTeeSinkAttributeAddedAfterSink.java $LUCENE/lucene/analysis/common/src/test/org/apache/lucene/analysis/sinks/
cd $LUCENE && ./gradlew :lucene:analysis:common:test --tests org.apache.lucene.analysis.sinks.TestTeeSinkAttributeAddedAfterSink -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off: -Ptests.asserts=false (same failure)
- Expected
- The sink replays the token the tee consumed:
foxes. - Observed
- The sink's first
incrementToken()throwsIllegalArgumentException("...KeywordAttributeImpl that is not in in this AttributeSource").
More files, environment, full output213 words
Copy the file to lucene/analysis/common/src/test/org/apache/lucene/analysis/sinks/. It sends one token, foxes, through WhitespaceTokenizer -> TeeSinkTokenFilter, creates the sink, then wraps the tee in PorterStemFilter, consumes the stemmed stream and reads the sink. Deterministic: no randomness, the seed only fixes the runner. It reads both streams by hand on purpose: assertTokenStreamContents adds a check attribute of its own to every stream it reads, which would be a second late attribute (in this order the sink throws for KeywordAttributeImpl either way). Name tests.asserts explicitly: the build randomizes it per seed otherwise, and DEADBEEF picks off. Through IndexWriter the same exception rejects the document in addDocument; that is described, not tested here.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); the 10.6.0 release and every release since 3.2.0 also fail |
|---|---|
| jdk | OpenJDK 25.0.3 |
| os | Linux aarch64 |
TestTeeSinkAttributeAddedAfterSink > testSinkAfterStemmerOnTee FAILED
    java.lang.AssertionError: expected the sink to replay "foxes", but it threw java.lang.IllegalArgumentException: State contains AttributeImpl of type org.apache.lucene.analysis.tokenattributes.KeywordAttributeImpl that is not in in this AttributeSource
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:FE21949B5686915D]:0)
        at org.apache.lucene.analysis.sinks.TestTeeSinkAttributeAddedAfterSink.testSinkAfterStemmerOnTee(TestTeeSinkAttributeAddedAfterSink.java:30)

        Caused by:
        java.lang.IllegalArgumentException: State contains AttributeImpl of type org.apache.lucene.analysis.tokenattributes.KeywordAttributeImpl that is not in in this AttributeSource
            at org.apache.lucene.core@11.0.0-SNAPSHOT/org.apache.lucene.util.AttributeSource.restoreState(AttributeSource.java:326)
            at org.apache.lucene.analysis.sinks.TeeSinkTokenFilter$SinkTokenStream.incrementToken(TeeSinkTokenFilter.java:121)
            at org.apache.lucene.analysis.sinks.TestTeeSinkAttributeAddedAfterSink.testSinkAfterStemmerOnTee(TestTeeSinkAttributeAddedAfterSink.java:28)

1 test completed, 1 failed

# the same with -Ptests.asserts=false and on the 10.6.0 release jars; with the recommended fix the test passes- The class javadoc creates the sinks first, then wraps the tee in another filter;
newSinkTokenStream()promises a sink that "receives all tokens consumed by this stream". - The stemmer adds its attribute when it is built, as
TokenStreamrequires; no creation-order limit is documented. - The design goal was a sink with "exactly the same attributes" as the tee (LUCENE-1693).
The full argument262 words
- The documented order fails once the filter on the tee adds a new attribute. The example creates
sink1andsink2and then writesTokenStream final1 = new LowerCaseFilter(source1);(TeeSinkTokenFilter.java:36-40); the class is pitched for fields that "share many common analysis steps and then go their separate ways" (:28-30). The only documented constraint is that "tees are consumed before sinks" (:53-57). - The promise.
newSinkTokenStream(): "Returns a new SinkTokenStream that receives all tokens consumed by this stream" (:67). - The design intent. In LUCENE-1693 (#2767, 2009), which added the class, Michael Busch wrote that the factory method is the way to "ensure that the sink tokenstream has exactly the same attributes as the TeeSinkTokenFilter". Related history, not a precedent for replaying: the pre-5.5
addSinkTokenStream(), which attached an existing sink to a second tee, had a loop to "add eventually missing attribute impls to the existing sink" when it was attached (removed with that method by LUCENE-6973, first released in 5.5.0). - The stemmer follows the rules.
TokenStream: "the attributes must be added during instantiation" (TokenStream.java:64-66). - A similar class states and checks its precondition.
ConcatenatingTokenStream: "All of the input TokenStreams must have the same attribute implementations" (ConcatenatingTokenStream.java:36), checked when it is built, with "Attempted to concatenate TokenStreams with different attribute types" (:68-83). NoTeeSinkTokenFilterjavadoc, CHANGES or MIGRATE entry mentions an attribute or creation-order limit, and no test asserts the exception. - Precedent. SOLR-8460 (2015) fixed the same kind of bug in Solr's
ListBasedTokenStreamby adding the source's attribute implementations.
The devil's-advocate check302 words
The strongest case for "works as designed" (rated moderate by the cross-model reviews; the devil's-advocate verifier built the same case and rejected it): cloneAttributes() is documented as a copy taken when it is called (AttributeSource.java:424-430), restoreState() says the target "must contain a corresponding instance for each argument contained in this state" (:305-311), TokenStream asks for attributes at instantiation, which could be read as "build the whole chain before deriving sinks", and upstream's TestTeeSinkTokenFilter.testGeneral adds its late check attribute to the sink by hand (TestTeeSinkTokenFilter.java:121-124, since LUCENE-2211 in 2010), so the authors knew. In 2009 on dev@ ("attribute thoughts"), asked by Yonik Seeley whether filters may add attributes after their constructor, Michael Busch said the TokenStream javadocs ask for all attributes up front ("We could change these semantics"); asked whether restoreState() should be able to add attributes, he said that could only work if both sources use the same AttributeFactory, and later agreed with Yonik Seeley's suggestion of an assertion that the factories are equal.
Why it fails: the class's own example creates the sinks first and then wraps the tee, and newSinkTokenStream() promises a sink that "receives all tokens consumed by this stream"; the snapshot and restoreState() rules are internal mechanics that TeeSinkTokenFilter itself has to reconcile, not a contract stated to its users; the stemmer adds its attribute at instantiation, as required; and the test workaround is unexplained test code (and redundant, because assertTokenStreamContents adds that attribute itself, BaseTokenStreamTestCase.java:162-163). A narrower, secondary point: when a payload-storing MemoryIndex reads the tee and something else reads the sink, the consumer adds the attribute, so "build the chain first" does not help there. Verdict: not intended, a usability and correctness defect with a loud failure mode. Maintainers may still prefer to fix it in the javadoc.
Recommended A: the sink adds the tee's missing attributes before replaying (validated)
Let the sink catch up: in reset() and end(), before replaying, it adds a copy of each attribute implementation the tee gained after the sink was made (+18 lines in TeeSinkTokenFilter). With it the repro and all 1,910 tests of the analysis-common module pass.
private void addTeeAttributes() {
  for (Iterator<AttributeImpl> impls = tee.getAttributeImplsIterator(); impls.hasNext(); ) {
    // addAttributeImpl does nothing for an implementation this sink already has
    addAttributeImpl(impls.next().clone());
  }
}

@Override
public void reset() {
  addTeeAttributes();
  it = cachedStates.getStates();
}
// end(): the same call before restoreState(finalState)
All options and trade-offs3 options · 858 words
Option A was applied in a scratch worktree of 645d4fe14a20 and run with gradle (the worktree was removed after the runs); it is the finder's fix with a renamed method and comments. Options B and C were not built. The sibling LFV-651 (a sink never clears attributes only its own chain adds) changes other lines of the same class; the two patches were not tested together.
The sink keeps a reference to the tee (newSinkTokenStream() passes this), and reset() and end() call addTeeAttributes() before replaying. addAttributeImpl returns at once for an implementation class the sink already has (AttributeSource.java:188-190), so existing attributes, including ones the sink's own chain added, are untouched; a new copy holds the tee's current values until the next restoreState overwrites them. Scope limit: addAttributeImpl registers a new class only for an interface the sink does not have yet (:193-200), so an implementation class whose interfaces the sink already has through other classes is not added and restoreState still throws; with the shared AttributeFactory this needs custom implementations added by hand. An attribute the tee gains after the sink's reset() is added only at the sink's end(), before the final state is restored; a token state replayed before that which contains it still throws. That needs the tee to be read after the sink's reset(), which is outside the documented order (tees consumed before sinks).
private void addTeeAttributes() {
  for (Iterator<AttributeImpl> impls = tee.getAttributeImplsIterator(); impls.hasNext(); ) {
    // addAttributeImpl does nothing for an implementation this sink already has
    addAttributeImpl(impls.next().clone());
  }
}

@Override
public void reset() {
  addTeeAttributes();
  it = cachedStates.getStates();
}
// end(): the same call before restoreState(finalState)
Trade-offs
- Fixes every tested trigger, including the split
MemoryIndex(storePayloads=true)case that a javadoc note cannot cover. - The sink's attribute set can now grow at
reset()andend(). In the setups that work today the sink normally lacks nothing, so nothing is added; where something is added, the extra implementations (holding the tee's current values until the nextrestoreState) are visible through the sink'sAttributeSource, e.g.hasAttributeorgetAttributeImplsIterator, and no test covers code that inspects them. A sink reused across documents keeps the grown set; reviewers may ask about this. - Cost: one
clone()per tee attribute implementation perreset()andend(), also for ones the sink already has (the copy is then discarded); a handful of small objects per sink and document, not benchmarked. - Not fully general: custom implementation classes added by hand with
addAttributeImplare not covered, and an attribute the tee gains after the sink'sreset()is added only atend(), so token states replayed before that still throw (only outside the documented order). - Backport: on 10.6.0 the sink's
incrementToken()andreset()are declaredfinal, so thereset()hunk needs a manual edit; only main was built with the fix. Not validated: another JDK or architecture, custom implementations whose interfaces overlap, or together with the LFV-651 fix.
What the checks validated
- Gradle in a scratch worktree of
645d4fe14a20, stock: the repro fails with assertions on and off (1 test, 1 failure each). - With the fix applied: the repro and
TestTeeSinkTokenFilter(3 upstream tests) pass with assertions on and off (4 tests, 0 failures); the whole:lucene:analysis:commontest task passes with assertions on: 340 suites, 1,910 tests, 0 failures, 18 skipped. - Earlier runs of the same patch: the whole analysis-common test task with assertions off and
:lucene:analysis:common:check -x test(format, ecjLint, forbiddenApis) passed; shadowed into the stock main jars (the patched class compiled ahead of them, not a built Lucene), the finder's 2 tests (incl. theIndexWritervariant) and the independent reproducer's 6 tests pass, and the devil's-advocate probe no longer throws for the stemmer or theMemoryIndex(storePayloads=true)case. - With the finder's patch (same logic): the cross-model reviewer's 5 tests pass, and the exhaustive model check has 0 mismatches (4,092 of 4,092 inputs fail on stock).
State in the class javadoc that sinks must be created after the tee's whole chain is built, and reorder the example (and fix its declared sink type: TeeSinkTokenFilter.SinkTokenStream sink1 = source1.newSinkTokenStream(); does not compile, the method returns TokenStream).
Trade-offs
No code change, but existing code that follows the current example's order with a filter that adds a new attribute keeps failing, and it does not help in the narrow split case where the tee's consumer adds an attribute (a payload-storing MemoryIndex reads the tee, something else reads the sink).
In reset(), check that the sink has every implementation of the tee and throw an IllegalStateException saying "create sinks after the tee's chain is built".
Trade-offs
A clearer and earlier error (at the sink's reset()), and the javadoc's LowerCaseFilter example keeps working, but the documented order with a filter that adds a new attribute still fails. It would also catch the MemoryIndex case: MemoryIndex adds PayloadAttribute before it resets the tee (MemoryIndex.java:1006-1008), so the tee already has it when the sink is reset later.
No security relevance found: only the application's own chain-building code can trigger it, and it fails closed (the document is rejected, the writer stays open, the index stays clean).
An AI tool wrote an executable model of the class javadoc (every sink replays exactly the tee's tokens) and checked the real class against it on every small input. When a filter that adds an attribute was put on the tee after the sinks, all 4,092 inputs failed; documented uses had none. It was reduced to a one-token test.
The method in full167 words
Method: semi-formal (bounded-exhaustive translation validation against reference semantics).
- The model states the javadoc's promise: every sink replays exactly the tee's token states and its end state. It was run against the stock
TeeSinkTokenFilterover 0 to 4 input tokens x position increments {1, 2} x offset gaps {0, 1} x final increment {0, 1} x final offset slack {0, 1} x 1 to 3 sinks, in five consumption scenarios of 4,092 checks each. - The scenario "a filter that adds an attribute is put on the tee after the sinks were created" failed on all 4,092 inputs with this exception; "tee consumed first", "
consumeAllTokens()plusend()" and "a sink read twice" had 0 mismatches. A fifth scenario,consumeAllTokens()without the tee'send(), had 3,579 mismatches (a stale end state, the same with the fix); its sibling report was withdrawn as works-as-designed. - The finder reduced it to a public-API JUnit with a stemmer and an
IndexWritervariant, later minimized to the one-token test on this page.
No prior report found (GitHub issues and PRs incl. the JIRA archive, mailing lists, downstream projects, the web; re-checked 2026-10-30). Upstream's own test adds its late check attribute to its sink by hand, without comment. Not fixed upstream.
Searches4 searches
No report of this bug was found, and upstream main still builds the sink from a creation-time copy. Upstream shows implicit awareness, none of it a report: TestTeeSinkTokenFilter.testGeneral has added its late check attribute to the sink by hand since LUCENE-2211 (2010); the LUCENE-1693 discussion states the "exactly the same attributes" intent; the 2009 dev@ thread "attribute thoughts" discusses whether restoreState() should add attributes in general. None of these is a public report of the bug, so the novelty stays new.
| Where | When | How | Found |
|---|---|---|---|
| GitHub (apache/lucene issues, PRs, commits, incl. the migrated JIRA archive) and downstream repositories | 2026-10-26 and 2026-10-27 | three automated passes, 175 queries (identifiers, the exact error phrase, triggers, pre-2.9 class names), plus manual searches; all 11 issues naming TeeSinkTokenFilter read | no report; closest #2767 (LUCENE-1693, design intent), #3287 (LUCENE-2211, the test workaround), #8030 (LUCENE-6973 rewrite), #4115 (LUCENE-3042, a different, fixed late-attribute bug) |
| Open PRs | 2026-10-27 | changed-file lists of all 409 open apache/lucene PRs | none touches TeeSinkTokenFilter.java or AttributeSource.java |
| JIRA archive, mailing lists, Stack Overflow, web | 2026-10-27 | LUCENE, SOLR and LUCENENET JIRA; dev@, java-user@, issues@, commits@ and the Solr lists (15 threads naming the class read); Stack Exchange API; general web queries | precedent only: SOLR-8460 (same kind of bug in Solr's ListBasedTokenStream, fixed by adding the source's attributes); the same error message elsewhere comes from attribute-factory mismatches (LUCENE-7382, outside streams) |
| Re-check for this page | 2026-10-30 | GitHub issue and PR search for TeeSinkTokenFilter and the exact error phrase; commit lists of TeeSinkTokenFilter.java and AttributeSource.java | the same 11 closed issues, no PR, no hit for the phrase in issues or PRs; the last commits on both files are cosmetic |
The creation-time copy came with the class in 2.9.0 (LUCENE-1693, 2009); a correct 2011 cache fix (LUCENE-3042) exposed it, so it fails from 3.2.0. Every executed release from 3.2.0 to 10.6.0, and main, fails.
Versions tested7 rows
LUCENE-1693 (#2767; commit 31a5f0edcc47 "Various improvements to the new TokenStream API", Michael Busch, 2009-07-24, first release 2.9.0) added TeeSinkTokenFilter with newSinkTokenStream() built from cloneAttributes() and the restoreState() replay. LUCENE-6973 "Improve TeeSinkTokenFilter" (#8030; Shai Erera, 2016-01-15; branch_5x 1ff4e84f89f, first release 5.5.0; main 073dbdc17e3, first release 6.0.0) rewrote the class and kept the copy. LUCENE-3042 (#4115; branch_3x 7904c536011, first release 3.2.0; trunk 49ab81b316c, first release 4.0.0-alpha; Uwe Schindler, 2011-04-22) fixed a stale per-filter state cache that had hidden the late attribute, which exposed the bug (for the stemmer that cache mattered only in 3.1.0: before it, PorterStemFilter added no KeywordAttribute, which arrived with LUCENE-2198, e9a979f1eb8, first release 3.1.0); swapping only AttributeSource.java flips the result both ways. A narrower variant (the tee's consumer calls tee.addAttribute(...) after the sink exists) fails from 2.9.0.
Every failing release has a passing same-version control that only swaps the creation order (145 runs on 21 releases and main). Versions between the executed points are inferred from unchanged code. The last commits on TeeSinkTokenFilter.java upstream are cosmetic (2026-05-15 final modifiers, 2026-01-15 a javadoc tag); 10.6.0 differs from main only in those. All on OpenJDK 25.0.3, Linux aarch64.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 (unreleased 11.0) | affected | fails, -ea and -da, gradle and standalone; passes with the fix |
| 10.6.0 | affected | fails, -ea and -da (release jars, the one-token test) |
| 10.0.0, 10.5.2, 9.0.0, 9.12.3 | affected | fail (10.5.2 also with verifiers' own tests, 9.12.3 with two) |
| 5.0.0, 5.5.5, 6.0.0, 7.7.3, 8.11.4 | affected | fail (before and after the LUCENE-6973 rewrite) |
| 3.2.0, 3.6.2, 4.0.0, 4.8.1, 4.9.0, 4.10.4 | affected | fail; 3.2.0 is the first release after LUCENE-3042 |
| 2.9.0, 2.9.4, 3.0.0, 3.0.3, 3.1.0 | masked | the stemmer trigger passes: in 2.9.x and 3.0.x PorterStemFilter adds no KeywordAttribute yet (LUCENE-2198, 3.1.0), and in 3.1.0 the stale state cache hides it; the same cache hides the StopFilter and custom-attribute triggers on all five; the narrower tee.addAttribute variant fails |
| 2.4.1 | n/a | no TeeSinkTokenFilter; its predecessor TeeTokenFilter/SinkTokenizer replays correctly |
An independent reproducer, executing cross-model reviews (OpenAI GPT-5.6) and a devil's advocate each reproduced it with their own tests and passing controls, and an adjudication re-ran one of them. The fix passes all of their tests and the analysis-common test suite.
Checks and verdicts397 words
Every check ran on the stock jars and voted real. The strongest dissent is the works-as-designed argument (rated moderate), answered in "Why it is a bug". Caveats carried from the adjudication: the failure is loud with easy workarounds, and maintainers may prefer a javadoc fix.
| Check | Verdict | What it found |
|---|---|---|
| Finder (finder) | candidate | Exhaustive model check: the late-attribute scenario fails on 4,092 of 4,092 inputs, 0 with the fix. Its 2-test JUnit fails 2 of 2 on main (-ea, -da), 10.5.2 and 9.12.3. |
| Cross-model review before the candidate, intended lens (OpenAI GPT-5.6) | real, high; intended argument moderate | Executed mode: reproduced it and found the fix passes its tests and the 3 upstream tests. |
| Independent reproducer | real | Own 6-test JUnit outside the package: stemmer, DelimitedPayloadTokenFilter and indexing fail, 3 controls pass, on main (-ea, -da), 10.5.2 and 9.12.3. |
| Cross-model review, refute lens (OpenAI GPT-5.6) | real, high; intended argument moderate | Executed mode: own test with KStemFilter, TypeAsSynonymFilter and a custom flags filter fails 3 of 5 (2 controls pass) on main, 10.5.2 and 9.12.3; 0 of 5 with the fix. |
| Intended-behaviour devil's advocate | real, medium-high | Built and rejected the works-as-designed case; found the split MemoryIndex(storePayloads=true) path. |
| Adjudication | confirmed, high | Re-ran the independent reproduction's test with a new seed: 3 of 6 fail with -ea and -da, controls pass; 6 of 6 pass with the fix. |
| Registry re-runs and credibility audit | keep | Fresh-seed re-runs of the finder's and the independent reproduction's tests fail as claimed; an independent KStemFilter test fails; the fix passes. |
| This page's runs | reproduced; fix validated | Gradle on a scratch worktree of 645d4fe14a20: the repro fails with assertions on and off and passes with the fix, as do TestTeeSinkTokenFilter and the 1,910 tests of analysis-common; the standalone runner reproduces it on main (assertions on and off) and on the 10.6.0 release jars. |
| Fact checks of two earlier versions | reproduced; wording corrected | Two rounds, each an independent re-run (gradle on a fresh worktree, the standalone runner on main and 10.6.0, the fix and the whole analysis-common test task; in round 1 also its own probe of every trigger, both workarounds and the MemoryIndex variants) and a cross-model fact check (OpenAI GPT-5.6), confirmed the bug, the repro, the fix and the security call; their wording, scope and attribution corrections are carried into this page. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 508 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,468 words
- Registry title
- TeeSinkTokenFilter: a sink created with newSinkTokenStream() before a filter that adds an attribute is put on the tee (the order of the class javadoc example), for example any stemmer adding KeywordAttribute, throws IllegalArgumentException from restoreState on its first token, so IndexWriter.addDocument rejects the document
- Area
- analysis / TeeSinkTokenFilter (sinks: newSinkTokenStream() attribute snapshot, SinkTokenStream replay through AttributeSource.restoreState)
- Priority
- Low, rank 612: The factory-less, little-used TeeSinkTokenFilter loudly rejects every document (without aborting the writer) when used in the order its javadoc shows, and reordering one line works around it, so it heads the loud opt-in crash rows just above LFV-329.
- Impact class
- crash
- Impact note
- Hits applications that build TeeSinkTokenFilter chains in Java (the class has no factory, so analysis configuration cannot reach it, and a code search finds no use in Solr, Elasticsearch or OpenSearch) and put a filter that adds an attribute on the tee after creating the sinks, the order the class javadoc shows: the typical stemmed-plus-unstemmed split with PorterStemFilter, KStemFilter, SnowballFilter or another keyword-aware filter (KeywordAttribute), DelimitedPayloadTokenFilter (PayloadAttribute) or TypeAsSynonymFilter (FlagsAttribute), or a tee consumed by MemoryIndex with storePayloads=true; then every document fails at the sink's field with IllegalArgumentException, whatever its text, deterministic with -ea and -da and at any size; the exception is non-aborting (the document is rejected, the writer stays open, CheckIndex is clean), and creating the sinks after the tee's whole chain is built, or adding the missing attributes to each sink, avoids it.
- Summary
- You create a sink with tee.newSinkTokenStream() and then wrap the tee in a further filter, as the class javadoc example does (sinks first, then final1 = new LowerCaseFilter(source1)), and expect the sink to replay every token the tee consumed, as newSinkTokenStream() promises. If that later filter adds an attribute the tee did not have yet, for example PorterStemFilter adding KeywordAttribute for a stemmed field next to an unstemmed sink field, the sink lacks it, because its attributes are a cloneAttributes() snapshot taken when it was created, and its restoreState throws IllegalArgumentException ('State contains AttributeImpl of type ...KeywordAttributeImpl that is not in in this AttributeSource') on the first token, so addDocument rejects the document. With LowerCaseFilter, the javadoc's own filter, nothing is added and the example works; creating the sink after the stemmer also works.
- Introduced
- 31a5f0edcc474f739e8392eac7261b9483fc60bf (LUCENE-1693 'AttributeSource/TokenStream API improvements', GitHub #2767, svn r797665, by Michael Busch; SVN/JIRA era, no PR): it added TeeSinkTokenFilter, whose newSinkTokenStream() builds the sink from this.cloneAttributes() and whose sinks replay the tee's captured states with restoreState() [read: git log -S and blame in the full-history clone; LUCENE-6973 (073dbdc17e3, 6.0.0) rewrote the class and kept this.cloneAttributes(); executed 5.5.5 and 6.0.0 both fail]. The reported trigger became reachable with LUCENE-3042 'AttributeSource can have an invalid computed state' (GitHub #4115; branch_3x 7904c536011, svn r1096078, first release 3.2.0; trunk 49ab81b316c, svn r1096073, first release 4.0.0), a correct fix of a stale per-instance state cache that had hidden the late attribute from the tee's captured states [exec: 7904c536011 is the only AttributeSource.java change between the 3.1 and 3.2 tags, and swapping only that file makes 3.1.0 fail 3 of 3 and 3.2.0 pass 3 of 3] (2009-07-24 (root cause, 31a5f0edcc4); 2011-04-22 (exposed by LUCENE-3042, 7904c536011 / 49ab81b316c))
- First affected version
- 3.2.0 [exec] for the reported trigger (an attribute-adding filter put on the tee after the sink was created); 2.9.0, 2.9.4, 3.0.0, 3.0.3 and 3.1.0 pass that trigger [exec] only because the pre-LUCENE-3042 stale state cache masked it. The narrower variant in which the tee's own consumer calls tee.addAttribute(...) after the sink was created fails from 2.9.0 [exec], the first release with TeeSinkTokenFilter (2.4.1 has no such class; its predecessor TeeTokenFilter/SinkTokenizer replays correctly [exec])
- Affected versions
- Every release from 3.2.0 to 10.6.0 (10.6.0 [exec] on its release jars, -ea and -da, 2026-10-30) and main a9779ef3c193; never fixed. [exec] follow-up version-specific main() probes, each failing case with a same-version control that differs only in creation order and passes (145 runs over 21 releases and main): the stemmer trigger fails on 3.2.0, 3.6.2, 4.0.0, 4.8.1, 4.9.0, 4.10.4, 5.0.0, 5.5.5, 6.0.0, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main; the DelimitedPayloadTokenFilter trigger fails at the executed points from 4.0.0 to main (3.x not run); the StopFilter trigger fails 3.2.0 to 4.8.1 and passes from 4.9.0, where the default PackedTokenAttributeImpl (LUCENE-5640) already provides the position increment [read]; the finder's JUnit fails 2 of 2 on main (-ea and -da), 10.5.2 and 9.12.3; the independent reproduction's JUnit fails 3 of 6 on main (-ea and -da), 10.5.2 and 9.12.3; the cross-model reviewer's own test fails 3 of 5 on main a9779ef3c193 (-ea and -da), ea57360912ed, 10.5.2 and 9.12.3; the intended-behaviour check's probe fails on main and 10.5.2. [read] versions between executed points are inferred from the unchanged cloneAttributes()/captureState()/restoreState() code; upstream main a95c754ee003 and branch_10x have no behavioural change to TeeSinkTokenFilter.java or AttributeSource.java since LUCENE-6973 (2016) and no open PR touches them, so the unreleased 10.x and 11.0 lines are affected (not executed). JDK 25.0.3, aarch64; pure Java logic.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (searched 2026-10-27, plus the finder's run of 2026-10-26, read-only; the prior-report record, verdict new): three hunt prior-report tool runs (175 queries over apache/lucene GitHub issues, PRs and commits, Solr, Elasticsearch, OpenSearch and Lucene.NET, the dev@, java-user@, issues@, commits@ and Solr lists, the LUCENE, SOLR and LUCENENET JIRA archive and the web), all 11 apache/lucene issues that mention TeeSinkTokenFilter read (no PR mentions it), exact-phrase searches for the error message (0 hits in apache/lucene, the JIRA archive and the downstream repositories), the changed files of all 409 open apache/lucene PRs (none touches TeeSinkTokenFilter.java or AttributeSource.java), the 15 list threads that mention TeeSinkTokenFilter, and Stack Overflow. Not fixed upstream: neither file has a behavioural change on main a95c754ee003 or branch_10x since LUCENE-6973 (2016). Nearest items, none a report of this bug: LUCENE-1693 / #2767 (design intent 'the sink tokenstream has exactly the same attributes as the TeeSinkTokenFilter'; a sink restoreState IllegalArgumentException with a different trigger, a custom impl installed below the tee, fixed in 2009 by switching to cloneAttributes()), the LUCENE-2211 commit 3f722b66a55 / #3287 (TestTeeSinkTokenFilter.testGeneral adds its check attribute to the sinks by hand: a test-side workaround, never explained), the 2009 dev@ thread 'attribute thoughts' (general restoreState design), LUCENE-6973 / #8030 (rewrite that kept the snapshot), LUCENE-3042 / #4115 (a different, fixed late-attribute bug whose fix exposed this one), SOLR-8460 (the analogous bug in Solr's ListBasedTokenStream, fixed by adding the source's impls: precedent for the fix), and LUCENE-7382 plus outside reports of the same message (attribute-factory mismatches). Gaps: keyword search only; private security reports are not visible; 'not found' is the best available evidence, not proof.
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the one-test repro with gradle in a scratch worktree, stock and with the recommended fix, plusTestTeeSinkTokenFilterand the whole analysis-common test task (the worktree was removed after the runs); a standalone runner on main (assertions on and off) and on the 10.6.0 release jars. Earlier: the finder's and verifiers' own tests on maina9779ef3c193(no cited source file differs from645d4fe14a20), 10.5.2 and 9.12.3, a third verifier's probe on main and 10.5.2, an adjudication's re-run, an independent fact check's probe on645d4fe14a20, and history probes on 21 releases. JDK OpenJDK 25.0.3, Linux aarch64.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/sinks/TeeSinkTokenFilter.java :28-58 (class javadoc and example: sinks created before final1 = new LowerCaseFilter(source1); NOTE on consumption order only), :67-70 (newSinkTokenStream javadoc 'receives all tokens consumed by this stream'; new SinkTokenStream(this.cloneAttributes(), cachedStates)), :83-96 (tee incrementToken/end captureState), :115-131 (SinkTokenStream incrementToken/end restoreState)lucene/core/src/java/org/apache/lucene/util/AttributeSource.java :305-331 (restoreState: target must contain a corresponding instance; throws IllegalArgumentException 'State contains AttributeImpl of type ... that is not in in this AttributeSource' at :326)
- The finding in 30 seconds
Lucene main 645d4fe14a20: lucene/analysis/common/src/java/org/apache/lucene/analysis/sinks/TeeSinkTokenFilter.java:28-30, :36-40, :67-70, :85, :95, :121, :129; lucene/core/src/java/org/apache/lucene/util/AttributeSource.java:78-85, :300-303, :305-311, :322-327, :424-431; lucene/core/src/java/org/apache/lucene/analysis/TokenFilter.java:34-37; lucene/core/src/java/org/apache/lucene/analysis/TokenStream.java:64-66; lucene/analysis/common/src/java/org/apache/lucene/analysis/en/PorterStemFilter.java:54; lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:1987, :1989-1994; lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThread.java:303-306; lucene/memory/src/java/org/apache/lucene/index/memory/MemoryIndex.java:1006-1008Lucene main 645d4fe14a20: grep -rl 'KeywordAttribute.class' lucene/analysis/common/src/java (49 files)
- Who is affected
Lucene main 645d4fe14a20: lucene/analysis.tests/src/test/org/apache/lucene/analysis/tests/TestAllAnalyzersHaveFactories.java:55-58
- Why it looks unintended
Lucene main 645d4fe14a20: lucene/analysis/common/src/java/org/apache/lucene/analysis/sinks/TeeSinkTokenFilter.java:28-30, :36-40, :53-57, :67; lucene/core/src/java/org/apache/lucene/analysis/TokenStream.java:64-66; lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ConcatenatingTokenStream.java:36, :68-83; lucene/core/src/java/org/apache/lucene/util/AttributeSource.java:305-311, :424-430; lucene/analysis/common/src/test/org/apache/lucene/analysis/sinks/TestTeeSinkTokenFilter.java:118-128; lucene/test-framework/src/java/org/apache/lucene/tests/analysis/BaseTokenStreamTestCase.java:162-163
- Suggested fix
Lucene main 645d4fe14a20: lucene/core/src/java/org/apache/lucene/util/AttributeSource.java:188-202; lucene/memory/src/java/org/apache/lucene/index/memory/MemoryIndex.java:1006-1008; lucene/analysis/common/src/java/org/apache/lucene/analysis/sinks/TeeSinkTokenFilter.java:36-38, :68 (the javadoc's declared sink type)
- TestTeeSinkAttributeAddedAfterSink.java (JUnit for Lucene's build):
repro/LFV-650/src/org/apache/lucene/analysis/sinks/TestTeeSinkAttributeAddedAfterSink.java(34 lines)
Made in parallel with this page: a summary card (PNG).
assets/LFV-650/bug.png(508 KB)