TeeSinkTokenFilter lets one analysis feed several fields: the tee saves every token's state, and a sink replays those states later, where more filters can be added.
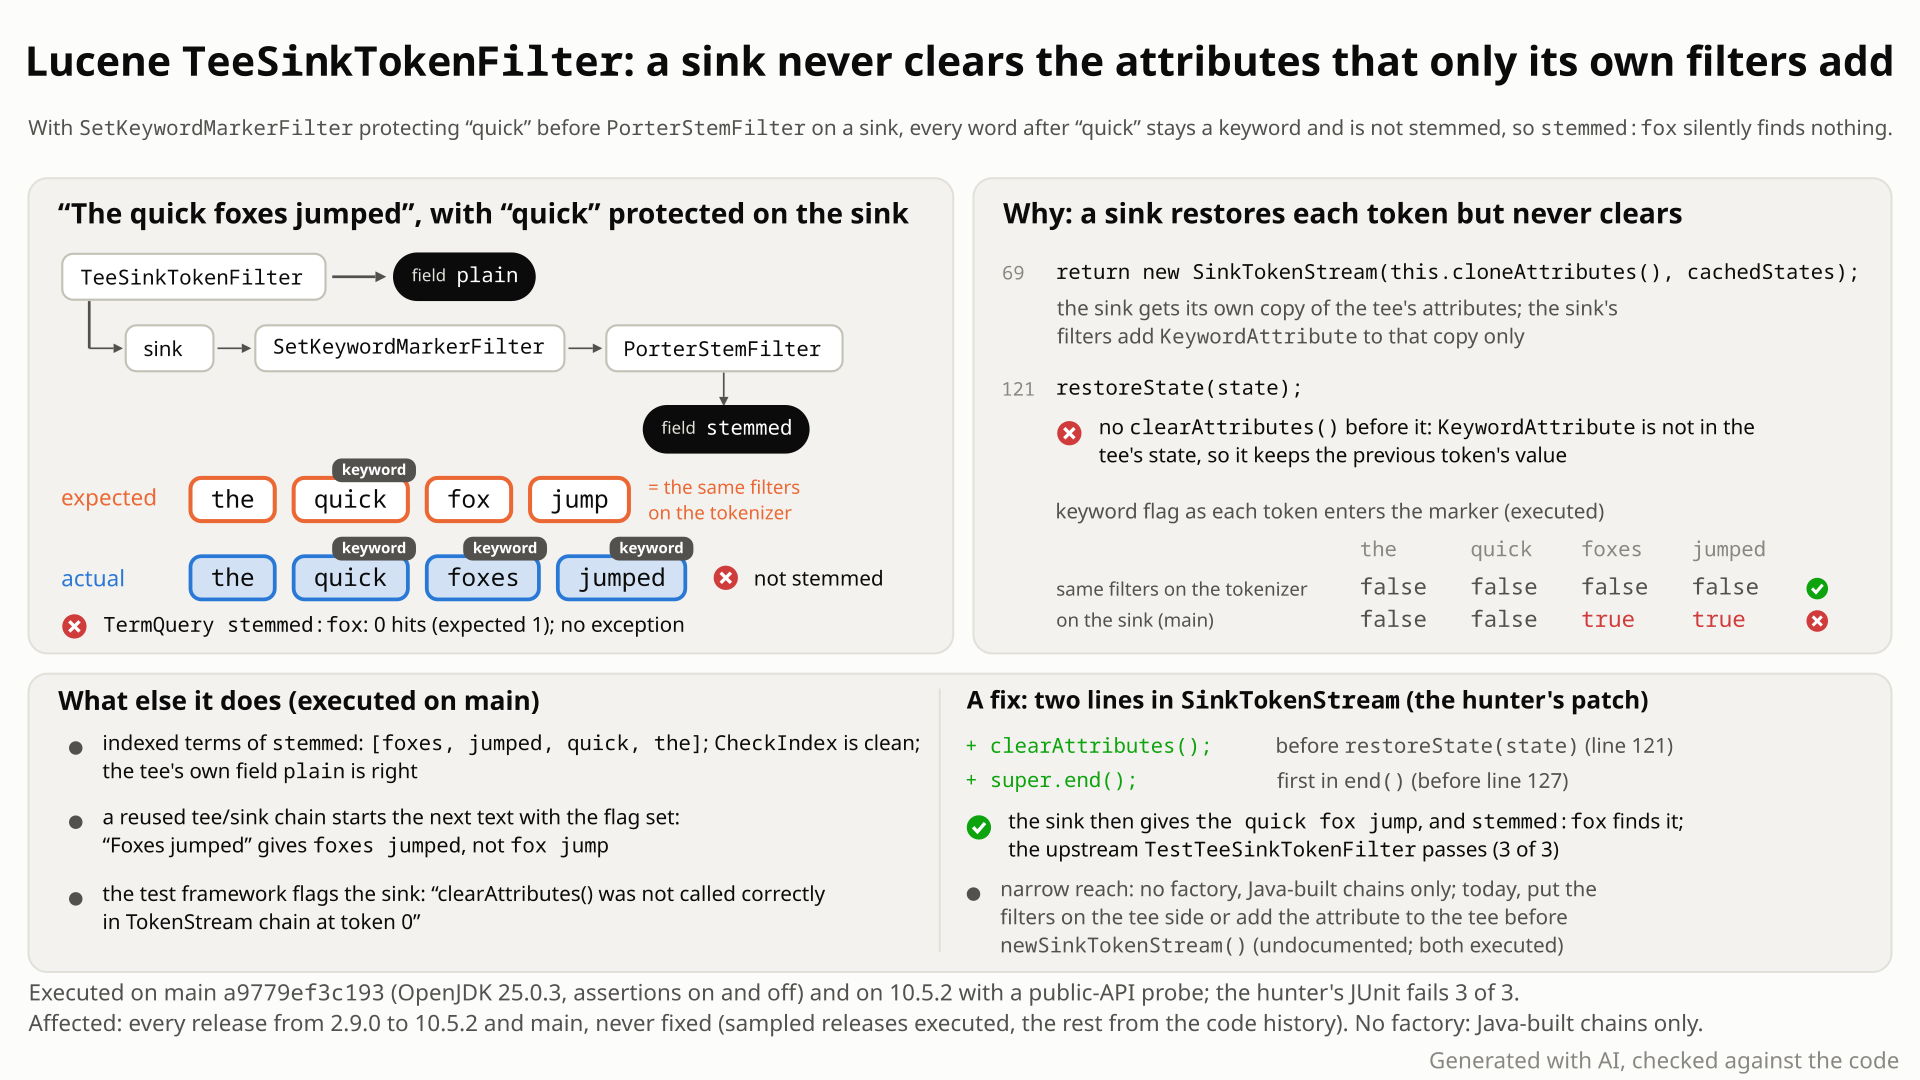
quick is never reset, so foxes and jumped skip the stemmer; then the effect, the fix and a summary card. Select the still to open it at full size. Generated with AI, checked against the code.- Tee
The quick foxes jumped(whitespace tokenizer, lowercased) into a fieldplain, and wrap a sink of the tee inSetKeywordMarkerFilter(protectquick) andPorterStemFilterfor a fieldstemmed. - You expect
stemmedto get[the, quick, fox, jump], which the same two filters give directly on the tokenizer. - The sink replays each token from the tee's saved state. The keyword flag exists only on the sink side, so no saved state holds it and nothing resets it: once
quickswitches it on,foxesandjumpedstill carry it and the stemmer skips them. - You get
[the, quick, foxes, jumped], andstemmed:foxfinds 0 documents instead of 1. No error: theplainfield andCheckIndexare fine.
Applications that build a TeeSinkTokenFilter in their own Java code (it has no factory; no use found in Solr, Elasticsearch or OpenSearch) and wrap a sink in a filter that flags some tokens: a keyword marker or StemmerOverrideFilter before a stemmer, PatternTypingFilter with DropIfFlaggedFilter, or NumericPayloadTokenFilter. Each value is then indexed wrong after its first flagged token.
Mechanism, terms and numbers508 words
TeeSinkTokenFilter lets one analysis chain feed several fields: the tee saves each token's state and a sink replays it later, where more filters can be added. A sink has its own copy of the tee's attributes, and SinkTokenStream.incrementToken() only calls restoreState(), never clearAttributes(). So an attribute that only the sink's own filters add is never reset between tokens. With SetKeywordMarkerFilter protecting quick before PorterStemFilter on a sink, The quick foxes jumped is indexed as [the, quick, foxes, jumped] instead of [the, quick, fox, jump], and stemmed:fox finds nothing. Silent, deterministic, in every release from 2.9.0 to 10.6.0 (10.6.0 by reading) and main; the fix adds clearAttributes() to SinkTokenStream.incrementToken(), plus a separate super.end() hardening in end().
- Attributes. A token stream describes the current token through attribute objects: the term text, offsets, position, type, and optional flags such as
KeywordAttribute("do not stem this word"). All filters of one chain share one set of attribute objects. - Clearing. The source at the start of a chain resets every attribute before each token ("Tokenizers must call
clearAttributes()in incrementToken()", a rule LUCENE-1801 applied to every token source). Filters that only ever switch a flag on rely on that reset. - Tee and sink.
TeeSinkTokenFiltersaves each token's state withcaptureState(); each sink fromnewSinkTokenStream()replays the saved states withrestoreState(). The class javadoc wraps sinks in further filters (new EntityDetect(sink1)).
newSinkTokenStream()gives each sink its own attribute source, a copy of the tee's attributes (new SinkTokenStream(this.cloneAttributes(), cachedStates),TeeSinkTokenFilter.java:69).SetKeywordMarkerFilterandPorterStemFilterwrapped around the sink addKeywordAttributeto that copy. The tee never has it, so none of the tee's saved states (:85) contains it.SinkTokenStream.incrementToken()only callsrestoreState(state)(:121).restoreState"does not affect attributes of the targetStream that are not contained in this state"; to reset them "the caller should first callTokenStream#clearAttributes()on the targetStream" (AttributeSource.java:312-316). The sink never does.KeywordMarkerFilteronly ever sets the flag to true (KeywordMarkerFilter.java:45-46), andPorterStemFilterskips keyword tokens (PorterStemFilter.java:64).- So:
the(flag false) is stemmed;quickis protected and the flag turns on;foxesandjumpedget their terms restored but keep the flag, and are not stemmed.
On the tee side the same filters are fine: they share the tokenizer's attributes, which the tokenizer clears for every token. Attributes the tee already has when the sink is created (term, type, offsets, position increment and length) are in every saved state and are restored correctly.
The quick foxes jumped: the sink chain gives [the, quick, foxes, jumped], the same chain on the tokenizer [the, quick, fox, jump]. Indexed with the tee as plain and the sink as stemmed (the documented order), stemmed:fox and stemmed:jump find 0 documents and plain:foxes finds 1. Adding KeywordAttribute to the tee before creating the sink gives the right terms. The test framework's own check reports "clearAttributes() was not called correctly in TokenStream chain at token 0" on a plain sink.
Exposure and likelihood285 words
- Who is exposed. Only chains built in Java:
TeeSinkTokenFilterhas no analysis factory (Lucene's factory test lists it as a "crazy component" without one), soCustomAnalyzerand factory-based schemas cannot reach it. A read-only code search found no use in Elasticsearch, OpenSearch or Solr (default branches only; private applications are unknown). - What triggers it. A sink-side filter that sets an attribute on some tokens only and relies on the chain's source to reset it. Executed:
SetKeywordMarkerFilter,PatternKeywordMarkerFilterorStemmerOverrideFilterbeforePorterStemFilter,EnglishMinimalStemFilter([cat, exempt, dogs]instead of[cat, exempt, dog]) orKStemFilter;StemmerOverrideFilter {dogs->canine, mice->mouse}also blocks its own second override ([canine, running, mice, walking]instead of[canine, run, mouse, walk]);PatternTypingFilter(digit tokens) +DropIfFlaggedFilterkeeps only[order]oforder 42 shipped to aliceinstead of[order, shipped, to, alice];NumericPayloadTokenFiltergives later tokens the number's payload. - Scale. In every value with a flagged token, the flagged token itself is right, but the attribute stays stale on all later tokens, and the output is wrong wherever a later filter depends on its default (here every later word the stemmer would change); deterministic, any size, assertions on or off. If one tee/sink chain is reused for several documents, the flag carries into the next document (
foxes jumpedindexed as[foxes, jumped]). - Effect. Wrong terms or payloads in the sink field only; queries on it miss documents (or over-match on payloads). The tee's field and stored values are right,
CheckIndexis clean, and documents stay wrong until reindexed. - Not affected. The same filters on the tee side; attributes added to the tee before the sink is created; sink-side filters that set their attribute on every token.
The test shows that a TeeSinkTokenFilter sink never clears attributes that only its own chain adds, so SetKeywordMarkerFilter's keyword flag for "quick" sticks to every later token and PorterStemFilter stops stemming.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.sinks;

import java.io.StringReader;
import java.util.ArrayList;
import java.util.List;
import org.apache.lucene.analysis.CharArraySet;
import org.apache.lucene.analysis.TokenStream;
import org.apache.lucene.analysis.Tokenizer;
import org.apache.lucene.analysis.core.WhitespaceTokenizer;
import org.apache.lucene.analysis.en.PorterStemFilter;
import org.apache.lucene.analysis.miscellaneous.SetKeywordMarkerFilter;
import org.apache.lucene.analysis.tokenattributes.CharTermAttribute;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestTeeSinkSinkOnlyAttribute extends LuceneTestCase {

  public void testKeywordMarkerOnSink() throws Exception {
    Tokenizer tokenizer = new WhitespaceTokenizer();
    tokenizer.setReader(new StringReader("quick foxes"));
    TeeSinkTokenFilter tee = new TeeSinkTokenFilter(tokenizer);
    TokenStream sink =
        new PorterStemFilter(
            new SetKeywordMarkerFilter(
                tee.newSinkTokenStream(), new CharArraySet(List.of("quick"), false)));
    tee.reset();
    tee.consumeAllTokens();
    tee.end();
    tee.close();

    CharTermAttribute term = sink.addAttribute(CharTermAttribute.class);
    List<String> terms = new ArrayList<>();
    sink.reset();
    while (sink.incrementToken()) {
      terms.add(term.toString());
    }
    sink.end();
    sink.close();
    // expected: only "quick" is protected, "foxes" is stemmed; actual: [quick, foxes]
    assertEquals(List.of("quick", "fox"), terms);
  }
}
# in a copy of this finding's repro folder (repro/LFV-651/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.sinks.TestTeeSinkSinkOnlyAttribute
- Expected vs actual
- Expected: the sink chain on "quick foxes" gives [quick, fox], as the same chain on the tokenizer does. Actual (-ea and -da): [quick, foxes].
More files, environment, full output36 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<[quick, fox]> but was:<[quick, foxes]>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:120)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.analysis.sinks.TestTeeSinkSinkOnlyAttribute.testKeywordMarkerOnSink(TestTeeSinkSinkOnlyAttribute.java:55)restoreStateleaves attributes the state lacks unchanged and tells the caller, here the sink, to callclearAttributes()first.- The javadoc and the 5.5.0 CHANGES entry (LUCENE-6973) say to wrap sinks in "any other TokenFilter"; nothing limits their attributes.
- Lucene's test-framework check fails on a plain sink; the upstream test avoids it by also adding its check attribute to the tee.
The full argument245 words
- Contract.
AttributeSource.restoreState(AttributeSource.java:312-316): attributes not in the state "remain unchanged"; to reset them "the caller should first callTokenStream#clearAttributes()on the targetStream". The package docs: "Tokenizers must callAttributeSource#clearAttributes()in incrementToken()" (package-info.java:404-405). LUCENE-1801 (#2876, 2009) applied that rule to "All Tokenizers/TokenStreams that are source of tokens"; a reviewer there noted thatrestoreState()alone is not enough.SinkTokenStreamalready existed and was not changed. - Documented use. Class javadoc: sinks "will further do additional token filtering" (
TeeSinkTokenFilter.java:49-51, examplenew EntityDetect(sink1)at:41). CHANGES 5.5.0 (API Changes), LUCENE-6973: "If you wish to filter the sinks, you can wrap them with any other TokenFilter (e.g. a FilteringTokenFilter)."PorterStemFilteralone addsKeywordAttributeto the sink. - Tests.
TestTeeSinkTokenFilter.testGeneraladdsCheckClearAttributesAttributeto the tee and to the sink (:123-124), so the check value rides in the saved states. No upstream test puts an attribute on the sink only. With it on the sink only the check fails; that is supporting evidence, and the stock filters' wrong terms are the stronger evidence. end().TokenStream.end(): "If you override this method, always callsuper.end()" (TokenStream.java:156);SinkTokenStream.end()does not, so a sink-only attribute keeps its last-token value afterend(). This is a separate, smaller contract gap: the wrong terms come fromincrementToken()alone.- History. The restore-only
incrementToken()came with the class (LUCENE-1693, 2009) and survived the LUCENE-6973 rewrite (2016, first released in 5.5.0); no commit ever addedclearAttributes()to the sink.
The devil's-advocate check235 words
Strongest case (rated weak by the intended-lens reviewer from another model family, the independent reproducer and the devil's advocate; moderate by the refute-lens reviewer and by the cross-model fact check of this doc): the package rule names only Tokenizers; restoreState says a reset "might be desirable"; CachingTokenFilter also restores without clearing and its end() also skips super.end(); the 2009 design wanted a sink with "exactly the same attributes as the TeeSinkTokenFilter"; a committer wrote on dev@ in 2014 that "clearAttributes() is not needed before restoreState()"; the Lucene.NET port suppressed its warning about the missing base.End() as intended.
Why it fails: CachingTokenFilter shares its chain's attributes, so filters after it are in its states (the same keyword chain over a CachingTokenFilter replay is correct), while a sink has a separate copy by construction. The javadoc puts the reset on the caller; the package rule's wording names Tokenizers, and LUCENE-1801 applied it to every TokenStream that is a source of tokens, which a sink is. The "same attributes" remark was about creating the sink; the same javadoc wraps sinks in filters. The 2014 remark was about a filter whose state covers the whole shared chain. The Lucene.NET rationale ("calling base.End() would clear the attributes that RestoreState then sets") does not hold when super.end() runs before restoreState. Verdict: a defect. Expect the reply "add the attribute to the tee first": it works, but nothing documents it.
Recommended Clear before restoring, and call super.end() (validated)
In SinkTokenStream, call clearAttributes() before restoreState(state) (this alone fixes the wrong terms) and, as separate end-of-stream hardening, super.end() first in end() (+3 lines). The new test then passes 5 of 5; the lucene/analysis/common module (1,914 tests, 18 skipped) has 0 failures, assertions on and off. Tee attributes are unchanged: the restored state overwrites them.
       AttributeSource.State state = it.next();
+      // the sink is the source of its own chain: reset the attributes the state does not hold
+      clearAttributes();
       restoreState(state);
       return true;
     }

     @Override
     public void end() throws IOException {
+      super.end(); // endAttributes(), also for attributes that only this sink's chain added
       State finalState = cachedStates.getFinalState();
All options and trade-offs3 options · 562 words
Option A was built and validated with gradle in a scratch worktree; option B was run through the standalone runner; option C was not run.
Two calls in SinkTokenStream (TeeSinkTokenFilter.java:121, :126): each sink token starts from cleared attributes, as on any tokenizer-rooted chain, and end() runs endAttributes() before restoring the tee's final state. The first call fixes the bug. The second is a separate end() contract fix: without it a sink-only attribute keeps its last-token value after end() (executed: a reviewer's testSinkEndResetsSinkOnlyAttribute fails on stock and passes with the fix); no in-tree consumer impact of that part was shown.
       AttributeSource.State state = it.next();
+      // the sink is the source of its own chain: reset the attributes the state does not hold
+      clearAttributes();
       restoreState(state);
       return true;
     }

     @Override
     public void end() throws IOException {
+      super.end(); // endAttributes(), also for attributes that only this sink's chain added
       State finalState = cachedStates.getFinalState();
Trade-offs
- Tee attributes do not change: every one is in every saved state and is restored right after the clear (assuming, as
TokenStreamrequires, that the tee's attributes are all added before tokens are captured). Only sink-only attributes change, to their per-token default. - Cost: one
clearAttributes()per sink token; not benchmarked. - A sink-side filter that relied on its attribute persisting across tokens would change; none is known.
- Existing indexes keep their wrong terms until reindexed.
- In a path the model treats as a caller error (
consumeAllTokens()without the tee'send(), so no final state exists), the sink's end-of-stream values are wrong with or without the fix (3,579 of 4,092 model inputs on stock, 4,089 with it). - The same lines are in every 9.x and 10.x release, and the +3-line diff applies cleanly (
git apply --check) to the 10.5.2 and 9.12.3 sources; only main was built with gradle.
What the checks validated
- Scratch worktree at
a9779ef3c193, gradle, JDK 25: the new test fails 3 of 5 on stock and passes 5 of 5 with the fix;TestTeeSinkTokenFilter(3 upstream tests) and the new test pass (8 of 8). - The whole
lucene/analysis/commonmodule: 340 suites, 1914 tests, 0 failures (18 skipped), with assertions on and off;:lucene:analysis:common:check -x testpasses (google-java-format, ecjLint, forbiddenApis). - Standalone runner with the fix shadowed: the new test 5/5 (on and off), the independent reproducer's 5 tests 5/5, the follow-up's 4-test effect probe 4/4. The finder's exhaustive model (same logic) drops from 4,032 of 4,092 mismatching inputs to 0, and the documented-use scenarios stay at 0.
Fixes every wrong term and payload seen: the independent reproducer's 5 tests pass, 4 of 5 of the new test, and the follow-up's 4-test effect probe (payloads, dropped tokens, reused chain, deny rule) 4 of 4.
Trade-offs
Sink-only attributes keep their last-token value after end(), and the framework's end() check still fails on such a sink.
What the checks validated
Standalone runner on main: the new test's only failure is the framework's end() check, "super.end()/clearAttributes() was not called correctly in end()".
Say in the class javadoc that sink-side filters' attributes are never reset and must be added to the tee before newSinkTokenStream().
Trade-offs
No code change, so every existing chain stays wrong; stock filters such as PorterStemFilter add KeywordAttribute without the user asking.
Downstream, a content rule on the sink field can miss documents: with quick protected, the quick secrets kept secrets unstemmed, so a MUST_NOT stemmed:secret clause left it visible.
Bounded-exhaustive translation validation of TeeSinkTokenFilter against a reference model. While modelling a sibling bug, the finder read the sink code and added a scenario with a sink-side filter that flags one token: the real class mismatched on 4,032 of 4,092 inputs, every input with two or more tokens.
The method in full173 words
Method: bounded-exhaustive translation validation (semi-formal tier). A reference model of the tee and its sinks was compared with the stock jar on every input up to a small scope: 0 to 4 tokens, position increments 1 or 2, offset gaps 0 or 1, final position increment 0 or 1, final offset slack 0 or 1, and 1 to 3 sinks.
- The hypothesis came from reading
SinkTokenStreamwhile modelling the sibling bug (an attribute added to the tee after a sink exists makesrestoreStatethrow). - New scenario F wraps each sink in a filter that adds
KeywordAttributeand sets it on one token only, relying on the source's clear, and compares the result with the same filter run on the input itself. Stock main: 4,032 of 4,092 inputs mismatch; the documented-use scenarios A, C and D: 0. - The finding was reduced to a public-API JUnit on the stock main jars, then checked by a reviewer from another model family (OpenAI GPT-5.6) in lenses, an independent reproducer, a devil's advocate, an adjudication and an audit.
No prior report found (searched 2026-10-27): GitHub issues, PRs and commits, the changed files of all 409 open PRs, Solr, Elasticsearch, OpenSearch and Lucene.NET, the mailing lists, JIRA and the web. A Lucene.NET PR flagged only the separate end() detail and suppressed it as intended behaviour.
Searches4 searches
Verdict new. The nearest items are contract and history, not reports of this bug. The one outside touch, Lucene.NET PR #1288, is about the separate end() detail only, not the incrementToken() defect or its wrong terms.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene GitHub issues, PRs and commits; Solr, Elasticsearch, OpenSearch, Lucene.NET | 2026-10-27 | 161 queries of a scripted prior-report search in three runs (class, symptom, mechanism) plus the finder's run; 44 logged manual GitHub search calls (36 distinct queries); all 11 issues that mention TeeSinkTokenFilter read or triaged | no report; nearest: LUCENE-1801 #2876 (sources must clear), LUCENE-2211 #3287 (the check; its test mirrors the attribute on the tee), LUCENE-6973 #8030 (rewrite), LUCENE-1693 #2767 and LUCENE-5687 #6749 (design), LUCENE-2901 #3975, LUCENE-6667 #7725 (opposite problem) |
| Open apache/lucene PRs | 2026-10-27 | changed-file lists of all 409 open PRs | only #16911 (branch_10x decommission) touches the file; none touches KeywordMarkerFilter, StemmerOverrideFilter or AttributeSource |
| Lucene.NET | 2026-10-27 | PRs and code | PR #1288 (merged 2026-05) suppressed an analyzer warning that the sink's End() skips base.End(), as intended parity with Java; nothing on incrementToken() or wrong terms |
| Mailing lists, JIRA, web | 2026-10-27 | dev@, java-user@, issues@, commits@; LUCENE, SOLR, LUCENENET JIRA archives; web and Stack Overflow; 8 threads read in full | no report; a 2014 dev@ remark that clearing is not needed before restoreState() concerns a filter whose state covers the whole chain |
Present since TeeSinkTokenFilter was added (LUCENE-1693, 31a5f0edcc4, 2009-07-24), first released in 2.9.0; every release up to 10.6.0 (10.6.0 by reading) and main is affected, and nothing was ever fixed. The stock keyword-marker trigger exists from 3.1.0.
Versions tested6 rows
Introduced by 31a5f0edcc4 (LUCENE-1693, #2767, svn r797665, 2009-07-24, no PR), which added the class with the per-sink cloneAttributes() copy and the restore-only incrementToken(); git blame on main puts restoreState(state) on it. LUCENE-6973 (073dbdc17e3, backported as 1ff4e84f89f, first released in 5.5.0) rewrote the class and kept both. The missing super.end() dates from LUCENE-1448 (c311d5730cb, 2009) and matters only from 4.5.0, when the base end() began to reset attributes. Upstream main a95c754ee003 has a byte-identical file.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's test fails 3 of 5 (gradle and standalone, assertions on and off); passes 5 of 5 with the fix |
| 10.5.2, 9.12.3 | affected | this doc's test fails 3 of 5; the finder's JUnit 3 of 3 |
| 3.1.0 to 10.0.0 (3.1.0, 3.6.2, 4.0.0, 4.2.1, 4.3.0, 4.10.4, 5.0.0, 5.5.5, 6.0.0, 7.7.3, 8.11.4, 9.0.0, 10.0.0) | affected | keyword marker + PorterStemFilter on a sink gives [the, quick, foxes, jumped] |
| 2.9.0, 2.9.4, 3.0.0, 3.0.3 | custom attribute | a sink-side filter's own attribute stays set on later tokens (no stock keyword marker before 3.1.0); control passes |
31a5f0edcc4 (introducing commit) over the 2.9.0 core | introducing | the same failure; 2.9.0 with only clearAttributes() added passes |
| 2.4.1 | not affected | no TeeSinkTokenFilter; the predecessor TeeTokenFilter/SinkTokenizer replays correctly |
Confirmed by a reviewer from another model family (OpenAI GPT-5.6) in lenses, an independent reproducer, a devil's advocate, an adjudication and a credibility audit; each wrote its own test with passing controls, except the adjudication, which re-ran the independent reproducer's test with a new seed; this doc's test and fix were re-run with gradle on main.
Checks and verdicts280 words
Each check except the adjudication wrote and ran its own test on the stock jars (the adjudication re-ran the independent reproduction's with a new seed); the controls (the chain on the tokenizer, a CachingTokenFilter replay, the attribute added to the tee first) pass everywhere.
| Check | Verdict | What it found |
|---|---|---|
| cross-model review, intended lens | real, high; intended argument weak | Own test: sink keyword flags [false, true, true, true] where [false, true, false, false] is expected; also with assertions off and on 10.5.2. |
| cross-model review, refute lens | real, high; intended argument moderate | Own tests (PatternKeywordMarkerFilter + EnglishMinimalStemFilter, a custom attribute, an end() check, six controls), run by the reviewer on ea57360912ed (identical TeeSinkTokenFilter.java); re-run on main a9779ef3c193 and 10.5.2: 3 of 9 fail, 0 with the fix. |
| Independent reproducer | real | Own 5-test JUnit: 4 of 5 fail on main (assertions on and off), 10.5.2 and 9.12.3; the tee-first control passes; a clear-only fix passes 5 of 5. |
| Devil's advocate | real (high for incrementToken(), medium for end()) | Own test with StemmerOverrideFilter mice->mouse + PorterStemFilter fails on main and 10.5.2; four controls pass. |
| adjudication | confirmed, high | Re-ran the independent reproduction's test with a new seed: 4 of 5 fail with assertions on and off, 5 of 5 pass with the fix. |
| credibility audit | keep | Re-ran the finder's JUnit (3 of 3 fail, on and off); own test with PatternKeywordMarkerFilter + KStemFilter fails on main and 10.5.2, passes with the fix. |
| this doc | confirmed; fix validated | New 5-test JUnit fails 3 of 5 on main, 10.5.2 and 9.12.3; the fix passes it, and the module's 1,914 tests have 0 failures (18 skipped). |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 497 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,511 words
- Registry title
- TeeSinkTokenFilter: a sink never clears attributes that only its own filter chain adds (SinkTokenStream.incrementToken() calls restoreState() without clearAttributes()), so a keyword marker or StemmerOverrideFilter before a stemmer on a sink silently leaves every token after the first protected word unstemmed
- Area
- analysis / TeeSinkTokenFilter (SinkTokenStream replay through AttributeSource.restoreState without clearAttributes(): attributes that only the sink's chain adds)
- Priority
- Low, rank 307: Only the rarely used, factory-less TeeSinkTokenFilter with attribute-setting filters on the sink side is affected.
- Impact class
- silent wrong results
- Impact note
- Hits applications whose own Java code builds a TeeSinkTokenFilter (the class has no factory, so analysis configuration cannot reach it, and a code search finds no use in Solr, Elasticsearch or OpenSearch) and wraps a sink in a filter that sets an attribute on some tokens only and relies on the chain's source to clear it: a keyword marker (SetKeywordMarkerFilter, PatternKeywordMarkerFilter) or StemmerOverrideFilter before a stemmer, PatternTypingFilter with DropIfFlaggedFilter, or NumericPayloadTokenFilter; then every value that contains one marked token is indexed wrong in the sink field after that token (later words unstemmed, dropped or given a payload), silently and deterministically with -ea and -da at any size, so queries on that field miss or over-match; the tee's own field, the stored value and CheckIndex are fine, a reused tee/sink chain carries the stale value into the next document, and the same filters on the tee side, or adding the attribute to the tee before newSinkTokenStream() (undocumented), avoid it.
- Summary
- You index one field from a TeeSinkTokenFilter and a second field from one of its sinks, wrapped in a keyword marker and a stemmer (for example SetKeywordMarkerFilter protecting 'quick', then PorterStemFilter), and expect the sink field to get what the same chain gives on the tokenizer: [the, quick, fox, jump] for 'The quick foxes jumped'. Instead it gets [the, quick, foxes, jumped]: the sink replays each token with restoreState() but never calls clearAttributes(), and the KeywordAttribute that only the sink's chain added is not in the tee's captured states, so once 'quick' is marked as a keyword every later token stays marked and is not stemmed. Nothing is thrown; a query for stemmed:fox finds nothing.
- Introduced
- 31a5f0edcc474f739e8392eac7261b9483fc60bf (LUCENE-1693 'AttributeSource/TokenStream API improvements', GitHub #2767, svn r797665, by Michael Busch; SVN/JIRA era, no PR): it added TeeSinkTokenFilter, whose SinkTokenStream gets its own cloneAttributes() copy of the tee's attributes and an incrementToken() that only calls restoreState() [read: git blame -w -M -C in the full-history clone; exec: the introducing commit's own TeeSinkTokenFilter.java compiled over the 2.9.0 core fails, and 2.9.0 with only clearAttributes() added passes]. LUCENE-6973 (073dbdc17e3, backported as 1ff4e84f89f; first released in 5.5.0) rewrote the class and kept the restore-only incrementToken() and end(); the missing super.end() in SinkTokenStream.end() dates from LUCENE-1448 (c311d5730cb, 2009-07-25) [read] (2009-07-24 (31a5f0edcc4))
- First affected version
- 2.9.0 [exec], the first release with TeeSinkTokenFilter (reachable there with a sink-side filter that adds its own attribute; the stock trigger, KeywordMarkerFilter or StemmerOverrideFilter before PorterStemFilter, exists from 3.1.0 [exec]); 2.4.1 has no TeeSinkTokenFilter and its predecessor TeeTokenFilter/SinkTokenizer replays correctly [exec]
- Affected versions
- Every release from 2.9.0 to 10.6.0 (10.6.0 by reading) and main a9779ef3c193; never fixed. [exec] 40 follow-up history runs (seed DEADBEEF): a sink-side filter adding its own attribute set on one token fails on 2.9.0 (-ea and -da), 2.9.4, 3.0.0, 3.0.3, 3.1.0 and 3.6.2, each with a passing control that adds the attribute to the tee first; the stock keyword-marker + PorterStemFilter repro fails on 3.1.0, 3.6.2, 4.0.0, 4.2.1, 4.3.0, 4.10.4, 5.0.0, 5.5.5, 6.0.0, 7.7.3, 8.11.4, 9.0.0, 9.12.3 (-ea and -da), 10.0.0, 10.5.2 (-ea and -da) and main (-ea and -da), and passes on main with the fix; the finder's JUnit fails 3 of 3 on main, 10.5.2 and 9.12.3 (-ea and -da); the independent reproduction's JUnit fails 4 of 5 on main (-ea and -da), 10.5.2 and 9.12.3; the intended-behaviour check's on main (-ea and -da) and 10.5.2; the cross-model reviewers' own tests on ea57360912ed, a9779ef3c193 and 10.5.2. [read] versions between executed points from blame (the restore-only line is unchanged from 31a5f0edcc4 to main); upstream main a95c754ee003 has a byte-identical TeeSinkTokenFilter.java and branch_10x and branch_10_6 match 10.5.2, so 10.6.0 (released 2026-10-29 from branch_10_6) and the unreleased 10.x and 11.0 lines are affected (not executed). The end() half (no super.end()) has an effect only from 4.5.0, when LUCENE-3849 made the base TokenStream.end() reset attributes [read], and was not executed separately. JDK 25.0.3, aarch64; pure Java logic.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check, code reading
- Upstream and prior reports
- none found (searched 2026-10-27, plus the finder's run, read-only; the prior-report record, verdict new): three hunt prior-report tool runs (161 queries: the class side, the symptom side such as a KeywordAttribute that stays set and 'not stemmed', and the mechanism side such as replaying states without clearAttributes() and the test-framework message) over apache/lucene GitHub issues, PRs and commits, Solr, Elasticsearch, OpenSearch and Lucene.NET, the dev@, java-user@, issues@ and commits@ lists, the LUCENE, SOLR and LUCENENET JIRA archive and the web; 44 logged manual GitHub search calls (36 distinct queries) (all 11 apache/lucene issues that mention TeeSinkTokenFilter read or triaged; no PR mentions it), the changed files of all 409 open apache/lucene PRs (only #16911, the branch_10x decommission, touches TeeSinkTokenFilter.java; none touches KeywordMarkerFilter, StemmerOverrideFilter or AttributeSource.java), JIRA queries, 8 dev@/java-user@ threads read in full and 2 Stack Overflow questions. Not fixed upstream: TeeSinkTokenFilter.java on main a95c754ee003 is byte-identical to a9779ef3c193 and no commit ever added clearAttributes() or super.end() to SinkTokenStream. Nearest items, none a report of this bug: LUCENE-1801 / #2876 (2009: every Tokenizer or TokenStream that is a source of tokens must call clearAttributes(); a reviewer noted that restoreState() alone is not enough; SinkTokenStream was not changed), LUCENE-2211 / #3287 (2010: added the test-framework clearAttributes() check; TestTeeSinkTokenFilter puts the check attribute on the tee and the sinks, so the sink-only case was never exercised), LUCENE-6973 / #8030 (2016 rewrite; told users to wrap sinks in any TokenFilter), LUCENE-5687 / #6749 and LUCENE-1693 / #2767 (design discussion recommending filters on sinks), LUCENE-2901 / #3975 (why KeywordMarkerFilter only ever sets the flag), Lucene.NET PR #1288 (merged 2026-05: its analyzer flagged that SinkTokenStream.End() does not call base.End() and the PR suppressed that warning as intended parity with Java; it covers only the secondary end() part of the proposed fix and says nothing about incrementToken() or stale attributes), a 2014 dev@ thread 'BaseTokenStreamTestCase' (a committer: 'clearAttributes() is not needed before restoreState()', said of a TokenFilter inserting tokens, whose state covers the whole shared chain) and LUCENE-6667 / #7725 (the opposite problem in SynonymFilter). Gaps: keyword search only, some web queries throttled, private security reports not visible; 'not found' is the best available evidence, not proof.
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-27) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the release jars 10.5.2 and 9.12.3 (this doc's test) and, in the follow-up's history probes, 2.4.1 (not affected) and 2.9.0 to 10.0.0 (affected). The fix was validated in the scratch worktree: the new test, the 3 upstreamTestTeeSinkTokenFiltertests, the wholelucene/analysis/commonmodule (1,914 tests, 0 failures, 18 skipped) with assertions on and off, and:lucene:analysis:common:check -x test.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/sinks/TeeSinkTokenFilter.java :28-58 (class javadoc: sinks 'will further do additional token filtering', example new EntityDetect(sink1); NOTE on consumption order only), :67-70 (newSinkTokenStream: new SinkTokenStream(this.cloneAttributes(), cachedStates)), :83-96 (tee captureState), :114-123 (SinkTokenStream.incrementToken: restoreState(state) only), :125-131 (end: restoreState(finalState), no super.end())lucene/core/src/java/org/apache/lucene/util/AttributeSource.java :305-317 (restoreState javadoc: attributes of the target not contained in the state remain unchanged; to reset them 'the caller should first call TokenStream#clearAttributes() on the targetStream')lucene/core/src/java/org/apache/lucene/analysis/package-info.java :404-405 ('Tokenizers must call AttributeSource#clearAttributes() in incrementToken()'); lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/KeywordMarkerFilter.java :43-48 and StemmerOverrideFilter.java :72-83 (set KeywordAttribute only to true; StemmerOverrideFilter skips already-keyworded tokens)SECURITY.md lines 28, 46 and 50 (threat model; out-of-scope issues are public bug reports; in-scope reports)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/sinks/TeeSinkTokenFilter.java :35-51 (class javadoc), :68-70, :83-90, :114-131lucene/core/src/java/org/apache/lucene/util/AttributeSource.java :306-318 (restoreState javadoc and method)lucene/core/src/java/org/apache/lucene/analysis/package-info.java :404-405lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/KeywordMarkerFilter.java :43-48lucene/analysis/common/src/java/org/apache/lucene/analysis/en/PorterStemFilter.java :54, :64
- Who is affected
lucene/analysis.tests/src/test/org/apache/lucene/analysis/tests/TestAllAnalyzersHaveFactories.java :55-58
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/util/AttributeSource.java :312-316lucene/core/src/java/org/apache/lucene/analysis/package-info.java :404-405lucene/analysis/common/src/java/org/apache/lucene/analysis/sinks/TeeSinkTokenFilter.java :41, :49-51, :126-131lucene/CHANGES.txt :9693-9695 (LUCENE-6973, in the 5.5.0 section, header :9652)lucene/core/src/java/org/apache/lucene/analysis/TokenStream.java :156, :160-162lucene/core/src/java/org/apache/lucene/analysis/CachingTokenFilter.java :79, :84-88lucene/analysis/common/src/test/org/apache/lucene/analysis/sinks/TestTeeSinkTokenFilter.java :118-128
- TestTeeSinkSinkOnlyAttribute.java (JUnit test):
repro/LFV-651/src/org/apache/lucene/analysis/sinks/TestTeeSinkSinkOnlyAttribute.java(57 lines)
A light, step-by-step picture made in parallel with this doc from an executed probe on main a9779ef3c193 (assertions on and off), 10.5.2 and main with the fix; every code row and value drawn is checked against the source and the probe logs. The PNG is the final summary card.
assets/LFV-651/bug.png(497 KB)