ParallelLeafReader joins indexes that hold different fields of the same documents, so they read as one index. Copying that joined view into a real index, with addIndexes over SlowCodecReaderWrapper or from OneMerge.wrapForMerge, should keep every stored field under its own name.
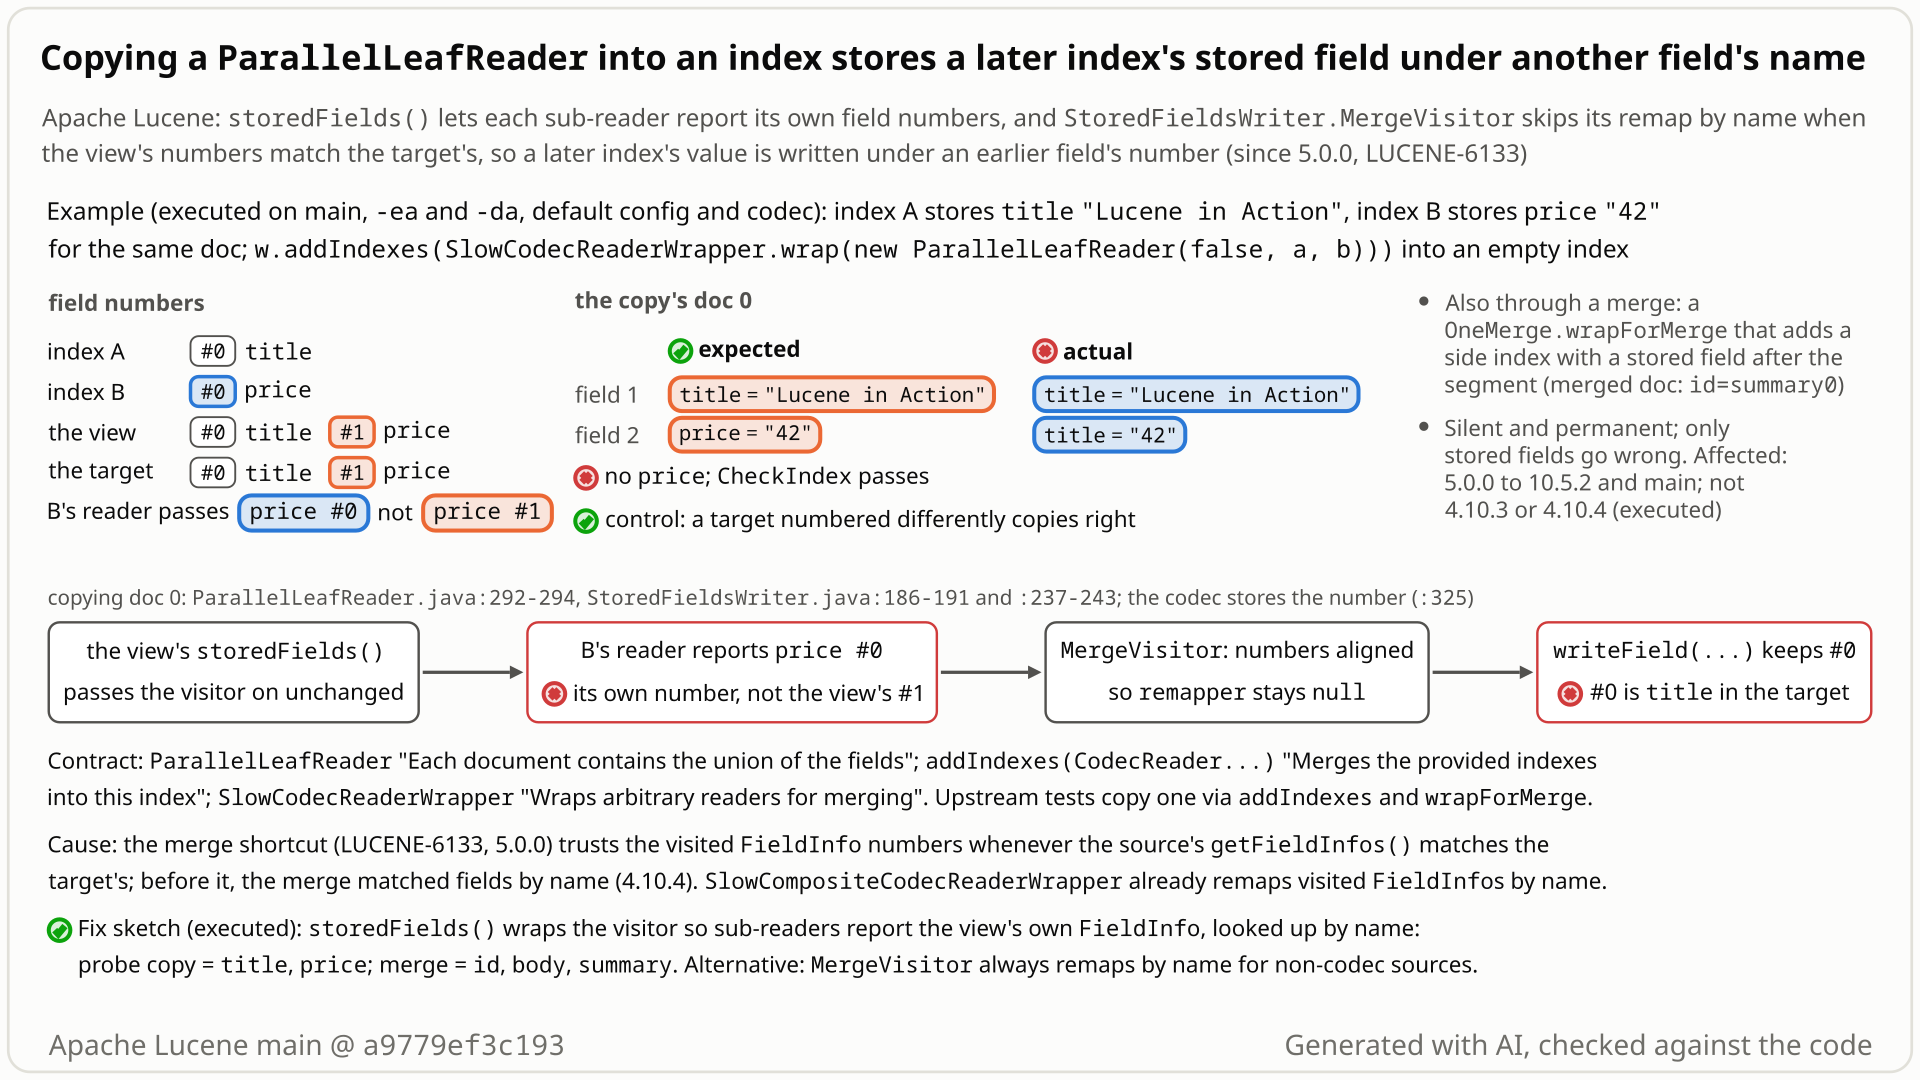
price to 1, but B still reports it as 0 during the copy, and field 0 of the new index is title. Select the still to open it at full size. Generated with AI, checked against the code.- Index A stores
title="Lucene in Action"and index B storesprice="42"for the same document. Each index numbers its own first field 0, sotitleandpriceare both field 0. - Join them with
new ParallelLeafReader(false, a, b). Reading works: the document hastitleandprice, and the joined view renumberspriceto field 1. - Copy the view into an empty index with
addIndexes(SlowCodecReaderWrapper.wrap(parallel)). You expecttitle="Lucene in Action"andprice="42". - You get
title="Lucene in Action"andtitle="42", and noprice. B reports its value as field 0; the merge sees that the view's numbers match the new index, skips its by-name check, and writes field 0:title. - No error, and
CheckIndexpasses; searches still match, because postings, doc values and points copied correctly in every tested case. A merge whosewrapForMergeadds a side index goes wrong the same way.
Applications that copy a ParallelLeafReader over two or more indexes, with addIndexes(SlowCodecReaderWrapper.wrap(...)) or a custom wrapForMerge, when a later index stores fields and the target gives the view's fields the view's numbers (an empty target, for one). Default config and codec. Stored values come back under wrong names; query matching is unaffected.
Mechanism, terms and numbers791 words
ParallelLeafReader joins indexes that hold different fields of the same documents; "Each document contains the union of the fields of all documents with the same document number". Reading through it is correct. Copying it into an index, with IndexWriter.addIndexes(SlowCodecReaderWrapper.wrap(parallelReader)) or from a MergePolicy.OneMerge.wrapForMerge that returns one, writes each stored value of a later reader under the name of whichever target field holds that reader's own field number (an earlier reader's field, or another field of the same reader) whenever the target gives the parallel reader's fields the parallel reader's numbers, for example an empty target. With index A storing title="Lucene in Action" and index B storing price="42", the copy holds title="Lucene in Action" and title="42" and no price, with no exception and a clean CheckIndex. storedFields() lets each sub-reader call the visitor with its own FieldInfo (price is number 0 in B), the parallel reader's getFieldInfos() numbers price 1, and StoredFieldsWriter.MergeVisitor skips its by-name remapping because those numbers match the target's, so it writes number 0, which in the target is title. In every tested case postings, doc values, points, vectors, norms and deletions were copied correctly. The merge shortcut came with LUCENE-6133 (5.0.0, 2014), a speed-up; 4.10.x copies correctly, and every release from 5.0.0 to 10.6.0 (10.6.0 run at its release revision) and main is affected.
- ParallelLeafReader: a
LeafReaderover several indexes with the same documents in the same order but different fields: "Each document contains the union of the fields of all documents with the same document number" (index/ParallelLeafReader.java:38-39). - Field numbers: every index gives each field name a number, in the order it first sees the names, so independently built indexes all start at 0. A
FieldInfocarries a field's name and number; stored fields are written on disk by number. - Copying a reader:
IndexWriter.addIndexes(CodecReader...)"Merges the provided indexes into this index";SlowCodecReaderWrapper.wrapturns anyLeafReaderinto theCodecReaderit needs. A merge can also wrap each segment withOneMerge.wrapForMerge, "in order to add/remove fields or documents".
- The view renumbers.
ParallelLeafReaderbuilds its ownFieldInfos, first reader wins (ParallelLeafReader.java:154-159); a field keeps its number only if it is still free, else it gets the lowest free one (FieldInfos.java:425-433). B'sprice, number 0, becomes 1. The javadoc says the numbers "will likely not correspond to the actual field numbers in the underlying readers" (:242-244). - Stored fields are visited with the sub-reader's own numbers.
storedFields().document(docID, visitor)hands the caller's visitor unchanged to each sub-reader (:291-296), andSlowCodecReaderWrapperpasses it straight through (SlowCodecReaderWrapper.java:332-335). B's reader reportspriceas number 0. - The merge trusts numbers that look aligned.
MergeVisitorturns its by-name remapping on only if a number in the source'sgetFieldInfos()names a different field in the target (codecs/StoredFieldsWriter.java:182-192, "if field numbers are aligned, we can save hash lookups"). For an empty target the merged numbering adopts the view's (title 0, price 1), so the check passes andremap()returns the visitedFieldInfoas is (:237-243). - The codec writes the foreign number. The default stored-fields writer copies a non-codec source field by field through this visitor (
Lucene90CompressingStoredFieldsWriter.java:678-685,:637-641) and records number 0, which in the new index istitle.
If the target gives even one of the view's fields a different number, the constructor check fails, remapping by name is on and the copy is correct. If only the first reader stores fields, no stored value carries a foreign number; if the earlier readers have no fields at all, a later reader keeps its own numbers and nothing is renamed (read from FieldInfos.java:425-427, not run).
| step | field numbers and values |
|---|---|
| index A | title#0 |
| index B | price#0 |
the view's getFieldInfos() | title#0, price#1 |
| what a visitor on the view receives | title#0="Lucene in Action", price#0="42" |
empty target after addIndexes | title#0, price#1: aligned, by-name remapping off |
| the copy | title="Lucene in Action", title="42", no price; CheckIndex clean |
control: target already numbered title#1, price#2 | not aligned, remapped by name: title, price correct |
merge path: segment id#0, body#1 + side index summary#0 | view id#0, body#1, summary#2; after forceMerge(1) doc 0 is id=id0, body=body0, id=summary0 |
With several stored fields in the later reader, each value lands on the name that holds its own number in the target: A color="red", B weight=7, shape="circle" copies as {color=[red, 7], weight=[circle]}. Values move down by as many names as the earlier readers have fields, so shape lands on B's own weight; with two fields in A they move down by two.
Exposure and likelihood440 words
- Who. Applications that copy a
ParallelLeafReader, or the leaves of aParallelCompositeReader(same result in one probe), built over two or more indexes:addIndexes(SlowCodecReaderWrapper.wrap(...))to turn a parallel index into a single one, or aOneMerge.wrapForMergethat folds a side index into segments as they merge (the pattern of upstream'sTestDemoParallelLeafReader). A rarely used API combination; everything else is default (IndexWriterConfig, codec, merge scheduler). - Trigger. Two conditions. (1) A later sub-reader has a stored field whose own number differs from its number in the view; that is always so in the usual setup, where every index numbers its fields from 0 and an earlier reader has at least one field. (2) The target gives each of the view's fields the view's number: an empty target, or one that already holds the same fields under the same numbers. No special data and no scale; in the usual setup every copied document with a stored value from a later reader is hit.
- Effect. Silent and permanent. In the copy each stored value of a later reader carries the name of whichever field holds that reader's own number in the target, and the real field is missing: with one field in B that is an earlier reader's field (
pricebecomestitle); with several, values move down by as many names as the earlier readers have fields, so some land on other fields of the same reader. Postings, doc values, points, vectors, norms and deletions were copied correctly in every tested case, so queries match the same documents; what breaks is the stored data the application loads: displayed values, highlighting, and any later re-indexing from stored fields, which carries the wrong names on. The stored-only cases areCheckIndex-clean, so nothing reports it; if the source indexes are discarded after the copy, the original values are lost. - Not hit when the target's numbering differs (the merge then remaps by name) or when only the first reader stores fields. The
wrapForMergepath needs the stored-field side index after the segment reader; upstream's demo puts its side index first and takes the safe path. - How often among small cases. A bounded-exhaustive run over 128,625 configurations found stored-field mismatches in 21,993 empty-target copies and none where the target's numbering differs; with fix A, none (8,040-configuration sample).
- Downstream, by reading only. Elasticsearch and OpenSearch use
ParallelLeafReaderon a read path only. Solr main (not in a release) has awrapForMergethat returnsSlowCodecReaderWrapper.wrap(new ParallelLeafReader(...)), but its side segments hold only doc values and its padding wrapper exposes no stored fields, so it is not hit as written. Nothing downstream was run.
The test shows that IndexWriter#addIndexes(SlowCodecReaderWrapper.wrap(new ParallelLeafReader(a, b))) into a fresh index stores b's stored field under a's field name (a: title="Lucene in Action", b: price="42").
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.StoredField;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestParallelLeafReaderAddIndexesStoredFields extends LuceneTestCase {

  private static void indexOneDoc(Directory dir, String field, String value) throws Exception {
    try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
      Document doc = new Document();
      doc.add(new StoredField(field, value));
      w.addDocument(doc);
    }
  }

  public void testAddIndexesOfParallelReader() throws Exception {
    Directory dirA = new ByteBuffersDirectory();
    Directory dirB = new ByteBuffersDirectory();
    Directory target = new ByteBuffersDirectory();
    indexOneDoc(dirA, "title", "Lucene in Action");
    indexOneDoc(dirB, "price", "42");
    try (DirectoryReader a = DirectoryReader.open(dirA);
        DirectoryReader b = DirectoryReader.open(dirB);
        ParallelLeafReader parallel =
            new ParallelLeafReader(false, getOnlyLeafReader(a), getOnlyLeafReader(b));
        IndexWriter w = new IndexWriter(target, new IndexWriterConfig())) {
      w.addIndexes(SlowCodecReaderWrapper.wrap(parallel));
    }
    try (DirectoryReader copy = DirectoryReader.open(target)) {
      Document doc = copy.storedFields().document(0);
      // expected price=42 in the copy; actual: the value is stored as a second "title" and price is null
      assertEquals("copied document: " + doc, "42", doc.get("price"));
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-652/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.index.TestParallelLeafReaderAddIndexesStoredFields
- Expected vs actual
- Expected the copy to have price=42; actual
Document<stored<title:Lucene in Action> stored<title:42>> expected:<42> but was:<null>, with-eaand-da.
More files, environment, full output39 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: copied document: Document<stored<title:Lucene in Action> stored<title:42>> expected:<42> but was:<null>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:120)
org.apache.lucene.index.TestParallelLeafReaderAddIndexesStoredFields.testAddIndexesOfParallelReader(TestParallelLeafReaderAddIndexesStoredFields.java:51)- Lucene's own composite merge wrapper maps each visited field to its own
FieldInfoby name;ParallelLeafReaderrenumbers but does not remap. addIndexes"Merges the provided indexes into this index", and the view itself returnsprice; only the copy loses it.- Up to 4.10.4 the merge matched fields by name and the copy is correct; the 5.0 change was a speed-up.
The full argument354 words
- Contracts.
ParallelLeafReader: "Each document contains the union of the fields of all documents with the same document number" (ParallelLeafReader.java:38-39).IndexWriter.addIndexes(CodecReader...): "Merges the provided indexes into this index" (IndexWriter.java:3255).SlowCodecReaderWrapper: "Wraps arbitrary readers for merging" (:38).OneMerge.wrapForMerge: "Wrap a reader prior to merging in order to add/remove fields or documents" (MergePolicy.java:302). TheaddIndexespath uses no experimental or internal API; the merge path does:MergePolicy,MergePolicy.OneMerge(which declareswrapForMerge) and the repro'sFilterMergePolicyare@lucene.experimental(MergePolicy.java:69,:189;FilterMergePolicy.java:27). - Lucene's own wrappers keep the invariant.
SlowCompositeCodecReaderWrapper(#12622, 2023): "Remap FieldInfos to make sure consumers only see field infos from the composite reader, not from individual leaves" (SlowCompositeCodecReaderWrapper.java:118-122, used in every visitor callback at:162-205). The test framework'sMismatchedLeafReader, which renumbers fields on purpose, also renumbers theFieldInfoits visitor passes on (MismatchedLeafReader.java:110-135); its issue, LUCENE-6135 (#7197), says merge shortcuts must be off when numbers do not line up, or values get mixed up across fields. - History. Before LUCENE-6133 the merge loaded each document and wrote it through
fieldInfos.fieldInfo(field.name()), by name; the removed code even had a TODO to "renumber the field number on the fly". LUCENE-6133 (5.0.0) was a speed-up, "Improve default StoredFieldsWriter.merge() to be more efficient" (lucene/CHANGES.txt:11324), and its issue (#7195) discusses only CPU cost. 4.10.4 copies correctly; builds of the commit fail and of its parent pass. - Copying parallel readers is a tested path.
TestParallelReaderEmptyIndex: "Adding this reader to a new index should not throw any exception", thenaddIndexes(SlowCodecReaderWrapper.wrap(pr))(:34-36,:129-134);TestDemoParallelLeafReaderreturnsSlowCodecReaderWrapper.wrap(ParallelLeafReader)fromwrapForMerge(:644-650); LUCENE-1918 (2.9.0) fixed exceptions when a ParallelReader was "passed to IndexWriter.addIndexes(IndexReader[])" (lucene/CHANGES.txt:19473-19478); in a 2009 java-user answer a committer (@mikemccand) suggested "use addIndexes(IndexReader[]), passing in your ParallelReader". None of these tests has a stored field in a later reader with an aligned target. - Precedent. LUCENE-3575 (#4649, 2011), "Field names can be wrong for stored fields / term vectors after merging", the same symptom in older merge code, was fixed as a bug.
The devil's-advocate check214 words
The intended-behaviour verifier built the strongest case for "not a bug": field numbers are internal; getFieldInfos() warns its numbers "will likely not correspond" to the sub-readers'; StoredFieldVisitor is @lucene.experimental (StoredFieldVisitor.java:35); the class javadoc names searching as the use case (ParallelLeafReader.java:42-44) and warns that indexes not "created and modified the same way" give "undefined behavior" (:46-49); and wrapForMerge is experimental merge-policy API where the application supplies the reader, so maintainers could ask that reader to present consistent FieldInfos.
Why it fails for addIndexes: the NOTE came with LUCENE-4055 (2012, about codec metadata), two and a half years before the merge shortcut, and describes a numbering difference, not renamed persisted data. The addIndexes user calls only public, non-experimental API and never sees a FieldInfo. The "same way" warning's only example concerns documents and their order and it states no field-number requirement, while the same javadoc expects different fields per index, which always number from 0. Upstream tests and CHANGES copy parallel readers. The cross-model reviews and the verifier rated the case weak; a cross-model fact check of this doc rates it moderate for wrapForMerge, the experimental path. Verdict: a defect. Copying is supported by tests, CHANGES and a list answer rather than by the class javadoc.
Recommended A: ParallelLeafReader.storedFields() presents its own FieldInfo
Make ParallelLeafReader.storedFields() hand each visitor the view's own FieldInfo, looked up by name, as Lucene's composite merge wrapper already does (+60/-1, one file). Both repros pass, and so do the 191 upstream tests in the 18 closest test classes. It does not cover the expert constructor's stored-only readers.
public void document(int docID, StoredFieldVisitor visitor) throws IOException {
  // Sub-readers report their own FieldInfo (their own field numbers); present this
  // reader's FieldInfo instead, so consumers that trust FieldInfo.number (e.g. the
  // stored fields merge) see numbers consistent with getFieldInfos().
  StoredFieldVisitor remapping = new RemappingStoredFieldVisitor(visitor, fieldInfos);
  for (StoredFields reader : fields) {
    reader.document(docID, remapping);
  }
}
// RemappingStoredFieldVisitor.remap(fi):
//   FieldInfo own = fieldInfos.fieldInfo(fi.name); return own == null ? fi : own;
All options and trade-offs4 options · 737 words
Two fixes were applied in a scratch worktree at a9779ef3c193 and run through gradle (seed DEADBEEF, assertions on): A, at the class that breaks the invariant, and B, a defensive check in the merge. Either one fixes both repros. Neither makes the expert-constructor aside copy correctly.
A: ParallelLeafReader.storedFields() presents its own FieldInfo (validated by the checks) (recommended)
Wrap the caller's visitor so that needsField and the seven value callbacks receive the parallel reader's FieldInfo for that field name, falling back to the sub-reader's when the name is unknown. The same pattern as SlowCompositeCodecReaderWrapper. Patch: optionA-parallelleafreader-remap-visitor.diff, the finder's sketch, +60/-1 in ParallelLeafReader.java.
public void document(int docID, StoredFieldVisitor visitor) throws IOException {
  // Sub-readers report their own FieldInfo (their own field numbers); present this
  // reader's FieldInfo instead, so consumers that trust FieldInfo.number (e.g. the
  // stored fields merge) see numbers consistent with getFieldInfos().
  StoredFieldVisitor remapping = new RemappingStoredFieldVisitor(visitor, fieldInfos);
  for (StoredFields reader : fields) {
    reader.document(docID, remapping);
  }
}
// RemappingStoredFieldVisitor.remap(fi):
//   FieldInfo own = fieldInfos.fieldInfo(fi.name); return own == null ? fi : own;
Trade-offs
- Two hash lookups by name (
FieldInfos.fieldInfo(String)) per loaded stored field (one inneedsField, one in the value callback; one for a skipped field) and one wrapper-visitor allocation perdocument()call, on every read through aParallelLeafReader, at search time too; it could be skipped for sub-readers whose numbering already matches. No benchmark was run. - Search-time visitors now see numbers consistent with
getFieldInfos(), arguably a fix too. - It protects
ParallelLeafReaderonly, not other wrapping readers.
What the checks validated
- Stock: the finder's test fails 2 of 2, the independent test 2 of 3 (its control passes), the expert test 1 of 1.
- With A: the finder's test 2/2 and the independent test 3/3 pass; the expert test still fails with the same rename.
- Closest suites with A:
TestParallel*(4 upstream classes and the 2 new ones),TestDemoParallelLeafReader,TestAddIndexes,TestFieldsReader,TestFilterCodecReader,TestFilterLeafReader,TestStoredFieldsConsumer,TestSortingStoredFieldsConsumer,TestStoredFieldsMergeReadAdvice,TestLucene90StoredFieldsFormat*andcodecs.lucene90.compressing.*: 20 classes, 196 tests, 8 skipped, 0 failures. - Earlier: the adjudication's re-run passes 3/3 with it; a cross-model reviewer ran 28 related upstream tests with it (all pass); the exhaustive harness shows 0 stored-field mismatches with it (8,040-configuration sample).
When the constructor found the numbering aligned, remap() checks that the visited number names the same field in the merged FieldInfos, and otherwise looks the field up by name. Patch: optionB-mergevisitor-check-number.diff, +9/-1 in StoredFieldsWriter.java.
// in MergeVisitor.remap(), after the existing remapper branch:
FieldInfo merged = mergeFieldInfos.fieldInfo(field.number);
if (merged != null && merged.name.equals(field.name)) {
  return field;
}
return mergeFieldInfos.fieldInfo(field.name);
Trade-offs
- Protects every merge that copies stored fields through
StoredFieldsWriter.MergeVisitor(the default merge and the Lucene90VISITORstrategy) against any wrapping reader that hands it foreignFieldInfo, at the cost of one array lookup and one string comparison per stored field on that path only; the codec's bulk and per-document copy paths are untouched. No benchmark was run. - A stored-fields format that overrides
mergewithoutMergeVisitoris not covered, and a name the target does not know still yieldsnull(theNullPointerExceptionof the expert aside). - Search-time visitors of a
ParallelLeafReaderstill see sub-reader numbers.
What the checks validated
- With B (A reverted): the finder's test 2/2 and the independent test 3/3 pass.
- The expert aside now fails with
NullPointerException: Cannot read field "number" because "info" is nullin the merge thread (Lucene90CompressingStoredFieldsWriter.writeField): B turns that silent rename into an exception, it does not make it copy. - The same closest core suites plus
TestSimpleTextStoredFieldsFormat(merges through the defaultStoredFieldsWriter.merge): 21 classes, 215 tests, 11 skipped, 0 failures.
A fixes the reader that breaks the invariant; B guards the merge against any other reader that does the same.
Trade-offs
Two changes to review. Each was validated alone through gradle and the closest suites; together they were run once, in this doc's fact check, through the JUnit runner with both patched files shadowed: the finder's and the independent repros pass 5 of 5 (not run through gradle or the suites).
Add their fields to the parallel FieldInfos, or reject copying such a reader.
Trade-offs
A design question for upstream: what that copy should contain is not documented. Not run.
Applications that copy a ParallelLeafReader with stored fields should check stored-field names in the copy; Solr main uses the same wrapForMerge pattern without stored fields, so it is not hit (code reading only).
Bounded-exhaustive metamorphic testing: copies of a ParallelLeafReader were compared with one reference index built from the class javadoc's rules, over 128,625 small configurations. The suspicion came first, while writing an executable model of the javadoc; the run then found stored-field mismatches in 21,993 empty-target copies and none where the target was numbered differently.
The method in full324 words
Method: bounded-exhaustive metamorphic translation validation (a hunt unit, 2026-10-27). No model checker, solver or prover was involved.
- The relation. A
ParallelLeafReaderover readers A and B, and itsaddIndexescopies into an empty target, a reverse-numbered target, an aligned target and through the expert constructor, must equal a reference single index built from the javadoc's union and first-owner rules, compared per live document: live docs,FieldInfos, postings, norms, doc values, points, vectors, stored fields and term vectors. - The space. 3 fields; in each of the 2 readers a field is absent or one of {stored, text with term vectors, numeric doc values, 1D int point, 2D float vector}, not absent in both, so 35 combinations per field; 35^3 x 3 deletion modes = 128,625 configurations, 3 documents per reader, 686,000 checks. Run on the stock jars of
ea57360912ed, whose stored-field code on this path is identical toa9779ef3c193(the only differences in the classes involved, inSlowCodecReaderWrapperand the stored-fields reader, are vector-hint and merge-stream code); local samples ona9779ef3c193agree. - The result. Stored-field mismatches in 21,993 empty-target copies, 21,993 aligned-target copies and 7,331 expert-constructor copies; 0 in reverse-numbered targets; 0 with the fix sketch (8,040-configuration sample). The only other mismatch kind was term vectors, a separate registered bug on the same path. Live docs, postings, norms, numeric doc values, 1D points and float vectors never differed; other doc-values types, byte vectors, multi-dimensional points, payloads and fields that are both stored and indexed were not in the model.
- Order of events. The hypothesis came from reading code while writing the model (the stored-fields visitor is passed through while
getFieldInfos()renumbers); a probe confirmed it; the exhaustive run measured it. The finder (an AI tool) then reduced it to a public-API JUnit, ran the release bracket and wrote the fix sketch. - Then cross-model reviews, independent verifiers, an adjudication, a history bisect, a prior-report search, a security screen and an audit (see Independent checks).
No prior report found (2026-10-27): 163 tool queries over Lucene issues, PRs, commits, JIRA, the mailing lists and downstream trackers, 23 manual GitHub searches, the changed files of all 409 open PRs, and 9 web queries. Nearest: LUCENE-3575 (same symptom in older code, fixed 2011) and #13812 (same class of bug, for doc values and points).
Searches4 searches
None of the searched items describes ParallelLeafReader handing sub-reader FieldInfo numbers to stored-field visitors, or the merge's aligned-numbers shortcut renaming stored values copied from such a reader. Word-based searches show what was found, not that no report exists; closed PR diffs and private lists cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene) | 2026-10-27 | three runs of the hunt's prior-report tool (76 issue/PR and 9 commit queries among its 163) and 23 manual searches, including all of GitHub; 38 issues and PRs read | no report; nearest #4649 (LUCENE-3575, fixed 2011), #7197 (LUCENE-6135, the invariant), #13812, #13809, #13805 (2024, doc values and points), #7195 (LUCENE-6133, the introducing change), #9093 (LUCENE-8045, dvGen), #1684 (LUCENE-606, Won't Fix) |
| Open PRs | 2026-10-27 | the changed files of all 409 open apache/lucene PRs; the diffs of 5 related PRs (#16847, #13342, #14512, #15683, #16690) | none changes ParallelLeafReader.storedFields(), the FieldInfo the visitor receives or the merge's alignment check |
| Mailing lists and JIRA archive | 2026-10-27 | 60 queries over dev@, java-user@, issues@ and commits@, 12 JIRA-archive queries; 10 threads read | no report; a 2009 java-user answer recommends copying a parallel reader with addIndexes |
| Downstream and web | 2026-10-27 | 6 queries on Elasticsearch, OpenSearch and Solr, a code search for ParallelLeafReader in those repositories, 9 web queries | no report; a downstream fork's issue merges through this path with a doc-values-only side index, and Solr main's DocAlignedMerge carries no stored fields: neither can hit it |
Introduced in 5.0.0 by LUCENE-6133 (2014-12-29), a stored-fields merge speed-up that skips the by-name lookup when field numbers look aligned; both commits bisected. Executed: 4.10.3 and 4.10.4 correct; the 14 releases run from 5.0.0 to 10.5.2, and main, wrong; tag containment covers the rest of that range. Not fixed upstream.
Versions tested7 rows
Introduced by LUCENE-6133 "improve default stored fields merge algorithm" (#7195, by @rmuir, 2014-12-29; a JIRA patch committed through SVN): trunk d249f8bc3378 and the same-day branch_5x backport 52b13f1946b5. It replaced the by-name stored-fields merge with MergeVisitor and its aligned-numbers shortcut. The reader side (renumbering in getFieldInfos(), the visitor passed through) dates from ParallelAtomicReader (LUCENE-3736, 2012) and was harmless while the merge matched by name; the only later edit to the shortcut lines is the behaviour-preserving #12116 (2023).
All 15 5.x release tags contain the backport and all 83 tags from 6.0.0 to 10.5.2 contain the trunk commit, so every release from 5.0.0 to 10.5.2 is affected. Entry points: addIndexes(CodecReader...) with SlowCodecReaderWrapper since 5.0.0 (LUCENE-6165), OneMerge.wrapForMerge since 6.2.0 (LUCENE-6766). Releases before 9.12.3 and the 4.10.x results were run by the finder and the history pass; this doc's fact check re-ran 4.10.4, 5.0.0 and 7.7.3 with the same results. Not fixed upstream: no later commit to the three files on main at search time, and no open PR changes the code.
| Version or commit | Verdict | Result |
|---|---|---|
| 4.10.3, 4.10.4 | not affected | copy correct (ParallelAtomicReader copied with addIndexes(IndexReader...)) |
branch_5x 52b13f1946b vs parent b1dbc30b1d5 | bisect | the commit copies title=Lucene in Action, title=42; its parent copies title, price |
trunk d249f8bc337 vs parent 410099b6fbd | bisect | the same: the commit renames, its parent copies correctly |
| 5.0.0, 5.1.0, 5.5.5, 6.0.0, 6.6.6, 7.0.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.4.2, 9.12.3 | affected | plain main() repro: the copy holds title twice and no price |
| 9.12.3, 10.0.0, 10.5.2 | affected | JUnit: 2 of 2 fail (addIndexes and wrapForMerge) |
main a9779ef3c193 | affected | JUnit: 2 of 2 fail with assertions on and off; 40 of 40 over 20 master seeds and 5 codecs |
| main + fix A, main + fix B | not affected | both repros pass; the expert aside still renames (A) or throws (B) |
Cross-model reviews (OpenAI GPT-5.6, running code), an independent reproducer, a devil's advocate, an adjudication and an audit all said real and re-ran it with their own tests or seeds; the strongest "intended" case was rated weak. This doc's tests and both fixes ran through gradle.
Checks and verdicts456 words
All checks ran on main a9779ef3c193 unless noted; the cross-model reviews ran on ea57360912ed, whose stored-field code on this path is identical, and the intended-lens verifier re-ran its test on a9779ef3c193.
| Check | Verdict | What it found |
|---|---|---|
| Finder (a hunt unit) | candidate | Exhaustive run: stored-field mismatches in 21,993 of 128,625 empty-target copies, 0 where the numbering differs, 0 with the fix sketch. JUnit fails 2/2 with -ea and -da, 40/40 over 20 iterations of one master seed (codec Asserting(Lucene104)), and on 10.5.2, 10.0.0 and 9.12.3. |
| Cross-model review, refute lens (OpenAI GPT-5.6, ran code) | real, high | Its own test (other field names, a shifted-numbering control) fails with -ea and -da, the control passes; with the fix 7 upstream tests pass. Rated the intended argument weak and flagged the expert-constructor gap. |
| Independent reproducer | real | Own JUnit fails 2 of 3 on main (-ea, -da), 10.5.2 and 9.12.3, control passes, CheckIndex clean; a probe shows the visitor gets numbers 0 and 1 while getFieldInfos() says 1 and 2; 3/3 pass with the fix. |
| Cross-model review, intended lens (OpenAI GPT-5.6, ran code) | real, high | Intended argument weak; own test fails with -ea, -da, the SimpleText codec and on 10.5.2, control passes; with the fix 28 related upstream tests pass; re-run on a9779ef3c193 fails. |
| Intended-behaviour devil's advocate | real (high for addIndexes, medium for wrapForMerge, low for the expert aside) | Traced the getFieldInfos() NOTE to 2012, two and a half years before the shortcut, and found that the in-tree composite merge wrapper remaps by name for this invariant; re-ran the repro on main and 10.5.2. |
| Adjudication | confirmed, high; data corruption | Re-ran the independent reproduction's test with a new seed: 2 of 3 fail with -ea and -da, control passes; 3/3 pass with the fix. |
| History follow-up and audit | bisected; keep | Builds of both introducing commits fail and of their parents pass; 15 releases run. The audit re-ran the finder's test on main with new seeds (2 of 2 fail, -ea and -da). |
| This doc's fix validation | both fixes pass the repros and the closest suites | Gradle in a scratch worktree: stock 5 of 6 fail; fix A 196 tests in 20 classes pass; fix B 215 tests in 21 classes pass; the expert aside stays broken under both (rename with A, NullPointerException with B). |
| Fact checks of this doc (independent, and cross-model with OpenAI GPT-5.6) | real; text corrections applied | Re-ran both repros (-ea, -da), the paste-ready gradle command, fix A, fix B and A+B together, 20 master seeds (40 of 40, 5 codecs), 4.10.4, 5.0.0, 7.7.3, 9.12.3 and 10.5.2; found three wording errors (seed/codec count, the experimental merge-policy API, where misplaced values land), corrected here. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 531 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,453 words
- Registry title
- Copying a ParallelLeafReader into an index (IndexWriter.addIndexes over SlowCodecReaderWrapper, or a merge whose OneMerge.wrapForMerge returns one) silently stores a later sub-reader's stored fields under another field's name: ParallelLeafReader.storedFields() lets each sub-reader visit with its own FieldInfo numbers while getFieldInfos() renumbers the fields, and StoredFieldsWriter.MergeVisitor skips its remap-by-name step when the numbers look aligned
- Area
- core / index (ParallelLeafReader stored fields x StoredFieldsWriter.MergeVisitor, on addIndexes and wrapForMerge copies)
- Priority
- Medium, rank 116: Silent, permanent stored-field corruption that CheckIndex misses, present in every release since 5.0, but it only happens when a ParallelLeafReader is copied, which is rare.
- Impact class
- data corruption
- Impact note
- Hits applications that copy a ParallelLeafReader (or the leaves of a ParallelCompositeReader) built over two or more lockstep indexes into an index, with IndexWriter.addIndexes(SlowCodecReaderWrapper.wrap(...)) or from a custom OneMerge.wrapForMerge, when a later sub-reader has stored fields and the target numbers its fields the way the parallel reader does (for example a fresh, empty target); default IndexWriterConfig and codec, any size, with -ea and -da; the later reader's stored values are persisted under an earlier field's name (or the field drops out of the stored document), silently and permanently, CheckIndex passes, and postings, doc values, points, vectors, norms and live docs are copied correctly; a target whose numbering differs takes the remap-by-name path and gets a correct copy.
- Summary
- You build two indexes in lockstep, as ParallelLeafReader requires (index A stores title='Lucene in Action', index B stores price='42'), wrap them in a ParallelLeafReader, which itself returns both fields correctly, and copy it into a new index with IndexWriter.addIndexes(SlowCodecReaderWrapper.wrap(reader)), expecting the copy to hold title and price. Instead the copy holds title='Lucene in Action' and title='42' and no price field, with no error and a clean CheckIndex: storedFields() lets B report price with B's own field number 0, the parallel reader's getFieldInfos() numbers price 1, and because the target's merged numbers equal the parallel reader's, the stored-fields merge skips its remap-by-name step and writes the value under number 0, which is title. A merge whose OneMerge.wrapForMerge adds a parallel index with stored fields behind each segment goes wrong the same way (a 'summary' value stored as a second 'id').
- Introduced
- d249f8bc3378d7a349a78fd53ae6e86c695475a5 (LUCENE-6133 'improve default stored fields merge algorithm', migrated as GitHub issue #7195, svn r1648327, by Robert Muir; SVN/JIRA era, no PR; a performance change) on trunk, and its same-day branch_5x backport 52b13f1946b582d5ff7edc718e38f3198260058b (svn r1648332), which the released 5.x builds contain: it replaced the by-name stored-fields merge (DocumentStoredFieldVisitor plus fieldInfos.fieldInfo(field.name())) with StoredFieldsWriter.MergeVisitor and its 'if field numbers are aligned, we can save hash lookups' shortcut [exec: lucene-core built from the commit and from its parent on both lines, the repro fails on d249f8bc337 and 52b13f1946b and passes on the parents 410099b6fbd and b1dbc30b1d5; read: git blame of StoredFieldsWriter.java:182-192 on main and git log -S]. The reader side (FieldInfos.Builder renumbering in getFieldInfos(), the visitor passed unchanged to each sub-reader) dates from ParallelAtomicReader (LUCENE-3736, 2012) and was harmless while the merge matched fields by name; the only later edit to the shortcut lines is the behaviour-preserving #12116 (2023) (2014-12-29)
- First affected version
- 5.0.0 [exec]; 4.10.3 and 4.10.4 copy correctly [exec] and no 4.x release tag contains either commit [git]
- Affected versions
- Every release from 5.0.0 through 10.6.0 (10.6.0 run at its RC1 revision 4ae946e5a9b) and main a9779ef3c193 and 645d4fe14a2 [exec]; never fixed. [exec] follow-up history runs: 5.0.0, 5.1.0, 5.5.5, 6.0.0, 6.6.6, 7.0.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0 and 9.12.3 fail the version-independent main() repro (copy = title twice, no price), the finder's JUnit fails 2 of 2 on 9.12.3, 10.0.0, 10.5.2 and main (-ea and -da), and the finder also ran 9.4.2 (fails); the independent reproduction's JUnit fails 2 of 3 on main (-ea and -da), 10.5.2 and 9.12.3; the intended-behaviour check re-ran the finder's repro on main and 10.5.2; not affected: 4.10.3 and 4.10.4 (a ParallelAtomicReader variant of the repro passes) and the parents of the introducing commits on trunk and branch_5x. [read] the 15 5.x tags contain the branch_5x commit and the 83 tags 6.0.0 to 10.5.2 contain the trunk commit; entry points: addIndexes(CodecReader...) with SlowCodecReaderWrapper since 5.0.0 (LUCENE-6165), OneMerge.wrapForMerge since 6.2.0 (LUCENE-6766, executed on 9.12.3, 10.0.0, 10.5.2 and main); no later commit to ParallelLeafReader.java, StoredFieldsWriter.java or SlowCodecReaderWrapper.java on upstream main through 645d4fe14a2 (2026-10-29) and no open PR changes the relevant code; 10.6.0 (released 2026-10-29; branch_10_6 RC1 4ae946e5a9b) [exec 2026-10-29: finder 2 of 2 with -ea and -da, the independent reproduction 2 of 3] and branch_10x 657014b3c579 [read: same sources on this path; #16905 only adds a vector forward to SlowCodecReaderWrapper]. Releases older than 9.12.3 were run only by the finder and the follow-up, not by a verifier. JDK 25.0.3, aarch64; pure Java logic.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (searched 2026-10-27, read-only; the prior-report record, verdict new): three hunt prior-report tool runs (163 non-web queries over apache/lucene GitHub issues, PRs and commits, Elasticsearch, OpenSearch and Solr, the dev@, java-user@, issues@ and commits@ lists and the LUCENE JIRA archive), 23 manual GitHub searches (including downstream repositories, all of GitHub), the changed files of all 409 open apache/lucene PRs (none changes ParallelLeafReader.storedFields(), the FieldInfo the visitor receives or MergeVisitor's alignment check), 9 web queries, 38 issues and PRs and 10 list threads read; not fixed upstream (no commit to ParallelLeafReader.java, StoredFieldsWriter.java or SlowCodecReaderWrapper.java after a9779ef3c193 at search time). Nearest items, none a report of this bug: #4649 (LUCENE-3575, 2011, fixed: wrong stored field names after merging, a bug in older SegmentMerger bulk-copy code that predates this one; precedent that such renaming is a bug), #7197 (LUCENE-6135, 2014: states that merge shortcuts must be off when field numbers do not line up, or values get mixed up across fields; its test-only MismatchedLeafReader renumbers the visitor's FieldInfo, which ParallelLeafReader does not), #13812, #13809 and #13805 (2024: the same class of bug fixed for doc values and points, not stored fields), #7195 (LUCENE-6133, the introducing change; its discussion is about CPU cost only), #9093 (LUCENE-8045, a ParallelLeafReader dvGen bug fixed in getFieldInfos()), #1684 (LUCENE-606, 2006, overlapping fields in ParallelReader, Won't Fix), and a downstream fork's issue (mkhludnev/solr#29) that merges through SlowCodecReaderWrapper over ParallelLeafReader with a doc-values-only sidecar, which cannot hit this bug. Gaps: keyword search only, GitHub search does not cover closed PR diffs, private lists are not searchable; 'not found' is the best available evidence, not proof.
- Lucene commit tested
- main
a9779ef3c193(2026-10-26 commit; runs on 2026-10-27): the finder's JUnit and an independent reproducer's JUnit through gradle with assertions on and off on stock main, and with fix A and fix B in a scratch worktree together with the closest core and codecs suites; repro runs by the finder, cross-model reviewers, verifiers, the adjudication and an audit with their own seeds; 14 releases from 5.0.0 to 10.5.2 (amain()repro up to 9.12.3, the JUnit on 9.12.3, 10.0.0 and 10.5.2; tag containment covers the rest of that range), 4.10.3 and 4.10.4; builds of the two introducing commits and their parents. OpenJDK 25.0.3, Linux aarch64.
- Finding record
lucene/core/src/java/org/apache/lucene/index/ParallelLeafReader.java :36-49 (class javadoc: 'Each document contains the union of the fields', lockstep warning), :154-159 (FieldInfos.Builder, first reader having a field wins), :239-245 (getFieldInfos NOTE: numbers 'will likely not correspond'), :277-298 (storedFields(): the caller's visitor is passed unchanged to each sub-reader)lucene/core/src/java/org/apache/lucene/codecs/StoredFieldsWriter.java :182-192 (MergeVisitor: remapper set only when the source's getFieldInfos() numbers disagree with mergeFieldInfos), :237-243 (remap(): without a remapper the visited FieldInfo is returned as is)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/index/ParallelLeafReader.java:38-39, 123-124, 154-159, 242-244, 277-298lucene/core/src/java/org/apache/lucene/index/FieldInfos.java:415-433lucene/core/src/java/org/apache/lucene/index/SlowCodecReaderWrapper.java:38, 319-350lucene/core/src/java/org/apache/lucene/index/MergeState.java:133lucene/core/src/java/org/apache/lucene/codecs/StoredFieldsWriter.java:176-245lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingStoredFieldsWriter.java:600-645, 678-698lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:3255; index/MergePolicy.java:302
- Who is affected
lucene/core/src/test/org/apache/lucene/index/TestDemoParallelLeafReader.java:178-182, 644-650
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/index/SlowCompositeCodecReaderWrapper.java:118-122, 162-205lucene/test-framework/src/java/org/apache/lucene/tests/index/MismatchedLeafReader.java:110-135lucene/core/src/java/org/apache/lucene/index/StoredFieldVisitor.java:35lucene/core/src/test/org/apache/lucene/index/TestParallelReaderEmptyIndex.java:34-36, 129-134lucene/CHANGES.txt:11324 (LUCENE-6133), 19473-19478 (LUCENE-1918)a Lucene clone git show d249f8bc3378 (removed by-name merge and its TODO)lucene/core/src/java/org/apache/lucene/index/MergePolicy.java:52, 69, 189; FilterMergePolicy.java:27 (@lucene.experimental)
- Suggested fix
lucene/core/src/java/org/apache/lucene/index/FieldInfos.java:330-332, 341-346
- History
a Lucene clone git log d249f8bc3378 (author, date, subject)
- TestParallelLeafReaderAddIndexesStoredFields.java (JUnit test):
repro/LFV-652/src/org/apache/lucene/index/TestParallelLeafReaderAddIndexesStoredFields.java(54 lines)
A step-by-step picture of the repro's example, made in parallel with this doc from a probe run on main that prints every field number involved, the numbers a visitor receives, the merge's alignment check, the copies and CheckIndex's verdict. The PNG is the final summary card.
assets/LFV-652/bug.png(531 KB)