Every LeafReader describes itself through getMetaData(): the Lucene version that created it, the oldest version that wrote to it, and its index sort. TermVectorLeafReader reports "created by 11, oldest writer unknown". LeafMetaData forbids an unknown oldest writer for anything created by 7 or later, so the method throws instead of returning.
TermVectorLeafReaderis a public highlighter class that "Wraps a Terms with a LeafReader, typically from term vectors": it turns one document's term vectors into a tiny searchable reader withmaxDoc()= 1.LeafMetaDatais whatLeafReader.getMetaData()returns: the major version that created the index, the minimum version that wrote to it, the index sort and a block flag. Its constructor checks these values and throwsIllegalArgumentExceptionon an invalid combination.- Some APIs read every leaf's metadata before they start: a search with a
Sort(to see whether it can stop early), theParallelLeafReaderconstructor, andIndexWriter.addIndexes(to check versions and sort).
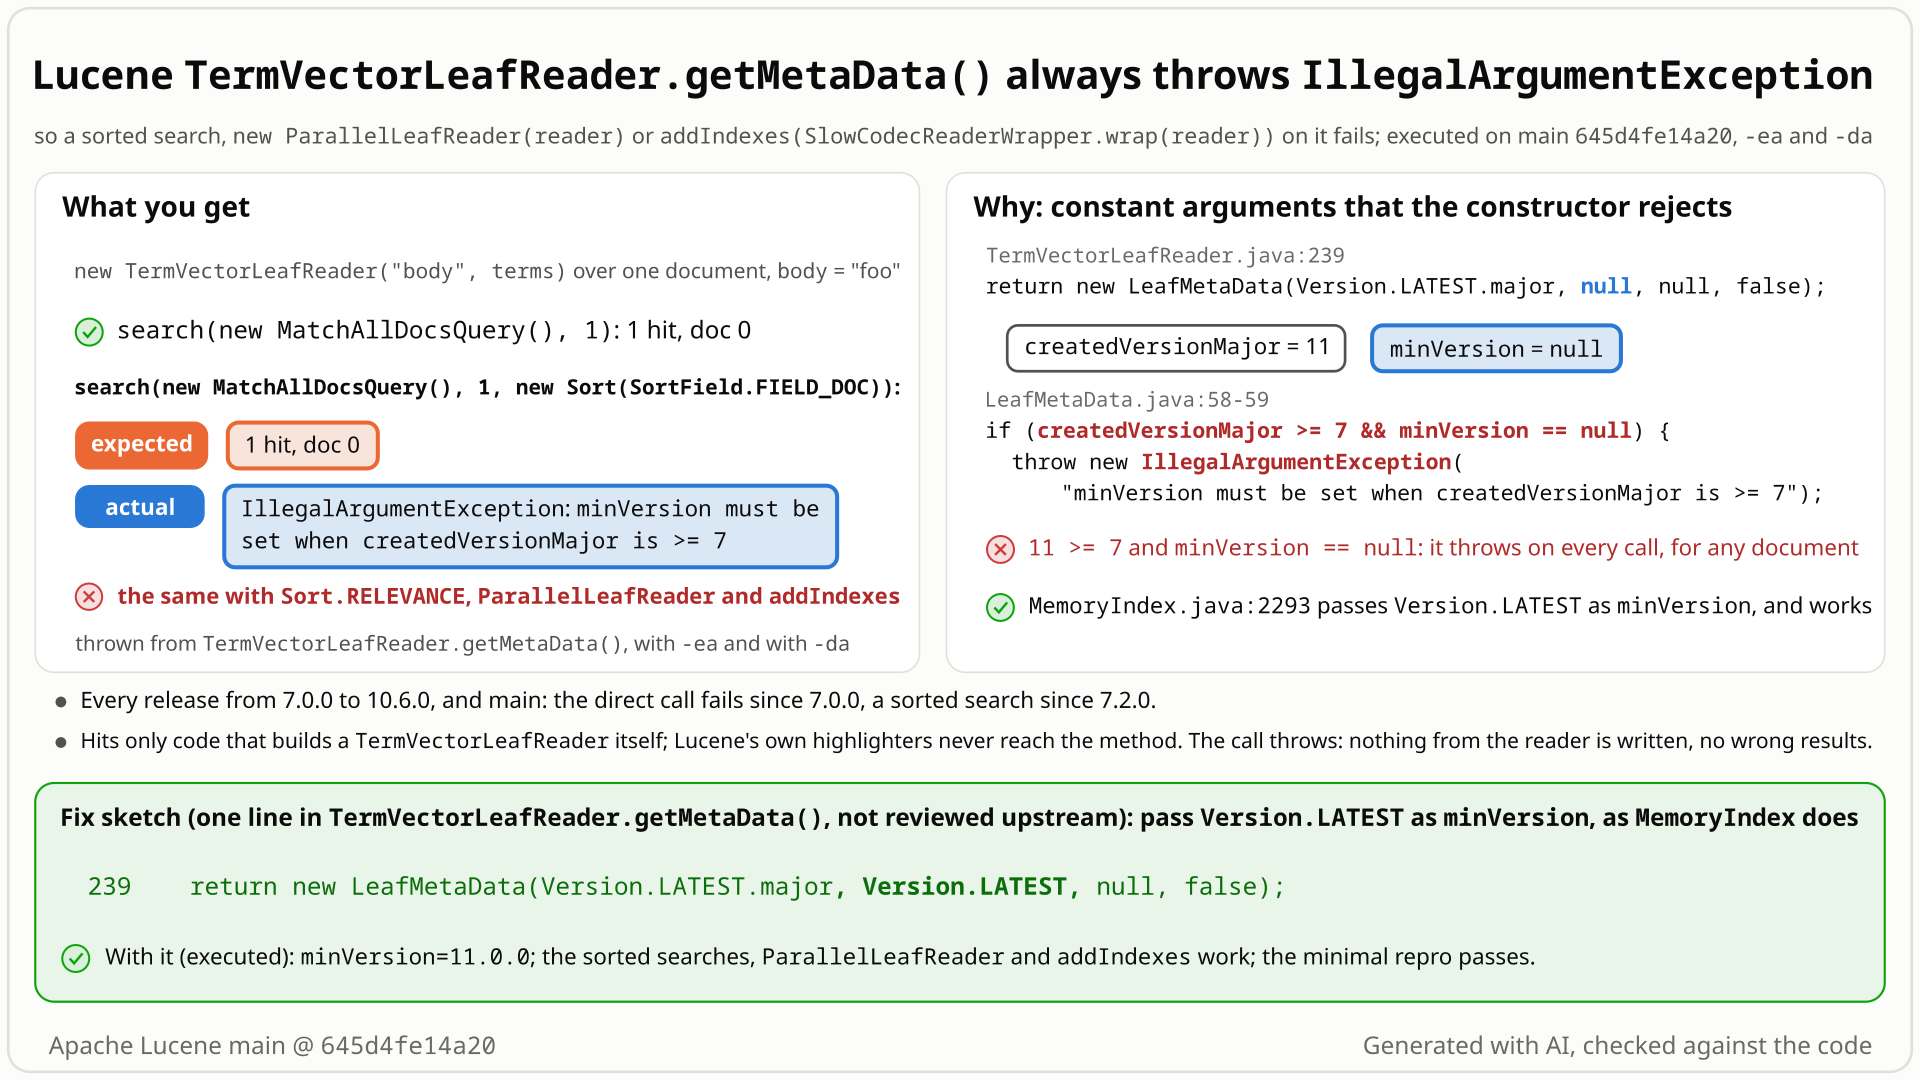
TermVectorLeafReader over them, a search sorted by doc id that asks the reader for its metadata, the LeafMetaData check that rejects "created by 11, oldest writer unknown", and the one-line fix. Select the still to open it at full size. Generated with AI, checked against the code.- Index one document whose text field
body= "foo" stores term vectors, and wrap them innew TermVectorLeafReader("body", terms): a reader with exactly 1 document. - Search it sorted by doc id:
searcher.search(new MatchAllDocsQuery(), 1, new Sort(SortField.FIELD_DOC)). You expect 1 hit, doc 0; the same search without aSortreturns it. - Instead it throws
IllegalArgumentException: minVersion must be set when createdVersionMajor is >= 7. A sorted search asks each reader for its metadata, and this reader answers "created by version 11, oldest writer unknown", a pairLeafMetaDatarejects for anything created by 7 or later. - The arguments are constants, so the call fails every time, for any document, with assertions on or off.
new ParallelLeafReader(reader)andaddIndexes(SlowCodecReaderWrapper.wrap(reader))fail the same way;MemoryIndex's reader passesVersion.LATESTand works.
Only applications that build a TermVectorLeafReader themselves and hand it to an API that reads leaf metadata: a search with any Sort, ParallelLeafReader or addIndexes. Lucene's own highlighters are not affected. The failure is a clean exception and nothing from the reader is written. Every release since 7.0.0; rare: no public report found in nine years.
Mechanism, terms and numbers450 words
TermVectorLeafReader (highlighter module, public, @lucene.experimental) wraps one document's term vectors as a one-document LeafReader. Its getMetaData() returns new LeafMetaData(Version.LATEST.major, null, null, false) (TermVectorLeafReader.java:237-240 on main 645d4fe14a20), and the LeafMetaData constructor throws IllegalArgumentException("minVersion must be set when createdVersionMajor is >= 7") for exactly that pair (LeafMetaData.java:58-60). The arguments are constants, so the method can never return. Every API that reads leaf metadata fails on the reader: a search with any Sort, Sort.RELEVANCE included (TopFieldCollector.java:58), new ParallelLeafReader(reader) (ParallelLeafReader.java:131) and IndexWriter.addIndexes(SlowCodecReaderWrapper.wrap(reader)) (IndexWriter.java:3229). Lucene's own highlighters do not ask for the reader's metadata (code reading of both in-tree call sites; their 21 term-vector tests pass), so the code that is hit is code that uses the class directly, and it gets a clean exception. The commit that added the check (LUCENE-7756, first released in 7.0.0) gave MemoryIndex's reader the valid Version.LATEST; passing the same here fixes it, and with that one-line change the repro and the whole highlighter test suite pass.
- The reader.
TermVectorLeafReader.java:237-240:return new LeafMetaData(Version.LATEST.major, null, null, false);.Version.LATESTisLUCENE_11_0_0on main (Version.java:259), so this is created major 11 with a nullminVersion. - The invariant.
LeafMetaDatais a record (LeafMetaData.java:45-46) whose compact constructor, "Expert: Sole constructor. Public for use by custom LeafReader impls." (:48-49), rejects a created major in the future (:50-53) or below 6 (:54-57), and thencreatedVersionMajor >= 7 && minVersion == null(:58-60). The third check always fires for this reader, whatever its document. - The consumers.
TopFieldLeafCollector's constructor readscontext.reader().getMetaData().sort()for every leaf (TopFieldCollector.java:53-59), and everyIndexSearcher.search(query, n, sort)goes through it, withSort.RELEVANCEandSort.INDEXORDERtoo.ParallelLeafReader's constructor reads every sub-reader's metadata (ParallelLeafReader.java:130-131).SlowCodecReaderWrapperforwardsgetMetaData()(SlowCodecReaderWrapper.java:140-143), andaddIndexes(CodecReader...)reads it in its up-frontvalidateMergeReader(IndexWriter.java:3228-3229,:3288-3290). - The sibling that works.
MemoryIndex's reader returnsnew LeafMetaData(Version.LATEST.major, Version.LATEST, null, false)(MemoryIndex.java:2291-2294), as does the test framework's fake reader (QueryUtils.java:312). Of the sevennew LeafMetaData(calls in the non-test sources, this is the only one that passes a literalnull.
| call on the 1-document reader | expected | actual |
|---|---|---|
searcher.search(new MatchAllDocsQuery(), 1) | 1 hit | 1 hit (doc 0) |
searcher.search(new MatchAllDocsQuery(), 1, new Sort(SortField.FIELD_DOC)) | 1 hit | IllegalArgumentException |
the same with Sort.RELEVANCE or Sort.INDEXORDER | 1 hit | IllegalArgumentException |
reader.getMetaData() | metadata, no sort | IllegalArgumentException |
new ParallelLeafReader(reader) | a reader | IllegalArgumentException |
writer.addIndexes(SlowCodecReaderWrapper.wrap(reader)) | 1 document copied | IllegalArgumentException; nothing from the reader added |
The message is always "minVersion must be set when createdVersionMajor is >= 7", from LeafMetaData.<init>(LeafMetaData.java:59) via TermVectorLeafReader.getMetaData(TermVectorLeafReader.java:239).
Exposure and likelihood283 words
- Who is hit. Code that constructs the reader itself (public class, public constructor) and passes it, or a
FilterLeafReaderthat delegates metadata to it, to a metadata-reading API: a search with anySort,new ParallelLeafReader(...),addIndexesthroughSlowCodecReaderWrapper, and othergetMetaData()callers such asSort.getPrimarySortFieldandCheckIndex(listed from code, not run). Default codec and settings; one document and one term are enough. - Not hit: Lucene's own highlighters. The unified highlighter builds the reader and wraps it in
OverlaySingleDocTermsLeafReader, aFilterLeafReaderover the real segment reader whose metadata it returns (TermVectorOffsetStrategy.java:48-50,FilterLeafReader.java:477-481). The classic highlighter builds it only for term vectors with positions and offsets (WeightedSpanTermExtractor.java:393-401) and only rewrites queries and builds span weights on it. The 21 tests ofTestTokenSources,TestHighlighterPhraseandTestUnifiedHighlighterTermVecpass on unfixed main; since the method throws on every call, a reached call would fail them. This rests on code reading of the two in-tree call sites plus these tests; it is not a proof for every query type or extension. - Downstream. A code search found no use of the class in Solr, Elasticsearch or OpenSearch (not exhaustive).
- Effect. An immediate
IllegalArgumentExceptionat the call. Nothing from the reader is written:addIndexesfirst flushes the writer's own buffered documents, as it always does (IndexWriter.java:3286), and then its up-front validation throws before anything from the reader is added (:3288-3290). Only anErroris treated as tragic there (:3390-3392), so the writer stays open. No wrong results, no hang. - How likely: rare. The class is a highlighter helper few applications build directly, and the documented searches found no public report since 7.0.0 (September 2017).
One JUnit test in the highlighter module, public API only: one document with term vectors, a TermVectorLeafReader over them, one search sorted by doc id. The test body makes no random calls; in-memory directory, single thread. It fails the same way with assertions on and off and with every seed tried.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.highlight;

import org.apache.lucene.analysis.standard.StandardAnalyzer;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.FieldType;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.MatchAllDocsQuery;
import org.apache.lucene.search.Sort;
import org.apache.lucene.search.SortField;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestTermVectorLeafReaderSortedSearch extends LuceneTestCase {

  public void testSortedSearch() throws Exception {
    FieldType withVectors = new FieldType(TextField.TYPE_NOT_STORED);
    withVectors.setStoreTermVectors(true);
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w = new IndexWriter(dir, new IndexWriterConfig(new StandardAnalyzer()))) {
      Document doc = new Document();
      doc.add(new Field("body", "foo", withVectors));
      w.addDocument(doc);
      try (DirectoryReader r = DirectoryReader.open(w)) {
        TermVectorLeafReader reader =
            new TermVectorLeafReader("body", r.termVectors().get(0, "body"));
        IndexSearcher searcher = new IndexSearcher(reader);
        int hits;
        try {
          hits =
              searcher.search(new MatchAllDocsQuery(), 1, new Sort(SortField.FIELD_DOC))
                  .scoreDocs
                  .length;
        } catch (IllegalArgumentException e) {
          throw new AssertionError("expected 1 hit from a doc-sorted search, got " + e, e);
        }
        assertEquals(1, hits);
      }
    }
  }
}
cp $REPRO/TestTermVectorLeafReaderSortedSearch.java $LUCENE/lucene/highlighter/src/test/org/apache/lucene/search/highlight/
cd $LUCENE && ./gradlew :lucene:highlighter:test --tests TestTermVectorLeafReaderSortedSearch -Ptests.seed=DEADBEEF
# also with -Ptests.asserts=false: the same failure
- Expected
- 1 hit (doc 0), the same as the search without a
Sort. - Observed
IllegalArgumentException: minVersion must be set when createdVersionMajor is >= 7fromTermVectorLeafReader.getMetaData(main, 10.6.0, 10.5.2 and 9.12.3; assertions on and off).
More files, environment, full output242 words
TestTermVectorLeafReaderSortedSearch (62 lines with the license header, one test method, package org.apache.lucene.search.highlight). ByteBuffersDirectory, a plain IndexWriterConfig(new StandardAnalyzer()), one document whose field body = "foo" stores term vectors (no positions or offsets needed). The test body makes no random calls. LuceneTestCase still randomizes the default codec, locale, time zone and similarity from the seed (SetupAndRestoreStaticEnv.java:144-230); the failure depends on none of them, and it failed with every seed tried. The catch only turns the exception into a message that states expected versus actual; a plain assertEquals(1, searcher.search(...).scoreDocs.length) that lets the exception propagate works as well.
The suggested regression test is this same test; it passes with the recommended fix.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); also the 10.6.0, 10.5.2 and 9.12.3 release jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (the only platform run; the code path is plain Java) |
cp $REPRO/TestTermVectorLeafReaderSortedSearch.java $LUCENE/lucene/highlighter/src/test/org/apache/lucene/search/highlight/
cd $LUCENE && ./gradlew :lucene:highlighter:test --tests TestTermVectorLeafReaderSortedSearch -Ptests.seed=DEADBEEF
# gradle, main 645d4fe14a20, -Ptests.seed=DEADBEEF (-Ptests.asserts=true; =false prints the same)
TestTermVectorLeafReaderSortedSearch > testSortedSearch FAILED
    java.lang.AssertionError: expected 1 hit from a doc-sorted search, got java.lang.IllegalArgumentException: minVersion must be set when createdVersionMajor is >= 7
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:FFA37021B6AA4628]:0)
        at org.apache.lucene.search.highlight.TestTermVectorLeafReaderSortedSearch.testSortedSearch(TestTermVectorLeafReaderSortedSearch.java:56)

        Caused by:
        java.lang.IllegalArgumentException: minVersion must be set when createdVersionMajor is >= 7
            at org.apache.lucene.core@11.0.0-SNAPSHOT/org.apache.lucene.index.LeafMetaData.<init>(LeafMetaData.java:59)
            at org.apache.lucene.search.highlight.TermVectorLeafReader.getMetaData(TermVectorLeafReader.java:239)
            at org.apache.lucene.core@11.0.0-SNAPSHOT/org.apache.lucene.search.TopFieldCollector$TopFieldLeafCollector.<init>(TopFieldCollector.java:58)
            at org.apache.lucene.core@11.0.0-SNAPSHOT/org.apache.lucene.search.TopFieldCollector$SimpleFieldCollector$1.<init>(TopFieldCollector.java:200)
            at org.apache.lucene.core@11.0.0-SNAPSHOT/org.apache.lucene.search.TopFieldCollector$SimpleFieldCollector.getLeafCollector(TopFieldCollector.java:199)
            at org.apache.lucene.core@11.0.0-SNAPSHOT/org.apache.lucene.search.IndexSearcher.searchLeaf(IndexSearcher.java:836)
            ...
            at org.apache.lucene.search.highlight.TestTermVectorLeafReaderSortedSearch.testSortedSearch(TestTermVectorLeafReaderSortedSearch.java:52)

# with the recommended fix: the test passes (assertions on and off), and the whole highlighter suite passesLeafReader.getMetaData()is an abstract method, "Return metadata about this leaf", with no throws clause; the class and its constructor are public.- The method can never succeed: its arguments are constants that the
LeafMetaDataconstructor rejects. - The 2017 commit that added the check gave the sibling
MemoryIndexreader valid metadata (Version.LATEST); this reader gotnull.
The full argument188 words
- Contract.
LeafReader.java:526-531:public abstract LeafMetaData getMetaData(), "Return metadata about this leaf",@lucene.experimental, no throws clause.TermVectorLeafReaderis a public class with a public constructor, whose javadoc reads "Wraps a Terms with a LeafReader, typically from term vectors" (TermVectorLeafReader.java:52-61), so a sorted search on it is ordinaryLeafReaderuse. The expected behaviour follows from the abstract method and theLeafMetaDatainvariant; it is not stated word for word. - History. LUCENE-7756 (
23b002a0fdf, 2017) addedLeafMetaDatawith the check, wrote this null call, and gaveMemoryIndexthe validVersion.LATESTin the same commit. The strict check was asked for in review (migrated issue #8807: throw "if minVersion is null but major version is >= 7"); the thread never mentionsTermVectorLeafReader. That this caller was overlooked is an inference. - No test. No test in the repository uses
TermVectorLeafReaderdirectly or expects "minVersion must be set", so no test calls this method directly. - Context only. The
LeafMetaDatajavadoc saysminVersionmay be null "if this information is not available" (LeafMetaData.java:30-31), but the constructor allows that only with created major 6 ("unknown",:27-29).
The devil's-advocate check241 words
The intended-behaviour checker and the cross-model reviews built the strongest case: the class and the method are @lucene.experimental; the class is a minimal highlighter helper with stub methods (getNormValues returns null with the comment "Is this needed?", null cache helpers, empty stored fields); Lucene's own callers avoid its metadata; and DocValuesLeafReader also throws from getMetaData() (DocValuesLeafReader.java:93-95).
Why it fails: the other stubs return values their contracts allow, and none throws; DocValuesLeafReader is package-private (:25), used only inside the indexing chain and throws UnsupportedOperationException by design, whereas this is a public reader whose one metadata method trips a constructor invariant on every call; @lucene.experimental allows API change, not a method that can never succeed; and the same commit gave MemoryIndex valid metadata. The cross-model reviews rated the argument weak, and the intended-behaviour check rejected it. What it does establish is narrow reach, hence low priority.
A dissenting rating: the cross-model fact check of this doc (OpenAI GPT-5.6, read-only) rated the case moderate, not weak. Its reasons: an experimental, minimal helper; term-vector Terms that are meant to be consumed only on the thread that acquired them (TermVectors.java:26-27); little practical value in sorting a one-document reader; and DocValuesLeafReader as a reader that throws by design. It still judged the bug a real, low-priority claim, not noise, and agreed with an ordinary public issue or small PR that leads with the direct call and the sorted search.
Recommended Pass Version.LATEST as minVersion, as MemoryIndex does
Pass Version.LATEST as the minimum version, as MemoryIndex does: a one-line change in TermVectorLeafReader.getMetaData(). That is the convention Lucene's other synthetic readers already follow. Validated: the repro passes with assertions on and off, and so do all 723 tests of the highlighter module.
   @Override
   public LeafMetaData getMetaData() {
-    return new LeafMetaData(Version.LATEST.major, null, null, false);
+    return new LeafMetaData(Version.LATEST.major, Version.LATEST, null, false);
   }
All options and trade-offs3 options · 522 words
One fix was built and validated; two alternatives were considered and not built.
One line in TermVectorLeafReader.getMetaData() (TermVectorLeafReader.java:239, 1 file, +1/-1). The reader then reports "created by and only written by this version" and no index sort, like MemoryIndex's reader (MemoryIndex.java:2293). Sorted searches and ParallelLeafReader accept it, and addIndexes gets past its metadata check (see the trade-offs).
   @Override
   public LeafMetaData getMetaData() {
-    return new LeafMetaData(Version.LATEST.major, null, null, false);
+    return new LeafMetaData(Version.LATEST.major, Version.LATEST, null, false);
   }
Trade-offs
Version.LATESTis a convention, not recorded provenance. The constructor gets only a field name and aTerms(TermVectorLeafReader.java:61), so the reader has no version input of its own, and its term vectors may come from a segment an older version wrote. It is the conventionMemoryIndexand the test framework'sQueryUtilsreader already use, and the created major is alreadyVersion.LATEST.major. No other trade-off is known.- With it,
addIndexesgets pastvalidateMergeReader, which checks the created major against the index's and requires a non-nullminVersionfor major >= 7 (IndexWriter.java:3228-3243). The document was copied in the earlier verifiers' test, which usesSerialMergeScheduler, and in the diagram probe, a plainmain()with the defaultIndexWriterConfig. Term-vectorTermsare meant to be consumed only on the thread that acquired them (TermVectors.java:26-27), soaddIndexesis a secondary path, not a general promise. - An upstream test of the
addIndexespath (not part of the repro) should useSerialMergeScheduler: with the fix, the test framework'sAssertingTermsrejected theTermsbeing consumed on aConcurrentMergeSchedulerthread in the first fixed run of the cross-model reviews.
What the checks validated
- Scratch worktree of
645d4fe14a20, gradle--no-daemon, OpenJDK 25.0.3, seed DEADBEEF: the repro test fails on the stock tree with assertions on and off, and passes with the fix with assertions on and off. - With the fix,
:lucene:highlighter:testwith assertions on: 35 suites (the repro included), 723 tests, 0 failures, 0 errors. :lucene:highlighter:checkGoogleJavaFormatpasses with the fix and the test in the tree.- Earlier, on main
a9779ef3c193: the finder's, the independent reproduction's, the cross-model review's and the intended-behaviour check's own tests all pass with the same change shadowed (the independent reproduction 6 of 6 covering the direct call,ParallelLeafReader,INDEXORDER-sorted search andaddIndexes).
The LeafMetaData javadoc treats created major 6 as "unknown" (LeafMetaData.java:27-29), and the constructor accepts it with a null minVersion. Not built.
Trade-offs
addIndexes would then reject the reader: validateMergeReader throws when the index's created major differs from the reader's (IndexWriter.java:3230-3236). So it trades one exception for another on that path.
Allow a null minVersion for created major >= 7, as the javadoc wording "or null if this information is not available" suggests (LeafMetaData.java:30-31). Not built.
Trade-offs
Broader and against the review that asked for the strict check; IndexWriter.java:3238-3242 separately rejects a null minVersion for created major >= 7 ("hides it"), so addIndexes would still fail.
No use of TermVectorLeafReader was found in Solr, Elasticsearch or OpenSearch; an application that builds one gets a clean exception from its own call, which no document or query can cause.
A hunt checking that ParallelLeafReader behaves as if its sub-readers were one index wrapped each public LeafReader type in the source tree in turn. Seven of eight types worked; TermVectorLeafReader failed as soon as the parallel reader was built. The failure was then reduced to a public-API JUnit test.
The method in full112 words
Method: non-formal (code reading plus execution; the hunt's hunt unit for ParallelLeafReader "as if one index" metamorphic checks, 2026-10-27, main a9779ef3c193).
- Reader sweep. One leg of the plan wrapped each public
LeafReadertype as aParallelLeafReadersub-reader:SegmentReader, the soft-deletes and exitable leaves,SlowCodecReaderWrapper,SortingCodecReader,FieldFilterLeafReader,MemoryIndex's reader andTermVectorLeafReader, each with construct, identity-dump andaddIndexes-copy checks, with assertions on and off. OnlyTermVectorLeafReaderfailed, at construction, with theminVersionexception. - Reduction. The lead from the plan's code reading was reduced to a public-API JUnit (direct
getMetaData(), thenParallelLeafReaderand a sorted search), and later minimized to the one-method sorted-search test shown above.
No prior report found (searched 2026-10-27, refreshed 2026-10-30): GitHub issues, PRs, commits and code, the downstream trackers, the mailing lists, the JIRA archive, the web and the changed files of 409 open Lucene PRs. Upstream main and branch_10_6 still have the line.
Searches4 searches
Nearest items, none a report of this bug: #8807 (LUCENE-7756, the introducing issue; it discusses a null minVersion only for pre-7.0 segments); #12685 and #13328 (edited the line or LeafMetaData and kept both the null and the check); SOLR-11406 (a different null-minVersion failure, pre-7.0 segments in SlowCompositeReaderWrapper, fixed in 2017); open PRs #13525, #13342 and #16847 touch TermVectorLeafReader.java for API changes and leave getMetaData as is. These searches show only that no report turned up in them. Gaps: keyword search only; GitHub does not index PR diffs; private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits; downstream trackers; the web | 2026-10-27 | a scripted prior-report search, two runs, 96 queries (the class, the method, both error strings, sort, exception, ParallelLeafReader, LeafMetaData); manual GitHub searches in all repositories for the class name and both error strings | only #7096, #8490 and #8007 mention the class, none about metadata; the error strings match no Lucene item |
| GitHub code search; open PRs | 2026-10-27 | TermVectorLeafReader everywhere and inside the Solr, Elasticsearch and OpenSearch repositories; the changed files of 409 open apache/lucene PRs | no downstream use; 3 open PRs touch the file without changing getMetaData; none touches LeafMetaData.java |
| Mailing lists and JIRA archive | 2026-10-27 | dev@, java-user@, issues@, commits@ and six more Lucene and Solr lists; the SOLR, LUCENE and LUCENENET JIRA archive | only the commit mails of the commits that wrote or edited the line; both error strings: 0 hits |
| GitHub (re-check for this doc) | 2026-10-30 (three times) | apache/lucene: TermVectorLeafReader, "minVersion must be set", TermVectorLeafReader getMetaData, LeafMetaData minVersion; items updated since 2026-10-29; the file on main and branch_10_6 | nothing new; main 2f424fd428da (line 239) and branch_10_6 91eaab4fb298 (line 228) still pass null |
Introduced in 7.0.0 by LUCENE-7756 (23b002a0fdf, 2017), the commit that added LeafMetaData with the check and wrote this null call; sorted search became a trigger in 7.2.0 (LUCENE-8059). Unchanged since, apart from an appended hasBlocks=false in 9.9.0. 6.x is not affected: the method did not exist.
Versions tested6 rows
Introduced by LUCENE-7756 "Only record the major Lucene version that created the index, and record the minimum Lucene version that contributed to segments" (23b002a0fdf2, Adrien Grand, authored 2017-03-30, committed 2017-04-04; JIRA patch era, migrated as #8807). It replaced TermVectorLeafReader.getIndexSort() with getMetaData() { return new LeafMetaData(Version.LATEST.major, null, null); }, added LeafMetaData with the check, and gave MemoryIndex Version.LATEST. git tag --contains puts it in 7.0.0 and in no 6.x release.
Sorted search became a trigger in 7.2.0 with LUCENE-8059 "Fold early termination support into TopFieldCollector" (812711416d9 on master, e4e7d12f5d8 on branch_7x, 2017-11-29), which made TopFieldCollector read every leaf's metadata. The only later edit to this call, #12685 (6677109ee60 on main, backported to 9.x as 26043819a5b, first released in 9.9.0), appended hasBlocks=false and kept the null; the 9.8.0 tag still has the three-argument call.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 and a9779ef3c193 | affected | the one-method test fails (gradle and the standalone runner, assertions on and off); direct call, ParallelLeafReader and addIndexes fail too |
| 10.6.0, 10.5.2, 9.12.3 | affected | the one-method test fails (assertions off) |
| 7.2.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 10.0.0 | affected | direct call, ParallelLeafReader, sorted search and addIndexes all throw (version-independent probe) |
| 7.0.0, 7.1.0 | sorted search OK | direct call, ParallelLeafReader and addIndexes throw; a sorted search still works |
| 6.5.0, 6.6.6 | method absent | no getMetaData() (its predecessor getIndexSort() returned null); all consumers work |
| main + fix | not affected | the test passes, and so do all 723 highlighter tests |
Verifiers (an independent reproducer, a cross-model review by OpenAI GPT-5.6 and an intended-behaviour devil's advocate), an earlier executing GPT-5.6 review, the adjudication and a credibility audit all rate it real. This doc re-ran the repro on 645d4fe14a20 and validated the fix with gradle; fact checks of the doc confirmed it and led to corrections.
Checks and verdicts397 words
The cross-model reviews ran with code execution and wrote their own tests. Versions older than 9.12.3 were run by the finder and the history probe only, not by a verifier. Not run on x86 (plain Java logic).
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Reader sweep: of 8 public reader types only TermVectorLeafReader fails. JUnit 2 of 2 fail (-ea, -da), also on 10.5.2; the fix passes. |
| cross-model review, refute lens | real, high | OpenAI GPT-5.6, executed: own test fails 4 of 6 (direct, ParallelLeafReader, sorted search, addIndexes), controls pass; the fix passes it and 16 highlighter tests; intended argument weak. |
| Independent reproducer | real | Own 6-test JUnit outside the highlighter package fails 4 of 6 on main (-ea, -da, 6 seeds), 10.5.2 and 9.12.3; controls pass; 6 of 6 with the fix. |
| Cross-model review, intended lens | real, high | OpenAI GPT-5.6, executed: own test fails 4 of 6, 0 of 6 with the fix; 21 existing highlighter tests pass with the fix; intended argument weak. |
| Intended-behaviour devil's advocate | real, high (low impact) | Found that a Sort.RELEVANCE search fails too; the classic highlighter phrase path and MemoryIndex controls pass; built the strongest works-as-designed case and showed why it fails. |
| adjudication | confirmed, high | Re-ran the independent reproduction's JUnit with a new seed (-ea, -da): 4 of 6 fail, both controls pass; 6 of 6 with the fix. |
| Registration check and credibility audit | keep | Re-ran the finder's JUnit with -da: 2 of 2 fail. Committer view: a real but small bug with an obvious one-line fix. |
| this doc's runs | reproduced; fix validated | The one-method test fails on 645d4fe14a20 (gradle and standalone, -ea and -da), 10.6.0, 10.5.2 and 9.12.3; with the fix it passes, and so do all 723 highlighter tests. |
| fact checks of this doc | real as described; corrections applied | An independent fact checker re-ran the repro (gradle and the standalone runner, -ea and -da, release jars), the fix with the whole highlighter suite, and its own probe of every consumer; a read-only cross-model fact check (OpenAI GPT-5.6) read the evidence. Two dating errors (#12685 first shipped in 9.9.0; 7.0.0 is nine years old) and two wording errors (what addIndexes writes; why Version.LATEST) were corrected, and several claims were scoped more narrowly. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 434 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,273 words
- Registry title
- TermVectorLeafReader.getMetaData() always throws IllegalArgumentException ('minVersion must be set when createdVersionMajor is >= 7'), so a TermVectorLeafReader cannot be searched with a Sort, wrapped in a ParallelLeafReader or copied with addIndexes
- Area
- highlighter / TermVectorLeafReader (LeafReader over one document's term vectors; LeafMetaData invariant)
- Priority
- Low, rank 662: TermVectorLeafReader.getMetaData always throws a clear IllegalArgumentException, but only when this rarely used helper is passed to sorted search, ParallelLeafReader or addIndexes.
- Impact class
- crash
- Impact note
- Hits only applications that construct a TermVectorLeafReader themselves (public class and constructor, @lucene.experimental; a code search finds no use in Solr, Elasticsearch or OpenSearch) and pass it to an API that reads leaf metadata: IndexSearcher.search(query, n, sort) with any Sort, Sort.RELEVANCE and Sort.INDEXORDER included (since 7.2.0), new ParallelLeafReader(...), or IndexWriter.addIndexes(SlowCodecReaderWrapper.wrap(...)); every such call throws IllegalArgumentException, deterministically with -ea and -da and whatever the document; the exception is clean (nothing is persisted, addIndexes leaves the writer open), relevance search without a Sort works, and Lucene's own highlighters never reach the method.
- Summary
- You build a TermVectorLeafReader over one document's term vectors (new TermVectorLeafReader(field, terms), the public helper that 'wraps a Terms with a LeafReader') and use it like any other LeafReader, expecting getMetaData() to return metadata with no index sort, as MemoryIndex's in-memory reader does. Instead getMetaData() throws IllegalArgumentException('minVersion must be set when createdVersionMajor is >= 7') on every call, because it passes minVersion=null together with createdVersionMajor=Version.LATEST.major, a combination the LeafMetaData constructor rejects. So a field-sorted search (even with Sort.RELEVANCE), new ParallelLeafReader(reader) and addIndexes(SlowCodecReaderWrapper.wrap(reader)) all fail; a plain relevance search without a Sort works.
- Introduced
- 23b002a0fdf2f6025f1eb026c0afca247fb21ed0 (LUCENE-7756 'Only record the major Lucene version that created the index, and record the minimum Lucene version that contributed to segments', migrated as apache/lucene#8807, by Adrien Grand; JIRA patch era, no PR): the same commit added the LeafMetaData constructor check and rewrote TermVectorLeafReader.getIndexSort() { return null; } as getMetaData() { return new LeafMetaData(Version.LATEST.major, null, null); }, while giving MemoryIndex the valid Version.LATEST [read: git log, -S/-G and blame in the full-history clone; exec: 6.5.0 and 6.6.6 pass, 7.0.0 fails; git tag --contains puts the commit in 7.0.0 and in no 6.x release]. The field-sorted-search trigger came with LUCENE-8059 'Fold early termination support into TopFieldCollector' (812711416d9 on master, e4e7d12f5d8 on branch_7x, first release 7.2.0), which made TopFieldCollector read getMetaData() for every leaf [exec: 7.1.0 sorted search works, 7.2.0 fails]. 6677109ee60 (#12685, first release 10.0.0) only appended hasBlocks=false and kept the null (2017-03-30 (authored), 2017-04-04 (committed to master); sorted-search trigger 2017-11-29 (LUCENE-8059))
- First affected version
- 7.0.0 [exec] (direct getMetaData(), ParallelLeafReader and addIndexes fail); field-sorted search fails from 7.2.0 [exec]. 6.x and older are not affected [exec 6.5.0 and 6.6.6]: getMetaData() did not exist and its predecessor getIndexSort() returned null
- Affected versions
- Every release from 7.0.0 to 10.6.0 (10.6.0 [exec: the minimal test fails on the release jars, -ea and -da, 2026-10-30]) and main a9779ef3c193; never fixed. [exec] follow-up version-independent main() probe: fails on 7.0.0, 7.1.0, 7.2.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main (-ea and -da), passes on 6.5.0 and 6.6.6 and on main with the one-line fix shadowed; the finder's JUnit fails 2 of 2 on main (-ea and -da), 10.5.2 and 10.0.0, and its main() repro fails on 9.12.3, 9.4.2, 8.11.4, 7.7.3 and 7.0.0; the independent reproduction's JUnit fails 4 of 6 on main (-ea and -da), 10.5.2 and 9.12.3; the intended-behaviour check's probe fails 2 of 5 on main (-ea and -da) and 10.5.2; the GPT reviewers' own tests fail 4 of 6 on ea57360912ed (identical TermVectorLeafReader and LeafMetaData), and the intended-lens one also on a9779ef3c193. [read] git tag --contains 23b002a0fdf lists every 7.0.0-8.8.1 and 9.0.0-10.5.2 tag and no 6.x tag (8.8.2-8.11.4 are not tagged in this clone; 8.11.4 executed); upstream main a95c754ee003, branch_10x and branch_10_6 still have the line (read through the GitHub contents API, not executed). JDK 25.0.3, aarch64; pure Java logic.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (searched 2026-10-27, read-only; the prior-report record, verdict new): two hunt prior-report tool runs (96 queries over apache/lucene GitHub issues, PRs and commits, Solr, Elasticsearch and OpenSearch, the dev@, java-user@, issues@ and commits@ lists, the LUCENE JIRA archive and the web), manual GitHub searches in all repositories for the class name and both error strings (only #7096, #8490 and #8007 mention TermVectorLeafReader, none about metadata; the error strings match no Lucene item), GitHub code search (no downstream use of the class), six more Lucene and Solr lists (0 hits), the SOLR, LUCENE and LUCENENET JIRA archive (error strings: 0 hits), six web searches, the changed files of 409 open apache/lucene PRs (#13525, #13342 and #16847 touch TermVectorLeafReader.java without changing getMetaData; none touches LeafMetaData.java) and the git history (the line is unchanged in substance since 2017). Not fixed upstream: main a95c754ee003, branch_10x and branch_10_6 still have the line. Nearest items, none a report of this bug: LUCENE-7756 / #8807 (the introducing issue; its discussion covers null minVersion only for pre-7.0 segments), #12685 (edited the line to add hasBlocks=false and kept the null), #13328 (made LeafMetaData a record and kept the check), SOLR-11406 (a different null-minVersion failure, pre-7.0 segments in SlowCompositeReaderWrapper, fixed 2017). Gaps: keyword search only; GitHub does not index PR diffs; private security reports are not visible; 'not found' is the best available evidence, not proof.
- Lucene commit tested
- main
645d4fe14a20(commit of 2026-10-28; runs of 2026-10-30) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the 10.6.0, 10.5.2 and 9.12.3 release jars. The hunt's earlier runs used maina9779ef3c193(the files involved are identical) and the releases 6.5.0 to 10.5.2. The recommended fix was validated in the scratch worktree: the repro test with assertions on and off, the whole highlighter test suite (35 suites, 723 tests) andcheckGoogleJavaFormat.
- Finding record
lucene/highlighter/src/java/org/apache/lucene/search/highlight/TermVectorLeafReader.java :51-56 (class javadoc 'Wraps a Terms with a LeafReader, typically from term vectors', @lucene.experimental, public class), :237-240 (getMetaData returns new LeafMetaData(Version.LATEST.major, null, null, false))lucene/core/src/java/org/apache/lucene/index/LeafMetaData.java :24-31 (javadoc: created major 6 means unknown; minVersion null 'if this information is not available'), :47-61 (constructor 'Public for use by custom LeafReader impls'; throws 'minVersion must be set when createdVersionMajor is >= 7' at :58-59)lucene/core/src/java/org/apache/lucene/index/LeafReader.java :526-531 (getMetaData 'Return metadata about this leaf', @lucene.experimental, no throws clause)lucene/memory/src/java/org/apache/lucene/index/memory/MemoryIndex.java :2293 (new LeafMetaData(Version.LATEST.major, Version.LATEST, null, false))lucene/core/src/java/org/apache/lucene/search/TopFieldCollector.java :58, lucene/core/src/java/org/apache/lucene/index/ParallelLeafReader.java :131, lucene/core/src/java/org/apache/lucene/index/SlowCodecReaderWrapper.java :140-143 (consumers that read getMetaData unconditionally)
- The finding in 30 seconds
lucene/highlighter/src/java/org/apache/lucene/search/highlight/TermVectorLeafReader.java:52-56 (at 645d4fe14a20) (class javadoc, @lucene.experimental), :61 (public constructor), :225-227 (maxDoc 1), :237-240 (getMetaData)lucene/core/src/java/org/apache/lucene/index/LeafMetaData.java:24-44 (at 645d4fe14a20) (javadoc), :45-61 (record and compact constructor; check at :58-60); lucene/core/src/java/org/apache/lucene/util/Version.java:259lucene/core/src/java/org/apache/lucene/search/TopFieldCollector.java:53-59; (at 645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/ParallelLeafReader.java:130-131; lucene/core/src/java/org/apache/lucene/index/SlowCodecReaderWrapper.java:140-143; lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:3228-3243, :3288-3290lucene/memory/src/java/org/apache/lucene/index/memory/MemoryIndex.java:2291-2294; (at 645d4fe14a20) lucene/test-framework/src/java/org/apache/lucene/tests/search/QueryUtils.java:312; git grep "new LeafMetaData(" over non-test sources (7 calls)
- Who is affected
lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/TermVectorOffsetStrategy.java:48-50; (at 645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/FilterLeafReader.java:477-481; lucene/highlighter/src/java/org/apache/lucene/search/highlight/WeightedSpanTermExtractor.java:393-401, :423; lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:3288-3290, :3390-3392lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:3286 (at 645d4fe14a20) (flush before the up-front validations)
- Minimal repro
lucene/test-framework/src/java/org/apache/lucene/tests/util/SetupAndRestoreStaticEnv.java:144-230 (at 645d4fe14a20) (seeded codec, locale, time zone and similarity)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/index/LeafReader.java:526-531; (at 645d4fe14a20) lucene/highlighter/src/java/org/apache/lucene/search/highlight/TermVectorLeafReader.java:52-61; lucene/core/src/java/org/apache/lucene/index/LeafMetaData.java:27-31; lucene/core/src/java/org/apache/lucene/index/DocValuesLeafReader.java:25, :93-95
- Suggested fix
lucene/memory/src/java/org/apache/lucene/index/memory/MemoryIndex.java:2293; (at 645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:3228-3243; lucene/core/src/java/org/apache/lucene/index/LeafMetaData.java:27-31
- TestTermVectorLeafReaderSortedSearch.java (lucene/highlighter, one test):
repro/LFV-655/src/org/apache/lucene/search/highlight/TestTermVectorLeafReaderSortedSearch.java(62 lines)
It ends on the summary card that is also the PNG.
assets/LFV-655/bug.png(434 KB)