Arabic attaches "and" (و) and "with the" or "for the" (بال, لل) to the front of a word. A light stemmer removes them so that every form of a word shares one index term. Lucene's stemmer removes only the first of these pieces it finds.
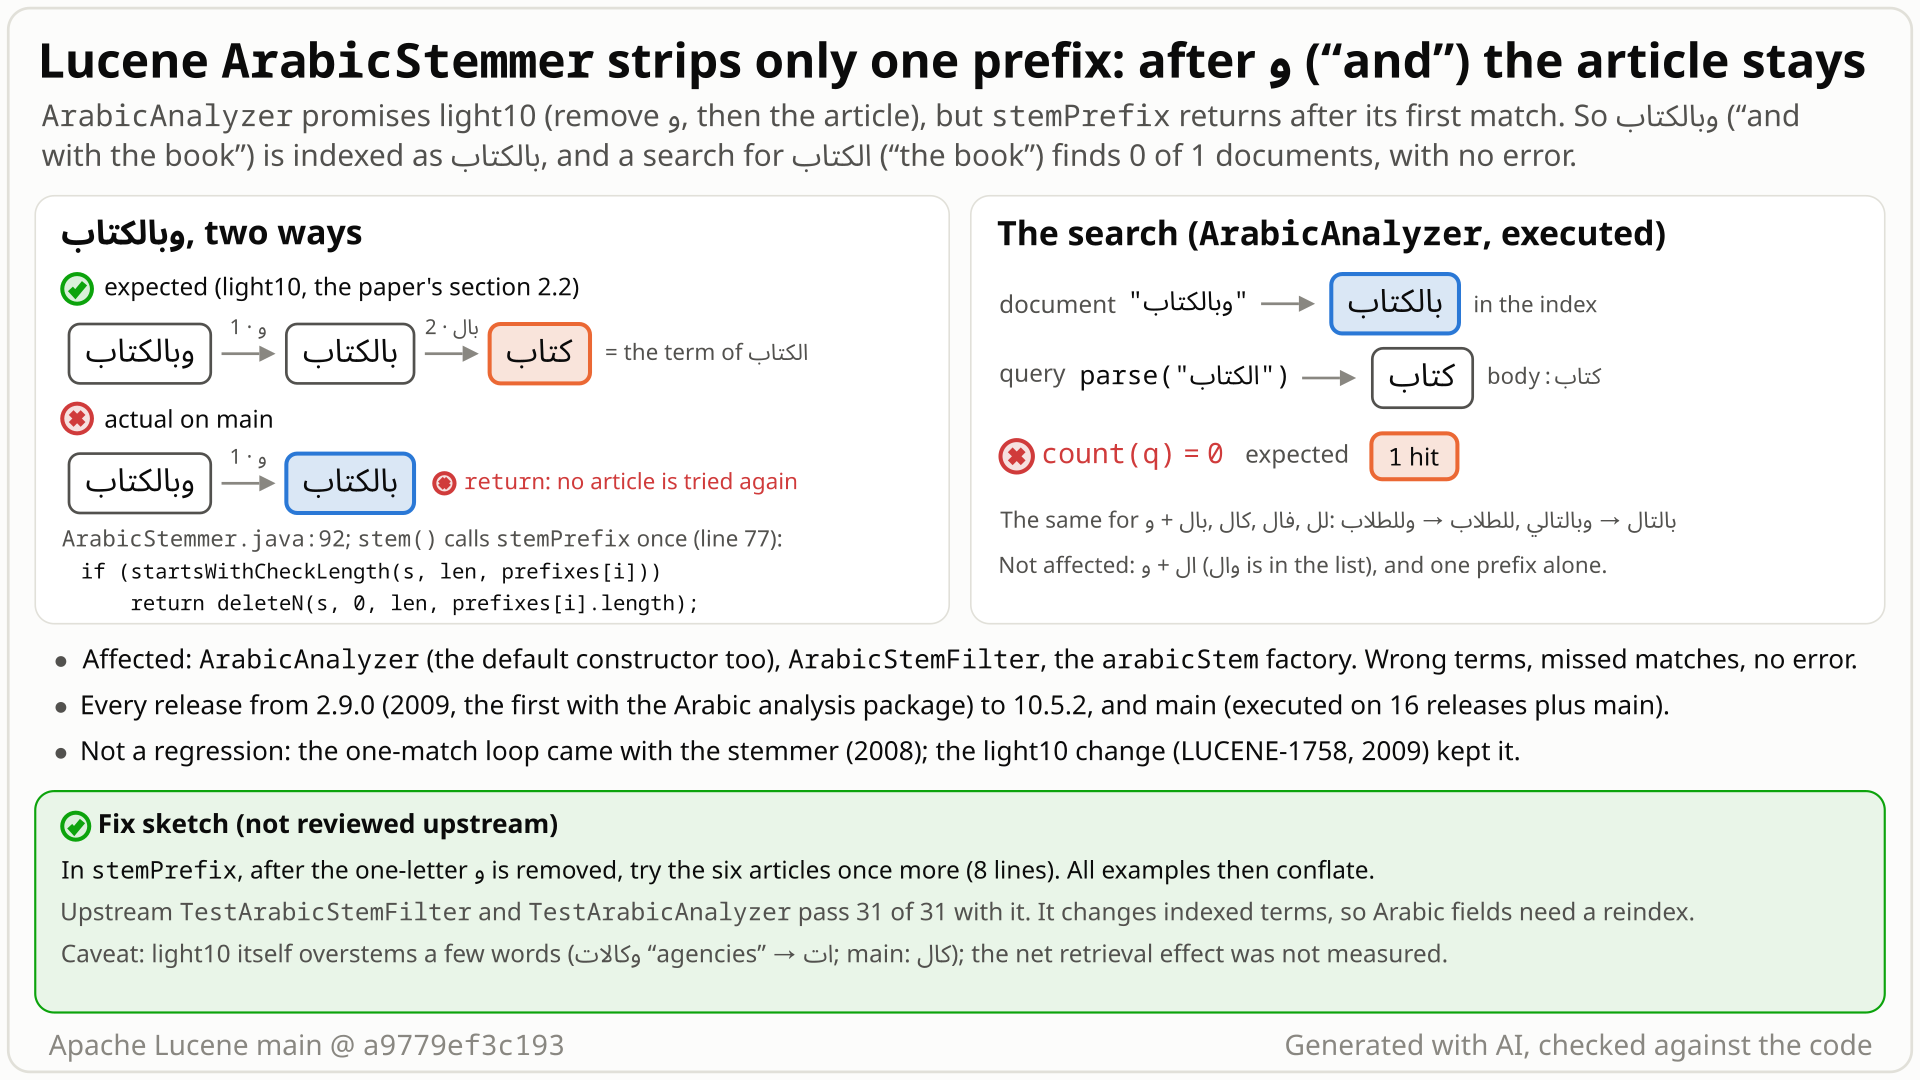
وبالكتاب ("and with the book") two ways: light10 removes و and then بال and gets كتاب; Lucene's stemPrefix returns after removing و and indexes بالكتاب, so a search for الكتاب ("the book") finds 0 of 1 documents. Select the still to open it at full size. Generated with AI, checked against the code.- Index the document
وبالكتاب, "and with the book" (و "and" + بال "with the" + كتاب "book"), with the stocknew ArabicAnalyzer(). Its javadoc says it stems "as specified by" the light10 paper. - Light10 runs ordered steps: remove a leading و if 3 or more letters remain, then one article (ال, وال, بال, كال, فال, لل) if 2 or more remain, then suffixes. You expect
كتاب, the same term asالكتاب("the book") andبالكتاب. - You get
بالكتاب.ArabicStemmer.stemPrefixkeeps the six articles and the و in one list, tried in order, and returns after the first match: it removes the و and never triesبالon the rest. - A
TermQueryfor the analyzedالكتاب(body:كتاب) finds 0 of 1 documents, with no error. The same happens for و + لل, كال and فال, and for real words such asوبالتالي("and therefore") becomesبالتالinstead ofتال. - Only و + ال works, because
والis in the list itself. The code is the same in every release from 2.9.0 (2009) to 10.5.2 and on main.
Everyone who indexes or searches Arabic text with the stock ArabicAnalyzer, ArabicStemFilter or the arabicStem factory. Real words such as وبالتالي, وبالنسبة and وللمرة always get a different term than light10 gives; a hit is missed when query and document use different forms of the word. There is no error; the net effect on ranking quality was not measured.
Mechanism, terms and numbers789 words
ArabicAnalyzer's javadoc says it "implements light-stemming as specified by: Light Stemming for Arabic Information Retrieval" (ArabicAnalyzer.java:38-39). Section 2.2 of that paper runs ordered steps: 1) remove a leading و ("and") if 3 or more characters remain, 2) remove one definite article (ال, وال, بال, كال, فال, لل) if 2 or more remain, 3) go through the suffixes once. ArabicStemmer.stemPrefix instead scans one array, the six articles followed by و (ArabicStemmer.java:46-54), and returns after the first match (:90-94); stem() calls it once (:76-81). So once it removes the و it never tries the articles on the rest: وبالكتاب ("and with the book") is indexed as بالكتاب instead of كتاب, the term of الكتاب and بالكتاب, and the same for و + لل, كال and فال (وللطلاب becomes للطلاب, وبالتالي becomes بالتال). A TermQuery for the analyzed الكتاب then finds 0 of 1 documents that contain only وبالكتاب, with no error. و + ال is unaffected because وال is in the array itself. The single-return loop came with the class (LUCENE-1406, 2008) and was kept when it moved to light10 (LUCENE-1758, 2009), so every release from 2.9.0 to 10.5.2 and main has it. The fix tries the articles again after removing the one-letter و; it changes indexed terms (reindex note needed) and also brings light10's own overstemming for a few words, so no retrieval gain is claimed.
- Light stemming: removing a few frequent prefixes and suffixes without a dictionary, so that
الكتاب("the book"),بالكتاب("with the book") andوبالكتاب("and with the book") all get the index termكتاب("book"). - The prefixes: the conjunction و (wa-, "and") and the definite articles ال (al-, "the"), وال (wa + al-), بال (bi-l-, "with the"), كال (ka-l-, "like the"), فال (fa-l-, "so the"), لل (li-l-, "for the"). They are written joined to the word, and و can come before one of the others.
- light10: the stemmer of Larkey, Ballesteros and Connell, "Light Stemming for Arabic Information Retrieval", which
ArabicAnalyzercites. Section 2.2 (page 13 of the paper): "1. Remove و (\"and\") ... if the remainder of the word is 3 or more characters long. ... 2. Remove any of the definite articles if this leaves 2 or more characters. 3. Go through the list of suffixes once ...".
ArabicStemmer.prefixesis one array:ال, وال, بال, كال, فال, لل, و, with و last (ArabicStemmer.java:46-54).stemPrefixtries the entries in order andreturnsdeleteN(...)on the first that matches (:90-94).stem()calls it once, then the suffixes (:76-81).- For
وبالكتابnone of the six articles matches (the word starts with و and then ب, so evenوالfails at its second letter); و matches and is removed, and the method returnsبالكتاب.بالwould match now (7 characters, it needs 5), but nothing tries it again. - The length rules (
:118-132: و needs 4 or more characters, the others their length + 2) are exactly the paper's 3 and 2 remaining characters; only the order of steps 1 and 2 was lost when they were folded into one list. ArabicStemFilterapplies the stemmer to every non-keyword token (ArabicStemFilter.java:44-55);ArabicAnalyzerends its chain with it (ArabicAnalyzer.java:131-142); the SPI factoryarabicStemcreates the same filter.- A double و before
وال(ووال...) is hit the same way, becauseوالno longer matches at position 0. Words too short for light10's length rules (for example و + بال + one letter) come out the same either way; in the follow-up's probe, 70 of 148,795 waw+article-shaped words are unchanged by the fix.
| input | light10 (and main with the fix) | main |
|---|---|---|
الكتاب, بالكتاب, والكتاب, وكتاب (controls) | كتاب | كتاب |
وبالكتاب (و + بال, "and with the book") | كتاب | بالكتاب |
وللطلاب (و + لل, "and for the students") | طلاب | للطلاب |
وكالبحر (و + كال, "and like the sea") | بحر | كالبحر |
وبالتالي ("and therefore") | تال | بالتال |
وبالنسبة | نسب | بالنسب |
وللمرة | مر | للمر |
ArabicAnalyzer("الكتاب بالكتاب وبالكتاب") | [كتاب, كتاب, كتاب] | [كتاب, كتاب, بالكتاب] |
one document وبالكتاب, TermQuery on the analyzed الكتاب | 1 hit | 0 hits |
The rows for وبالتالي, وبالنسبة and وللمرة come from a probe through the default ArabicAnalyzer, and the fact check's probe through ArabicStemFilter alone gives the same terms; the other word rows ran through ArabicStemFilter.
When the query text goes through the same analyzer (for example a query parser over ArabicAnalyzer), the miss goes both ways: the query وبالكتاب gives بالكتاب and misses documents that say الكتاب or بالكتاب. A TermQuery built from a raw string is not analyzed, and ArabicAnalyzer.normalize() does not stem.
Exposure and likelihood362 words
- Who is exposed. Applications that analyze Arabic text with the stock
ArabicAnalyzer(the default constructor included,ArabicAnalyzer.java:96-98),ArabicStemFilterdirectly, or thearabicStemfactory (for example in aCustomAnalyzer). No option turns the behaviour on or off. Tokens marked as keywords (for example by the analyzer's stem exclusion set) are not stemmed, and stopwords are removed before the stemmer. - Not affected. و + ال (
والكتاب), any single prefix alone, words without a leading و, words too short for light10's length rules, and the separate Snowball Arabic stemmer. - What triggers it. Real words of the shape و + بال, كال, فال or لل ("and with the", "and like the", "and so the", "and for the"), for example
وبالتالي("and therefore"),وبالنسبة,وللمرة, and a double و beforeوال. It is deterministic, at index time and, when the query is analyzed the same way, at query time, and needs no size or setting. How often these words occur in real text was not measured. - What the damage looks like. Mostly missed matches between a waw+article form and the other forms of the same word, inside each document's own field: the document
وبالكتابis not found byالكتابorبالكتاب, and the queryوبالكتابmisses them; much less often, extra conflations that light10 would not make (see the next point). No exception and no term longer than its input: a probe over 411,089 words on main (assertions on and off) found neither. The work per token stays a fixed handful of comparisons (from the code), and the index is not damaged. - Scale, honestly. Over that bounded, mostly constructed word set the stock stemmer loses 19,859,718 same-stem pairs that light10 would make and keeps 240,799 that light10 would not; over 29 real words it loses 18 pairs and keeps 2 (one right,
وكالة/وكالات; one spurious,وبالون/بال). These are counts over a constructed set, not corpus frequencies, and the net retrieval effect of a fix was not measured. - Existing indexes keep the old terms until reindexed; after a fix, new query terms and old documents disagree for these words until the field is reindexed.
The test shows that ArabicStemFilter removes the conjunction waw from وبالكتاب ("and with the book") but then not the article بال, unlike light10 (waw first, then the article).
package org.apache.lucene.analysis.ar;

import java.io.StringReader;
import org.apache.lucene.analysis.Tokenizer;
import org.apache.lucene.analysis.core.KeywordTokenizer;
import org.apache.lucene.tests.analysis.BaseTokenStreamTestCase;

public class TestArabicWawThenArticle extends BaseTokenStreamTestCase {

  public void testWawThenArticle() throws Exception {
    Tokenizer tokenizer = new KeywordTokenizer();
    tokenizer.setReader(new StringReader("وبالكتاب"));
    // light10 removes the waw, then the article: expected كتاب, actual بالكتاب
    assertTokenStreamContents(new ArabicStemFilter(tokenizer), new String[] {"كتاب"});
  }
}
# in a copy of this finding's repro folder (repro/LFV-665/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.ar.TestArabicWawThenArticle
- Expected vs actual
- Expected كتاب; actual بالكتاب (
term 0 expected:<[]كتاب> but was:<[بال]كتاب>), with-eaand-da.
More files, environment, full output38 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: term 0 expected:<[]كتاب> but was:<[بال]كتاب>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:262)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:513)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:598)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:622)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:689)
org.apache.lucene.analysis.ar.TestArabicWawThenArticle.testWawThenArticle(TestArabicWawThenArticle.java:14)ArabicAnalyzersays it stems "as specified by" the light10 paper, whose steps remove و first, then an article.- The light10 code the authors' lab distributed does the same with Lucene's tables: a 10-million-word diff finds 6,072 differences, all و + article, and 0 with the fix.
- No test, comment or discussion calls stopping after و deliberate.
The full argument443 words
- The analyzer's contract.
ArabicAnalyzer.java:38-39: "This analyzer implements light-stemming as specified by: <i> Light Stemming for Arabic Information Retrieval </i>" (the PDF URL after it is dead). - CHANGES of the light10 change (LUCENE-1758,
820620f3a72, 2009, the whole entry): "ArabicAnalyzer now uses the light10 algorithm, has a refined default stopword list, and lowercases non-Arabic text. You'll need to fully re-index any previously created indexes. This isn't a break in back-compatibility because ArabicAnalyzer has not yet been released. (Robert Muir)" - The stemmer's javadoc defines stemming as "Removal of attached definite article, conjunction, and prepositions" (
ArabicStemmer.java:26-29). - The paper, section 2.2 (page 13): "We tried several versions of light stemming, all of which followed the same steps: 1. Remove و (\"and\") for light2, light3, and light8, and light10 if the remainder of the word is 3 or more characters long. ... 2. Remove any of the definite articles if this leaves 2 or more characters. 3. Go through the list of suffixes once ...". Lucene's length rules are exactly these 3 and 2 characters. Its Table 1 (page 14) lists the light10 "prefixes" as ال, وال, بال, كال, فال, لل, و, the same strings in the same order as
ArabicStemmer.java:46-54. - The lab's distributed code. The Lemur Toolkit's
arabic_light10(University of Massachusetts) does "Remove waw (advance pointer) if remainder >= 3 chars", then "Remove definite article if remainder >=2 chars", then the suffixes; its article and suffix tables equal Lucene's. A diff of Lucene against a Java port of its stemming steps (Lemur's normalization and stopword steps left out, asArabicStemFilterdoes neither), every word up to 6 letters over 13 letters plus 5 million random longer words (10,229,043 words), finds 6,072 differences, every one و followed by an article, and 0 with the fix. It is the light10 code the lab distributed, not necessarily the code of the paper's experiments (which ran on an in-house engine). - The original author's aim (LUCENE-1406, #2480): "the major motivation for implementing it exactly the way it is presented in the paper is that the algorithm is TREC-tested".
- Tests.
TestArabicStemFilterchecks each prefix alone (والحسن,بالحسن,كالحسن,فالحسن,للاخر,وحسن), و plus suffixes and two suffixes; none has و followed by an article other thanوال, and none asserts that such an article is kept. - History. Neither LUCENE-1406 nor LUCENE-1758 discusses stopping after one prefix; no CHANGES or MIGRATE entry mentions it. (The 2008 light8 code cited an earlier paper by the same authors, "Improving Stemming for Arabic Information Retrieval: Light Stemming and Co-occurrence Analysis" (2002), which was not checked here; the light10 paper says light8 followed the same steps.)
The devil's-advocate check242 words
The intended-behaviour checks built the strongest case for "works as designed" (rated moderate by the cross-model reviewer): the helper's javadoc says "Stem a prefix off" (singular) while the suffix helper says "Stem suffix(es) off"; the array copies the paper's Table 1 column, which lists و next to the articles and also وال, so "remove one Table 1 prefix" is a possible reading; the output has been stable since 2009 with no report; a fix forces a reindex; on LUCENE-8028 a committer asked to be conservative about changing the default; ArabicStemmer is package-private and ArabicStemFilter only promises to "apply" it; and the fix brings light10's own overstemming (وكالات, "agencies", becomes ات instead of كال).
Why it fails: the public contract is the analyzer's "as specified by" and the CHANGES "now uses the light10 algorithm", and the paper's steps are explicitly separate and ordered. The lab's own light10 code keeps وال in its article table and still removes و first, so the Table 1 reading does not hold. The original author said they followed the paper "exactly", and the length rules do. Nothing records stopping after و as a decision. The reindex cost and the overstemming are real, but they are a compatibility and quality decision for maintainers, not evidence that the current output is the documented one; the overstemming is the paper's own behaviour, and stock already overstems the same way without the و (بالون gives ون).
Recommended After removing و, try the articles once more
After stemPrefix removes the one-letter و, try the six articles once more (+15/-2 in ArabicStemmer.java). With it the repro passes and the module's full check passes (1,915 tests). Indexed terms change, so the CHANGES entry needs a reindex note, and a few words overstem as light10 does (وكالات becomes ات).
All options and trade-offs4 options · 777 words
Two equivalent code fixes were validated (A through gradle and the module's check, B with the standalone runner); C and D are the alternatives a maintainer may prefer.
In ArabicStemmer.stemPrefix, when the matched prefix is the one-letter و, try the six articles on the rest before returning (+15/-2 as formatted by tidy; the same logic as the finder's +9/-1 sketch). A regression test: the repro's class, or its cases added to TestArabicStemFilter.
int stemPrefix(char[] s, int len) {
  for (int i = 0; i < prefixes.length; i++) {
    if (startsWithCheckLength(s, len, prefixes[i])) {
      len = deleteN(s, 0, len, prefixes[i].length);
      // light10 removes the conjunction waw (step 1) before a definite article (step 2):
      // after removing waw, try the articles once more
      if (prefixes[i].length == 1) {
        for (int j = 0; j < prefixes.length - 1; j++) {
          if (startsWithCheckLength(s, len, prefixes[j])) {
            return deleteN(s, 0, len, prefixes[j].length);
          }
        }
      }
      return len;
    }
  }
  return len;
}
Trade-offs
- Changes indexed terms for waw+article words long enough for light10's length rules: the CHANGES entry should advise reindexing fields analyzed with
ArabicAnalyzer,ArabicStemFilterorarabicStem; it suits main (11.0). (LUCENE-1758's reindex note of 2009 is no precedent: it came before the analyzer's first release.) - Brings light10's own overstemming where the و is a root letter followed by letters that look like an article:
وكالات("agencies") becomesاتinstead ofكال, so it no longer conflates withوكالة("agency",كالon both);وبالونbecomesون, asبالونalready does on stock, instead ofبال. That is the paper's behaviour; no retrieval gain is claimed. - Relies on و being the only one-letter entry and the last one in
prefixes, and on every entry before it being a light10 article (true today,ArabicStemmer.java:46-53). - Cost: at most 6 more 2-3-character comparisons and one more in-place shift for a token that starts with و.
What the checks validated
- Scratch worktree at
a9779ef3c193, gradle, JDK 25: the new test fails 5 of 6 on stock and passes 6 of 6 with the fix; the 5 Arabic suites pass 56 of 56 with assertions on and off (TestArabicStemFilter 23, TestArabicNormalizationFilter 15, TestArabicAnalyzer 8, TestArabicFilters 4, the new 6);:lucene:analysis:common:checkpasses: checkGoogleJavaFormat, ecjLint, forbiddenApis and the whole module's tests (340 suites, 1,915 tests, 0 failed, 18 skipped). - An exhaustive diff against a light10 reference written from the paper (every word up to 6 letters over 13 letters, 5,229,042 words): 0 mismatches with the fix, 3,042 on stock. The diff against the lab's code port (10.2 million words) gave 0 with the finder's equivalent sketch.
Step 1: if the word starts with و and has 4 or more characters, remove it. Step 2: try the six articles once (+10/-2).
int stemPrefix(char[] s, int len) {
  // light10 step 1: remove the conjunction waw if 3 or more characters remain
  if (len >= 4 && s[0] == WAW) {
    len = deleteN(s, 0, len, 1);
  }
  // light10 step 2: remove one definite article if 2 or more characters remain
  for (int i = 0; i < prefixes.length - 1; i++) {
    if (startsWithCheckLength(s, len, prefixes[i])) {
      return deleteN(s, 0, len, prefixes[i].length);
    }
  }
  return len;
}
Trade-offs
Reads like the paper and gives the same output as A on the tested space (for a word that starts with وال, removing و and then ال removes the same 3 characters as وال alone, under the same length rules). It still loops to prefixes.length - 1, so it relies on و staying the last entry; moving و out of the array would be cleaner but touches more lines. Same reindex and overstemming notes as A.
What the checks validated
The doc's test 6 of 6 and the upstream TestArabicStemFilter, TestArabicAnalyzer and TestArabicFilters 35 of 35 with it on the classpath; the exhaustive diff (5,229,042 words) finds 0 mismatches. Not run through gradle tidy or check.
Say in the ArabicAnalyzer and ArabicStemmer javadocs that at most one prefix is removed, so و + بال, كال, فال, لل keep the article.
Trade-offs
No reindex, but the analyzer would no longer implement the algorithm it cites, and the missed matches stay.
Keep the default and add a switch (a constructor flag on ArabicStemFilter, a factory parameter). Not built.
Trade-offs
Avoids silent term changes for existing indexes, but adds API surface for what the docs already promise, and the default stays different from light10.
A bounded-exhaustive check ran the stock ArabicStemFilter and an independent reference written from section 2.2 of the cited paper over 408,800 constructed words. They differed on 119,138, every one a و before an article, and on none with the fix. The finder then reduced it to a public-API test and read the code and its history.
The method in full178 words
Method: bounded-exhaustive differential checking against a reference written from the published rules (the study's "semi-formal" tier). Hunt unit "light stemmers against their published rules", 2026-10-27, main a9779ef3c193.
- The reference implements light10 steps 1-3 from section 2.2 of the paper that
ArabicAnalyzercites, independently of Lucene's code. - Word space: 14 prefix chains x 2,380 stems (length 0 to 3 over 13 letters: the 11 letters of the affix tables plus 2 neutral letters, د and س) x 13 suffix chains = 433,160 combinations, which the harness deduplicates to 408,800 distinct words, each run through the stock
ArabicStemFilterand the reference. - Result: 119,138 mismatches, every one with a و before an article (و + بال, كال, فال, لل: 4 x 29,744; a double و before وال: 162); 0 mismatches with the fix sketch on the classpath.
- An AI finder then wrote the public-API JUnit and traced the cause in
stemPrefixand the git history; independent AI tools reproduced it, built their own exhaustive diffs (one against the light10 code the authors' lab distributed) and judged it (see the checks).
No prior report: 134 scripted prior-report search queries in two runs (GitHub, mailing lists, JIRA, the web in English and Arabic) plus manual searches (2026-10-27); the final run's 565 hits include none of this bug. Related: LUCENE-8028 / lucene-solr PR #274, an unmerged opt-in stemmer whose own table covers و + article; it never calls the default stemmer wrong.
Searches5 searches
No report of this defect was found. The closest item is related work: a maintainer may answer "use or revive that stemmer".
| Where | When | How | Found |
|---|---|---|---|
| scripted prior-report search (two runs) | 2026-10-27 | 51 and 83 queries: GitHub issues, PRs and commits, downstream projects, the dev, java-user, issues and commits lists, JIRA and 8 web queries in English and Arabic | final run: 565 distinct hits, 0 high, 20 medium; none reports this bug |
| GitHub (manual) | 2026-10-27 | apache/lucene "arabic" (all 59 titles read), ArabicStemmer, ArabicStemFilter, ArabicAnalyzer, open and closed PRs; apache/lucene-solr; Elasticsearch, OpenSearch, Solr, Lucene.NET; all of GitHub; the trackers of two ports | no report; no open PR changes stemPrefix |
| JIRA archive and mailing lists | 2026-10-27 | LUCENE and SOLR (arabic, waw, prefix, ArabicStemmer); java-user@, dev@, solr-user@, users@solr (four Arabic threads read in full) | no report |
| Related items (read) | 2026-10-27 | LUCENE-8028 / #9076 and lucene-solr PR #274; LUCENE-1406 / #2480; LUCENE-1758 / #2832; tomoya55/ar-stemmer#4 | a separate opt-in stemmer whose table covers و + article, never calling the default wrong; a 2008 remark that light8 misses "many common 'prefix'/suffix combinations", naming no waw+article case; the light10 change; another contributor's port that stopped looping over prefixes because it overstemmed |
| History | 2026-10-27 | git log on ArabicStemmer.java and TestArabicStemFilter.java; lucene/CHANGES.txt on main | no behaviour change to stemPrefix since 2009 |
Introduced with the class by LUCENE-1406 (8dfe073760c, 2008-10-20) and kept by the light10 change LUCENE-1758 (820620f3a72, 2009-08-05), both before the first release, 2.9.0; never changed since. It fails on 16 releases from 2.9.0 to 10.5.2 and on main; 2.4.1 has no Arabic package.
Versions tested7 rows
Introduced by 8dfe073760c (LUCENE-1406, #2480; patch by rmuir, committed by gsingers as svn r706342, 2008-10-20), light8: stem() calls stemPrefix() once and it returns after the first match; the loop is already in the contributor's patch. From then on و + بال, كال and فال keep their article. 820620f3a72 (LUCENE-1758, #2832, rmuir, 2009-08-05) moved to light10: it added the لل entry just before و, the light10 javadoc and the CHANGES line, and left the loop alone, so و + لل is affected too.
Both landed before 2.9.0 (2009-09-24), the first release with the Arabic package, so no release ever shipped a different variant. Later commits on these lines (LUCENE-2503 rename, LUCENE-9570 reformat, LUCENE-10003 array syntax, LUCENE-10561 visibility) keep the behaviour. All 136 release tags in the history clone that contain the light10 commit have the same code; upstream main a95c754ee003 (read 2026-10-27) still has it.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's test 5 of 6 fail (gradle and the standalone runner, assertions on and off); the finder's test 2 of 3; the stemmer and filter probes 4 of 4 |
| 10.5.2, 9.12.3 | affected | this doc's test 5 of 6 fail; the finder's test 2 of 3; the probes 4 of 4 |
| 9.1.0, 10.0.0 | affected | the finder's test 2 of 3 fail (10.0.0 also the stemmer probe) |
| 3.0.3, 3.1.0, 3.6.2, 4.0.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0 | affected | the stemmer probe (4 controls; not on 3.1.0) and/or the public filter probe (3 controls; 3.1.0, 3.6.2, 4.10.4 to 8.11.4): 4 of 4 waw+article words keep the article in each run, the controls stem |
| 2.9.0, 2.9.4 | affected | the stemmer probe: 4 of 4; the 2.9 filter probe (2 controls, 2 waw+article words): 2 of 2, and ArabicAnalyzer gives [كتاب, كتاب, بالكتاب] |
| 2.4.1 | no API | no Arabic package: the probe does not compile |
| main with the fix | fix | this doc's test 6 of 6 and the probes pass |
An independent reproducer, a devil's advocate and an adjudication found it real and re-ran it on main with assertions on and off; two executed reviews by another model family agreed (real, high). A later audit and this doc re-ran it, the doc through gradle with the fix and the module's full check.
Checks and verdicts517 words
Each check wrote or ran its own tests against the stock jars at a9779ef3c193 (the cross-model reviews read ea57360912ed, whose analysis sources are identical, and their test was re-run on a9779ef3c193).
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Exhaustive diff against the paper's steps (408,800 words, 119,138 mismatches, all و + article); JUnit fails 2 of 3 on main (on and off), 10.5.2 and 9.12.3; passes with the fix; upstream Arabic tests 31 of 31 with it. |
| Independent reproducer | real | Own JUnit written from the claim only: 5 of 6 fail on main (on and off), 10.5.2 and 9.12.3, including the 0-hit search; 6 of 6 with the fix. Own exhaustive diff (5.2 million words): 3,042 mismatches, all و + article, 0 with the fix. This doc's test is based on it. |
| cross-model review, refute lens | real (high) | An independent reviewer from another model family (OpenAI GPT-5.6, executed mode) wrote its own test (وبالصقر gives بالصقر): fails 2 of 3 with assertions on and off and over 3 iterations, passes with the fix; root cause agreed. |
| cross-model review, intended lens | real (high) | Built the works-as-designed case (singular javadoc, one-at-a-time tests, stable output, reindex cost) and rated it moderate; rejected because the analyzer's javadoc and CHANGES promise the paper's light10. |
| The cross-model review re-runs | reproduced | The reviewer's test re-run on a9779ef3c193 (assertions on and off), 10.5.2 and 9.12.3: 2 of 3 fail; 3 of 3 pass with the fix. |
| Devil's advocate | real (high) | Read the lab's light10 code: و first, then the article, with Lucene's tables; a diff against a port of it (10.2 million words) finds 6,072 mismatches, all و + article, 0 with the fix. Flagged the overstemming and LUCENE-8028. |
| adjudication | confirmed (high) | Re-ran the independent reproduction's test: 5 of 6 fail with assertions on and off, 6 of 6 with the fix; read section 2.2 and the lab's code; duplicate of none; framing and reindex caveats. |
| Follow-up | new, security none | History runs on 16 releases plus main, prior-report search (new), security probe (411,089 words, no exception, no term longer than its input). |
| audit 4 | keep | Re-ran the finder's test with a fresh seed: 2 of 3 fail with assertions on and off; code, paper and the lab's code re-read; impact kept. |
| this doc | reproduced, fix validated | The doc's test through gradle on stock (5 of 6 fail, on and off) and with fix A (6 of 6); the module's full check with fix A (1,915 tests pass); the standalone runner on main, 10.5.2, 9.12.3 and both fixes. |
| fact checks of this doc | reproduced; corrections applied | An independent fact check re-ran the doc's gradle command (5 of 6 fail, assertions on and off), fix A with the module's check (1,915 tests pass) and the standalone runner on main, 10.5.2 and 9.12.3 with assertions on and off. A second one, by another model family (OpenAI GPT-5.6, read-only), re-read the sources and logs. Both found the bug as described; their counting, quoting and wording corrections are applied. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 454 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,409 words
- Registry title
- ArabicStemmer removes at most one prefix, so after it strips the conjunction waw it never strips the article that follows (wa+bi-al-, wa+li-l-, wa+ka-al-, wa+fa-al-), unlike the light10 algorithm ArabicAnalyzer documents
- Area
- analysis-common / Arabic light stemmer (ArabicStemmer.stemPrefix; ArabicStemFilter, ArabicAnalyzer and the 'arabicStem' factory)
- Priority
- Low, rank 293: A one-language stemming-quality gap unreported since 2.9.0, whose fix changes indexed terms and has an unmeasured net effect, so it is not urgent.
- Impact class
- silent wrong results
- Impact note
- Missed matches (plus a few accidental extra conflations), with no error: every application that indexes or queries Arabic text through ArabicAnalyzer (default constructor included), ArabicStemFilter or the 'arabicStem' factory, on every release from 2.9.0 through 10.5.2 and on main, gets the article form instead of the stem for words that start with the conjunction waw followed by bi-al-, li-l-, ka-al- or fa-al- (for example 'and with the book' is indexed as 'with-the-book', not 'book'), so a search for 'the book' misses a document that only contains 'and with the book'; wa+al- is not affected, no scale is needed, the result is the same with -ea and -da, the net retrieval effect of a fix was not measured (the paper-faithful fix also overstems a few words), and because a fix changes indexed terms, affected fields need reindexing after it.
- Summary
- You index Arabic text with the stock ArabicAnalyzer, whose javadoc says it implements light stemming 'as specified by' the light10 paper; that paper removes a leading waw ('and') first and then a definite article, so 'وبالكتاب' ('and with the book') should stem to 'كتاب' ('book'), like 'الكتاب' and 'بالكتاب'. Instead ArabicStemmer.stemPrefix scans one list (the six articles, then waw) and returns after the first match, so once it has removed the waw it never tries the articles: 'وبالكتاب' becomes 'بالكتاب' and 'وللطلاب' becomes 'للطلاب'. A TermQuery for the analyzed form of 'الكتاب' then finds 0 of 1 documents that contain only 'وبالكتاب', with no error.
- Introduced
- 8dfe073760c5f97a980390ae5daad3a881fd7730 (LUCENE-1406 'new Arabic Analyzer (Apache license)', GitHub #2480; patch by rmuir, committed by gsingers as svn r706342, 2008-10-20) [read: history clone, git log -L on stemPrefix, and the contributor's LUCENE-1406.patch, which already has the single-return loop]: stem() calls stemPrefix() once and stemPrefix() returns after the first match in one list {al, wal, bal, kal, fal, waw}, so wa+bal-, wa+kal- and wa+fal- keep their article from this commit on. 820620f3a7224c6416d001984570897682112676 (LUCENE-1758 'improve arabic analyzer: light8 -> light10', GitHub #2832, rmuir, 2009-08-05) added the lil- entry just before waw, the light10 javadoc citation and the CHANGES line 'ArabicAnalyzer now uses the light10 algorithm', without changing the loop, so wa+lil- is affected from then on. Not a regression: later commits on these lines (3241eb9291c LUCENE-2503 rename, 6faa4f98e04 LUCENE-9570 reformat, 8ac26737913 LUCENE-10003 array syntax, 694d797526a LUCENE-10561 visibility) preserve behaviour. (2008-10-20 (light10 contract and the lil- entry 2009-08-05; first released 2009-09-24 in 2.9.0))
- First affected version
- 2.9.0 [exec] (tag releases/lucene/2.9.0, 2009-09-24, the first release with the org.apache.lucene.analysis.ar package; it contains both commits). The last release before it, 2.4.1, has no Arabic package [exec: the probe does not compile, class ArabicStemmer not found], so no release ever shipped a different variant.
- Affected versions
- Every release that ships the Arabic analysis API, 2.9.0 through 10.5.2, and main a9779ef3c193; not fixed. [exec] a same-package stemmer probe, a public ArabicStemFilter/ArabicAnalyzer probe, or both (4 of 4 waw+article words keep the article, 4 controls stemmed) fail on 2.9.0, 2.9.4, 3.0.3, 3.1.0, 3.6.2, 4.0.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main, and the stemmer probe passes on main with the fix shadowed; the finder's JUnit fails 2 of 3 on 9.1.0, 9.12.3, 10.0.0, 10.5.2 (-ea and -da) and main (-ea and -da). [read] all 136 release tags in the history clone that contain 820620f3a72 have the same prefix list, stem() and stemPrefix() bodies and length rules (the 8.9-8.11.x tags are missing from the clone; 8.11.4 was executed); upstream main a95c754ee003 still has the single-return stemPrefix (read 2026-10-27).
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (searched 2026-10-27, read-only; the prior-report record, verdict new): two scripted prior-report searches (the finder's 51 queries and the follow-up's 83 queries over GitHub issues and PRs, commits, downstream repositories, the dev, java-user, issues and commits lists, JIRA and 8 web queries in English and Arabic; 565 distinct hits, 0 high, 20 medium), manual GitHub searches (apache/lucene 'arabic' with all 59 titles read, ArabicStemmer, ArabicStemFilter, ArabicAnalyzer; apache/lucene-solr; Elasticsearch, OpenSearch, Solr, Lucene.NET; all of GitHub; the trackers of two ports), JIRA (LUCENE, SOLR), the Lucene and Solr user lists, and the file's full git history. No issue, PR, JIRA ticket, list thread, commit or web page reports that ArabicStemmer stops after the waw and keeps the following article, or that it departs from the light10 step order; no open PR changes stemPrefix. Related, not the same bug: LUCENE-8028 / #9076 (open, 2017) and lucene-solr PR #274 (open, never merged) propose a separate, opt-in dictionary-assisted stemmer from other papers whose compound-prefix table includes وبال, وكال, وفال and ولل; neither says the default stemmer departs from light10 (a maintainer asked to keep the default unchanged and add the new stemmer as an option). LUCENE-1406 / #2480 has a 2008 remark by its contributor (rmuir) that 'many common prefix/suffix combinations are not stemmed by light8 algorithm', a coverage remark that names no waw+article case. An outside Ruby port (tomoya55/ar-stemmer#4, 2016) dropped looping over all prefixes because it overstemmed; not about Lucene. Gaps: academic papers that evaluate Lucene's analyzer were not searched exhaustively; some Stack Overflow and blog pages could not be fetched.
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-27) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the release jars 10.5.2 and 9.12.3 (this doc's test); 2.9.0, 2.9.4, 3.0.3, 3.1.0, 3.6.2, 4.0.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.1.0 and 10.0.0 with the follow-up's probes or the finder's test; 2.4.1 (no Arabic package). Fix A was validated in the scratch worktree with the module'schecktask (1,915 tests); fix B with the standalone runner.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/ar/ArabicStemmer.java:21-32 (at a9779ef3c193) (class javadoc: 'Removal of attached definite article, conjunction, and prepositions'), :46-54 (prefixes {ال, وال, بال, كال, فال, لل, و}, waw last), :76-81 (stem(): stemPrefix once, then stemSuffix), :83-94 (stemPrefix: 'Stem a prefix off'; returns deleteN(...) on the first match), :96-108 (stemSuffix goes through the suffix list once), :118-132 (startsWithCheckLength: waw needs len >= 4, the others prefix length + 2)lucene/analysis/common/src/java/org/apache/lucene/analysis/ar/ArabicAnalyzer.java:35-39 (at a9779ef3c193) (javadoc: 'implements light-stemming as specified by: Light Stemming for Arabic Information Retrieval'), :95-98 (default constructor), :130-143 (createComponents: StandardTokenizer, LowerCaseFilter, DecimalDigitFilter, StopFilter, ArabicNormalizationFilter, ArabicStemFilter); lucene/analysis/common/src/java/org/apache/lucene/analysis/ar/ArabicStemFilter.java:26-27, :44-55 (applies ArabicStemmer to every non-keyword token); lucene/analysis/common/src/java/org/apache/lucene/analysis/ar/ArabicStemFilterFactory.java:41 (SPI name 'arabicStem')GitHub, read-only (2026-10-27): apache/lucene #2480 (LUCENE-1406 comments), #9076 (LUCENE-8028 body and comments), apache/lucene-solr PR #274 (description), apache/lucene main a95c754ee003 ArabicStemmer.java (stemPrefix unchanged; last commits 51b3a5baa73e #14804, 694d797526ae LUCENE-10561)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/ar/ArabicStemmer.java:46-54 (at a9779ef3c193) (prefixes), :76-81 (stem), :90-94 (stemPrefix), :103-108 (stemSuffix), :118-132 (startsWithCheckLength)lucene/analysis/common/src/java/org/apache/lucene/analysis/ar/ArabicAnalyzer.java:38-39 (at a9779ef3c193) (javadoc), :131-142 (createComponents), :146-150 (normalize, no stemming); ArabicStemFilter.java:44-55; ArabicStemFilterFactory.java:41, :57-58
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/ar/ArabicAnalyzer.java:96-98 (at a9779ef3c193) (default constructor), :109-119 (stem exclusion set), :131-142 (:136 StopFilter before the stemmer, :139-141 SetKeywordMarkerFilter); ArabicStemFilter.java:47 (keyword tokens skipped); ArabicStemmer.java:90-94 and StemmerUtil.deleteN (work per token)lucene/analysis/common/src/java/org/apache/lucene/analysis/ar/ArabicStemFilterFactory.java:41 (at a9779ef3c193) (SPI name arabicStem); lucene/analysis/common/src/java/org/tartarus/snowball/ext/ArabicStemmer.java (at a9779ef3c193) (separate Snowball stemmer)
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/ar/ArabicAnalyzer.java:38-39; (at a9779ef3c193) ArabicStemmer.java:26-29, :83-94 ('Stem a prefix off'), :96-108 ('Stem suffix(es) off'), :118-132lucene/analysis/common/src/test/org/apache/lucene/analysis/ar/TestArabicStemFilter.java:31-57, (at a9779ef3c193) :99-105
- TestArabicWawThenArticle.java (JUnit test):
repro/LFV-665/src/org/apache/lucene/analysis/ar/TestArabicWawThenArticle.java(16 lines)
A light, step-by-step picture of one concrete example (the document وبالكتاب, the query الكتاب), made in parallel with this doc. Every term, scan result and hit count on screen comes from an executed probe on main a9779ef3c193 (stock and with the fix sketch), and every numbered code line is checked against the code at that commit. The PNG is the final summary card.
assets/LFV-665/bug.png(454 KB)