Sorani's vowel e is AE ە, and the normalizer also folds a word-final HEH ه to it. It deletes invisible formatting characters such as direction marks too, but only after it has already looked at the HEH.
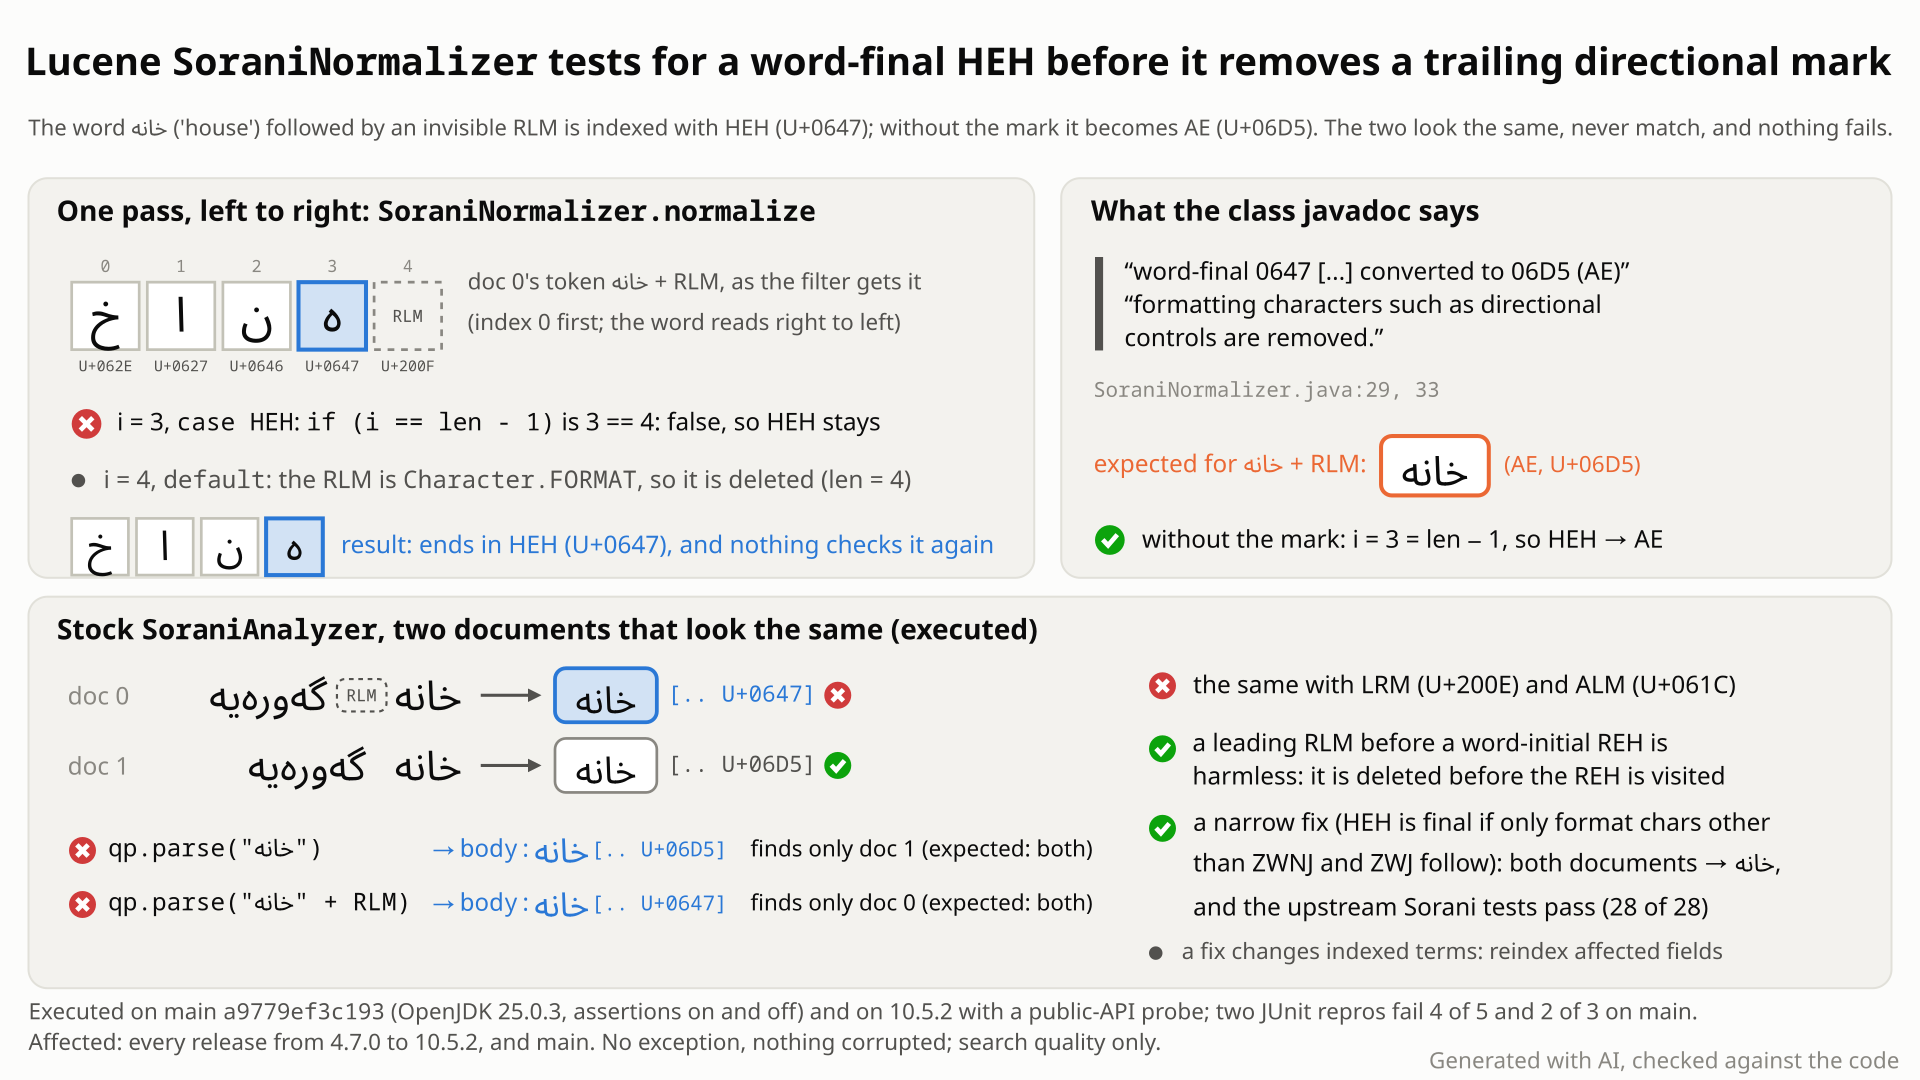
خانه + RLM is walked once, left to right, so its HEH is tested before the mark is deleted, and why two documents that look the same then never match. Select the still to open it at full size. Generated with AI, checked against the code.- Index three documents with
new SoraniAnalyzer()that spell "house" three ways:خانە(AE),خانه(HEH) andخانهfollowed by an invisible right-to-left mark (RLM, U+200F), each followed byگەورەیە("is big"). - The normalizer's own rules say a word-final HEH becomes AE and direction marks are removed, so all three should be indexed as
خانە, and a search forخانەshould find 3 of 3 documents. - It finds 2 of 3. The normalizer walks the word once, left to right. At the HEH it asks "is this the last character?", and the answer is no, because the RLM is still behind it. One step later it deletes the RLM, but it never looks at the HEH again.
- So the marked word is indexed as
خانه(U+0647 at the end), and a query copied with the mark finds only that document, 1 of 3. The same happens with LRM and ALM, at query time (Analyzer.normalize) and after stemming. No error is raised. - It has been like this since the Sorani analyzer was added in 4.7.0 (2014). Treating the HEH as final when only invisible formatting characters (other than ZWNJ and ZWJ) follow it fixes it, and all 30 upstream Sorani tests still pass.
Anyone indexing Sorani Kurdish with SoraniAnalyzer (default constructor included), SoraniNormalizationFilter or the soraniNormalization factory. It needs a word whose final e is typed as HEH with an invisible RLM, LRM or ALM right after it: rare, but silent, at index and query time, and the two spellings then never match.
Mechanism, terms and numbers739 words
Lucene's Sorani normalizer (SoraniNormalizer, used by SoraniNormalizationFilter, SoraniAnalyzer and the soraniNormalization factory) documents two rules that meet here: a word-final HEH (U+0647) is converted to AE (U+06D5), and "formatting characters such as directional controls are removed". It applies them in one left-to-right pass and tests i == len - 1 when it reaches the HEH, while a trailing RLM, LRM or ALM is still in the buffer; the mark is deleted one step later and the HEH, now last, is never converted. StandardTokenizer keeps such a mark inside the token, so the stock analyzer indexes خانه + RLM as خانه and خانه as خانە: the two look the same and do not match each other, at index and query time, with no error. Every release from 4.7.0 (2014) to 10.5.2 and main is affected. A 15-line fix that looks past trailing formatting characters the class deletes (any Character.FORMAT character except ZWNJ and ZWJ) passes the new test and all 30 upstream Sorani tests.
- Sorani normalization:
SoraniNormalizationFilter, andSoraniAnalyzerwhich uses it, runsSoraniNormalizer.normalizeon every token. The class javadoc lists its rules, among them "Alternate forms of vowel 'e' (0647+200C, word-final 0647, 0629) are converted to 06D5 (AE)" and "Harakat, tatweel, and formatting characters such as directional controls are removed." (SoraniNormalizer.java:29,:33). - HEH and AE: AE
ە(U+06D5) is Sorani's letter for the vowel e. At the end of a word the normalizer treats HEHه(U+0647) as the same vowel; the upstream test gives the reason: "always (and in final form by def), so frequently omitted" (TestSoraniNormalizationFilter.java:70-73). - Direction marks: invisible characters such as RLM (U+200F), LRM (U+200E) and ALM (U+061C) that steer the display of mixed left-to-right and right-to-left text. Java classifies them as
Character.FORMAT. They do not change how the HEH joins (Unicode joining type Transparent), soخانه+ RLM looks exactly likeخانه.
normalizewalks the buffer once, left to right, with oneswitchper character (SoraniNormalizer.java:72-128).case HEHconverts the HEH onlyif (i == len - 1): if it is the last character of the buffer at that moment (:89-93).- A trailing mark is still in the buffer then. The
defaultbranch deletes it later, like everyCharacter.FORMATcharacter (:120-124). - For
خانه+ RLM (len = 5): ati = 3the test is3 == 4, false, so the HEH stays; ati = 4the RLM is deleted (len = 4); the resultخانهends in an unconverted HEH. - The class's other position rule is safe: a leading mark is deleted before the REH is visited, so a word-initial REH still becomes RREH (
:100-104). The ZWNJ rule rewrites the HEH before it itself (:82-88). SoraniAnalyzertokenizes withStandardTokenizer, which keeps a trailing format character inside the token (UAX#29 rule WB4,StandardTokenizerImpl.jflex:83-85), and itsnormalize(the query side) applies the same filter (SoraniAnalyzer.java:113-130).
- Filter output for
خانه+ one tail, stock and with the fix: no tail..06D5both; RLM, LRM, ALM, PDF (U+202C), RLO (U+202E), PDI (U+2069):..0647, with the fix..06D5; ZWNJ..06D5both (its own rule); ZWJ, TATWEEL and FATHA..0647both (not claimed: they force a joining form or mark a consonant). SoraniAnalyzer, three documentsخانە گەورەیە(AE spelling),خانه گەورەیە(HEH spelling) and the HEH spelling with an RLM afterخانه: a search forخانەor forخانهfinds 2 of 3; the query copied with the mark finds 1 of 3; with the fix every query finds 3 of 3.- Stemming:
کوردییه("Kurdish") is stemmed to[..06CC 06CC], with a trailing RLM to[..06CC 06CC 0647]. - Exhaustive, all 1,118,481 strings of length 0 to 5 over a 16-character alphabet: within that alphabet the fix changes exactly the 31,420 inputs whose last HEH is followed only by RLM, LRM, ALM, PDF or soft hyphen, and in each only that HEH.
- Every BMP character after
خانه: the fix changes the output (HEH to AE) for exactly 41 characters, theCharacter.FORMATcharacters other than ZWNJ and ZWJ on JDK 25. Besides the direction marks they include U+FEFF, U+200B, U+2060-U+2064, U+206A-U+206F, U+180E, U+FFF9-U+FFFB and the prepended concatenation marks (U+0600-U+0605, U+06DD, U+070F, U+0890, U+0891, U+08E2). None of them is join-causing (ICU: 26 Transparent, 15 Non_Joining).
Exposure and likelihood592 words
- Who is exposed. Applications that index Sorani Kurdish text with
new SoraniAnalyzer()or any other constructor (no option avoids it), withSoraniNormalizationFilterin a custom chain, or with the SPI factorysoraniNormalization(the factory javadoc shows the Solr formsolr.SoraniNormalizationFilterFactory). Downstream servers that ship a built-in Sorani analyzer on this filter, such as Elasticsearch'ssoranianalyzer with itssorani_normalizationfilter, inherit it (read in their documentation; not executed). - Default or opt-in. You opt in by choosing the Sorani analyzer or filter for a field; inside it, this is the default behaviour.
- What triggers it. A word whose final vowel is typed as HEH and whose final HEH is followed only by one or more invisible formatting characters that the class deletes, such as RLM, LRM, ALM, PDF, RLO, PDI or the soft hyphen, with no ZWNJ or ZWJ among them (HEH + RLM + ZWNJ already becomes AE through the ZWNJ rule). Deterministic: every such input, every time; no size or scale is needed.
- Effect. The marked word is indexed and queried as
..0647, the unmarked one as..06D5, so they do not match each other in either direction (a search finds 2 of 3 spellings, a query copied with the mark 1 of 3). The stemmer then sees a different word, so the stemmed terms differ too (کوردییه:[..06CC 06CC]without the mark,[..06CC 06CC 0647]with it). The marked term is one that HEH + TATWEEL or HEH + FATHA already produce, so a query typed with the mark also matches a document whose word ends in HEH + TATWEEL (executed in the follow-up's probe). - Not affected. Words spelled with AE, words without a trailing mark, marks anywhere but directly after a final HEH. No exception, no hang, no extra cost; offsets and positions are consistent and
CheckIndexis clean (the follow-up's probe: 3,000 trigger-dense strings,checkRandomData(200),CheckIndexafterforceMerge(1)). - How likely. Rare. The upstream Sorani vocabulary test file (8,272 rows of frequent corpus words) has 11 words with a trailing direction control (U+202E), none of them after a HEH, and the prior-report searches found no report in the 12 years since 4.7.0.
- Existing indexes and rollout. A fix changes indexed terms of affected words, so those fields need a reindex, and index-time and query-time analysis must change together: with the fixed analyzer at query time only, a query typed with the mark no longer finds the old marked documents, so neither spelling finds them (reasoning).
- Workaround. Until a fix ships, a
patternReplacechar filter that deletes the direction marks in front of the tokenizer gives..06D5and 3 of 3 hits (executed with SPI names throughCustomAnalyzer); it must be in both the index-time and the query-time analyzer. Its pattern leaves out the soft hyphen and the other format characters the fix covers, and the executedCustomAnalyzerhas no stop filter or keyword marker, so it is not the same asSoraniAnalyzer; to keepSoraniAnalyzer(afinalclass), wrap it in anAnalyzerWrapperthat adds the char filter inwrapReaderandwrapReaderForNormalization(not executed). - Unicode versions and older JDKs. JDK 25's
Characterdata is Unicode 16.0,StandardTokenizer's tables are Unicode 12.1, and the joining types here come from ICU (Unicode 17). ALM (U+061C) and the isolates LRI, RLI, FSI and PDI (U+2066-U+2069) were added in Unicode 6.3, after Java 8's Unicode 6.2, so on Java 8 they are not format characters and would stay in the term (not executed); RLM and LRM behave the same on every supported JDK.
The test shows that SoraniNormalizationFilter leaves a word-final HEH (U+0647) unconverted when an invisible RLM (U+200F) follows it: the RLM is removed, but only after the word-final test has already been made.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.ckb;

import org.apache.lucene.tests.analysis.BaseTokenStreamTestCase;

public class TestSoraniFinalHehBeforeRlm extends BaseTokenStreamTestCase {

  public void testFinalHehFollowedByRlm() throws Exception {
    // expected: word-final HEH U+0647 becomes AE U+06D5 and the trailing RLM is removed; actual: HEH
    assertTokenStreamContents(
        new SoraniNormalizationFilter(keywordMockTokenizer("\u062E\u0627\u0646\u0647\u200F")),
        new String[] {"\u062E\u0627\u0646\u06D5"});
  }
}
# in a copy of this finding's repro folder (repro/LFV-668/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.ckb.TestSoraniFinalHehBeforeRlm
- Expected vs actual
- Expected the term U+062E U+0627 U+0646 U+06D5 (AE, as without the mark); actual U+062E U+0627 U+0646 U+0647 (-ea and -da).
More files, environment, full output38 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: term 0 expected:<خان[ە]> but was:<خان[ه]>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:262)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:513)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:598)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:622)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:689)
org.apache.lucene.analysis.ckb.TestSoraniFinalHehBeforeRlm.testFinalHehFollowedByRlm(TestSoraniFinalHehBeforeRlm.java:25)- The class javadoc: "word-final 0647" is converted to AE, and "directional controls are removed" (
SoraniNormalizer.java:29,:33). - Its word-initial rule ignores a removed mark: a leading RLM before REH still gives RREH. Only the trailing case breaks.
- No test keeps HEH before a mark; the upstream vocabulary treats its 11 words with a trailing mark as if it were absent.
The full argument356 words
- The contract. The class javadoc (
SoraniNormalizer.java:21-35): "Alternate forms of vowel 'e' (0647+200C, word-final 0647, 0629) are converted to 06D5 (AE)" (:29) and "Harakat, tatweel, and formatting characters such as directional controls are removed." (:33). The publicSoraniNormalizationFilteris "A TokenFilter that applies SoraniNormalizer to normalize the orthography" (SoraniNormalizationFilter.java:24).SoraniNormalizerwas a public class, with this rule list in its published javadoc, from 4.7.0 to 9.12.x (javap of the 4.7.0 and 9.12.3 jars; Lucene renders javadoc with-protected); it is package-private only since 10.0.0 (LUCENE-10561). The javadoc states no order of operations and no general "removed characters never change the result" rule, so the claim is that this order leaves two documented rules in tension, not that a stated invariant is broken. - The rule's reason.
testFinalH: "always (and in final form by def), so frequently omitted" (TestSoraniNormalizationFilter.java:70-73). The rule is about the final letter form; RLM, LRM, ALM, PDF and RLO have Unicode joining type Transparent (PDI: Non_Joining), so a HEH before them is still drawn in final form. - The class's own symmetry. A leading RLM, LRM, ALM, RLE or TATWEEL before REH still gives word-initial RREH, and the ZWNJ rule looks past a mark (HEH + RLM + ZWNJ gives AE). Only the trailing check runs before the deletion.
- Upstream data. The vocabulary of
TestSoraniStemFilter.testVocabulary(8,272 rows) has 11 words ending in U+202E whose expected output drops the mark and normalizes and stems as if it were absent (none of them ends in a HEH). Of its words ending in a HEH before characters the class removes, 320 end in HEH + ZWNJ (made AE by the ZWNJ rule) and one is HEH + TATWEEL -> HEH, which is not claimed (TATWEEL forces a joining form) and which the fix keeps; none has a HEH before a direction mark. - History. Both rules came in the first commit, in today's order (LUCENE-5379, 2014); the four later commits on the file change only the license header, formatting, array syntax and visibility (package-private from 10.0.0). No test, comment, commit message, CHANGES or MIGRATE entry mentions trailing marks.
The devil's-advocate check296 words
The intended-behaviour checker and the cross-model intended lens (which rated it moderate) built the strongest case: the javadoc is an unordered list of independent rules, and "word-final" can be read literally as "the last character of the token as given"; the upstream vocabulary pins HEH + TATWEEL -> HEH, so a trailing removable character can block the rule on purpose; the class is package-private, so its javadoc is no published contract; the behaviour has been stable for 12 years; and a fix forces a reindex.
The answer: the same class treats removed characters as absent for its word-initial rule and its ZWNJ rule; the stated reason is the final letter form, which the marks do not change, while TATWEEL and ZWJ do, so the pinned row agrees with the narrow claim and the narrow fix keeps it; the class promises to remove direction controls itself and the stock tokenizer hands them over inside the token; the project's own vocabulary expects trailing marks to be ignored; no record supports the literal reading. The package-private point does not hold for most of the bug's life: the class was public, with this list in its published javadoc, from 4.7.0 to 9.12.x; and a reindex is the usual cost of an analyzer fix.
Limits of the answer: the javadoc states no order of operations; the leading-mark case shows what the loop order allows, not what the authors meant for trailing marks; the 11 vocabulary words with a trailing mark do not end in a HEH; no Sorani reference is cited. Verdict: a real, narrow order-of-operations defect, best presented as an inconsistency between two documented rules that appears unintended, with the compatibility cost acknowledged. Do not argue idempotence: it is not documented, and HEH + TATWEEL stays non-idempotent with the fix.
Recommended Treat the HEH as word-final when only formatting characters other than ZWNJ and ZWJ follow it
In SoraniNormalizer, count the HEH as word-final when only formatting characters that the class deletes follow it (any Character.FORMAT character except ZWNJ and ZWJ; +15/-1). Validated with gradle: the new test and all 30 upstream Sorani tests pass, assertions on and off, plus format and lint checks. Affected fields need a reindex.
static final char ZWJ = '\u200D';                      // new constant
case HEH:
  if (isWordFinal(s, i, len)) {                       // was: if (i == len - 1)
    s[i] = AE;
  }
  break;
private static boolean isWordFinal(char[] s, int pos, int len) {
  for (int i = pos + 1; i < len; i++) {
    if (s[i] == ZWNJ || s[i] == ZWJ || Character.getType(s[i]) != Character.FORMAT) {
      return false;
    }
  }
  return true;
}
All options and trade-offs4 options · 1,249 words
Two equivalent fixes were built and validated with gradle in a scratch worktree at a9779ef3c193; A has the same condition as the finder's fix, which every verifier also ran. A wider fix fails the upstream vocabulary. Until a fix ships, a patternReplace char filter that deletes the direction marks in front of the tokenizer works around it (executed: 3 of 3 hits).
Treat the HEH as word-final when only formatting characters other than ZWNJ and ZWJ follow it (validated by the checks) (recommended)
case HEH calls a helper instead of i == len - 1: the HEH is word-final if every character after it is a Character.FORMAT character other than ZWNJ and ZWJ (+15/-1 in SoraniNormalizer.java, with a new ZWJ constant). It tests no Unicode joining property: on JDK 25 it admits 41 BMP characters, every format character the class deletes except ZWNJ and ZWJ (see the validation). The helper's javadoc in the diff ("does not change joining") is a draft; more exact: "a formatting character that normalize deletes, other than ZWNJ (handled by its own case) and ZWJ (which joins the HEH to what follows)". The code below is an excerpt; the full diff:
--- a/lucene/analysis/common/src/java/org/apache/lucene/analysis/ckb/SoraniNormalizer.java
+++ b/lucene/analysis/common/src/java/org/apache/lucene/analysis/ckb/SoraniNormalizer.java
@@ -45,6 +45,7 @@
   static final char HEH = '\u0647';
   static final char AE = '\u06D5';
   static final char ZWNJ = '\u200C';
+  static final char ZWJ = '\u200D';
   static final char HEH_DOACHASHMEE = '\u06BE';
   static final char TEH_MARBUTA = '\u0629';

@@ -87,7 +88,7 @@
           i--;
           break;
         case HEH:
-          if (i == len - 1) {
+          if (isWordFinal(s, i, len)) {
             s[i] = AE;
           }
           break;
@@ -126,4 +127,17 @@
     }
     return len;
   }
+
+  /**
+   * Returns true if every char after {@code pos} is a formatting character that {@link #normalize}
+   * removes and that does not change joining (not ZWNJ or ZWJ), such as a directional mark.
+   */
+  private static boolean isWordFinal(char[] s, int pos, int len) {
+    for (int i = pos + 1; i < len; i++) {
+      if (s[i] == ZWNJ || s[i] == ZWJ || Character.getType(s[i]) != Character.FORMAT) {
+        return false;
+      }
+    }
+    return true;
+  }
 }
static final char ZWJ = '\u200D'; // new constant
case HEH:
if (isWordFinal(s, i, len)) { // was: if (i == len - 1)
s[i] = AE;
}
break;
private static boolean isWordFinal(char[] s, int pos, int len) {
for (int i = pos + 1; i < len; i++) {
if (s[i] == ZWNJ || s[i] == ZWJ || Character.getType(s[i]) != Character.FORMAT) {
return false;
}
}
return true;
}Trade-offs
- Existing indexes keep the old term for affected words until reindexed; worth a CHANGES line.
- Cost: a forward scan from a HEH that stops at the first other character. The extra scan reads each character at most once per token, so the fix adds only linear work. (
normalize()itself is not linear today: every deletion shifts the rest of the buffer,StemmerUtil.delete.) - Breadth: it admits every format character the class deletes, not only the direction marks. If maintainers want only the direction marks and the soft hyphen, the helper can test an explicit list instead (not built or tested).
- Index-time and query-time analysis must change together during the rollout.
- Unchanged by design: HEH + TATWEEL, ZWJ or a vowel mark stays HEH; HEH + ZWNJ was already AE.
- Only main was built and tested with gradle;
normalize()is the same, ignoring whitespace, from 4.7.0 on, so a backport should need at most context changes.
What the checks validated
- Gradle, JDK 25, scratch worktree at
a9779ef3c193: the new test fails 5 of 7 on stock (assertions on and off) and passes 7 of 7 with the fix; every test inorg.apache.lucene.analysis.ckbpasses: 6 suites, 37 tests (30 upstream, includingcheckRandomDataoverSoraniAnalyzerand the 8,272-row vocabulary, plus the 7 new), 0 skipped, assertions on and off. checkGoogleJavaFormat,ecjLintMain,ecjLintTest,forbiddenApisMainandforbiddenApisTestoflucene/analysis/commonpass.- Exhaustive, all 1,118,481 strings of length 0 to 5 over a 16-character alphabet: within that alphabet it changes exactly the 31,420 inputs whose last HEH is followed only by RLM, LRM, ALM, PDF or soft hyphen, and only that HEH, from U+0647 to U+06D5.
- Every BMP character after
خانه(surrogates skipped): the output changes for exactly 41 characters, each from..0647to..06D5: the direction marks and controls (U+200E, U+200F, U+061C, U+202A-U+202E, U+2066-U+2069), U+00AD, U+200B, U+2060-U+2064, U+FEFF, U+206A-U+206F (deprecated format controls, including INHIBIT and ACTIVATE ARABIC FORM SHAPING), U+180E, U+FFF9-U+FFFB and the prepended concatenation marks (U+0600-U+0605, U+06DD, U+070F, U+0890, U+0891, U+08E2). ICU 78.3: 26 Transparent, 15 Non_Joining, none join-causing. ThroughStandardTokenizer38 of them stay in the token; U+200B, U+0890 and U+0891 do not. Fix B gives the same output. - The finder's fix has the same condition; with it every verifier's claim tests passed (finder 5 of 5, the independent reproduction 12 of 12, adjudication 10 of 10), as did the 28 (finder) and 30 (refute reviewer) upstream tests they ran.
Trim trailing formatting characters other than ZWNJ and ZWJ before the loop (equivalent) (validated by the checks)
Before the loop, drop trailing Character.FORMAT characters other than ZWNJ and ZWJ (+10):
--- a/lucene/analysis/common/src/java/org/apache/lucene/analysis/ckb/SoraniNormalizer.java
+++ b/lucene/analysis/common/src/java/org/apache/lucene/analysis/ckb/SoraniNormalizer.java
@@ -45,6 +45,7 @@
   static final char HEH = '\u0647';
   static final char AE = '\u06D5';
   static final char ZWNJ = '\u200C';
+  static final char ZWJ = '\u200D';
   static final char HEH_DOACHASHMEE = '\u06BE';
   static final char TEH_MARBUTA = '\u0629';

@@ -70,6 +71,11 @@
    * @return length of input buffer after normalization
    */
   int normalize(char[] s, int len) {
+    // remove trailing formatting characters that do not change joining (such as directional marks)
+    // first, so that they do not hide a word-final HEH
+    while (len > 0 && isTrailingRemovable(s[len - 1])) {
+      len--;
+    }
     for (int i = 0; i < len; i++) {
       switch (s[i]) {
         case YEH:
@@ -126,4 +132,8 @@
     }
     return len;
   }
+
+  private static boolean isTrailingRemovable(char ch) {
+    return ch != ZWNJ && ch != ZWJ && Character.getType(ch) == Character.FORMAT;
+  }
 }
Trade-offs
Reads as "strip trailing invisible marks first" and touches no case of the switch; A keeps the change inside the HEH rule. Choose by taste.
What the checks validated
- The same output as A on all 1,118,481 inputs of the exhaustive run (identical output digests).
- Gradle: the new test and the 30 upstream
ckbtests pass (assertions on), andcheckGoogleJavaFormatpasses; standalone: the new test 7 of 7. - The same output as A for every BMP character after
خانه(the 41-character scan).
The finder's first fix also skipped harakat and TATWEEL after the HEH.
Trade-offs
Fails the upstream vocabulary test (هـ expected ه, got ە; 1 of 28 fails): TATWEEL forces a joining form, and a vowel mark can mark the HEH as the consonant h. A post-pass "if the output ends in HEH, make it AE" would change the same HEH + tail inputs and fail the same row, and more: a word ending in HEH DOACHASHMEE (U+06BE), which the class rewrites to HEH, would also become AE (reasoning).
Change the javadoc instead of the code.
Trade-offs
Keeps the two documented rules in tension (a removed mark would still change the result), unlike the word-initial rule, and leaves two spellings of the same word unmatched.
Downstream, a deny or moderation rule written as an analyzed Sorani term query could miss a document whose word carries the invisible mark; servers with a built-in Sorani analyzer on this filter inherit the mismatch.
Semi-formal. A bounded-exhaustive check ran the stock filter on all 732,541 strings of up to 4 characters over a 29-character alphabet against rules taken from the javadoc. "Deleting a character the class removes must not change the result" failed on 23,190 inputs, all a HEH followed only by removable characters; the claim was then narrowed to direction marks.
The method in full153 words
Method: bounded-exhaustive translation validation of the script normalizers against their documented rules (the hunt's "semi-formal" tier), 2026-10-27.
- The harness (
NormalizerTV.java) ran the stockSoraniNormalizationFilteron every string of length up to 4 over a 29-character alphabet (letters including ZWNJ and TATWEEL, the harakat and 6 format characters), 732,541 inputs, and compared it with oracles derived from the class javadoc. - The deletion-invariance oracle (deleting a character that the javadoc says is removed must not change the result) failed on 23,190 inputs, all a HEH followed only by removable characters at the end. A residual run that excluded that shape found 0 other violations.
- The upstream vocabulary pins HEH + TATWEEL -> HEH, and a wider fix failed it, so the finder narrowed the claim to trailing format characters other than ZWNJ and ZWJ and wrote the public-API JUnit on the stock jars.
- Independent verifiers then reproduced and judged it (see the checks).
No prior report: two scripted prior-report search runs (68 and 33 queries), 57 manual GitHub, downstream and JIRA searches, the OSS-Fuzz feed, the files of all 409 open PRs and the introducing issue, searched 2026-10-27. Related only: a withdrawn fuzzer crash and a scanner advisory, both about exceptions in the same method.
Searches4 searches
No issue, PR, JIRA ticket, list thread, downstream issue or web page reports a word-final HEH left unconverted before a direction mark, or the order of the HEH test and the format-character deletion. Searches are lexical and PR review threads are not indexed, so this is "no report found".
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene) | 2026-10-27 | a scripted prior-report search (22 issue and PR queries, 3 commit queries), 27 manual searches for the class names, code points, mark names, Character.FORMAT, ZWNJ and the sibling normalizers, the introducing issue's body and comments, the file's full history; a later read-only re-check | only the introducing issue #6442 (LUCENE-5379); unrelated hits such as #7426 (package naming) and PR #540 (a remark on the ZWNJ constant) |
| Open PRs | 2026-10-27 | the changed files of all 409 open apache/lucene PRs | only #16911 touches ckb (it decommissions branch_10x) |
| Mailing lists and JIRA | 2026-10-27 | 56 list queries over dev@, java-user@, issues@ and commits@ (two tool runs, including RLM, 200F, 200E, 061C, "directional marks" and "bidi"); 11 tool and 7 manual JIRA queries (LUCENE, SOLR, LUCENENET) | a java-user@ thread on scanner advisory sonatype-2025-002284, about an exception from invalid buffer or length input: not this bug |
| Downstream, the web and fuzzing feeds | 2026-10-27 | 3 tool and 23 manual searches in Elasticsearch, OpenSearch, Solr, lucene-solr and Lucene.NET; 6 web queries; the OSV feed of OSS-Fuzz findings for Lucene | OSV-2025-253, a withdrawn fuzzer crash inside the same method (an exception, not this bug); #7048 (LUCENE-5986), a declined request about the Arabic normalizer; no report |
Present since the Sorani analyzer was added: LUCENE-5379 (2140f4368ad, backport a670b8d5b22, 2014-01-04), first released in 4.7.0. It fails on all 12 releases run from 4.7.0 to 10.5.2 and on main; 4.6.1 has no Sorani API. Not a regression, and not fixed upstream.
Versions tested7 rows
Introduced by LUCENE-5379 ("Kurdish Analyzer", issue #6442; author rmuir): 2140f4368ad on trunk and the same-day branch_4x backport a670b8d5b22, which shipped in 4.7.0 (tagged 2014-02-25). A Subversion commit, no PR. Both rules arrived together, in today's order. The four later commits on the file (813ca77250d LUCENE-7013 license header, 8ef6a0da568 LUCENE-9570 reformat, 8ac26737913 LUCENE-10003 array syntax, 694d797526a LUCENE-10561 package-private, first released in 10.0.0) do not change the logic; ignoring whitespace and the signature, normalize() is identical from 4.7.0 to main. Not fixed upstream: main a95c754ee003 (2026-10-26) still tests i == len - 1. Every run used JDK 25.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the brief's test 5 of 7 fail (gradle and standalone, assertions on and off); the finder's 4 of 5; the independent reproduction's 6 of 10; the main() 5 of 5 checks |
| 10.5.2, 9.12.3 | affected | the brief's test 5 of 7 fail; the main() 5 of 5 checks (10.5.2 also with plain javac and java) |
| 6.6.6, 7.0.0, 7.7.3, 8.11.4, 9.0.0, 10.0.0 | main() | 5 of 5 checks fail; both controls pass |
| 4.7.0, 4.10.4, 5.0.0, 5.5.5 | main() | 4 of 4 checks fail (Analyzer.normalize exists only from 6.2.0); both controls pass |
| 4.6.1 | no API | no Sorani analysis classes: the repro does not compile |
| main + the fix | not affected | every check passes; 37 ckb tests pass with gradle |
upstream main a95c754ee003, branch_10x | read | still if (i == len - 1) in case HEH |
An independent reproducer, a devil's advocate, an adjudication and a credibility audit, plus two executed reviews by another model family (OpenAI GPT-5.6, refute and intended-behaviour lenses), all found it real with their own runs on main, assertions on and off. This doc's own test, exhaustive comparison and gradle runs agree.
Checks and verdicts385 words
Every verifier wrote or ran its own tests against the stock jars; each verdict below names what it ran.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | JUnit fails 4 of 5 on main (assertions on and off), 10.5.2 and 9.12.3; 5 of 5 with the narrow fix; the 28 upstream tests it ran pass with the narrow fix, 1 fails with the wider one. |
| Independent reproducer | real | Own JUnit from the claim: 6 of 10 fail on main (on and off), 10.5.2 and 9.12.3; 4 controls pass; only the trailing position of a mark changes the output; impact JUnit 2 of 2 fail (sentence, stem); 12 of 12 pass with the fix. |
| Cross-model review, refute lens | real (high) | An independent reviewer from another model family (OpenAI GPT-5.6, executed mode, on ea57360912ed with identical analysis sources): own JUnits fail through the filter, normalize() and the full indexing chain; the 30-test ckb suite passes with the fix. |
| Cross-model review, intended lens | real (high); intended-behaviour argument moderate | Its expected-semantics test fails on main, 10.5.2 and 9.12.3 and passes with the fix; the review step re-ran it on a9779ef3c193 (1 of 6 fail, assertions on and off). |
| Devil's advocate | real (high), low impact | Built the strongest intended case and showed why it fails; probe: HEH kept before RLM, LRM, ALM, PDF, RLO and PDI; a leading mark before REH is ignored; the fix keeps HEH before TATWEEL, ZWJ and DAMMA. |
| adjudication | confirmed, high | Re-ran the independent reproduction's JUnit (6 of 10 fail, assertions on and off) and the independent reproduction's JUnit with the fix (10 of 10 pass); class silent wrong results. |
| Follow-up | history, prior art, security | 12 releases plus main executed; prior-report verdict new; security none after an executed probe. |
| credibility audit | keep | Re-ran the finder's JUnit (4 of 5 fail, on and off) and an own end-to-end TermQuery test: the document with HEH + RLM in running text is missed (2 of 3 fail, on and off). |
| this doc's runs | reproduced; fix validated | The new test 5 of 7 fail on main (gradle and standalone, on and off), 10.5.2 and 9.12.3; the fix passes it and the 30 upstream ckb tests; the exhaustive run shows the fix changes only the bug's inputs. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 437 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,524 words
- Registry title
- SoraniNormalizer checks for a word-final HEH before it removes trailing directional marks, so a word ending in HEH followed by RLM, LRM or ALM keeps HEH (U+0647) instead of becoming AE (U+06D5) as the class javadoc says
- Area
- analysis-common / Sorani normalizer (SoraniNormalizer.normalize; SoraniNormalizationFilter, SoraniAnalyzer and the 'soraniNormalization' factory)
- Priority
- Low, rank 310: Needs a word-final HEH followed by an invisible directional mark in Sorani text, a rare input.
- Impact class
- silent wrong results
- Impact note
- Search quality only, with no error: applications that analyze Sorani Kurdish text with SoraniAnalyzer (default constructor included), SoraniNormalizationFilter or the 'soraniNormalization' factory, on every release from 4.7.0 through 10.5.2 and on main, index and query a word whose final vowel is typed as HEH and that carries an invisible trailing RLM, LRM or ALM (StandardTokenizer keeps it inside the token) as a different term from the same word without the mark ([..U+0647] vs [..U+06D5]; the stemmed term can differ too), so the two visually identical spellings do not match each other; no scale is needed, -ea and -da behave the same, the mark must sit directly after the final HEH, and because a fix changes indexed terms, affected fields need reindexing after it.
- Summary
- You analyze Sorani Kurdish text with the stock SoraniAnalyzer or SoraniNormalizationFilter. The normalizer's javadoc says a word-final HEH (U+0647) is converted to AE (U+06D5) and that formatting characters such as directional controls are removed, so خانه ('house') followed by an invisible right-to-left mark should normalize like خانه itself, to خانە. Instead the HEH rule asks 'is this the last character?' while the trailing mark is still in the buffer, and the mark is deleted only later in the same pass, so خانه+RLM (and +LRM, +ALM) becomes خانه with a plain HEH and no longer matches خانە, with no error.
- Introduced
- 2140f4368ade00f1d3b6f2bb25ecaf257c639c3d (trunk, Subversion r1555359, 'LUCENE-5379: Kurdish Analyzer' by rmuir; JIRA LUCENE-5379, migrated as apache/lucene#6442; no PR, pre-GitHub) with its same-day branch_4x backport a670b8d5b22 (r1555360), the copy that shipped in 4.7.0 [read: git log --follow and a whitespace-insensitive compare of normalize() across release tags in the history clone]: the 'case HEH: if (i == len - 1)' test and the later FORMAT deletion in the default branch arrived together, in today's order. Not a regression: the four later commits on the file (813ca77250d LUCENE-7013 license header, 8ef6a0da568 LUCENE-9570 reformat, 8ac26737913 LUCENE-10003 array syntax, 694d797526a LUCENE-10561 package-private) do not change the logic. (2014-01-04 (trunk and branch_4x; first released in 4.7.0, tagged 2014-02-25))
- First affected version
- 4.7.0 [exec] (the first release with the org.apache.lucene.analysis.ckb package; the follow-up's cross-version main() repro fails all 4 filter and analyzer checks there, Analyzer.normalize being absent before 6.2.0, and both controls pass). 4.6.1, the last release before it, has no Sorani analysis API [exec: the repro does not compile], so no release ever applied the rule across a trailing mark.
- Affected versions
- Every release that ships the Sorani analysis API, 4.7.0 through 10.5.2, and main a9779ef3c193; not fixed. [exec] the follow-up's version-independent public-API repro (SoraniNormalizationFilter with a trailing RLM, LRM and ALM, the SoraniAnalyzer token stream and, from 6.2.0, SoraniAnalyzer.normalize; 2 controls) fails on 4.7.0, 4.10.4, 5.0.0, 5.5.5, 6.6.6, 7.0.0, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 (-ea and -da) and main (-ea and -da), with both controls passing, and passes on main with the fix shadowed; the finder's JUnit fails 4 of 5 on 9.12.3, 10.5.2 and main (-ea and -da) (it needs org.apache.lucene.tests.analysis, so it does not compile on 9.0.0); the independent reproduction's JUnit fails 6 of 10 on 9.12.3, 10.5.2 and main. [read] the normalize() body is identical, ignoring whitespace and the signature, from 4.7.0 to main, and upstream main a95c754ee003 (2026-10-26) and branch_10x still contain 'case HEH: if (i == len - 1)' (read 2026-10-27). All runs used JDK 25.0.3; ALM (U+061C, Unicode 6.3) is not a FORMAT character on JDKs with older Unicode tables (Java 8), where the ALM would stay in the term and the HEH would still stay HEH (not executed).
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (searched 2026-10-27, read-only; the prior-report record, verdict new): scripted prior-report search merged run (22 GitHub issue/PR queries on apache/lucene, 3 commit, 3 downstream-repository, 28 mailing-list queries over the dev, java-user, issues and commits lists, 6 JIRA, 6 web; 0 errors) plus a second run (28 list and 5 JIRA queries for RLM, 200F, 200E, 061C, 'directional marks' and 'bidi'), 27 manual apache/lucene searches (code points, mark names, Character.FORMAT, ZWNJ, sibling normalizers, OSS-Fuzz, Sonatype), 23 manual downstream searches (Elasticsearch, OpenSearch, Solr, lucene-solr, Lucene.NET), 7 manual JIRA queries (SOLR, LUCENE, LUCENENET), the OSV OSS-Fuzz feed for Lucene, the changed files of all 409 open apache/lucene PRs, the introducing issue gh#6442 (LUCENE-5379; body and all 3 comments) and the file's full git history; the finder's run (23 queries) and the intended-behaviour check's list and JIRA run (23 queries) found only LUCENE-5379. No issue, PR, JIRA ticket, list thread, downstream issue or web page reports a word-final HEH left unconverted before a directional mark, or the order of the HEH test and the format-character deletion. Related, not the same bug: OSV-2025-253 (OSS-Fuzz 407477665, an exception inside SoraniNormalizer.normalize after WordDelimiterGraphFilter; published 2025-04-03, withdrawn 2026-10-01) and a java-user@ thread on scanner advisory sonatype-2025-002284 (2025-09-01, an exception from invalid buffer or length input): both report an exception, while this bug throws nothing and its fix touches only the HEH condition; gh#7048 (LUCENE-5986, a declined request to stop folding word-final TEH MARBUTA in ArabicNormalizer); gh#11597 (LUCENE-10561, visibility only). Not fixed upstream: main a95c754ee003 and branch_10x unchanged; the only open PR that touches ckb is #16911 (decommissions branch_10x). Gaps: the OSS-Fuzz tracker entry was not readable; PR review threads are not search-indexed (PR #540's were read by hand). Update 2026-11-02: #16911 (open when searched) merged 2026-10-29 as 48cf3f515d6, which emptied branch_10x to a README tombstone (10.6 is the last 10.x minor; 10.x fixes go to branch_10_6); it fixes nothing here.
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-27) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the release jars 10.5.2 and 9.12.3 with the same test; the follow-up's version-independent repro on 12 releases from 4.7.0 to 10.5.2 (4.6.1 has no Sorani API); the cross-model reviews onea57360912ed, whoselucene/analysissources equala9779ef3c193. The fix was validated in the scratch worktree: the new test, all 30 upstreamckbtests with assertions on and off, and the module's format, ecj-lint and forbidden-API checks; an exhaustive run over 1,118,481 strings shows it changes only the bug's inputs.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/ckb/SoraniNormalizer.java:21-35 (at a9779ef3c193) (class javadoc; package-private class at :36), :29 ('Alternate forms of vowel 'e' (0647+200C, word-final 0647, 0629) are converted to 06D5 (AE)'), :33 ('Harakat, tatweel, and formatting characters such as directional controls are removed.'), :72-73 (single left-to-right loop), :82-88 (case ZWNJ rewrites the previous HEH), :89-93 (case HEH: if (i == len - 1) s[i] = AE), :100-104 (case REH: word-initial RREH), :120-124 (default: Character.FORMAT deleted)lucene/analysis/common/src/java/org/apache/lucene/analysis/ckb/SoraniNormalizationFilter.java:24-37 (at a9779ef3c193) (public filter applying the normalizer to the term buffer); SoraniNormalizationFilterFactory.java:40 (SPI name 'soraniNormalization'); SoraniAnalyzer.java:78 (default constructor), :114-115 (StandardTokenizer then SoraniNormalizationFilter), :125-126 (normalize applies the same filter)lucene/core/src/java/org/apache/lucene/analysis/standard/StandardTokenizerImpl.jflex:83-85 (at a9779ef3c193) (UAX#29 WB4: Format characters stay attached to the preceding token); lucene/analysis/common/src/test/org/apache/lucene/analysis/ckb/TestSoraniNormalizationFilter.java:70-73 (testFinalH: 'always (and in final form by def), so frequently omitted')GitHub, read-only (2026-10-27): apache/lucene #6442 (LUCENE-5379), #7048 (LUCENE-5986), #11597 (LUCENE-10561), PR #540, PR #16911; apache/lucene main a95c754ee003 and branch_10x SoraniNormalizer.java (condition unchanged); osv.dev OSV-2025-253; lists.apache.org java-user@ thread x0l9sdfftmsnbng82bd19no9vzjq5d67
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/ckb/SoraniNormalizer.java:21-35 (at a9779ef3c193) (class javadoc), :29, :33, :72-128 (normalize), :82-88 (ZWNJ), :89-93 (HEH), :100-104 (REH), :120-124 (FORMAT deletion)lucene/analysis/common/src/java/org/apache/lucene/analysis/ckb/SoraniAnalyzer.java:113-130 (at a9779ef3c193)lucene/core/src/java/org/apache/lucene/analysis/standard/StandardTokenizerImpl.jflex:83-85 (at a9779ef3c193) (UAX#29 WB4)lucene/analysis/common/src/test/org/apache/lucene/analysis/ckb/TestSoraniNormalizationFilter.java:70-73 (at a9779ef3c193) (testFinalH)
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/ckb/SoraniAnalyzer.java:78-101 (at a9779ef3c193) (constructors), :113-130lucene/analysis/common/src/java/org/apache/lucene/analysis/ckb/SoraniNormalizationFilterFactory.java:26-32 (at a9779ef3c193) (Solr example), :40 (SPI name)lucene/analysis/common/src/test/org/apache/lucene/analysis/ckb/ckbtestdata.zip (at a9779ef3c193) (8,272 rows; 11 trailing U+202E; read 2026-10-27)lucene/core/src/java/org/apache/lucene/analysis/standard/StandardTokenizerImpl.jflex:42 (at a9779ef3c193) (%unicode 12.1)
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/ckb/SoraniNormalizer.java:21-36, (at a9779ef3c193) :29, :33, :82-88, :100-104lucene/analysis/common/src/java/org/apache/lucene/analysis/ckb/SoraniNormalizationFilter.java:24 (at a9779ef3c193)lucene/analysis/common/src/test/org/apache/lucene/analysis/ckb/TestSoraniNormalizationFilter.java:70-73 (at a9779ef3c193)lucene/analysis/common/src/test/org/apache/lucene/analysis/ckb/TestSoraniStemFilter.java:107 (at a9779ef3c193) (testVocabulary), ckbtestdata.ziplucene/CHANGES.txt:2179 (at a9779ef3c193) (LUCENE-10561, under the 10.0.0 header at :2155), :12736 (LUCENE-5379)Lucene main a9779ef3c193 build-tools/build-infra/src/main/java/org/apache/lucene/gradle/plugins/java/RenderJavadocPlugin.java:464 (-protected)
- Suggested fix
lucene/analysis/common/src/java/org/apache/lucene/analysis/util/StemmerUtil.java:85-90 (at a9779ef3c193) (delete shifts the buffer)
- TestSoraniFinalHehBeforeRlm.java (JUnit test):
repro/LFV-668/src/org/apache/lucene/analysis/ckb/TestSoraniFinalHehBeforeRlm.java(29 lines)
Made in parallel with this doc from executed probes on main a9779ef3c193 (stock and with the fix) and on 10.5.2. The PNG is the summary frame. Its "28 of 28" upstream tests is the finder's run, which left out one factory suite; the gradle run of the whole ckb package counts 30 upstream tests, all passing.
assets/LFV-668/bug.png(437 KB)