Bengali has three s-letters, শ, ষ and স, which Lucene's Bengali normalizer folds to স so that spelling variants match. A visarga ঃ inside a word doubles the next consonant, so the normalizer replaces it by a copy of that letter. It copies the letter before folding it.
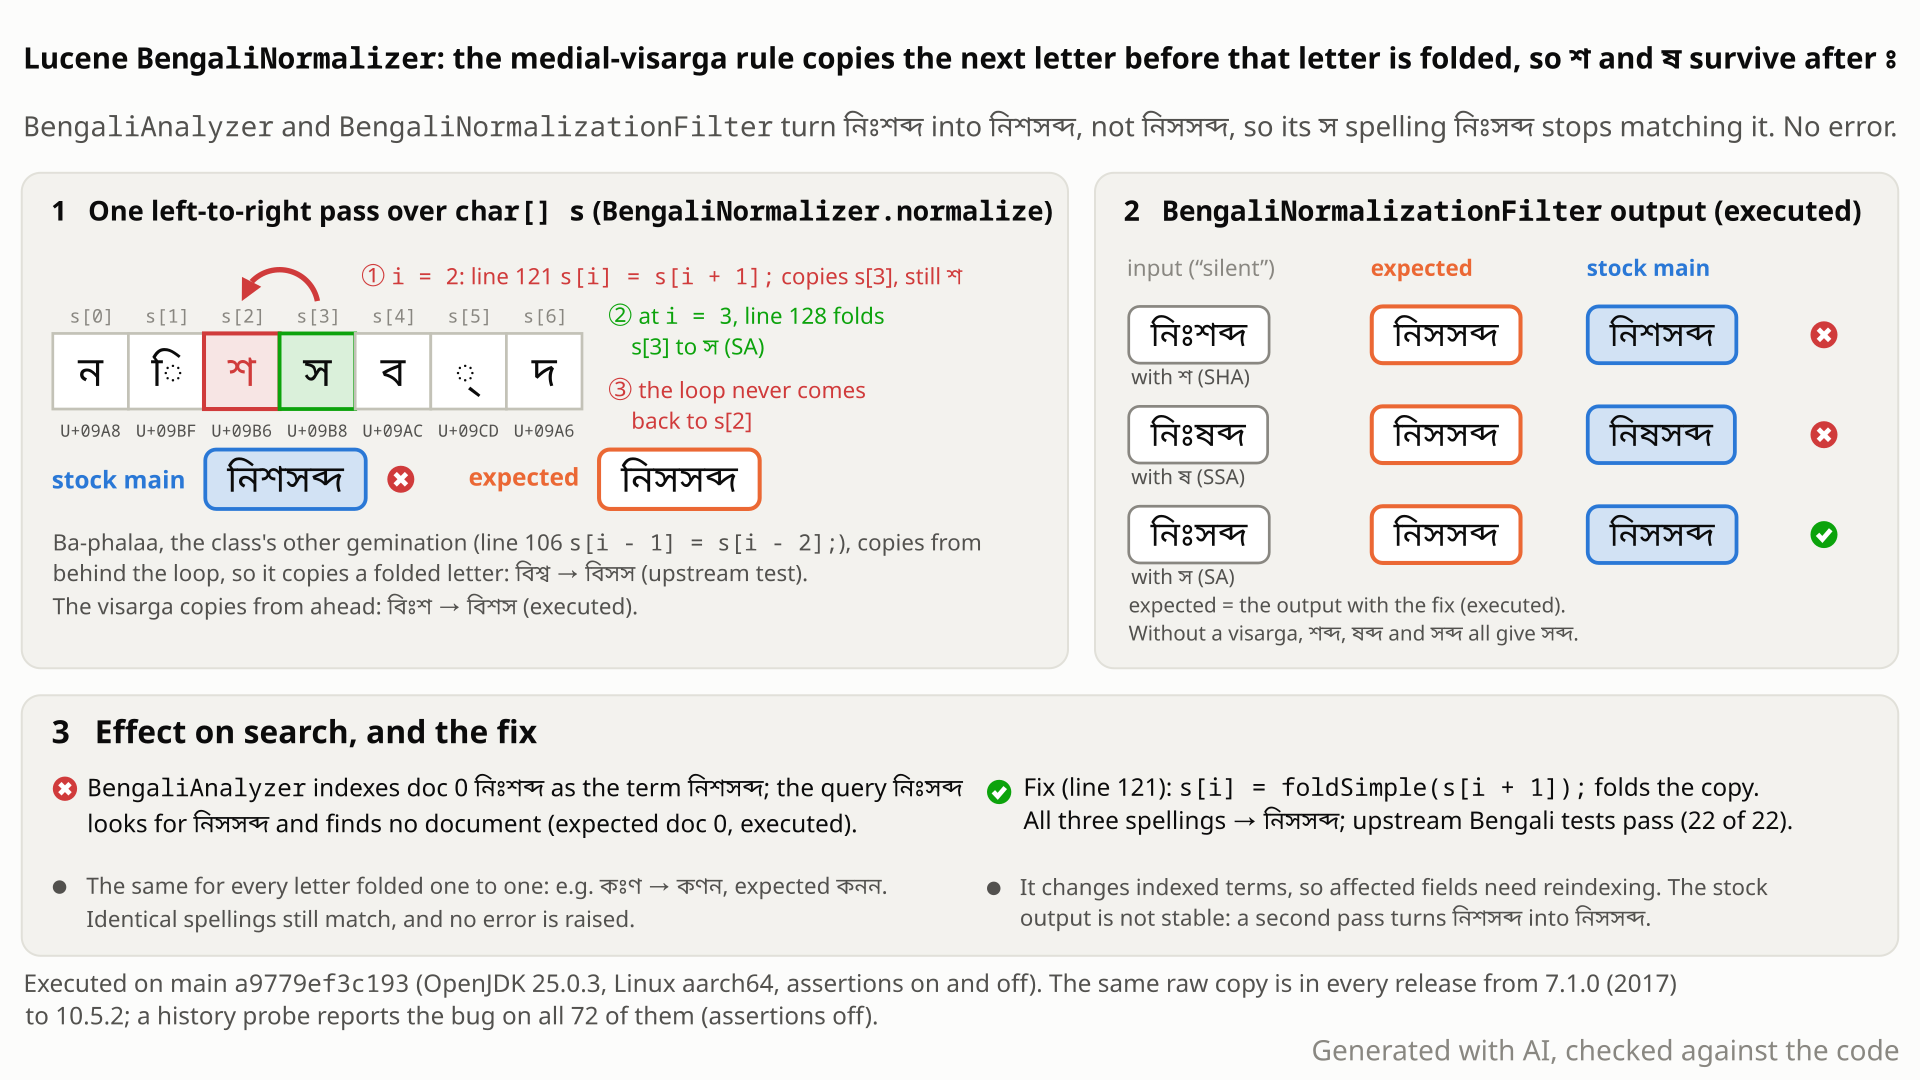
নিঃশব্দ, where line 121 copies শ before line 128 folds it and the loop never comes back. Panel 2: the filter output for the three spellings, stock versus expected. Panel 3: the effect on search, and the fix. Select the still to open it at full size. Generated with AI, checked against the code.- Index Bengali text with the stock
new BengaliAnalyzer()(orBengaliNormalizationFilter). Its normalizer folds the s-letters শ and ষ to স, soশব্দandসব্দboth index asসব্দ. - It also turns a visarga ঃ in the middle of a word into a copy of the next letter. You expect
নিঃশব্দ("silent"),নিঃষব্দandনিঃসব্দall to becomeনিসসব্দ, just as the class's other doubling rule turnsবিশ্বintoবিসসin an upstream test. - You get
নিশসব্দ,নিষসব্দandনিসসব্দ: three terms. The normalizer is one left-to-right pass, ands[i] = s[i + 1](BengaliNormalizer.java:121) copies শ before the loop reaches it and folds it to স; the copy is never revisited. - In an index with one document per spelling, each spelling's query finds 1 of 3 documents; with the fix, 3 of 3. No error, and identical spellings still match. The other folded characters (ণ, ঙ, ড় U+09DC, ঢ় U+09DD, ৎ, ী, ূ) behave the same way after a visarga.
Applications that index Bengali with the stock BengaliAnalyzer (default constructor), BengaliNormalizationFilter or the bengaliNormalization factory, on every release since 7.1.0. A word with a medial visarga before শ, ষ, ণ or another folded character does not match its variant spelling. Identical spellings still match; a fix needs a reindex.
Mechanism, terms and numbers634 words
BengaliNormalizer (package-private; used by BengaliNormalizationFilter, by BengaliAnalyzer at index and query time and by the bengaliNormalization factory) is one left-to-right pass over the term. It folds SHA শ and SSA ষ to SA স everywhere (and NNA, RRA, RHA, khanda-ta, II, UU and NGA one to one), and it turns a medial visarga ঃ into a copy of the next letter: s[i] = s[i + 1] at BengaliNormalizer.java:121. That copy is made before the loop has folded the next letter, and the loop never returns to it, so নিঃশব্দ ("silent") becomes নিশসব্দ (SHA SA), নিঃষব্দ becomes নিষসব্দ, and only নিঃসব্দ gives নিসসব্দ. The class's other gemination, Ba-phalaa, copies an already folded letter (বিশ্ব -> বিসস, pinned by an upstream test), and the cited paper gives SHA, SSA and SA one code. Through BengaliAnalyzer the three spellings get three terms and do not match each other. Every release from 7.1.0 to 10.5.2 and main has it. The fix, s[i] = foldSimple(s[i + 1]), changes indexed terms of the affected words, so those fields need a reindex.
- Visarga ঃ (U+0983): inside a word it doubles the sound of the next consonant, so
নিঃশব্দis said like nishshabdo. The normalizer models this as gemination: the visarga becomes a copy of the next letter. A final visarga becomes হ in a short word and is deleted in a longer one. - The folds: one-to-one rewrites the class applies at every position: SHA শ U+09B6 and SSA ষ U+09B7 to SA স U+09B8 (
// All sh), NNA ণ to NA ন, RRA ড় U+09DC and RHA ঢ় U+09DD to RA র U+09B0, khanda-ta ৎ to TA ত, NGA ঙ to anusvara ং, and the vowel signs II ী to I ি and UU ূ to U ু. BengaliNormalizer: a left-to-right rewrite of each token, oneswitch (s[i])case per character. It is package-private and reached throughBengaliNormalizationFilter, whichBengaliAnalyzeruses in its main chain (indexing and analyzed queries) and innormalize()(multi-term queries), and through thebengaliNormalizationfactory. Tokens marked as keywords skip it.
- The visarga case (
BengaliNormalizer.java:112-123) runss[i] = s[i + 1];(:121) for a medial visarga. - At that moment position i + 1 has not been visited, so the copy is the raw letter. The loop then folds the original at i + 1 (
// All sh,:125-129) and never returns to i. Forনিঃশব্দ:ন ি ঃ শ ব ্ দ->ন ি শ শ ব ্ দ->ন ি শ স ব ্ দ. - Ba-phalaa, the class's other gemination, copies backwards,
s[i - 1] = s[i - 2](:106), from a position already folded:বিশ্ব->বিসস. The visarga version of the same doubling,বিঃশ, givesবিশস. - The result is not even a fixed point of the class's own rules: normalizing
নিশসব্দagain givesনিসসব্দ.
| input | as the folds define | stock filter and BengaliAnalyzer term |
|---|---|---|
নিঃশব্দ (SHA) | নিসসব্দ | নিশসব্দ |
নিঃষব্দ (SSA) | নিসসব্দ | নিষসব্দ |
নিঃসব্দ (SA) | নিসসব্দ | নিসসব্দ |
নিঃশেষ (exhausted) | নিসসেস | নিশসেস |
নিঃশ্বাস (breath) | নিসসসাস | নিশসসাস |
দুঃণা vs দুঃনা (NNA vs NA, synthetic) | both দুননা | দুণনা vs দুননা |
বিঃশ vs বিশ্ব (two geminations) | both বিসস | বিশস vs বিসস |
শব্দ vs সব্দ (no visarga) | both সব্দ | both সব্দ |
The hunt's bounded check found 23,947 violations of "no character that an unconditional rule rewrites or deletes may survive" (chandrabindu and the visarga included) over all 551,881 strings of up to 4 characters on a 27-character alphabet; every one contains a visarga. A folded character survives in 20,097 of them, and the recommended fix removes all of those; the other 3,850 keep only a chandrabindu or a visarga, cases that no fix option covers.
Exposure and likelihood382 words
- Who is exposed.
BengaliAnalyzer(the default constructor included),BengaliNormalizationFilter, and thebengaliNormalizationfactory, for example in aCustomAnalyzer. No setting turns the rule off. Only tokens marked as keywords skip it, together with the whole normalizer (BengaliNormalizationFilter.java:48);BengaliAnalyzermarks the words of its stem-exclusion set, if one is given (BengaliAnalyzer.java:123-125). - Ordinary input. Tatsama words such as
নিঃশব্দ,নিঃশেষ,নিঃশ্বাসandদুঃশাসনhave a medial visarga before শ. Every such word gets the unfolded term, at index and query time alike. - What the damage looks like. Silent: no error, and identical spellings still match. What fails is the match the folds exist for: a document and a query that spell the letter after the visarga differently (শ, ষ or স; ণ or ন) do not meet, although the analyzer conflates them anywhere else in a word. With one document per spelling of
নিঃশব্দ, each spelling's query finds 1 of 3 documents; with the fix, 3 of 3. An independent end-to-end test: the স-spelled query finds 0 of 1 শ-spelled documents, while the no-visarga control finds 1 of 1. - Only lost matches. Over 2,000,718 generated short strings (a synthetic set, not a corpus), 9,779,308 pairs of strings get the same output with the fix but different outputs on stock, and no pair the other way; the fix changes the output of 167,664 strings, each containing a visarga, and never changes an output's length.
- How likely. Rare: a missed match needs the two sides to spell that one letter differently, and no report of it was found in 9 years.
- Scale. One word reproduces it; assertions on and off behave the same.
- Reindex. A fix changes the term of every affected word, so fields analyzed before the fix keep the old terms until they are reindexed.
- What is not shown. No corpus count or native-speaker check measures how often the variant spellings (
নিঃষব্দ,নিঃসব্দforনিঃশব্দ) occur; the cross-spelling impact is inferred from the class's own folds and the cited paper's codes. - Downstream remark. An application that filters on analyzed text (a denylist query, a
MUST_NOTclause) misses a variant spelling the same way any query does. Authorization is the application's job under Lucene's SECURITY.md, so this is not a Lucene security issue.
The test shows that BengaliNormalizationFilter's medial-visarga rule copies the next letter before it is folded, so a SHA (শ) survives after a visarga.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.bn;

import org.apache.lucene.analysis.Tokenizer;
import org.apache.lucene.tests.analysis.BaseTokenStreamTestCase;

public class TestBengaliVisargaRule extends BaseTokenStreamTestCase {

  public void testVisargaCopyIsFolded() throws Exception {
    Tokenizer tokenizer = whitespaceMockTokenizer("নিঃশব্দ");
    // expected: SA SA (নিসসব্দ, as নিঃসব্দ gives; every SHA folds to SA); actual: SHA SA (নিশসব্দ)
    assertTokenStreamContents(new BengaliNormalizationFilter(tokenizer), new String[] {"নিসসব্দ"});
  }
}
# in a copy of this finding's repro folder (repro/LFV-676/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.bn.TestBengaliVisargaRule
- Expected vs actual
- Expected
নিঃশব্দto normalize toনিসসব্দ(SA SA), as the SA spellingনিঃসব্দdoes; actual:নিশসব্দ(SHA SA):term 0 expected:<নি[স]সব্দ> but was:<নি[শ]সব্দ>, with-eaand-da.
More files, environment, full output38 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: term 0 expected:<নি[স]সব্দ> but was:<নি[শ]সব্দ>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:262)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:513)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:598)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:622)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:689)
org.apache.lucene.analysis.bn.TestBengaliVisargaRule.testVisargaCopyIsFolded(TestBengaliVisargaRule.java:27)- Ba-phalaa, the class's other doubling rule, copies an already folded letter; an upstream test pins
বিশ্ব->বিসস(স স, not শ স). - The cited paper says a medial visarga "gets the code of next character" and gives শ, ষ and স one code.
- The only upstream visarga test uses খ, which no rule folds; nothing documents the order.
The full argument398 words
- The class's own folds.
// All sh,// check naand the others are unconditional. After a visarga the output still holds a letter the class rewrites everywhere else, and a second pass changes it (নিশসব্দ->নিসসব্দ). That alone does not prove a bug: another rule interaction also changes on a second pass (কঁ্ি->ক্ি->খ, where deleting the chandrabindu exposes the khio pattern). It supports the diagnosis together with the next two points. - The other gemination. Ba-phalaa (
BengaliNormalizer.java:106,s[i - 1] = s[i - 2]) copies a letter the loop has already folded, andTestBengaliNormalizer.testBaPhalaa(same commit) assertscheck("বিশ্ব", "বিসস"). The visarga copy givesবিঃশ->বিশসfor the same doubling. The difference comes only from loop order: one rule looks back at a processed position, the other ahead at an unprocessed one. - The cited paper (UzZaman and Khan, named in the class javadoc). Visarga "Case 1: In the medial position ... acts as a diacritic, geminating the sound of the consonant it follows. So, it gets the code of next character"; its example of a medial visarga before স encodes to
<dussmy>. SHA, SSA and SA share the code<s>, and the Ba-phalaa exampleবিশ্বencodes to<biss>. - Tests.
testVisargachecksদুঃখ->দুখখ,উঃ->উহ,পুনঃ->পুন. খ is not folded, so a raw copy and a folded copy give the same output: no test pins the current behaviour, and the fix breaks none.testRandomcan generate a folded letter after a visarga but checks only the length. - History. The copy and the folds arrived together in the contributor's first commit
1bca06b8a938(2017-08-24, LUCENE-7940, gh#8989, lucene-solr PR #238). Two later commits of the same PR only added the Ja-phala and Ba-phalaa bounds checks from the review (3197d5af71d,40dddf9324e); commits after the 2017-09-05 landing only reformat or change visibility. None of them touches the visarga lines, and the review never discussed the visarga. - No public javadoc for the mapping. The normalizer is package-private; the public filter says only that it normalizes "the orthography" and that "the normalization may cause unrelated terms to conflate". No javadoc promises a folded copy or a stable output, so there is no public contract; the evidence of intent is the class's rules, its tests and the cited paper.
The devil's-advocate check269 words
The strongest "intended" case (the devil's-advocate verifier and the intended-lens review by another model family, rated moderate): the class is a one-pass transcription of the paper, and "gets the code of next character" can be read as "copy the next character", which s[i] = s[i + 1] does literally; the paper describes phonetic codes for a spelling checker, not search normalization; nothing promises that the output is closed under the folds or stable under a second pass, and another rule interaction is not stable either; the normalizer is package-private; no expected-output test covers a folded letter after a visarga; the output has been stable for 9 years and the original review measured relevance with this code; a maintainer defends the Indic folds as "working as documented" in gh#14659; another contributor's evaluation found the Bengali folds too aggressive for search; and nothing measures how often the variant spellings occur. So the missing conflation may be called harmless or not worth a reindex.
Why it fails: in the paper "code" is the phonetic code, which SHA, SSA and SA share; the class's own Ba-phalaa gemination copies the folded letter and an upstream test from the same commit pins it; the output is not a fixed point of the class's rules (supporting evidence, not proof on its own); and nothing documents the ordering. Long life is not evidence that anyone chose it. Verdict: a defect (adjudication: confirmed, high). What the counter-case gets right: the impact is small, a fix changes indexed terms, and documenting the raw copy is a legitimate maintainer choice; a maintainer may also ask for a Bengali-language check first.
Recommended One table of the one-to-one folds, shared by the loop and the visarga copy
Make the copy carry the folded letter: s[i] = foldSimple(s[i + 1]) at BengaliNormalizer.java:121, with the class's one-to-one folds moved into foldSimple so the loop and the copy share one table. The repro and all 1,912 tests of the module pass. It changes the terms of affected words, so they need a reindex.
} else {
  // the copy is normalized like the next character itself
  s[i] = foldSimple(s[i + 1]);
}
break;

default:
  s[i] = foldSimple(s[i]);
  break;
All options and trade-offs4 options · 767 words
Options A and B give identical output on every probe word; B avoids a second copy of the fold table. Add the new visarga cases to TestBengaliNormalizer with whichever is chosen. Not covered by any option (not claimed): what the copy should become when the next character is itself deleted (chandrabindu) or part of a context rule (KA + HASANTA, Ja/Ba-phala). Both options fold only the nine one-to-one characters; before anything else (ZWNJ or ZWJ, punctuation, a Latin letter, a supplementary character) the visarga is still a raw copy of one UTF-16 code unit. With a single-token KeywordTokenizer, কঃ😀 gives [0995 D83D D83D DE00], an unpaired high surrogate that IndexWriter stores as U+FFFD, on stock and with both fixes; BengaliAnalyzer splits the emoji off, so it is not affected (executed).
One table of the one-to-one folds, shared by the loop and the visarga copy (validated by the checks) (recommended)
The seven one-to-one cases (II, UU, NGA, SHA/SSA, NNA, RRA/RHA, khanda-ta) move with their comments into private static char foldSimple(char c); the switch's default calls it, so every non-visarga output stays the same, and the medial visarga copies foldSimple(s[i + 1]). +40/-37 in BengaliNormalizer.java.
} else {
  // the copy is normalized like the next character itself
  s[i] = foldSimple(s[i + 1]);
}
break;

default:
  s[i] = foldSimple(s[i]);
  break;
Trade-offs
- Changes the indexed term of every word with a medial visarga before a folded character: this would likely warrant a CHANGES entry and a MIGRATE note (reindex fields analyzed with
BengaliAnalyzer,BengaliNormalizationFilteror thebengaliNormalizationfactory); MIGRATE.md has such a note for the Romanian change in 10.0 (a precedent, not a rule). Main is the natural target; a 10.x backport is debatable. - The filter conflates more, but only within its own folds.
- A larger diff than the minimal patch, but the table of one-to-one folds exists once, which removes the risk of two copies drifting apart (a special case added to the switch later could still differ from the copy). Cost: one static call for each character that reaches the switch's
defaultand for each medial-visarga copy (chandrabindu, KA, YA, BA and the visarga keep their own cases); no allocation (by reading).
What the checks validated
- Scratch worktree at
a9779ef3c193, gradle, JDK 25: the new test fails 3 of 3 on stock (assertions on and off) and passes with the fix;org.apache.lucene.analysis.bn.*: 5 suites, 25 tests (22 upstream + 3 new), 0 failures, with assertions on (seed 5EED0676) and off (seed 5EED0677);:lucene:analysis:common:checkGoogleJavaFormatpasses; the whole:lucene:analysis:common:test: 340 suites, 1,912 tests, 18 skipped, 0 failures, with assertions on (seed 5EED0678) and with the seed's choice (seed 5EED0676). - Standalone runner with the fix shadowed: the new test 3 of 3 pass and the 4 upstream suites 22 of 22, each with
-eaand-da; the probe gives 3 of 3 hits for every spelling and leaves the upstream examples and the digit case unchanged.
Change line 121 to s[i] = foldSimple(s[i + 1]); and add a helper with the same nine mappings as the switch's one-to-one cases (+25/-1). The finder's original fix.
-            s[i] = s[i + 1];
+            s[i] = foldSimple(s[i + 1]);
Trade-offs
The smallest behavioural diff, but the mapping table then exists twice, so a later edit to one fold must update both. Same reindex note.
What the checks validated
Gradle: the 5 Bengali suites, 25 tests, 0 failures with assertions on and off; checkGoogleJavaFormat passes. Standalone: the new test 3 of 3 pass (-ea, -da); earlier the finder's test 3 of 3, the upstream suites 22 of 22 and the independent reproducer's test 9 of 9.
Pin নিঃশব্দ -> নিশসব্দ in a test and comment that the copy is raw. Not run.
Trade-offs
It keeps every indexed term (no reindex, exact output stability), no public javadoc promises a folded copy, and nothing measures how often the variant spellings occur, so a maintainer may reasonably prefer it or ask for a Bengali-language check first. Its cost: the two geminations stay inconsistent, the output stays not a fixed point of the class's own rules, and the copy keeps differing from the cited paper's coding.
A one-line idea that fixes the sibilant cases.
Trade-offs
It loops forever on a doubled visarga: কঃঃক gives no result within 2 s through the filter and BengaliAnalyzer, while the stock code and both fixes return কঃকক (executed).
A bounded-exhaustive check of the stock Bengali filter against its own unconditional rules: no character such a rule rewrites or deletes may survive, and শ and স must give the same output. Over 551,881 short strings it found 23,947 violations, all with a visarga, pointing at line 121; in 20,097 a folded character survives; the recommended fix removes those.
The method in full206 words
Method: bounded-exhaustive translation validation on the stock main jars (the study's "semi-formal" tier). A hunt unit, "script normalizers against their documented rules", 2026-10-27.
- A closure oracle (no character that an unconditional rule rewrites or deletes may survive in the output: the folded characters, chandrabindu and the visarga) and a mapping-invariance oracle (SHA/SSA/SA and the other folded pairs must give the same output) ran over all 551,881 strings of length 0 to 4 on a 27-character alphabet (consonants, vowel signs, hasanta, chandrabindu, anusvara, visarga, khanda-ta; 23,947 closure violations) and all 5,380,840 strings of length 0 to 7 on a 9-character alphabet (1,010,898).
- A fact check later split the 23,947: a folded character survives in 20,097, and only a chandrabindu or a visarga in the other 3,850. With the recommended fix (option B), 4,372 remain, all chandrabindu/visarga-only (cases no fix option covers), and no folded character survives.
- Every closure violation contains a visarga, and a residual run that excludes visarga and KA + HASANTA inputs has 0 closure and 0 mapping-invariance violations, which isolates the cause to the visarga copy (KA + HASANTA is the separate khio bug).
- Then an AI finder wrote the public-API JUnit, and independent AI tools reproduced, reviewed and judged it (see the checks).
No prior report of the unfolded copy was found (best-effort search, 2026-10-27): two runs of the scripted prior-report search (65 and 63 entries over GitHub, commits, downstream projects, mailing lists, JIRA and the web), manual GitHub searches and all 409 open PRs. Another contributor's wiki page restates the rule and reports a different side effect of the same branch (digit doubling).
Searches4 searches
None of the issues, PRs, commits, JIRA entries, list threads or web pages found reports that the visarga copy escapes the folds. Upstream main, branch_10x and branch_10_5 still have the line.
Near-miss, to disclose: another contributor's wiki page of Bengali analysis notes (mediawiki.org, 2022, linked from a comment in gh#14659) restates the rule as "delete ঃ and double the following letter if it is not the last letter" and reports that a visarga used as a colon doubles the next digit (১৬ঃ৯, 16:9, becomes ১৬৯৯). That is a different effect of the same branch, which the fix does not change; the page never mentions the unfolded copy.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues and PRs (apache/lucene), commits | 2026-10-27 | 47 issue/PR and 6 commit queries in two runs of a scripted prior-report search; manual searches for visarga, Bengali (all 12 results read) and BengaliNormalizer; gh#8989 (30 comments) and lucene-solr PR #238 with its review | no report; gh#3539 mentions the visarga only as a character typed as ':'; the introducing review never discusses it |
| Open PRs | 2026-10-27 | the changed files of all 409 open apache/lucene PRs | none touches analysis/bn; #14699 (Telugu IndicNormalizer) is related, not the same |
| Mailing lists and JIRA | 2026-10-27 | 48 queries over dev@, java-user@, issues@ and commits@; Solr and general lists; 12 JIRA-archive queries plus searches across all JIRA projects | no report |
| Downstream repositories, all of GitHub and the web | 2026-10-27 | 6 downstream queries plus Elasticsearch, OpenSearch, Solr, lucene-solr and Lucene.NET (visarga: 0 hits); code search (36 copies and ports, all read); 8 web queries plus 1 direct fetch of the wiki page | no report; every copy has the same line; the wiki page above |
Present since the contributor's first commit 1bca06b8a938 (2017-08-24, LUCENE-7940), first released in 7.1.0; the visarga lines never changed except for formatting. It reproduces on all 72 releases from 7.1.0 to 10.5.2 and on main; 7.0.1 has no Bengali API.
Versions tested5 rows
Introduced by 1bca06b8a938 "LUCENE-7490: Added bengali language analyzer" (a typo for LUCENE-7940; lucene-solr PR #238, gh#8989), 2017-08-24, by sunkuet02. rmuir landed it on 2017-09-05 on branch_7x (squash e18532cb687c, 7.1.0) and master (merge 08128f712fc8, 8.0.0 and later); CHANGES lists "LUCENE-7940: Add BengaliAnalyzer." under 7.1.0. The visarga copy and the folds arrived together in one switch. Two later commits of the same PR added the Ja-phala and Ba-phalaa bounds checks from the review (3197d5af71d, 40dddf9324e); commits after the landing only reformat or change visibility (8ef6a0da568, 8ac26737913, 694d797526a, f99deb58b74). None touches the visarga lines. Not a regression; never fixed.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the brief's test 3 of 3 fail (gradle and the standalone runner, assertions on and off) |
| 10.5.2, 9.12.3 | affected | the brief's test 3 of 3 fail; the finder's test 3 of 3; the independent reproducer's 5 of 9 |
| 7.1.0-7.7.3, 8.0.0-8.11.4, 9.0.0-9.12.3, 10.0.0-10.5.2 (72 releases) | affected | the history probe reports BUG_PRESENT on each (assertions off; 7.1.0 also on), with byte-identical output |
| 7.0.1, 7.0.0, 6.6.6 | API absent | the probe does not compile: no org.apache.lucene.analysis.bn package |
| main + fix | not affected | all repros pass; the 5 Bengali suites, 25 tests, and the module's 1,912 tests, 0 failed |
An independent reproducer, a devil's advocate, an adjudication and reviews by another model family (which ran their own tests) all found it real; the adjudication confirmed it with high confidence. Registry re-runs and a final audit reproduced it with new seeds.
Checks and verdicts450 words
Every check wrote or ran its own test against the stock jars; all but the intended-lens review also ran with assertions off.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Public-API JUnit fails 3 of 3 on main (-ea, -da), 10.5.2 and 9.12.3; with the fix 3 of 3 pass and the upstream Bengali suites 22 of 22. |
| cross-model review, refute lens | real (high) | An independent reviewer from another model family (OpenAI GPT-5.6) ran its own JUnit on main ea57360912ed (analysis sources identical to a9779ef3c193) with -ea over three seeds and -da once; it fails, and passes with the fix; it cites the existing 10.5.2 and 9.12.3 runs. |
| Independent reproducer | real | Own 9-test JUnit fails 5 of 9 on main, 10.5.2 and 9.12.3, including the end-to-end search (0 of 1 hits); its 4 controls pass; a portable main() fails on 8.11.4 and 7.7.3; found the Ba-phalaa comparison. |
| Cross-model review, intended lens | real (high) | OpenAI GPT-5.6: the intended-behaviour argument is moderate and rejected; reproduced through index-time analysis, Analyzer.normalize and the factory (-ea, on main, 10.5.2 and 9.12.3). |
| Devil's advocate | real | Re-ran the finder's test; its own probe shows বিঃশ → বিশস but বিশ্ব → বিসস, and that a second normalization pass changes the output. |
| adjudication | confirmed (high) | Re-ran the independent reproduction's test with a new seed (5 of 9 fail, -ea and -da) and the finder's (3 of 3, -da); class silent wrong results. |
| security assessment | none | 0 exceptions over 2,000,718 generated strings; no output longer than its input; the bug only loses matches; outside Lucene's SECURITY.md scope. |
| registry re-run and audit | keep | The finder's test re-run on main with new seeds (3 of 3 fail, -ea and -da); an independent full-analyzer probe with index and search fails 3 of 5, passes 5 of 5 with the fix. |
| brief runs | reproduced | The brief's test through gradle (main) and the standalone runner (main, 10.5.2, 9.12.3); options A and B validated; the i-- variant shown to hang; after the fact checks, a code-unit probe of the copy before non-folded characters (stock and both fixes). |
| fact checks of this doc | reproduced; corrections applied | An independent fact check re-ran the doc's gradle command (3 of 3 fail, assertions on and off), fix B with the 5 Bengali suites (25 tests pass), the standalone runner on main, 10.5.2 and 9.12.3, the options probe and its own closure split. A second one, by another model family (OpenAI GPT-5.6, read-only), re-read the sources and logs. A diagram check re-ran the diagram's probe. All found the bug as described; their precision corrections are applied. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 457 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,506 words
- Registry title
- BengaliNormalizer's medial-visarga rule copies the next character before that character is folded, so SHA, SSA, NNA (and the other one-to-one folded letters) survive after a visarga and those spellings stop matching the SA/NA spelling the same normalizer conflates everywhere else
- Area
- analysis-common / Bengali normalizer (BengaliNormalizer.normalize; BengaliNormalizationFilter, BengaliAnalyzer and the 'bengaliNormalization' factory)
- Priority
- Low, rank 297: Relevance-only in one language analyzer, and a miss needs variant spellings at a medial-visarga position.
- Impact class
- silent wrong results
- Impact note
- Relevance only, with no error: every application that analyzes Bengali text with BengaliAnalyzer (default constructor included), BengaliNormalizationFilter or the 'bengaliNormalization' factory, on every release from 7.1.0 through 10.5.2 and on main, gets a term that keeps the unfolded letter for every word with a medial visarga before SHA (শ), SSA (ষ), NNA (ণ) or another letter the class folds one to one (vowel signs II and UU, NGA, RRA, RHA, khanda-ta), as in common words such as নিঃশব্দ, নিঃশেষ and নিঃশ্বাস, so the SHA/SSA spelling and the SA spelling of such a word no longer match each other although the analyzer conflates them in every other position; identical spellings still match, no scale is needed, -ea and -da behave the same, and because a fix changes indexed terms, affected fields need reindexing after it.
- Summary
- You index or query Bengali text with the stock BengaliAnalyzer or BengaliNormalizationFilter. Its normalizer folds SHA (শ) and SSA (ষ) to SA (স) everywhere and turns a medial visarga (ঃ) into a copy of the next letter (gemination), so নিঃশব্দ ('silent'), নিঃষব্দ and নিঃসব্দ should all become নিসসব্দ (SA SA), just as the class's other gemination rule turns বিশ্ব into বিসস in an upstream test. Instead the visarga branch copies the next character before the loop has folded it and never revisits the copy, so নিঃশব্দ becomes নিশসব্দ (SHA SA) and নিঃষব্দ becomes নিষসব্দ (SSA SA): the three spellings give three different terms, and a document written with one of them is not found by a query written with another, with no error.
- Introduced
- 1bca06b8a938bfe89b288877399942d217c8453d (author sunkuet02; the first commit of apache/lucene-solr PR #238, LUCENE-7940 'Bengali Analyzer for Lucene', now apache/lucene#8989; its message says 'LUCENE-7490', a typo for LUCENE-7940) [read: git blame -w on main lines 112-130 and the introducing diff in the history clone]: the visarga copy s[i] = s[i+1] and the fold cases ('All sh', 'check na', II, UU, NGA, khanda-ta) arrived together in one left-to-right switch. It landed on branch_7x as the squash e18532cb687c (7.1.0) and on master through the merge 08128f712fc8 (8.0.0 and later), both by rmuir on 2017-09-05. Not a regression: the later commits on the file are formatting or visibility only (8ef6a0da568 LUCENE-9570, 8ac26737913 LUCENE-10003, 694d797526a LUCENE-10561, f99deb58b74 #13661), and the Ja/Ba-phala boundary fixes 3197d5af71d and 40dddf9324e inside PR #238 leave the visarga case unchanged. (2017-08-24 (authored; landed on branch_7x and master 2017-09-05; first released in 7.1.0))
- First affected version
- 7.1.0 [exec] (the first release with the org.apache.lucene.analysis.bn package; the history probe reports BUG_PRESENT there with -da and with -ea, all 5 controls OK). 7.0.1, 7.0.0 and 6.6.6 have no Bengali analysis API [exec: the probe does not compile], so no release ever folded the visarga copy.
- Affected versions
- Every release that ships the Bengali analysis API, 7.1.0 through 10.5.2 (72 releases: 7.1.0-7.7.3, 8.0.0-8.11.4, 9.0.0-9.12.3, 10.0.0-10.5.2), and main a9779ef3c193; not fixed. [exec] the follow-up's public-API main() probe (WhitespaceTokenizer + BengaliNormalizationFilter, and BengaliAnalyzer) reports BUG_PRESENT (4 mismatches, 5 of 5 controls OK) on each of the 72 releases with -da (7.1.0 also with -ea) and on main, and BUG_ABSENT on main with the fix sketch shadowed; the finder's JUnit fails 3 of 3 on main (-ea and -da), 10.5.2, 10.0.0, 9.12.3 and 9.1.0; the independent reproduction's JUnit fails 5 of 9 on main (-ea and -da), 10.5.2 and 9.12.3, and the independent reproduction's portable main() fails on 8.11.4 and 7.7.3. [read] the file has three blobs across all release tags in the history clone (7.1.0-8.8.1, 9.0.0-9.12.3, 10.0.0-10.5.2 and main), all with the same raw copy; upstream main a95c754ee00 (2026-10-26), branch_10x and branch_10_5 still have s[i] = s[i + 1] at line 121 (read 2026-10-27).
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (searched 2026-10-27, read-only; the prior-report record, verdict new): two scripted prior-report searches (65 and 63 queries: 47 GitHub issue/PR queries on apache/lucene, 6 commit queries, 6 downstream-repository queries, 48 mailing-list queries over the dev, java-user, issues and commits lists, 12 JIRA-archive queries, 8 web queries; 98 and 56 distinct hits, 0 high), the intended-behaviour check's own scripted prior-report search (12 GitHub, 20 mailing-list and 2 JIRA queries, 0 high), manual GitHub searches ('visarga', 'Bengali' with all 12 results read, 'BengaliNormalizer'), the changed files of all 409 open apache/lucene PRs (none under analysis/bn/), the introducing issue gh#8989 (LUCENE-7940, 30 comments) and lucene-solr PR #238 with its review (no visarga discussion), JIRA across all projects, the solr and general lists, downstream trackers (Elasticsearch, OpenSearch, Solr, lucene-solr, Lucene.NET: 'visarga' 0 hits), GitHub code search (36 copies and ports, all with the raw copy) and the file's full git history. No issue, PR, JIRA ticket, list thread, commit or web page reports that the visarga copy escapes the folds. Near-miss, not a report: another contributor's wiki page of Bengali analysis notes (mediawiki.org, written 2022-08-15, last edited 2023-04-05, linked from a comment in gh#14659) restates the rule as 'delete the visarga and double the following letter' and reports a different side effect of the same branch (a visarga used as a colon doubles the next digit, 16:9 written in Bengali digits becomes 1699), which the proposed fix does not change. Related, not the same bug: gh#14659 and PR #14699 (Telugu IndicNormalizer, open), where a maintainer defends the Indic folds as working as documented; gh#3539 (LUCENE-2465) mentions the visarga only as a character typed as ':'. Gaps: best effort; the web search did not return the wiki page (it was fetched through the gh#14659 link); code search is not exhaustive.
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-27) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the 10.5.2 and 9.12.3 release jars (the brief's test); a version-independent probe on all 72 release jars from 7.1.0 to 10.5.2 (7.0.1 has no Bengali API). Fix B was validated in the scratch worktree (the new test, the 5 Bengali suites with assertions on and off,checkGoogleJavaFormat, the whole module's 1,912 tests with assertions on and with the seed's choice); fix A with the Bengali suites and the format check.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/bn/BengaliNormalizer.java:21-28 (at a9779ef3c193) (class javadoc: 'Implements the Bengali-language specific algorithm specified in: A Double Metaphone encoding for Bangla and its application in spelling checker'; package-private class), :40-54 (chandrabindu deletion, II -> I, UU -> U), :70-73 (NGA -> anusvara), :92-110 (Ba-phalaa; :106 s[i - 1] = s[i - 2] copies an already processed character), :112-123 (visarga; :114-119 final visarga, :121 s[i] = s[i + 1]), :125-144 ('All sh' SHA/SSA -> SA, 'check na' NNA -> NA, 'check ra' RRA/RHA -> RA, khanda-ta -> TA)lucene/analysis/common/src/java/org/apache/lucene/analysis/bn/BengaliNormalizationFilter.java:26-31 (at a9779ef3c193) (javadoc: 'normalize the orthography'; 'the normalization may cause unrelated terms to conflate', KeywordAttribute protection); BengaliAnalyzer.java:104, :127, :134-138 (default constructor, the filter in createComponents and in normalize); BengaliNormalizationFilterFactory.java:35, :40 (SPI name 'bengaliNormalization')lucene/analysis/common/src/test/org/apache/lucene/analysis/bn/TestBengaliNormalizer.java:53-57 (at a9779ef3c193) (testBaPhalaa: check("বিশ্ব", "বিসস")), :59-63 (testVisarga: দুঃখ -> দুখখ, উঃ -> উহ, পুনঃ -> পুন; no folded letter after a visarga)a Lucene main checkout: git diff --stat ea57360912ed a9779ef3c193 -- lucene/analysis/ is empty (the cross-model review ran on ea57360912ed)GitHub, read-only (2026-10-27, via the follow-up prior-report step and the intended-behaviour check): apache/lucene #8989 (LUCENE-7940 comments), apache/lucene-solr PR #238 (conversation and review), apache/lucene #14659 and PR #14699, apache/lucene #3539; apache/lucene main a95c754ee00 BengaliNormalizer.java (line 121 unchanged)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/bn/BengaliNormalizer.java:21-28 (at a9779ef3c193) (class javadoc, package-private), :36-152 (the pass), :46-54, :70-73, :92-110 (Ba-phalaa; :106), :112-123 (visarga; :121), :125-144 (folds)lucene/analysis/common/src/java/org/apache/lucene/analysis/bn/BengaliNormalizationFilter.java:26-53; (at a9779ef3c193) BengaliAnalyzer.java:118-140; BengaliNormalizationFilterFactory.java:40, :54-62
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/bn/BengaliNormalizationFilter.java:29-31, (at a9779ef3c193) :48 (keyword tokens skip the normalizer); BengaliAnalyzer.java:123-125 (stem-exclusion set marked as keywords)lucene/analysis/common/src/java/org/apache/lucene/analysis/bn/BengaliAnalyzer.java:103-106, (at a9779ef3c193) :118-140; BengaliNormalizationFilterFactory.java:40
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/bn/BengaliNormalizer.java:24-26, (at a9779ef3c193) :106, :112-123, :125-144; BengaliNormalizationFilter.java:27-31lucene/analysis/common/src/test/org/apache/lucene/analysis/bn/TestBengaliNormalizer.java:53-57 (at a9779ef3c193) (testBaPhalaa), :59-63 (testVisarga), :71-88 (testRandom)
- Suggested fix
lucene/MIGRATE.md:871-873 (at a9779ef3c193)
- History
lucene/CHANGES.txt:7861 (at a9779ef3c193)
- TestBengaliVisargaRule.java (JUnit test):
repro/LFV-676/src/org/apache/lucene/analysis/bn/TestBengaliVisargaRule.java(29 lines)
A light, step-by-step picture of the repro (the word নিঃশব্দ and its spellings), made in parallel with this doc from executed runs on main a9779ef3c193 and the code.
assets/LFV-676/bug.png(457 KB)