BooleanPerceptronClassifier learns one weight per term from the labelled documents of an index, in a single pass. Its batchSize constructor argument is documented as "the size of the batch of docs to use for updating the perceptron weights".
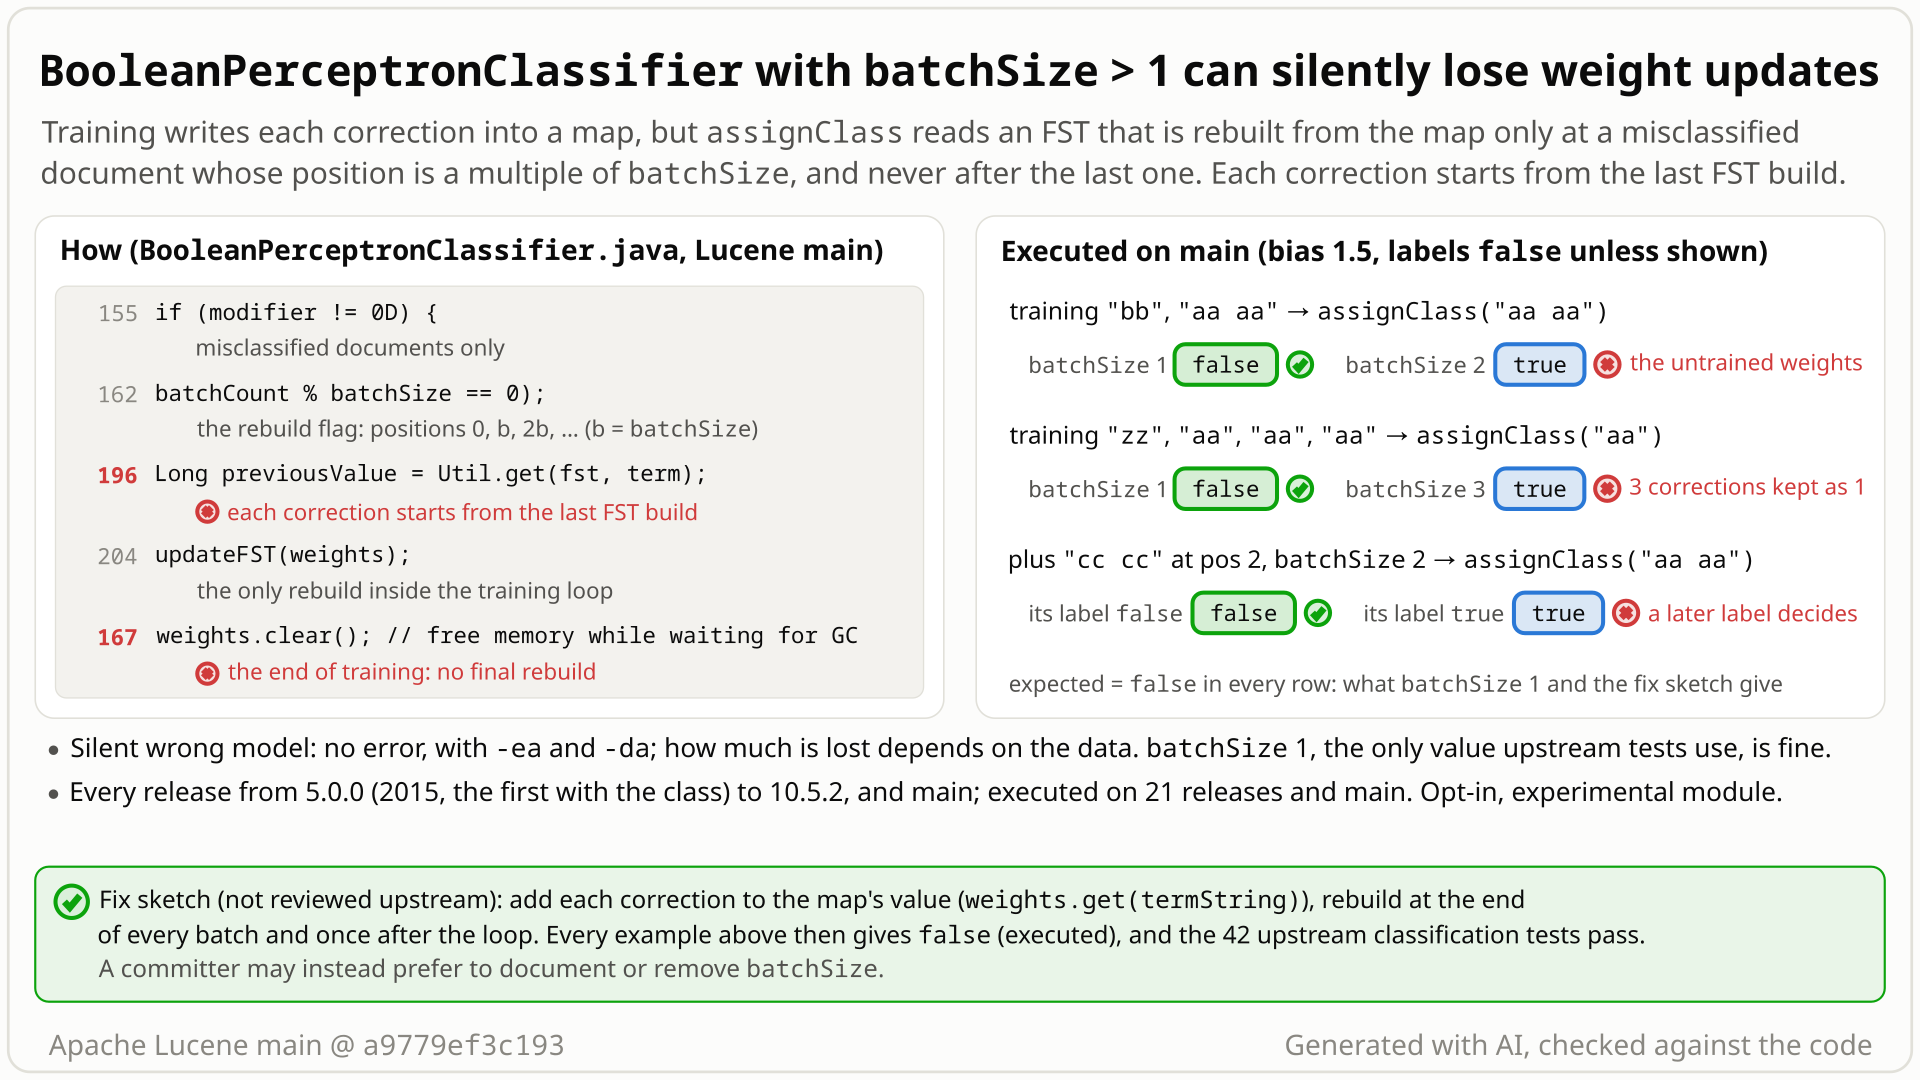
- Index two training documents, both labelled false: "bb" and "aa aa". Every term starts with its total term frequency as its weight: bb = 1, aa = 2. Train
BooleanPerceptronClassifierwith bias 1.5 and batchSize 2. - Training classifies "aa aa" as true (2 + 2 = 4 >= 1.5), which is wrong, and computes the correction aa = 2 - 2 = 0.
- You expect
assignClass("aa aa")to return false, as it does with batchSize 1 (aa = 0). - You get true (score 0.81), with no error. The correction waits in a pending map, the weight FST is rebuilt only when a misclassified document sits at position 0, 2, 4, ..., and training ends by clearing the map, so the FST still says aa = 2.
- More of the same: add "cc cc" labelled true and the update is still lost, label it false and it is applied; and three corrections of aa made before the next rebuild keep only one (aa = 2 instead of 1).
Applications that train BooleanPerceptronClassifier (the experimental lucene/classification module) with any batchSize > 1. Training is deterministic, and with batchSize > 1 the model can be wrong with no error; how much is lost depends on the data and on which documents land on rebuild points. batchSize 1, the only value Lucene's tests use, is unaffected.
Mechanism, terms and numbers760 words
BooleanPerceptronClassifier trains in its constructor: every term starts with its total term frequency as its weight, each labelled training document is classified once, and the weights of a misclassified document's terms are corrected. The weights used for classification live in an FST that is rebuilt from a pending map. With batchSize > 1 the FST is rebuilt only when a misclassified document sits at position 0, batchSize, 2 x batchSize, ..., never after the last document, and each correction is computed from the last FST build and written over the pending value. So corrections after the last rebuild are dropped when training clears the map (always including every correction in the last batch except one made by its first document), whether an earlier one survives depends on whether a later, unrelated document at a batch boundary is misclassified, and several corrections of one term between two rebuilds keep only one. Trained on "bb" and "aa aa", both labelled false, with bias 1.5 and batchSize 2, the classifier still answers true for "aa aa" (score 0.81); batchSize 1 answers false. It is silent, deterministic, the same with assertions on and off, and present in every release that has the class (5.0.0 to 10.6.0: 21 executed, the others checked by their source, 10.6.0 included) and main. batchSize 1, the only value Lucene's tests use, is unaffected. Accumulating on the pending map and rebuilding at each batch end and once after the loop fixes it; the repro and the whole classification test suite pass with that change.
BooleanPerceptronClassifier(lucene/classification,@lucene.experimental): a perceptron that assignstrueorfalseto a text.assignClass(text)sums the weights of the text's tokens and answersoutput >= bias, with score1 - exp(-|bias - output| / bias)(BooleanPerceptronClassifier.java:222-240).- Training happens in the constructor (
:81-168). Every term of the text field starts with its index-widetotalTermFreqas its weight (:116-123; like every term statistic it also counts unlabelled, filtered-out and deleted documents). The training documents, the hits of the class-field query that have a stored text and a stored class field (:130-148), are visited once, in hit order (with no training query, doc id order); each is classified, and a misclassified one moves the weights of its terms by its term frequency, towards the right answer, clamped at 0 (:140-166,:191-201). - Pending map and FST. The weights live in a pending
SortedMap("TODO : remove this map as soon as we have a writable FST",:116), and classification reads an FST rebuilt from that map (updateFST,:208-220).
- The training loop calls
updateWeightsonly for a misclassified document and passes it the rebuild flagbatchCount % batchSize == 0(:155-162);batchCountcounts every training document (:164). So the FST is rebuilt only when a misclassified document sits at position 0, batchSize, 2 x batchSize, ...: a boundary reached by a correctly classified document flushes nothing. updateWeightscomputes each new weight fromUtil.get(fst, term), the last FST build, and writes it over the pending value (:196-200); it rebuilds only if the flag is set (:203-205). So several corrections of one term between two rebuilds keep only the last one.- Training ends with
weights.clear(); // free memory while waiting for GC(:167) and no rebuild, so whatever is pending is dropped. - batchSize 1 rebuilds after every correction, so the FST always reflects the map (LFV-395's ordering defect aside) and nothing is lost. With batchSize >= the number of training documents, at most the first document's correction is applied (only if that document is misclassified).
| training documents | batchSize | answer | batchSize 1 |
|---|---|---|---|
| "bb", "aa aa" | 2 | "aa aa" -> true (score 0.81; FST aa = 2) | false (aa = 0) |
| "bb", "aa aa", "cc cc" (true) | 2 | "aa aa" -> true: "cc cc" is classified correctly, so position 2 rebuilds nothing | false |
| "bb", "aa aa", "cc cc" (false) | 2 | "aa aa" -> false: "cc cc" is misclassified at position 2, and its rebuild also flushes aa = 0 | false |
| "zz", "aa", "aa", "aa" | 3 | "aa" -> true (score 0.28; FST aa = 2): the batch is flushed at position 3, but three corrections of aa keep one | false (aa = 1) |
| "aa", "aa", "aa" | 10 | "aa" -> true (FST aa = 2): only the first correction is applied | false (aa = 1) |
Exposure and likelihood359 words
- Who is exposed. Direct users of
BooleanPerceptronClassifierwho passbatchSize> 1, the value the parameter exists for. Nothing in Lucene constructs the class outside its tests, and before the 2021 repository split Solr's classification update processor offered only the k-NN and naive Bayes classifiers. - Default vs opt-in. The public constructor has no default batchSize; the caller picks it. batchSize 1 is unaffected. No index-size prerequisite: two documents are enough.
- Silent and deterministic. The same index and settings always give the same model, with assertions on and off; when it is wrong, nothing reports it. Not every run loses a correction: in the finder's harness 314,860 of the 458,124 batchSize > 1 configurations differed from the reference. A one-pass perceptron is expected to be imperfect, so a worse model is easy to miss.
- How much is lost depends on the data. It is not a rule that a larger batch loses more: with "bb", "aa aa", "dd", "cc cc" (all false),
assignClass("aa aa")is wrong with batchSize 2 and 4 but right with 3, where the misclassified "cc cc" at position 3 triggers a rebuild. In the finder's bounded-exhaustive harness (tiny training sets) the query checks whose class or score differs from a reference perceptron grow from 1,002,793 for batchSize 2 to 1,697,228 for 3 and 1,785,810 for 5, of 3,054,160 each; they count differing answers, not lost corrections. An audit probe with 12 short spam/ham training texts,StandardAnalyzerand bias 4 answered spam for 4 of its 10 queries ("meeting tomorrow", "team lunch", "project notes", "the meeting") with batchSize 8, where a classifier that applies every batch answers ham; with the fix all 10 agree. - Cost. Measured on one synthetic 4,000-document probe only: stock batchSize > 1 trained in at most 0.54x of the batchSize 1 time (it skips rebuilds by losing updates), the fix in at most 0.76x (a shared, loaded host; relative order only; memory not measured). By construction both rebuild the FST at most 1 + ceil(N / batchSize) times for N training documents, against at most 1 + N for batchSize 1.
- How likely. Plausible but quiet: nobody has reported it since 5.0.0 (2015).
The test shows that BooleanPerceptronClassifier with batchSize 2, trained on 'bb' and 'aa aa' (both labelled false, bias 1.5), never applies the weight update for the misclassified 'aa aa' (batch position 1), because the FST is rebuilt only when a misclassified document is at a multiple of batchSize and never after the last batch.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.classification;

import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.standard.StandardAnalyzer;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.FieldType;
import org.apache.lucene.document.StringField;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestBooleanPerceptronBatchSize extends LuceneTestCase {

  public void testUpdateOfSecondDocumentInBatchIsLost() throws Exception {
    Analyzer analyzer = new StandardAnalyzer();
    FieldType textType = new FieldType(TextField.TYPE_STORED);
    textType.setStoreTermVectors(true);
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig(analyzer))) {
        for (String text : new String[] {"bb", "aa aa"}) {
          Document doc = new Document();
          doc.add(new Field("text", text, textType));
          doc.add(new StringField("cls", "false", Field.Store.YES));
          w.addDocument(doc);
        }
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        BooleanPerceptronClassifier online =
            new BooleanPerceptronClassifier(reader, analyzer, null, 1, 1.5, "cls", "text");
        BooleanPerceptronClassifier batched =
            new BooleanPerceptronClassifier(reader, analyzer, null, 2, 1.5, "cls", "text");
        assertEquals(Boolean.FALSE, online.assignClass("aa aa").assignedClass());
        // expected false (as with batchSize 1), actual true: the 'aa aa' update is dropped
        assertEquals(Boolean.FALSE, batched.assignClass("aa aa").assignedClass());
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-680/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/classification/build/libs/lucene-classification-$V.jar
CP=$CP:$LUCENE/lucene/grouping/build/libs/lucene-grouping-$V.jar
CP=$CP:$LUCENE/lucene/queries/build/libs/lucene-queries-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.classification.TestBooleanPerceptronBatchSize
- Expected vs actual
- Expected: assignClass("aa aa") = false, as with batchSize 1 on the same data. Actual on main with -ea and with -da: true (expected:<false> but was:<true>).
More files, environment, full output34 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<false> but was:<true>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:120)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.classification.TestBooleanPerceptronBatchSize.testUpdateOfSecondDocumentInBatchIsLost(TestBooleanPerceptronBatchSize.java:55)- The javadoc says batchSize is "the size of the batch of docs to use for updating the perceptron weights"; the 2013 commit called batchSize 1 "no batch updates of FST".
- Training computes each correction, then clears it with no final rebuild.
- Whether "aa aa" is learned depends on an unrelated later document's label.
The full argument257 words
- The contract. "@param batchSize the size of the batch of docs to use for updating the perceptron weights" (
BooleanPerceptronClassifier.java:74). The ordinary reading is that each batch's updates reach the weights; the javadoc does not say when, or what happens to a partial last batch. - The design, from the 2013 commit. The introducing commit called the no-argument constructor "Default constructor, no batch updates of FST" (batchSize 1): batching was meant to group FST rebuilds, not to decide which updates count. The pending map is a staging copy ("TODO : remove this map as soon as we have a writable FST",
:116), andweights.clear(); // free memory while waiting for GC(:167) treats it as already applied. - The original patch applied every update. The only attachment of LUCENE-4818 (March 2013) read the pending weight from the map and rebuilt the FST after every update; batching, the read from the last FST build and the boundary-only rebuild arrived together in the commit.
- Nothing documents dropped updates. No javadoc, CHANGES or MIGRATE entry mentions it. All five constructions in Lucene's tests pass batchSize 1 (
TestBooleanPerceptronClassifier.java:39,:54,:70,:85;TestConfusionMatrixGenerator.java:194), which is why it never showed. - An unrelated later document decides whether a computed correction is kept. Whether the correction for "aa aa" reaches the model changes with the label of "cc cc": not because "cc cc" teaches anything about "aa", but because only its misclassification triggers a rebuild. A staleness trade-off would delay an update, not keep or drop it.
The devil's-advocate check162 words
The strongest "works as designed" case, built by the intended-lens review (another model family) and the devil's advocate: the class is @lucene.experimental; the javadoc defines no mini-batch equation, no flush point and no rule for the last partial batch; batchSize could be read as a lazy FST refresh that accepts stale weights; a one-pass perceptron need not classify its training documents correctly; and only batchSize 1 was ever tested.
Why it fails: experimental status allows API changes, not a parameter that silently drops training signal. A lazy refresh would delay updates, not keep or drop one depending on a later document's label, and it would still refresh at the end. The repro compares with batchSize 1 on the same data, so it does not rely on training-set accuracy, and the expected answers hold under online and mini-batch rules alike. The missing tests explain why nobody noticed; they are not evidence of intent. Verdict: a defect (adjudication: confirmed, high; every verifier: real).
Recommended Accumulate on the pending map, rebuild at each batch end and once after the loop
Accumulate each correction on the pending weights instead of the last FST build, rebuild the FST at the end of every batch that has corrections and once after the loop (+13/-14 lines). The repro, the whole classification test suite (46 tests) and the module's format and lint checks pass.
        if (modifier != 0D) {
          updateWeights(termVectors, scoreDoc.doc, assignedClass, weights, modifier);
          pending = true;
        }
        batchCount++;
        if (pending && batchCount % batchSize == 0) {
          updateFST(weights); // end of a batch: apply its accumulated updates
          pending = false;
        }
      }
    }
    if (pending) {
      updateFST(weights); // apply the last, partial batch
    }
All options and trade-offs4 options · 661 words
Documents inside a batch are classified with the FST as it stood at the batch start (mini-batch behaviour). The fix also moves the rebuild points: stock rebuilds during the correction of a misclassified document at position 0, b, 2b, ..., so that correction is already visible to the next document; the fix rebuilds after positions b - 1, 2b - 1, ... and once after the loop. batchSize 1 behaves exactly as before. A committer may instead prefer to drop batching or deprecate batchSize, since only batchSize 1 was ever tested. Workaround until a fix ships: pass batchSize 1. Side note, from reading the code only: batchSize 0 throws ArithmeticException and a null batchSize NullPointerException at the first misclassified document; a fix could validate batchSize >= 1.
Accumulate on the pending map, rebuild at each batch end and once after the loop (validated by the checks) (recommended)
In the training loop, mark a batch as pending when a correction is made and rebuild the FST when batchCount % batchSize == 0 after the increment, then once more after the loop if anything is pending. In updateWeights, read the previous weight from the pending map (Double previousValue = weights.get(termString);) instead of Util.get(fst, term), and drop its boolean updateFST parameter and its own rebuild. +13/-14 in BooleanPerceptronClassifier.java.
        if (modifier != 0D) {
          updateWeights(termVectors, scoreDoc.doc, assignedClass, weights, modifier);
          pending = true;
        }
        batchCount++;
        if (pending && batchCount % batchSize == 0) {
          updateFST(weights); // end of a batch: apply its accumulated updates
          pending = false;
        }
      }
    }
    if (pending) {
      updateFST(weights); // apply the last, partial batch
    }
Trade-offs
- Cost: at most one rebuild per batch that has a correction, the partial last batch included (at most 1 + ceil(N / batchSize) builds, against at most 1 + N for batchSize 1). On the 4,000-document probe it trained in at most 0.76x of the batchSize 1 time, slower than today's batchSize > 1 (at most 0.54x), which skips rebuilds by losing updates; one synthetic workload, memory not measured.
- The per-update clamp at 0 (LUCENE-6853) is kept; a committer may prefer to clamp once per batch, which the javadoc does not specify.
- Models trained with batchSize > 1 change; today's models are the wrong ones.
What the checks validated
- Scratch worktree of main
a9779ef3c193, gradle: the new test passes 3 of 3; the whole:lucene:classification:testpasses with assertions on and off (13 suites, 46 tests, 0 failures, 1@Monstertest skipped). :lucene:classification:check -x testpasses (checkGoogleJavaFormat,ecjLintMain,ecjLintTest,forbiddenApisMain,forbiddenApisTest).- Standalone runner with the fix shadowed: this doc's test (
-ea,-da), the finder's (2/2) and the independent reproducer's (3/3) pass; on 5.0.0 the same minimal fix in a shadowed class passes the finder's test. - The finder's harness, re-run with the fixed class shadowed in, found the classifier matching its mini-batch reference (clamp at 0 per update) in all 12,216,640 checks.
Read the pending map and rebuild after every misclassified document, ignoring batchSize, as the original LUCENE-4818 patch did.
Trade-offs
Simplest, and identical to batchSize 1, which Lucene's tests cover. Every caller then pays one FST rebuild (linear in the vocabulary) per correction, the cost batching was added to avoid, and batchSize does nothing. Not run as a separate change.
Treat the class as batchSize 1 only.
Trade-offs
Fits an experimental class never tested with batchSize > 1. Deprecation alone changes no behaviour, and removing the parameter breaks source compatibility; callers get batchSize 1 behaviour (slower training, a correct model) only once a constructor without batchSize, or one that forces 1, exists and they move to it. Not run.
Add updateFST(weights) before weights.clear().
Trade-offs
Not recommended: it fixes the lost last batch and the later-document dependence, but not the overwrite of corrections inside a batch (test 3). Not run.
An application that uses this classifier's label for spam filtering or moderation makes wrong decisions with a model trained with batchSize > 1, but that depends on its own use of the API; no untrusted input or attacker is involved.
A bounded-exhaustive harness compared the real classifier with a reference perceptron written from its javadoc over all 1-3 document training sets on 3 words plus 20,000 seeded larger ones (12,216,640 checks): batchSize 1 always matched, batchSize > 1 often did not. A transcription of the code's own update rule pinned the cause; independent AI tools then reproduced, reviewed and judged it.
The method in full169 words
Method: semi-formal (the hunt's tier for tool-guided finds that are not a formal tool's own output): bounded-exhaustive translation validation, a hunt unit (classification, k-NN and utils against reference implementations), 2026-10-27, stock main jars.
- The harness ran the real
BooleanPerceptronClassifieron every training set of 1-3 documents over a 3-word vocabulary plus 20,000 seeded sets of 4-7 documents, with batchSize 1, 2, 3 and 5, automatic and fixed bias, and 20 query texts (every combination of 1-3 vocabulary words plus one word not in the vocabulary): 12,216,640 checks. - It compared each answer with a reference perceptron written from the class javadoc and with a transcription of the code's own update rule. batchSize 1 matched the reference everywhere; the transcription matched the real classifier everywhere; 314,860 of the 458,124 batchSize > 1 configurations differed from the reference.
- The signal came from the reference run, the root cause from the transcription. It was then reduced to a public-API JUnit test, and independent AI tools reproduced, reviewed and judged it (see the checks).
No prior report found (best-effort search, 2026-10-27): two 53-query tool runs and a 43-query run over GitHub issues, PRs and commits, the mailing lists, JIRA and the web, plus all 409 open PRs and every classification-module issue. Closest: LUCENE-4818 (#5883), which added the class, and LUCENE-6853 (#7911), a threshold fix.
Searches4 searches
No issue, PR, commit, JIRA entry, list thread, downstream issue or web page reports or discusses that BooleanPerceptronClassifier with batchSize > 1 loses weight updates. Not fixed: the file is unchanged on upstream main a95c754ee003 and branch_10x since 942065cc3e7e (2024-09-10, record conversion).
Closest items, none a report of this bug: #5883 (LUCENE-4818) added the class, and its comments say nothing on batching; #7911 (LUCENE-6853) fixed the classifier's threshold sensitivity in 2017 (the clamp at 0) and left the three batch fragments in place; #7107 (LUCENE-6045) added the batchSize javadoc for precommit; #6761 (LUCENE-5699) is about score normalization; open PR #16847 is the only open PR touching the file and changes only the updateWeights docId type. Gaps: GitHub's search rate limit was reached; closed, unmerged PRs were checked by text search only; code search shows the first 30 copies; private channels cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene, lucene-solr, solr; two downstream search engines) | 2026-10-27 | scripted prior-report search, two specs of 53 queries each plus the finder's earlier 43-query run; manual searches | no report; 12 hits read, none the same bug |
| Open PRs and the classification module | 2026-10-27 | the changed files of all 409 open apache/lucene PRs; all 68 issues and PRs labelled module:classification | only #16847 touches the file (a parameter type); only #5883 and #7911 concern the perceptron |
| JIRA archive and mailing lists | 2026-10-27 | all 47 JIRA issues of the classification component (summary, description, comments); dev@, java-user@, issues@, commits@, general@ | no mention of batching; perceptron mails map to known commits |
| Web and local history | 2026-10-27 | 8 web queries; git log of the file (34 commits) and git log --grep=batch on the module | nothing relevant; the batch logic dates from 2013 |
Introduced with the class itself in LUCENE-4818 (2013, 05940e34ab8) and first released in 5.0.0; the batch logic is unchanged since. The repro fails on all 21 releases run from 5.0.0 to 10.5.2 and on main, and every other release's source has the same three fragments; no earlier release has the class.
Versions tested7 rows
Introduced by 05940e34ab8 (trunk, 2013-09-03, @tteofili, svn r1519590, "LUCNE-4818 - added boolean perceptron classifier"; issue LUCENE-4818, now #5883; no pull request). The first version already has all three fragments: the boundary-only rebuild flag passed only for misclassified documents, the read from the last FST build, and no rebuild after the loop. The issue's only patch (March 2013) had no batching. It reached a release through the branch_5x backport 55594bad9b0 (LUCENE-5944, 2014-09-18): first release 5.0.0 (2015-02-19); on the trunk line it first ships in 6.0.0.
Not a regression. Later commits (LUCENE-6433, LUCENE-6045, LUCENE-6853, the 2021 reformat, #12010, #13328) touched the file but left the three fragments in place: LUCENE-6433 (dbf063d3d1e) moved batchCount++ inside the new stored-field check and LUCENE-6853 (cbad533d7a4) added the clamp at 0, but no commit changed the conditional rebuild, the read from the last FST build or the missing final rebuild. All 98 release tags that contain the file have the three fragments; the 9 late 8.x releases, which have no tag in the apache/lucene repository, were all executed. Upstream main a95c754ee00, branch_10x and branch_10_6 carry the same file as a9779ef3c193.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's test: 3 of 3 fail (gradle and the standalone runner, assertions on and off); the finder's test: 2 of 2 fail |
| 10.0.0, 10.5.2, 9.12.3 | affected | this doc's test: 3 of 3 fail, the same messages and scores |
| 5.0.0, 5.5.5, 6.0.0, 6.3.0, 6.4.0, 6.6.6, 7.0.0, 7.7.3, 8.8.2, 8.9.0, 8.10.0, 8.10.1, 8.11.0, 8.11.1, 8.11.2, 8.11.3, 8.11.4, 9.0.0 | release sweep | the finder's test in API-adapted copies (assertions on): 2 of 2 fail, the batchSize 1 control passes (5.0.0 also with a second seed and with assertions off) |
| every other release from 5.0.0 to 10.5.2 | by source | all 98 release tags that contain the file have the three fragments (conditional rebuild, read from the last FST build, no final rebuild) |
| 5.0.0 with only this class shadowed | fix control | the minimal batch fix passes; the unmodified 5.0.0 file fails |
| 4.10.4 and earlier | no API | the class does not exist (only the k-NN and naive Bayes classifiers) |
| main + the fix | not affected | every repro passes; the whole classification test suite and the module's checks pass |
An independent reproducer, two executed reviews by another model family, a devil's advocate and an audit each found it real with their own tests; an adjudication confirmed it by re-running two of them with fresh seeds. This doc's own test reproduced it through gradle and validated the fix.
Checks and verdicts419 words
Every check on main ran on the stock jars with assertions on and off (the fix checks with a shadowed class). The reviews by the other model family (OpenAI GPT-5.6) executed their own tests on main ea57360912ed, whose classification module is identical to a9779ef3c193; a separate run re-ran the intended lens's test and the finder's test on a9779ef3c193.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Bounded-exhaustive harness (12,216,640 checks); public-API JUnit fails 2 of 2 on main (-ea, -da), 10.5.2 and 9.12.3; passes with the fix, as do the 42 upstream classification tests. |
| Independent reproducer | real | Own 3-test JUnit with other data fails 3 of 3 on main (-ea, -da), 10.5.2 and 9.12.3, including a pending update never applied across two later complete batches; controls pass; passes with the fix. |
| Cross-model review, refute lens | real (high) | Another model family (OpenAI GPT-5.6), executed: own test fails on main (-ea, -da); moving the misclassified document to batch position 0 makes its update count; passes with the fix. Intended-behaviour argument: moderate. |
| Cross-model review, intended lens | real (high) | Own batch-position and repeated-term tests fail 2 of 2 on main (-ea, -da); the position test also fails on 10.5.2 (1 of 1); both pass with the fix; 5 relevant upstream tests pass with the fix. Intended-behaviour argument: moderate. |
| Devil's advocate | real | Built the strongest "works as designed" case and rejected it; its probe shows that the label of an unrelated third document decides whether "aa aa" is learned, and isolates the in-batch overwrite; found that the original LUCENE-4818 patch applied every update. |
| adjudication | confirmed (high) | Re-ran the independent reproduction's JUnit with seed 1A2B3C4D (3 of 3 fail with -ea and -da, controls pass, passes with the fix) and the finder's with -da (2 of 2 fail); no duplicate. |
| registry re-runs and audit | keep | New seeds: the finder's test fails 2 of 2 (-ea, -da) and passes with the fix. An independent plain-main() probe with StandardAnalyzer disagrees with an apply-every-batch reference on 4 of 10 queries at batchSize 8, and on none with the fix. |
| this doc's runs | reproduced, fix validated | The doc's 3-test JUnit fails 3 of 3 through gradle (assertions on and off) and the standalone runner on main, 10.0.0, 10.5.2 and 9.12.3; with the fix it and the whole classification test suite pass, and :lucene:classification:check -x test passes. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 463 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,429 words
- Registry title
- BooleanPerceptronClassifier with batchSize > 1 can silently lose the weight updates of misclassified training documents: the weight FST is rebuilt only when a misclassified document sits at a multiple of batchSize and never after the last batch, and updates inside a batch are computed from the last FST build and overwrite each other, so the trained model is wrong (released since 5.0.0)
- Area
- classification / BooleanPerceptronClassifier (batched training)
- Priority
- Medium, rank 185: Any batchSize greater than 1 silently gives a wrong perceptron model on every training run, but it is limited to the less used BooleanPerceptronClassifier.
- Impact class
- silent wrong results
- Impact note
- Applications that use the opt-in, @lucene.experimental lucene/classification module and build a BooleanPerceptronClassifier with any batchSize > 1 get a silently wrong model on every training run, with -ea and -da alike and no error: updates of misclassified documents made after the last FST rebuild (always including the final batch, and any batch whose boundary document happens to be classified correctly) never reach the model, and several updates of one term inside a batch keep only one; the larger the batch, the more is lost (with batchSize >= the number of training documents at most the first document's update is applied), no scale is needed, batchSize 1 (the only value upstream tests use) is unaffected, and every release from 5.0.0 through 10.6.0 (10.6.0 by reading) and main is affected.
- Summary
- You index two training documents labelled false, 'bb' and 'aa aa', train BooleanPerceptronClassifier with bias 1.5 and batchSize 2, and expect assignClass('aa aa') = false, which is what batchSize 1 gives on the same data and what both an online and a mini-batch perceptron give. Instead it returns true (score 0.81): the update for the misclassified 'aa aa' (batch position 1) is written only to the pending weight map, because the FST that holds the weights is rebuilt only when a misclassified document sits at a position that is a multiple of batchSize, and the constructor ends by clearing that map without a final rebuild. Updates inside a batch are also computed from the last FST build and overwrite each other, so with batchSize 10 and three training documents 'aa' labelled false only the first update is applied and the model still answers true.
- Introduced
- 05940e34ab8c2a961fef8498b39d592f4099e8e2 (trunk, svn r1519590, message 'LUCNE-4818 - added boolean perceptron classifier' ('LUCNE' is a typo in the original); issue LUCENE-4818 'Create a boolean perceptron classifier', migrated as GitHub issue #5883; by GitHub tteofili; svn era, no pull request) [read: git log --follow, git blame and git log -S on the defect fragments in the full-history clone]: the first committed version already has all three fragments (the rebuild flag batchCount % batchSize == 0 passed only for misclassified documents, the update read from the last FST build with Util.get(fst, term), and no rebuild after the loop). The issue's only attachment, LUCENE-4818.patch (March 2013), had no batching: it read the pending weight from the map and rebuilt the FST after every update, so batching and the stale read arrived in the commit. It reached a release through the branch_5x creation backport 55594bad9b0 (LUCENE-5944, 2014-09-18). Not a regression: later commits (LUCENE-6433 dbf063d3d1e / 70ce247cdb0, LUCENE-6479 8b2e0d937d5, LUCENE-6853 cbad533d7a4, the 2021 reformat 7f8b7ffbcad, 06f91792957, 47f8c1baa2e) left the batch logic unchanged. (2013-09-03 (05940e34ab8, trunk); 2014-09-18 (branch_5x backport 55594bad9b0); first release 5.0.0, tagged 2015-02-19)
- First affected version
- 5.0.0 [exec] (the first release with the class, via the branch_5x backport: the 5.x API copy of the repro fails 2 of 2 with -ea (seeds DEADBEEF and 0BADF00D) and -da; shadowing only BooleanPerceptronClassifier with the minimal batch fix makes it pass, while shadowing the unmodified 5.0.0 file still fails). No earlier release has the class (the 4.10.4 classification jar holds only Classifier, KNearestNeighborClassifier and SimpleNaiveBayesClassifier [exec: jar listing]). On the trunk line the first release tag containing 05940e34ab8 is 6.0.0, which is also the JIRA fix version.
- Affected versions
- Every release that has the class, 5.0.0 through 10.5.2 (107 releases) and 10.6.0 (by reading), and main a9779ef3c193; not fixed upstream. [exec] the finder's repro (lost update at batch position 1 with batchSize 2; batchSize 10 applies only the first of three updates; batchSize 1 controls pass), in API-adapted copies for old releases, fails 2 of 2 on 5.0.0 (-ea two seeds, -da), 5.5.5, 6.0.0, 6.3.0, 6.4.0, 6.6.6, 7.0.0, 7.7.3, 8.9.0, 8.11.4, 9.0.0, 9.12.3 (-ea, -da), 10.0.0, 10.5.2 (-ea, -da) and main a9779ef3c193 (-ea two seeds, -da); the independent reproduction's own test fails 3 of 3 on main, 10.5.2 and 9.12.3. [read] the other releases by code identity (file blobs 993dd9e3b5 through d45bcb1f81 all contain the three fragments; 8.8.2-8.11.3, released from the old lucene-solr repository, lie between 8.8.1 and the executed 8.9.0 and 8.11.4); upstream main a95c754ee00 (2026-10-26), branch_10x 1309534296e and branch_10_6 2763db11b0a carry the same file blob d45bcb1f81 as a9779ef3c193, and the only open PR touching the file (#16847) changes just a parameter type.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-27, read-only; the prior-report record verdict new): a scripted prior-report search in two runs of 53 queries each (GitHub issues, PRs and commits, downstream repositories, the dev, java-user, issues and commits lists, JIRA and the web) plus the finder's earlier 43-query run; manual GitHub searches on apache/lucene, lucene-solr, solr and two downstream search engines; the changed files of all 409 open apache/lucene PRs (only #16847 touches the file, and only the updateWeights docId type); all 68 module:classification issues and PRs; all 47 JIRA issues of component modules/classification (only LUCENE-4818, 5290, 5311, 5699, 6045 and 6853 mention the perceptron, none mentions batching); the mailing list archives; the web; and the local history (git log --all --grep=batch -- lucene/classification finds nothing). 12 hits assessed, none the same bug; the nearest are #5883 / LUCENE-4818 (adds the class, nothing on batching) and #7911 / LUCENE-6853 (threshold/bias sensitivity, fixed in 2017, batch logic untouched). Not fixed: the file is unchanged on upstream main a95c754ee003 and branch_10x since 942065cc3e7e (2024-09-10).
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-27) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the 10.0.0, 10.5.2 and 9.12.3 release jars (this doc's test). The release runs used assertions on. The finder's test, in API-adapted copies, fails on 21 releases from 5.0.0 to 10.5.2 and on main. The cross-model reviews ran on mainea57360912ed, whose classification module is identical toa9779ef3c193; the intended lens's test and the finder's test were re-run ona9779ef3c193. The fix was validated in the scratch worktree: the new test, the whole:lucene:classification:test(assertions on and off) and:lucene:classification:check -x test.
- Finding record
lucene/classification/src/java/org/apache/lucene/classification/BooleanPerceptronClassifier.java:50-57 (at a9779ef3c193) (class javadoc: weights from totalTermFreq, FST used for class assignment; @lucene.experimental)lucene/classification/src/java/org/apache/lucene/classification/BooleanPerceptronClassifier.java:74 (at a9779ef3c193) (javadoc '@param batchSize the size of the batch of docs to use for updating the perceptron weights')lucene/classification/src/java/org/apache/lucene/classification/BooleanPerceptronClassifier.java:116-124 (at a9779ef3c193) (pending weight map 'TODO : remove this map as soon as we have a writable FST'; initial weights; first updateFST)lucene/classification/src/java/org/apache/lucene/classification/BooleanPerceptronClassifier.java:128, (at a9779ef3c193) :155-164 (batchCount counts every labelled training document; the rebuild flag batchCount % batchSize == 0 is passed only to updateWeights, which runs only for misclassified documents)lucene/classification/src/java/org/apache/lucene/classification/BooleanPerceptronClassifier.java:167 (at a9779ef3c193) (weights.clear() with no final rebuild)lucene/classification/src/java/org/apache/lucene/classification/BooleanPerceptronClassifier.java:196-200 (at a9779ef3c193) (update computed from Util.get(fst, term), the last FST build, and written over the pending value)lucene/classification/src/java/org/apache/lucene/classification/BooleanPerceptronClassifier.java:203-205 (at a9779ef3c193) (the only conditional rebuild)
- The finding in 30 seconds
lucene/classification/src/java/org/apache/lucene/classification/BooleanPerceptronClassifier.java:50-57, :74, :81-168, :170-206, :208-220, :222-240; lucene/core/src/java/org/apache/lucene/index/TermsEnum.java:133-137 (totalTermFreq counts deleted documents)
- Who is affected
lucene/classification/src/java/org/apache/lucene/classification/BooleanPerceptronClassifier.java:57, :81-89grep -rl BooleanPerceptronClassifier lucene/*/src/java (only the class itself), 2026-10-27
- Why it looks unintended
lucene/classification/src/java/org/apache/lucene/classification/BooleanPerceptronClassifier.java:57, :74, :116, :167lucene/classification/src/test/org/apache/lucene/classification/TestBooleanPerceptronClassifier.java:39-40, :54-55, :70-71, :85-86; lucene/classification/src/test/org/apache/lucene/classification/utils/TestConfusionMatrixGenerator.java:194-195
- Suggested fix
lucene/classification/src/java/org/apache/lucene/classification/BooleanPerceptronClassifier.java:155-167, :196-205
- History
a Lucene clone: git show <tag>:lucene/classification/src/java/org/apache/lucene/classification/BooleanPerceptronClassifier.java for each of the 98 release tags that contain it (all three fragments present)
- TestBooleanPerceptronBatchSize.java (JUnit test):
repro/LFV-680/src/org/apache/lucene/classification/TestBooleanPerceptronBatchSize.java(59 lines)
A summary still; the PNG is the summary. This caption and alt text follow the traced scenarios as they stood when the doc was written.
assets/LFV-680/bug.png(463 KB)