DatasetSplitter (module lucene/classification) copies the documents of an index into a training, a test and a cross-validation index. fieldNames picks the fields to copy, or null for all of them. Every copied value becomes a stored, indexed TextField in the new index.
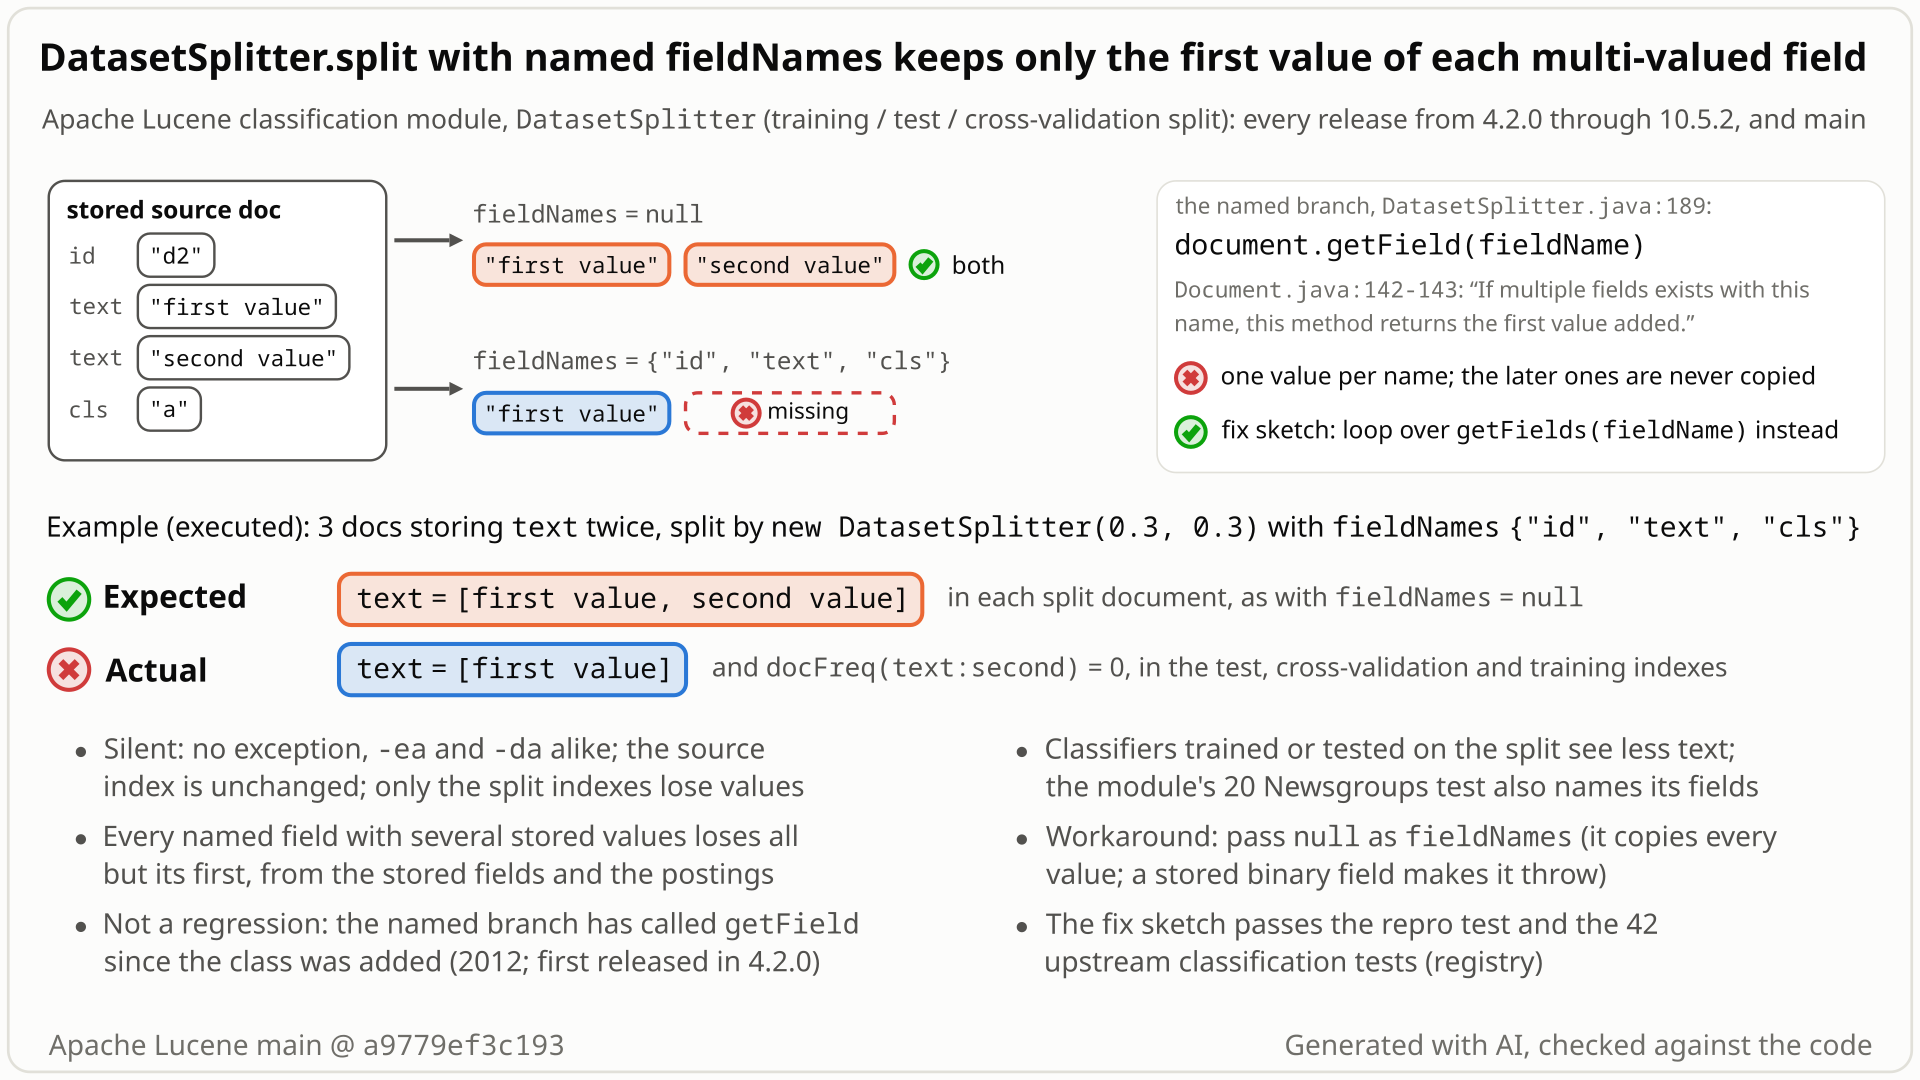
text values, split with fieldNames = null (both values arrive) and with {"id", "text", "cls"} (the second is missing), beside the line that causes it, document.getField(fieldName). Select the still to open it at full size. Generated with AI, checked against the code.- Index 3 documents whose stored
textfield has two values, "first value" and "second value". Split them withnew DatasetSplitter(0.3, 0.3): one document goes into each of the test, cross-validation and training indexes. - With no field names (
null, "all should be used"), each copied document keeps both values, and the termsecondis in every output index:docFreq(text:second)= 1. - Now name every stored field,
"id", "text", "cls". You expect the same three indexes. - You get
text= [first value] in all three anddocFreq(text:second)= 0, so a classifier trained on the split never sees the second value. No error, with assertions on or off; the source index is unchanged. - Why: for each name, the copy takes
document.getField(name), which returns only the first value added, while thenullbranch loops over every value. Looping overgetFields(name)fixes it.
Users of the opt-in lucene/classification module who prepare data with DatasetSplitter.split and name the fields to copy, on documents where a named stored field has several values (tags, authors, a body stored in parts). The default, null, does not lose values. No setting or scale is needed, and the source index is never changed.
Mechanism, terms and numbers551 words
DatasetSplitter.split copies the documents of an index into a training, a test and a cross-validation index for classifier work. Its fieldNames parameter lists the "names of fields that need to be put in the new indexes or null if all should be used". With null it copies every stored text, string and numeric value; with names it calls document.getField(fieldName) once per name, and Document.getField returns only the first value when several fields share the name. So every value after the first of a named multi-valued field is silently dropped, from the stored fields and from the postings of all three output indexes, because each output field is re-indexed from the copies. On 3 documents with two text values each, naming every stored field leaves text = [first value] and docFreq(text:second) = 0 in each output index, where null keeps both values and 1. It needs the opt-in classification module and an explicit name list, is in every release from 4.2.0 to 10.6.0 (10.6.0 by reading) and main, and looping over getFields(fieldName) fixes it.
- Split:
new DatasetSplitter(testRatio, crossValidationRatio).split(reader, training, test, cv, analyzer, termVectors, classFieldName, fieldNames...)groups the source documents by class and sends each one to the test, cross-validation or training index (DatasetSplitter.java:80-180). fieldNames: "names of fields that need to be put in the new indexes ornullif all should be used" (:76-77).- Multi-valued field: a document may hold several fields with the same name ("A Document is a set of fields",
Document.java:31).getField(name)returns the first one,getFields(name)all of them (Document.java:141-161).
- Every output field gets the same type,
new FieldType(TextField.TYPE_STORED)(DatasetSplitter.java:129). createNewDocreads the stored source document (:186). With a non-emptyfieldNames(:187) it takes, for each name,IndexableField field = document.getField(fieldName)(:189) and addsnew Field(fieldName, field.stringValue(), ft)(:191).Document.getField: "If multiple fields exists with this name, this method returns the first value added" (Document.java:142-143). The other values are never read.- With
nullor no names it loops overdocument.getFields()(:195) and copies every value (:196-204); a stored binary field makes that branch throw instead (:198-199,Field.java:213-214). - So in named mode each output document has one value per named field. The output index is built from these copies, so the dropped values are missing from the stored fields and from the postings of the test, cross-validation and training indexes alike.
Source: 3 documents d0, d1, d2, each with id, text = "first value" + "second value" (stored TextFields) and class cls = "a" (stored, plus sorted doc values). new DatasetSplitter(0.3, 0.3) sends d0 to test, d1 to cross-validation and d2 to training (executed, stock main):
fieldNames | test (d0) | cross-validation (d1) | training (d2) |
|---|---|---|---|
null | text = [first value, second value], docFreq(text:second) = 1 | same | same |
{"id", "text", "cls"} | text = [first value], docFreq(text:second) = 0 | same | same |
{"id", "text", "cls"}, with the fix | text = [first value, second value], docFreq(text:second) = 1 | same | same |
At a larger size (the security screen's probe: 257 live documents in 12 segments), naming every field kept 257 of 641 body values and 257 of 342 acl values, one per document; null kept all of them.
Exposure and likelihood186 words
- Who is exposed. Callers of
DatasetSplitter.splitwith a non-emptyfieldNameslist. Passing names is the module's own pattern:Test20NewsgroupsClassification(a@Monstertest) splits withCATEGORY_FIELD, BODY_FIELD, SUBJECT_FIELD, CATEGORY_FIELD, with single-valued fields, so it is not hit itself. No production code in Lucene calls the class. - What triggers it. Any named field with more than one stored value. One document with two values shows it; every such document loses values, deterministically.
- What breaks. The split indexes, and so classifiers trained or evaluated on them, see fewer values than the source: in the probe of 257 documents about 60% of the
bodyvalues (384 of 641) were gone. Silent: no exception,CheckIndexclean on all 9 output indexes of the probe. - Not affected. The source index (its contents;
split()does close the reader it is given),nullor emptyfieldNames, single-valued fields, and which document goes to which index. - How likely. Certain once a named text, string or numeric field has several values, but the utility has few users, the loss only shows as weaker training data, and no public report was found (104 logged queries).
The test shows that DatasetSplitter.split(..., "cls", "text") with an explicit field name copies only the first value of the multi-valued stored field text into the split index.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.classification.utils;

import java.util.Arrays;
import java.util.List;
import org.apache.lucene.analysis.standard.StandardAnalyzer;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.SortedDocValuesField;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;

public class TestDatasetSplitterMultiValuedField extends LuceneTestCase {

  public void testNamedFieldKeepsAllValues() throws Exception {
    try (Directory src = new ByteBuffersDirectory();
        Directory train = new ByteBuffersDirectory();
        Directory test = new ByteBuffersDirectory();
        Directory cv = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(src, new IndexWriterConfig())) {
        Document doc = new Document();
        doc.add(new TextField("text", "first", Field.Store.YES));
        doc.add(new TextField("text", "second", Field.Store.YES));
        doc.add(new SortedDocValuesField("cls", new BytesRef("a")));
        w.addDocument(doc);
      }
      DirectoryReader reader = DirectoryReader.open(src);
      new DatasetSplitter(0, 0)
          .split(reader, train, test, cv, new StandardAnalyzer(), false, "cls", "text");
      try (DirectoryReader r = DirectoryReader.open(train)) {
        // expected: both values of the named field "text"; actual: only the first one
        assertEquals(
            List.of("first", "second"),
            Arrays.asList(r.storedFields().document(0).getValues("text")));
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-681/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/classification/build/libs/lucene-classification-$V.jar
CP=$CP:$LUCENE/lucene/grouping/build/libs/lucene-grouping-$V.jar
CP=$CP:$LUCENE/lucene/queries/build/libs/lucene-queries-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.classification.utils.TestDatasetSplitterMultiValuedField
- Expected vs actual
- Expected: the training document stores both values
[first, second]; actual (-ea and -da):[first]only, becausecreateNewDoccopiesdocument.getField(name)(DatasetSplitter.java:189).
More files, environment, full output35 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<[first, second]> but was:<[first]>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:120)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.classification.utils.TestDatasetSplitterMultiValuedField.testNamedFieldKeepsAllValues(TestDatasetSplitterMultiValuedField.java:53)- The javadoc:
fieldNamesare the "names of fields that need to be put in the new indexes", with no one-value limit. nullmeans "all should be used" and copies every value, so naming every field gives less than "all".- No test, javadoc or CHANGES entry records a first-value rule; LUCENE-5833 and SOLR-8871 made the same change elsewhere.
The full argument197 words
- Contract. "@param fieldNames names of fields that need to be put in the new indexes or
nullif all should be used" (DatasetSplitter.java:76-77). It selects fields by name against "all"; it is implied, not stated, that a named field keeps all its values. - Symmetry. The
nullbranch of the same method copies every value (:194-205); naming every field of a document gives a smaller result thannullfor the same document. - Tests.
TestDataSplitteradds one value per field and checks onlymaxDocper output; itstestSplitOnSomeFieldsnamesidandtext. No test uses a multi-valued field withfieldNames, and the fix keeps the whole module suite green. - History. The named branch has read
getField(fieldName)since the first commit (3459b28334e, LUCENE-4345, 2012), next to anelsebranch that looped overgetFields(); LUCENE-4345 never discusses multi-valued fields. No javadoc, comment, CHANGES or MIGRATE entry records a first-value rule. - Precedents. LUCENE-5833 (2014,
DocumentDictionary, CHANGES "New Features": it "now enumerates each value separately in a multi-valued field (not just the first value)") and SOLR-8871 (96489d23846, 2016,KNearestNeighborClassifier, part of a set of classification improvements) made the same change.
The devil's-advocate check196 words
The strongest "intended" case (the cross-model reviewers rated it moderate; the devil's-advocate verifier rejected it): Document.getField documents first-value semantics, so the code does what it calls; the splitter is lossy anyway (every copied value is rebuilt as a stored TextField, doc values and points are dropped); the line is unchanged since 2012; some classifiers in the module read only the first value; and both precedents went in as a feature or an improvement, not as bug fixes.
Why it fails: the lossiness both modes share changes field types, never values; named mode alone drops values, from the stored fields and the postings (the verifier's 3-valued field: tags:beta matches 0 of 6 training documents named, 6 of 6 with null). The javadoc sets names against "all should be used", so naming every field should equal null. Here the full behaviour already exists in the same method, while the precedents added it where it did not. What a classifier reads is a separate choice; the splitter decides what data exists at all. Every reviewer rated the bug real, and the adjudication confirmed it with high confidence; a maintainer may still label the fix an improvement.
Recommended Loop over every value of each named field (fix A)
In createNewDoc, loop over document.getFields(fieldName) instead of taking document.getField(fieldName) (one changed loop at DatasetSplitter.java:189). The repro then passes 2 of 2, and TestDataSplitter, the whole lucene/classification suite (assertions on and off) and check -x test pass with it.
     if (fieldNames != null && fieldNames.length > 0) {
       for (String fieldName : fieldNames) {
-        IndexableField field = document.getField(fieldName);
-        if (field != null) {
+        for (IndexableField field : document.getFields(fieldName)) {
           doc.add(new Field(fieldName, field.stringValue(), ft));
         }
       }
All options and trade-offs4 options · 608 words
One fix was built and validated in a scratch worktree of a9779ef3c193; the alternatives are listed with their trade-offs.
In createNewDoc (DatasetSplitter.java:189), iterate document.getFields(fieldName) instead of taking document.getField(fieldName). A name the document lacks still adds nothing, because getFields returns an empty array. The hunt's own fix is the same change.
     if (fieldNames != null && fieldNames.length > 0) {
       for (String fieldName : fieldNames) {
-        IndexableField field = document.getField(fieldName);
-        if (field != null) {
+        for (IndexableField field : document.getFields(fieldName)) {
           doc.add(new Field(fieldName, field.stringValue(), ft));
         }
       }
Trade-offs
- Named mode then copies every value of each named field, in order, like
nullmode; the repro's three indexes hold both values anddocFreq(text:second)= 1 each. - No change in meaning was found for text and string values, the only kind the fix was run with. Output size and indexing work grow with the values now kept (the security probe's two 20,000-value documents: 40,000 values copied instead of 2).
- A named field whose first value is text and a later value binary is copied (text only) today; with the fix the binary value is reached and
split()throws (Field.java:245). Binary, numeric and mixed-type values andtermVectors = truewere not run with the fix. - It keeps two limits that both modes share and that are not this bug: a stored binary field makes
split()throw (named mode:value must not be null;nullmode:cannot set a BytesRef value on a tokenized field), and numeric fields are copied as text.
What the checks validated
- Gradle, JDK 25, scratch worktree of
a9779ef3c193: the new test fails 1 of 2 on stock with assertions on and off; with the fix, the new test plusTestDataSplitterpass (2 suites, 4 tests), the whole:lucene:classification:testpasses with assertions on and off (13 suites, 45 tests, 1 skipped, 0 failures each), and:lucene:classification:check -x testpasses. - Standalone runner with the fix shadowed: the new test 2 of 2 (
-ea,-da), the finder's test 1 of 1, the devil's-advocate verifier's test 3 of 3. - Earlier, in the hunt: the 42 upstream classification tests with the same change.
Move the per-value copy of the null branch (DatasetSplitter.java:196-204) into a helper and call it from both branches, the named one looping over getFields(fieldName).
Trade-offs
The two modes share one code path and cannot drift again, but it is a larger diff. Numeric fields come out the same (both branches copy them as text); a named binary field would still make split() throw, only with the null branch's message (cannot set a BytesRef value on a tokenized field instead of value must not be null).
Add "only the first value of each named field is copied" to the fieldNames javadoc.
Trade-offs
No behaviour change: the silent loss and the difference from null mode stay.
Pass null (or no) field names: every value of every stored text, string or numeric field is copied; a stored binary field in the source makes this mode throw. Or store multi-valued content as one value per field before splitting. The source index is untouched, so re-running the split after a fix is enough, into new or empty output directories: split() opens its writers with the default OpenMode.CREATE_OR_APPEND (DatasetSplitter.java:92-94, LiveIndexWriterConfig.java:135), so re-using the old ones appends to the faulty output.
Trade-offs
null also copies stored fields you did not want.
The Lucene.NET port has the same named-field copy (unreported); issue searches in Solr, OpenSearch and Elasticsearch found no mention of DatasetSplitter.
An AI finder ran a bounded-exhaustive check of the real DatasetSplitter.split on every small index of 1-4 documents, checking that each copied document keeps all values of the requested fields. Over those sizes it found 3,392 mismatches in 24,816 splits (4 documents alone: 2,696 in 20,736), all with named fields and a 2-valued field; a public-API JUnit confirmed it.
The method in full182 words
Method: semi-formal (a bounded-exhaustive check of the real code), then a JUnit test. A hunt unit (classification k-NN and utilities against reference semantics), 2026-10-27, main a9779ef3c193.
- The finder's checker enumerated 1 to 4 documents (class none, a or b; 1 or 2 values of a stored
textfield; one segment or one per document; no deletion or the first document deleted;fieldNamesnullor{id, text, cls}; ratios 0.1 / 0.1 or 0.5 / 0.25) and ran the realspliton each, checking among others C2: each output document has the requested stored fields with all of their values. - Over all indexes of 1-4 documents (the checker's counters run on across sizes): 3,392 field mismatches in 24,816 splits; 4 documents alone: 2,696 in 20,736. All are in named mode with a 2-valued field, none in
nullmode; splits that threw or lost a document are counted separately. Example: expectedtext=[t0v0, t0v1], gottext=[t0v0]. - The finding was reduced to a public-API JUnit on the stock main jars that fails with assertions on and off, and on 10.5.2 and 9.12.3.
No prior report found (searched 2026-10-27): 104 logged queries over GitHub issues, PRs and commits, JIRA, the mailing lists, downstream projects and the changed files of every open PR. The nearest items are about class grouping and counting; LUCENE-5833 and SOLR-8871 made the same change elsewhere.
Searches5 searches
None of the hits is the same bug. The nearest items are listed below.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene, lucene-solr, solr, lucenenet, OpenSearch, Elasticsearch, all of GitHub) | 2026-10-27 | the scripted prior-report search (16 issue and PR, 3 commit, 2 downstream queries) and manual searches: DatasetSplitter, createNewDoc, fieldNames, getField, multi-valued, "only the first value"; every body and comment of the 68 module:classification issues and PRs; a code search | no report; #8251, #8453 and #8642 are about class grouping and counting |
| Open PRs | 2026-10-27 | the changed files of every open apache/lucene PR | #16847 is the only one touching DatasetSplitter.java (Math.toIntExact(maxDoc())); createNewDoc untouched |
| JIRA and mailing lists | 2026-10-27 | LUCENE and SOLR, including all 47 LUCENE modules/classification issues; dev@, java-user@, issues@, commits@ and four more lists (solr-user@lucene, users@solr, dev@solr, general@lucene) | no report; the LUCENE-4345 commit mail got no replies |
| History, CHANGES and the web | 2026-10-27 | the file's full git history, CHANGES.txt and MIGRATE.md, 6 web queries | no change to the first-value behaviour; only generic multi-valued Q&A on the web |
| Nearest items (read) | 2026-10-27 | #5411 / LUCENE-4345, #8251 / LUCENE-7196, #8453 / LUCENE-7400, #8642 / LUCENE-7591, #12942, #6895 / LUCENE-5833, SOLR-8871, lucenenet #27 and #1261 | the introducing issue (no multi-valued discussion), class-counting fixes, a different test failure, two precedents of the same change elsewhere, and the .NET port, which also copies only the first value |
Present since the class was written, 3459b28334e (LUCENE-4345, 2012), so since 4.2.0 (2013). Executed on all 128 releases from 4.2.0 to 10.5.2 and on main: every one loses the second value. Not fixed upstream (main a95c754ee003, 2026-10-26).
Versions tested6 rows
Introduced by 3459b28334e (trunk, 2012-11-29, svn r1415060, LUCENE-4345 / #5411, "added utility class for creating training / test / cv index from a single index"; no pull request), whose named branch already read getField(fieldName) while its else branch looped over getFields(). The release line got it through the branch_4x backport 21e86983ed4 (2013-02-20, LUCENE-4781), identical to 4.2.0's file. Later commits kept getField: bf1355346c6 (LUCENE-6045, first in 6.0.0) added the null check, 112078eaf909 (LUCENE-7196, trunk, first released in 7.0.0; in 6.1.0 through its identical branch_6x cherry-pick ff3661abdaa) moved the code into createNewDoc, 7f8b7ffbcad (LUCENE-9570) reformatted it and 47f8c1baa2e (#11998) switched to StoredFields.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's test: 1 of 2 fails (gradle and the standalone runner, assertions on and off), all three output indexes |
| 10.5.2, 9.12.3 | affected | this doc's test: 1 of 2 fails, the same message (10.5.2 also with assertions off) |
| 4.2.0 to 10.5.2 (128 releases) | release sweep | the history repro: null keeps 3 of 3 documents whole and docFreq(text:second) = 3; named 0 of 3 and 0 (9.12.3 and 10.5.2 also with assertions off) |
| 4.1.0 | no API | no classification module and no DatasetSplitter class |
| main with the fix | not affected | named 3 of 3 and docFreq(text:second) = 3; this doc's test 2 of 2 |
upstream main a95c754ee003, branch_10x, branch_10_6 | code reading | DatasetSplitter.java:189 still calls document.getField(fieldName) |
An independent reproducer, cross-model reviews (OpenAI GPT-5.6, executed), a devil's-advocate verifier (3-valued field: tags:beta 0 of 6 named, 6 of 6 with null), an adjudication (confirmed, high) and an audit agree on the root cause. This doc's gradle runs reproduced it on main a9779ef3c193 and validated the fix.
Checks and verdicts360 words
Every executed check reproduced the same symptom (values after the first missing in named mode, null mode intact) and the same root cause at DatasetSplitter.java:189.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Bounded-exhaustive check over all indexes of 1-4 documents: 3,392 field mismatches in 24,816 splits (4 documents alone: 2,696 in 20,736). Its JUnit fails 1 of 1 on main (assertions on and off), 10.5.2 and 9.12.3, and passes with the fix. |
| independent reproducer | real | Own JUnit, 6 documents with every stored field named: stored body of d0 expected:[alpha0, omega0] but was:[alpha0]; body:omega0 hits=0 on main (assertions on and off), 10.5.2 and 9.12.3; the null control passes; 2 of 2 with the fix. |
| cross-model review, refute lens | real (high) | OpenAI GPT-5.6, executed: its own FSDirectory-based test loses the second and third values, also with assertions off and over 3 seeds; root cause and fix agree; intended argument moderate. |
| cross-model review, intended lens | real (high) | OpenAI GPT-5.6, executed: its own named-versus-null parity test fails on main, 9.12.3 and 10.5.2; intended argument moderate (a lossy rebuilding utility; getField documents first-value semantics). |
| devil's advocate | real (high) | 3-valued tags: named mode keeps [alpha] and tags:beta matches 0 of 6 training documents against 6 of 6 with null, on main (assertions on and off), 10.5.2 and 9.12.3; 3 of 3 with the fix. Every intended-behaviour argument rejected. |
| adjudication | confirmed (high) | Re-ran the independent reproduction's test with a new seed (1 of 2 fails, assertions on and off; control passes) and with the fix (2 of 2). |
| audit | keep | Re-ran the finder's test with a new seed, assertions on and off: fails, same message; the control passes. |
| the version-history runs | 4.2.0 to main | Version-portable main() in 7 API-era variants: all 128 releases from 4.2.0 to 10.5.2 and main reproduce in all three output indexes; main with the fix passes. |
| this doc | reproduced | New 2-test class through gradle and the standalone runner on main a9779ef3c193, 10.5.2 and 9.12.3, checking all three output indexes; the fix validated against the new test, TestDataSplitter and the whole module suite. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 457 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,347 words
- Registry title
- DatasetSplitter.split with explicit fieldNames copies only the first value of each multi-valued field into the split indexes
- Area
- classification / utils: DatasetSplitter (split, createNewDoc fieldNames branch)
- Priority
- Low, rank 340: In the little-used offline DatasetSplitter utility, with an easy workaround (null fieldNames).
- Impact class
- silent wrong results
- Impact note
- Anyone who builds training, test and cross-validation indexes with DatasetSplitter.split and passes an explicit fieldNames list (as the module's own 20 Newsgroups example does) silently loses every value after the first of each named multi-valued stored field, from the stored fields and from the indexed terms of all three output indexes, so a classifier trained or evaluated on the split sees less text than the source; there is no error and no scale condition, -ea and -da behave the same, the source index is not changed, and passing null fieldNames avoids the loss (a stored binary field in the source makes that mode throw).
- Summary
- You split an index into training, test and cross-validation indexes with DatasetSplitter.split and name the fields to copy, for example {id, text, cls}, where text has two stored values in each document. You expect each new document to carry both values of text, as it does when fieldNames is null ('all should be used'). Instead only the first value is copied, because the named-fields branch reads document.getField(name), which returns only the first value, so the second and later values are missing from the stored fields and from the postings of every output index, with no error.
- Introduced
- 3459b28334e2f3103336c0485b3f21da6dbaeeb9 (trunk, 2012-11-29, svn r1415060, '[LUCENE-4345] - added utility class for creating training / test / cv index from a single index'; no PR, it predates GitHub PRs; JIRA LUCENE-4345 / #5411 is the issue under which the classification module was built). The released code came through the branch_4x backport 21e86983ed42 (2013-02-20, 'LUCENE-4781 - backporting classification module to branch_4x'), whose DatasetSplitter.java is byte-identical to release 4.2.0's [read: git log --follow (31 commits), git log --all -S 'getField(fieldName)' and -G 'getFields\(fieldName\)' (no hit) in the history clone]. Not a regression: from the first commit the named-fields branch read getField(fieldName) and the all-fields branch looped over getFields(). Later commits did not change the behaviour: bf1355346c6 (LUCENE-6045, trunk 2015-05-04, first released in 6.0.0) only added the null check, 112078eaf909 (LUCENE-7196, trunk, first released in 7.0.0; in 6.1.0 through its identical branch_6x cherry-pick ff3661abdaa) moved the copy unchanged into createNewDoc() (git blame of today's lines points there; 6.0.1 and 6.1.0 both reproduce), 7f8b7ffbcad (LUCENE-9570) reformatted and 47f8c1baa2e (#11998) switched to StoredFields [read: git show of each commit and of the 5.5.0 and 6.0.0 tags]. (2012-11-29 (trunk commit 3459b28334e); release line: backport 21e86983ed4 on 2013-02-20; first released in 4.2.0 (tagged 2013-03-11))
- First affected version
- 4.2.0 [exec] (2013-03-11, the first release that ships the classification module and DatasetSplitter). There is no last unaffected release: 4.1.0 has no lucene/classification directory [read], no lucene-classification jar on Maven Central (HTTP 404) [exec] and no DatasetSplitter class in its other jars (ClassNotFoundException) [exec].
- Affected versions
- Every release that has DatasetSplitter, 4.2.0 through 10.5.2 (128 releases) and 10.6.0 (by reading), and main a9779ef3c193; not fixed. [exec] the follow-up's version-portable main() repro (7 API-era variants; 3 documents with two stored text values each, DatasetSplitter(0.3, 0.3) so one document lands in each output index; control fieldNames null, then {id, text, cls}) reproduced in all 132 runs: all 128 releases 4.2.0-10.5.2 with -ea, main with -ea, and -da on 9.12.3, 10.5.2 and main; control 3/3 documents keep both values and docFreq(text:second)=3, named mode 0/3 and docFreq 0, in the test, cross-validation and training indexes alike; with the candidate fix shadowed in on main it passes. The finder's JUnit fails on main (-ea and -da), 10.5.2 and 9.12.3, and so do the independent reproduction's and the intended-behaviour check's own JUnits. [read] upstream main a95c754ee00 (2026-10-26), branch_10x 1309534296e and branch_10_6 2763db11b0a have the same DatasetSplitter.java as a9779ef3c193.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (searched 2026-10-27, read-only; the prior-report record, verdict new): 104 logged queries, among them a scripted prior-report search (51 queries: 16 GitHub issue/PR, 3 commit, 2 downstream, 20 mailing-list queries over the dev, java-user, issues and commits lists, 4 JIRA, 6 web) and 53 manual searches (GitHub issues and PRs of apache/lucene, lucenenet, solr, lucene-solr, OpenSearch and Elasticsearch, a code search, every body and comment of the 68 module:classification issues and PRs, the changed files of every open apache/lucene PR, JIRA LUCENE and SOLR including all 47 LUCENE modules/classification issues, four more lists (solr-user@lucene, users@solr, dev@solr, general@lucene), the full git history). Every DatasetSplitter item upstream is about class grouping or counting, not field values: #8251 / LUCENE-7196, #8453 / LUCENE-7400, #8642 / LUCENE-7591, and the introducing #5411 / LUCENE-4345, which never discusses multi-valued fields; #12942 notes a different DatasetSplitter test failure; the only open PR touching the file, #16847 (a large PR), changes only Math.toIntExact(maxDoc()) in it and leaves createNewDoc alone. Precedents of the same getField-to-getFields fix elsewhere, not this bug: #6895 / LUCENE-5833 (suggest's DocumentDictionary) and SOLR-8871 (commit 96489d23846, KNearestNeighborClassifier in this module). The Lucene.NET port also copies only GetField(fieldName), unreported. Not fixed: upstream main a95c754ee003 (2026-10-26) still calls document.getField(fieldName) at DatasetSplitter.java:189. Gaps: GitHub's search rate limit was reached (throttled queries were retried and completed); the open-PR file scan was reused from a read-only scan made about an hour earlier and topped up; private reports and chat are not searchable.
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-27) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the 10.5.2 and 9.12.3 release jars. The version-history runs ran a version-portable repro on all 128 releases from 4.2.0 to 10.5.2 and on main. The fix was validated in the scratch worktree: the new test,TestDataSplitter, the wholelucene/classificationsuite with assertions on and off, and:lucene:classification:check -x test.
- Finding record
lucene/classification/src/java/org/apache/lucene/classification/utils/DatasetSplitter.java:44-46 (at a9779ef3c193) (class javadoc 'Utility class for creating training / test / cross validation indexes from the original index'), :76-77 ('@param fieldNames names of fields that need to be put in the new indexes or <code>null</code> if all should be used'), :129 (every output field is rebuilt as TextField.TYPE_STORED), :150 (createNewDoc call), :182-208 (createNewDoc: named branch :187-193 with document.getField(fieldName) at :189; all-fields branch :194-205 loops over document.getFields())lucene/core/src/java/org/apache/lucene/document/Document.java:31 (at a9779ef3c193) ('A Document is a set of fields'), :141-143 (getField: 'If multiple fields exists with this name, this method returns the first value added'), :161 (getFields(String name), every value)lucene/classification/src/test/org/apache/lucene/classification/utils/TestDataSplitter.java (at a9779ef3c193) (one value per field, maxDoc checks only) and lucene/classification/src/test/org/apache/lucene/classification/Test20NewsgroupsClassification.java:149-160 (the module's example calls split with explicit field names BODY_FIELD, SUBJECT_FIELD, CATEGORY_FIELD)GitHub and JIRA, read-only (2026-10-27): apache/lucene #5411, #8251, #8453, #8642, #6375, #6895, #12942, #16847; SOLR-8871; apache/lucenenet #27 and #1261
- The finding in 30 seconds
lucene/classification/src/java/org/apache/lucene/classification/utils/DatasetSplitter.java:44-46, 65-79 (76-77), 80-180 (92-94, 129-134, 143-161), 182-208 (186, 187, 189, 191, 194-205)lucene/core/src/java/org/apache/lucene/document/Document.java:31, 141-152 (142-143), 154-161
- Who is affected
lucene/classification/src/test/org/apache/lucene/classification/Test20NewsgroupsClassification.java:71 (@Monster), 149-160 (split with field names), 394-395 (single-valued fields)a Lucene main checkout: git grep -l DatasetSplitter -- 'lucene/*.java' (DatasetSplitter.java, TestDataSplitter.java, Test20NewsgroupsClassification.java only)
- Why it looks unintended
lucene/classification/src/java/org/apache/lucene/classification/utils/DatasetSplitter.java:76-77, 187-205lucene/classification/src/test/org/apache/lucene/classification/utils/TestDataSplitter.java:59-75, 94-96, 123-130
- Suggested fix
lucene/classification/src/java/org/apache/lucene/classification/utils/DatasetSplitter.java:187-205; lucene/core/src/java/org/apache/lucene/document/Document.java:154-161; lucene/core/src/java/org/apache/lucene/document/Field.java:245lucene/classification/src/java/org/apache/lucene/classification/utils/DatasetSplitter.java:92-94, 198-203; lucene/core/src/java/org/apache/lucene/document/Field.java:213-214, 264-266; lucene/core/src/java/org/apache/lucene/index/LiveIndexWriterConfig.java:135
- TestDatasetSplitterMultiValuedField.java (JUnit test):
repro/LFV-681/src/org/apache/lucene/classification/utils/TestDatasetSplitterMultiValuedField.java(59 lines)
A light summary card (the PNG), made in parallel with this text from an executed probe trace on main a9779ef3c193 (assertions on and off, and with the fix as a control). The diagram uses WhitespaceAnalyzer and the repro StandardAnalyzer; this data gives the same terms and numbers with both.
assets/LFV-681/bug.png(457 KB)