DatasetSplitter copies an index into training, test and cross-validation indexes, class by class, for classifier experiments. Both ratios are documented as the share of the original index for that output, "between 0.0 and 1.0".
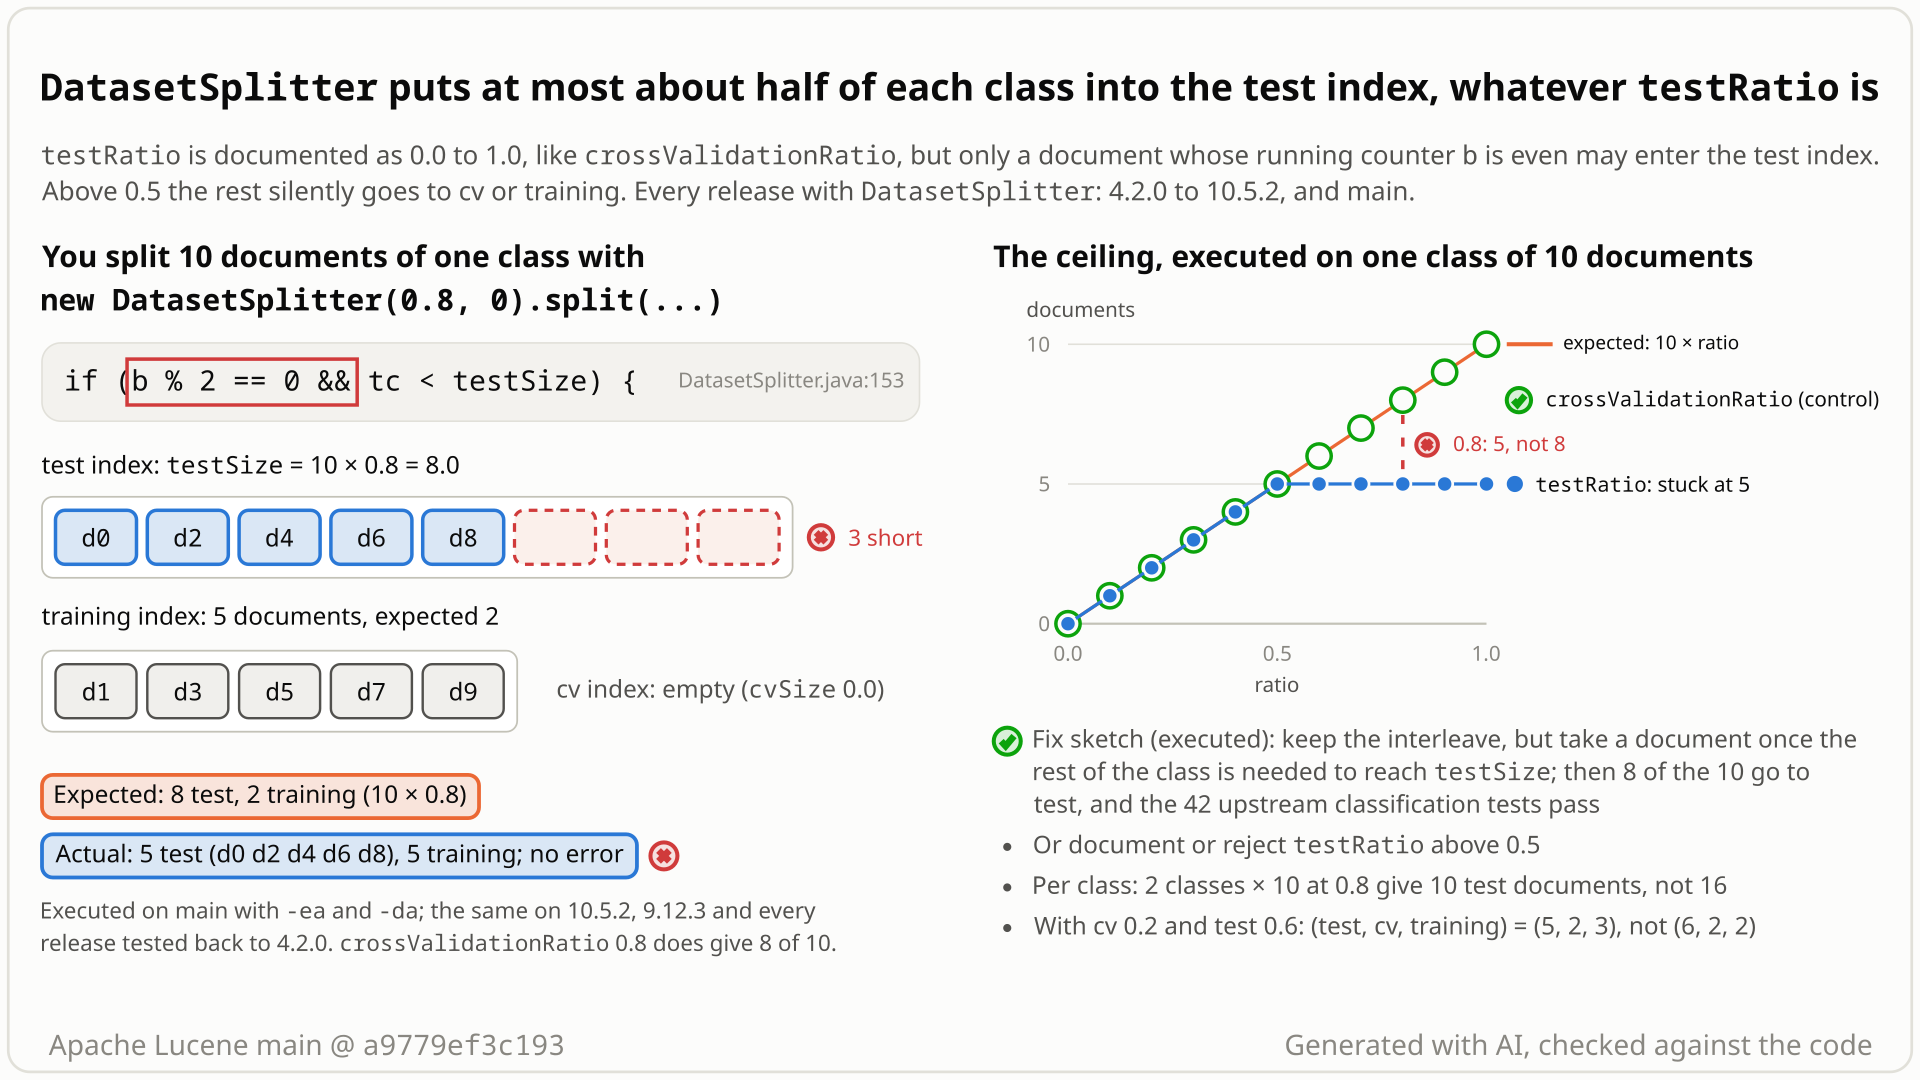
- Index 10 documents of one class and split them with
new DatasetSplitter(0.8, 0).split(...): 80% for the test index, none for cross-validation, the rest for training. - You expect 8 test and 2 training documents, just as
new DatasetSplitter(0, 0.8)puts 8 of the 10 into the cross-validation index. - You get 5 test and 5 training documents, with no error.
testRatio1.0 also gives 5; 0.6 with cross-validation 0.2 gives 5/2/3 instead of 6/2/2. - Why: a document may go to test only when a running counter is even,
if (b % 2 == 0 && tc < testSize); the cross-validation branch has no such check. So each class gives the test index at most about half its documents. - On 1,000 documents in 10 random classes, shaped like Lucene's own
TestDataSplitterfixture, everytestRatiofrom 0.5 to 1.0 gives exactly 500 test documents. Up to 0.5 the sizes are right, up to per-class rounding.
Anyone who prepares classifier data with DatasetSplitter (the opt-in classification module) and asks for a test share above one half, for example a small-training-set experiment. The split is wrong every time, with no error: they train on more and evaluate on fewer documents than configured. testRatio up to 0.5 is unaffected.
Mechanism, terms and numbers621 words
DatasetSplitter(testRatio, crossValidationRatio).split(...) copies an index into test, cross-validation and training indexes, class by class. Both ratios are documented in the same words, as the share of the original index for that output, "between 0.0 and 1.0". But a document may enter the test index only when a running counter b is even (if (b % 2 == 0 && tc < testSize)), and the cross-validation branch has no such condition. So each class gives the test index at most about half of its documents, whatever testRatio asks for, and the documents it should have taken silently go to training (cross-validation still gets just its own share unless the two ratios together ask for more than the whole class). One class of 10 documents with testRatio 0.8 gives test/cv/training 5/0/5 instead of 8/0/2; crossValidationRatio 0.8 gives 0/8/2 as documented. It is deterministic, the same with assertions on and off, raises no error, and is in every release that has the class (4.2.0 through 10.5.2) and main. testRatio up to 0.5 is honoured up to per-class rounding. Keeping the interleave but sending every remaining document to test once it is needed to reach the test size fixes it (+6/-2 lines) and leaves splits with testRatio up to 0.5 unchanged; the repro and the whole classification test suite pass with it.
DatasetSplitter(lucene/classification,org.apache.lucene.classification.utils): "Utility class for creating training / test / cross validation indexes from the original index" (DatasetSplitter.java:44-46). The constructor takestestRatioandcrossValidationRatio, both documented as "the ratio of the original index to be used for the test IDX" ("c.v. IDX") "as a double between 0.0 and 1.0" (:55-58); it checks neither (:60-63). What is neither test nor cross-validation goes to training.split(...)groups the live documents by the class field (sorted doc values,:74-75), groups and documents in index order (:119-126), and sends each document to one of the three new indexes.
- One counter,
int b = 0;(:136), counts every document of every class and is never reset (b++,:162). - For each class,
testSize = totalHits * testRatioandcvSize = totalHits * crossValidationRatio(:142-146). - A document goes to test only
if (b % 2 == 0 && tc < testSize)(:153), else to cross-validationif (cvc < cvSize)(:156), else to training (:159-160). The cross-validation branch has no parity condition. - So a class of n documents gives the test index at most ceil(n/2) documents (floor(n/2) when it starts on an odd
b). Below one half,tc < testSizeusually stops first and the size is right up to rounding (close to one half, a class that starts on an oddbcan get one test document fewer); above one half, the parity check stops first. The odd positions fall through to cross-validation untilcvSizeis reached, then to training, so with ratios that sum to at most 1 the missing test documents end up in training.
| testRatio, crossValidationRatio | expected test/cv/training | stock | with the fix |
|---|---|---|---|
| 0, 0.8 (control) | 0/8/2 | 0/8/2 | 0/8/2 |
| 0.2, 0 (control) | 2/0/8 | 2/0/8 | 2/0/8 |
| 0.5, 0 (control) | 5/0/5 | 5/0/5 | 5/0/5 |
| 0.8, 0 | 8/0/2 | 5/0/5 | 8/0/2 |
| 1.0, 0 | 10/0/0 | 5/0/5 | 10/0/0 |
| 0.6, 0.2 | 6/2/2 | 5/2/3 | 6/2/2 |
With testRatio 0.8 the test index holds d0, d2, d4, d6 and d8, and training d1, d3, d5, d7 and d9. On 1,000 documents in 10 random classes, shaped like Lucene's own TestDataSplitter fixture, every testRatio from 0.5 to 1.0 gives 500 test documents, and testRatio 0.7 with cross-validation 0.1 gives 500/106/394 instead of about 700/100/200.
Exposure and likelihood286 words
- Who is exposed. Applications that build training, test and cross-validation indexes with
DatasetSplitter(opt-inlucene/classificationmodule; the class is not marked experimental) and pass atestRatioabove 0.5, which the javadoc allows, for example a learning-curve or small-training-set experiment (70% test, 10% cross-validation, 20% training). Nothing in Lucene calls the class outside tests; the in-tree callers use testRatio 0.1, 0.2 and 0.2. - Default vs opt-in. There is no default ratio: the caller passes both. testRatio up to 0.5 is unaffected (up to per-class rounding). No index-size condition: 10 documents are enough.
- Silent and deterministic. The same wrong split every time, with assertions on and off, and no error or log line. In a probe on a fully labelled index the outputs were well-formed (CheckIndex clean), every live document landed in exactly one of them, and the source index was untouched, so nothing looks wrong. (With unlabelled documents a labelled class can vanish from all outputs: LFV-683, a separate bug.)
- Scale. At most about half of the index can ever be test data (per class ceil(n/2) or floor(n/2), depending on where the shared counter starts); the shortfall grows with the ratio (testRatio 1.0: about half of every class is missing from the test index).
- Bounded. No crash and no corruption in the probe, and no cost that grows with the ratio: a grouped search over the live documents (a first and a second pass) and one copy loop, 8-115 ms per split whatever the ratio (main only, one synthetic 400-document index, one host, so the timing is directional).
- How likely. Rare: test sets larger than training sets are unusual, and no public report was found in the sources searched, although the class has shipped since 4.2.0 (2013).
The test shows that new DatasetSplitter(0.8, 0).split(...) on one class of 10 documents puts only 5 documents into the test index.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.classification.utils;

import org.apache.lucene.analysis.standard.StandardAnalyzer;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.SortedDocValuesField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;

public class TestDatasetSplitterTestRatio extends LuceneTestCase {

  public void testTestRatioAboveHalf() throws Exception {
    StandardAnalyzer analyzer = new StandardAnalyzer();
    try (Directory source = new ByteBuffersDirectory();
        Directory training = new ByteBuffersDirectory();
        Directory test = new ByteBuffersDirectory();
        Directory cv = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(source, new IndexWriterConfig(analyzer))) {
        for (int i = 0; i < 10; i++) {
          Document doc = new Document();
          doc.add(new SortedDocValuesField("class", new BytesRef("a")));
          w.addDocument(doc);
        }
      }
      DatasetSplitter splitter = new DatasetSplitter(0.8, 0);
      splitter.split(DirectoryReader.open(source), training, test, cv, analyzer, false, "class");
      try (DirectoryReader testReader = DirectoryReader.open(test)) {
        // expected 8 of the 10 documents in the test index (testRatio 0.8); actual 5
        assertEquals("test index size for testRatio 0.8", 8, testReader.numDocs());
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-682/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/classification/build/libs/lucene-classification-$V.jar
CP=$CP:$LUCENE/lucene/grouping/build/libs/lucene-grouping-$V.jar
CP=$CP:$LUCENE/lucene/queries/build/libs/lucene-queries-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.classification.utils.TestDatasetSplitterTestRatio
- Expected vs actual
- Expected: 8 (testRatio 0.8 of 10, as documented for the 0.0-1.0 range); actual (-ea and -da): 5, because the guard
b % 2 == 0 && tc < testSize(DatasetSplitter.java:153) admits only every other document.
More files, environment, full output39 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: test index size for testRatio 0.8 expected:<8> but was:<5>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:647)
org.apache.lucene.classification.utils.TestDatasetSplitterTestRatio.testTestRatioAboveHalf(TestDatasetSplitterTestRatio.java:49)- Both ratios have the same javadoc, a share of the original index "between 0.0 and 1.0"; only the cross-validation ratio is honoured over that range.
- The redesign that introduced today's loop (LUCENE-7196) states the intent "split-ratio * | docs in c | documents for each class c".
TestDataSplitterexpects maxDoc x testRatio test documents, yet tests only 0.1 and 0.2.
The full argument204 words
- The contract. "@param testRatio the ratio of the original index to be used for the test IDX as a double between 0.0 and 1.0", and "@param crossValidationRatio the ratio of the original index to be used for the c.v. IDX as a double between 0.0 and 1.0" (
DatasetSplitter.java:55-58, wording unchanged since 2012). Only the cross-validation ratio is honoured over that range. No javadoc, package doc, CHANGES or MIGRATE entry mentions a cap, and the constructor checks nothing (:60-63). - The author's stated intent. LUCENE-7196 (#8251, 2016), opened by the class's author and the change that introduced today's per-class loop: "the generated index should contain split-ratio * | docs in c | documents for each class c".
- Lucene's own test oracle.
TestDataSplitter.assertSplitexpects(int) (originalIndex.maxDoc() * testRatio)test documents within 20 (TestDataSplitter.java:128) but runs only testRatio 0.1 and 0.2 (:91,:95); the 2012 test asserted the exact size. On the same fixture shape, testRatio 0.7 fails that oracle:expected:<700.0> but was:<500.0>. - No other reading explains it. The cap does not protect the training share: nothing limits cross-validation, so training can get far less than half (testRatio 0.2 with cross-validation 0.7 leaves 90 of 1,000 documents, 9%, for training).
The devil's-advocate check186 words
The strongest "works as designed" case (the intended-lens review by another model family rated it moderate; the devil's advocate built it in full): the every-other-document interleave is longstanding and appears intentional, in the first version (2012) and kept by the same author through the LUCENE-7196 rewrite, although no comment, issue or commit message says why; every in-tree caller uses test ratios of 0.2 or less; test sets larger than training sets are unusual; and "between 0.0 and 1.0" could be read as the type's range, not a promise for every value.
Why it fails: keeping the interleave suggests intent about which positions are sampled, not about silently cutting the size, and the fix keeps it. The identically documented cross-validation ratio is honoured, the author's stated intent and the project's own size oracle both say size = ratio x class size, and nothing documents or enforces a limit. Verdict: a defect (adjudication: confirmed, high; every verifier: real). The cross-model fact check of this doc rates the "works as designed" case moderate and suggests the most neutral framing: a documentation and validation defect with an apparent behavioural mismatch.
Recommended Keep the interleave, but take every remaining document once it is needed to reach the test size
Keep the every-other-document interleave, but once the rest of a class is needed to reach the test size, send every remaining document to test (+6/-2 lines). Splits with testRatio up to 0.5 stay exactly as today. The repro, the whole classification test suite (48 tests) and the module's format and lint checks pass.
        int i = 0;
        for (ScoreDoc scoreDoc : group.scoreDocs()) {
          ...
          // add it to one of the IDXs; interleave test documents, but take every remaining
          // document once the rest of the group is needed to reach the test size
          boolean needed = totalHits - i <= testSize - tc;
          i++;
          if ((b % 2 == 0 || needed) && tc < testSize) {
All options and trade-offs4 options · 726 words
A maintainer may instead prefer to document the limit or reject testRatio above 0.5 (option C), which would make this a documentation or validation defect. Workaround until a fix ships: for a test share above one half, pass it as crossValidationRatio (honoured over the whole range) and use the cross-validation output as the test index. If a real cross-validation set is needed too, swap both: pass the wanted cross-validation share as testRatio and read the test output as the cross-validation set; that share is then capped the same way, so keep it at or below 0.5 (and the two shares at most 1 together). Separate hardening note, not this bug: the constructor accepts out-of-range ratios (NaN, negative, above 1) without validation; a probe saw bounded, exception-free behaviour.
Keep the interleave, but take every remaining document once it is needed to reach the test size (validated by the checks) (recommended)
In the per-class loop of DatasetSplitter.split, count the documents seen in the class and also admit a document to the test index when the documents left in the class are no more than the test documents still missing. +6/-2 in DatasetSplitter.java.
        int i = 0;
        for (ScoreDoc scoreDoc : group.scoreDocs()) {
          ...
          // add it to one of the IDXs; interleave test documents, but take every remaining
          // document once the rest of the group is needed to reach the test size
          boolean needed = totalHits - i <= testSize - tc;
          i++;
          if ((b % 2 == 0 || needed) && tc < testSize) {
Trade-offs
- testRatio up to 0.5 gives exactly the same split as today, document by document: a transcription of the loop found no difference in the per-class counts over 92,400 configurations, nor (in the fact check) in any document's destination over 2,325,600 configurations; the fixture sweep agrees for 0.1, 0.3 and 0.5.
- Above 0.5 each class gets at least floor(n x testRatio) test documents and cross-validation at least min(floor(n x cvRatio), n - test) (same transcription, for ratios in [0, 1] that sum to at most 1, which the constructor does not enforce). So the fix rounds down above 0.5 where the stock loop rounds up below it: on the 1,000-document fixture 595, 695, 795 and 894 rather than about 600, 700, 800 and 900. The cross-validation and training documents then come from the front of each class (10 documents, testRatio 0.8: training gets d1 and d3).
- Constant extra work per document (an increment, two subtractions and one comparison); the split stays linear.
What the checks validated
- Scratch worktree of main
a9779ef3c193, gradle: the new test passes 5 of 5 withTestDataSplitter; the whole:lucene:classification:testpasses with assertions on and off (13 suites, 48 tests, 0 failures, 1@Monstertest skipped). :lucene:classification:check -x testpasses (checkGoogleJavaFormat,ecjLintMain,ecjLintTest,forbiddenApisMain,forbiddenApisTest).- Standalone runner with the fix shadowed: this doc's test (
-ea,-da), the devil's advocate's upstream-oracle test (2 of 2; 0.7 with cross-validation 0.1 gives 695/106/199), the finder's (1 of 1), the independent reproducer's (7 of 7) and the 42 upstream classification tests pass.
Change if (b % 2 == 0 && tc < testSize) to if (tc < testSize): each class gives its first test-size documents to test, the next to cross-validation, the rest to training.
Trade-offs
Simplest, one line. It changes which documents are picked at every ratio, including the common 0.1-0.2 (a block instead of every other document), so existing splits are not reproducible across the change.
What the checks validated
Standalone runner only: this doc's test 5 of 5 and TestDataSplitter 2 of 2 pass; the independent reproducer's 7 tests pass.
A javadoc note on the constructor, or an IllegalArgumentException for testRatio > 0.5; the same change could validate both ratios (in [0, 1], sum at most 1).
Trade-offs
No split changes; the limit becomes explicit instead of silent. Users who want a larger test share must swap the roles of the ratios. Not run.
For example, take position i when floor((i + 1) x testRatio) > floor(i x testRatio).
Trade-offs
Honours any ratio and samples the whole class, but changes every split; more than a bug fix needs. Not run.
Downstream relevance is limited to experiment correctness: a classifier evaluated on such a split is trained on more and measured on fewer documents than configured.
While writing down DatasetSplitter's assignment rule for a reference model, the finder noticed the parity check and probed the size rule: one class of 100 documents, testRatio 0.6, 0.8 and 1.0 all gave 50 test documents, while cross-validation 0.8 gave 80. Independent AI tools then reproduced, reviewed and judged it.
The method in full120 words
Method: semi-formal (the hunt's tier for tool-guided finds that are not a formal tool's own output): a bounded check of the split-size rule on the real jar, a hunt unit (classification, k-NN and utils against reference semantics), 2026-10-27, stock main jars.
- The signal came from code reading while modelling: the test branch has a parity condition the cross-validation branch lacks.
- The probe (
SplitterRatio.java) split one class of 100 documents with seven ratio pairs: testRatio 0.5, 0.6, 0.8 and 1.0 all gave 50 test documents; testRatio 0 with cross-validation 0.8 gave 80; 0.1/0.1 gave 10/10 and 0.3/0.6 gave 30/60. - It was reduced to a public-API JUnit test, and independent AI tools reproduced, reviewed and judged it (see the checks).
No prior report found (best-effort search, 2026-10-27): three tool runs (43, 39 and 52 queries) over GitHub, the mailing lists, JIRA and the web, plus all 409 open PRs and every classification-module issue. Closest: LUCENE-7196 (#8251), the 2016 redesign that kept the check.
Searches4 searches
No issue, PR, commit, JIRA entry, list thread, Stack Overflow question or web page reports or discusses DatasetSplitter capping the test index at about half, or testRatio above 0.5 not being honoured, and none calls the cap by design. The identifiers testRatio and crossValidationRatio return no hits on GitHub, JIRA or any list searched. Not fixed: upstream main a95c754ee003 (2026-10-26) and branch_10x still have the check unchanged.
Closest items, none a report of this bug: #8251 (LUCENE-7196) is the per-class redesign; it kept the guard and states the size intent. #5411 (LUCENE-4345) introduced the class; no comment discusses its ratios. #8453 (LUCENE-7400) and #8642 (LUCENE-7591) concern class grouping and counting. #12942 is a different DatasetSplitter failure (topNGroups must be >= 1). #16847 is the only open PR found touching the file and changes one unrelated line. Gaps: GitHub search is token-based and GitHub's search rate limit was reached (throttled queries were retried); the open-PR scan listed only 3000 of the 7630 files of one branch-decommission PR; private channels cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene, lucene-solr, solr, lucenenet; two downstream search engines; GitHub-wide) | 2026-10-27 | three scripted prior-report search runs: 43 queries (2,646 hits, 3 ranked high, unrelated term overlap), 39 queries (97 hits, 7 ranked high, all related history, none a report) and 52 queries including 7 web queries (347 distinct hits, 0 high); 21 manual queries; the whole module:classification label (68 items) | no report; closest #8251, #5411, #8453, #8642, #12942 |
| Open apache/lucene PRs | 2026-10-27 | the changed files of all 409 open PRs | only #16847 was found to touch the file (one unrelated line; one PR's file list was truncated at 3000 of 7630 files) |
| JIRA archive and mailing lists | 2026-10-27 | 8 JQL queries including all 47 classification-component issues; dev@, java-user@, issues@, general@, commits@ and the Solr lists | no discussion of the split ratios |
| Stack Overflow and the web | 2026-10-27 | 4 Stack Overflow and 7 web queries | nothing relevant |
Introduced with the class itself in LUCENE-4345 (2012, 3459b28334e) and first released in 4.2.0 (2013); the 2016 per-class redesign kept the check. The repro fails on all 14 releases run from 4.2.0 to 10.5.2 and on main; no earlier release has the class.
Versions tested6 rows
Introduced by 3459b28334e (trunk, 2012-11-29, @tteofili, svn r1415060, "[LUCENE-4345] - added utility class for creating training / test / cv index from a single index"; issue LUCENE-4345, now #5411; no pull request). The first version already had if (b % 2 == 0 && testWriter.maxDoc() < size * testRatio) for the test branch and no parity condition for cross-validation; the constructor javadoc came the same day (232ca1503d2). It reached a release through the branch_4x backport 21e86983ed4 (LUCENE-4781, #5846, 2013-02-20): first release 4.2.0 (its tag points to a commit of 2013-03-11). 4.1.0 and earlier have no DatasetSplitter.
Kept in the redesign. LUCENE-7196 (#8251) made the split per class and kept b % 2 == 0. It landed on trunk as 112078eaf909 (2016-04-08) and was cherry-picked to 6.x as ff3661abdaa, which first shipped in 6.1.0; git blame points the line at 112078eaf909 only because the right half of the condition was rewritten. Not a regression: the check is in all 119 release tags of the history clone that contain the class, and upstream main a95c754ee003 still has it.
Executed and read. 14 releases were run (assertions on) and main (on and off); the other releases are read from their tags. The history clone has no tags for 8.8.2 to 8.11.4: 8.8.2 to 8.11.3 were neither run nor read and count as affected because they lie between the executed 8.8.1 and 8.11.4.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's test: 3 of 5 fail (gradle and the standalone runner, assertions on and off), controls pass; the finder's test: 1 of 1 fails |
| 10.0.0, 10.5.2, 9.12.3 | affected | this doc's test (assertions on): 3 of 5 fail, the same counts |
| 4.2.0, 4.10.4, 5.0.0, 6.0.1, 6.1.0, 6.3.0, 6.4.0, 7.7.3, 8.8.1, 8.11.4, 9.0.0 | release sweep | era-specific main() drivers (4.2.0-8.11.4) and the finder's JUnit (9.0.0), assertions on: testRatio 0.8 on 10 documents gives 5/0/5; the cross-validation 0.8 control gives 8 of 10 |
4.2.0, 6.1.0, 8.8.1 with only b % 2 == 0 && removed | shadow control | 8/0/2: the drivers detect exactly this check |
| 4.1.0 and earlier | no API | the class does not exist |
| main + the fix | not affected | every repro passes; the whole classification test suite and the module's checks pass |
An independent reproducer, two executed reviews by another model family and a devil's advocate each found it real with their own tests; an audit re-ran the finder's test, and an adjudication confirmed it by re-running two of the tests with a fresh seed. This doc's own test reproduced it through gradle and validated the fix.
Checks and verdicts590 words
The checks on main ran on the stock jars (the fix checks with a shadowed class); the finder's, the independent reproducer's, the refute-lens reviewer's and this doc's tests ran with assertions on and off, the other checks with one setting, as listed. The reviews by the other model family (OpenAI GPT-5.6) executed their own tests on main ea57360912ed, whose classification and grouping sources equal a9779ef3c193; the review step re-ran the intended-lens reviewer's test on a9779ef3c193, and the refute-lens reviewer's test ran only on ea57360912ed.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Size-rule probe (100 documents, seven ratio pairs); public-API JUnit fails 1 of 1 on main (-ea, -da), 10.5.2 and 9.12.3; passes with the fix, as do the 42 upstream classification tests. |
| Independent reproducer | real | Own 7-test JUnit fails 4 of 7 on main (-ea, -da), 10.5.2 and 9.12.3 (for example 20 documents, testRatio 1.0: 10 instead of 20); controls pass; removing only the parity check makes all 7 pass, and so does the fix. |
| Cross-model review, refute lens | real (high) | Another model family (OpenAI GPT-5.6), executed on main ea57360912ed: two classes of 8, testRatio 0.75 gives 8/0/8 instead of 12/0/4 after a passing 0.5 control, also with -da; passes with the fix. Intended-behaviour argument: moderate. |
| Cross-model review, intended lens | real (high) | Own JUnit on 12 documents, assertions on: testRatio 0.75 gives 6 instead of 9 while cross-validation 0.75 gives 9, on main ea57360912ed, 10.5.2 and 9.12.3, and again on a9779ef3c193 when the review step re-ran it; with the fix the 42 non-Monster classification tests pass. A separate sweep on a9779ef3c193 (-ea, -da): 0.55 to 1.0 on 20 documents all give 10. |
| Devil's advocate | real | Built the strongest "works as designed" case and rejected it; on the upstream fixture shape every testRatio from 0.5 to 1.0 gives 500 of 1,000 test documents, and the upstream oracle fails at 0.7 (assertions on). |
| adjudication | confirmed (high) | Re-ran the independent reproduction's JUnit with seed 1234ABCD and -da (4 of 7 fail, controls pass) and the finder's with seed 1234ABCD and -ea (1 of 1 fails), and the independent reproduction's with the fix (7 of 7 pass); no duplicate. |
| registry re-runs, security probe and audit | keep | New seed 5EED7A71: the finder's test fails with -ea and -da. A security probe (one fully labelled index: 16 segments, 4 classes, 57 deletions) found only wrong sizes: every live document in exactly one output, CheckIndex clean. The audit re-ran the finder's test (-ea) and kept the row. |
| this doc's runs | reproduced, fix validated | The doc's 5-test JUnit fails 3 of 5 through gradle (assertions on and off) and the standalone runner on main, 10.0.0, 10.5.2 and 9.12.3, controls passing; with the fix it and the whole classification test suite pass, and :lucene:classification:check -x test passes. |
| fact checks of this doc | confirmed; wording corrected | An independent fact check re-ran this doc's gradle command on a clean copy of a9779ef3c193 (3 of 5 fail with -ea and with -da), validated the fix (the whole classification suite: 13 suites, 48 tests) and compared every document's destination with and without the fix for testRatio up to 0.5 (2,325,600 configurations, 0 differences). A second fact check by another model family (OpenAI GPT-5.6) re-checked the claims against the code and the run logs. Both found the bug real; their wording and attribution corrections are applied in this doc. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 399 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,418 words
- Registry title
- DatasetSplitter puts at most about half of each class into the test index, whatever testRatio is
- Area
- classification / utils: DatasetSplitter (split, test/cv/training assignment loop)
- Priority
- Low, rank 343: In the little-used offline DatasetSplitter utility, and only for a testRatio above 0.5.
- Impact class
- silent wrong results
- Impact note
- Anyone who builds training, test and cross-validation indexes with DatasetSplitter and asks for a test share above one half (testRatio 0.6, 0.8 or 1.0, legal under the documented 0.0-1.0 range) gets only about half of each class in the test index, and the rest silently goes to cross-validation or training; there is no error, no scale condition, -ea and -da behave the same, the source index is not changed, testRatio <= 0.5 is honoured up to per-class rounding, and crossValidationRatio, documented in the same words, is honoured over the whole range.
- Summary
- You split an index with new DatasetSplitter(0.8, 0).split(...) to put 80% of the documents into the test index. You expect about 8 of every 10 documents of each class in the test index, as crossValidationRatio 0.8 gives 8 of 10 in the cross-validation index. Instead the test index gets only 5 of 10 and training gets the other 5, because the loop lets a document into the test index only when its running counter b is even (DatasetSplitter.java:153, 'if (b % 2 == 0 && tc < testSize)'), so at most every other document can be a test document, with no error.
- Introduced
- 3459b28334e2f3103336c0485b3f21da6dbaeeb9 (trunk, 2012-11-29, svn r1415060, '[LUCENE-4345] - added utility class for creating training / test / cv index from a single index', tteofili; no PR, it predates GitHub PRs; JIRA LUCENE-4345 / #5411 is the issue under which the classification module was built). It added 'if (b % 2 == 0 && testWriter.maxDoc() < size * testRatio)' for the test branch and no parity condition on the cross-validation branch. The released code came through the branch_4x backport 21e86983ed42 (2013-02-20, LUCENE-4781 / #5846), with the same guard. Not a regression: the guard is in the first commit of the class. 112078eaf909 (LUCENE-7196 / #8251, 2016-04-08, first released in 6.1.0) rewrote the loop per class and kept 'b % 2 == 0' unchanged; git blame of line 153 points there only because the right half of the condition was rewritten [read: git log --follow, -S 'b % 2 == 0' across all refs and -G 'b % 2 == 0' on main in the history clone]. (2012-11-29 (trunk commit 3459b28334e); release line: backport 21e86983ed4 on 2013-02-20; first released in 4.2.0 (tagged 2013-03-11))
- First affected version
- 4.2.0 [exec] (2013-03-11, the first release that ships the classification module and DatasetSplitter). There is no last unaffected release: DatasetSplitter.java is absent from the 4.0.0-alpha, 4.0.0-beta, 4.0.0 and 4.1.0 tags [read], and Maven Central has no lucene-classification 4.1.0 jar (HTTP 404) [exec].
- Affected versions
- Every release that has DatasetSplitter, 4.2.0 through 10.5.2, and main a9779ef3c193; not fixed. [exec] the follow-up's history runs (one class of 10 documents, testRatio 0.8, cv 0; each run first checks the control crossValidationRatio 0.8 -> 8 of 10, which passes in every version): 4.2.0, 4.10.4, 5.0.0, 6.0.1, 6.1.0, 6.3.0, 6.4.0, 7.7.3, 8.8.1 and 8.11.4 (version-specific main() drivers for the four API eras) and 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main with -ea and -da (the candidate JUnit) all give test/cv/training 5/0/5 instead of 8 test documents; shadow controls on 4.2.0, 6.1.0 and 8.8.1 (the release's own source with only 'b % 2 == 0 && ' removed) give 8/0/2, so the drivers detect exactly this guard. The finder's JUnit (also re-run by the intended-behaviour check) and the own tests of the independent reproduction also fail on 10.5.2 and 9.12.3. [read] the guard is in all 119 release tags of the history clone (8.8.2 and 8.9.0-8.11.3 are not tagged there and lie between the executed 8.8.1 and 8.11.4); upstream main a95c754ee003 (2026-10-26) and branch_10x still have line 153 unchanged.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal
- Upstream and prior reports
- none found (searched 2026-10-27, read-only; the prior-report record, verdict new): scripted prior-report searches by the finder (43 queries), the intended-behaviour check (39) and the follow-up (52 with an expanded spec plus 7 web queries; 347 distinct hits, 0 high), and manual searches: 21 GitHub queries on apache/lucene issues and PRs (the whole module:classification label, 68 items), further queries on apache/lucene-solr, apache/solr, elastic/elasticsearch, opensearch-project/OpenSearch, apache/lucenenet and GitHub-wide, full threads of 13 apache/lucene and 2 lucenenet items, the changed files of all 409 open apache/lucene PRs, 8 JIRA queries (LUCENE, SOLR, LUCENENET, including all 47 modules/classification issues), lists.apache.org (Lucene and Solr lists), Stack Overflow and the web. The identifiers testRatio and crossValidationRatio return no hits on GitHub, JIRA or any list searched. Closest items, none the same bug: #8251 / LUCENE-7196 (the 2016 per-class redesign; kept the guard and states the size intent 'split-ratio * |docs in c| documents for each class c'), #5411 / LUCENE-4345 (introduced the class; no comment discusses its ratios), #8453 / LUCENE-7400 and #8642 / LUCENE-7591 (class grouping and counting), #12942 (a different DatasetSplitter failure, 'topNGroups must be >= 1'), #16847 (the only open PR touching the file; one unrelated line). Not fixed: upstream main a95c754ee003 (2026-10-26) still has 'if (b % 2 == 0 && tc < testSize)' at DatasetSplitter.java:153, and no commit message, JIRA thread, CHANGES or MIGRATE entry documents the cap. Gaps: GitHub search is token-based and GitHub's search rate limit was reached (throttled queries were retried); the open-PR scan listed only 3000 of #16911's 7630 files (a branch decommission PR, not a fix); private reports and chat are not searchable. Update 2026-11-02: #16911 (open when searched) merged 2026-10-29 as 48cf3f515d6, which emptied branch_10x to a README tombstone (10.6 is the last 10.x minor; 10.x fixes go to branch_10_6); it fixes nothing here.
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-27) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the 10.0.0, 10.5.2 and 9.12.3 release jars with assertions on (this doc's test). The finder's test and era-specificmain()drivers fail on 14 releases from 4.2.0 to 10.5.2 (assertions on) and on main (on and off). The cross-model reviews ran on mainea57360912ed, whose classification and grouping sources equala9779ef3c193; the review step re-ran the intended-lens reviewer's test ona9779ef3c193(assertions on), while the refute-lens reviewer's test ran only onea57360912ed. The fix was validated in the scratch worktree: the new test withTestDataSplitter, the whole:lucene:classification:test(assertions on and off) and:lucene:classification:check -x test.
- Finding record
lucene/classification/src/java/org/apache/lucene/classification/utils/DatasetSplitter.java:44-46 (at a9779ef3c193) (class javadoc 'Utility class for creating training / test / cross validation indexes from the original index'), :55-58 ('@param testRatio the ratio of the original index to be used for the test IDX as a double between 0.0 and 1.0', and the same words for crossValidationRatio), :60-63 (constructor, no range check), :136 (int b = 0, one counter for all classes), :143 (double testSize = totalHits * testRatio), :145 (cvSize), :153 ('if (b % 2 == 0 && tc < testSize)'), :156 ('else if (cvc < cvSize)', no parity condition), :159-160 (training branch), :162 (b++)lucene/classification/src/test/org/apache/lucene/classification/utils/TestDataSplitter.java:91, (at a9779ef3c193) :95 (ratios 0.1/0.1 and 0.2/0.35 only), :128 (size oracle 'assertEquals((int) (originalIndex.maxDoc() * testRatio), testReader.maxDoc(), 20)')GitHub and JIRA, read-only (2026-10-27): apache/lucene #5411, #5846, #8251, #8453, #8642, #12942, #16847; apache/lucenenet #27
- The finding in 30 seconds
lucene/classification/src/java/org/apache/lucene/classification/utils/DatasetSplitter.java:44-46, :55-58, :60-63, :74-75, :119-126, :136, :142-146, :153, :156, :159-160, :162
- Who is affected
lucene/grouping/src/java/org/apache/lucene/search/grouping/GroupingSearch.java:146-211 (first-pass and second-pass grouped search); DatasetSplitter.java:140-163 (copy loop)lucene/classification/src/java/org/apache/lucene/classification/utils/DatasetSplitter.java:44-47 (no @lucene.experimental), :55-63grep -rln DatasetSplitter lucene --include='*.java' (DatasetSplitter.java, TestDataSplitter.java, Test20NewsgroupsClassification.java only), 2026-10-27lucene/classification/src/test/org/apache/lucene/classification/utils/TestDataSplitter.java:91, :95; lucene/classification/src/test/org/apache/lucene/classification/Test20NewsgroupsClassification.java:149
- Why it looks unintended
lucene/classification/src/java/org/apache/lucene/classification/utils/DatasetSplitter.java:55-58, :60-63, :153, :156GitHub apache/lucene #8251 (LUCENE-7196 issue text), read-only 2026-10-27lucene/classification/src/test/org/apache/lucene/classification/utils/TestDataSplitter.java:91, :95, :128
- Suggested fix
lucene/classification/src/java/org/apache/lucene/classification/utils/DatasetSplitter.java:60-63, :144-160
- TestDatasetSplitterTestRatio.java (JUnit test):
repro/LFV-682/src/org/apache/lucene/classification/utils/TestDatasetSplitterTestRatio.java(53 lines)
A summary still; the PNG is the summary. This caption and alt text follow the traced example as it stood when the doc was written.
assets/LFV-682/bug.png(399 KB)