DatasetSplitter.split copies an index into training, test and cross-validation indexes, grouping the documents by their class so that the test and cross-validation shares are taken from each class separately. The class field must be indexed with sorted doc values; nothing says every document must have a value.
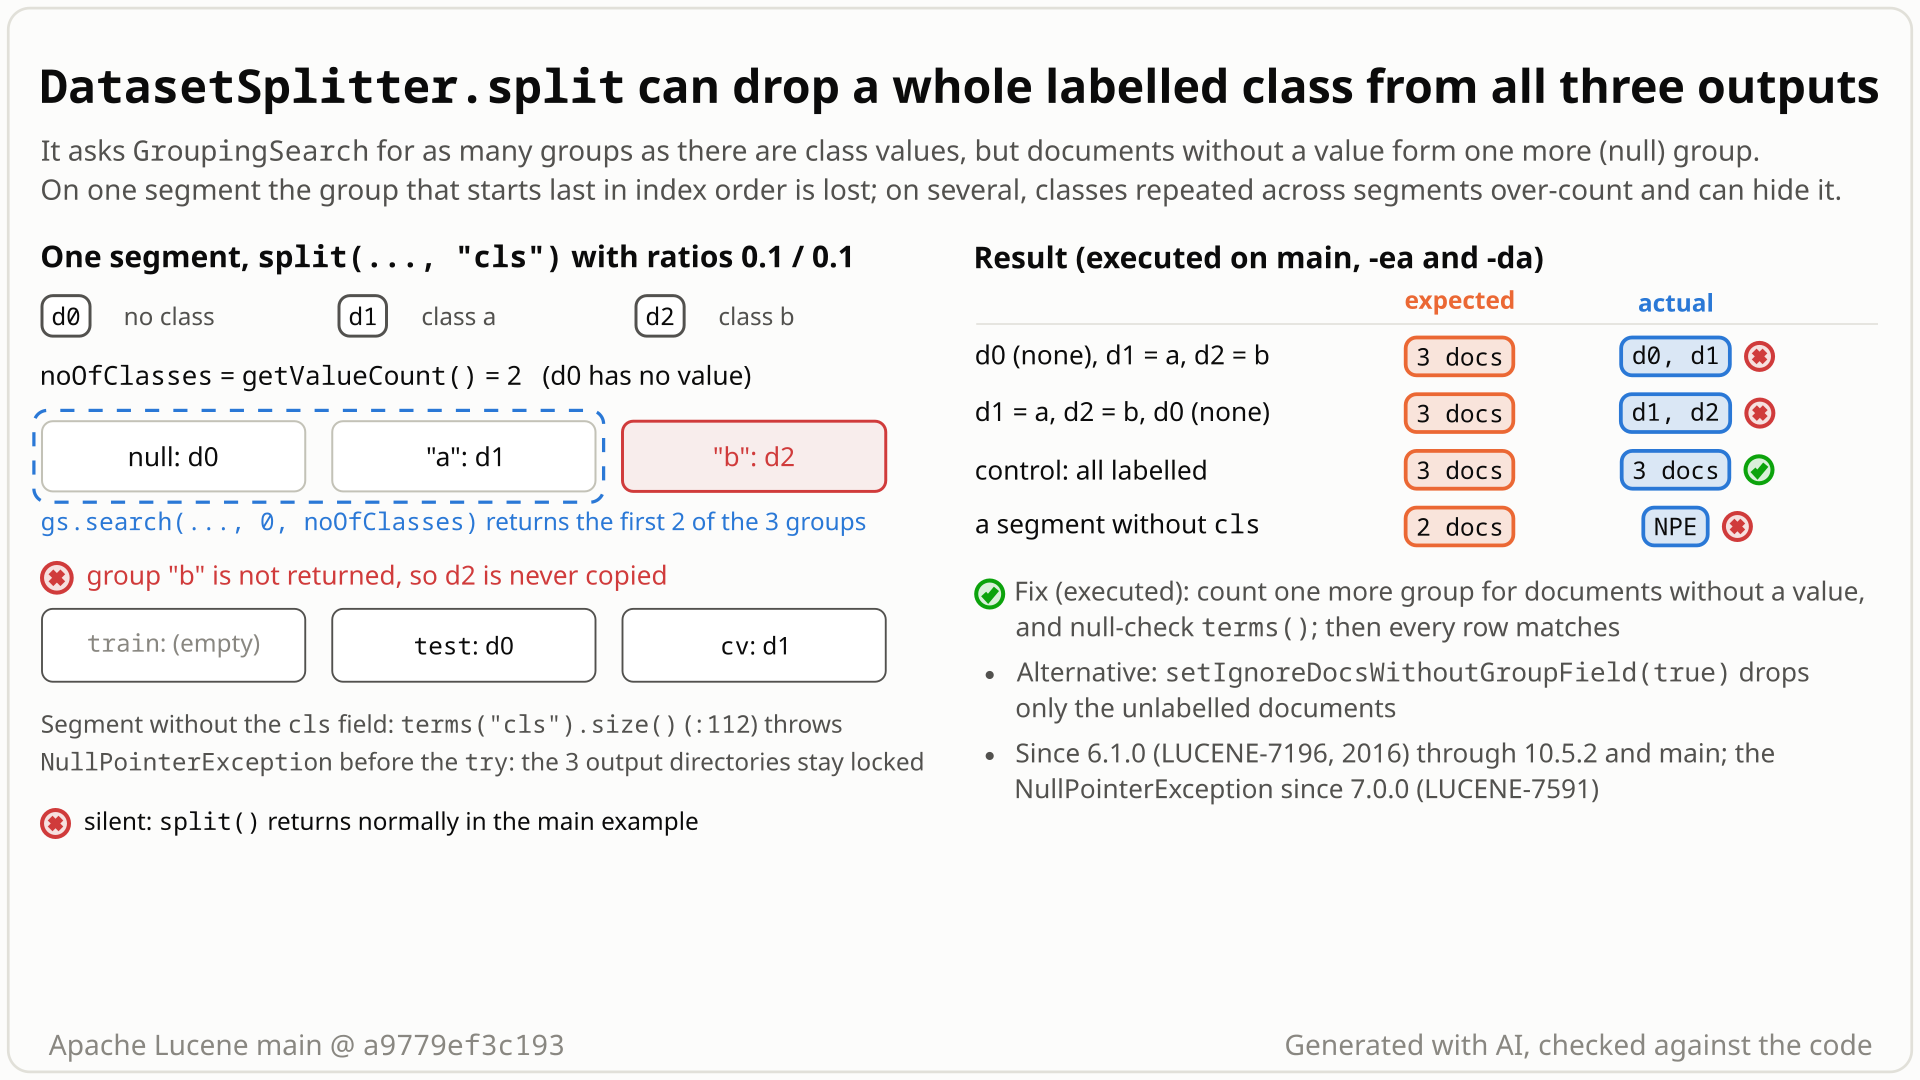
NullPointerException. Select the still to open it at full size. Generated with AI, checked against the code.- Index three documents into one segment: d0 with no class value, d1 of class a, d2 of class b. Call
new DatasetSplitter(0.1, 0.1).split(reader, train, test, cv, analyzer, false, "cls"). - You expect every document in one of the three new indexes, and both classes present.
- You get test = [d0], cross-validation = [d1], training empty: d2, and with it all of class b, is in none of them. split returns normally.
- Why: split asks the grouping for as many groups as there are class values (2). Documents without a value form a third group, the null group, and groups are taken in index order: null, a. The group that starts last is cut.
- Second symptom: a segment with no class field makes split throw
NullPointerExceptionbefore itstry, so its three writers stay open and the output directories stay locked.
Anyone who splits an index for classifier work with DatasetSplitter while some documents have no class value, a state the module's classifiers handle on purpose. No option needed. On one segment the loss is deterministic once an unlabelled document precedes the first document of the class that starts last; classes repeated across segments, or deleted documents, can hide it.
Mechanism, terms and numbers830 words
DatasetSplitter.split copies an index into three new indexes (training, test, cross-validation) for classifier work. Since LUCENE-7196 (6.1.0) it groups the documents by the class field with GroupingSearch, so that the test and cross-validation shares are taken from each class separately, and it asks for as many groups as there are class values. Documents without a class value form one more group, the null group (the grouping default), which that count never includes. On a single segment that holds an unlabelled document the limit is one group short (unless a class value left only on deleted documents inflates the count), and the group whose first document comes last in index order is left out of all three outputs. With d0 (no class value), d1 (class a) and d2 (class b) in one segment, d2 and all of class b are missing; with one unlabelled document ahead of 1,000 documents each of classes a, b and c, all 1,000 class-c documents are missing. If the unlabelled documents come last, only they are lost. Separately, a segment with no class field at all makes split throw NullPointerException from terms(classFieldName).size() before its try, so the three writers it opened are never closed and the output directories stay locked. Every release from 6.1.0 to 10.5.2 and main is affected (the NullPointerException since 7.0.0); indexes in which every document has a value of the documented single-valued sorted doc-values class field are not. Counting one extra group, null-checking the terms and opening the writers inside the try fixes both; the repro, the whole classification test suite and the module's checks pass with that change.
DatasetSplitter(lucene/classification,org.apache.lucene.classification.utils): "Utility class for creating training / test / cross validation indexes from the original index" (DatasetSplitter.java:44-46).split(reader, train, test, cv, analyzer, termVectors, classFieldName, fieldNames...)copies each document into one of the three outputs; the class field "must be indexed with sorted doc values" (:74-75).- Grouping. split runs
GroupingSearchon the class field over all documents, groups sorted by index order (the position of each group's first document), and copies the documents of the returned groups group by group (:119-164). - Null group. By default the grouping puts documents without the group field into one extra group with the value null;
setIgnoreDocsWithoutGroupField(true)leaves them out instead (GroupingSearch.java:63,:393-403). split does not call it.
- split opens its three
IndexWriters first (:92-94). - It counts the classes: per segment, the value count of the class field's sorted doc values; a segment without them also adds
terms(classFieldName).size()("approximate with no. of terms",:96-115). Documents without a value are never counted. - It asks for that many groups:
gs.search(indexSearcher, MatchAllDocsQuery.INSTANCE, 0, noOfClasses)(:126). On one segment with at least one unlabelled document (and an exact count, step 6) there arenoOfClasses + 1groups, so the group whose first document comes last is cut, whole, from all three outputs. That group is a labelled class whenever the first unlabelled document comes before it (in [u, a, b, c] class c goes, class a stays); otherwise it is the unlabelled documents. - For a segment where no document has the class field,
terms(classFieldName)is null ("or null if it has none",LeafReader.java:134) and:112throwsNullPointerException. That line is before thetry(:117), so thefinallythat closes the writers and the reader (:176-179) never runs. - Several segments: the count adds up per-segment dictionaries, so when classes repeat across segments it exceeds the real number and the null group fits. [d0 unlabelled, d1 = a] + [d2 = b] still loses d2; [d0, a, b] + [a, b] keeps everything.
- Deleted documents: the count is the segment's dictionary size, and a class value left only on deleted documents still counts. One segment [d0 unlabelled, d1 = a, d2 = b, d3 = c] with d3 deleted and not merged copies d0, d1 and d2 (count 3); after
forceMerge(1)the count is 2 and d2 is lost again.
| one segment | count | groups seen, in index order | groups kept | missing from all outputs |
|---|---|---|---|---|
| d0 (none), d1 (a), d2 (b) | 2 | null, a, b | null, a | d2 (class b) |
| d1 (a), d2 (b), d0 (none) | 2 | a, b, null | a, b | d0 (unlabelled only) |
| 1 unlabelled, then 1,000 each of a, b, c | 3 | null, a, b, c | null, a, b | all 1,000 of class c (2,001 of 3,001 copied) |
| 1,000 a, 1 unlabelled, 1,000 b, 1,000 c | 3 | a, null, b, c | a, null, b | all 1,000 of class c |
| 1 unlabelled, then 10 classes of 100 | 10 | null, k0, ..., k9 | null, k0, ..., k8 | all 100 of class k9 |
| every document labelled | k | k classes | all | nothing |
In the three-document case the outputs are test = [d0], cross-validation = [d1], training empty; with the fix test = [d0, d2], cross-validation = [d1].
Exposure and likelihood347 words
- Who is exposed. Applications that build training, test and cross-validation indexes with
DatasetSplitter.split(opt-inlucene/classificationmodule; not marked experimental) from an index where some live documents have no class value. Nothing in Lucene calls it outside tests, and a code search of the Apache organisation found no caller in Solr. - Unlabelled documents are a normal input to the module. Its classifiers skip them on purpose (LUCENE-5338), and its own test base indexes "unlabeled doc" and "second unlabeled doc" (
ClassificationTestBase.java:227,:333). That is classifier support, not a statement aboutDatasetSplitter, which documents no contrary restriction. - Default call; one segment exposes it. No setting is involved: any ratios,
fieldNamesnull or not.TestDataSplitter, the class's only regular (non-@Monster) test, force-merges to one segment and passes a single leaf (TestDataSplitter.java:78-80); theoriginalIndexjavadoc still reads "an {@link org.apache.lucene.index.LeafReader} on the source index" (DatasetSplitter.java:68); and from 6.1.0 to 6.3.0 split accepted only aLeafReader. How common each layout is was not studied. - Silent. split returns normally and the outputs are well-formed indexes that just lack a class: a classifier trained on them never learns it, and its evaluation never tests it.
- Realistic data (one workload, not a prevalence study). 500 documents, 4 classes with skewed frequencies (rarest 3%), about 2% unlabelled at random positions, force-merged to one segment: 64 of 100 trials lose labelled documents (1,386 in total). The same data left in several segments: 0 of 100.
- Bounded. At most one group per split, cut whole; no deleted, duplicated or foreign document appears in any output, CheckIndex is clean and the source index is unchanged (3,000 random indexes).
- Second symptom. A segment with no class field (for example a flush of only unlabelled documents) throws
NullPointerExceptionand leaves the three output directories locked; on a file-system directory the lock is held until the JVM exits, and the caller's reader is left open (on success split closes it). - How likely. Plausible: a little-used utility, and multi-segment indexes with repeated classes hide it; nobody has reported it since 6.1.0 (2016).
The test shows that DatasetSplitter(0.1, 0.1).split(..., "cls") on one segment d0 (no class value), d1 (class a), d2 (class b) asks GroupingSearch for 2 groups (the class count), but the unlabelled document forms a third (null) group that takes a slot, so class b is cut.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.classification.utils;

import java.util.ArrayList;
import java.util.List;
import org.apache.lucene.analysis.standard.StandardAnalyzer;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.SortedDocValuesField;
import org.apache.lucene.document.StringField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;

public class TestDatasetSplitterUnlabelledDocs extends LuceneTestCase {

  private static Document doc(String id, String cls) {
    Document doc = new Document();
    doc.add(new StringField("id", id, Field.Store.YES));
    if (cls != null) {
      doc.add(new SortedDocValuesField("cls", new BytesRef(cls)));
    }
    return doc;
  }

  public void testUnlabelledDocumentDropsLabelledClass() throws Exception {
    Directory src = new ByteBuffersDirectory();
    try (IndexWriter w = new IndexWriter(src, new IndexWriterConfig())) {
      w.addDocument(doc("d0", null));
      w.addDocument(doc("d1", "a"));
      w.addDocument(doc("d2", "b"));
    }
    Directory[] outputs = {
      new ByteBuffersDirectory(), new ByteBuffersDirectory(), new ByteBuffersDirectory()
    };
    new DatasetSplitter(0.1, 0.1)
        .split(
            DirectoryReader.open(src),
            outputs[0],
            outputs[1],
            outputs[2],
            new StandardAnalyzer(),
            false,
            "cls");
    List<String> ids = new ArrayList<>();
    for (Directory out : outputs) {
      try (DirectoryReader r = DirectoryReader.open(out)) {
        for (int i = 0; i < r.maxDoc(); i++) {
          ids.add(r.storedFields().document(i).get("id"));
        }
      }
    }
    assertTrue(
        "expected d2 (the only document of class b) in one of the outputs, but they hold " + ids,
        ids.contains("d2"));
  }
}
# in a copy of this finding's repro folder (repro/LFV-683/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/classification/build/libs/lucene-classification-$V.jar
CP=$CP:$LUCENE/lucene/grouping/build/libs/lucene-grouping-$V.jar
CP=$CP:$LUCENE/lucene/queries/build/libs/lucene-queries-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.classification.utils.TestDatasetSplitterUnlabelledDocs
- Expected vs actual
- Expected
d2(the only document of class b) in one of the three outputs; actual: the outputs hold[d0, d1].
More files, environment, full output47 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected d2 (the only document of class b) in one of the outputs, but they hold [d0, d1]
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.assertTrue(Assert.java:42)
org.apache.lucene.classification.utils.TestDatasetSplitterUnlabelledDocs.testUnlabelledDocumentDropsLabelledClass(TestDatasetSplitterUnlabelledDocs.java:72)- The class promises "training / test / cross validation indexes from the original index", and LUCENE-7196 added the grouping for "guaranteed class coverage"; losing a whole class is the opposite.
- No javadoc requires a class value on every document; the module's classifiers handle unlabelled documents on purpose.
- Which group vanishes depends only on where the first unlabelled document sits.
The full argument347 words
- The contract. "Utility class for creating training / test / cross validation indexes from the original index" (
DatasetSplitter.java:44-46); the class field "must be indexed with sorted doc values" (:74-75), a property of the field, not a rule that every document has a value; the only documented failure is "@throws IOException if any writing operation fails on any of the indexes" (:78). The contract is implied, not literal: no javadoc promises that every document lands in exactly one output. - The grouping exists for class coverage. LUCENE-7196 (#8251, "DataSplitter should be providing class centric doc sets in all generated indexes") added it, committed as "guaranteed class coverage in split indexes through grouping by class". Before that, split copied every hit of a
MatchAllDocsQuery(6.0.1), so this is a regression of that change. - The count was meant to be enough. The code comment says "get the exact no. of existing classes" (
:96); LUCENE-7591 (#8642) calls its fallback "an approximate count (upper bound)". - A missing class field was handled before. 6.1.0 checked
if (terms != null)and otherwise fell back to 10,000 groups; on main, LUCENE-7591 replaced the laterIllegalStateException(the LUCENE-7400 version) with the terms fallback but no null check. The module has fixed the same null-Termspattern elsewhere: LUCENE-7303 (#8357, "Avoid NPE if classField doesn't exist in SNBC") and LUCENE-7950 (#8999). - Unlabelled documents are expected. LUCENE-5338 made the classifiers skip them, and the module's test base indexes them (
ClassificationTestBase.java:227,:333).TestDataSplitter, the only regular splitter test, labels every document (TestDataSplitter.java:64-80), which is why it never showed (the other caller, the@MonsterTest20NewsgroupsClassification, is skipped by default); no javadoc, CHANGES or MIGRATE entry mentions documents without a class value. - Index order alone decides. Of 996 single-segment indexes of 1-5 documents that mix labelled and unlabelled documents, 660 lose a labelled document and 336 lose only unlabelled ones; all 363 fully labelled ones are correct, and the other 5 of the 1,364, with no labelled document at all, throw an exception (not with the fix).
The devil's-advocate check199 words
The strongest "works as designed" case, built by the intended-lens review (another model family) and the devil's advocate: a supervised dataset is fully labelled; the class field "must be indexed with sorted doc values"; the only regular upstream test labels every document; there is no explicit promise of a complete partition; and 6.2.0-6.6.6 deliberately threw IllegalStateException for a segment without sorted doc values.
Why it fails: nothing documents a fully labelled precondition, and the module's classifiers handle unlabelled documents on purpose, with no contrary restriction in DatasetSplitter. The cut group is chosen by index order, so a labelled class can vanish while the unlabelled documents are kept, the opposite of any "ignore unlabelled" design. LUCENE-7591 replaced the old exception with a fallback meant to handle such segments, so the NullPointerException is not an intended rejection, and leaving the writers locked is wrong for any exception. Verdict: a defect (adjudication: confirmed, high; every verifier: real; the cross-model lenses rated the intended-behaviour argument weak; a later fact check by the same model family rated it moderate for the labelled-class loss and weak for the NullPointerException half, and suggested inviting maintainers to choose whether unlabelled documents are kept or left out).
Recommended Count the null group, null-check the terms, open the writers inside the try
Count one extra group for documents without a class value, null-check terms(classFieldName), and open the three writers inside the try so any failure closes them (+14/-6 lines). The repro, the whole classification test suite and the module's format and lint checks pass; 3,000 random indexes lose nothing.
        Terms terms = leave.reader().terms(classFieldName);
        if (terms != null) {
          noOfClasses += terms.size();
        }
      }
      noOfClasses += valueCount;
    }
    // documents without a class value form one more group (the null group)
    noOfClasses++;

    IndexWriter testWriter = null;
    IndexWriter cvWriter = null;
    IndexWriter trainingWriter = null;
    try {
All options and trade-offs3 options · 649 words
Unlabelled documents keep being copied, as today when they are not the cut group. A maintainer may prefer to leave them out on purpose with setIgnoreDocsWithoutGroupField(true) (option B); either removes the labelled loss. The two options are a policy choice (keep or leave out the unlabelled documents), not two ways to the same output. Workaround until a fix ships: give every document a value of the sorted doc-values class field (for example an explicit "none" class), or delete the unlabelled documents and commit before opening the reader for split; that route was run on main for one segment and for a segment without the class field (IndexWriter drops a fully deleted segment); a merge policy that keeps fully deleted segments was not tried.
Count the null group, null-check the terms, open the writers inside the try (validated by the checks) (recommended)
After the class count, add noOfClasses++ ("documents without a class value form one more group"); in the terms fallback, add only when terms != null; declare the three writers as null before the try and create them as its first statements (IOUtils.close in the finally skips nulls). +14/-6 in DatasetSplitter.java.
        Terms terms = leave.reader().terms(classFieldName);
        if (terms != null) {
          noOfClasses += terms.size();
        }
      }
      noOfClasses += valueCount;
    }
    // documents without a class value form one more group (the null group)
    noOfClasses++;

    IndexWriter testWriter = null;
    IndexWriter cvWriter = null;
    IndexWriter trainingWriter = null;
    try {
Trade-offs
- Unlabelled documents form their own group, so they also get the test and cross-validation ratios. The extra group changes nothing when every document is labelled.
- It also removes the empty-index
topNGroups must be >= 1 (got 0)error seen in PR #12942 (the limit is then 1). - A failure while opening a writer now reaches the caller wrapped in
IOExceptionby the existingcatch, and thefinallycloses the caller's reader, as for every failure inside thetrytoday (read, not run separately). - Not changed:
Terms.size()may return -1 when a codec does not store it (the default codec does); a SortedSet or terms-only class field still fails in the grouping even when every document is labelled (a separate lead).
What the checks validated
- Scratch worktree of main
a9779ef3c193, gradle: the new test passes 2 of 2; the whole:lucene:classification:testpasses with assertions on and off (13 suites, 45 tests, 0 failures, 1@Monstertest skipped). :lucene:classification:check -x testpasses (checkGoogleJavaFormat,ecjLintMain,ecjLintTest,forbiddenApisMain,forbiddenApisTest).- Standalone runner with the patched class shadowed: this doc's test (
-ea,-da), the finder's (2/2) and the independent reproducer's (4/4) pass; the devil's advocate probe passes its 4 tests of this bug, including all 1,364 enumerated indexes. - 3,000 random indexes (several segments, deletions, empty indexes): 0 losses, 0
NullPointerExceptions, 0 empty-index errors (stock main: 264 labelled losses, 151 unlabelled-only losses, 264NullPointerExceptions, 12 empty-index errors); the 3,001-document cases copy every document.
Same as the recommended option, but call gs.setIgnoreDocsWithoutGroupField(true) (added in PR #15167) instead of counting an extra group.
Trade-offs
Fits "classifiers skip unlabelled documents", but changes the outputs: unlabelled documents are never copied, while today they usually are. The empty-index error stays (the limit is still 0; add Math.max(1, noOfClasses)). The flag is honoured by the returned groups, which is all split reads; totalGroupCount still counts the null group. Validated partly: this doc's test passes 2 of 2 with it; the finder's and the independent reproducer's tests then fail only where they expect the unlabelled document to be copied.
Pass an upper bound that cannot be short.
Trade-offs
The first grouping pass sizes its comparators and its group map by the limit (FirstPassGroupingCollector.java:116, :121), so memory grows with the index instead of with the number of classes. Not run.
A classifier trained on such a split (for example for spam filtering or moderation) never sees the lost class, but that depends on the application's own use; the application makes the call on its own index, and no untrusted input is involved.
A bounded-exhaustive check ran the real split() on every index of 1-4 documents and checked that every live document lands in exactly one output. 7,680 of 24,816 splits lost documents, each with an unlabelled document; 9,264 threw NullPointerException; none failed when every document was labelled. Independent AI tools then reproduced, reviewed and judged it.
The method in full171 words
Method: semi-formal (the hunt's tier for tool-guided finds that are not a formal tool's own output): a bounded-exhaustive check of the real jar, a hunt unit (classification, k-NN and utils against reference semantics), 2026-10-27, stock main jars.
- The harness enumerated every index of 1-4 documents: class none, a or b; 1 or 2 values of a stored text field; one segment or one per document; no deletion or the first document deleted;
fieldNamesnull or {id, text, cls}; ratios 0.1/0.1 or 0.5/0.25. - At n = 4: 24,816 splits; 7,680 lost documents (every one with a live unlabelled document; none duplicated a document or copied a deleted one; the count mixes unlabelled-only and labelled losses), 9,264 threw
NullPointerException(every one with a segment without the class field), and none failed when every document had a class value. - It was then reduced to a public-API JUnit test, and independent AI tools reproduced, reviewed and judged it (see the checks). The devil's advocate's enumeration separates the labelled losses: 660 of 996 mixed single-segment indexes.
No prior report found (best-effort search, 2026-10-27): two scripted prior-report search runs and 28 direct searches over GitHub, the mailing lists, JIRA and the web, plus every open PR and every classification-module issue. Related: PR #12942 shows the same group-limit call failing on an empty index, left undiagnosed.
Searches4 searches
No issue, PR, review comment, commit, CHANGES or MIGRATE entry, JIRA ticket, list thread, downstream issue or web page reports that DatasetSplitter drops a labelled class when some documents have no class value, or the NullPointerException with the output writers left locked. Not fixed: DatasetSplitter.java last changed upstream in #15499 (2025-12-11, a refactor).
Closest items, none a report of this bug: PR #12942 (merged 2023-12-14) shows Test20NewsgroupsClassification failing in DatasetSplitter.split with topNGroups must be >= 1 (got 0) ("I'm not quite sure how to fix this one so I leave it be"); its trigger is an empty index, the same call with a different defect: an empty index has no null group, it fails loudly with a limit of 0 instead of losing documents, and the obvious fix for it, Math.max(1, noOfClasses), would leave this bug in place. #8251 / LUCENE-7196, #8642 / LUCENE-7591 and #8453 / LUCENE-7400 are the history that introduced the code. #8357 / LUCENE-7303 and #8999 / LUCENE-7950 fixed the same null-Terms pattern in other classifiers. PR #15167 added setIgnoreDocsWithoutGroupField. Open PR #16847 is the only open PR touching the file and changes one unrelated line. Gaps: the GitHub search quota was briefly exhausted (all logged queries completed after back-off); private channels cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene, apache/solr, two downstream search engines, apache/lucenenet, all of GitHub) | 2026-10-27 | two scripted prior-report search runs (16 GitHub, 3 commit queries each, plus 2 downstream) and 28 direct searches, including every module:classification item (68) | no report; 13 hits read, none the same bug; PR #12942 related |
| Open PRs | 2026-10-27 | the changed files of every open apache/lucene PR (up to 400), for classification and grouping files | only #16847 touches the file (one unrelated line) |
| JIRA archive and mailing lists | 2026-10-27 | 4 JIRA queries per tool run, all 47 modules/classification titles read, SOLR searches; 20 list queries per run over dev@, java-user@, issues@, commits@ and the Solr lists | commit notices for LUCENE-7400 and LUCENE-7591 only |
| Web and local history | 2026-10-27 | two web queries; git log --follow on the file and --grep DatasetSplitter|DataSplitter | nothing relevant; no fix commit |
Introduced in 6.1.0 by LUCENE-7196 (2016), which replaced "copy every document" with grouping by class and a group limit that never counts the null group; the NullPointerException came with LUCENE-7591 in 7.0.0. Executed on all 93 releases from 5.5.5 to 10.5.2: every one from 6.1.0 on loses the class.
Versions tested8 rows
Labelled-class loss: introduced by LUCENE-7196 (2016-04-08, @tteofili, pushed directly to git, with no pull request and no CHANGES entry): branch_6x commit ff3661abdaa ("guaranteed class coverage in split indexes through grouping by class"), first released in 6.1.0 (release commit of 2016-06-12, tagged 2016-06-16); its trunk twin 112078eaf90 is what git blame on main credits. Later rewrites of the count (LUCENE-6766, LUCENE-7350, LUCENE-7400, LUCENE-7591) kept the missing null group.
NullPointerException: introduced by LUCENE-7591 (87d8b5450a6, 2016-12-12, "approximate to no. of terms when DVs are not available"), first released in 7.0.0 (release commit of 2017-09-08, tagged 2017-09-18). It replaced an IllegalStateException with terms(classFieldName).size() and no null check. The writers have been opened before the try since the class was created (LUCENE-4345, 2012).
Commit isolation (only DatasetSplitter.java swapped into old jars): 6.0.1 jars with the LUCENE-7196 file lose d2, with its parent they keep all three; 6.6.6 jars with the LUCENE-7591 file throw the NullPointerException, with its parent the IllegalStateException.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's test: 2 of 2 fail (gradle and the standalone runner, assertions on and off) |
| 10.5.2, 9.12.3 | affected | this doc's test: 2 of 2 fail, the same messages, with assertions on and off |
| 7.0.0 - 10.5.2 (74 releases) | release sweep | d2 lost; a segment without the class field throws NullPointerException and leaves the writers locked |
| 6.2.0 - 6.6.6 (15 releases) | release sweep | d2 lost; a segment without sorted doc values throws IllegalStateException (the documented precondition), writers left locked |
| 6.1.0 | first release | d2 lost; a missing class field falls back to 10,000 groups and is copied |
| 5.5.5, 6.0.0, 6.0.1 | no grouping | split has no class parameter and copies every document |
| 6.0.1 jars + the LUCENE-7196 file vs its parent | commit isolation | the LUCENE-7196 file loses d2; its parent keeps all three |
| main + the fix | not affected | every repro passes; the whole classification test suite and the module's checks pass |
An independent reproducer, two executed reviews by another model family, a devil's advocate and an audit each found it real with their own tests; an adjudication confirmed it by re-running two of them with a fresh seed. This doc's own test reproduced it through gradle and validated the fix.
Checks and verdicts415 words
Every check on main ran on the stock jars with assertions on and off (the fix checks with a shadowed class). The reviews by the other model family (OpenAI GPT-5.6) executed their own tests on main ea57360912ed, whose classification and grouping sources equal a9779ef3c193's; separate runs re-ran their tests and the finder's on a9779ef3c193.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Bounded-exhaustive check (24,816 splits at n = 4); public-API JUnit fails 2 of 2 on main (-ea, -da), 10.5.2 and 9.12.3; passes with its fix sketch, as do the 42 upstream classification tests. |
| Independent reproducer | real | Own 4-test JUnit: 3 fail on main (-ea, -da), 10.5.2 and 9.12.3 (unlabelled first loses class b, unlabelled last loses only u0, a segment without the field gives the NullPointerException and a locked directory); the control passes; deterministic over 25 iterations. |
| Cross-model review, refute lens | real (high) | Another model family (OpenAI GPT-5.6), executed: own 4-test JUnit, the 2 bug tests fail and the 2 controls pass, also with a second seed and with -da; passes with the fix, and upstream TestDataSplitter passes. Intended-behaviour argument: weak. |
| Cross-model review, intended lens | real (high) | Own expected-behaviour JUnit fails 2 of 2 on main and passes with the fix together with TestDataSplitter (4 of 4); the same behaviour on 10.5.2 and 9.12.3. Intended-behaviour argument: weak. |
| Devil's advocate | real | Built the strongest "works as designed" case and rejected it for the labelled loss; enumerated 1,364 single-segment indexes (660 of 996 mixed ones lose a labelled document, 336 only unlabelled ones, all 363 fully labelled ones correct; all pass with the fix); found the multi-segment masking. |
| adjudication | confirmed (high) | Re-ran the independent reproduction's JUnit with seed 7E57CAFE (3 of 4 fail, the control passes) and the finder's with -da (2 of 2 fail); no duplicate. |
| Follow-up and audit | keep | History matrix of 104 executed runs; security probe (none); re-runs with new seeds fail 2 of 2. A realistic 500-document probe loses labelled documents in 64 of 100 force-merged trials and 0 of 100 multi-segment ones. |
| this doc's runs | reproduced, fix validated | The doc's 2-test JUnit fails 2 of 2 through gradle on main and through the standalone runner on main, 10.5.2 and 9.12.3, each with assertions on and off; with the fix it and the whole classification test suite pass, :lucene:classification:check -x test passes, and 3,000 random indexes lose nothing. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 394 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,635 words
- Registry title
- DatasetSplitter.split can silently leave a whole labelled class out of all three output indexes when some documents have no class value, and throws NullPointerException, leaving the output writers locked, when a segment has no class field
- Area
- classification / utils: DatasetSplitter (split: class count used as the GroupingSearch group limit)
- Priority
- Low, rank 341: In the little-used offline DatasetSplitter utility, and only on force-merged indexes that also hold unlabelled documents.
- Impact class
- silent wrong results
- Impact note
- Anyone who builds training, test and cross-validation indexes with DatasetSplitter.split from an index in which some live documents have no class value (unlabelled documents, which the module's classifiers skip on purpose) can silently lose every document of one labelled class from all three outputs: on a single-segment index (the upstream test force-merges to one) the class whose first document comes last in index order is dropped whenever an unlabelled document comes before it, while multi-segment indexes whose classes repeat across segments over-count the classes and hide the loss; a segment with no class field at all instead makes split throw NullPointerException and leave the three output directories locked and the caller's reader open; there is no scale condition, -ea and -da behave the same, the source index is not changed, and fully labelled indexes are not affected.
- Summary
- You split an index with DatasetSplitter.split(reader, train, test, cv, analyzer, false, "cls"), where one segment holds d0 without a class value, d1 of class a and d2 of class b. You expect every live document in one of the three new indexes, and every class present, which is what the grouping by class was added for (LUCENE-7196). Instead d2, and with it all of class b, is in none of the outputs: split asks GroupingSearch for as many groups as there are class values, but the documents without a value form one more (null) group that takes one of those slots; and if a segment has no class field at all, split throws NullPointerException from terms(classFieldName).size() before its try block, so its three IndexWriters are never closed.
- Introduced
- Labelled-class loss: ff3661abdaa5b4ae33496dc378ae917f7a7a723b (branch_6x, 2016-04-08, 'LUCENE-7196 - guaranteed class coverage in split indexes through grouping by class (cherry picked from commit 112078e)'), the commit that shipped in 6.1.0; its trunk twin 112078eaf909bdda27a092d13a8431c046a82ac0 (same day, same DatasetSplitter.java, first released in 7.0.0) is what git blame on main credits for the GroupingSearch lines and the gs.search(..., 0, noOfClasses) call. It replaced 'copy every hit of a MatchAllDocsQuery' with GroupingSearch by class and a group limit equal to the number of class values, which never counts the null group of documents without a value; the later rewrites of that count kept this (LUCENE-6766 in 6.2.0, LUCENE-7350 in 6.4.0, LUCENE-7400 in 7.0.0). So it is a regression of LUCENE-7196, not inherited behaviour. NullPointerException half: 87d8b5450a6d75fdd4b724b24a3722054b6d00f8 (master, 2016-12-12, 'LUCENE-7591 - approximate to no. of terms when DVs are not available', first released in 7.0.0), which replaced a deliberate IllegalStateException with leave.reader().terms(classFieldName).size() and no null check. The writers have been opened before the try since the class was created (3459b28334e2, LUCENE-4345, 2012); an input can reach that leak only since 6.2.0, when a check that can throw came before the try. All are svn-era commits by @tteofili with no pull request and no CHANGES entry; the issues LUCENE-7196 / #8251 and LUCENE-7591 / #8642 never mention documents without a class value. [exec: commit isolation with only DatasetSplitter.java swapped in: 6.0.1 jars with the ff3661abdaa file lose d2, with its parent f18cb90104a (the 6.0.1 file) they keep all three documents; 6.6.6 jars with the 87d8b5450a6 file throw NullPointerException, with its parent 25c7855bbae (the LUCENE-7400 file) IllegalStateException, both leaving the writers locked. read: git log --follow, git blame and git tag --contains in the history clone] (2016-04-08 (LUCENE-7196, labelled-class loss); 2016-12-12 (LUCENE-7591, NullPointerException half))
- First affected version
- 6.1.0 [exec] (tagged 2016-06-12) for the labelled-class loss; 7.0.0 [exec] (tagged 2017-09-08) for the NullPointerException. Last unaffected release: 6.0.1 [exec], whose split() has no classFieldName parameter and copies every document.
- Affected versions
- Labelled-class loss: every release from 6.1.0 to 10.5.2 (90 releases) and main a9779ef3c193; not fixed. Segment without the class field: 7.0.0-10.5.2 (74 releases) and main throw NullPointerException and leave all three output directories locked; 6.2.0-6.6.6 (15 releases) throw IllegalStateException ('the classFieldName "cls" must index sorted doc values', the documented precondition) before the try and also leave the three directories locked; 6.1.0 copies that document and releases the locks. Not affected: 5.5.5, 6.0.0 and 6.0.1 (no class-aware split; every document is copied). [exec] the follow-up's version-portable main() probe (core API only, split() overload chosen by reflection, NIOFSDirectory) on all 93 releases 5.5.5-10.5.2 and on main with -ea, plus -da on 10.5.2 and main (104 executed runs with the JUnit and commit-isolation runs): scenario A (one segment: u0 unlabelled, d1=a, d2=b) gives [d1, u0] on every affected version; the fully labelled control gives [d0, d1, d2] everywhere; scenario A2 (unlabelled document last) gives [d1, d2], so then only the unlabelled document is dropped. The finder's JUnit (compiles from 9.5 on) fails 2 of 2 on 9.12.3, 10.5.2 and main (-ea and -da); the independent reproduction's JUnit fails 3 of 4 on main (-ea and -da), 10.5.2 and 9.12.3. [read] lucene/classification and lucene/grouping are unchanged between ea57360912ed and a9779ef3c193; upstream, DatasetSplitter.java last changed in #15499 (2025-12-11, a refactor), and no open PR changes the class count or the null handling (prior-report search against upstream main a95c754ee003, 2026-10-26).
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (searched 2026-10-27, read-only: the finder's scripted prior-report search, the prior-report record, verdict new): two scripted prior-report searches (16 GitHub, 3 commit, 20 mailing-list and 4 JIRA queries each, plus 2 downstream queries in the second), 28 direct GitHub searches (apache/lucene incl. all 68 module:classification items, and apache/solr, elastic/elasticsearch, opensearch-project/OpenSearch, apache/lucenenet and all of GitHub), the changed files of every open apache/lucene PR (up to 400), the dev, java-user, issues and commits lists plus Solr lists, JIRA LUCENE (all 47 modules/classification titles read) and SOLR, two web queries and the full git history. Nothing describes the dropped labelled class or the NullPointerException with the writers left locked. Related, not this bug: PR #12942 (merged 2023-12-14) shows DatasetSplitter.split failing with 'topNGroups must be >= 1 (got 0)' in Test20NewsgroupsClassification, left undiagnosed; its trigger is an empty source index, so it is the same group-limit call with a different trigger and defect. History, not reports: #8251 / LUCENE-7196 (introduced the grouping), #8642 / LUCENE-7591 (introduced the terms().size() fallback, calling the count 'an approximate count (upper bound)'), #8453 / LUCENE-7400. Precedents for the same null-Terms fix elsewhere in the module: #8357 / LUCENE-7303 and #8999 / LUCENE-7950; LUCENE-5338 shows unlabelled documents are an expected input. PR #15167 (merged 2025-10-06) added GroupingSearch.setIgnoreDocsWithoutGroupField, a possible fix tool. The only open PR touching the file, #16847, changes one line (Math.toIntExact(maxDoc())) and leaves the count and the null handling alone. Not fixed upstream. Gaps: the GitHub search quota was briefly exhausted mid-run (all logged queries completed after back-off); the independent reproduction's own search hit a rate limit; private reports and chat are not searchable.
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-27) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the 10.5.2 and 9.12.3 release jars through the standalone runner, with assertions on and off (this doc's test). A version-portable probe ran on all 93 releases from 5.5.5 to 10.5.2 and on main. The cross-model reviews ran on mainea57360912ed, whose classification and grouping sources equala9779ef3c193's, and their tests were re-run ona9779ef3c193. The fix was validated in the scratch worktree: the new test, the whole:lucene:classification:test(assertions on and off) and:lucene:classification:check -x test.
- Finding record
lucene/classification/src/java/org/apache/lucene/classification/utils/DatasetSplitter.java:44-46 (at a9779ef3c193) (class javadoc 'Utility class for creating training / test / cross validation indexes from the original index'), :74-75 (class field 'must be indexed with sorted doc values'), :78 ('@throws IOException if any writing operation fails on any of the indexes'), :92-94 (three IndexWriters opened before the try), :96-115 (noOfClasses counts class values only; :112 leave.reader().terms(classFieldName).size() with no null check), :117 (try), :119-126 (GroupingSearch, Sort.INDEXORDER, gs.search(indexSearcher, MatchAllDocsQuery.INSTANCE, 0, noOfClasses)), :174-179 (catch wraps in IOException; finally closes the writers and the reader)lucene/core/src/java/org/apache/lucene/index/LeafReader.java:134 (at a9779ef3c193) ('Returns the Terms index for this field, or null if it has none')lucene/grouping/src/java/org/apache/lucene/search/grouping/GroupingSearch.java:63 (at a9779ef3c193) (ignoreDocsWithoutGroupField defaults to false), :393-403 (setIgnoreDocsWithoutGroupField: 'instead of putting them in a null group'); FirstPassGroupingCollector.java:80-88 (same null-group javadoc)lucene/classification/src/test/org/apache/lucene/classification/utils/TestDataSplitter.java:64-80 (at a9779ef3c193) (every document labelled, SortedDocValuesField class field, forceMerge(1)); lucene/classification/src/test/org/apache/lucene/classification/ClassificationTestBase.java:227, :333 (unlabeled documents in the module's own tests)GitHub and JIRA, read-only (2026-10-27): apache/lucene #8251, #8642, #8453, #8357, #8999, #12932, #12942, #15167, #16847, #10060; LUCENE-5338; apache/lucenenet #27 and #1261
- The finding in 30 seconds
lucene/classification/src/java/org/apache/lucene/classification/utils/DatasetSplitter.java:44-46, :66-78, :92-94, :96-115, :117, :119-126, :140-164, :174-179lucene/grouping/src/java/org/apache/lucene/search/grouping/GroupingSearch.java:63, :393-403; FirstPassGroupingCollector.java:80-88lucene/core/src/java/org/apache/lucene/index/LeafReader.java:134lucene/core/src/java/org/apache/lucene/index/Terms.java:99-101 ("does not take deleted documents into account")
- Who is affected
lucene/classification/src/java/org/apache/lucene/classification/utils/DatasetSplitter.java:68lucene/classification/src/test/org/apache/lucene/classification/utils/TestDataSplitter.java:64-80lucene/classification/src/test/org/apache/lucene/classification/ClassificationTestBase.java:227, :333
- Why it looks unintended
lucene/classification/src/java/org/apache/lucene/classification/utils/DatasetSplitter.java:44-46, :74-75, :78, :96lucene/classification/src/test/org/apache/lucene/classification/utils/TestDataSplitter.java:64-80; ClassificationTestBase.java:227, :333
- Suggested fix
lucene/core/src/java/org/apache/lucene/util/IOUtils.java:71-100 (close skips nulls); lucene/core/src/java/org/apache/lucene/index/Terms.java:99lucene/grouping/src/java/org/apache/lucene/search/grouping/FirstPassGroupingCollector.java:97-98, :116, :121
- TestDatasetSplitterUnlabelledDocs.java (JUnit test):
repro/LFV-683/src/org/apache/lucene/classification/utils/TestDatasetSplitterUnlabelledDocs.java(76 lines)
A summary still (the PNG), made in parallel with this doc from an executed trace of the main jars, with the fix as control.
assets/LFV-683/bug.png(394 KB)