Lucene's classification module can train on part of an index: the classifiers take a training query, documented as "a Query to eventually filter the docs used for training the classifier, or null if all the indexed docs should be used". The k-NN classifiers then vote among the k most similar labelled documents, weighting each vote by its score.
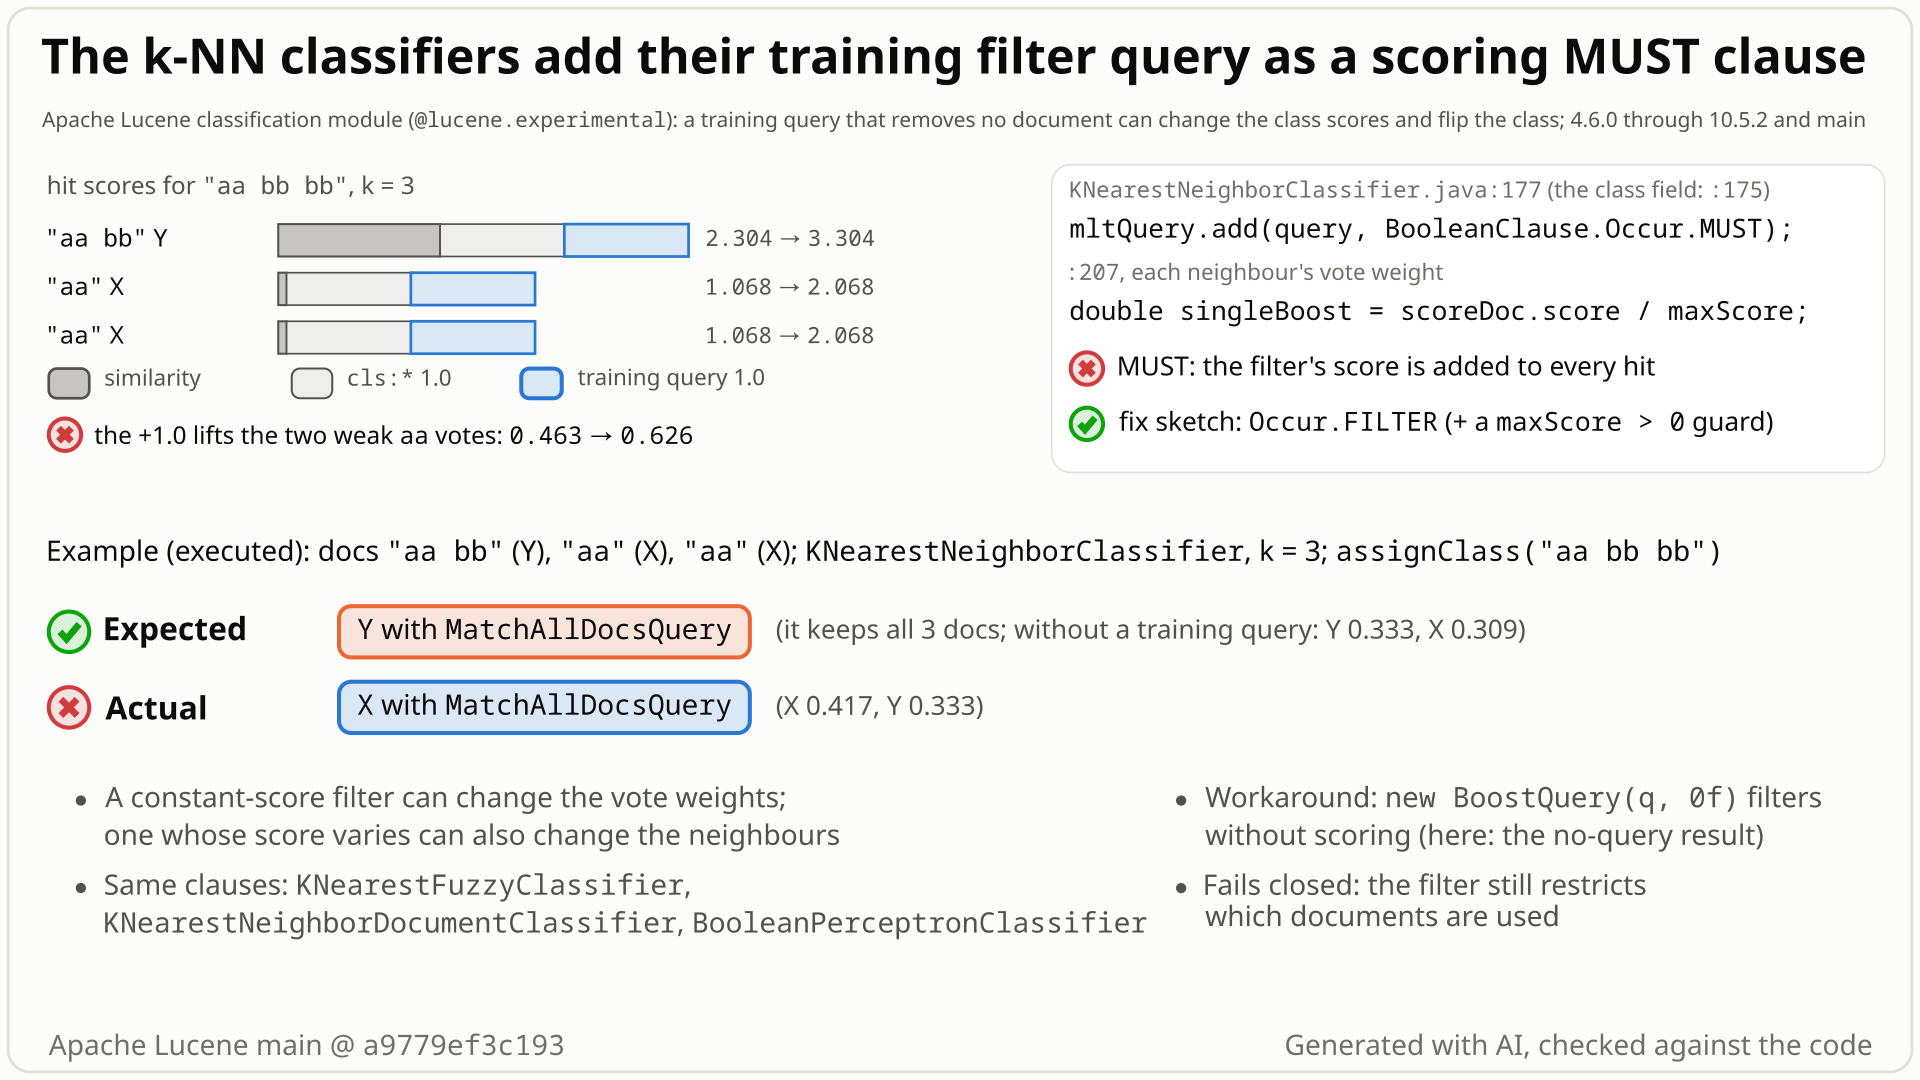
MatchAllDocsQuery. The extra 1.0 lifts each "aa" vote from 0.463 to 0.626, so X beats Y; expected against actual on main. Select the still to open it at full size. Generated with AI, checked against the code.- Index three labelled documents: "aa bb" (class Y), "aa" (X), "aa" (X). Classify "aa bb bb" with
KNearestNeighborClassifier, k = 3, minDocFreq 1, minTermFreq 1: with no training query you get Y (Y 0.333, X 0.309). - Pass a training query that keeps all three documents:
MatchAllDocsQuery, orIntPoint.newRangeQuery("year", 2020, 2025). The javadoc calls it "a Query to eventually filter the docs used for training", so, read as a filter, you expect Y again. - You get X (X 0.417, Y 0.333). No error, with assertions on or off. The same filter with score 0,
new BoostQuery(q, 0f), gives Y. - Why: the filter is added as a scoring MUST clause, so each neighbour's score gains 1.0 ("aa bb" 2.30 to 3.30, each "aa" 1.07 to 2.07). Votes are weighted by score / top score, so each X vote grows from 0.46 to 0.63 and two X votes beat one Y vote.
- A filter whose score varies, such as a term on a text field, can even swap the nearest neighbour (k = 1: "aa", class X, becomes "aa bb", class Y). The fuzzy, document and perceptron classifiers are hit too;
Occur.FILTERfixes it.
Applications that pass a training query to KNearestNeighborClassifier, KNearestNeighborDocumentClassifier, KNearestFuzzyClassifier or BooleanPerceptronClassifier (opt-in, @lucene.experimental). In a 300-document probe the class scores moved in 590 to 705 of 800 cases; the class flipped in 0 of 800 for constant-score filters and up to 320 of 800 for text-scored ones.
Mechanism, terms and numbers826 words
KNearestNeighborClassifier, KNearestNeighborDocumentClassifier, KNearestFuzzyClassifier and BooleanPerceptronClassifier take a training query, documented as "a Query to eventually filter the docs used for training the classifier, or null if all the indexed docs should be used". The k-NN classifiers add it, and the class-field restriction WildcardQuery(class:*), to their similarity search as scoring Occur.MUST clauses, so the filter's score is added to every neighbour's score; each vote is then weighted by score / top score. A filter that keeps every document can therefore still change the class scores (from 5.3.0 for constant-score filters), and the class whenever the shift outweighs the similarity gap: on three documents, MatchAllDocsQuery or a year range turns Y (Y 0.333, X 0.309) into X (X 0.417, Y 0.333). A filter whose score varies between documents can also change which documents are the nearest neighbours, and the perceptron, which trains in the score order of the same kind of query, can learn a different model. The filter still restricts which documents are used. Every release from 4.6.0 to 10.5.2 and main is affected; Occur.FILTER for the training query fixes it, and new BoostQuery(q, 0f) (same matches, no score) is a workaround.
- Training query: a constructor argument of
KNearestNeighborClassifier,KNearestNeighborDocumentClassifier,KNearestFuzzyClassifierandBooleanPerceptronClassifier: "a Query to eventually filter the docs used for training the classifier, or null if all the indexed docs should be used" (KNearestNeighborClassifier.java:82-83; the same in the other three). For example, train only on the training split, one tenant or one time window. - k-NN vote: the classifier searches for the k labelled documents most similar to the input (MoreLikeThis, or
NearestFuzzyQueryfor the fuzzy variant). Each neighbour votes for its class with weightscore / maxScore, its score divided by the top hit's score (KNearestNeighborClassifier.java:195,:207); a class's score is the sum of its neighbours' weights divided by k (:219-225). - MUST and FILTER: in a
BooleanQuery, aMUSTclause must match and adds its score;FILTERis "Like MUST except that these clauses do not participate in scoring" (BooleanClause.java:35).
knnSearchadds the similarity query asSHOULD(MUSTin the fuzzy classifier, so there a neighbour must match at least one fuzzy term), thenWildcardQuery(class:*)asMUSTand the training query asMUST(KNearestNeighborClassifier.java:171-178;KNearestFuzzyClassifier.java:141-145;KNearestNeighborDocumentClassifier.java:144-151).- So every hit's score is its similarity plus 1.0 for the class-field clause plus the training query's score.
MatchAllDocsQueryand point ranges add a constant 1.0; a term on a text field adds a BM25 score that varies with field length. - The vote divides each score by the top score. Adding the same number to every score pulls every weight towards 1, which favours the class with more, weaker neighbours; a varying addition can also reorder the top k.
BooleanPerceptronClassifierbuilds the same twoMUSTclauses and trains over the hits in score order (BooleanPerceptronClassifier.java:130-140). Without a training query every hit scores 1.0 (doc-id order), and a constant-score filter keeps that order; a text-scored filter can reorder the training. The weights change only for a document the current model misclassifies (:155), and with batch size 1 each change takes effect at once (:162), so the model depends on the order.
- k = 3, documents "aa bb" (Y), "aa" (X), "aa" (X), input "aa bb bb". Similarity: "aa bb" 1.3037, each "aa" 0.0676. With the class-field +1.0: 2.3037 and 1.0676, weights 1.0 and 0.4634, so X = 2 x 0.4634 / 3 = 0.3090 < Y = 0.3333. With
MatchAllDocsQuery(another +1.0): 3.3037 and 2.0676, weights 1.0 and 0.6258, so X = 0.4172 > Y = 0.3333. AnIntPointyear range over all three documents gives the same numbers;KNearestNeighborDocumentClassifierflips the same way;KNearestFuzzyClassifierkeeps X, 0.4997 becomes 0.5554. - k = 1, documents "aa" (X, tags "train news sports 2024") and "aa bb" (Y, tags "train"), input "aa", training query
TermQuery(tags:train). Similarity: "aa" 0.0960, "aa bb" 0.0729. The tag term scores 0.1098 on the one-word tags field and 0.0665 on the four-word one, so "aa bb" ranks first (1.1828 against 1.1625) and the answer changes from X to Y. BooleanPerceptronClassifier(batch size 1, bias 1.5) on two "aa" documents labelled true (tags "train pad") and false (tags "train"): "aa" is false without and true withTermQuery(tags:train).- Control everywhere:
new BoostQuery(q, 0f)matches the same documents with score 0, and for these filters, which keep every document, it gives exactly the no-query answer, so the cause is the filter's score, not its matches. - Secondary: with no training query at all, the class-field clause's 1.0 still gives neighbours that share no term with the input a non-zero vote (in the text and document classifiers; the fuzzy classifier requires a fuzzy term match). The vote formula is not documented, so this is a side effect of the same
MUSTclauses, not a contract break.
Exposure and likelihood326 words
- Who is exposed. Users of the opt-in
lucene/classificationmodule (the four classes are@lucene.experimental) who pass a training query, for example to train on one split, tenant or time window. Callers that passnullget only the secondary class-field effect. - How often. On a 300-document, 3-segment index (283 live) with four filters that select the same 168 documents, the class list differed from the zero-score control in 590 to 705 of 800 cases per classifier and filter (a case is one of 5 values of k and one of 160 input texts; each calls
getClassesandassignClass). The assigned class changed in 0 of 800 cases for the two constant-score filters (aStringFieldterm, anIntPointrange) and in 40 to 320 of 800 for the two whose score varies (a text-field term, a text-scoredBooleanQuery). That probe ran the three k-NN classifiers on main only. In the finder's bounded-exhaustive run over 3,717,152 tiny cases,MatchAllDocsQuerychanged theKNearestNeighborClassifierscores in 2,185,012 cases and the class in 15,617; an all-matching text-field term changed the class in 31,412. - Scale. None needed: three documents flip the class. The shift depends on the filter's score next to the similarity scores:
MatchAllDocsQueryand point ranges add 1.0, while aStringFieldterm every document has adds very little (a verifier saw X 0.31893 become 0.32096, no flip). - Silent. Nothing fails, and there is no unfiltered baseline to compare with; the scores look plausible.
- Not affected. Which documents are used: in 9,600 filtered cases (19,200 filtered calls) there were 0 neighbours from outside the filter and 0 deleted documents. The naive-Bayes classifiers'
MUSTsites only count hits.BM25NBClassifieradds the training query asMUSTtoo, and a verifier's probe showsMatchAllDocsQuerymoving its class scores (Y 0.680 / X 0.320 to Y 0.561 / X 0.439); it is not part of the confirmed claim. - Versions. Every release from 4.6.0 (2013) to 10.5.2 and main; constant-score filters matter from 5.3.0.
The test shows that KNearestNeighborClassifier scores its training query (added as Occur.MUST), so MatchAllDocsQuery, a training query that filters out nothing, changes the assigned class (3 docs, k = 3).
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.classification;

import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.StringField;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.search.MatchAllDocsQuery;
import org.apache.lucene.search.Query;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.analysis.MockAnalyzer;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestKnnTrainingQueryIsScored extends LuceneTestCase {

  public void testMatchAllTrainingQueryChangesAssignedClass() throws Exception {
    Analyzer analyzer = new MockAnalyzer(random());
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig(analyzer))) {
        for (String[] d : new String[][] {{"aa bb", "Y"}, {"aa", "X"}, {"aa", "X"}}) {
          Document doc = new Document();
          doc.add(new TextField("text", d[0], Field.Store.NO));
          doc.add(new StringField("cls", d[1], Field.Store.YES));
          w.addDocument(doc);
        }
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        // MatchAllDocsQuery filters out nothing, so it must give the null-query class Y; it gives X
        assertEquals(
            assign(reader, analyzer, null), assign(reader, analyzer, MatchAllDocsQuery.INSTANCE));
      }
    }
  }

  private static String assign(DirectoryReader reader, Analyzer analyzer, Query trainingQuery)
      throws Exception {
    return new KNearestNeighborClassifier(
            reader, null, analyzer, trainingQuery, 3, 1, 1, "cls", "text")
        .assignClass("aa bb bb")
        .assignedClass()
        .utf8ToString();
  }
}
# in a copy of this finding's repro folder (repro/LFV-684/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/classification/build/libs/lucene-classification-$V.jar
CP=$CP:$LUCENE/lucene/grouping/build/libs/lucene-grouping-$V.jar
CP=$CP:$LUCENE/lucene/queries/build/libs/lucene-queries-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.classification.TestKnnTrainingQueryIsScored
- Expected vs actual
- Expected the null-training-query class
Y; actualX(expected:<[Y]> but was:<[X]>), with-eaand-da.
More files, environment, full output32 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: expected:<[Y]> but was:<[X]>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.classification.TestKnnTrainingQueryIsScored.testMatchAllTrainingQueryChangesAssignedClass(TestKnnTrainingQueryIsScored.java:49)- Every constructor calls it "a Query to eventually filter the docs used for training the classifier";
nullmeans all docs. Occur.FILTERis "Like MUST except that these clauses do not participate in scoring"; theseMUSTclauses predateFILTER(2013).- No javadoc, test or issue says the filter should score; the same all-matching filter with score 0 gives the unfiltered answer.
The full argument302 words
- Contract.
KNearestNeighborClassifier.java:82-83: "@param query a Query to eventually filter the docs used for training the classifier, or null if all the indexed docs should be used"; the field javadoc (:69-72): "a Query used to filter the documents that should be used from this classifier's underlying LeafReader". The same wording inKNearestFuzzyClassifier.java:65,:79,KNearestNeighborDocumentClassifier.java:58andBooleanPerceptronClassifier.java:72. Read as a filter, a query that keeps every document should give thenullresult. The javadoc does not say in so many words that the score is ignored, so this is the natural reading of the contract rather than its literal text; Lucene's CHANGES entries say the same about filtering in general: LUCENE-6227 addedFILTER"to filter documents without participating in scoring (on the contrary to MUST)" (lucene/CHANGES.txt:10935-10936, 5.1.0), and LUCENE-6301 asks for "the BooleanClause.Occur.FILTER clause in order to let Lucene know that a Query should be used for filtering but not scoring" (:9931-9934, 5.4.0). - Tests.
TestKNearestNeighborClassifier#testBasicUsageWithQuery(:145-159) and the matching fuzzy, perceptron, naive-Bayes and document tests check only the assigned class on one sample index. No test compares a filtered and an unfiltered run, and both fixes keep the whole module suite green, so no test pins the scored behaviour. - History. LUCENE-5284 (#6348, commit
e60f7af1d16, 2013-10-17, "added method for training with a Query filter") added the query as aMUSTclause;Occur.FILTERarrived only with LUCENE-6227 (a70006f2f5f, 2015-02-10, 5.1.0). LUCENE-5338 (#6402,debb363f6e3, "avoid considering unlabeled documents for training") added the class-field clause, also as a filter. LUCENE-6654 (#7712,35810f4c77d, 5.3.0) added thescore / maxScorevote because "the MLT score the documents accordingly" and tested only with anullquery. The document (2015) and fuzzy (2017) classifiers copied the clauses; no commit ever usedFILTERin the module.
The devil's-advocate check325 words
The strongest "intended" case: a Query normally scores and MUST keeps the score on purpose; FILTER already existed when LUCENE-6654 added the score-weighted vote and kept MUST; later classes copied the pattern; BM25NBClassifier uses a scored MUST clause (the class term) as its signal; the module is @lucene.experimental; and a zero-boost workaround exists. The cross-model reviewer rated this argument moderate in both of its lenses. The later fact check by a reviewer from the same family adds: callers may have used the query's score as a secondary ranking signal, so a fix changes results that have shipped since 4.6.0; the class-field constant gives every admitted neighbour a vote, much like the count vote before 5.3.0; and an online perceptron depends on example order anyway.
Why the bug reading is still the stronger one for the k-NN classifiers: every javadoc and the introducing issue call the parameter a filter, with null meaning "all the indexed docs", Lucene's CHANGES entries tell users to use FILTER when a query should filter but not score, and nothing anywhere says its score should shift the similarity or the votes (an absence, not proof). The MUST clauses predate FILTER and were carried over unchanged; no commit, issue or comment discusses the choice, and LUCENE-6654 attributes the ranking to the MoreLikeThis score. An ordinary year-range filter that keeps every document flips the class. The BoostQuery(q, 0f) workaround is undocumented; for such a filter it gives exactly the unfiltered result. @lucene.experimental allows API changes, not results that contradict the javadoc. Narrower points stand: the javadoc never says in so many words that the score is ignored; the class-field constant is a weaker finding because the vote formula is undocumented; and the perceptron's training order is undocumented. Every reviewer rated the bug real; the adjudication confirmed it with high confidence. The fact-check reviewer rated the intended case moderate for the training query and the class field and strong for the perceptron order.
Recommended Make the training-query clause a FILTER (fix B)
Add the training query as Occur.FILTER instead of Occur.MUST in the four classifiers, one word each. A filter that keeps every document then gives exactly the no-query result, and callers without a training query see no change. The new test, the closest suites and the whole lucene/classification suite pass with it, assertions on and off.
// KNearestNeighborClassifier:177 and KNearestNeighborDocumentClassifier:151
-      mltQuery.add(query, BooleanClause.Occur.MUST);
+      mltQuery.add(query, BooleanClause.Occur.FILTER);
// KNearestFuzzyClassifier:145
-      bq.add(query, BooleanClause.Occur.MUST);
+      bq.add(query, BooleanClause.Occur.FILTER);
// BooleanPerceptronClassifier:135
-      q.add(new BooleanClause(query, BooleanClause.Occur.MUST));
+      q.add(new BooleanClause(query, BooleanClause.Occur.FILTER));
All options and trade-offs3 options · 853 words
The training query still decides which documents can be neighbours or training examples; it just adds no score. Fix B leaves the class-field clause as a scoring MUST, so maxScore stays at least 1 and no division by zero can appear; fix A, the hunt's original proposal, also turns that clause into FILTER, which changes results for callers without a training query too. Until a fix ships, pass new BoostQuery(query, 0f) as the training query: it stays a required clause that matches the same documents, with score 0, so it acts as a non-scoring filter (for a filter that keeps every document, exactly the unfiltered result). Nothing is stored wrong, so no reindex is needed. Fix B changes results for callers that pass a training query, so it needs a CHANGES entry. Either way, add a test that a filter keeping every document gives the null result for each classifier. BM25NBClassifier has the same training-query MUST (BM25NBClassifier.java:216, :227); if it is included, change only those clauses, because its class TermQuery score is the intended signal there.
KNearestNeighborClassifier.java:177, KNearestNeighborDocumentClassifier.java:151, KNearestFuzzyClassifier.java:145, BooleanPerceptronClassifier.java:135: MUST becomes FILTER.
// KNearestNeighborClassifier:177 and KNearestNeighborDocumentClassifier:151
-      mltQuery.add(query, BooleanClause.Occur.MUST);
+      mltQuery.add(query, BooleanClause.Occur.FILTER);
// KNearestFuzzyClassifier:145
-      bq.add(query, BooleanClause.Occur.MUST);
+      bq.add(query, BooleanClause.Occur.FILTER);
// BooleanPerceptronClassifier:135
-      q.add(new BooleanClause(query, BooleanClause.Occur.MUST));
+      q.add(new BooleanClause(query, BooleanClause.Occur.FILTER));
Trade-offs
Implements the natural, non-scoring reading of the documented filter with the smallest change, and changes nothing without a training query. Callers that pass one get different scores, neighbours and sometimes classes than current releases give (the scored behaviour has shipped since 4.6.0), so it needs a CHANGES entry. It leaves the secondary class-field constant as it is (the independent reproducer's class-field test still fails with it), and the perceptron's initial weights and default bias still come from the whole index (BooleanPerceptronClassifier.java:99-124).
What the checks validated
- Scratch worktree of
a9779ef3c193, gradle, JDK 25: the new test fails 4 of 5 on stock with assertions on and off; with the fix, the new test plusTestKNearestNeighborClassifier,TestKNearestFuzzyClassifier,TestKNearestNeighborDocumentClassifierandTestBooleanPerceptronClassifierpass (5 suites, 21 tests); the whole:lucene:classification:testpasses with assertions on and off (13 suites, 48 tests, 1 skipped, 0 failures each);:lucene:classification:check -x test(google-java-format, ecj lint, forbidden APIs) passes. - Standalone runner with the fix shadowed: the new test 5 of 5 with
-eaand-da; the finder's test 4 of 4; the independent reproducer's test 7 of 8 (only its class-field case fails, as expected).
Occur.FILTER for WildcardQuery(class:*) and the training query in the four classes, plus double singleBoost = maxScore > 0 ? scoreDoc.score / maxScore : 1d; in KNearestNeighborClassifier.java:207 and KNearestFuzzyClassifier.java:172: with FILTER, when no neighbour shares a selected term (text and document classifiers), maxScore is 0 and the weights would be 0/0 = NaN. The class-field change matters differently per class: in the text and document classifiers it stops neighbours with no shared term from voting, in the fuzzy classifier (whose NearestFuzzyQuery stays MUST) it only removes the constant 1.0, and in the perceptron it changes nothing, because a constant score does not change the training order.
-    mltQuery.add(new BooleanClause(classFieldQuery, BooleanClause.Occur.MUST));
+    mltQuery.add(new BooleanClause(classFieldQuery, BooleanClause.Occur.FILTER));
     if (query != null) {
-      mltQuery.add(query, BooleanClause.Occur.MUST);
+      mltQuery.add(query, BooleanClause.Occur.FILTER);
     }
...
-          double singleBoost = scoreDoc.score / maxScore;
+          double singleBoost = maxScore > 0 ? scoreDoc.score / maxScore : 1d;
Trade-offs
- Also removes the class-field constant, so the vote becomes pure similarity weighting: in the lead case the no-query result becomes Y 0.3333, X 0.0346 instead of X 0.3090.
- Changes class scores for every caller, including those without a training query, and sometimes the class: on the lead data the fuzzy classifier with no training query answers Y (0.3333 against X 0.3321) instead of X (0.4997).
- The
maxScore > 0fallback (an unweighted vote) is a design choice for maintainers; neighbours with score 0 still fill the top k.
What the checks validated
Scratch worktree, gradle: the whole :lucene:classification:test passes with assertions on and off (13 suites, 48 tests, 1 skipped, 0 failures each) and :lucene:classification:check -x test passes (its forbiddenApisTest task was reported up to date from the fix B run; the other check tasks ran). Standalone runner: the new test 5 of 5 with -ea and -da, the independent reproducer's test 8 of 8; earlier the finder's test 4 of 4, the 42 upstream classification tests and the security probe (0 violations, 0 non-finite scores) with the same sources.
Pass new BoostQuery(query, 0f) (or new BoostQuery(new ConstantScoreQuery(query), 0f)) as the training query.
Trade-offs
It keeps the query's matches and adds no score, the same effect as fix B; a selective query still removes the documents it does not match. Every executed control used a filter that keeps every document, and there it gave exactly the unfiltered result. Every caller has to know about it; it is undocumented and not a fix.
Solr's classification update processor passes its knn.filterQuery setting to KNearestNeighborDocumentClassifier as this training query, so Solr setups that use that setting get the shifted scores too.
An AI finder compared the four classifiers with a small reference k-NN that weights votes by similarity alone, over 3.7 million tiny indexes per classifier, plus two checks that a training query keeping every document leaves the answer unchanged. Both checks failed thousands of times, and the finder reduced the signal to a public-API JUnit test.
The method in full184 words
Method: semi-formal, bounded-exhaustive translation validation: the real classifiers against an independently written reference, over every case in a small bounded space.
- The reference is a weighted k-NN over the MoreLikeThis or
NearestFuzzyQuerysimilarity alone. Two metamorphic relations: training queryMatchAllDocsQueryagainst none, and a text-fieldTermQuerythat every document matches against none. - Scope: a 4-word vocabulary; every training set of 1 to 3 documents over 2 classes (2-document sets also with each document deleted); 3,000 seeded sets of 4 to 6 documents over 2 or 3 classes; every query text of 1 to 3 words; k = 1 to 4: 3,717,152 cases per classifier.
KNearestNeighborClassifier:MatchAllDocsQuerychanged the scores in 2,185,012 cases and the class in 15,617; the all-matching term changed the class in 31,412. The document variant equalled the text variant in every case.- With fix A, a reduced run of 527,680 cases showed 0 differences of any kind: the independently written reference equals the fixed code.
- The finder then wrote the 4-test JUnit; the independent reproducer, a cross-model reviewer, a devil's advocate and an adjudication each re-ran or rewrote it.
No prior report found (searched 2026-10-27): 189 tool queries plus manual searches over GitHub issues, PRs and commits, JIRA, four mailing lists and downstream projects, all 68 classification-module issues and PRs, all 47 JIRA classification issues and the files of all 409 open PRs. The nearest items are the issues that added the clauses and the weighted vote.
Searches5 searches
Keyword search only: GitHub search hit the shared rate limit twice (re-run), one web query was throttled, and private reports are not visible. Nearest items, none the same bug: #6348 / LUCENE-5284 and #6402 / LUCENE-5338 (added the clauses, as filters); #7712 / LUCENE-6654 (added the score-weighted vote); #9039 / LUCENE-7991 (a different score leak in knnSearch, a boost factor carried to the next field, fixed in 7.2); #9158 / LUCENE-8110 (open, getClasses(text, max) IndexOutOfBoundsException). SOLR-8871 added Solr's knn.filterQuery; no Solr report of the effect. Hunt-internal: LFV-391 (the naive-Bayes classifiers apply the training query to only part of their statistics) is a different bug in different classes with a different fix.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene and the old lucene-solr repository) | 2026-10-27 | the scripted prior-report search in two runs (107 and 82 queries: class names, knnSearch, buildListFromTopDocs, training query, filter, Occur.FILTER, WildcardQuery, "should not score", ConstantScoreQuery, filterQuery), the finder's earlier 43-query run, the verifiers' searches, about 20 manual searches including the javadoc phrase "eventually filter" and the BoostQuery workaround | no report; history items only |
| Classification module items and open PRs | 2026-10-27 | all 68 module:classification issues and PRs read; the changed files of all 409 open PRs plus the 6 opened since 2026-10-25 | only #16847, #681 and #12295 touch the module; none touches these clauses |
| JIRA and mailing lists | 2026-10-27 | all 47 LUCENE modules/classification issues, 5 text queries over the classifier names, 6 SOLR queries; dev@, java-user@, issues@ and commits@ through both tool runs | only JIRA mirrors, the feature issues and unrelated threads |
| Downstream, web and Q&A | 2026-10-27 | Solr, Lucene.NET and two other downstream search engines on GitHub; 4 web searches; Stack Overflow | nothing; SOLR-8871 (knn.filterQuery) reaches the bug but reports nothing |
| Code history | 2026-10-27 | git log -S for Occur.FILTER, the WildcardQuery clause, the query clause and the javadoc wording, plus the per-file logs of the four classes | no commit ever changed these occurs |
Introduced in 4.6.0 by LUCENE-5284 (2013), which added the training query as a scoring MUST clause. Since 5.3.0 (LUCENE-6654, score-weighted votes) constant-score filters change results too. All 121 releases from 4.6.0 to 10.5.2 and main were run and are affected; not fixed upstream.
Versions tested8 rows
Introduced by LUCENE-5284 (#6348, "Make it possible to filter classification training by Query"): trunk e60f7af1d16 (@tteofili, 2013-10-17, "added method for training with a Query filter"); the branch_4x backport 3df19e13b2d (LUCENE-5290, the same day) put it into 4.6.0 (2013-11-22). LUCENE-5338 (debb363f6e3 / a8a8242f50f, 2013-11-11, also 4.6.0) added the class-field MUST clause and moved the training query next to the similarity clauses. LUCENE-6654 (35810f4c77d / 2ddb06f6087, 2015-08-03, 5.3.0) added the score / maxScore vote, from which point constant-score filters matter. BooleanPerceptronClassifier is affected from 5.0.0, KNearestNeighborDocumentClassifier from 6.0.0 and KNearestFuzzyClassifier from 7.0.0, each from its first release. Similarity changes (BM25 in 7.0, its 8.0 revision) move the exact numbers between eras, but in every release from 4.6.0 at least one probe check changes the result.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's test: 4 of 5 fail (gradle and the standalone runner, assertions on and off), Y 0.3333 / X 0.3090 becomes X 0.4172 / Y 0.3333 |
| 10.5.2, 9.12.3 | affected | this doc's test: 4 of 5 fail, the same numbers (10.5.2 also with assertions off) |
| 5.3.0 to 10.5.2 (103 releases) | release sweep | history probes: a text-scored filter swaps the neighbour (X to Y), MatchAllDocsQuery changes the scores or the class; zero-score controls equal the no-query result |
| 4.6.0 to 5.2.1 (18 releases) | varying-score filters only | a text-scored filter swaps the neighbour; MatchAllDocsQuery gives the same answer on 4.7.0-5.2.1, because the vote still counted neighbours (not runnable on 4.6.x) |
3df19e13b2d vs its parent 584a01ca770 (branch_4x) | bisect | the backport introduces it (X to Y); its parent has no training-query API |
2ddb06f6087 vs its parent e3e312702f6 (branch_5x) | bisect | the LUCENE-6654 backport makes MatchAllDocsQuery flip Y to X; its parent gives the same answer |
| 4.2.0 to 4.5.1 (7 releases) | no API | no training-query API |
| fix A or fix B on main | not affected | every repro passes; the whole classification suite passes |
An independent reproducer, a cross-model review (OpenAI GPT-5.6, lenses, executed), a devil's advocate, an adjudication and an audit each confirmed it with executed tests; every zero-score control of an all-matching filter matched the unfiltered result. This doc's gradle runs reproduced it on main a9779ef3c193 and validated both fixes.
Checks and verdicts392 words
The cross-model review ran on main ea57360912ed, whose classification sources equal a9779ef3c193; a separate run re-ran its intended-lens test on a9779ef3c193. Not done: a probe of BM25NBClassifier beyond the devil's advocate's single run.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | The bounded-exhaustive comparison flagged it in 3.7 million cases per classifier; the JUnit test fails 4 of 4 on main with assertions on and off, on 10.5.2 and on 9.12.3, and passes with fix A. |
| independent reproducer | real | Own 8-test class with other data: 7 of 8 fail on main (assertions on and off), 10.5.2 and 9.12.3; the passing test is the zero-score control; 8 of 8 with fix A. Found the secondary class-field case. |
| cross-model review, refute and intended lenses | real (high), intended argument moderate | An independent reviewer from another model family (OpenAI GPT-5.6): its own tests fail on main (2 of 3 and 2 of 4; the zero-score controls pass, and one MatchAllDocsQuery data set did not change the assigned class) and pass with fix A. |
| devil's advocate | real (high for the training query; medium for the class-field and perceptron parts) | Built the strongest intended case and showed why it fails; an IntPoint range over every document flips Y to X, and BoostQuery(q, 0f) restores the unfiltered answer. |
| adjudication | confirmed (high) | Re-ran the independent reproducer with a new seed: 7 of 8 fail with assertions on and off, 8 of 8 with fix A; the finder's test 4 of 4 fail; not a duplicate. |
| audit | keep | Re-ran the finder's test on main: 4 of 4 fail with assertions on and off; code and score re-checked. |
| this doc | reproduced | New 5-test class through gradle and the standalone runner on main, 10.5.2 and 9.12.3; fixes A and B validated; found that the finder's k = 1 case is an exact score tie. |
| fact checks of this doc | pass; substantially sound | An independent fact check re-ran the repro through gradle and the standalone runner (main, 10.5.2, 9.12.3), both fixes and the number probe; every number matched. A second fact check by a reviewer from another model family (OpenAI GPT-5.6) read the sources and logs without running anything and found 4 factual errors (0 high), 8 overclaims and 6 missing caveats; all are addressed on this page. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 390 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,559 words
- Registry title
- KNearestNeighborClassifier, KNearestFuzzyClassifier, KNearestNeighborDocumentClassifier and BooleanPerceptronClassifier add their documented training filter query (and the class-field restriction) as scoring Occur.MUST clauses, so a training query that filters out nothing changes the k-NN class scores and can flip the assigned class, the nearest neighbours or the learned perceptron model (released since 4.6.0)
- Area
- classification / k-NN classifiers and BooleanPerceptronClassifier (training query)
- Priority
- Low, rank 338: In the experimental, little-used classification module.
- Impact class
- silent wrong results
- Impact note
- Applications that use the opt-in, @lucene.experimental lucene/classification module and pass a training query to KNearestNeighborClassifier, KNearestFuzzyClassifier, KNearestNeighborDocumentClassifier or BooleanPerceptronClassifier get silently different results, with -ea and -da alike and no error: any training query with a non-zero score shifts the k-NN class scores on most calls (since 5.3.0; the class list changed in 590 to 705 of 800 calls in the security probe), a query whose score varies between documents (for example a term on a text field) also changes which documents are the nearest neighbours and, for the perceptron, the training order and so the model, and the assigned class flips whenever the shift outweighs the similarity gap (security probe on a 300-document index: 0 of 800 calls for two constant-score filters, 40 to 320 of 800 for two varying-score filters; the finder's 3-document repro flips with MatchAllDocsQuery); no scale is needed, the training query still restricts which documents are used, and every release from 4.6.0 through 10.5.2 and main is affected.
- Summary
- You index three labelled documents ('aa bb' as Y, 'aa' as X, 'aa' as X), build KNearestNeighborClassifier with k = 3 once with no training query and once with MatchAllDocsQuery (the parameter is documented as 'a Query to eventually filter the docs used for training the classifier', and this one removes nothing), and expect the same answer for 'aa bb bb'. Instead the answer flips from Y (class scores Y 0.333, X 0.309) to X (X 0.417, Y 0.333), because the training query and the class-field WildcardQuery are added as scoring Occur.MUST clauses, so their scores are added to every neighbour's MoreLikeThis score before each vote is weighted by score / maxScore; a training query whose score differs between documents, such as TermQuery(split:train) on a text field every document has, even replaces the nearest neighbour (k = 1: 'aa', class X, becomes 'aa bb', class Y). KNearestFuzzyClassifier and KNearestNeighborDocumentClassifier return different class scores in the same way, and BooleanPerceptronClassifier, which trains in the score order of the same kind of query, learns a different model ('aa' answers true instead of false).
- Introduced
- e60f7af1d16c5467a1300abe575ddb983212bfb2 (trunk, LUCENE-5284 "added method for training with a Query filter", Tommaso Teofili, 2013-10-17, svn r1532983): the training query is added to the k-NN search as a scored Occur.MUST clause (and BooleanPerceptronClassifier trains in its score order). The branch_4x backport 3df19e13b2dc55b4dc3d1e4c804ec5c2affd48ad (LUCENE-5290, same day, r1533003) is the commit that put it into a release (4.6.0). Today's lines KNearestNeighborClassifier.java:174-178 blame to debb363f6e3 / branch_4x a8a8242f50f (LUCENE-5338, 2013-11-11, class-field WildcardQuery MUST, training-query MUST moved into the MoreLikeThis BooleanQuery; also 4.6.0) and e60f7af1d16. Constant-score training queries started to matter with 35810f4c77d / branch_5x 2ddb06f6087 (LUCENE-6654, 2015-08-03, score/maxScore vote weighting, 5.3.0). Commit-level runs confirm each step [exec]. No later commit changed these clause occurs; Occur.FILTER has never appeared in lucene/classification [read: git log --all -S]. (2013-10-17 (trunk e60f7af1d16, branch_4x backport 3df19e13b2d the same day); 2013-11-11 (LUCENE-5338 class-field clause, debb363f6e3 / a8a8242f50f); 2015-08-03 (LUCENE-6654 score/maxScore vote weighting, 35810f4c77d / 2ddb06f6087); first release 4.6.0, 2013-11-22)
- First affected version
- 4.6.0 [exec] (KNearestNeighborClassifier with a training query whose score varies between documents; commit-level runs isolate 3df19e13b2d as the step that introduces it, its parent has no training-query API). Constant-score training queries such as MatchAllDocsQuery change results from 5.3.0 (LUCENE-6654), when the vote became score / maxScore. The classification module's earlier releases 4.2.0-4.5.1 have no training-query API [exec]. Per class, each from its first release [exec]: BooleanPerceptronClassifier 5.0.0, KNearestNeighborDocumentClassifier 6.0.0, KNearestFuzzyClassifier 7.0.0.
- Affected versions
- Every release from 4.6.0 to 10.5.2 [exec]: all 121 releases in that range (4.6.0-4.6.1, 4.7.0-4.7.2, 4.8.0-4.8.1, 4.9.0-4.9.1, 4.10.0-4.10.4, all 5.x, 6.x, 7.x, 8.x including 8.8.2-8.11.4, 9.x, and 10.0.0-10.5.2), plus main a9779ef3c193 (unreleased 11.0) with -ea and -da. Not affected: 4.2.0-4.5.1 (7 releases; the classification module first shipped in 4.2.0), which have no training-query API [exec]. Per class [exec]: KNearestNeighborClassifier 4.6.0+; BooleanPerceptronClassifier 5.0.0+ (its first release); KNearestNeighborDocumentClassifier 6.0.0+ (first release); KNearestFuzzyClassifier 7.0.0+ (first release). Constant-score training queries (MatchAllDocsQuery) change k-NN results only from 5.3.0 (LUCENE-6654); in 4.6.0-5.2.1 only training queries whose score varies between documents do. Not fixed upstream as of main a9779ef3c193. [exec] The candidate JUnit fails 4 of 4 on 9.12.3 (9.x API copy), 10.5.2 and main (-ea and -da); the independent reproduction's JUnit fails 7 of 8 on main (-ea and -da), 10.5.2 and 9.12.3 (its one passing test is the zero-score control); the follow-up history probes ran 248 executions over every release from 4.2.0 to 10.5.2, main and five commit-level checkouts.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-27, read-only; the prior-report record verdict new, confidence high): a scripted prior-report search in two runs (107 and 82 queries over GitHub issues and PRs, commits, downstream repositories, the dev, java-user, issues and commits lists, and JIRA), plus the finder's earlier 43-query run and the independent reproduction's and the intended-behaviour check's own searches; all 68 module:classification GitHub issues and PRs; all 47 JIRA issues of component modules/classification and 6 SOLR queries; about 20 manual GitHub searches over apache/lucene, lucene-solr, solr, lucenenet and two downstream search engines (including the javadoc phrase 'eventually filter' and the BoostQuery workaround); the changed files of all 409 open apache/lucene PRs (only #16847, #681 and #12295 touch the module, none of them these clauses); Stack Overflow; the local history. Nearest items, none the same bug: #6348 / LUCENE-5284 (added the training query as a 'Query filter'), #6402 / LUCENE-5338 (added the class-field clause to filter unlabelled documents), #7712 / LUCENE-6654 (added the score / maxScore vote; its tests use a null query), #9039 / LUCENE-7991 (a different knnSearch score leak, a boost factor carried to the next field, fixed in 7.2). Downstream: Solr's knn.filterQuery (SOLR-8871) is passed as the training query to KNearestNeighborDocumentClassifier; no Solr report. Not fixed: every MUST site is still on main a9779ef3c193.
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-27) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the 10.5.2 and 9.12.3 release jars. The version-history runs ran probes on every release from 4.2.0 to 10.5.2 (from the released jars), main and commit-level checkouts of the introducing commits (248 runs: a k-NN probe on 128 releases and main, a probe of the other classifiers on 108 releases and main, 6 commit-level runs, 4 JUnit runs). Fixes A and B were validated in the scratch worktree: the new test, the closest suites (fix B), the wholelucene/classificationsuite with assertions on and off, and:lucene:classification:check -x test.
- Finding record
lucene/classification/src/java/org/apache/lucene/classification/KNearestNeighborClassifier.java:46-50 (at a9779ef3c193) (class javadoc, @lucene.experimental)lucene/classification/src/java/org/apache/lucene/classification/KNearestNeighborClassifier.java:69-72 (at a9779ef3c193) (field javadoc 'a Query used to filter the documents that should be used from this classifier's underlying LeafReader')lucene/classification/src/java/org/apache/lucene/classification/KNearestNeighborClassifier.java:82-83 (at a9779ef3c193) ('@param query a Query to eventually filter the docs used for training the classifier, or null if all the indexed docs should be used')lucene/classification/src/java/org/apache/lucene/classification/KNearestNeighborClassifier.java:174-178 (at a9779ef3c193) (class-field WildcardQuery and training query added as Occur.MUST to the scored k-NN query)lucene/classification/src/java/org/apache/lucene/classification/KNearestNeighborClassifier.java:195, (at a9779ef3c193) 207 (maxScore = top hit score; neighbour weight scoreDoc.score / maxScore)lucene/classification/src/java/org/apache/lucene/classification/KNearestFuzzyClassifier.java:48, (at a9779ef3c193) 79, 143, 145, 172 (experimental; same javadoc; MUST clauses; score / maxScore)lucene/classification/src/java/org/apache/lucene/classification/document/KNearestNeighborDocumentClassifier.java:44, (at a9779ef3c193) 46, 58, 149, 151 (experimental; extends KNearestNeighborClassifier and reuses buildListFromTopDocs; same javadoc; MUST clauses)lucene/classification/src/java/org/apache/lucene/classification/BooleanPerceptronClassifier.java:57, (at a9779ef3c193) 72, 130-140 (experimental; same javadoc; MUST clauses; training loop over the hits in score order)lucene/classification/src/java/org/apache/lucene/classification/BM25NBClassifier.java:216, (at a9779ef3c193) 227 (training query also added as MUST; not part of the confirmed claim, see notes)lucene/core/src/java/org/apache/lucene/search/BooleanClause.java:27, (at a9779ef3c193) 35 (MUST; FILTER 'Like MUST except that these clauses do not participate in scoring')
- The finding in 30 seconds
lucene/classification/src/java/org/apache/lucene/classification/KNearestNeighborClassifier.java:50, 69-72, 82-83, 156-179 (171, 174-178), 190-235 (195, 207, 219-225, 229)lucene/classification/src/java/org/apache/lucene/classification/KNearestFuzzyClassifier.java:48, 65, 79, 135-147, 157-172lucene/classification/src/java/org/apache/lucene/classification/document/KNearestNeighborDocumentClassifier.java:44-46, 58, 101, 110, 123-153lucene/classification/src/java/org/apache/lucene/classification/BooleanPerceptronClassifier.java:57, 72, 130-140lucene/core/src/java/org/apache/lucene/search/BooleanClause.java:27-36
- Who is affected
lucene/classification/src/java/org/apache/lucene/classification/KNearestNeighborClassifier.java:50; KNearestFuzzyClassifier.java:48; document/KNearestNeighborDocumentClassifier.java:44; BooleanPerceptronClassifier.java:57; BM25NBClassifier.java:216, 227
- Why it looks unintended
lucene/classification/src/java/org/apache/lucene/classification/KNearestNeighborClassifier.java:69-72, 82-83; KNearestFuzzyClassifier.java:65, 79; document/KNearestNeighborDocumentClassifier.java:58; BooleanPerceptronClassifier.java:72lucene/core/src/java/org/apache/lucene/search/BooleanClause.java:35lucene/classification/src/test/org/apache/lucene/classification/TestKNearestNeighborClassifier.java:145-159a Lucene clone (git log --all -S 'Occur.FILTER' -- lucene/classification: empty)
- Suggested fix
lucene/classification/src/java/org/apache/lucene/classification/BM25NBClassifier.java:207, 216, 225-227
- TestKnnTrainingQueryIsScored.java (JUnit test):
repro/LFV-684/src/org/apache/lucene/classification/TestKnnTrainingQueryIsScored.java(63 lines)
A light summary card, made in parallel with this doc from an executed probe trace on main a9779ef3c193 (assertions on and off, and with the fix as a control); the PNG is the summary card. Its fix line names the hunt's fix sketch (Occur.FILTER plus a maxScore > 0 guard, fix A); the doc recommends the narrower fix B.
assets/LFV-684/bug.png(390 KB)