A surround field prefix such as title: is a node around its operand. The parser puts ^N on the operand, and the prefix node builds that operand with the method that skips the operand's own boost, so no BoostQuery is created. The boolean composites (OR, AND, NOT) build their children with the method that applies it.
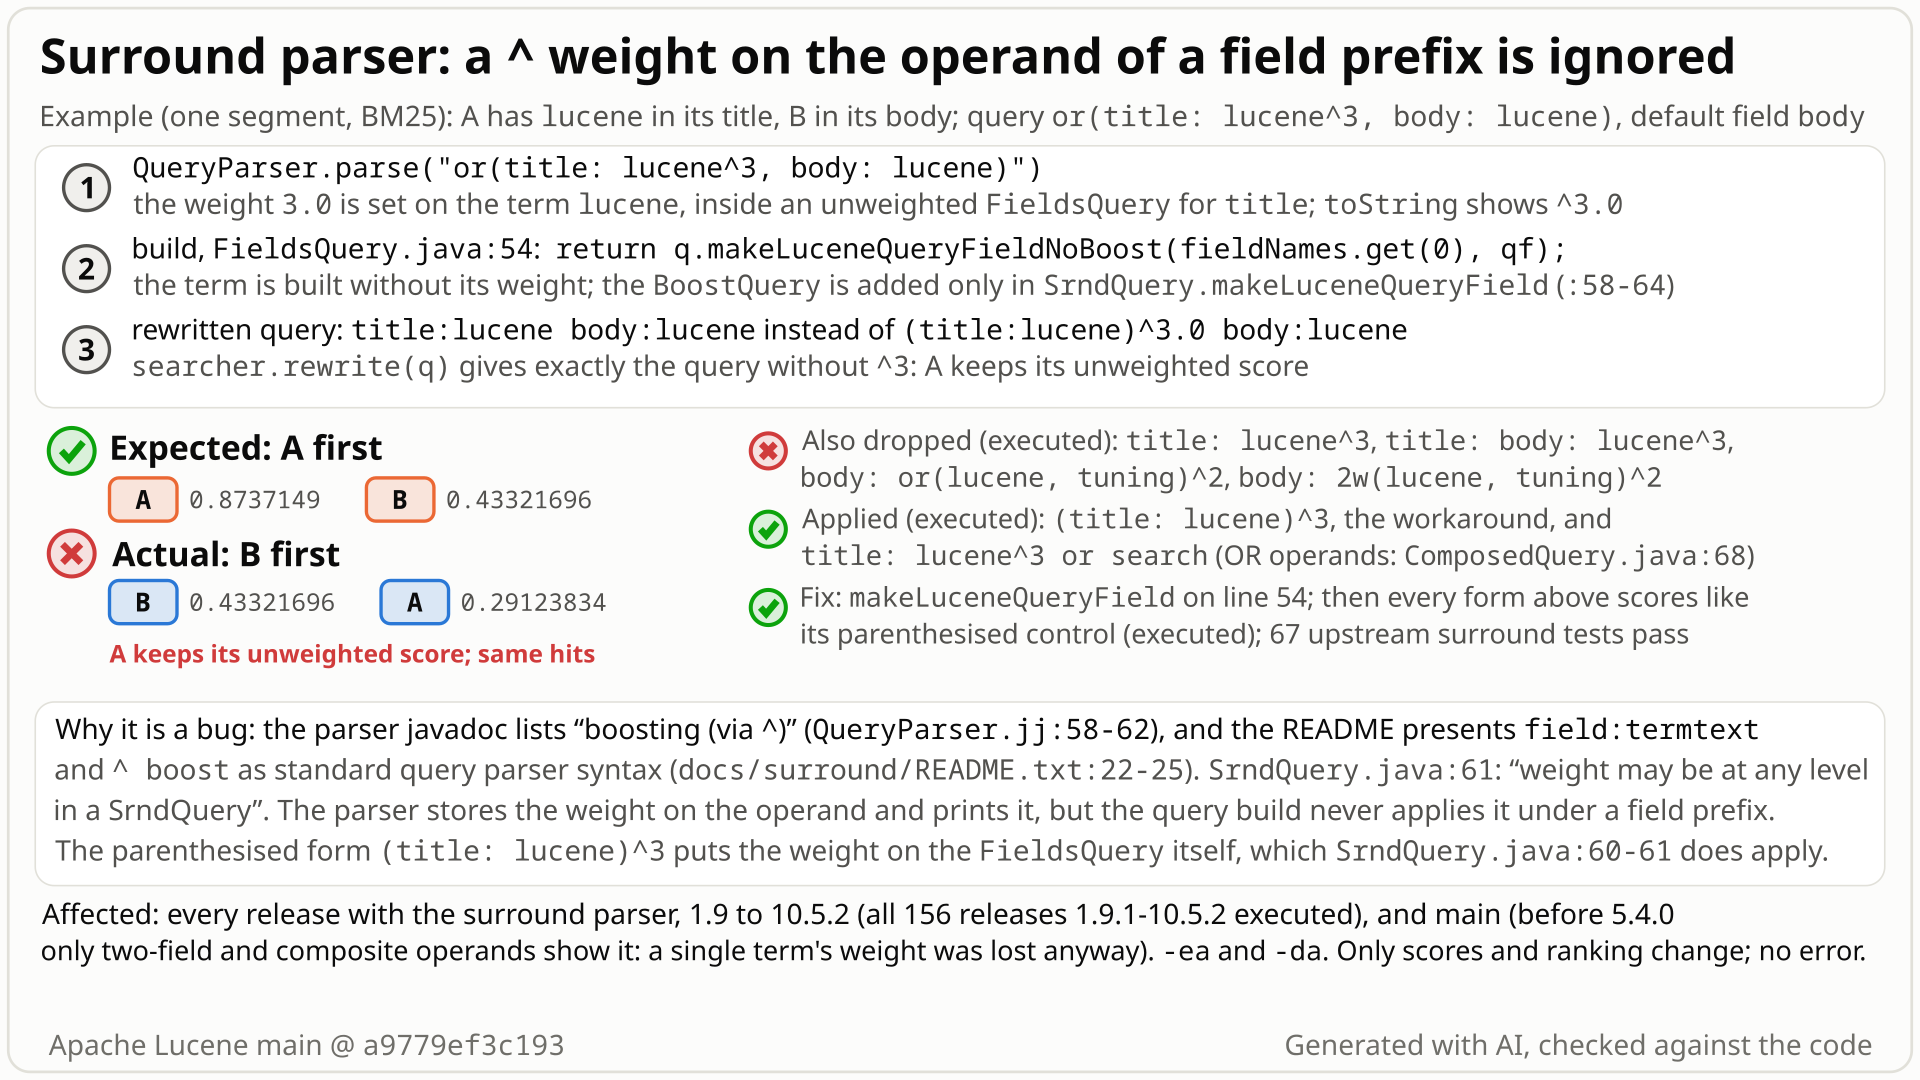
lucene in its title, B in its body, and or(title: lucene^3, body: lucene) should put A first. The parser puts ^3 on the term, FieldsQuery builds the term without it, and the query rewrites to title:lucene body:lucene, so B ranks first. Select the still to open it at full size. Generated with AI, checked against the code.- You index two documents with the default analyzer and similarity: A has
lucenein its title (lucene in action), B in its body (lucene tuning and lucene scoring). You search with the surround queryor(title: lucene^3, body: lucene): a title match should count three times. - You expect A first, as when the same weight is put on the parenthesised field query,
or((title: lucene)^3, body: lucene): A scores 0.874, B 0.433. - Instead A scores 0.291, its unweighted score, and B ranks first. The parser keeps the weight on the term (the query prints as
or((title:lucene^3.0), (body:lucene))), but the field-prefix node builds that term withmakeLuceneQueryFieldNoBoost, which skips its boost: the query rewrites to justtitle:lucene body:lucene. - Every weight written directly on a field prefix's operand that was tried is lost the same way:
title: body: lucene^3,body: or(lucene, search)^2,body: 2w(lucene, search)^2andtitle: (a or b)^3all score like their unweighted forms. - No error, and the same documents match.
(title: lucene)^3andtitle: lucene^3 or searchwork. Every release since 1.9 (2006) behaves this way.
Applications that pass query text to the opt-in surround parser (Solr's {!surround}) and weight a field-prefixed clause in the standard-parser style, field: term^N. Default settings and two documents show it. On its own a weighted clause only shifts absolute scores; combined with other clauses it changes the ranking. The same documents match. Workaround: (title: lucene)^3.
Mechanism, terms and numbers909 words
In the surround query language you weight a clause with ^N and restrict it to a field with a prefix such as title:. When the weight is written on the operand of the field prefix, as in title: lucene^3, the parser stores it on the operand and prints it ((title:lucene^3.0)), but FieldsQuery, the node for the prefix, builds its operand with makeLuceneQueryFieldNoBoost, so no BoostQuery is ever created and the clause scores as if unweighted. Every operand shape that was run loses it: a term, a term under two prefixes, a prefix OR, a distance query and a parenthesised query; other operands reach the same line (from the code, not run). Only scores and ranking change: the same documents match, and the reproduced queries run without an error. Inside a larger query the ranking flips: with A matching in its title and B in its body, or(title: lucene^3, body: lucene) scores A 0.291 (unweighted) below B 0.433, while or((title: lucene)^3, body: lucene) ranks A first (0.874). The boolean composites (OR, AND, NOT) keep their children's weights, so title: lucene^3 or search works while title: lucene^3 does not. The call dates from the parser's first commit (2005), so every release since 1.9 is affected. A one-line fix (makeLuceneQueryField instead of makeLuceneQueryFieldNoBoost) makes the repro pass and keeps the whole lucene/queryparser suite green.
- Surround query parser: an opt-in parser in
lucene/queryparserfor span-based queries:WandNproximity,AND,OR,NOT, truncation, field prefixes and^weights, in infix (a or b) and prefix (or(a, b)) form. You callQueryParser.parse(text), thenmakeLuceneQueryField(defaultField, new BasicQueryFactory()). - Field prefix:
title: qlimitsqto the fieldtitle;title: body: qmeansqin either field (an OR over the fields). Internally aFieldsQuerynode wraps the operandq. - Weight:
^Nmultiplies a clause's score by N. In Lucene a weight becomes aBoostQueryaround the clause.
- Where the weight goes. The grammar parses a field query as optional field names followed by an OR query (
QueryParser.jj:251-258), and attaches^Nto a primary query: a term, a prefix-operator query or a parenthesised query (:376-385,OptionalWeights:456-469). Intitle: lucene^3the weight sits on the termlucene; in(title: lucene)^3it sits on theFieldsQuery. - How weights are applied.
SrndQuery.makeLuceneQueryFieldbuilds a node withmakeLuceneQueryFieldNoBoostand wraps it in aBoostQuerywhen the node is weighted ("weight may be at any level in a SrndQuery",SrndQuery.java:58-63). OR, AND and NOT build each child withmakeLuceneQueryField(ComposedQuery.java:64-71; "subqueries can be individually boosted",OrQuery.java:34,AndQuery.java:32). The proximity composites (W,N) differ:DistanceQueryalso extendsComposedQuerybut builds aDistanceRewriteQuery(DistanceQuery.java:29, 100-101) whose span clauses ignore the children's weights (SpanNearClauseFactory.java:123-134), so2w(lucene^3, tuning)scores like2w(lucene, tuning): the separate, known span case (LUCENE-8143). A weight around a whole distance query,(body: 2w(lucene, search))^2, is applied. - The exception.
FieldsQuery.makeLuceneQueryNoBoostbuilds its operand withq.makeLuceneQueryFieldNoBoost(fieldNames.get(0), qf)(FieldsQuery.java:51-54), which skips the operand'sBoostQuery. It is the only place in the surround package that builds a child with the NoBoost variant. - Two or more fields. The multi-field branch (
:55-67) clones the weighted operand into one unweightedFieldsQueryper field inside an OR; each copy reaches line 54, so the weight is dropped there too. - Nothing shows it. The parsed query prints the weight (
(title:lucene^3.0)), and so does the Lucene query, whosetoStringembeds the surround term (SimpleTermRewriteQuery(title, lucene^3.0, ...)); but noBoostQueryis in the tree.
Two documents, the default IndexWriterConfig (StandardAnalyzer) and similarity (BM25), default field body: A has title lucene in action, B has body lucene tuning and lucene scoring.
| query | A | B | order |
|---|---|---|---|
or(title: lucene, body: lucene) | 0.29123834 | 0.43321696 | B, A |
or((title: lucene)^3, body: lucene) (control) | 0.8737149 | 0.43321696 | A, B |
or(title: lucene^3, body: lucene) | 0.29123834 | 0.43321696 | B, A |
With searcher.rewrite(q), the bug form becomes title:lucene body:lucene, the same query as without the weight; the control becomes (title:lucene)^3.0 body:lucene. The same numbers with assertions off, on 10.5.2, and, with the fix, the bug form scores like the control.
The repro test uses four documents, StandardAnalyzer, BM25, default field title. Doc 0: lucene in a ten-word title; doc 1: body lucene; doc 2: lucene search in both fields; doc 3: filler. The test does not print the control scores; a main() print of the same index does (the first row's expected column), and it gives the bug form exactly the test's numbers.
| query | expected (the control) | actual |
|---|---|---|
or(title: lucene^5, body: lucene) | doc 0 1.0140707 above doc 1 0.40773362 (or((title: lucene)^5, body: lucene)) | doc 0 0.20281413 below doc 1 0.40773362 |
title: lucene^3, doc 0 | 0.6084424 (lucene^3) | 0.20281413 (unweighted) |
title: body: lucene^3, doc 0 | 0.6084424 ((title: body: lucene)^3) | 0.20281413 |
body: or(lucene, search)^2, doc 1 | 0.81546724 ((body: or(lucene, search))^2) | 0.40773362 |
body: 2w(lucene, search)^2, doc 2 | 1.5176961 ((body: 2w(lucene, search))^2) | 0.7588481 |
lucene^3, (title: lucene)^3, title: lucene^3 or search | weight applied | applied |
In the hunt's two-document index, or(title: lucene^3, body: lucene) gives the title document 0.13076457 instead of 0.39229375, a tie with the body document instead of first place.
Exposure and likelihood287 words
- Who. Applications that pass query text to the surround
QueryParser(lucene/queryparser; opt-in and niche; Solr exposes it as{!surround}) and weight a field-prefixed clause in the standard-parser style the README points to (it listsfield:termtextand^ boostas separate items and has no weighted example):field: term^N,field: (...)^N,field: or(...)^N,field: 2w(...)^N, with one field or several. A 2017 solr-user post used exactly that shape,field1:(W(X, A) OR ...)^10, in a boost query, and nobody in the thread noticed the weight. - Effect. Silent: the weighted clause scores as if unweighted. At top level only absolute scores change (every hit is off by the same factor); inside a disjunction or conjunction with other clauses the ranking changes (the flip above). The set of matching documents and the total hit count never change, because weights must be greater than 0; a changed order can change which documents make a top-N cut. The reproduced queries run without an error.
- Default vs opt-in. The diagram's probe uses the default
IndexWriterConfig(StandardAnalyzer), codec, searcher and similarity (BM25). The JUnit repro setsStandardAnalyzerand BM25 explicitly and runs under the test framework's randomized codec (CheapBastardin the cited runs); a default-codec print of its index gives the same scores. Assertions on and off. The surround parser itself is opt-in. - Scale. None needed: an index of two documents shows it, deterministically, every time the syntax is used.
- How likely.
field: term^Nis the natural way to weight a field clause and fails every time; but the parser is niche, only scores change, and nobody reported it in 21 years. - Workaround. Put the weight on the parenthesised field query:
(title: lucene)^3.
The test shows that the surround parser drops a ^ weight written on the operand of a field prefix: or(title: lucene^3, body: lucene) scores as if unweighted.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.queryparser.surround.query;

import org.apache.lucene.analysis.standard.StandardAnalyzer;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.queryparser.surround.parser.QueryParser;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.Query;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestSrndFieldPrefixOperandWeight extends LuceneTestCase {

  public void testWeightOnFieldPrefixOperand() throws Exception {
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig(new StandardAnalyzer()))) {
        Document doc = new Document();
        doc.add(new TextField("title", "lucene", Field.Store.NO));
        w.addDocument(doc);
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        IndexSearcher searcher = new IndexSearcher(reader);
        String weighted = "or(title: lucene^3, body: lucene)";
        // expected: same score as or((title: lucene)^3, body: lucene); actual: the ^3 is dropped
        assertEquals(
            weighted,
            score(searcher, "or((title: lucene)^3, body: lucene)"),
            score(searcher, weighted),
            0f);
      }
    }
  }

  private static float score(IndexSearcher searcher, String surround) throws Exception {
    Query q = QueryParser.parse(surround).makeLuceneQueryField("body", new BasicQueryFactory());
    return searcher.search(q, 1).scoreDocs[0].score;
  }
}
# in a copy of this finding's repro folder (repro/LFV-686/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/facet/build/libs/lucene-facet-$V.jar
CP=$CP:$LUCENE/lucene/queries/build/libs/lucene-queries-$V.jar
CP=$CP:$LUCENE/lucene/queryparser/build/libs/lucene-queryparser-$V.jar
CP=$CP:$LUCENE/lucene/sandbox/build/libs/lucene-sandbox-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.queryparser.surround.query.TestSrndFieldPrefixOperandWeight
# the module(s) facet also need their third-party runtime jars
- Expected vs actual
- Expected: the score of
or((title: lucene)^3, body: lucene), 0.39229375. Actual: 0.13076457 (one third of it: the ^3 is not applied), with -ea and -da.
More files, environment, full output37 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: or(title: lucene^3, body: lucene) expected:<0.39229375> but was:<0.13076457>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:577)
org.apache.lucene.queryparser.surround.query.TestSrndFieldPrefixOperandWeight.testWeightOnFieldPrefixOperand(TestSrndFieldPrefixOperandWeight.java:46)- The parser documents "boosting (via ^)", and its README presents
field:termtextand^ boostas standard-parser syntax. - The boolean composites (OR, AND, NOT) keep their children's weights:
title: lucene^3 or searchworks,title: lucene^3does not. - No document or test says the weight is ignored; the parser stores and prints it.
The full argument298 words
- The documented syntax. The parser javadoc lists "boosting (via
^)" (QueryParser.jj:58-62). The README introduces "Query terms from the Lucene standard query parser: field:termtext, ^ boost" (docs/surround/README.txt:22-25) with field-prefix examples such astitle: text: aa(:44-47). In the classic parser,field:term^Nwraps that clause in aBoostQuery(classicQueryParser.jj:372,QueryParserBase.java:813-829). - The code's own intent. "weight may be at any level in a SrndQuery" (
SrndQuery.java:61); "subqueries can be individually boosted" (OrQuery.java:34,AndQuery.java:32). The parser stores the weight andtoStringprints it; under a field prefix, no query-building or scoring code applies it (onlytoStringreads it). - The author's description. In LUCENE-6590 (#7648, 2015) the parser's author wrote that for OR queries "the given boosts are passed to the generated boolean query clauses and they are used there as expected", and that "there are no tests for expected score values of surround queries". The weights they named as ignored were those inside proximity (span) operands, a different case (LUCENE-8143); here the weight is on the whole operand, and
(body: 2w(a, b))^2works whilebody: 2w(a, b)^2does not. - Inconsistency no design would choose.
title: lucene^3 or searchapplies the weight (the term is a child of the OR),title: lucene^3andtitle: (lucene or zzz)^3drop it, and adding a prefix equal to the default field cuts the score oflucene^3from 0.6084424 to 0.20281413. - No test pins it. The upstream surround tests contain no
^at all. - What is inferred. No document says that
f: q^Nequals(f: q)^N: the README listsfield:termtextand^ boostseparately and has no weighted field example. The expectation rests on the standard-parser syntax the README points to, the parser's own comments and the behaviour of the boolean composites.
The devil's-advocate check312 words
The strongest case for "intended" (an independent reviewer from another model family rated it moderate): the grammar attaches the weight to the operand before FieldsQuery wraps it, so title: a^4 and (title: a)^4 are different trees; FieldsQuery calls the NoBoost variant explicitly, and has since the 2005 contribution; the parser's author kept that call in an unmerged 2016-17 rework (LUCENE-7613, #8664, Won't Fix in 2018), also for its per-field DisjunctionMaxQuery clauses, in a patch whose description does discuss boosts ("This uses SpanBoostQuery when proximity (sub)queries are boosted. There is no effect on the scores yet"); FieldsQuery is commented "mostly untested" and the README says "Not tested: multiple fields"; nothing documents f: q^N as equal to (f: q)^N; and a fix changes the scores of queries that have run this way for 20 years. Separately, open #16820 proposes deprecating rarely maintained parsers for Lucene 11: a won't-fix risk, not an intent argument.
Why it fails: no document or test says the weight is ignored, and no query-building code applies it after the parser stores and prints it. The "untested" comments explain why nobody noticed, not a decision. The LUCENE-7613 patch discusses boosts only for proximity subqueries, never the weight on a field prefix's operand; its surround tests have no ^ and no score assertion, and it says it "does not affect the syntax". That it simply carried the old call forward is an inference, not something the patch says. The README lists field:termtext and ^ boost among its terms from the standard parser, where a field-qualified boost works, and the boolean composites (OR, AND, NOT) keep their children's weights. The span limitation the author did name is a different, discussed case. The score change is the fix and belongs in a CHANGES entry. Verdict: not intended, a defect (the independent reproducer, the cross-model reviewer, the devil's advocate and the adjudication all agree).
Recommended Apply the operand's weight in FieldsQuery (validated)
In FieldsQuery.makeLuceneQueryNoBoost, build the operand with q.makeLuceneQueryField(...) instead of q.makeLuceneQueryFieldNoBoost(...): one line, and it also covers multi-field prefixes. With it the repro passes (6 of 6 with assertions on and off, 60 of 60 over 10 iterations), and the whole lucene/queryparser suite (539 tests) and its lint, format and javadoc checks pass.
     if (fieldNames.size() == 1) {
       /* single field name: no new queries needed */
-      return q.makeLuceneQueryFieldNoBoost(fieldNames.get(0), qf);
+      return q.makeLuceneQueryField(fieldNames.get(0), qf);
     } else {
All options and trade-offs5 options · 679 words
One fix was applied in a scratch checkout at a9779ef3c193 and run through gradle; the alternatives were not run. The score change is the point of the fix, so a PR wants a CHANGES entry.
Workaround today: write the weight on the parenthesised field query, (title: lucene)^3.
Related, separate (not part of this bug, not verified by the adjudication): FieldsQuery.toString never appends the FieldsQuery's own weight (FieldsQuery.java:84-92), so the surround objects for or((title: a)^3, z) and or((title: a), z) print and compare equal (SrndQuery.equals compares toString). Lucene Query equality is not affected. Executed by the devil's advocate's probe; a weightToString(r) call would fix it (not run).
Call q.makeLuceneQueryField(fieldNames.get(0), qf) in the single-field branch of FieldsQuery.makeLuceneQueryNoBoost (FieldsQuery.java:54). The multi-field branch builds per-field FieldsQuery copies that reach the same line, so it is fixed too. Weights compose by multiplication: in (title: lucene^3)^2 the operand weight and the outer FieldsQuery weight give BoostQuery(BoostQuery(q, 3), 2), as OptionalWeights already multiplies lucene^3^2 (QueryParser.jj:469); no weight is applied twice (executed: with the fix (title: lucene^3)^2 scores 6.0x title: lucene, stock 2.0x). In the multi-field form each per-field clause is boosted instead of their OR: the same score (identical floats in the repro).
     if (fieldNames.size() == 1) {
       /* single field name: no new queries needed */
-      return q.makeLuceneQueryFieldNoBoost(fieldNames.get(0), qf);
+      return q.makeLuceneQueryField(fieldNames.get(0), qf);
     } else {
Trade-offs
Behaviour change by design: queries that use this syntax score differently after the fix, so it wants a CHANGES entry. Small structural overhead, not benchmarked: one extra BoostQuery per weighted operand and field (a two-field prefix gets one per field). The hunt's sketch is the same change with a trailing comment. By shadowing it passed the finder's test (2 of 2), the cross-model reviewer's refute-lens class (4 of 4) and the two failing methods of its intended-lens class (the only ones that run selected), the devil's advocate's probe except its separate toString test (8 of 9), and the 67 upstream surround tests; the independent reproducer and the adjudication ran the reproducer's test with its own, identical one-line change (6 of 6).
What the checks validated
Executed in a scratch checkout at a9779ef3c193 through gradle (removed afterwards). Stock: the repro fails 5 of 6 with assertions on and off and 50 of 50 executions over 10 iterations (seed C0FFEE68), while the 67 upstream surround tests pass. With the fix: the repro passes 6 of 6 with assertions on and off and 60 of 60 over 10 iterations; the whole lucene/queryparser module passes (31 classes, 539 tests, 0 failures; 1 test is @Ignored in the source); ecjLintMain, ecjLintTest, checkGoogleJavaFormat and renderJavadoc pass; tidy changes nothing (re-checked with file hashes and git status before and after); both diffs apply cleanly. Not tested: Solr's surround plugin, benchmarks (no other Lucene module uses the surround package).
In getFieldsQuery, transfer the operand's weight to the new FieldsQuery.
Trade-offs
Needs a way to clear a weight (SrndQuery has none) and a JavaCC regeneration; FieldsQuery.toString never prints its own weight, so the printed query would lose the ^3.0.
Throw a ParseException and point users to (field: q)^N.
Trade-offs
Loud instead of silent, but breaks queries that parse today.
Keep makeLuceneQueryFieldNoBoost for the operand, and wrap the finished single- or multi-field query in one BoostQuery with q.getWeight().
Trade-offs
It should give the same scores, but there is one wrapper around the per-field OR instead of one per field, so the query tree, the rewrite output, equals and query-cache keys differ from the recommended fix.
A javadoc and README note: write (field: q)^N; a weight directly after a field prefix is ignored.
Trade-offs
No score change, but the silent drop and the misleading toString stay.
Downstream, Solr exposes this parser as {!surround}, and a 2017 solr-user post used the affected shape field1:(...)^10 in a boost query without anyone noticing that the weight is lost.
Bounded-exhaustive checking: an independent reference semantics of the surround language was compared with the real parser on 33,320 generated queries over 507 two-field documents. A weight relation (in or(S^3, Y) a document matching only S scores 3x) failed 3,336 times, always with the weight on a field prefix's operand; hits never differed; with the fix, 0 failures.
The method in full149 words
Method: bounded-exhaustive differential and metamorphic translation validation on the real jar (semi-formal tier), in a hunt unit on surround query semantics.
- An independent reference semantics of the surround language (W, N, AND, OR, NOT, field prefixes, truncations) evaluated 33,320 generated queries on 507 two-field documents: 88,620 checks.
- Hit sets (relation C1): 0 failures. Weight relation C6, "for
or(S^3, Y), a document that matches S and not Y must score 3x its score underor(S, Y)": 3,336 failures, every one a weight on the operand of a field prefix (operand a term 104, a W query 1,568, an N query 1,664). With the one-line fix shadowed in: 0 failures. - Then reduced to a public-API JUnit test on the stock main jar (found 2026-10-27). Checked by an independent reproducer, two executed reviews by an independent reviewer from another model family (OpenAI GPT-5.6), an intended-behaviour devil's advocate and an adjudication.
No prior report found (2026-10-27: two prior-report tool runs with 148 queries, 23 manual GitHub searches, all 409 open PRs, JIRA, the Lucene and Solr lists, the web). Nearest: LUCENE-6590 (#7648), where the parser's author describes OR boosts as working, and an unmerged rework (#8664, Won't Fix 2018) that keeps the same call.
Searches5 searches
Verdict new: no issue, PR, JIRA ticket, list thread, Q&A post or downstream report says that a weight on the operand of a surround field prefix is dropped. Nearest items, not this bug: #7648 (LUCENE-6590, the boost refactoring), #8664 (LUCENE-7613, keeps the call; it discusses boosts only for proximity subqueries, never a field prefix's operand weight; a reviewer may read it as evidence of intent), #9191 / PR #155 (LUCENE-8143, weights inside span operands, intended), the 2017 solr-user "match in order" thread (the trigger shape, unnoticed), open #10322 and #10051 (other surround defects), open PR #13008 (does not touch FieldsQuery.java), open #16820 (proposed deprecation of rarely maintained parsers). The Lucene.NET port has the same code and no report. Keyword search cannot prove absence.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; downstream repositories incl. Solr; dev@, java-user@, issues@, commits@; the JIRA archive; the web (run 2; run 1's 6 web queries were left pending) | 2026-10-27 | the hunt's prior-report tool, two runs: 51 and 97 queries (225 and 573 distinct hits) | no high-overlap hit; #7648 and an unrelated JIRA ticket at medium |
| GitHub (apache/lucene, lucene-solr, solr, lucenenet, GitHub-wide) | 2026-10-27 | 23 manual issue and PR searches (surround with boost, weight, field, score; FieldsQuery; SrndQuery; makeLuceneQueryField) | no report |
| Open apache/lucene PRs | 2026-10-27 | changed files of all 409 open PRs | only #13008 touches surround/, not FieldsQuery.java or SrndQuery.java |
| Related threads; JIRA | 2026-10-27 | 15 full threads read (#7648, #8664 with its patch, #9191, PR #155, #10322, #10051, #16820, ...); 6 JQL queries, 7 tickets read | context only |
| Solr and Lucene mailing lists; web; Stack Overflow | 2026-10-27 | 15 list queries, 12 messages read; 6 web queries; Stack Overflow API | the 2017 solr-user thread with the trigger shape, unnoticed; no report |
In the parser's first commit (2005, LUCENE-368), so every release from 1.9 (2006) to 10.5.2 and main; all 156 Maven releases from 1.9.1 were executed. Before 5.4.0 a single-term operand could not show it, because single-term weights were lost anyway (a separate defect, fixed in 5.4.0). Not fixed upstream.
Versions tested6 rows
Introduced by the parser's first commit, 9d70229506f (2005-07-05, "#34331 - Add Paul Elschot's Surround query language parser"; LUCENE-368 = #1446, svn era, no PR). First release 1.9 (its tag points to a commit of 2006-02-27; no Maven artifacts, its contrib/surround tree is identical to 1.9.1's). The single-field branch (lines 52-54) was later edited only to remove a cast (5b83cc59b2e, LUCENE-1257, 2009) and to reformat it (2cbf261032d, LUCENE-9570, 2021); the whole method has 8 later commits, all cosmetic (collection types, casts, a removed System.out, the diamond operator, static fields, formatting). Not a regression.
Why single terms start at 5.4.0. Before 5.4.0 a weight on a single surround term was lost anyway: the term's rewrite wrapper dropped its own boost. LUCENE-6590 / LUCENE-6783 (fb2a8aaac40 on branch_5x, 5.4.0; trunk 962313b83ba, 6.0.0) made makeLuceneQueryField wrap weights in BoostQuery. Runs on 5.3.1 with each fix alone show the two defects are independent.
A reflection-based probe ran unchanged on every release jar, comparing the bug form B with the parenthesised control C, and counting a group only where C differs from the unweighted U. Unfixed: upstream main a95c754ee003 still has the call.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the doc's test 5 of 6 fail via gradle, assertions on and off; the hunt's test 2 of 2 |
| 5.4.0 to 10.5.2 (100 releases) | affected | every group: B scores exactly like U (10.5.2: U 0.13076457, C 0.39229375, B 0.13076457) |
| 1.9.1 to 5.3.2 (56 releases) | composite and two-field operands | two-field and composite operands affected (1.9.1: U 0.25259075, C 0.30110815, B 0.25259075); a single-term weight was lost anyway (separate defect) |
| 1.9 | read | same source tree as 1.9.1; no Maven artifacts |
| 1.4.3 and older | not affected | no surround parser |
fix on a9779ef3c193 | not affected | the doc's 6 tests pass (assertions on and off, 10 iterations); the whole queryparser suite passes |
An independent reproducer and an intended-behaviour devil's advocate reproduced it with their own tests; an independent reviewer from another model family (OpenAI GPT-5.6) reproduced it in two executed reviews. An adjudication confirmed it with a new seed, and this doc's gradle runs reproduce it on a9779ef3c193 and validate the fix.
Checks and verdicts328 words
Every executing check wrote or re-ran its own test on stock main; every control passed.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Exhaustive check (C6: 3,336 failures, 0 with the fix); JUnit 2 of 2 fail with assertions on and off and on 10.5.2 and 9.12.3; the fix sketch passes with the 67 upstream surround tests. |
| independent reproducer | real | Own test from the claim only (the doc's repro): 5 of 6 fail on main (assertions on and off), 10.5.2 and 9.12.3; the control passes; found the ranking flip and the OR and distance operands; 6 of 6 pass with its own one-line fix. |
| cross-model reviews (refute, intended) | real, high (the lenses) | An independent reviewer from another model family (OpenAI GPT-5.6), executed: its own tests fail 3 of 4 and 2 of 7 on main, also on 10.5.2 and 9.12.3, while its boost controls pass; root cause agrees, the fix fixes it; intended-behaviour argument rated moderate. |
| intended-behaviour devil's advocate | real, high | No intended, documented, misuse or unreachability argument survives; probe 5 of 9 fail on main and 10.5.2 (one is the separate toString observation); showed the inconsistency (title: lucene^3 or zzz works, a redundant default-field prefix changes the score). |
| adjudication | confirmed, high | Re-ran the reproducer's test with a new seed (5 of 6 fail, assertions on and off; 6 of 6 with the fix). |
| Registration check and audit | keep | Re-runs on a clean a9779ef3c193 checkout with new seeds: 2 of 2 fail, the fix passes; a score print shows the tie in the two-document index. |
| this doc's gradle runs | reproduced; fix validated | Stock main through gradle: the repro fails 5 of 6 (assertions on and off), 50 of 50 executions over 10 iterations; the upstream surround suites pass. With the one-line fix: 6 of 6 and 60 of 60 pass, the whole queryparser module passes (539 tests) and the lint, format and javadoc checks pass. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 568 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,326 words
- Registry title
- Surround query parser ignores a ^ weight written directly on the operand of a field prefix (title: lucene^3, title: body: lucene^3, body: or(a, b)^2), because FieldsQuery builds its operand with makeLuceneQueryFieldNoBoost
- Area
- queryparser / surround (FieldsQuery field prefixes and ^ weights)
- Priority
- Low, rank 376: Ranking-only in the niche surround parser, and the parenthesised form works.
- Impact class
- silent wrong results
- Impact note
- Hits applications that pass query text to the opt-in, niche surround QueryParser (lucene/queryparser) and write a ^ weight directly on the operand of a field prefix (title: lucene^3, title: body: lucene^3, body: or(a, b)^2, body: 2w(a, b)^2): the weight is parsed and shown by toString but never applied, with the default codec, searcher and similarity, with -ea and -da, at any scale and in every release since 1.9, so the weighted clause scores as if unweighted and, inside a larger query such as a disjunction, the ranking can flip; the matching documents never change (weights must be > 0), the reproduced queries throw nothing, and the parenthesised form (title: lucene)^3 is a working alternative.
- Summary
- You parse the surround query or(title: lucene^3, body: lucene), whose parser documents 'boosting (via ^)', and expect the title match to count three times, exactly like the same weight on the parenthesised field query or((title: lucene)^3, body: lucene). Instead the weight is kept on the parsed term (toString shows title:lucene^3.0), but FieldsQuery.makeLuceneQueryNoBoost builds its operand with makeLuceneQueryFieldNoBoost, so no BoostQuery is created: the title document scores 0.13076457 instead of 0.39229375, no more than the body-only match, which the weight was meant to outrank (in the independent reproduction's index, or(title: lucene^5, body: lucene) ranks the title match below a body match). Every weight on the direct operand of a field prefix is dropped (a term, an OR, a distance query, with one field or several); only scores and ranking change, never which documents match.
- Introduced
- 9d70229506f88d3259ba0d24a824c0dbadc52c8e (trunk, '#34331 - Add Paul Elschot's Surround query language parser', svn r209183, the surround parser's first commit; contribution LUCENE-368 = #1446, no pull request): its FieldsQuery.makeLuceneQueryNoBoost already returns q.makeLuceneQueryFieldNoBoost(fieldNames.get(0), qf) for one field name, and the multi-field branch reaches that line through per-field FieldsQuery copies [read: git log -L; the single-field branch (lines 52-54) was later edited only by 5b83cc59b2e (LUCENE-1257 generics, cast removed, 2009) and 2cbf261032d (LUCENE-9570 reformatting, 2021); the whole method has 8 later commits (d5a40278bc3, 5b83cc59b2e, efb74380fda, 49f43806a89, 124edc221c6, 3b67b174932, e80643e5a77, 2cbf261032d), all cosmetic, none changes behaviour]; not a regression: the bug is as old as the parser (2005-07-05 (trunk 9d70229506f); first release 1.9 (2006-02-27))
- First affected version
- 1.9 [read: no Maven artifacts, its contrib/surround tree is identical to 1.9.1's]; 1.9.1 [exec] is the first executed release; 1.4.3 and earlier have no surround parser [read]
- Affected versions
- every release that has the surround parser, 1.9 to 10.5.2, and main a9779ef3c193 (unreleased 11.0) [exec: all 156 Maven Central releases from 1.9.1 to 10.5.2 fail the follow-up's release-portable history probe with -ea, and with -da on 1.9.1, 5.3.2, 5.4.0, 9.12.3, 10.5.2 and main; the candidate JUnit fails 2 of 2 on main (-ea and -da), 10.5.2 and 9.12.3]; 1.9 [read]. From 5.4.0 on every weight on the direct operand of a field prefix is dropped. In 1.9.1-5.3.2 the defect shows for composite operands and two-field prefixes, while a single-term operand cannot show it, because a weight on a single surround term was lost anyway in those releases (a separate defect, fixed in 5.4.0 by LUCENE-6590 / LUCENE-6783) [exec: attribution runs on 5.3.1]. Not fixed upstream: upstream main a95c754ee003 still calls makeLuceneQueryFieldNoBoost (2026-10-27) [read]. Executed on Linux aarch64 with JDK 25 only.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-27, read-only; the prior-report record verdict new): two scripted prior-report searches (51 and 97 queries over apache/lucene issues, PRs and commits, downstream repositories including Solr, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and, in run 2, the web; 225 and 573 distinct hits, none high overlap), 23 manual apache/lucene issue and PR searches plus searches in lucene-solr, solr, lucenenet, two downstream search engines and GitHub-wide, the changed files of all 409 open apache/lucene PRs (only #13008 touches surround/, and not FieldsQuery.java or SrndQuery.java), the full threads of 15 related issues, LUCENE and SOLR JIRA queries with 7 tickets read, the Solr and Lucene user and dev lists (12 messages read), web search and Stack Overflow. Nearest items, none the same bug: #7648 (LUCENE-6590, the boost refactoring; the parser's author wrote that OR sub-query boosts 'are used there as expected' and that 'there are no tests for expected score values of surround queries'; field prefixes are not discussed), #8664 (LUCENE-7613, an unmerged Won't Fix update patch by the same author that keeps the same NoBoost call; it discusses boosts only for proximity subqueries ('This uses SpanBoostQuery when proximity (sub)queries are boosted'), never a field prefix's operand weight), #9191 and PR #155 (LUCENE-8143, weights inside span operands, intended and different code), a 2017 solr-user thread ('match in order') that used the trigger shape field1:(...)^10 without anyone noticing the weight, open #10322 and #10051 (different surround defects), open PR #13008 (TermStates, does not fix this), open #16820 (proposes deprecating rarely maintained parsers for Lucene 11). Not fixed upstream: upstream main a95c754ee003 still has the call; the Lucene.NET port has the same code and no report. Gap: token-based searches can miss a report that names none of the searched terms.
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26): the doc's public-API test through gradle in a scratch checkout, stock and with the one-line fix, assertions on and off and 10 iterations, plus the surround suites stock and the wholelucene/queryparsermodule, lint, format and javadoc checks with the fix (2026-10-27/28). Hunt runs on maina9779ef3c193(andea57360912ed, identical surround sources) and on the 10.5.2 and 9.12.3 jars; a history probe on every Maven Central release from 1.9.1 to 10.5.2.
- Finding record
lucene/queryparser/src/java/org/apache/lucene/queryparser/surround/query/FieldsQuery.java:26 (at a9779ef3c193) ('/* mostly untested */'), :51-54 (makeLuceneQueryNoBoost, single-field branch: 'return q.makeLuceneQueryFieldNoBoost(fieldNames.get(0), qf);'), :55-67 (multi-field branch: per-field FieldsQuery copies of q.clone(), OrQuery.makeLuceneQueryField), :71-73 (makeLuceneQueryFieldNoBoost delegates to makeLuceneQueryNoBoost)lucene/queryparser/src/java/org/apache/lucene/queryparser/surround/query/SrndQuery.java:58-63 (at a9779ef3c193) (makeLuceneQueryField wraps a weighted query in BoostQuery: 'weight may be at any level in a SrndQuery')lucene/queryparser/src/java/org/apache/lucene/queryparser/surround/query/ComposedQuery.java:64-71 (at a9779ef3c193) (makeLuceneSubQueriesField builds every child with makeLuceneQueryField, keeping its weight)lucene/queryparser/src/java/org/apache/lucene/queryparser/surround/parser/QueryParser.jj:58-62 (at a9779ef3c193) (class javadoc: 'quoting (with "), and boosting (via ^)'), :251-258 (FieldsQuery = OptionalFields then OrQuery), :376-385 (PrimaryQuery: 'bracketed weighted query or weighted term', OptionalWeights on the operand), :456-469 (OptionalWeights; weights <= 0 rejected)lucene/queryparser/docs/surround/README.txt:22-25 (at a9779ef3c193) ('Query terms from the Lucene standard query parser: field:termtext, ^ boost'), :44-47 (field-prefix examples 'title: text: aa'), :61 ('Not tested: multiple fields')
- The finding in 30 seconds
lucene/queryparser/src/java/org/apache/lucene/queryparser/surround/parser/QueryParser.jj:251-258, 376-385, 456-469lucene/queryparser/src/java/org/apache/lucene/queryparser/surround/query/SrndQuery.java:58-63; query/ComposedQuery.java:64-71; query/OrQuery.java:34; query/AndQuery.java:32lucene/queryparser/src/java/org/apache/lucene/queryparser/surround/query/FieldsQuery.java:51-73lucene/queryparser/src/java/org/apache/lucene/queryparser/surround/query/DistanceQuery.java:29, 100-101; query/SpanNearClauseFactory.java:123-134; query/RewriteQuery.java:39-48
- Who is affected
lucene/queryparser/src/java/org/apache/lucene/queryparser/surround/parser/QueryParser.jj:466-468 (weights <= 0 rejected)lucene/queryparser/docs/surround/README.txt:22-25, 44-47 (field:termtext and ^ boost listed separately; no weighted example)
- Why it looks unintended
lucene/queryparser/src/java/org/apache/lucene/queryparser/surround/parser/QueryParser.jj:58-62; parser/QueryParser.java:27lucene/queryparser/docs/surround/README.txt:22-25, 44-47, 61lucene/queryparser/src/java/org/apache/lucene/queryparser/surround/query/SrndQuery.java:61; query/OrQuery.java:34; query/AndQuery.java:32; query/FieldsQuery.java:26lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/QueryParser.jj:372; classic/QueryParserBase.java:813-829
- Suggested fix
lucene/queryparser/src/java/org/apache/lucene/queryparser/surround/parser/QueryParser.jj:106-112, 469; query/FieldsQuery.java:84-92; query/SrndQuery.java:91-107
- TestSrndFieldPrefixOperandWeight.java (JUnit test):
repro/LFV-686/src/org/apache/lucene/queryparser/surround/query/TestSrndFieldPrefixOperandWeight.java(59 lines)
Made in parallel with this doc from a plain probe program run on main a9779ef3c193 (default IndexWriterConfig and similarity, two documents, default field body; assertions on and off, 10.5.2, and with the fix shadowed in); every value on screen comes from the probe's log. The doc's repro test uses its own four-document index and the same mechanism.
assets/LFV-686/bug.png(568 KB)