The surround parser (lucene/queryparser) treats "..." as one literal term. Its lexer allows two escapes inside the quotes, \" and \\, but the parser passes the text between the quotes to the term query without removing them.
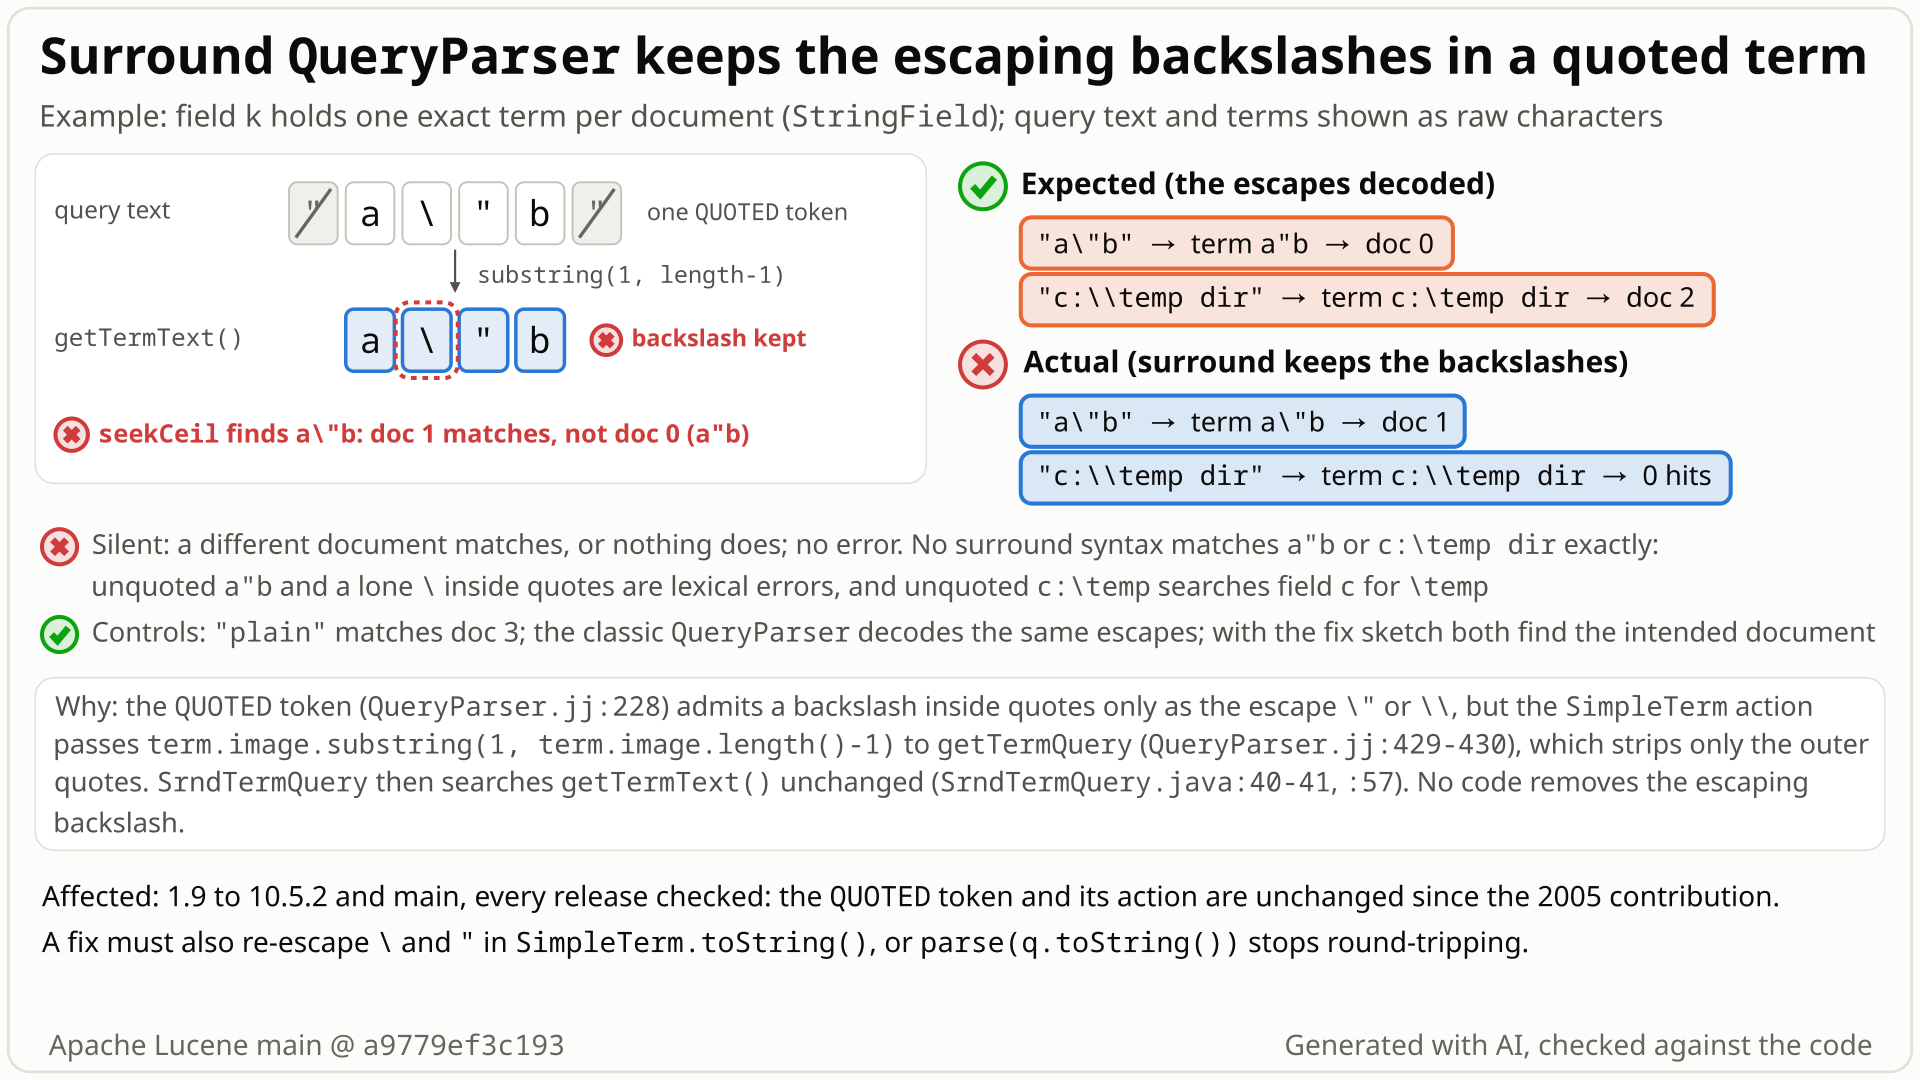
k. The query "a\"b" is one quoted token; the parser cuts off only the outer quotes, so it searches a\"b (4 characters) and matches the document holding a\"b, not a"b. The query "c:\\temp dir" searches c:\\temp dir and finds nothing. Select the still to open it at full size. Generated with AI, checked against the code.- You index one untokenized value per document in field
k: doc quote holdsa"b, and doc raw-quote holdsa\"b, the same text with a backslash in it. - You search the surround query
"a\"b". Inside quotes the parser accepts a backslash only as\"(a quote) or\\(a backslash); its grammar says "escape quoted quote or backslash by backslash". - You expect the term
a"b: 1 hit, doc quote. The classicQueryParserdecodes the same text toa"b. - Instead the parser cuts off only the outer quotes, so it searches
a\"b: doc raw-quote matches, doc quote does not, and without doc raw-quote you get 0 hits. Likewise"c:\\temp dir"searchesc:\\temp dir, not the pathc:\temp dir. - No error, and no other surround spelling matches
a"bexactly: a quote cannot appear in an unquoted term.
Applications that pass query text to the surround parser, including Solr's surround plugin, and need an exact term with a double quote, or a quoted term with a backslash (a value with a space or :, such as a Windows path). No setting is involved; it happens every time, at any index size. Rare: the parser is niche.
Mechanism, terms and numbers571 words
In the surround query language a term in double quotes is one literal term. Inside the quotes the lexer accepts a backslash only as \" or \\ and rejects a lone backslash, and the grammar comment on the token says "escape quoted quote or backslash by backslash". But the parser action for the token only removes the outer quotes, so SrndTermQuery searches the text with the escaping backslashes still in it: "a\"b" searches a\"b and "c:\\temp dir" searches c:\\temp dir. The intended term gets 0 hits, or a term that literally contains the backslashes matches instead; nothing throws. Since a quote cannot appear in an unquoted term and a lone backslash cannot appear inside quotes, no surround syntax matches such terms exactly. The classic and flexible parsers use a similar, broader quoted-token idiom and do remove the escapes. The token and its action date from the 2005 contribution and are semantically unchanged; every release checked from 1.9 to 10.5.2, 10.6.0 (by reading), and main, is affected. Unescaping in the parser and re-escaping in SrndTermQuery.toString fixes it and keeps parse(toString()) round-tripping.
- Lexer (
QueryParser.jj:223-228): the comment "Literal non empty term between single quotes, escape quoted quote or backslash by backslash." sits above the token<QUOTED: "\"" ( (~["\"", "\\"]) | ("\\" ["\\", "\""]))+ "\"">. Inside the quotes a character is anything except"and\, or a backslash followed by\or". A lone backslash, as in"p\q", is aParseException. - Parser action (
QueryParser.jj:429-430, generatedQueryParser.java:479-487):getTermQuery(term.image.substring(1, term.image.length()-1), true /* quoted */). Only the outer quotes are cut off; nothing removes the backslash of\"or\\. - Query (
SrndTermQuery.java:40-41,:50-61):getTermQuerybuildsnew SrndTermQuery(text, true), which seeks exactly that text (seekCeil,:57). When the text is not in the index the query rewrites toMatchNoDocsQuery(SimpleTermRewriteQuery.java:48).
Five documents with one untokenized StringField value each, searched with QueryParser.parse(text).makeLuceneQueryField("k", new BasicQueryFactory()):
| query text | intended term | term searched (getTermText()) | documents matched |
|---|---|---|---|
"plain" (control) | plain | plain | plain (correct) |
"a\"b" | a"b | a\"b | raw-quote (a\"b) instead of quote (a"b) |
"c:\\temp dir" | c:\temp dir | c:\\temp dir | raw-path (c:\\temp dir) instead of path (c:\temp dir) |
Without the raw-escaped documents both queries return 0 hits instead of 1. On a WhitespaceAnalyzer field, which keeps the token "hello" with its quotes, said w "\"hello\"" finds 0 of 1 documents.
- An unquoted term cannot contain
"(_TERM_CHAR,QueryParser.jj:194-196), soa"bis a lexical error. - Unquoted,
c:\temp diris two terms andc:is the field operator:c:\tempparses as fieldc, term\temp. - The truncated form
"c:\temp dir"*(TRUNCQUOTED,:227, no escapes) keeps backslashes as typed, but it is a prefix query and also matches longer terms. It cannot contain a quote ("a\"b"*is a lexical error), so for a term with a quote only a prefix that stops before the quote is left:"say "*matchessay "hi", and every other term that starts withsay. ?can stand in for an inner quote (abc?def), but it also matches any other character, and it needs at least 3 other characters:a?bis rejected ("Too unrestrictive truncation").- An unquoted term with a backslash already works:
a\bmatchesa\b.
Exposure and likelihood224 words
- Who. Callers of
QueryParser.parse/parse2andmakeLuceneQueryFieldinorg.apache.lucene.queryparser.surround: an opt-in, niche parser; open issue #16820 proposes deprecating it for Lucene 11. Solr'sSurroundQParserPluginpasses the query string straight toQueryParser.parseandmakeLuceneQueryField(read on apache/solr main, not executed). - Which terms. An exact value that contains a double quote (
12" pipe,say "hi", or a whitespace token that keeps its quotes), or a value with a backslash that also needs quotes because of a space,:or an operator character (c:\temp dir). Users are pointed to exactly this syntax: the one answer to Stack Overflow question 16935363 (2013, Solr 4.0) recommends"sec\"ond". - Default vs opt-in. No setting is involved: a probe with a plain
new IndexWriterConfig(), the default codec, a plainIndexSearcherandBasicQueryFactory(its 1024-clause limit still applies) gives the same wrong match; the compact repro runs under the test framework's randomized configuration. Only the parser is opt-in. - Always, silently. The term text is wrong before the index is touched, so it happens every time, with assertions on and off, at any scale: 0 hits, or hits on a different term that literally contains the backslashes. No exception.
- Likelihood: rare. Such terms are unusual in fields searched with surround, and the only public trace the searches found in 21 years is the 2013 question.
The test shows that the surround query parser keeps the escaping backslash inside a quoted term, so "a\"b" searches for a\"b instead of a"b.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.queryparser.surround.query;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.StringField;
import org.apache.lucene.index.IndexReader;
import org.apache.lucene.queryparser.surround.parser.QueryParser;
import org.apache.lucene.search.Query;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.index.RandomIndexWriter;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestSrndQuotedTermEscapes extends LuceneTestCase {

  public void testEscapedQuoteInQuotedTerm() throws Exception {
    Directory dir = newDirectory();
    RandomIndexWriter w = new RandomIndexWriter(random(), dir);
    Document doc = new Document();
    doc.add(new StringField("k", "a\"b", Field.Store.NO));
    w.addDocument(doc);
    IndexReader reader = w.getReader();
    w.close();
    Query q = QueryParser.parse("\"a\\\"b\"").makeLuceneQueryField("k", new BasicQueryFactory());
    int hits = newSearcher(reader).count(q);
    reader.close();
    dir.close();
    // "a\"b" must match the term a"b: expected 1 hit, actual 0 (it searches for a\"b)
    assertEquals("hits for the term a\"b", 1, hits);
  }
}
# in a copy of this finding's repro folder (repro/LFV-687/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/facet/build/libs/lucene-facet-$V.jar
CP=$CP:$LUCENE/lucene/queries/build/libs/lucene-queries-$V.jar
CP=$CP:$LUCENE/lucene/queryparser/build/libs/lucene-queryparser-$V.jar
CP=$CP:$LUCENE/lucene/sandbox/build/libs/lucene-sandbox-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.queryparser.surround.query.TestSrndQuotedTermEscapes
# the module(s) facet also need their third-party runtime jars
- Expected vs actual
- Expected: 1 hit on the one document whose StringField holds a"b. Actual (-ea and -da): 0 hits.
More files, environment, full output38 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: hits for the term a"b expected:<1> but was:<0>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:647)
org.apache.lucene.queryparser.surround.query.TestSrndQuotedTermEscapes.testEscapedQuoteInQuotedTerm(TestSrndQuotedTermEscapes.java:44)- The grammar says "escape quoted quote or backslash by backslash", and the lexer rejects a lone backslash: strong evidence that the escape is meant to be removed.
- The classic and flexible parsers accept these escapes too and remove them; LUCENE-573 and LUCENE-1189 fixed quoted-escape bugs there.
- No surround test puts an escape inside quotes; all 67 pass with the fix.
The full argument289 words
- Grammar.
QueryParser.jj:223-225: "Literal non empty term between single quotes, escape quoted quote or backslash by backslash. Evt. truncated." (it says single quotes, but the token uses double quotes). The token admits a backslash only as such an escape. With raw semantics"p\q"would be unambiguous, yet it is rejected, and requiring\\would make every quoted single-backslash term impossible. - Docs and intent. The class javadoc lists "quoting (with
")" (QueryParser.java:27). The parser's author wrote on java-user on 2004-06-09 ("Syntax for query parsers"): "double quotes can be used to search for any single term". A term with a quote that is not preceded by a backslash, such asa"b, cannot be searched exactly today. - Sibling parsers. Classic
QueryParser.jj:188, 207define QUOTED with a similar, broader idiom (a backslash may escape any character,:182, and the body may be empty), andQueryParserBase.handleQuotedTermcallsdiscardEscapeCharon the inner text (QueryParserBase.java:809), documented as "Returns a String where the escape char has been removed, or kept only once if there was a double escape" (:834-840). The flexibleStandardSyntaxParser.jj:831does the same. Surround has the lexical half, restricted to\"and\\, without the decoding. - Precedent. LUCENE-573 ("Escaped quotes inside a phrase cause a ParseException", 2006) and LUCENE-1189 ("QueryParser does not correctly handle escaped characters within quoted strings", 2008) were fixed as bugs in the classic parser.
- Tests and history.
Test01Exceptions,Test02Boolean,Test03DistanceandTestSrndQuerynever put an escape inside quotes; with the fix all 67 pass. The token and its action are semantically unchanged since the 2005 contribution. No CHANGES or MIGRATE entry says the backslashes are meant to stay, and the searches found no issue or list thread that does.
The devil's-advocate check236 words
The cross-model reviews (refute and intended lens) built the strongest case for "intended" and rated it moderate; the devil's advocate built the same case and concluded that none of it survives. The case: surround can be read as raw, the text between the quotes being the term, with the backslash rule only keeping the token from ending early. Unquoted terms and the truncated form "..."* also keep backslashes as typed. Keeping the raw text makes parse(q).toString() round-trip exactly, which matters because surround query equality is toString() equality (LUCENE-2945). No complaint was found in 21 years, a fix changes what existing queries with \\ mean, and the protected getTermQuery(String, boolean) hook lets an application decode itself.
Why it fails: under the raw reading ordinary terms cannot be written exactly (a term with a quote that is not preceded by a backslash, such as a"b; a quoted term with one backslash, such as c:\temp dir), the lexer's rejection of a lone backslash would serve no evident purpose, and the grammar's "escape" comment would describe nothing. That is strong evidence, not proof. The round trip is kept by re-escaping in toString (the validated fix). Age without reports reflects how niche the parser is; the hook is a workaround, and the javadoc says parse() is the only method clients should need. Verdict: a defect. Upstream may still prefer to document raw semantics, but the impossible terms would remain.
Recommended Unescape in the QUOTED action and re-escape in SrndTermQuery.toString
Remove the backslash of each \" and \\ in the parser's QUOTED action (a small unescapeQuoted helper in QueryParser.jj, then regenerate), and re-escape \ and " in SrndTermQuery.toStringUnquoted() for quoted terms, so parsed queries print and compare exactly as before. The repro and the whole lucene/queryparser suite pass.
   | term=<QUOTED>
-    {return getTermQuery(term.image.substring(1, term.image.length()-1), true /* quoted */);}
+    {return getTermQuery(unescapeQuoted(term.image.substring(1, term.image.length()-1)), true /* quoted */);}

   // SrndTermQuery.toStringUnquoted()
+    if (isQuoted()) {
+      return getTermText().replace("\\", "\\\\").replace("\"", "\\\"");
+    }
     return getTermText();
All options and trade-offs3 options · 642 words
One fix was built and validated in a clean worktree; the parser-only variant from the hunt is shown for comparison. Any decoding fix changes what existing quoted queries with \\ or \" mean, so it needs a CHANGES entry.
Unescape in the QUOTED action and re-escape in SrndTermQuery.toString (validated by the checks) (recommended)
In QueryParser.jj, a static unescapeQuoted(String) drops the backslash of each \" and \\ (the lexer guarantees that a backslash inside QUOTED is followed by one of the two), and the QUOTED action calls it; QueryParser.java and its checksum file are regenerated with ./gradlew :lucene:queryparser:regenerateSurroundQueryParser. In SrndTermQuery.toStringUnquoted(), a quoted term writes \ as \\ and " as \", so parse(q).toString() is unchanged and still parses back to an equal query.
   | term=<QUOTED>
-    {return getTermQuery(term.image.substring(1, term.image.length()-1), true /* quoted */);}
+    {return getTermQuery(unescapeQuoted(term.image.substring(1, term.image.length()-1)), true /* quoted */);}

   // SrndTermQuery.toStringUnquoted()
+    if (isQuoted()) {
+      return getTermText().replace("\\", "\\\\").replace("\"", "\\\"");
+    }
     return getTermText();
Trade-offs
- Meaning change.
"a\\b"then searchesa\binstead ofa\\b, and"a\"b"searchesa"b. Worth a CHANGES line. - Hook input. Subclasses that override the protected
getTermQuery(String, boolean)now receive the decoded text for quoted terms. - Direct construction. A
SrndTermQuerybuilt by hand with quoted=true and a backslash or quote in its text now prints with escapes, so itstoString,equalsandhashCodechange: it equals a parsed query only when its text is the decoded form. What it matches does not change. - Truncated form left as is. TRUNCQUOTED (
"..."*) has no escapes and keeps a lone backslash, so"a\\b"would meana\bwhile"a\\b"*still means the prefixa\\b. Upstream can decide whether to give it the same escapes; that would turn today's"x\y z"*into a lexical error. - Tests to add upstream. By inspection,
unescapeQuotedand the re-escaping are inverses on every body the QUOTED token accepts, but the round-trip guard runs only three strings: add adjacent and repeated escape pairs and directly constructed queries.
What the checks validated
- Stock main
a9779ef3c193, gradle in a clean worktree: the repro fails 2 of 4 with assertions on and with assertions off. - With the fix: the whole
lucene/queryparsersuite passes (31 classes, 537 tests, 0 failures, 1 skipped by an existing@Ignore), including the repro 4 of 4 and the four surround suites (67 tests); the repro also passes 4 of 4 with assertions off. - With the fix:
checkGoogleJavaFormat,ecjLintMain,ecjLintTest,forbiddenApisMain,forbiddenApisTestandregenerateSurroundQueryParserChecksumCheckpass;QueryParser.javawas regenerated from the grammar by the project's own task. - Fix shadowed onto the stock jars: the finder's test 3 of 3 and the independent reproducer's 7 of 7 pass; the devil's advocate's 4 bug tests and its round-trip check pass, and only its info test that records today's behaviour flips, as expected.
- Not run: a benchmark (the helper returns its input unchanged when it has no backslash).
One replaceAll on the text between the quotes. Fixes matching: the finder's, the reproducer's, both reviewers' and the devil's advocate's bug tests pass, and the 67 surround tests pass.
Trade-offs
Breaks the toString round trip, so query equality changes: the parsed query "a\"b" then prints as "a"b", which does not parse back (this repro's guard fails: expected:<"a[\]"b"> but was:<"a[]"b">). Not recommended alone.
Change the grammar comment and the javadoc to say that backslashes inside quotes are kept.
Trade-offs
No compatibility change, but a term with a quote that is not preceded by a backslash (a"b), or a quoted term with a single backslash (c:\temp dir), stays impossible to search exactly. Not explored: also accepting a lone backslash inside quotes (fixes "c:\temp dir", not a"b), or changing nothing and leaving it to the deprecation discussed in #16820.
Solr's surround query parser plugin hands user query text to this parser, so Solr users who quote a term with \" or \\ get the same wrong term (read in the Solr source, not executed).
Code reading, not a formal tool. While writing the quoted-term renderer for a bounded-exhaustive differential harness of the surround parser, the finder noticed that the QUOTED token accepts escapes that the parser never removes; the harness itself passed for quoted terms without escapes. A probe on the stock jar and a public-API JUnit confirmed it.
The method in full132 words
- Method: non-formal code reading. The hunt unit checked surround query parsing against a reference semantics with a bounded-exhaustive translation-validation harness. Its check passed for quoted terms without escapes, so the harness did not give the signal.
- While writing the harness's renderer for quoted leaves, the finder read the lexer's QUOTED token, saw that it admits
\"and\\, and found no code that removes them. - A probe on the stock main jar showed
"a\"b","a\\b"and"c:\\temp"rewriting toMatchNoDocsQuery(0 hits), while unquoteda\bmatched and the classic parser decoded the same quoted escapes. A public-API JUnit followed (2026-10-27). - An independent reproducer, reviewers from another model family (OpenAI GPT-5.6) and an intended-behaviour devil's advocate then reproduced it with their own tests, and an adjudication confirmed it with new seeds.
No prior report found (2026-10-27) in three runs of the hunt's prior-report tool, GitHub searches across Lucene, Solr, Lucene.NET and two downstream engines, 409 open PRs, 204 JIRA surround issues, 54 list queries, Stack Overflow and the web. Closest: a 2013 Stack Overflow question whose answer recommends the broken syntax.
Searches5 searches
Verdict new: no report was found in the sources searched. The closest item shares the user need, not the diagnosis: in Stack Overflow question 16935363 (2013, Solr 4.0) a user could not search a term with a double quote through surround (all their attempts were unquoted, which the grammar rejects by design); the one answer (2014, not accepted) recommends "sec\"ond", the syntax this bug breaks, and nobody reported the result.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; mailing lists; JIRA archive; downstream repos; the web | 2026-10-27 | three runs of the hunt's prior-report tool: the finder's (51 queries, 6 of them web queries left pending; 232 distinct hits) and two follow-up runs (54 and 38 queries); the intended-behaviour check's own run (87 hits) | no hit with high overlap; the medium-overlap hits read: none about quoted escapes in surround |
| GitHub: apache/lucene, apache/solr, apache/lucenenet, Elasticsearch, OpenSearch | 2026-10-27 | surround with quote, quoted, escape, backslash, unescape, double quote, quoted term, special characters; SrndTermQuery, SimpleTerm, QUOTED, TRUNCQUOTED, LUCENE-368; surround in:title (all read) | context only: #1446 (LUCENE-368, the contribution), #5112 (LUCENE-4040, open, surround docs), #4019 (LUCENE-2945, equality via toString), #8664 (LUCENE-7613, Won't Fix), #16820 (open, deprecation proposal); the Lucene.NET port has the same code and no report |
| open apache/lucene PRs and the surround files' upstream history | 2026-10-27 | changed-file lists of all 409 open PRs; commits on the four fix-site files on main and branch_10x | only #13008 (stale) touches surround files, and not the term text; not fixed upstream (main a95c754ee003 has the same code) |
| LUCENE and SOLR JIRA archive | 2026-10-27 | all 204 issues mentioning surround, scanned for quote, escape or backslash | nothing on quoted escapes; LUCENE-573 and LUCENE-1189 are classic-parser precedents |
| lists.apache.org (java-user@, dev@, solr-user@, general@, Solr lists), Stack Overflow, the web | 2026-10-27 | 54 list queries; Stack Overflow through its public API; 6 web queries; the Solr reference guide's surround section | Stack Overflow 16935363 (closest, need only); the author's 2004 java-user post (intent evidence); no report |
In the original 2005 contribution of the surround parser (9d70229506f, LUCENE-368) and semantically unchanged since, so every release checked that ships surround is affected: 1.9 to 10.5.2, 10.6.0 (by reading) and main. Executed on 26 releases from 1.9.1 to 10.5.2 and main; all 147 release tags read. Not fixed upstream.
Versions tested7 rows
Introduced by 9d70229506f (SVN r209183, 2005-07-05), "#34331 - Add Paul Elschot's Surround query language parser" (ASF Bugzilla #34331 = LUCENE-368 = GitHub #1446; no pull request). The QUOTED token, its comment and the action were written together and are semantically unchanged since (git blame, git log -L; git log --all -S also lists the 2025 reformat of the generated Java, #15393, layout only, and aad44bc6e36, a 2021 note commit on a separate branch_8x pointer ref that deletes the whole tree). The 2004 pre-contribution archive attached to LUCENE-368 has the same rule and action. First release 1.9 (2006-02-27); 1.4.3 and earlier have no surround parser, so no release that contains surround is unaffected. 8.8.2 to 8.11.3 are not tagged locally and were neither read nor run; they lie between 8.8.1 and the executed 8.11.4 and are inferred to be affected. Not fixed upstream: main a95c754ee003 and 20ced71c1e6e, branch_10_6 and branch_10x have the same token and action.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the compact JUnit fails 2 of 4 through gradle, assertions on and off, and through the classpath runner with -ea and -da; the hunt's tests fail too |
| 10.5.2, 9.12.3 | affected | the compact JUnit 2 of 4 with assertions on and off; the finder's 2 of 3; the reproducer's 4 of 7; the devil's advocate's 4 of 11; the parse probe keeps the backslashes |
| 9.5.0 | affected | the compact JUnit 2 of 4 (-ea); on 9.0 to 9.4 it does not compile (no IndexSearcher.storedFields(); 9.4.2 run), which says nothing about the bug there |
| 9.1.0, 10.0.0 | affected | the finder's JUnit 2 of 3, control passes |
| 1.9.1 to 10.4.0 (22 releases) | parse probe | 1.9.1, 2.0.0, 2.4.1, 2.9.4, 3.0.3, 3.1.0, 3.6.2, 4.0.0, 4.10.4, 5.0.0, 5.5.5, 6.0.0, 6.6.6, 7.0.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.9.2, 9.10.0, 10.3.2, 10.4.0: the parse probe shows the term text keeps the backslashes; end to end on 1.9.1, 2.0.0, 2.4.1, 2.9.4, 5.5.5, 6.6.6, 7.7.3, 8.11.4: 0 hits, control 1 |
| 1.9.1, main + parser-only fix | parser-only fix shadowed | with the hunt's parser-only fix: the parse probe keeps no backslash on 1.9.1 and main; the end-to-end probe finds the document on 1.9.1 (1 hit). Not a test of the recommended fix's toString re-escaping |
| 1.4.3 and earlier | no surround parser | nothing to run |
An independent reproducer and an intended-behaviour devil's advocate reproduced it with their own tests, controls passing; two executed reviews by a model from another family (OpenAI GPT-5.6) rated it real with a moderate intended argument; an adjudication re-ran it with new seeds; this doc's gradle runs reproduce it on a9779ef3c193 and validate the fix.
Checks and verdicts380 words
Each check ran its own code against the stock jars; the cross-model reviewers ran on main ea57360912ed, where the four surround files are byte-identical.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Probe and public-API JUnit: 2 of 3 fail on main (-ea, -da), 10.5.2 and 9.12.3, control passes; the parser-only fix passes it and the 67 surround tests. |
| cross-model review, refute lens (OpenAI GPT-5.6) | real, high | Its own test fails on main with three seeds (-ea and -da), its control passes, and the fix passes its test and the 67 surround tests; noted that a production fix must re-escape in toString. |
| independent reproducer | real | Own test from the claim: 4 of 7 fail on main (-ea, -da), 10.5.2 and 9.12.3; showed the hits land on the raw-escaped documents; 3 controls pass; 7 of 7 with the fix. |
| cross-model review, intended lens (the cross-model review, OpenAI GPT-5.6) | real, high; intended argument moderate | Own test 2 of 6 fail on main, 10.5.2 and 9.12.3; the classic parser decodes the same escapes; the parser-only fix breaks the round trip. Re-run on a9779ef3c193: same. |
| intended-behaviour devil's advocate | real; no intended argument survives | Found the author's 2004 list post; own test 4 of 11 fail on main, 10.5.2 and 9.12.3, incl. a WhitespaceAnalyzer field. |
| adjudication | confirmed, high | Re-ran the reproducer's test with seed 1A2B3C (4 of 7 fail, -ea and -da) and the finder's with -da, seed 77AA (2 of 3). |
| Registration check and audit | keep | Finder repro re-run on a clean a9779ef3c193: 2 of 3 fail with -ea and -da (seeds DEADBEEF, C0FFEE12); 3 of 3 with the fix. |
| this doc | reproduced; fix validated | Compact JUnit through gradle on a clean worktree: 2 of 4 fail stock, 4 of 4 pass with the fix, assertions on and off; the queryparser suite passes with the fix. |
| fact checks of this doc | reproduced; wording fixed | An independent fact check re-ran the compact repro on main, 10.5.2, 9.12.3 (assertions on and off), 9.5.0 and earlier 9.x, the recommended and the parser-only fix, and its own probe; a reading-only cross-model fact check (OpenAI GPT-5.6) and a diagram check followed. Every result matched; their wording and precision points were fixed in this doc. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 455 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,428 words
- Registry title
- Surround query parser keeps the escaping backslashes inside a quoted term, so "a\"b" searches for a\"b instead of a"b and "c:\\temp dir" searches for c:\\temp dir instead of c:\temp dir
- Area
- queryparser / surround (QueryParser.jj QUOTED token and SimpleTerm production, SrndTermQuery)
- Priority
- Low, rank 379: Needs an escaped quote or backslash inside a quoted term of the niche surround parser.
- Impact class
- silent wrong results
- Impact note
- Hits applications that pass query text to the surround QueryParser (an opt-in, niche parser of the queryparser module; open issue #16820 proposes deprecating it) when a quoted term uses one of the two escapes the lexer accepts inside quotes, \" or \\: with the default IndexWriterConfig, codec and searcher, at any scale and with -ea or -da, the term is searched with its backslashes still in it, so the intended term (one that contains a double quote, or a quoted term that contains a backslash because it also needs quotes for a space, ':' or an operator character) gets 0 hits, or a document whose field holds the backslash-escaped text matches instead; nothing throws and the index is not touched.
- Summary
- You parse a surround query with a quoted term that escapes a double quote or a backslash, such as "a\"b" or "c:\\temp dir", and run it on a field that holds the untokenized value a"b or c:\temp dir. You expect a match, because the grammar comment on the QUOTED token says 'escape quoted quote or backslash by backslash' and the lexer accepts a backslash inside quotes only as such an escape. Instead the parser strips only the outer quotes, so SrndTermQuery searches for a\"b and c:\\temp dir with the backslashes kept: 0 hits, or a silent match on a different document that holds that escaped text, and no surround syntax matches those terms exactly.
- Introduced
- 9d70229506f88d3259ba0d24a824c0dbadc52c8e (SVN r209183, the original contribution of the surround parser, ASF Bugzilla #34331 = LUCENE-368 = GitHub issue #1446; no pull request) [read: git blame and git log -L on QueryParser.jj:223-228 and :429-430 list only this commit, git log -S on the token text and on the action text finds the same commit, and all 147 release tags that contain the surround parser (1.9-rc1 to 10.5.2) have the identical QUOTED token and SimpleTerm action with no unescape code] [exec: with only the escape-removing change shadowed, the history probes pass on 1.9.1 and on main]; the 2004 pre-contribution archive attached to LUCENE-368 already has the same rule and action (2005-07-05)
- First affected version
- 1.9 (2006-02-27; also 1.9-rc1 of 2006-02-21) [read]; 1.9.1, the first surround artifact on Maven Central, [exec]; there is no unaffected release: 1.4.3 and earlier have no surround parser
- Affected versions
- every release that ships the surround parser, 1.9 to 10.5.2, and main a9779ef3c193 [exec: a version-independent parse probe on 25 releases (1.9.1, 2.0.0, 2.4.1, 2.9.4, 3.0.3, 3.1.0, 3.6.2, 4.0.0, 4.10.4, 5.0.0, 5.5.5, 6.0.0, 6.6.6, 7.0.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.9.2, 9.10.0, 9.12.3, 10.0.0, 10.3.2, 10.4.0, 10.5.2) and main; an end-to-end index-and-search probe on 1.9.1, 2.0.0, 2.4.1, 2.9.4, 5.5.5, 6.6.6, 7.7.3 and 8.11.4; the finder's JUnit on 9.1.0, 9.12.3, 10.0.0, 10.5.2 and main (main with -ea and -da); the independent reproduction's, the cross-model review's and the intended-behaviour check's own tests on 10.5.2 and 9.12.3] [read: the 147 release tags 1.9-rc1 to 10.5.2 in the history clone have the identical code; the clone's 8.x tags stop at 8.8.1]; not fixed upstream: upstream main a95c754ee003 (2026-10-26) has the same code [read]; branch_10_6 and branch_10x were not read in the hunt; the bug doc's read of 2026-10-28 finds the same token and action on branch_10_6 2763db11b0a7 (contained in 10.6.0, released 2026-10-29) and on branch_10x, so 10.6.0 is affected too [read]; a regression window does not exist (the code is unchanged since the contribution); executed on Linux aarch64 with JDK 25 only
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (2026-10-27, the prior-report record verdict new, all read-only: the finder's scripted prior-report search (45 queries: 16 GitHub issue and PR, 3 commit, 2 downstream, 20 mailing-list, 4 JIRA archive; 232 distinct hits, none with high overlap) and two follow-up runs (54 queries including 6 web, and 38 queries); GitHub issue and PR searches on apache/lucene (surround with quote, quoted, escape, backslash, unescape, double quote, quoted term, SrndTermQuery, SimpleTerm, LUCENE-368 and more), apache/solr, apache/lucenenet, Elasticsearch and OpenSearch; the file lists of all 409 open apache/lucene PRs; the upstream commit history of the four surround files on main and branch_10x; the LUCENE and SOLR JIRA archive (204 surround issues scanned for quote, escape or backslash); 54 lists.apache.org queries over java-user@, dev@, solr-user@, general@ and the Solr lists; Stack Overflow and the web; the independent reproduction's gh searches and the intended-behaviour check's own scripted prior-report search (87 hits, none with high or medium overlap) found nothing either); not fixed upstream: upstream main a95c754ee003 has the same code, and the only open PR that touches surround files, #13008 (stale), changes TermStates handling, not the term text; closest item: Stack Overflow question 16935363 (2013, Solr 4.0): a user could not search a term containing a double quote with surround (all their attempts were unquoted and threw parse exceptions, which the grammar intends), and the one unaccepted answer (2014) recommends the quoted escape "sec\"ond", the syntax this bug breaks, with no follow-up; context only: #1446 (LUCENE-368, the contribution), #5112 (LUCENE-4040, open, surround syntax poorly documented, nothing on escapes), #4019 (LUCENE-2945, equals/hashCode via toString, which constrains the fix), #8664 (LUCENE-7613, Won't Fix), #16820 (open, proposes deprecating surround for Lucene 11); classic-parser precedents where quoted-escape handling was fixed as a bug: LUCENE-573, LUCENE-1189; the Lucene.NET port has the same code and no report; gaps: GitHub search is token based and was rate-limited several times (every logged query was retried and completed), and Stack Overflow was read through its public API
- Lucene commit tested
- main
a9779ef3c193(2026-10-26): the compact JUnit through gradle in a clean worktree, stock and with the fix, assertions on and off, plus the wholelucene/queryparsertest suite and its lint checks with the fix (2026-10-28); through the hunt's classpath runner the same JUnit on main (-ea,-da, fix shadowed), 10.5.2 and 9.12.3 (-eaand-da) and 9.5.0 (it needs 9.5+ to compile). Hunt runs: a parse probe on 25 releases from 1.9.1 to 10.5.2 and main, an end-to-end probe on 8 of them, and the hunt's JUnits on 9.1.0, 9.12.3, 10.0.0, 10.5.2 and main.
- Finding record
a Lucene main checkout lucene/queryparser/src/java/org/apache/lucene/queryparser/surround/parser/QueryParser.jj:223-225 (comment 'Literal non empty term between single quotes, escape quoted quote or backslash by backslash. Evt. truncated.'), :227 (TRUNCQUOTED, no escapes), :228 (QUOTED token), :429-430 (SimpleTerm action getTermQuery(term.image.substring(1, term.image.length()-1), true))a Lucene main checkout lucene/queryparser/src/java/org/apache/lucene/queryparser/surround/parser/QueryParser.java:27 (class javadoc 'quoting (with ")'), :113-114 (getTermQuery), :479-487 (generated QUOTED case)a Lucene main checkout lucene/queryparser/src/java/org/apache/lucene/queryparser/surround/query/SrndTermQuery.java:40-41 (getLuceneTerm uses getTermText() unchanged), :50-61 (visitMatchingTerms seekCeil(new BytesRef(getTermText()))); SimpleTerm.java:48-60 (toString re-wraps the raw text in quotes); the four surround files are byte-identical in Lucene main ea57360912ed
- The finding in 30 seconds
a Lucene main checkout lucene/queryparser/src/java/org/apache/lucene/queryparser/surround/parser/QueryParser.jj:194-196, 223-228, 429-430a Lucene main checkout lucene/queryparser/src/java/org/apache/lucene/queryparser/surround/parser/QueryParser.java:113-115, 479-487a Lucene main checkout lucene/queryparser/src/java/org/apache/lucene/queryparser/surround/query/SrndTermQuery.java:40-41, 50-61; surround/query/SimpleTermRewriteQuery.java:38, 48
- Who is affected
apache/solr main solr/core/src/java/org/apache/solr/search/SurroundQParserPlugin.java:20-23, 83, 93 (read through the GitHub API, 2026-10-28)a Lucene main checkout lucene/queryparser/src/java/org/apache/lucene/queryparser/surround/query/BasicQueryFactory.java:34-41 (default 1024)
- Why it looks unintended
a Lucene main checkout lucene/queryparser/src/java/org/apache/lucene/queryparser/surround/parser/QueryParser.jj:61, 223-228; surround/parser/QueryParser.java:21-22, 27a Lucene main checkout lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/QueryParser.jj:188, 207; classic/QueryParserBase.java:798-810, 834-840; flexible/standard/parser/StandardSyntaxParser.jj:136, 159, 831
- Suggested fix
a Lucene main checkout lucene/queryparser/src/java/org/apache/lucene/queryparser/surround/query/SimpleTerm.java:48-61; surround/query/SrndQuery.java:68-70, 92-93, 103-106 (equality via toString, LUCENE-2945)
- History
a Lucene clone (fresh clone): git show origin/main 20ced71c1e6e, origin/branch_10_6 2763db11b0a7, origin/branch_10x 1309534296e3 on surround/parser/QueryParser.jj:228, 430 and SrndTermQuery.java:45-47 (2026-10-28)
- TestSrndQuotedTermEscapes.java (JUnit test):
repro/LFV-687/src/org/apache/lucene/queryparser/surround/query/TestSrndQuotedTermEscapes.java(46 lines)
Made in parallel with this doc from its own public-API probe on main a9779ef3c193 (-ea and -da, also 10.5.2, and with the hunt's parser-only fix shadowed, which gives the same matches as the recommended fix); every value on screen comes from that probe. It uses four documents (doc 0 to 3) instead of the compact repro's five.
assets/LFV-687/bug.png(455 KB)