The document suggester (SuggestField with a completion postings format) answers completion queries from an FST of all suggestions. RegexCompletionQuery should return the suggestions that have a prefix matching the regex, as in its javadoc example su[g|b] for the prefixes sug and sub.
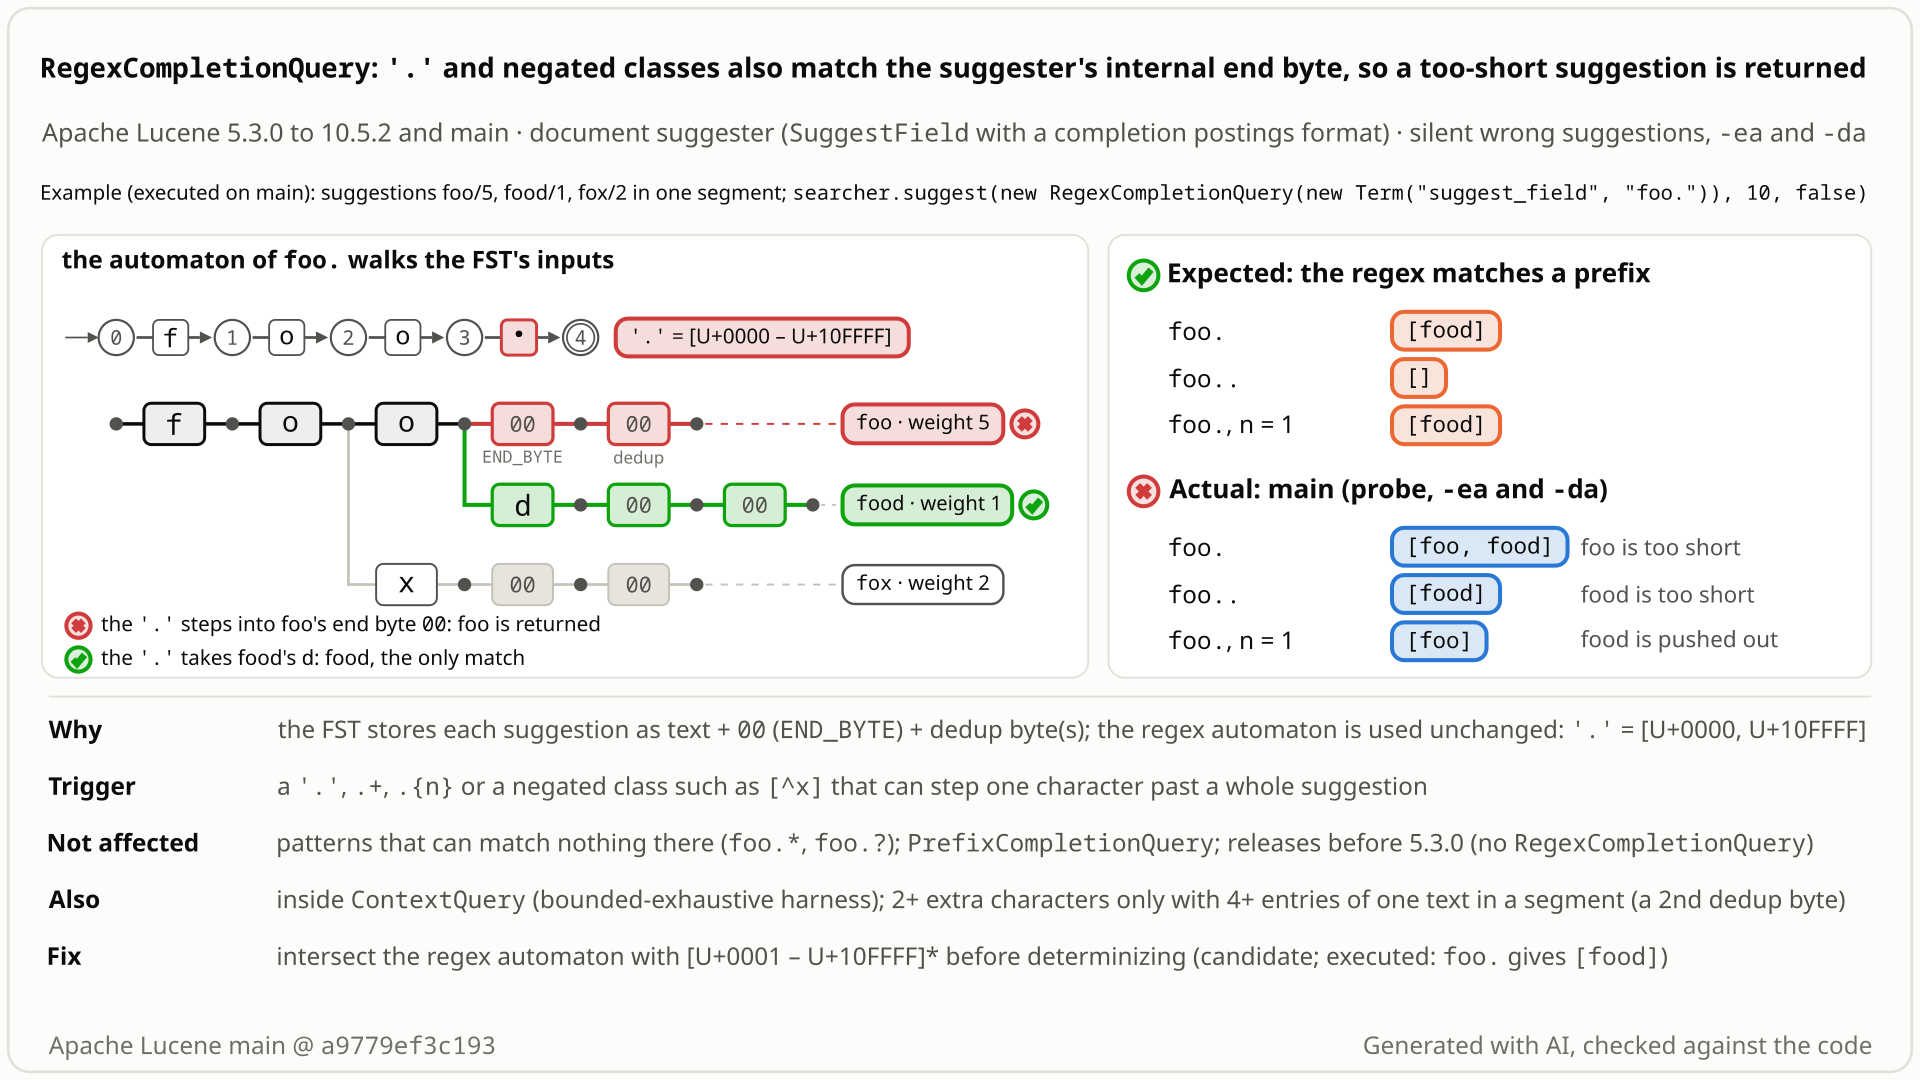
foo, food and fox as a prefix tree, the automaton of foo. walking it into foo's end byte, and a summary card with the expected and actual results. Select the still to open it at full size. Generated with AI, checked against the code.- Index three suggestions with
SuggestFieldin one segment:foo(weight 5),food(1) andfox(2). - Run
RegexCompletionQuerywithfoo., "foo plus one more character". You expect[food]: it is the only four-character suggestion that starts withfoo. - Inside, each suggestion is stored as its text, a hidden end byte
00and a dedup byte. The query's.matches any code point including U+0000, so it can takefoo's end byte instead of a fourth letter. - You get
[foo, food], withfoofirst. With n = 1 you get[foo]: the only correct suggestion is gone.foo..(five characters) returns[food]instead of[]. - No error, with assertions on or off.
foo.*andPrefixCompletionQuerygive the right results on the same data.
Applications that query the document suggester with RegexCompletionQuery, directly, inside a ContextQuery or through a downstream completion-suggester regex option, whenever the pattern ends in ., .+, .{n} or a negated class right after a shorter suggestion. The extra suggestion is often the highest weighted, so it can push the right one out of the top n.
Mechanism, terms and numbers727 words
RegexCompletionQuery "takes a regular expression as the prefix of the query term": a suggestion should match when some prefix of it matches the regex. The document suggester stores every suggestion in its FST as the analyzed form, then a reserved end byte 0x00, then dedup bytes, and the query intersects the regex automaton with these stored inputs unchanged. In Lucene's RegExp, . covers U+0000 to U+10FFFF and a negated class is "any character" minus the class, so both can consume the end byte. Over foo (weight 5), food (1) and fox (2), foo. and foo[^x] return [foo, food] instead of [food], foo. with n = 1 returns [foo], and foo.. returns [food] instead of []; with five entries foo in one segment, foo.. returns [foo, foo]. The same happens inside ContextQuery. Nothing throws; filters, deletions and contexts still apply. Every release from 5.3.0 to 10.5.2 and main is affected. An 8-line fix in RegexCompletionQuery.createWeight (intersect the automaton with "any code point except U+0000, repeated") passes the new test and the whole lucene/suggest module.
- Document suggester. A
SuggestField(orContextSuggestField) indexed with a completion postings format. Each segment keeps an FST whose inputs are the suggestions' analyzed forms; a completion query intersects an automaton with those inputs and then collects the best-weighted suggestions below each match. - End byte and dedup bytes. Every stored input is the analyzed form, then
END_BYTE0x00, then one dedup byte per entry (0, 1, 2, ...), which keeps several entries with the same text apart. After 3 entries of one form a second dedup byte is opened.SuggestFieldrejects 0x00 in values, so the end byte is never text. RegexCompletionQuery. "A CompletionQuery which takes a regular expression as the prefix of the query term" (RegexCompletionQuery.java:31-43,@lucene.experimental), default flagsRegExp.ALL.
createWeightbuildsOperations.determinize(new RegExp(text, flags).toAutomaton(), determinizeWorkLimit)and hands it toCompletionWeightunchanged (RegexCompletionQuery.java:92-97)..isAutomata.makeAnyChar()=[U+0000, U+10FFFF](RegExp.java:695-696,Automata.java:104-107); a negated class is any character minus the class (RegExp.java:1299-1302). Both contain U+0000.NRTSuggesterBuilder.startTermappendsEND_BYTE0x00 to every analyzed form andfinishTermthe dedup bytes (NRTSuggesterBuilder.java:43,:66-69,:81-97,:124-134). Sofoois stored asf o o 00 00,foodasf o o d 00 00.NRTSuggester.lookupintersects the automaton with the stored inputs throughFSTUtil.intersectPrefixPaths(NRTSuggester.java:131-132), which follows every arc the automaton accepts, 0x00 included, and reports the first accepting node as a matching prefix (FSTUtil.java:71-123).- For
foo., the.takesfoo's00; the completion search from that node still findsfoo(NRTSuggester.java:230-253), sofoois returned next tofood. - Two extra characters (
foo..) end on a node with nothing left after it when a form has one dedup byte; the search does not emit such an empty completion (allowEmptyStringfalse,NRTSuggester.java:245-248,Util.java:284). With 4 or more entries of one form in a segment, the second dedup byte leaves one byte to complete, and copies of the short suggestion come back.
| query (suggestions) | expected | actual |
|---|---|---|
fo. (foo/5, food/1, fox/2), control | [foo, fox, food] | [foo, fox, food] |
foo.*, control | [foo, food] | [foo, food] |
foo. | [food] | [foo, food] |
foo[^x] | [food] | [foo, food] |
foo., n = 1 | [food] | [foo] |
foo.. | [] | [food] |
foo.. over 3 copies of foo, control | [] | [] |
foo.. over 5 copies of foo | [] | [foo, foo] |
ContextQuery around foo., context c | [food] | [foo, food] |
Every row ran on main with assertions on and off; the first eight also on 10.5.2. PrefixCompletionQuery foo gives [foo, food]. Contexts still restrict the results (executed). By code reading, filters and deleted documents are still honoured: every completed path goes through CompletionScorer.accept (NRTSuggester.java:207, CompletionScorer.java:82-92).
The test lists duplicates (suggest(query, num, false)). With duplicate suppression on, five copies give [foo] for foo.. (still not []), and foo. over foo, food and fox still gives [foo, food]; with the fix [] and [food].
Expected results are stated over the analyzed form, which is what the FST stores. Here it equals the visible text. With other analysis (token separators, position increments, stop words, graph expansion; CompletionAnalyzer.java:69-99) the analyzed form, not the visible length, decides what should match.
Exposure and likelihood301 words
- Who is exposed. Users of the document suggester (
SuggestFieldorContextSuggestFieldwith a completion postings format) who runRegexCompletionQuery: directly, wrapped in aContextQuery, or through a downstream engine's completion-suggester regex option. A read-only code search found two downstream completion field mappers that pass the user's pattern toRegexCompletionQueryunchanged. The API is@lucene.experimental. - What triggers it. A pattern that can match one more character, from a class that contains U+0000, right after a complete, shorter suggestion: a trailing
.,.+("at least one more letter"),.{n}, or a negated class such as[^x]. Patterns that can match nothing there, such asfoo.*orfoo.?, give the same results with and without the fix. - Effect. Extra, too-short suggestions, often ranked first:
bar.with n = 1 over bar/10, bark/3, barn/2 gives[bar]instead of[bark];ba...gives[bark, barn]although no suggestion has five characters. Two or more extra characters reach a result only when 4 or more entries share one analyzed form in one segment. - Scale. Deterministic; no large index is needed (three documents reproduce it); one or several segments (the harness covered 1 to 3), assertions on or off, completion postings formats from Completion50 to Completion104, and ordinary analyzers (whitespace, keyword,
StandardAnalyzerthroughCompletionAnalyzer). - Not affected.
PrefixCompletionQuery, which has no wildcard (the prefixfoogives[foo, food]); zero-width tails; releases before 5.3.0, which have noRegexCompletionQuery. Nothing is written to the index, so a fix needs no reindexing. - Cost. No resource-exhaustion effect was observed, and none was benchmarked. Each wrong match adds a prefix path, and the lookup multiplies the number of results it searches for by the number of prefix paths (
NRTSuggester.java:142-144,:292-301), so the extra work is bounded but not zero.
The test shows that RegexCompletionQuery("foo.") over the suggestions foo and food also returns foo, because '.' matches the suggester's internal end byte 0x00.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.suggest.document;

import java.util.Arrays;
import java.util.List;
import org.apache.lucene.analysis.standard.StandardAnalyzer;
import org.apache.lucene.codecs.PostingsFormat;
import org.apache.lucene.codecs.lucene104.Lucene104Codec;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.Term;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestRegexCompletionEndByte extends LuceneTestCase {

  public void testDotNeedsARealCharacter() throws Exception {
    IndexWriterConfig iwc = new IndexWriterConfig(new StandardAnalyzer());
    iwc.setCodec(
        new Lucene104Codec() {
          final PostingsFormat completion = new Completion104PostingsFormat();

          @Override
          public PostingsFormat getPostingsFormatForField(String field) {
            return completion;
          }
        });
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w = new IndexWriter(dir, iwc)) {
      w.addDocument(List.of(new SuggestField("suggest", "foo", 2)));
      w.addDocument(List.of(new SuggestField("suggest", "food", 1)));
      try (DirectoryReader reader = DirectoryReader.open(w)) {
        RegexCompletionQuery query = new RegexCompletionQuery(new Term("suggest", "foo."));
        TopSuggestDocs hits = new SuggestIndexSearcher(reader).suggest(query, 10, false);
        List<String> keys =
            Arrays.stream(hits.scoreLookupDocs()).map(hit -> hit.key.toString()).toList();
        // expected: [food], the only suggestion with 4 characters; actual: [foo, food]
        assertEquals(List.of("food"), keys);
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-691/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/suggest/build/libs/lucene-suggest-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.suggest.document.TestRegexCompletionEndByte
- Expected vs actual
- Expected
[food]; actual[foo, food]:expected:<[food]> but was:<[foo, food]>(-ea and -da).
More files, environment, full output35 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<[food]> but was:<[foo, food]>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:120)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.search.suggest.document.TestRegexCompletionEndByte.testDotNeedsARealCharacter(TestRegexCompletionEndByte.java:55)- The javadoc: the query "takes a regular expression as the prefix of the query term"; no prefix of
foomatchesfoo.. - The byte the
.takes is reserved:SuggestFieldrejects 0x00 in values. - A committer on a sibling issue: "Completion queries should always match a prefix from the suggestions"; no upstream test pins the current behaviour.
The full argument212 words
- Contract. Class javadoc (
RegexCompletionQuery.java:31-43): "A CompletionQuery which takes a regular expression as the prefix of the query term", with the examplesu[g|b]for "a prefix of 'sug' and 'sub'".CompletionQuerymatches "documents containing terms with a specified prefix" (CompletionQuery.java:32). The introducing issue LUCENE-6459 (#7518): "Return documents with values that match the prefix of a regular expression". - The end byte is internal.
SuggestFieldrefuses 0x00 in values as "a reserved character" (SuggestField.java:86-96,:140-149). - Same concern elsewhere. A TODO in
FuzzyCompletionQuery(:177-181): "We probably don't want to allow the trailing dedup bytes to be edited". On #9335, @jimczi: "Completion queries should always match a prefix from the suggestions". - Consistency.
PrefixCompletionQueryreturns[foo, food]forfoo; LUCENE-8287 already aligned the empty regex withPrefixCompletionQuery(RegexCompletionQuery.java:90-91). - Tests.
TestRegexCompletionQueryuses only[a|w|s]s?ugg, the empty regex,[a|s][d|u|s][u|d|g]and[a|s][d|u|s][u|g], none of which can run past a suggestion; the 236 upstreamlucene/suggesttests run with 0 failures with the fix. - History. The unchanged automaton came with the class (LUCENE-6459, 2015); the FST layout with the end byte is older (LUCENE-6339, 5.1.0), when only a prefix lookup on the analyzed key existed. No later commit, issue comment or test that was found discusses or changes it.
The devil's-advocate check206 words
Strongest case (built by the devil's advocate and by the lenses of the reviewer from another model family; all rated it weak): the API is @lucene.experimental; the regex already runs over raw FST byte labels rather than characters (#9526: non-ASCII patterns do not match); the expert CompletionWeight javadoc speaks of "every partial path in the index that matched the query automaton" (CompletionWeight.java:66); and a literal U+0000 in the pattern works today as an end anchor ("foo\u0000" returns only foo).
Why it fails: the natural reading of every public description (the class javadoc, the LUCENE-6459 text, the committer quote) is a prefix of the analyzed suggestion; none of them exposes the end or dedup bytes as matchable content (the javadoc literally says "prefix of the query term"), and the end byte is a marker no value may contain. The trigger is ordinary regex syntax with the default flags. @lucene.experimental allows API changes, not wrong results. The CompletionWeight sentence describes how a match is reported, not which inputs should match. The U+0000 anchor appears in no doc, test or downstream code that was found, and #9526 is a different problem (missing matches) whose natural fix, a UTF32ToUTF8 conversion, keeps U+0000 in ..
Recommended Keep the regex off the reserved bytes in RegexCompletionQuery
In RegexCompletionQuery.createWeight, intersect the regex automaton with "any code point except U+0000, repeated" before determinizing (+8/-1). The reserved end and dedup bytes become unreachable, while the token separator stays matchable. The new test then passes 8 of 8, and the whole lucene/suggest module passes with assertions on and off.
        getTerm().text().isEmpty()
            ? Automata.makeEmpty()
            : Operations.determinize(
-                new RegExp(getTerm().text(), flags).toAutomaton(), determinizeWorkLimit);
+                // each suggestion is stored as its analyzed form, the reserved END_BYTE (0x00)
+                // and dedup bytes: the regex must match the analyzed form, never those bytes
+                Operations.intersection(
+                    new RegExp(getTerm().text(), flags).toAutomaton(),
+                    Operations.repeat(
+                        Automata.makeCharRange(
+                            NRTSuggesterBuilder.END_BYTE + 1, Character.MAX_CODE_POINT))),
+                determinizeWorkLimit);
All options and trade-offs4 options · 770 words
One fix was built and validated with gradle; the alternatives were not run.
Keep the regex off the reserved bytes in RegexCompletionQuery (validated by the checks) (recommended)
The dedup bytes always follow END_BYTE, so an automaton that cannot read 0x00 reaches neither. Suggestion values cannot contain 0x00, so with ordinary analyzers no real match is lost. It also makes U+0000 unmatchable anywhere in the analyzed form: SuggestField checks the raw value, not the analyzer's output, so an analyzed form with U+0000 from custom analysis can no longer be matched through that byte (untested). The determinize work limit still applies.
        getTerm().text().isEmpty()
            ? Automata.makeEmpty()
            : Operations.determinize(
-                new RegExp(getTerm().text(), flags).toAutomaton(), determinizeWorkLimit);
+                // each suggestion is stored as its analyzed form, the reserved END_BYTE (0x00)
+                // and dedup bytes: the regex must match the analyzed form, never those bytes
+                Operations.intersection(
+                    new RegExp(getTerm().text(), flags).toAutomaton(),
+                    Operations.repeat(
+                        Automata.makeCharRange(
+                            NRTSuggesterBuilder.END_BYTE + 1, Character.MAX_CODE_POINT))),
+                determinizeWorkLimit);
Trade-offs
- Removes an undocumented trick: a literal U+0000 in the pattern acted as an end anchor (
"foo\u0000"returned[foo], now[]). No doc, test or downstream code using it was found; one sentence in the PR is enough. - Analyzer output: an analyzed form that contains U+0000 (custom analysis only) can no longer be matched through that byte (
SuggestField.java:86-98checks the value,:103-105wraps the analyzer's stream unchecked). Untested. - Coverage: only
RegexCompletionQueryis fixed; a customCompletionQuerythat builds its own "any character" automaton would still reach the internal bytes. - Cost: one intersection per query with an automaton of one live state (a [U+0001, U+10FFFF] self-loop), before the determinize that already runs; not benchmarked.
- Index and backport: query-side only, no reindexing. 10.5.2 has the identical
createWeightexpression; 9.12.3 builds it withtoAutomaton(determinizeWorkLimit), so a 9.x backport needs a slightly different patch. Only main was built and tested with gradle.
What the checks validated
- Gradle, scratch worktree at
a9779ef3c193, JDK 25: the new test fails 5 of 8 on stock and passes 8 of 8 with the fix; the seven closest suites (the new test,TestRegexCompletionQuery,TestContextQuery,TestPrefixCompletionQuery,TestFuzzyCompletionQuery,TestSuggestField,TestContextSuggestField) pass 66 of 66; the wholelucene/suggestmodule, 32 suites and 244 tests (7 skipped), passes with assertions on and off;:lucene:suggest:check -x testpasses (google-java-format, ecjLint, forbiddenApis). - Standalone runner with the fix: the new test 8/8 (assertions on and off), the independent reproducer's 8/8, the devil's advocate's 7/7, the finder's 4/4, and the
ContextQueryand keep-behaviour probes 4/4 (foo baris still returned forfoo.). - With the finder's identical change, the bounded-exhaustive harness loses the whole end-byte mismatch class, while the separate #9335 class stays. (That run also had another unit's unrelated fuzzy-query fix shadowed in; the end-byte class is regex-only, so the attribution holds.)
Make "a query automaton never consumes END_BYTE" a property of the suggester: intersect in the CompletionWeight constructor, or stop NRTSuggester.lookup's prefix walk at 0x00. Also covers custom CompletionQuery subclasses and FuzzyCompletionQuery, whose TODO raises the same concern.
Trade-offs
FSTUtil is shared with AnalyzingSuggester; the walk needs a deterministic automaton, and the product of two deterministic automata stays deterministic, so a central intersection needs a new determinize only when its input is not already deterministic; it cannot treat every 0x00 label as END_BYTE, because context values are checked only for U+001D (ContextSuggestField.java:166-178, ContextQuery.java:128-139) and custom analysis may emit U+0000, so it must find the real end of the analyzed form (for example after the context prefix); it touches every completion query, so it needs the fuzzy and context suites and a benchmark. A design choice for the committers.
Say in the javadoc that . and negated classes can match past the end of a suggestion.
Trade-offs
No code change; every affected pattern stays wrong, including those that downstream regex options pass through.
Use a class that excludes U+0000, a literal NUL character in the Java string: foo[^\u0000] for foo., and foo[^x\u0000] for foo[^x]. Applications can rewrite user patterns this way, or subclass RegexCompletionQuery with the fix above.
Trade-offs
Every place that builds a pattern must do it; a pattern written by a user still needs rewriting.
What the checks validated
On stock main with assertions off: foo[^\u0000] and foo[^x\u0000] give [food] (also with n = 1), foo[^\u0000][^\u0000] gives [] (also over five copies of foo), and fo[^\u0000] still gives [foo, fox, food].
Two downstream engines' completion suggesters pass a user's regex to RegexCompletionQuery unchanged, so, by code reading (not run on those engines), their regex suggestions would get the same extra, too-short results.
Bounded-exhaustive translation validation: the real suggester was compared with a small reference ("a suggestion matches when some prefix of it matches the regex") on every suggestion of 1 to 3 letters over {a, b, c} and 40 patterns. One class of mismatches was explained, every time, by the pattern consuming the end byte, and vanished with the fix.
The method in full159 words
Method: bounded-exhaustive translation validation (semi-formal tier). Leg A of the harness compared the stock main jar with an independent reference evaluated with java.util.regex, over every suggestion of length 1 to 3 over {a, b, c} as its own document, 1 to 3 segments and index sort, SuggestField and ContextSuggestField, 40 RegexCompletionQuery patterns with RegExp.ALL and RegExp.NONE, and num 1, 3 and 200: 2,085,120 checks per run over all completion query kinds, with assertions on and off.
- Class REGEX-END-BYTE (16 plain and 88
ContextQuerychecks) was explained in every case by "the pattern may also consume the 0x00 end byte" and disappeared with the fix shadowed in. - The separately classified, known #9335 class (184
ContextQuerychecks) stayed with the fix. - The finding was reduced to a public-API JUnit on the stock main jars, then checked by a reviewer from another model family (OpenAI GPT-5.6) in lenses, an independent reproducer, a devil's advocate, an adjudication and an audit.
No prior report found (searched 2026-10-27): GitHub issues, PRs and commits, the changed files of all 409 open PRs, downstream engines, the mailing lists, JIRA and the web. The nearest item, #9335 (open since 2018), is a separate sibling bug: inside ContextQuery a . eats a different internal marker and trips an assertion.
Searches3 searches
Verdict new: a separate bug, not a partial overlap. #9335 / LUCENE-8288 is in the same family (a wildcard consuming an internal marker of the completion FST), but it is a different defect: a different marker (0x1F after the context), path (ContextQuery only), symptom (an assertion) and fix. Its text never mentions the end byte, the dedup bytes, plain RegexCompletionQuery or a . at the end of a pattern, and its repro patch adds a plain-query test with . that passes. Neither fix covers the other: with the fix here, the bounded-exhaustive harness still counts all 184 #9335 checks, and #9335's patch touches only ContextQuery. Related: #9526 / LUCENE-8480 (regex over code points against UTF-8 bytes; a UTF32ToUTF8 fix would keep U+0000 in .).
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene GitHub issues, PRs and commits; apache/lucene-solr, apache/solr, Lucene.NET and two downstream engines | 2026-10-27 | three runs of a scripted prior-report search (114, 282 and 1443 hits) plus 50 manual searches, GraphQL and code searches | no report; nearest #9335 / LUCENE-8288 (sibling), #9526 / LUCENE-8480, #9334 / LUCENE-8287 (empty regex, fixed), #7518 / LUCENE-6459 (introducing issue, 23 comments, none on the end byte) |
| Open apache/lucene PRs | 2026-10-27 | changed-file lists of all 409 open PRs | none touches the fix site; #16847 only renames calls in NRTSuggester |
| Mailing lists, JIRA, web and forums | 2026-10-27 | 15 queries on dev@, java-user@ and issues@; 6 JIRA queries over LUCENE and SOLR; 12 web and Q&A searches; two downstream forums | no report; only notification mails of the issues above and unrelated syntax questions |
Present since RegexCompletionQuery was added (LUCENE-6459, be4d58c7740, 2015-05-28), first released in 5.3.0. The same failure was executed on 22 releases from 5.3.0 to 10.5.2 and on main; it was never fixed.
Versions tested6 rows
Introduced by be4d58c7740b (trunk, svn r1682158, 2015-05-28, "LUCENE-6459: add common suggest API for document based NRT suggester", no PR) and the branch_5x backport 380bb29f3959 (same day), which created RegexCompletionQuery with the unchanged automaton. The FST layout with the end byte came earlier (LUCENE-6339, 5.1.0), when the only public lookup was a prefix lookup. Later edits to createWeight (LUCENE-8287, LUCENE-10010, LUCENE-10296) left this unchanged. Upstream main a95c754ee003 and branch_10x have no fix. All 94 release tags from 5.3.0 to 10.5.2 that the release-tag clone holds have the unchanged automaton and END_BYTE = 0x0. The clone lacks 8.8.2 to 8.11.4; all nine of those were executed (8.11.4 in the follow-up, the other eight in the fact check).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's test fails 5 of 8 (gradle and standalone, assertions on and off); passes 8 of 8 with the fix |
| 10.5.2 | affected | this doc's test fails 5 of 8, assertions on and off |
| 5.3.0, 5.3.2, 5.5.5, 6.0.0, 6.6.6, 7.0.0, 7.7.3, 8.0.0, 8.4.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0 | affected | the history probe fails the same 3 of 3 checks (5.3.0 also with assertions off); control passes |
| 8.8.2, 8.9.0, 8.10.0, 8.10.1, 8.11.0, 8.11.1, 8.11.2, 8.11.3 | affected | the history probe fails the same 3 of 3 checks with assertions off; control passes (run by the fact check: these tags are missing from the release-tag clone) |
| 5.3.0 with the fix applied | causality | the probe passes: [food], [food], [] |
| 5.2.1 | not affected | no RegexCompletionQuery: the probe does not compile |
Confirmed by a reviewer from another model family (OpenAI GPT-5.6) in lenses, an independent reproducer, a devil's advocate, an adjudication and a credibility audit, each with its own test and passing controls except the adjudication, which re-ran the reproducer's test with new seeds. Gradle re-ran this doc's test and fix on main; fact checks re-checked the doc.
Checks and verdicts360 words
Each check except the adjudication wrote and ran its own test on the stock jars; the controls (fo., foo.*, bar[kn], three copies of a suggestion, PrefixCompletionQuery) pass everywhere.
| Check | Verdict | What it found |
|---|---|---|
| cross-model review, refute lens | real, high; intended argument weak | Own JUnit ab. over ab and abc fails with assertions on and off, and so does a plain main(); the fix passes 58 suggest/document tests. |
| cross-model review, intended lens | real, high; intended argument weak | Own test fails 3 of 5 (for example [cat, cats] instead of [cats]) on main and 10.5.2; 5 of 5 with the fix. |
| Independent reproducer | real | Own 8-test JUnit outside the package (bar/10, bark/3, barn/2): 5 of 8 fail on main, 10.5.2 and 9.12.3, assertions on and off; ran the dedup-byte path; 8 of 8 with the fix. |
| Devil's advocate | real, high; no intended argument survives | foo.+ gives [foo, food]; foo. with n = 1 gives [foo]; found the literal U+0000 anchor that the fix removes; 7 of 7 with the fix. |
| adjudication | confirmed, high | Re-ran the independent reproduction's test with new seeds (5 of 8 fail, assertions on and off; 8 of 8 with the fix) and the finder's repro with assertions off. |
| credibility audit | keep | Own plain main() with CompletionAnalyzer(StandardAnalyzer): 4 mismatches on main and 10.5.2 with assertions off, 0 with the fix. |
| this doc | confirmed | New 8-test JUnit through gradle and the standalone runner; the fix through the whole module; the ContextQuery path in a JUnit; the workaround. |
| fact check of this doc | ok, no errors | Re-ran the gradle command with assertions on and off, the standalone runner (main, 10.5.2, the fix) and the whole module with the fix; ran foo.?, foo.{1}, foo.+ and the history probe on eight more 8.x releases. |
| cross-model fact check (OpenAI GPT-5.6, read-only) | bug real; wording errors fixed | Found 3 errors, 7 overclaims and 4 missing caveats in the wording (none disputes the bug or the fix); all were addressed in this version, and the duplicate-suppression caveat was run. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 404 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,769 words
- Registry title
- RegexCompletionQuery lets '.' and negated character classes match the document suggester's internal end byte (0x00), so a suggestion one character shorter than the pattern is returned ('foo.' returns foo as well as food, 'foo..' returns food)
- Area
- suggest / document (NRT) suggester (RegexCompletionQuery automaton intersected with the NRTSuggester FST, including the internal END and dedup bytes; also inside ContextQuery)
- Priority
- Medium, rank 49: In the opt-in document suggester, a regex with a trailing '.' or a negated class quietly returns a non-matching suggestion that can push the only correct one out of the top n, which is on par with LFV-660 (too few results) and worse than the score-only LFV-254, so it goes between them.
- Impact class
- silent wrong results
- Impact note
- Hits applications that use the document suggester (SuggestField with a completion postings format) with RegexCompletionQuery, directly, inside a ContextQuery or through a downstream completion suggester's regex option, whenever the pattern can match one more character than a whole suggestion has (a trailing '.', '.+', '.{n}' or a negated class such as [^x]; patterns that can match zero characters there, such as 'foo.*' or 'foo.?', are unaffected): the too-short suggestion is returned, is often the highest weighted and can push the only correct suggestion out of the top n ('bar.' with n=1 gives [bar] instead of [bark]); two or more extra characters leak only when four or more entries share one analyzed form in one segment; deterministic with the stock codec and analyzers, -ea and -da, at any scale, in every release from 5.3.0 to 10.5.2 and on main; nothing throws, and filters, deleted documents and contexts are still honored.
- Summary
- You run a RegexCompletionQuery, which 'takes a regular expression as the prefix of the query term', over the suggestions foo (weight 5), food (1) and fox (2), and expect 'foo.' and 'foo[^x]' to return only food (the only suggestion with a matching four-character prefix) and 'foo..' to return nothing (no suggestion has five characters). Instead 'foo.' and 'foo[^x]' return [foo, food] with foo ranked first, and 'foo..' returns [food]. The document suggester stores every suggestion in its FST as the analyzed text followed by an internal end byte 0x00 and dedup bytes, and RegexCompletionQuery hands the regex automaton, whose '.' and negated classes include U+0000, to the FST intersection unchanged, so the pattern runs past the end of the suggestion into these internal bytes.
- Introduced
- be4d58c7740bea4e797eb1acff6355eb260e7c93 (trunk, svn r1682158, 'LUCENE-6459: add common suggest API for document based NRT suggester'; issue LUCENE-6459 = apache/lucene#7518; CHANGES credits Areek Zillur via Mike McCandless; svn era, no pull request) and the branch_5x backport 380bb29f39595de1c3947075296d1d0a36f02fd8 (svn r1682170, same day): the commit that created RegexCompletionQuery already passed new RegExp(text, flags).toAutomaton() unchanged to CompletionWeight, over an FST whose inputs already ended in END_BYTE 0x00 plus dedup bytes. Design origin, not the bug: that FST layout and the reservation of 0x00 in suggestion values come from LUCENE-6339 (b7adb6ac7704, 2015-03-27, apache/lucene#7400, release 5.1.0), whose only public lookup was a prefix lookup on the analyzed key, so no wildcard could reach the end byte before LUCENE-6459 [read: git log and blame in the full-history clone; git log -S END_BYTE on suggest/document finds only LUCENE-6339 and LUCENE-6459; the later createWeight changes 0159e4b974b (LUCENE-8287, empty regex), 84e4b85b094 (LUCENE-10010) and 7a872c7a5c0 (LUCENE-10296) leave this unchanged; exec: the candidate fix shadowed into the 5.3.0 RegexCompletionQuery turns the 5.3.0 history probe from fail into pass]; not a regression: the bug is as old as the class (2015-05-28 (trunk be4d58c7740 and branch_5x backport 380bb29f395, same day))
- First affected version
- 5.3.0 [exec: the history probe fails 3 of 3 checks with -ea and -da, control passing; CHANGES.txt lists LUCENE-6459 under 'Lucene 5.3.0 / New Features'; tag date 2015-08-20]; 5.2.1 and older have no RegexCompletionQuery or CompletionQuery, so the probe does not compile [exec]. Correction to the candidate's and judge's 'since 5.2': the branch_5x backport 380bb29f395 is not an ancestor of the 5.2.1 tag
- Affected versions
- every release that has RegexCompletionQuery: 5.3.0-5.5.5, 6.0.0-6.6.6, 7.0.0-7.7.3, 8.0.0-8.11.4, 9.0.0-9.12.3, 10.0.0-10.5.2, and main a9779ef3c193 (unreleased 11.0) [exec: the version-portable history probe fails the same 3 of 3 checks, with its control passing, on 5.3.0 (-ea, -da), 5.3.2, 5.5.5, 6.0.0, 6.6.6, 7.0.0, 7.7.3, 8.0.0, 8.4.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 (-ea, -da) and main (-ea, -da), across the completion postings formats Completion50, Completion84, Completion90, Completion912 and Completion104; the finder's JUnit fails 3 of 4 on main, 10.5.2 and 9.12.3; the independent reproduction's test fails 5 of 8 on main, 10.5.2 and 9.12.3 with -ea and -da]; the releases in between [read: code-identity check of all 94 release tags from 5.3.0 to 10.5.2 in the release-tag clone (no intersection, char-range or END_BYTE handling in RegexCompletionQuery, END_BYTE = 0x0 in NRTSuggesterBuilder), 0 differ; 8.8.2-8.11.4 are missing from that clone and 8.11.4 was executed]. Not affected: 5.2.1 and older (no such API) [exec on 5.2.1]. Not fixed upstream: upstream main a95c754ee003 (2026-10-26) and branch_10x have no fix, and no open PR touches the fix site (2026-10-27) [read]. Executed on Linux aarch64 with JDK 25 only.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check; also reached by code reading
- Upstream and prior reports
- none found (2026-10-27, read-only; the prior-report record verdict new; the finder's scripted prior-report search found nothing either): three scripted prior-report searches (16 to 30 GitHub queries each plus commit, downstream, mailing-list, JIRA and web queries; 114, 282 and 1443 hits, none about this defect), 50 manual GitHub issue and PR searches over apache/lucene, apache/lucene-solr, apache/solr, Lucene.NET and two downstream search engines, GitHub GraphQL and code searches, the file lists of all 409 open apache/lucene PRs, the commit history of the suggest/document files, 15 list queries on dev@, java-user@ and issues@, 6 JIRA queries, 12 web and Q&A searches and two downstream forums. Nearest items, none the same bug: #9335 / LUCENE-8288 (open since 2018: inside ContextQuery a regex '.' consumes the optional separator label 0x1F after the context and trips an assertion; same family, a wildcard consuming an internal marker label, but a different marker, position, query path, symptom and fix, and neither fix covers the other; on it a committer wrote 'Completion queries should always match a prefix from the suggestions'), #9526 / LUCENE-8480 (open: the regex automaton is over code points while the FST holds UTF-8 bytes, so non-ASCII patterns fail; its UTF32ToUTF8 fix keeps U+0000 in '.', so it would not fix this), #9334 / LUCENE-8287 (empty regex in ContextQuery, fixed), #7518 / LUCENE-6459 (the introducing issue; none of its 23 comments discusses the end byte), and downstream completion-suggester issues about empty regexes, Unicode, request syntax and duplicates. Not fixed upstream (main a95c754ee003, branch_10x). Gaps: GitHub's search rate limit and the web search were throttled a few times (queries retried or replaced); PR review comments, private reports and chat are not searchable.
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-27) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the release jars 10.5.2 (this doc's test, on and off) and, in the history probe, 5.2.1 (no such class) and 22 releases from 5.3.0 to 10.5.2 (affected; 14 in the follow-up, the eight 8.x releases missing from the release-tag clone in the fact check). The fact check also ran the gradle command with assertions off (same five failures). The fix was validated in the scratch worktree: the new test, the seven closest suites (66 tests), the wholelucene/suggestmodule (244 tests, 0 failures, 7 skipped) with assertions on and off, and:lucene:suggest:check -x test.
- Finding record
lucene/suggest/src/java/org/apache/lucene/search/suggest/document/RegexCompletionQuery.java:31-43 (at a9779ef3c193) (class javadoc: 'A CompletionQuery which takes a regular expression as the prefix of the query term', example su[g|b] for the prefixes 'sug' and 'sub'; @lucene.experimental at :43), :86-97 (createWeight: Operations.determinize(new RegExp(getTerm().text(), flags).toAutomaton(), determinizeWorkLimit) passed unchanged to CompletionWeight)lucene/suggest/src/java/org/apache/lucene/search/suggest/document/NRTSuggesterBuilder.java:43 (at a9779ef3c193) (END_BYTE = 0x0), :66-69 (startTerm appends the end byte to every analyzed form), :81-97 (finishTerm appends one or more dedup bytes, a new one after maxNumArcsForDedupByte entries)lucene/suggest/src/java/org/apache/lucene/search/suggest/document/SuggestField.java:140-149 (at a9779ef3c193) (isReserved: SEP_LABEL, HOLE_CHARACTER and END_BYTE are reserved in suggestion values)lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/FSTUtil.java:52-125 (at a9779ef3c193) (intersectPrefixPaths follows every FST arc the automaton accepts and reports accepted nodes as prefix paths)lucene/suggest/src/java/org/apache/lucene/search/suggest/document/NRTSuggester.java:131-132 (at a9779ef3c193) (FSTUtil.intersectPrefixPaths(scorer.automaton, fst)), :230-256 (each prefix path seeds the TopNSearcher, which completes it to the suggestions below that node)lucene/core/src/java/org/apache/lucene/util/automaton/RegExp.java:695-696 (at a9779ef3c193) (REGEXP_ANYCHAR -> Automata.makeAnyChar()) and Automata.java:105-107 (makeAnyChar = [U+0000, U+10FFFF])lucene/suggest/src/java/org/apache/lucene/search/suggest/document/FuzzyCompletionQuery.java:176-181 (at a9779ef3c193) (TODO: 'We probably don't want to allow the trailing dedup bytes to be edited')lucene/suggest/src/test/org/apache/lucene/search/suggest/document/TestRegexCompletionQuery.java:70, (at a9779ef3c193) 97, 129, 166, 197 (upstream patterns '[a|w|s]s?ugg', '', '[a|s][d|u|s][u|d|g]', '[a|s][d|u|s][u|g]': none can run past the end of a suggestion)
- The finding in 30 seconds
lucene/suggest/src/java/org/apache/lucene/search/suggest/document/RegexCompletionQuery.java:31-43 (at a9779ef3c193) (class javadoc, @lucene.experimental), :61 (RegExp.ALL), :92-97 (createWeight)lucene/core/src/java/org/apache/lucene/util/automaton/RegExp.java:695-696 (at a9779ef3c193) (REGEXP_ANYCHAR), :1299-1302 (negated class); Automata.java:104-107 (makeAnyChar)lucene/suggest/src/java/org/apache/lucene/search/suggest/document/NRTSuggesterBuilder.java:43 (at a9779ef3c193) (END_BYTE = 0x0), :66-69 (startTerm), :81-97 (finishTerm dedup bytes), :124-134 (maxNumArcsForDedupByte)lucene/suggest/src/java/org/apache/lucene/search/suggest/document/SuggestField.java:86-96, (at a9779ef3c193) :140-149 (isReserved: END_BYTE)lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/FSTUtil.java:52-126 (at a9779ef3c193) (intersectPrefixPaths)lucene/suggest/src/java/org/apache/lucene/search/suggest/document/NRTSuggester.java:131-132, (at a9779ef3c193) :207, :230-253 (lookup, accept, addStartPaths with allowEmptyString false); lucene/core/src/java/org/apache/lucene/util/fst/Util.java:284lucene/suggest/src/java/org/apache/lucene/search/suggest/document/CompletionScorer.java:82-92 (at a9779ef3c193) (accept); CompletionAnalyzer.java:69-99 (preserveSep, position increments, graph expansions)
- Who is affected
lucene/suggest/src/java/org/apache/lucene/search/suggest/document/RegexCompletionQuery.java:43 (at a9779ef3c193) (@lucene.experimental)lucene/suggest/src/java/org/apache/lucene/search/suggest/document/NRTSuggester.java:142-144 (at a9779ef3c193) (topN = count * prefixPaths.size(), queue size), :292-301; PrefixCompletionQuery.java:73-75; CompletionQuery.java:141-153 (validate rejects U+001E and U+001F only)
- Why it looks unintended
lucene/suggest/src/java/org/apache/lucene/search/suggest/document/RegexCompletionQuery.java:31-43, (at a9779ef3c193) :90-91; CompletionQuery.java:32; CompletionWeight.java:66; SuggestField.java:86-96, :140-149; FuzzyCompletionQuery.java:177-181lucene/suggest/src/test/org/apache/lucene/search/suggest/document/TestRegexCompletionQuery.java (at a9779ef3c193) (patterns)
- Suggested fix
lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/FSTUtil.java:53 (at a9779ef3c193) (assert deterministic)lucene/suggest/src/java/org/apache/lucene/search/suggest/document/SuggestField.java:86-98, (at a9779ef3c193) :103-105; ContextSuggestField.java:166-178; ContextQuery.java:128-139; lucene/core/src/java/org/apache/lucene/util/automaton/Operations.java:392 (intersection)
- TestRegexCompletionEndByte.java (JUnit test):
repro/LFV-691/src/org/apache/lucene/search/suggest/document/TestRegexCompletionEndByte.java(59 lines)
A light, step-by-step picture made in parallel with this doc from an executed probe on main a9779ef3c193 (assertions on and off) and main with the fix shadowed in; every probe value on screen is parsed from the probe output and asserted, and code panels are taken from main. The PNG is the final summary card. Step 8 writes the fix range as makeCharRange(1, ...); the recommended diff writes NRTSuggesterBuilder.END_BYTE + 1. END_BYTE is 0, so both build the same automaton. The values on screen come from the diagram probe, which forces one segment; the repro JUnit named in step 1 indexes the same data with a randomized writer configuration.
assets/LFV-691/bug.png(404 KB)