Stempel stores its stemming rules in a trie of rows; each cell of a row has a patch command and/or a reference to a child row. A merge pass joins compatible rows. Doing that a second time breaks the trie.
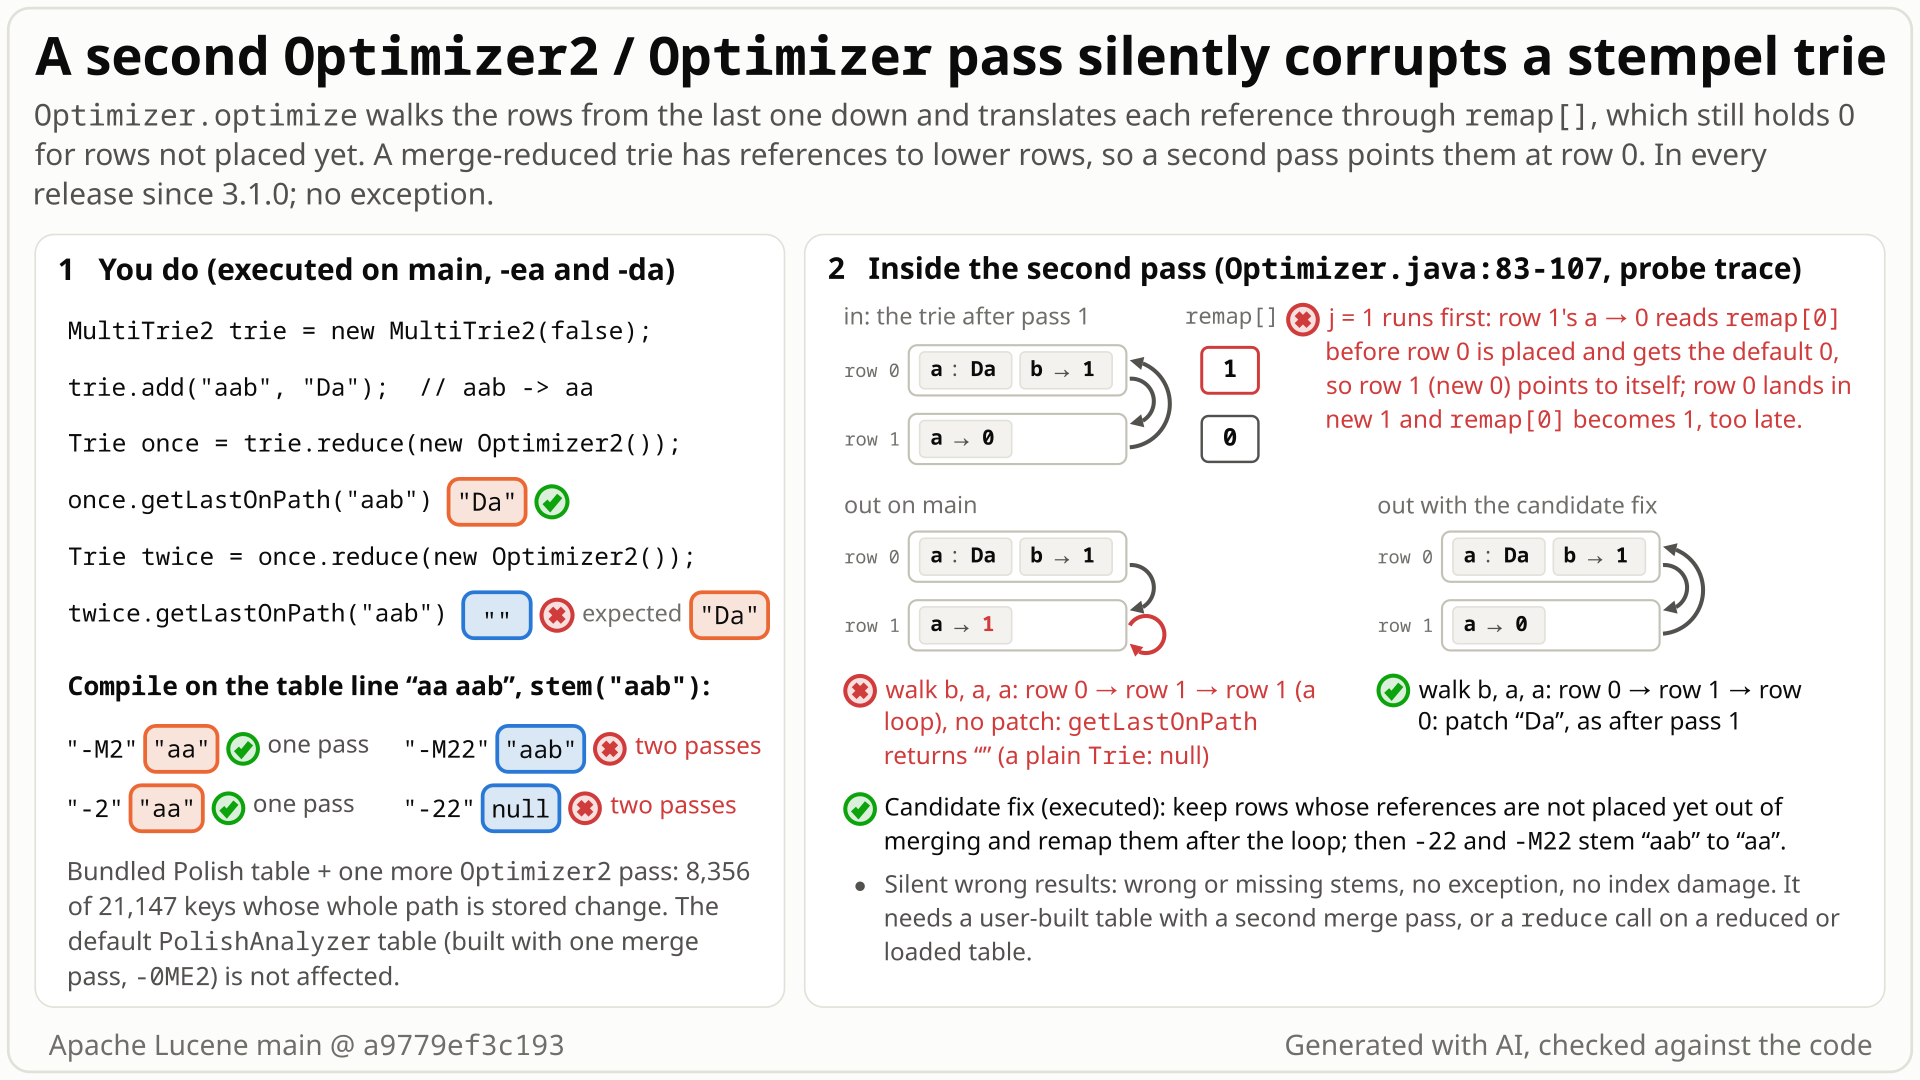
aab -> aa before and after each Optimizer2 pass, and the lookup of aab: Da after one pass, nothing after two. Select the still to open it at full size. Generated with AI, checked against the code.- You build a one-word stemmer trie, read backward like the bundled Polish table:
aabstems toaa(patchDa). OneOptimizer2pass shrinks it from 3 rows to 2, andgetLastOnPath("aab")is stillDa. - You run
Optimizer2again on the result, asCompile -22does, or as code does on a loaded table. You expectDaagain: the javadoc says Optimizer2 keeps "words for which the original trie was built". - You get
null, with no error. After pass 1, row R1 points back to row R0. Pass 2 places rows from the last one down, so it remaps R1's reference before R0 is placed; the unset slot reads 0, R1's own new index. R1 now points to itself, and the walk never reachesDa. - At table scale:
Compile -2and-M2stem all 9 training words of TestCompile's data;-22stems all 9 tonulland-M22returns all 9 unchanged. One more pass over the bundled Polish table changes 8,356 of 21,147 sampled stored keys. - Not affected:
PolishAnalyzerandStempelPolishStemFilterFactoryload the bundled table, compiled with-0ME2(one merge pass) and never reduced again.
Only people who build or modify their own stempel tables: a Compile method string with two merge letters (-22, -M22, -0ME22, -0M11), or reduce(new Optimizer2()) / reduce(new Optimizer()) on a trie a merge pass already reduced, such as the bundled table. One word is enough; no error; every release since 3.1.0. Rare: the recipes found use one merge pass.
Mechanism, terms and numbers726 words
The stempel table compiler Compile shrinks a stemmer trie with reduction passes named by letters (1 = Optimizer, 2 = Optimizer2, the two "merge" passes); the same reducers are public API (Trie.reduce(new Optimizer2())). One merge pass keeps the training words in every case tested. A second merge pass over a trie that a merge pass already reduced can silently corrupt it: Optimizer.optimize (inherited by Optimizer2) walks the rows from the last one down and remaps each child reference through an int[] remap whose slots are read before they are filled (Java zero-fills the new array), so a reference to a row it has not placed yet becomes 0. That is only right when every child row comes after its parent, which holds for a freshly built trie but not for the output of a merge pass. A one-word trie loses its only word; Compile -22 and -M22 lose all 9 training words of TestCompile's data; one more pass over the bundled Polish table changes 8,356 of 21,147 sampled stored keys. No error, with assertions on and off, in every release since 3.1.0. The default PolishAnalyzer and StempelPolishStemFilterFactory are not affected.
- Stemmer trie: stempel stores each training word with a patch command that turns it into its stem (
aab->aaisDa, delete one character). The trie is a list of rows; a row maps a character to a cell with a command and/or a reference to a child row. Polish tables are read backward, from the last character. - Merge passes:
Optimizer(1) andOptimizer2(2) join rows that do not conflict (Optimizer2only when the shared cells are identical) to shrink the table.Compileapplies the reduction letters of its method string in turn: the bundled table used-0ME2.
Optimizer.optimize(Optimizer.java:79-110, inherited byOptimizer2) allocatesint[] remap = new int[orows.size()]and never fills it (:83), so every slot is 0.- It walks the rows from the last one down (
:85) and buildsnew Remap(orows.get(j), remap)(:86), which setsnc.ref = remap[nc.ref]for every child (Reduce.java:121), before rowjitself gets its new index (:94,:100). - On a fresh trie that is right:
Trie.addappends every new row (Trie.java:351-354), so children always come after their parent and are placed first. - A merge pass breaks that order:
removeGapsrenumbers rows in pre-order (Reduce.java:88-102), so a row merged with a deeper row, or shared by several parents, can sit at the same or a lower index than a parent. The bundled table has 31,837 such references. - In a second pass, such a reference reads
remap[child]before the child is placed, gets 0, and points to whichever row was placed first. Row 0 is a real row, not a sentinel (removeGapsuses -1,Optimizer.java:106).
| state | rows | lookup aab (b, a, a) |
|---|---|---|
| fresh | R0 {b -> R1}, R1 {a -> R2}, R2 {a: Da} | Da |
| after pass 1 | R0 {a: Da, b -> R1}, R1 {a -> R0} (R2 merged into R0) | Da |
| pass 2 | R1 is placed first; its reference to R0 reads remap[0] = 0, the new index of R1 itself | |
| after pass 2 | R0 {a: Da, b -> R1}, R1 {a -> R1} (self-loop) | null |
- TestCompile's
testRules.txt(4 lines, 9 training words):-2and-M2stem all 9;-22stems all 9 tonull;-M22returns all 9 unchanged. Compile's statistics after the second pass are identical to those after the first. - Two-word trie {
aa->Da,ab->Db}: after twoOptimizerpassesabreturnsDa. - 2,000 random small tries: about 930 lose a key after two
Optimizer2passes, about 800 after twoOptimizerpasses, none after one pass. - Bundled table plus one more
Optimizer2pass: 8,356 of 21,147 sampled keys whose whole path is stored change their answer (0 with the fix). - An 11-lemma Polish table (94 training forms):
-0ME2stems 93 correctly in every run;-0ME22about two thirds and-0M22almost none (67 and 0 in the finder's run, 63 to 74 and 0 to 3 in later runs; the counts depend on hash iteration order).
Exposure and likelihood234 words
- Who is exposed. People who compile their own stempel tables with a method string that has two of the merge letters
1/2, or whose code callsTrie.reduce(new Optimizer2())orreduce(new Optimizer())on a table loaded withStempelStemmer.loadthat a merge pass built (such as the bundled one) or on any other trie that was already merge-reduced.Optimizer2's javadoc also says the class "allows the stemmer to be self-teaching", which reads like adding words to a table and reducing it again; nobody tested that flow. - Not exposed.
PolishAnalyzerandStempelPolishStemFilterFactoryload the bundledstemmer_20000.tbl(its header names-0ME2, one merge pass) and never reduce it (PolishAnalyzer.java:61, 89,StempelPolishStemFilterFactory.java:50). A table that was never merge-reduced is not affected by one more pass: a-0Mtable reduced once withOptimizer2changes 0 forms. - What it takes. No scale: one word suffices. Not every twice-reduced trie loses a key (about 930 of 2,000 random tries do with
Optimizer2), but every minimal case and every word table tested does. Exact counts vary with hash iteration order (since 9.11.0) and seeds; the failures always occur. - Silent. No exception or warning; the table loads and stems, just wrongly. The same with
-eaand-da. - Likelihood: rare. The recipes found (the bundled
-0ME2, a downstream port's-0ME2) use one merge pass, and the searches found no report since 3.1.0 (2011).
two Optimizer2 passes over the one-word backward trie {aab -> Da} (MultiTrie2, public API) lose the word's patch; a second merge pass on an already merge-reduced trie corrupts it.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.stempel;

import org.apache.lucene.tests.util.LuceneTestCase;
import org.egothor.stemmer.MultiTrie2;
import org.egothor.stemmer.Optimizer2;
import org.egothor.stemmer.Trie;

public class TestOptimizer2SecondPass extends LuceneTestCase {

  public void testTwoOptimizer2PassesKeepTheOnlyWord() {
    MultiTrie2 trie = new MultiTrie2(false);
    trie.add("aab", "Da");
    Trie twice = trie.reduce(new Optimizer2()).reduce(new Optimizer2());
    // expected: the word the trie was built for keeps its patch "Da"; actual: "" (lost)
    assertEquals("Da", String.valueOf(twice.getLastOnPath("aab")));
  }
}
# in a copy of this finding's repro folder (repro/LFV-693/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/analysis/stempel/build/libs/lucene-analysis-stempel-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.stempel.TestOptimizer2SecondPass
- Expected vs actual
- Expected getLastOnPath("aab") = "Da" (Optimizer2 keeps the words the trie was built for); actual "" on main 645d4fe14a2 with -ea and -da.
More files, environment, full output32 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: expected:<[Da]> but was:<[]>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.analysis.stempel.TestOptimizer2SecondPass.testTwoOptimizer2PassesKeepTheOnlyWord(TestOptimizer2SecondPass.java:31)Optimizer2's javadoc promises it keeps "words for which the original trie was built", with no condition on the input.Trie.reduce,OptimizerandOptimizer2are public;Compileruns every method letter in turn, repeats included. Nothing says "one merge pass only".- The bad input is Lucene's own output: the first merge pass creates the backward references (the bundled table has 31,837).
The full argument352 words
- Contract.
Optimizer2.java:60-63: "Information loss, resulting in the stemmer not being able to recognize words (as in Optimizer), is curtailed, allowing the stemmer to recognize words for which the original trie was built."Trie.reduce(Trie.java:361-369): "Remove empty rows from the given Trie and return the newly reduced Trie." Neither states a condition on the input. The module'soverview.html(lines 175-177) says only: "Several optimization steps are applied in turn to reduce and optimize the initial trie", a chain of steps each run on the previous output, with no recipe and no limit. - The API composes reducers.
Trie.reduce,MultiTrie2.reduce,OptimizerandOptimizer2are public in the exportedorg.egothor.stemmerpackage; a reducer returns an ordinaryTrie.Compileapplies every letter1,2,E,L,Gin turn without rejecting repeats (Compile.java:145-171). The method string is case-sensitive and partly positional: a leading-selects a backward trie, then an optional0stores original forms and an optionalMselectsMultiTrie2(Compile.java:88-100); of the rest, only the uppercase letters run a reduction and any other character is skipped (Compile.java:168-169); the "list ... in the package description" its javadoc cites (Compile.java:76-78) does not exist (package-info.java: "Egothor stemmer API."). - Tests.
TestStemmer.assertTrieContentsasserts that each reduction keeps every inserted key, on fresh tries only;TestCompile's methodstest,-testandMtestcontain no reduction letter. No upstream test composes two merge passes. - History. The logic is the 2010 import (LUCENE-2298), never changed; no commit, issue or list thread calls repeated merge passes invalid.
- Optimizer vs Optimizer2.
Optimizer2's javadoc saysOptimizerloses information. But oneOptimizerpass keeps every key of 2,000 random tries and two lose keys in about 800 of them; and with the finder's fix sketch shadowed (the same idea as fix A), the bounded checks' only remaininggetLastOnPathviolations are sequences withLift(false)before anOptimizerpass (E1in the length-2 run;E1,2E1,E21,LE1and others in the length-3 run): the documented loss. The same root cause affects both.
The devil's-advocate check171 words
The intended-behaviour checker's strongest case (moderate; the cross-model reviews rated it weak): these are legacy offline compiler passes with an unstated "fresh trie only" precondition, since Optimizer, Gener and Lift all walk rows downward; every known recipe uses one merge pass; a second pass gains little; and maintainers treat the forked code as frozen (#8841: "I think we should avoid applying these kinds of modifications to forked code").
Why it fails: nothing documents that precondition; the bad input is produced by Lucene's own merge pass and shipped in its own table; on such input Gener's downward walk treats a row it has not visited yet as alive (Gener.java:84) and Lift on the loaded bundled table changes 0 stems, while Optimizer sends the reference to an unrelated row; and the unfilled slot is not a deliberate sentinel (Gener fills its array with 1, alive; removeGaps uses -1, not placed yet). The frozen-fork stance is a triage preference, not a statement of intent. Verdict: not intended, a defect.
Recommended A. Keep rows with unresolved references unmerged and remap them after the loop (validated)
Fix A: in Optimizer.optimize, fill remap with -1, place a row whose reference points to a row not placed yet without merging it, and remap such rows after the loop (+24/-1 in Optimizer.java and Reduce.java). The repro and the whole stempel test task pass; a first pass over a fresh trie gives byte-identical output.
All options and trade-offs3 options · 698 words
Fix A was built and validated in a scratch worktree at a9779ef3c193; options B and C come from the adjudication and the audit and were not built.
A. Keep rows with unresolved references unmerged and remap them after the loop (validated) (recommended)
Reduce.Remap records whether any reference got a negative (unassigned) value. Optimizer.optimize fills remap with -1; a row whose Remap has an unresolved reference is placed as it is, is never used as a merge target, and is remapped once every row has its new index. Every other row goes through the old merge code, except that deferred rows are never merge targets. Same idea as the finder's sketch, written more compactly.
--- a/lucene/analysis/stempel/src/java/org/egothor/stemmer/Optimizer.java
+++ b/lucene/analysis/stempel/src/java/org/egothor/stemmer/Optimizer.java
     int[] remap = new int[orows.size()];
+    Arrays.fill(remap, -1);
+    // Rows are placed from the last one down, so a reference to the same or a lower row is not
+    // resolved yet. A trie that is already reduced has such references: keep those rows unmerged
+    // and remap them once every row is placed.
+    BitSet deferred = new BitSet();

     for (int j = orows.size() - 1; j >= 0; j--) {
-      Row now = new Remap(orows.get(j), remap);
+      Remap now = new Remap(orows.get(j), remap);
+      if (now.unresolved) {
+        remap[j] = rows.size();
+        deferred.set(rows.size());
+        rows.add(orows.get(j));
+        continue;
+      }
       boolean merged = false;

       for (int i = 0; i < rows.size(); i++) {
+        if (deferred.get(i)) {
+          continue;
+        }
         Row q = merge(now, rows.get(i));
@@ after the loop
+    for (int i = deferred.nextSetBit(0); i >= 0; i = deferred.nextSetBit(i + 1)) {
+      rows.set(i, new Remap(rows.get(i), remap));
+    }
--- a/lucene/analysis/stempel/src/java/org/egothor/stemmer/Reduce.java
+++ b/lucene/analysis/stempel/src/java/org/egothor/stemmer/Reduce.java
   class Remap extends Row {
+    /** true if a reference points to a row that has no new index yet (remap value below 0) */
+    boolean unresolved;
@@ in the constructor
           nc.ref = remap[nc.ref];
+          unresolved |= nc.ref < 0;
(plus import java.util.BitSet; full patch: fix-a.diff)
Trade-offs
- A second pass now merges little: one more
Optimizer2pass over the bundled table keeps all 6,815 rows of its 8 sub-tries (stock goes from 6,815 to 6,577 rows, with a corrupted result). The fix makes a second pass safe, not useful. - It touches
Reduce.Remap, whichremoveGapsalso uses (thereunresolvedis never read). KeepingReduceuntouched with a separate scan of each row's cells (the finder's sketch) passes the same tests, but every iteration of a row's cell map advances that map's iteration seed, so the extra scan changes the order in which later code visits the cells, and the output bytes change even for fresh tries: with the finder's sketch shadowed, all 13 identity-probe hashes differ from stock. - Forked code (#8841): a maintainer may prefer B or C.
What the checks validated
- The repro class: 3 of 3 fail on stock (gradle, assertions on and off); with fix A the whole
:lucene:analysis:stempel:testtask passes: 6 classes, 22 tests, 0 failures (assertions on), 6 classes, 22 tests, 0 failures (assertions off). ecjLintMain,ecjLintTest,checkGoogleJavaFormatof the module with fix A and the repro class: pass (a first run flagged one line wrap in the test's javadoc; rewrapped).- The independent reproducer's 10 tests and the finder's 4 pass with fix A; the bundled-table check reports
changed=0of 21,147 stored-path keys. - Byte-identical output on stock and with fix A (SHA-256) for 5,000 random fresh tries after one
Optimizerand after oneOptimizer2pass, and forCompilewith 11 one-merge method strings, including the bundled-0ME2. - The one-word trie: with fix A a second pass returns exactly the pass-1 trie.
Optimizer.optimize throws IllegalArgumentException when a row refers to the same or a lower row, and Compile rejects a second merge letter.
Trade-offs
Turns silent corruption into an error, but blocks re-reducing loaded tables, which fix A handles correctly in the tested cases. Not built.
State in the Optimizer/Optimizer2 javadoc that the input must be a trie built by add and not merge-reduced yet, and document Compile's method letters (the missing "package description" list).
Trade-offs
Cheapest, but Java callers stay exposed to silent corruption. Not built.
Applications that use PolishAnalyzer or StempelPolishStemFilterFactory get the bundled table and are not affected; only code or tooling that compiles or re-reduces its own stempel tables is.
Bounded-exhaustive translation validation: every trie of up to 4 keys over {a,b} (length up to 3), forward and backward, under every sequence of up to two reductions, compared with the unreduced trie (183,540 tries, 21.3M key checks). Every single pass kept every inserted key (by getLastOnPath, the stemmer's lookup); each sequence with two merge passes lost keys on some tries.
The method in full189 words
Method: bounded-exhaustive translation validation on the real jar (the hunt's "semi-formal" tier), unit "stempel trie and diff round trips", main a9779ef3c193, 2026-10-27.
- The harness built every set of at most 4 keys over {a,b} of length at most 3 with 3 commands, forward and backward, and applied every reduction sequence of length at most 2 over {1, 2, L, E, G} and of length 3 over {1, 2, L, E} on tries of at most 3 keys. The reference was the unreduced trie, itself checked against an independent longest-match reference (0 mismatches).
- Result (by
getLastOnPath): every single pass kept the inserted keys; each sequence with two merge passes (11,12,21,22,2E2, ...) lost keys on some tries. With the finder's shadow fix ofOptimizer.optimize(a one-file sketch of the same idea as fix A), all of those violations disappeared; only sequences withLift(false)before anOptimizerpass (E1,2E1, ...: Optimizer's documented loss) remained. - An AI finder then wrote the public-API JUnit and traced the cause; independent AI tools reproduced and judged it (see the checks).
No prior report found (GitHub issues, PRs and commits, JIRA, the Lucene lists, ports and forks; searched 2026-10-27). Closest: #6584, an undiagnosed 2014 report that "optimize" fails on a path that never runs Optimizer. See also #8841 (forked-code stance).
Searches5 searches
Verdict new. #6584 belongs to a sibling bug in Reduce.optimize.
| Where | When | How | Found |
|---|---|---|---|
| Prior-art tool, two runs | 2026-10-27 | 57 queries each over apache/lucene GitHub issues, PRs and commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, JIRA and ingested web results; plus the finder's run (45 completed queries; its 6 web queries stayed pending) | 411 and 167 hits, none about this defect |
| GitHub (apache/lucene), manual | 2026-10-27 | Optimizer2, org.egothor.stemmer, egothor, StempelStemmer, MultiTrie2, -0ME2, stemmer table; every stempel issue and PR title; open PRs touching stempel | no report; no open PR touches lucene/analysis/stempel |
| Related items (read) | 2026-10-27 | #6584, #6569, #8841, #7678, #9465 and the stempel issues | #6584 (LUCENE-5521, open): 'optimize method does not work correctly' after the toUpperCase fix of #6569; that path runs only Lift(false), never Optimizer. #8841: maintainer reply on forked code |
| Ports, forks, downstream | 2026-10-27 | Lucene.NET, buda-base/stemmer, other ports, Elasticsearch, OpenSearch, Solr, the old Egothor tracker | Lucene.NET has the same loop and no report; a fork replaced Optimizer because the optimizers 'give different results' (single-pass loss on unseen words, not this) |
| Mailing lists and JIRA | 2026-10-27 | dev@, java-user@ (all 52 'egothor' mails read), issues@, solr lists; JIRA 'egothor', 'Optimizer' AND 'stempel', 'stemmer table' | no report |
Present since stempel was added (LUCENE-2298, 98c47c57e0a, 2010-05-03); first release 3.1.0 (2011). Fails on all 19 releases run from 3.1.0 to 10.5.2 and on main; the logic never changed.
Versions tested5 rows
Introduced by 98c47c57e0a (trunk, svn r940433, 2010-05-03), "LUCENE-2298: Add stempel, an algorithmic stemmer with included Polish support" (issue #3374; svn era, no PR), the import of the whole org.egothor.stemmer package; the release line got it through the branch_3x backport 58328f03790 (2010-05-06). The StempelStemmer javadoc says the implementation is "taken verbatim from the Egothor project", and a 2010 copy of the original Stempel source has the same loop, so the defect most likely predates Lucene.
Later commits made only cosmetic changes to these lines (for example 8ac26737913 LUCENE-10003 and dbaf97f5dcc #14965) or changed Row's cell map to a hash map (#13420: main commit 6e2a8fc9b75, first released in 10.0.0; the 9.x backport 6f774936ef6 is in 9.11.0), which changes exact counts, not the defect. A code-identity check finds one variant of the four methods in all 131 release tags from 3.1 to 10.5.2 present in the clones, plus main.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's test 3 of 3 fail (gradle and runner, assertions on and off); the probe fails 5 of 5 checks |
| 10.5.2, 9.12.3 | affected | this doc's test 3 of 3 fail (the repro runner, assertions on); the finder's and the reproducer's tests fail too |
| 3.1.0 to 10.0.0 (17 releases: 3.1.0, 3.2.0, 3.6.2, 4.0.0, 4.10.4, 5.0.0, 5.5.5, 6.0.0, 6.6.6, 7.0.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.10.0, 9.11.0, 10.0.0) | affected | the main() probe fails all 5 bug checks (4 on training words; the fifth compares 8 arbitrary words) and passes all 5 controls |
| 3.0.3 | no stempel | the stempel module does not exist; the probe does not compile |
| 3.1.0 and main with the finder's fix sketch shadowed | fix sketch | the probe passes: 0 of 5 bug checks fail |
The finder, an independent reproducer, an intended-behaviour devil's advocate, reviews from another model family (OpenAI GPT-5.6) and an adjudication all ran code and said real; an audit kept it. This doc's gradle runs reproduced it and validated fix A.
Checks and verdicts259 words
Every check executed code. The cross-model reviews ran on main ea57360912ed, whose stempel sources are identical to a9779ef3c193.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Bounded check (183,540 tries); public-API JUnit fails 4 of 4 on main (-ea, -da), 40 of 40 over 10 iterations, and on 10.5.2 and 9.12.3; passes with the shadow fix. |
| refute review (OpenAI GPT-5.6, executed) | real, high | Own public-API test reproduces; traced a lower-row reference turning into a self-loop; the fix also passed TestStemmer and TestPolishAnalyzer; intended argument weak. |
| independent reproducer | real | Own 10-test JUnit: 6 of 10 fail on main (-ea, -da), 10.5.2 and 9.12.3; 4 controls pass; the bundled stored-path oracle (8,356 of 21,147); 10 of 10 pass with the fix. |
| intended-lens review (OpenAI GPT-5.6, executed) | real, high | Structural probe: 0 lower-row references in a fresh trie, 2 after one merge, value lost after the second; intended argument weak. |
| intended-behaviour devil's advocate | real, medium-high | Strongest 'fresh trie only' case rated moderate and rejected; TestCompile data loses 9 of 9 with -22 and -M22; a never-merged table reduced once changes 0 forms. |
| adjudication | confirmed, high | Re-ran the reproducer's test (6 of 10 fail, -ea and -da), with the fix (10 of 10 pass) and the finder's test (4 of 4 fail). |
| audit | keep | Re-ran the finder's test with a new seed (4 of 4 fail, -ea and -da) and an own probe (929 / 786 of 2,000 random tries lose a key after two passes; 0 after one). |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 509 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,756 words
- Registry title
- Stempel: running Optimizer or Optimizer2 on an already merge-reduced trie silently corrupts it, because Optimizer.optimize remaps references to rows it has not placed yet to row 0
- Area
- analysis-stempel / egothor stemmer trie reductions (Optimizer, Optimizer2; Compile tool, Trie.reduce)
- Priority
- Low, rank 461: A second Optimizer or Optimizer2 pass silently corrupts a whole stempel table, but only for self-compiled tables with an undocumented two-merge-pass method string or a re-reduced table while the bundled Polish table is unaffected, matching the custom-dictionary silent-stemming Hunspell profile.
- Impact class
- silent wrong results
- Impact note
- Hits only people who build or modify their own stempel stemmer table, when a trie that a merge pass has already reduced goes through a second Optimizer or Optimizer2 pass (a Compile method string with two of the merge letters 1/2, such as '-22', '-M22' or '-0ME22', or Trie.reduce(new Optimizer()) / reduce(new Optimizer2()) on a loaded or already reduced table); then the failures always occur and need no scale (a one-word table suffices; about half of 2000 random small tries are hit), with -ea and -da, in every release since 3.1.0 (exact counts vary with hash iteration order), and nothing throws: the table loads and stems, but wrongly (Compile '-22' stems every training form of a small table to null, '-M22' leaves them unstemmed, and one more Optimizer2 pass over the bundled Polish table changes 8,356 of 21,147 keys whose whole path is stored); the default PolishAnalyzer and StempelPolishStemFilterFactory load the bundled table (compiled '-0ME2', one merge pass, never reduced again) and are not affected.
- Summary
- You build a stempel table with the Compile tool and a method string that has two merge passes (for example '-M22' or '-0ME22'), or you call reduce(new Optimizer2()) (or Optimizer) on a table that a merge pass already reduced, such as a loaded table; Optimizer2's javadoc says its row joining keeps the stemmer able to 'recognize words for which the original trie was built', so the training words should keep their stems, as they do after one pass. Instead the second pass silently corrupts the trie: two Optimizer2 passes over the one-word trie {aab -> Da} lose its only entry, Compile '-22' stems every training form of a small table to null and '-M22' leaves every form unstemmed (while '-2' and '-M2' are correct), and one more Optimizer2 pass over the bundled Polish table changes 8,356 of 21,147 keys whose whole path is stored. The cause is Optimizer.optimize (inherited by Optimizer2): it walks the rows from the highest index down and remaps every child reference through a remap[] array that is still 0 for rows it has not placed yet, which is only correct when every child has a higher index than its parent; a freshly built trie has that property, but the output of a merge pass does not (shared rows, self-loops, pre-order renumbering).
- Introduced
- 98c47c57e0a54ab4aab9d91dd60c33edef130893 (trunk, svn r940433, 'LUCENE-2298: Add stempel, an algorithmic stemmer with included Polish support', committed by GitHub rmuir on 2010-05-03; issue LUCENE-2298 = apache/lucene#3374, no pull request in the svn era): the import of the whole org.egothor.stemmer package, whose Optimizer.optimize already leaves remap[] unfilled and walks the rows downward; the release line got it through the branch_3x backport 58328f0379049045b325d2082295836a7a50e9ce (svn r941704, 2010-05-06). Not a regression: the code is the Egothor stemmer (the StempelStemmer javadoc says the implementation is 'taken verbatim from the Egothor project'), and the prior-report search found the same loop in a 2010 copy of the original Stempel source, so the defect most likely predates Lucene. Later commits only reformatted these lines (8ac26737913 LUCENE-10003, dbaf97f5dcc #14965) or changed Row's cell map (6e2a8fc9b75 #13420, backport 6f774936ef6) [read: git blame and git log -G remap in the full-history clone; code-identity check over 131 release tags] (2010-05-03 (trunk 98c47c57e0a; branch_3x backport 58328f03790 on 2010-05-06))
- First affected version
- 3.1.0 [exec] (tagged 2011-03-30; the first release with the stempel module, through the branch_3x backport; the trunk commit first shipped in 4.0.0-ALPHA). No release that has the API is unaffected: 3.0.3 has no stempel module [exec: the probe does not compile, packages org.egothor.stemmer and org.apache.lucene.analysis.stempel do not exist].
- Affected versions
- Every release that ships stempel, 3.1.0 to 10.5.2, and main a9779ef3c193; no upstream fix. [exec: the history probe (a main() class, public API that exists from 3.1.0 to main) fails all 5 bug checks with all 5 controls passing on 3.1.0 (-ea and -da), 3.2.0, 3.6.2, 4.0.0, 4.10.4, 5.0.0, 5.5.5, 6.0.0, 6.6.6, 7.0.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.10.0, 9.11.0, 9.12.3, 10.0.0, 10.5.2 (-ea and -da) and main (-ea and -da); with the candidate fix shadowed it passes on 3.1.0 and on main; the finder's JUnit fails 4 of 4 and the independent reproduction's and the intended-behaviour check's own tests fail on 10.5.2 and 9.12.3] [read: a code-identity check of the normalized Optimizer.optimize, Reduce.removeGaps, Reduce.Remap and Optimizer2.merge finds one variant in all 131 release tags from 3.1 to 10.5.2 present in the clones, plus main (tags 8.8.2-8.11.4 are missing from the clones; 8.11.4 was executed); upstream main a95c754ee00, 2 commits ahead of a9779ef3c193, does not touch lucene/analysis/stempel]. Since 9.11.0 (Row cells in a hash map, the #13420 backport) the exact counts differ (the probe's '-0ME22' check changes 31 instead of 27 of 94 Polish training forms); the defect is the same.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (searched 2026-10-27 plus the finder's run, read-only; the prior-report record, verdict new): two scripted prior-report searches of 57 queries each (apache/lucene GitHub issues, PRs and commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, JIRA, ingested web results; 411 and 167 distinct hits, none rated high) plus the finder's 51-query run; manual GitHub searches on apache/lucene (Optimizer2, org.egothor.stemmer, egothor, StempelStemmer, MultiTrie2, '-0ME2', 'stemmer table', every stempel issue and PR title), GitHub-wide and code search, Lucene.NET, three outside ports or forks, Elasticsearch, OpenSearch and Solr, the Lucene and Solr lists and JIRA. No issue, PR, commit, JIRA entry, list thread, downstream report or fork discussion describes a second merge pass (or any merge pass on an already reduced or loaded trie) sending references to unplaced rows to row 0. Closest: #6584 (LUCENE-5521, open since 2014, no patch) 'Egothor Stemmer Bug for Optimizing (removing holes in the rows) for the given Trie' says only that 'optimize method does not work correctly and TestCompile.java throws error' once Compile's ignored toUpperCase (#6569) is fixed; upper-cased, TestCompile's methods 'test', '-test' and 'Mtest' contain only the reduction letter E (Lift(false)), so no Optimizer code runs on that path; it is the anchor of LFV-692, not of this bug (re-read read-only in the registration check). #8841 (LUCENE-7790, open) asks to make Trie.add public; jpountz replied 'I think we should avoid applying these kinds of modifications to forked code' (a maintainer stance, not a defect report). Another contributor's fork (buda-base/stemmer#1, closed 2018) replaced Optimizer because the stock optimizers 'give different results'; its tests concern Optimizer's documented single-pass loss on unseen words, not this defect, and nothing was filed against Lucene. Lucene.NET's Optimizer.cs has the same loop and no report. Not fixed: no open PR touches lucene/analysis/stempel, and upstream main a95c754ee00 (2 commits ahead of a9779ef3c193) does not touch it. Gaps: the list archive search is keyword-based, the original Stempel site is offline, and private reports are not searchable.
- Lucene commit tested
- main
a9779ef3c193(gradle in a scratch worktree, assertions on and off, and the standalone JUnit runner); the release jars 10.5.2 and 9.12.3 with this doc's test; amain()probe on 19 releases from 3.1.0 to 10.5.2 and on main; fix A with the whole:lucene:analysis:stempel:testtask (assertions on and off), lint and format checks, and a byte-identity check on tries without backward references. OpenJDK 25.0.3, Linux aarch64.
- Finding record
a Lucene main checkout lucene/analysis/stempel/src/java/org/egothor/stemmer/Optimizer.java:79-110 (optimize: remap = new int[orows.size()] at :83 left at 0, downward loop at :85, new Remap(orows.get(j), remap) at :86, remap[j] set at :94/:100, removeGaps at :105-107)a Lucene main checkout lucene/analysis/stempel/src/java/org/egothor/stemmer/Reduce.java:88-102 (removeGaps: pre-order renumbering) and :112-127 (Remap: nc.ref = remap[nc.ref] at :121)a Lucene main checkout lucene/analysis/stempel/src/java/org/egothor/stemmer/Optimizer2.java:57-65 (class javadoc: joining rows 'allowing the stemmer to recognize words for which the original trie was built. Use of this class allows the stemmer to be self-teaching.'; extends Optimizer, so it inherits optimize)a Lucene main checkout lucene/analysis/stempel/src/java/org/egothor/stemmer/Compile.java:73-81 (javadoc: args[0] names the algorithm, 'a list is available in the package description'), :104-107 (every char after the flags is a step), :139-172 (letters 1, 2, E, L, G applied in sequence, no repeat check); Trie.java:340-356 (add appends new rows, so children get higher indexes), :361-369 (public reduce, 'Remove empty rows from the given Trie and return the newly reduced Trie'); MultiTrie2.java:195 (public add), :277 (public reduce)a Lucene main checkout lucene/analysis/stempel/src/test/org/egothor/stemmer/TestCompile.java:79, :93, :107 (methods 'test', '-test', 'Mtest': no merge letter); Lucene main ea57360912ed and a Lucene main checkout lucene/analysis/stempel/src are identical (diff -r, registration check)https://github.com/apache/lucene/issues/6584 (read-only gh issue view in the registration check: body 'However optimize method does not work correctly and TestCompile.java throws error', one comment moving the issue to 4.9)
- The finding in 30 seconds
a Lucene main checkout lucene/analysis/stempel/src/java/org/egothor/stemmer/Optimizer.java:79-110 (:83 remap never filled, :85 downward loop, :86 Remap, :94/:100 remap[j], :106 fill -1)a Lucene main checkout lucene/analysis/stempel/src/java/org/egothor/stemmer/Reduce.java:88-102 (removeGaps, pre-order), :112-127 (Remap, nc.ref = remap[nc.ref] at :121)a Lucene main checkout lucene/analysis/stempel/src/java/org/egothor/stemmer/Trie.java:327-359 (add appends rows at :351-354)
- Who is affected
a Lucene main checkout lucene/analysis/stempel/src/java/org/egothor/stemmer/Optimizer2.java:60-63 (javadoc, 'self-teaching')a Lucene main checkout lucene/analysis/stempel/src/java/org/apache/lucene/analysis/pl/PolishAnalyzer.java:61, 89; .../stempel/StempelPolishStemFilterFactory.java:50a Lucene main checkout lucene/analysis/stempel/src/resources/org/apache/lucene/analysis/pl/stemmer_20000.tbl (header bytes: writeUTF '-0ME2')
- Why it looks unintended
a Lucene main checkout lucene/analysis/stempel/src/java/org/egothor/stemmer/Optimizer2.java:60-63; Trie.java:361-369; Compile.java:76-78, 145-171; package-info.java; Gener.java:84; src/java/overview.html:175-177a Lucene main checkout lucene/analysis/stempel/src/test/org/egothor/stemmer/TestStemmer.java:151-168 (assertTrieContents), TestCompile.java:79, 93, 107https://github.com/apache/lucene/issues/8841 (maintainer reply, via the prior-report follow-up)
- Suggested fix
a Lucene main checkout lucene/core/src/java/org/apache/lucene/internal/hppc/CharObjectHashMap.java:110 (seed taken when a map is built), :432-434 (nextIterationSeed, called by each iterator at :463, :530, :588)
- Prior reports
https://github.com/apache/lucene/issues/6584 (read-only, registration check)
- TestOptimizer2SecondPass.java (JUnit test):
repro/LFV-693/src/org/apache/lucene/analysis/stempel/TestOptimizer2SecondPass.java(33 lines)
A step-by-step picture of the one-word example, made in parallel with this doc from an executed trace on main a9779ef3c193.
assets/LFV-693/bug.png(509 KB)