TSTLookup is a suggester that keeps its entries in a ternary search tree, one node per UTF-16 code unit. store() and load() save and reload that tree. An emoji or a CJK Extension B character takes two code units (a surrogate pair), so it becomes two nodes.
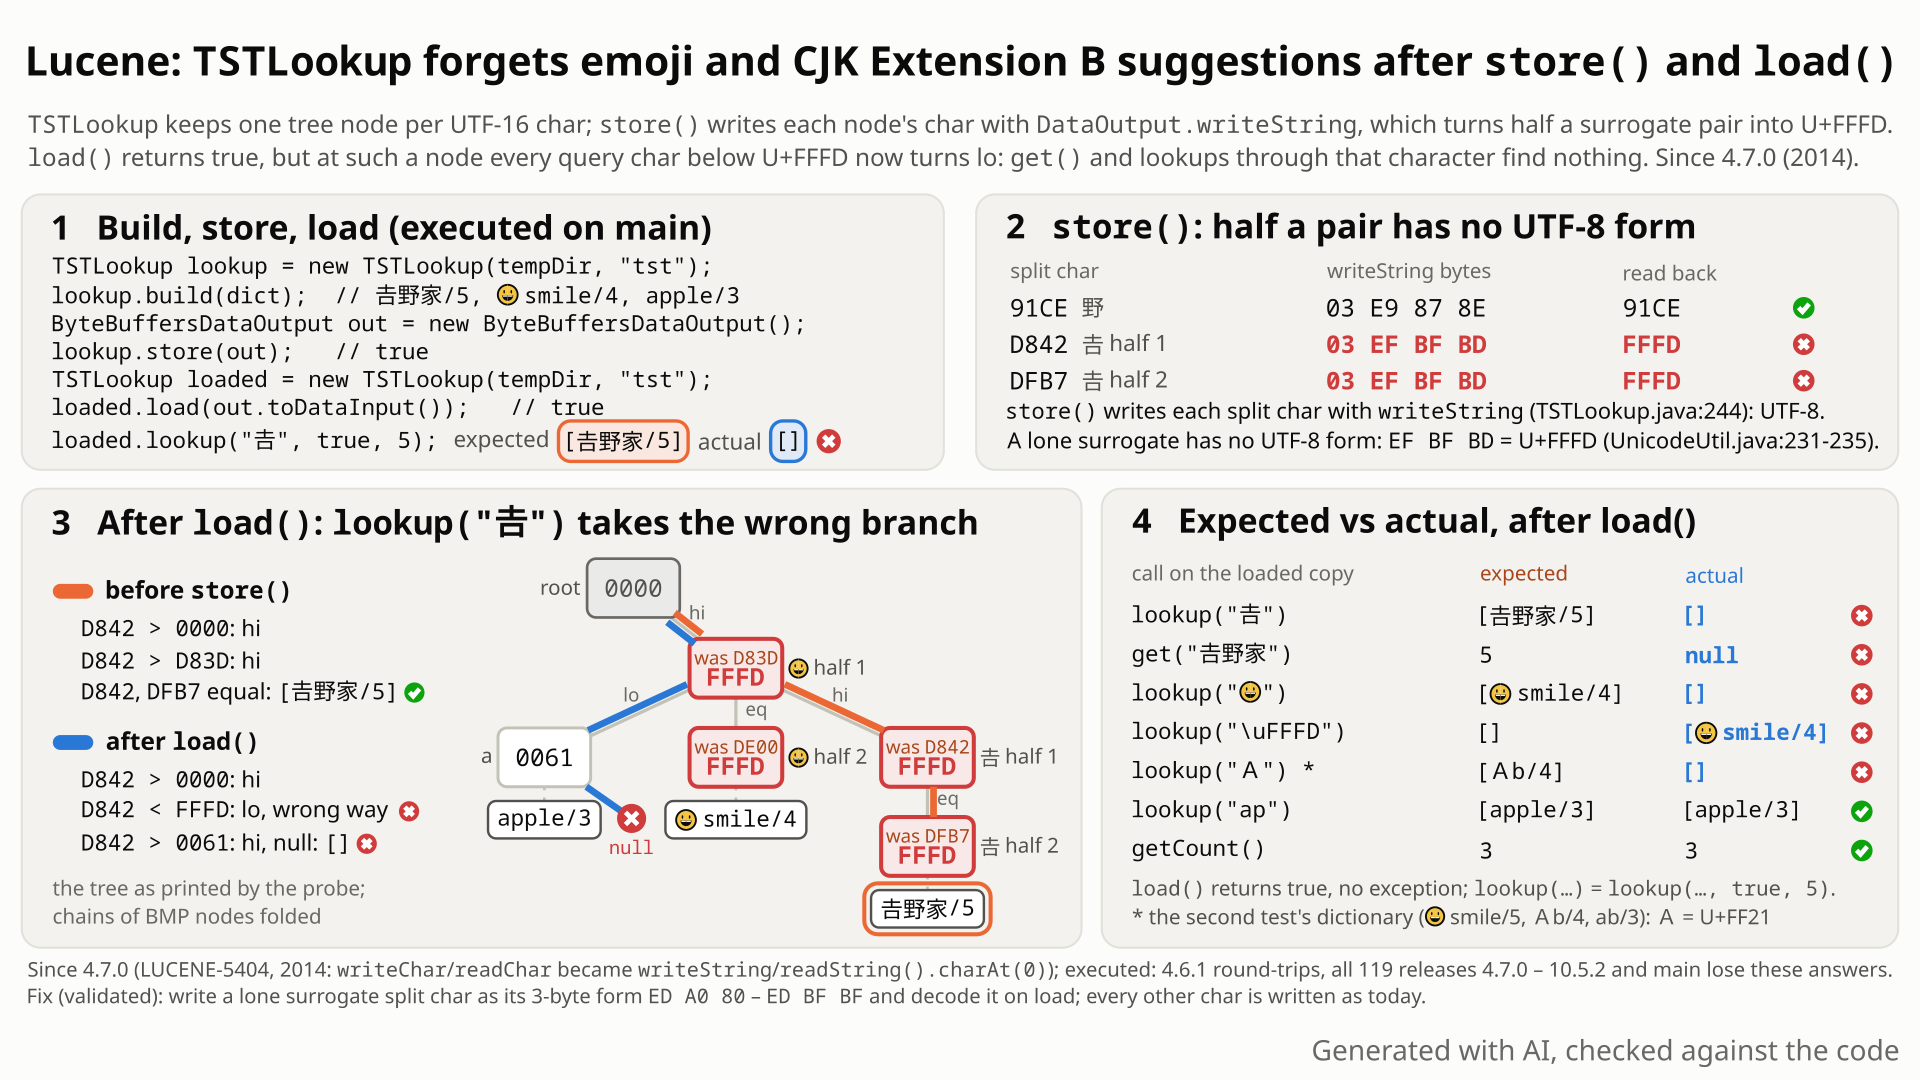
store() writes each half of 😀 and 𠮷 as U+FFFD, and the reloaded search for 𠮷 takes the wrong branch; the recommended fix writes a lone surrogate in a 3-byte form. Select the still to open it at full size. Generated with AI, checked against the code.- Build a
TSTLookupfrom𠮷野家(weight 5),😀 smile(4) andapple(3).lookup("𠮷")returns[𠮷野家/5]andget("𠮷野家")returns 5. - Save it with
store()and read it back withload()into a freshTSTLookup. Both return true;getCount()is still 3 andlookup("ap")is still[apple/3]. - You expect the reloaded copy to answer the same. Instead
lookup("𠮷")andlookup("😀")return[],get("𠮷野家")returns null, andlookup("�")(U+FFFD), empty before, now returns[😀 smile/4]. - Why: the tree has one node per UTF-16 unit, so 𠮷 is two nodes,
D842andDFB7.store()writes each node's char as its own UTF-8 string; half a pair has no UTF-8 form, so both are saved as U+FFFD. Afterload()the search comparesD842withFFFDand takes the wrong branch. - Neighbours are hit too: in a lookup of
😀 smile,Abandab, the fullwidth key is lost (lookup("A")gives[], was[Ab/4]). Nothing fails loudly.
Applications that use TSTLookup, save it with store(), reload it with load() (for example at startup) and have emoji or CJK Extension B characters in their suggestions. One entry is enough. The loss is silent and lasts until the lookup is rebuilt (the stored tokens would allow a repair, but no version does it); every release since 4.7.0 is affected.
Mechanism, terms and numbers758 words
TSTLookup keeps its suggestions in a ternary search tree with one node per UTF-16 code unit (TSTAutocomplete.java:63), so a supplementary character such as the emoji 😀 (U+1F600) or the CJK Extension B character 𠮷 (U+20BB7) becomes two nodes, a high surrogate and a low surrogate. store() writes each node's split char as a one-char String with DataOutput.writeString (TSTLookup.java:244), which encodes UTF-8; a lone surrogate has no UTF-8 form and is written as EF BF BD, U+FFFD, and load() reads it back with readString().charAt(0) (:219). load() returns true, the count and the ASCII entries survive, but get() and every lookup whose prefix reaches such a character return nothing, BMP keys on the high side of such a node (fullwidth forms, halfwidth katakana) can be lost too, and a U+FFFD prefix can return keys it never matched. It is a regression from LUCENE-5404 (2014), which replaced the lossless writeChar/readChar: 4.6.1 round-trips, and every release from 4.7.0 to 10.5.2 and main does not. A layout-compatible fix keeps every existing file loadable; stores already written with such characters stay lossy until they are rebuilt (their tokens are stored whole, so a loader could also repair them; a probe showed this).
TSTLookup: a prefix suggester inlucene/suggest.build()sorts the entries and inserts them into a ternary search tree;lookup(prefix, ...)walks the tree along the prefix and lists the entries below;get(key)returns a key's weight. Each node has a split char and three children: lower, equal (next char of the key) and higher.- Surrogate pair: Java strings are UTF-16. A character above U+FFFF, such as 😀 U+1F600 (
D83D DE00) or 𠮷 U+20BB7 (D842 DFB7), is stored as twochars, a high and a low surrogate. Neither half is a character on its own. Lookup.store/Lookup.load: "Persist the constructed lookup data" and "load it from a previously saved copy" (Lookup.java:236-252), for example to avoid rebuilding at startup.
TSTAutocomplete.insertmakes one node perchar:newNode.splitchar = s.charAt(x)(TSTAutocomplete.java:63).𠮷野家is four nodes:D842,DFB7,91CE,5BB6. The publicTSTLookup.add(key, value)calls the sameinsert(TSTLookup.java:149-150).TSTLookup.writeRecursivelywritesout.writeString(new String(new char[] {node.splitchar}, 0, 1))(TSTLookup.java:244).writeStringencodes UTF-8 (DataOutput.java:263-275, throughnew BytesRef(s), whose javadoc asks for text "with no unpaired surrogates",BytesRef.java:77, andUnicodeUtil.UTF16toUTF8), andUnicodeUtilwritesEF BF BD(U+FFFD) for an "unpaired surrogate" (UnicodeUtil.java:231-235).readRecursivelyreadsin.readString().charAt(0)(TSTLookup.java:219): U+FFFD. Everything else (node layout, tokens, weights, the count) round-trips, soload()returns true.- The search compares the query's char with each node's split char (
TSTAutocomplete.java:103-114). A query charD842meets a node that now holdsFFFD, goes to the lower child, and finds nothing.
 before store()                             after load()
  hi: D83D  first half of 😀                  hi: FFFD
      lo: 'a' p p l e -> apple/3                  lo: 'a' p p l e -> apple/3
      eq: DE00 ' smile' -> 😀 smile/4              eq: FFFD ' smile' -> 😀 smile/4
      hi: D842  first half of 𠮷                  hi: FFFD
          eq: DFB7 野 家 -> 𠮷野家/5                    eq: FFFD 野 家 -> 𠮷野家/5

 lookup("𠮷") after load():  D842 < FFFD -> lower child 'a' -> D842 > 'a' -> no higher child -> []
 lookup("�") after load():  FFFD = FFFD -> list everything below -> [😀 smile/4]
(The tree's top node is an empty root with split char U+0000; the dump starts at its higher child.)
| effect | example (executed) |
|---|---|
get() and lookups whose prefix reaches a surrogate node miss | lookup("𠮷"): [𠮷野家/5] -> []; get("𠮷野家"): 5 -> null |
| a BMP key whose char at that level is in U+E000..U+FFFD and sits on the high side of the node is lost (a char below U+FFFD turns lo, U+FFFD itself now goes down the surrogate's eq branch; U+FFFE and U+FFFF still go hi) | lookup("A"): [Ab/4] -> [] (fullwidth U+FF21); keys at U+E000 and U+FFFD lost beside a surrogate node, keys at U+D7FF, U+FFFE, U+FFFF kept; a halfwidth katakana key in an independent test |
| a U+FFFD prefix can match supplementary keys | lookup("�"): [] -> [😀 smile/4] |
Tokens are stored whole, so a prefix that ends before the first surrogate node still lists the key (the prefix a still finds a😀): the loss depends on the lookup path, not only on the key. ASCII keys and getCount() are unchanged.
Exposure and likelihood313 words
- Who is exposed.
TSTLookupis opt-in: an application picks it among theLookupimplementations. It is not deprecated and has no experimental tag of its own (class javadocTSTLookup.java:36-42), though its base classLookupis@lucene.experimental(Lookup.java:38). Only lookups that are persisted withstore()and reloaded withload()are hit, and only for text with characters above U+FFFF, whether built withbuild()or added withadd(). - Silent.
load()returns true,getCount()is right and ASCII entries work. Only lookups whose path reaches a surrogate node change: users who type such a character, and users who type some BMP prefixes beside such a node (the fullwidthA, U+FFFD), get missing or wrong suggestions. It does not depend on randomness: the same with assertions on and off and with every seed tried. - Lasting. The saved file holds U+FFFD in place of the surrogate split chars, and no Lucene version, fixed or not, reads them back. The tokens and weights are stored whole, though: a white-box probe re-derived the lost split chars from them and got every answer back. Without such a repair step, the lookup has to be rebuilt from its source.
- How much changes. In the finder's random sweep (100,000 dictionaries of 1-6 keys, with U+00E9, U+1F600 and U+FFFD among the possible keys; 341,084,860 lookups over 20 suggester configurations), the round trip changed 245,800
TSTLookupresults, and 0 with the fix. An independent test: 13 of 24 code-point-boundary prefixes change. - Siblings are fine.
FSTCompletionLookupandWFSTCompletionLookupround-trip the same keys. - Downstream (read, not run). In a 2020 Lucene/Solr source snapshot, Solr's suggester reloads a persisted lookup from a
storeDir, andTSTLookupFactorycreates aTSTLookup. The Lucene.NET port carries the same two lines. - How likely. Rare: it needs a persisted
TSTLookup, such characters in the dictionary, and a lookup through them; no report of it was found.
The test shows that TSTLookup.store/load loses a key that contains a supplementary character (U+20BB7): each surrogate split char is written with writeString and comes back as U+FFFD.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.suggest.tst;

import java.io.StringReader;
import org.apache.lucene.search.suggest.FileDictionary;
import org.apache.lucene.store.ByteBuffersDataOutput;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestTSTLookupStoreLoadSupplementary extends LuceneTestCase {

  public void testStoreLoadKeepsSupplementaryKey() throws Exception {
    String key = "\uD842\uDFB7\u91CE\u5BB6";
    try (Directory dir = newDirectory()) {
      TSTLookup lookup = new TSTLookup(dir, "tst");
      lookup.build(new FileDictionary(new StringReader(key + "\t5")));
      ByteBuffersDataOutput out = new ByteBuffersDataOutput();
      lookup.store(out);
      TSTLookup loaded = new TSTLookup(dir, "tst");
      loaded.load(out.toDataInput());
      // key starts with U+20BB7; expected get() after store/load to be 5, actual null
      assertEquals(Long.valueOf(5), loaded.get(key));
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-699/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/suggest/build/libs/lucene-suggest-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.suggest.tst.TestTSTLookupStoreLoadSupplementary
- Expected vs actual
- Expected
get(key)on the reloaded lookup to return the weight 5; actualnull(expected:<5> but was:<null>), with-eaand-da.
More files, environment, full output34 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<5> but was:<null>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:120)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.search.suggest.tst.TestTSTLookupStoreLoadSupplementary.testStoreLoadKeepsSupplementaryKey(TestTSTLookupStoreLoadSupplementary.java:37)Lookup.loadpromises to "load it from a previously saved copy", andTSTLookup.loadreturns true.- Upstream
TestPersistencechecks that every key keeps its exact weight after aTSTLookupstore/load (ASCII keys only); before the reload, every emoji key is found. - A regression: 4.6.1 wrote the split char losslessly with
writeCharand round-trips; 4.7.0 switched towriteStringand does not.
The full argument192 words
- The contract.
Lookup.store: "Persist the constructed lookup data ... @return true if successful";Lookup.load: "Discard current lookup data and load it from a previously saved copy" (Lookup.java:236-252).TSTLookupimplements both and returns true (TSTLookup.java:267-280). - The upstream test.
TestPersistence.testTSTPersistencerunsrunTest(TSTLookup.class, true)(TestPersistence.java:50-52): it stores, reloads into a newTSTLookupand asserts that every key returns 1 hit with its exact weight (:82-105), for 15 ASCII words (:31-48). - Nothing limits it to the BMP. No javadoc restricts
TSTLookupto BMP text; it sorts its input with a comparator whose comment explains where supplementary code points go (TSTLookup.java:73-115; a TODO at:71asks whether the comparator is needed at all); beforestore()every repro's supplementary key is found. - History. Before LUCENE-5404 the split char was written with
DataOutputStream.writeCharand read withreadChar(4.6.1,TSTLookup.javalines 154 and 179), lossless for any UTF-16 unit. LUCENE-5404 (2014) moved store/load toDataOutput/DataInputand replaced them withwriteString/readString().charAt(0). Its discussion (19 comments) and its 4.7.0 CHANGES entry never mention characters. A probe round-trips on 4.6.1 and not on 4.7.0.
The devil's-advocate check232 words
The strongest "intended" case (the devil's-advocate verifier; the reviews by another model family rated it weak): writeString is documented as UTF-8, and since LUCENE-510 (2008) "If any text ... has illegal UTF-16 surrogate characters, these characters are now silently replaced with the Unicode replacement character U+FFFD"; store/load is an "Optional operation" with no format header or version, and Lookup is @lucene.experimental; no upstream test stores non-ASCII keys in a TSTLookup; and LUCENE-5404 changed the format on purpose.
Why it fails: the caller's text is valid; TSTLookup itself splits it into lone surrogates and passes one to writeString as if it were a string, so DataOutput behaves as documented and TSTLookup's use of it is the defect; writeString builds a new BytesRef(s), whose javadoc asks for text "with no unpaired surrogates" (BytesRef.java:77). "Optional" lets an implementation return false; it does not allow returning true and loading a different lookup. An untested input is not an unsupported one, and the comparator anticipates it. The format change was deliberate; the character loss was a side effect nobody discussed. Verdict: a defect (adjudication: confirmed, high).
What a maintainer may still choose: the second cross-model fact check rated "intended" weak but "acceptable / won't fix" moderate. A maintainer could document the limit, deprecate TSTLookup, or prefer a format break with a header to a hand-written decoder in an unversioned format.
Recommended Keep the layout; write a lone surrogate as its 3-byte generalized-UTF-8 form
Write a lone surrogate split char as its 3-byte form (ED A0 80 to ED BF BF) and decode it on load; every other char is written as today, so existing files load as before. The repro and the module's 238 tests pass. Old stores stay lossy until rebuilt, or repaired from their stored tokens.
All options and trade-offs4 options · 1,187 words
All options make the split char round-trip; they differ in what happens to files already on disk. Executed matrix (two dictionaries, each stored by each build with store(OutputStream) and loaded by each build): a stock file read by fix B answers exactly as on stock; an ASCII-only file is byte-identical under fix B; a fix B file read by stock answers as today. Under fix A, both stock files in the probe load with load() = true and every lookup empty, the ASCII-only one included, which works today; a fix A file makes stock and fix B throw StringIndexOutOfBoundsException. The 10.5.2 and 9.12.3 readers print exactly what main's stock reader prints for all six files (executed). A pre-9.0 reader misreads the weights of every file written by 9.0 or later, stock files included (9.0 made the Directory API little-endian, LUCENE-9047; executed with 8.8.1: apple/2 reads back as apple/144115188075855872), independent of this bug. Options A-C do not repair files written by 4.7.0 to main: their surrogate nodes already hold U+FFFD. The tokens are stored whole, though, so a loader could re-derive the split chars (option D; a probe did it, no patch). Add the new test with whichever option, and a CHANGES note that such stores must be rebuilt (unless the fix adds option D).
Keep the layout; write a lone surrogate as its 3-byte generalized-UTF-8 form (validated by the checks) (recommended)
writeRecursively and readRecursively call two small helpers instead of writeString/readString().charAt(0). A surrogate is written as length 3 plus ED A0 80..ED BF BF (the same length as today's EF BF BD); that byte pattern never occurs in valid UTF-8 (after ED the next byte must be 80-9F), so the reader can tell it from every file written today. Every other char goes through writeString as before. +32/-2 in TSTLookup.java.
private static void writeSplitChar(DataOutput out, char c) throws IOException {
  if (Character.isSurrogate(c)) {
    out.writeVInt(3);
    out.writeByte((byte) (0xE0 | (c >> 12)));
    out.writeByte((byte) (0x80 | ((c >> 6) & 0x3F)));
    out.writeByte((byte) (0x80 | (c & 0x3F)));
  } else {
    out.writeString(String.valueOf(c));
  }
}

private static char readSplitChar(DataInput in) throws IOException {
  int length = in.readVInt();
  byte[] bytes = new byte[length];
  in.readBytes(bytes, 0, length);
  if (length == 3 && (bytes[0] & 0xFF) == 0xED && (bytes[1] & 0xE0) == 0xA0) {
    return (char) (0xD000 | ((bytes[1] & 0x3F) << 6) | (bytes[2] & 0x3F));
  }
  return new String(bytes, 0, length, StandardCharsets.UTF_8).charAt(0);
}
Trade-offs
- No break for today's readers: old files load as today (still lossy until rebuilt); new files without supplementary characters are byte-identical, and with them differ only in the surrogate nodes (11 of 154 bytes in the probe); main's stock reader and the 9.12.3 and 10.5.2 readers load a new file exactly as today (executed), because
readStringdecodes with the JDK's UTF-8 decoder, which turns eachED A0 80..ED BF BFinto a String that starts with U+FFFD (a single U+FFFD for all 2048 forms on OpenJDK 25.0.3, executed). Pre-9.0 readers cannot read any file written today (see above). - 32 lines instead of 2, and a hand-written decoder for one byte pattern.
- The format stays unversioned; a maintainer may prefer to add a header at the same time (option C).
- Cost on load: one small
byte[]per node, asreadStringallocates today. readSplitCharchecks the first two bytes (ED, thenA0-BF) but not that the third is80-BF; every filestore()writes satisfies that, but a reviewer may ask for the check. The new test covers two surrogate pairs; a production test may add boundary cases like the probe's.- A maintainer may prefer option C, or option A with a header in a major release, to a hand-written decoder in an unversioned format (the second cross-model fact check's view).
What the checks validated
- Gradle, scratch worktree of
a9779ef3c193, JDK 25: stock + the new test fails 2 of 2 with assertions on and off; with the fix, the new test andTestPersistence(4 tests) pass with assertions on and off; the wholelucene/suggestmodule, 32 suites, 238 tests (7 skipped), 0 failures with assertions on and off;:lucene:suggest:check -x test(ecjLint, forbiddenApis,checkGoogleJavaFormat) passes. - Standalone runner: the new test 2 of 2 pass with
-eaand-da. - Compatibility matrix as described above (executed), including the 10.5.2, 9.12.3 and 8.8.1 readers.
- Every surrogate value: 1,031 keys covering D800-DFFF plus BMP keys at U+D7FF, U+E000, U+FFFD, U+FFFE, U+FFFF; 3,093 checks after a round trip: stock changes 3,078, fix B (
-eaand-da) 0, fix A 0. The fix B bytes hold 2,04803 ED A0..BF 80..BFforms and one03 EF BF BD(the real U+FFFD key).
out.writeVInt(node.splitchar) / (char) in.readVInt(). +2/-2.
-    node.splitchar = in.readString().charAt(0);
+    node.splitchar = (char) in.readVInt();
...
-    out.writeString(new String(new char[] {node.splitchar}, 0, 1));
+    out.writeVInt(node.splitchar); // a lone surrogate must survive (writeString maps it to U+FFFD)
Trade-offs
Simplest, lossless, and ASCII nodes get 1 byte smaller (the ASCII file is 337 instead of 392 bytes). But every node's byte layout changes and nothing marks the format: a fixed reader misparses files written by 4.7.0 to main (both old files in the probe loaded with load() = true and every lookup empty, the ASCII-only one included), and an older reader threw StringIndexOutOfBoundsException on both new files (executed). Acceptable only with an explicit "rebuild your lookups" note in a major release, or together with option C.
What the checks validated
Gradle: the new test and TestPersistence pass with assertions on and off; the whole module, 238 tests, passes with assertions on; checkGoogleJavaFormat passes. Standalone: 2 of 2 pass with -ea and -da; the finder's and the independent reproducer's tests pass with it.
Write a header (for example with CodecUtil.writeHeader) and the split char with writeVInt or writeShort; read headerless files with today's decoding. Not built.
Trade-offs
Lets the format evolve later. Detecting "no header" is not free: today's files start with a VLong count, so the reader must tell the header's magic bytes apart from a count. The LUCENE-5404 discussion already noted the missing codec header.
Each node's split char equals token.charAt(depth) for any token stored at or below the node on its eq side, where depth is the number of eq edges from the root (TSTAutocomplete.insert advances the char index only on eq, TSTAutocomplete.java:57-86). A loader can re-derive every split char after readRecursively, keeping the tree shape. Combined with B or C, files written by 4.7.0 to main would answer correctly again. Executed only as a white-box probe on the stock files: for the supplementary file it changed the 4 surrogate nodes back and every answer then equals a fresh build; the ASCII file was unchanged.
Trade-offs
One more pass over the tree on load. Only a white-box probe exists: no patch, test or review.
Downstream, Solr's suggester can reload a persisted TSTLookup from its storeDir (seen in 2020 source, not run), so such deployments would lose these suggestions after a restart.
A randomized differential check ran 20 configurations of seven suggesters against a reference written from their javadoc and required a store()/load() round trip to change nothing. Over 100,000 small random dictionaries whose keys may include an emoji, the round trip changed 245,800 TSTLookup results, and none with the fix.
The method in full174 words
Method: randomized differential translation validation on the stock main jars (the study's "semi-formal" tier). A hunt unit, "suggest lookups, cross-implementation differential", 2026-10-27.
- 20 configurations of seven
Lookupclasses (TSTLookup,FSTCompletionLookup,WFSTCompletionLookup,AnalyzingSuggester,FuzzySuggester,AnalyzingInfixSuggester,BlendedInfixSuggester; not everyLookup:FreeTextSuggester, for example, was not modelled) were run against an independent reference written from their javadoc, plus a store/load round trip that must reproduce every result list andgetCount(). - Scope R1: 100,000 random dictionaries of 1-6 entries over {a,b,c}^1..3 plus keys with U+00E9, U+1F600 and U+FFFD; 341,084,860 lookups over 20 suggester configurations. The class "TST RT:changed" (a
TSTLookupresult that differs after the round trip) appeared 245,800 times on the stock jar and 0 times with the fix shadowed. - The mechanism (
writeStringof a one-char String) had first been noticed while writing the model. The ASCII-only bounded-exhaustive scope (596,908 dictionaries) could not reach it. - An AI finder then wrote the public-API JUnit, and independent AI tools reproduced, reviewed and judged it (see the checks).
No prior report found (2026-10-27): three runs of a prior-art search over GitHub, JIRA, the mailing lists and downstream projects, manual searches and the changed files of all 409 open PRs. The discussion of the introducing change never mentions characters.
Searches4 searches
None of the issues, PRs, commits, JIRA entries, list threads or web pages found reports TSTLookup losing suggestions after store()/load(), lone surrogates in its split chars, or the writeString / readString().charAt(0) pair. Upstream main and branch_10x still have both lines.
Related, not this bug: gh#6467 / LUCENE-5404 (the introducing change; body and 19 comments never mention the char encoding); SOLR-2375 (the original, lossless store/load); gh#1588 / LUCENE-510 (writeString's U+FFFD substitution; background); a downstream remark (kitodo/kitodo-presentation#594) that TSTLookup gave "a flood of errors", without details (this bug raises no error); the Lucene.NET port's TSTLookup.cs, which has the same code (source, not a report).
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene), downstream repositories, mailing lists, JIRA archive | 2026-10-27 | three runs of a scripted prior-report search with different specs (identifiers and mechanism; user symptoms such as emoji, restart, storeDir; the general writeString / lone-surrogate mechanism), 51 queries each | 119, 414 and 347 distinct hits; the only high-overlap hit, gh#4915, is unrelated |
| GitHub (apache/lucene and all repositories), Solr, Elasticsearch, OpenSearch, Lucene.NET | 2026-10-27 | manual searches (TSTLookup with surrogate, unicode, store, emoji; TernaryTreeNode, TSTAutocomplete, splitchar; lone/unpaired surrogate; LUCENE-5404) | only 9 apache/lucene issues name TSTLookup, all read or triaged; nothing about this bug |
| JIRA (LUCENE, SOLR) and the Lucene and Solr lists | 2026-10-27 | 22 JQL queries; dev@, java-user@, issues@, commits@, solr-user@ and the Solr lists | no report; SOLR-2375 and a few suggester threads read |
| Open PRs and code history | 2026-10-27 | the changed files of all 409 open apache/lucene PRs; git log --follow of TSTLookup.java; upstream main and branch_10x | no PR touches lucene/suggest/.../tst/; the two lines are unchanged since 2014 |
Introduced by LUCENE-5404 (2014-02-07), which replaced the lossless writeChar/readChar with writeString/readString; first released in 4.7.0. A probe round-trips on all 14 releases up to 4.6.1 and fails on all 119 from 4.7.0 to 10.5.2 and on main.
Versions tested6 rows
Introduced by LUCENE-5404 (issue "Add support to get number of entries a Suggester Lookup was built with and minor refactorings"; commit subject "Add .getCount method to all suggesters (Lookup), persist count metadata on .store(), ...") by Areek Zillur, 2014-02-07: b5926da2d678 on trunk (released in 6.0.0 and later) and fdf4595051a on branch_4x (released in 4.7.0 to 5.5.5). No GitHub PR; the patch was reviewed on JIRA (now gh#6467). git blame of TSTLookup.java:219 and :244 on main points to b5926da2d678; fdf4595051a is the only commit touching TSTLookup.java between the 4.6.1 and 4.7.0 tags. Store/load itself is older (SOLR-2375, 2011) and was lossless until then. Not fixed upstream.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the brief's test 2 of 2 fail (gradle and the standalone runner, assertions on and off) |
| 10.5.2, 9.12.3 | affected | the brief's test 2 of 2 fail; the finder's 2 of 2; the independent reproducer's 3 of 3 |
| 4.7.0-10.5.2 (119 releases) | affected | the version-independent probe loses the same 7 of 10 answers on each, with 0 control changes |
| 3.6.0-3.6.2, 4.0.0-4.6.1 (14 releases) | not affected | the probe round-trips: 10 of 10 answers unchanged |
| 4.6.1 vs 4.7.0 | boundary | 4.6.1 round-trips with assertions on and off; 4.7.0 changes 7 of 10 answers with both |
| main + fix | not affected | all repros pass; the whole lucene/suggest module, 238 tests, 0 failed |
An independent reproducer, a devil's advocate, an adjudication and reviews by another model family (which ran their own tests) all found it real; the adjudication confirmed it with high confidence. Registry re-runs and a final audit reproduced it with new seeds.
Checks and verdicts295 words
Every check wrote or ran its own test against the stock jars, with assertions on and off.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Public-API JUnit fails 2 of 2 on main (-ea, -da), 20 of 20 iterations, 10.5.2 and 9.12.3; passes with the fix; with the unit's fixes, 47 of 47 tests of four upstream suggest suites (TestPersistence among them) pass. |
| cross-model review, refute lens | real (high) | An independent reviewer from another model family (OpenAI GPT-5.6) ran its own JUnit on main ea57360912ed (whose lucene/suggest is identical; -ea with two seeds, and -da), 10.5.2 and 9.12.3; narrowed the scope to lookup paths and flagged that the VInt fix changes the byte layout. |
| Independent reproducer | real | Own 3-test JUnit fails 3 of 3 on main (-ea, -da), 10.5.2 and 9.12.3: 13 of 24 prefixes change, a halfwidth katakana key is lost; passes with its own two-line fix. |
| Cross-model review, intended lens | real (high) | OpenAI GPT-5.6: the intended-behaviour argument is weak; its expected-behaviour test fails on main and passes with the fix; FSTCompletionLookup keeps the same key. |
| Devil's advocate | real (high) | Built the LUCENE-510 / optional-operation case and rejected it; its probe fails on main and 10.5.2, the FST and WFST controls round-trip; history probe 4.6.1 OK, 4.7.0 and later changed. |
| adjudication | confirmed (high) | Silent wrong results, duplicate of nothing; re-ran the independent reproduction's test (-ea), the finder's (-da) and the independent reproduction's fix. |
| registry re-run and audit | keep | Fresh seeds: the finder's and the independent reproduction's tests fail with -ea and -da and pass with the fix; the audit's own probe finds 8 differences in 10 checks after a reload. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 519 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,523 words
- Registry title
- TSTLookup.store/load writes each tree node's split char with DataOutput.writeString, so the two surrogate halves of an emoji or CJK Extension B character come back as U+FFFD: after load(), get() and lookups whose prefix runs through such a character silently find nothing, and some neighbouring BMP keys are lost too (every release since 4.7.0)
- Area
- suggest / ternary search tree suggester persistence (TSTLookup.store and load, writeRecursively and readRecursively)
- Priority
- Low, rank 273: Needs the little-used TSTLookup plus its optional store/load plus supplementary characters in the dictionary.
- Impact class
- silent wrong results
- Impact note
- Hits applications that use the opt-in TSTLookup suggester, persist it with Lookup.store and reload it with Lookup.load (for example to skip a rebuild at restart), and whose suggestion text contains supplementary characters (emoji, CJK Extension B): after the reload, which returns true, get() and every lookup whose prefix runs through such a character return nothing, some BMP keys stored beside a surrogate node (fullwidth forms, halfwidth katakana, depending on the tree shape) disappear as well, and a U+FFFD prefix can return emoji keys it never matched before; nothing fails loudly, no scale is needed, ASCII-only dictionaries and getCount() are unaffected, and every release since 4.7.0 has it.
- Summary
- You build a TSTLookup from ordinary text that contains an emoji or a CJK Extension B character (for example the key 𠮷野家 with weight 5), store() it, load() it back, and expect the reloaded copy to answer like the original, as Lookup.load promises ('load it from a previously saved copy'). Instead lookup('𠮷', true, 5) returns [] instead of [𠮷野家/5] and get('𠮷野家') returns null after the reload, because TSTLookup keeps one tree node per UTF-16 code unit, writeRecursively writes each node's split char with DataOutput.writeString of a one-char String, and a lone surrogate has no UTF-8 form, so it is written and reloaded as U+FFFD and the tree's char comparisons then take the wrong branches. ASCII keys and getCount() survive, while some BMP keys next to a surrogate node are lost too (in the finder's test lookup('A') returns [] instead of [Ab/4]).
- Introduced
- b5926da2d67820f5fdf8c8ec9b2e642b74d12070 (trunk, svn r1565810; the line released in 6.0.0 and later) and its branch_4x twin fdf4595051ada90409a47f8259a6d6e17d4711be (svn r1565811; the line released in 4.7.0-5.5.5), both 'LUCENE-5404: Add .getCount method to all suggesters (Lookup), persist count metadata on .store(), ...' by Areek Zillur (now apache/lucene#6467; an svn-era JIRA patch, no GitHub PR) [read: git blame of TSTLookup.java:219 and :244 on main points to b5926da2d678; it is the only commit touching TSTLookup.java between the 4.6.1 and 4.7.0 tags; exec: 4.6.1 round-trips correctly, 4.7.0 does not]. It moved Lookup.store/load from java.io streams to Lucene DataOutput/DataInput and replaced the lossless DataOutputStream.writeChar(node.splitchar) / readChar() with writeString(new String(new char[] {node.splitchar}, 0, 1)) / readString().charAt(0); the issue discussion never mentions characters, so the loss is a side effect of that move, not a design choice. No later commit changed the two lines. (2014-02-07)
- First affected version
- 4.7.0 [exec] (release tag dated 2014-02-25); the last unaffected release is 4.6.1 [exec]; TSTLookup store/load existed before (since Lucene 3.3, stream API since 3.6.0) and was lossless there [exec: 3.6.0-4.6.1]
- Affected versions
- every release from 4.7.0 through 10.5.2 and main a9779ef3c193; not fixed upstream. [exec] the follow-up's main() probe on 133 releases: 3.6.0-4.6.1 (14 releases) round-trip correctly, and all 119 cached releases from 4.7.0 to 10.5.2 lose the same 7 of 10 answers with 0 control changes (also -da on 4.6.1, 4.7.0, 9.12.3 and 10.5.2), main with -ea and -da, and main with the fix shadowed passes; the finder's JUnit fails on main (-ea and -da), 10.5.2 and 9.12.3; the independent reproduction's JUnit on main (-ea and -da), 10.5.2 and 9.12.3; the refute reviewer's JUnit on main, 10.5.2 and 9.12.3; the intended-behaviour check's history probe on 4.6.1 (OK), 4.7.0, 4.10.4, 5.5.5, 8.11.4, 10.5.2 and main (CHANGED). [read] both lines are present unchanged in all 110 release tags of the history clone that contain the introducing commit and absent (writeChar/readChar) in every earlier tag; upstream main head a95c754ee003 and branch_10x still have them. All runs on JDK 25.0.3 (aarch64); the defect is pure-Java string encoding, so the platform does not matter.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check, code reading
- Upstream and prior reports
- none found (2026-10-27, read-only; the prior-report record, verdict new): three follow-up scripted prior-report searches with different specs (identifiers and mechanism; user-visible symptoms such as emoji, restart and storeDir; the general writeString / lone-surrogate mechanism), 51 queries each over GitHub issues, PRs and commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists and the JIRA archive (119, 414 and 347 distinct hits; the only 'high' overlap hit, #4915, is unrelated), plus the finder's run (51 queries, nothing relevant); manual GitHub searches on apache/lucene (only 9 issues name TSTLookup, all read or triaged) and across GitHub, apache/solr, Elasticsearch, OpenSearch and Lucene.NET; 22 JQL queries on LUCENE and SOLR; list searches on the Lucene and Solr dev and user lists; the changed-file lists of all 409 open apache/lucene PRs (none touches lucene/suggest/.../tst/); the file history of TSTLookup.java; 8 web queries. The independent reproduction and the intended-behaviour check searched with more phrasings and found nothing either. Not fixed upstream: main head a95c754ee003 and branch_10x still have both lines. Related, none a report of this bug: #6467 / LUCENE-5404 (the change that introduced it; body and 19 comments never mention the char encoding), SOLR-2375 (added the original, lossless store/load), #1588 / LUCENE-510 (made writeString standard UTF-8 with U+FFFD for unpaired surrogates; background), kitodo/kitodo-presentation#594 (a downstream remark that TSTLookup gave 'a flood of errors', with no details; this bug raises no error) and the Lucene.NET port, whose TSTLookup.cs carries the same code (source, not a report).
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-27) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the 10.5.2 and 9.12.3 release jars (the brief's test); a version-independent probe on 133 release jars from 3.6.0 to 10.5.2. Fix B was validated in the scratch worktree (the new test andTestPersistencewith assertions on and off, the wholelucene/suggestmodule's 238 tests with assertions on and off,:lucene:suggest:check -x test); fix A with the same suites (the module with assertions on) and the format check; a store-format compatibility matrix (stock, fix A, fix B writing and reading each other's files, also read by the 10.5.2, 9.12.3 and 8.8.1 release jars) was executed, as were a probe that stores every surrogate value as a split char (stock, fix A, fix B) and a white-box probe that repairs a stock file from its stored tokens.
- Finding record
lucene/suggest/src/java/org/apache/lucene/search/suggest/tst/TSTLookup.java:219 (readRecursively: node.splitchar = in.readString().charAt(0)), :244 (writeRecursively: out.writeString(new String(new char[] {node.splitchar}, 0, 1))), :222 and :253 (tokens read and written whole with readString/writeString), :268-279 (store/load write and read a VLong count plus the tree and return true), :71-115 (utf8SortedAsUTF16SortOrder comparator that handles supplementary code points explicitly), :36-42 (class javadoc: no @lucene.experimental, not deprecated)lucene/suggest/src/java/org/apache/lucene/search/suggest/tst/TSTAutocomplete.java:57-86 (insert: one node per UTF-16 code unit, newNode.splitchar = s.charAt(x) at :63; comparisons at :72 and :74), :103-105 (prefixCompletion compares s.charAt(x) with p.splitchar)lucene/suggest/src/java/org/apache/lucene/search/suggest/Lookup.java:38 (@lucene.experimental), :237-243 (store: 'Persist the constructed lookup data ... Optional operation', true if successful), :246-252 (load: 'Discard current lookup data and load it from a previously saved copy. Optional operation.')lucene/core/src/java/org/apache/lucene/store/DataOutput.java:266-275 (writeString writes UTF-8 through new BytesRef(s)); lucene/core/src/java/org/apache/lucene/util/UnicodeUtil.java:172-176 ('replace unpaired surrogate or out-of-order low surrogate with substitution character', EF BF BD)lucene/suggest/src/test/org/apache/lucene/search/suggest/TestPersistence.java:50-51 (testTSTPersistence: runTest(TSTLookup.class, true), exact round trip, ASCII keys only)
- The finding in 30 seconds
lucene/suggest/src/java/org/apache/lucene/search/suggest/tst/TSTAutocomplete.java:57-86 (at a9779ef3c193) (insert, :63 one node per char, :72/:74 comparisons), :97-148 (prefixCompletion, :103-114 descent)lucene/suggest/src/java/org/apache/lucene/search/suggest/tst/TSTLookup.java:219 (at a9779ef3c193) (readRecursively), :244 (writeRecursively), :222/:253 (tokens), :267-280 (store/load return true), :135-141 (build decodes to String), :149-150 (add calls the same insert)lucene/core/src/java/org/apache/lucene/store/DataOutput.java:263-275; (at a9779ef3c193) lucene/core/src/java/org/apache/lucene/util/BytesRef.java:77 ("no unpaired surrogates"), :79-82; lucene/core/src/java/org/apache/lucene/util/UnicodeUtil.java:199-240 (:231-235 substitution); lucene/core/src/java/org/apache/lucene/store/DataInput.java:226-231lucene/suggest/src/java/org/apache/lucene/search/suggest/Lookup.java:236-252 (at a9779ef3c193)
- Who is affected
lucene/suggest/src/java/org/apache/lucene/search/suggest/tst/TSTLookup.java:36-42; (at a9779ef3c193) lucene/suggest/src/java/org/apache/lucene/search/suggest/Lookup.java:38 (at a9779ef3c193)
- Why it looks unintended
lucene/suggest/src/java/org/apache/lucene/search/suggest/Lookup.java:236-252; (at a9779ef3c193) lucene/suggest/src/java/org/apache/lucene/search/suggest/tst/TSTLookup.java:71-115, (at a9779ef3c193) :267-280; lucene/core/src/java/org/apache/lucene/util/BytesRef.java:77lucene/suggest/src/test/org/apache/lucene/search/suggest/TestPersistence.java:31-48, (at a9779ef3c193) :50-52, :82-105a Lucene clone releases/lucene-solr/4.6.1:lucene/suggest/src/java/org/apache/lucene/search/suggest/tst/TSTLookup.java:154, :179 (readChar/writeChar)
- Suggested fix
lucene/core/src/java/org/apache/lucene/store/DataInput.java:226-231 (at a9779ef3c193) (readString decodes with the JDK UTF-8 decoder); a Lucene clone releases/lucene-solr/4.7.0 DataInput.java:187-192, 6.6.6 :234-239, 8.8.1 :255-260, releases/lucene/9.12.3 :303-308, 10.5.2 :230-235 (the same decoding; whole-file compatibility only from 9.0 on, see LUCENE-9047)
- History
a Lucene clone: releases/lucene-solr/4.6.1 and 4.7.0 TSTLookup.java (readChar/writeChar vs readString/writeString); git log 4.6.1..4.7.0 -- TSTLookup.java (fdf4595051a only)
- TestTSTLookupStoreLoadSupplementary.java (JUnit test):
repro/LFV-699/src/org/apache/lucene/search/suggest/tst/TestTSTLookupStoreLoadSupplementary.java(40 lines)
A picture of the repro, made in parallel with this doc from executed runs on main a9779ef3c193 and the code, and updated after the checks to show the recommended fix (option B); the alt text describes the intended content.
assets/LFV-699/bug.png(519 KB)