BlendedInfixSuggester re-ranks the suggestions it fetched and keeps the best num in a sorted set that also merges identical ones. When the set is full, it removes the weakest entry before inserting a new one, even when the new one is a copy that the set then ignores.
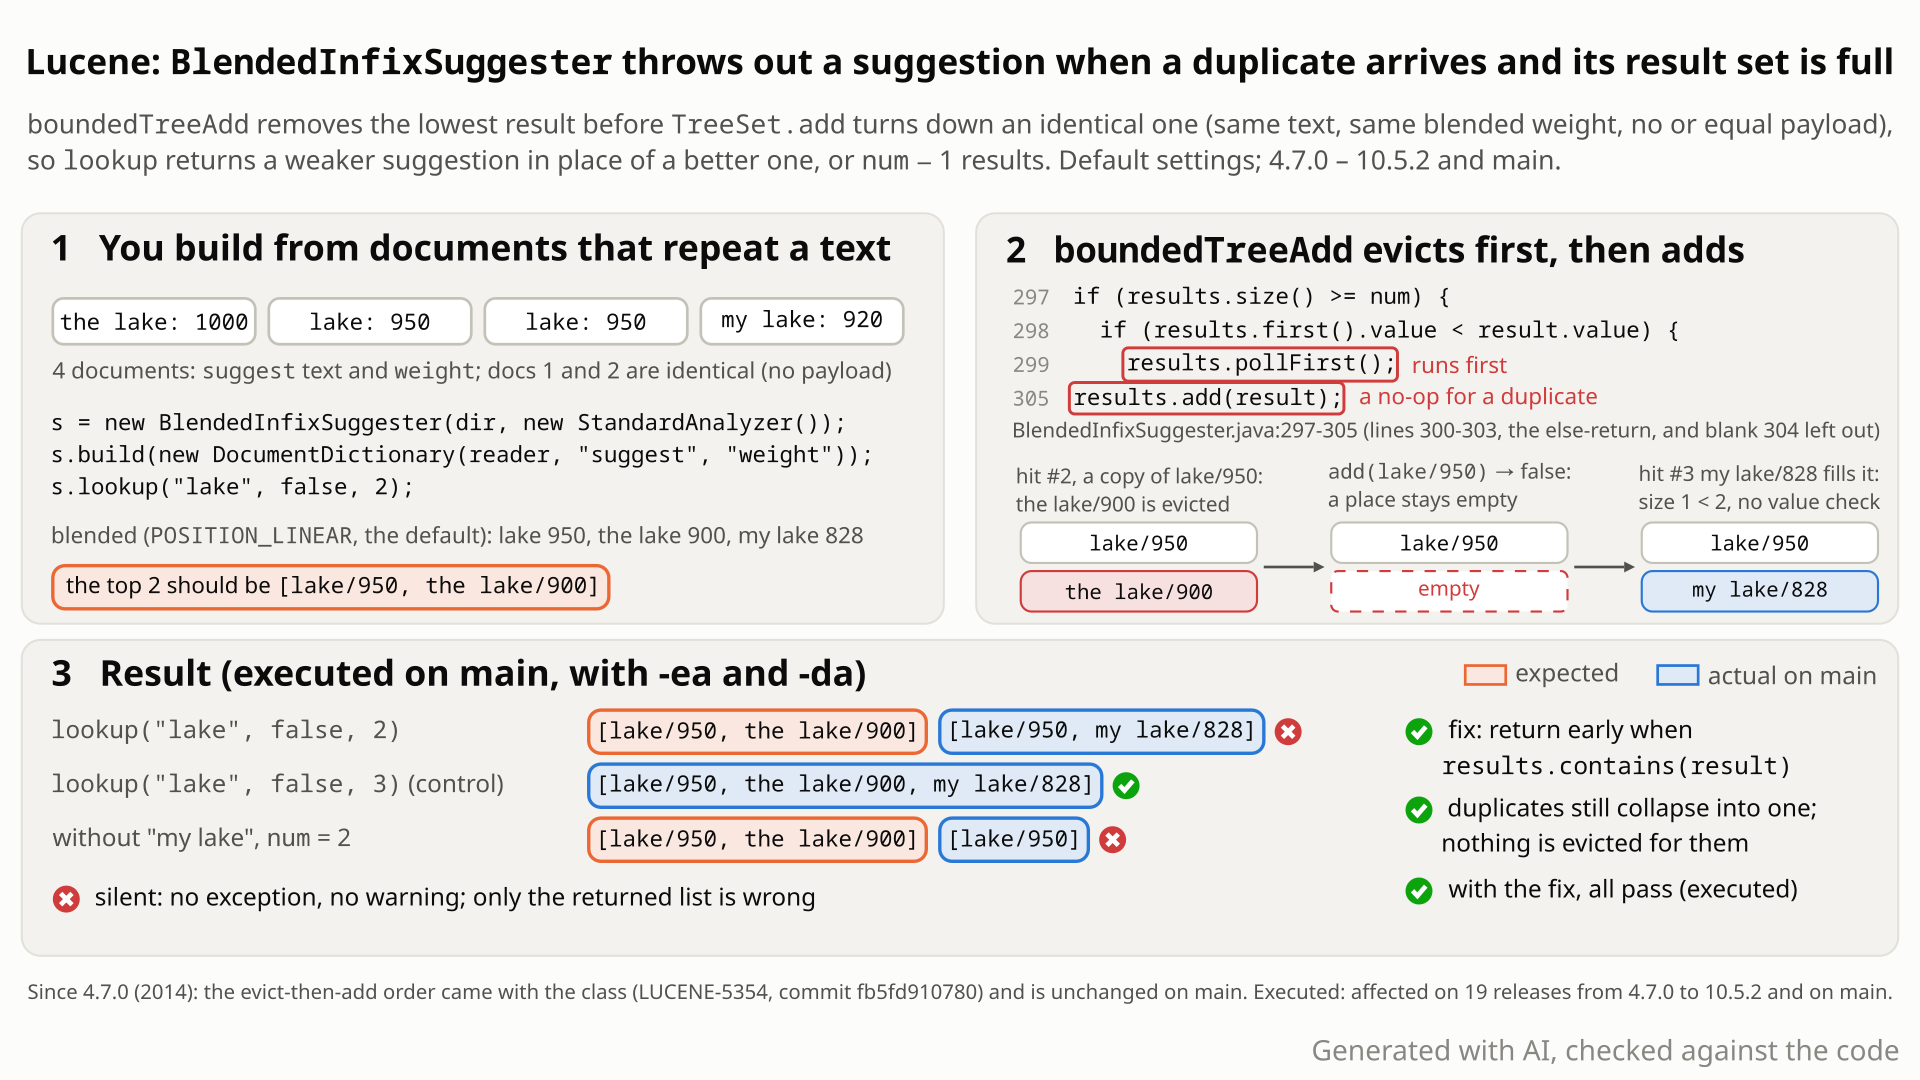
the lake, the ignored repeat of lake, and the returned list against the expected one. Select the still to open it at full size. Generated with AI, checked against the code.- Index four documents with a name and a weight:
the lake1000,lake950,lake950,my lake920. Build the defaultBlendedInfixSuggesterfrom aDocumentDictionary; it shows a repeated suggestion once. - Blending lowers a match that is not the first word by 10% per position:
the lake900,my lake828,lakestays 950.lookup("lake", false, 3)returns[lake/950, the lake/900, my lake/828]. - You expect
lookup("lake", false, 2)to return the first two of those:[lake/950, the lake/900]. - You get
[lake/950, my lake/828]. The set already holdsthe lakeandlakewhen the secondlakearrives: the code first removes the lowest entry,the lake, then insertslake, which is a duplicate and is ignored.my laketakes the free slot. - Without
my lakeyou get just[lake/950], and documents with no weight field (weight 0 for all) behave the same. Nothing throws;num=1is never affected.
Applications using BlendedInfixSuggester (opt-in, experimental; default settings included) whose dictionary repeats a suggestion text with weights that blend to the same value and no distinct payload, typically a DocumentDictionary over a field whose values repeat, with or without a weight field. Three entries suffice; each affected lookup silently loses at most one suggestion.
Mechanism, terms and numbers902 words
BlendedInfixSuggester re-ranks the hits it fetched by a blended weight and keeps the best num in a sorted set that also merges identical suggestions (same text, same blended weight, same or no payload). When the set is full and a better hit arrives, boundedTreeAdd removes the lowest entry before it inserts the new one (BlendedInfixSuggester.java:294-306); if the new hit is a copy of a suggestion already in the set, the insert does nothing, so a different, already-collected suggestion is lost. With the default constructor and a DocumentDictionary over {the lake 1000, lake 950, lake 950, my lake 920}, lookup("lake", false, 2) returns [lake/950, my lake/828] instead of [lake/950, the lake/900], the first two of the num=3 answer; without my lake it returns [lake/950]. A dictionary with no weight field behaves the same. Nothing throws and the index is unchanged. Every release from 4.7.0 (2014, the first with this class) to 10.6.0 and main is affected (19 releases and main run, 10.6.0 by reading), and a one-line guard that skips a duplicate before evicting fixes it.
- Blending:
BlendedInfixSuggesterfetchesnum * numFactormatches (defaultnumFactor10) in raw-weight order, then scores each one by where the query matched: a suggestion that starts with the key keeps its weight; otherwisePOSITION_LINEAR(the default) multiplies it by1 - 0.1 * positionof the first matching word (BlendedInfixSuggester.java:72-84, 259-264). Weight 0 becomes 1, and weights below 10 are multiplied by 10 (:265-270). The blended value is cut to along(:271). - Result set: a
TreeSetordered byLookUpComparator, bounded at thenumthe caller asked for (:224-227,:281). The comparator orders on the blended value, then the text, then the payload when there is one, and returns 0 when all are equal (:383-407);TreeSet.addignores an element that compares 0 to one it holds. That is how identical suggestions are merged, which upstream tests on purpose (testBlendedInfixSuggesterDedupsOnWeightTitleAndPayload, LUCENE-6680).
boundedTreeAdd (:294-306):
if (results.size() >= num) {
  if (results.first().value < result.value) {
    results.pollFirst();      // the lowest entry is removed first
  } else {
    return;
  }
}
results.add(result);          // ... and this add does nothing for a duplicate
Step by step for lookup("lake", false, 2) over {the lake 1000, lake 950, lake 950, my lake 920} (hits in raw-weight order, set bounded at 2):
| hit | blended | what happens | set after |
|---|---|---|---|
| the lake 1000 | 900 (lake is word 1: x 0.9) | add | {the lake/900} |
| lake 950 | 950 (starts with lake: x 1) | add | {the lake/900, lake/950} |
| lake 950 (repeat) | 950 | full and 900 < 950: pollFirst() removes the lake/900; add(lake/950) is a no-op | {lake/950} |
| my lake 920 | 828 | set not full: add | {lake/950, my lake/828} |
Result [lake/950, my lake/828]; the num=3 lookup returns [lake/950, the lake/900, my lake/828], so the num=2 answer is not its first two. Without the fourth document the set ends at {lake/950}.
- Two entries that compare equal: the same text, the same blended long value and equal or absent payloads. Identical entries do it, and so does the same text with raw weights that blend to the same value (1001 and 1000 at word 1 both give 900). Entries with unique payloads are told apart and are not affected.
- The later copy must blend above the lowest collected value while the set is full: an earlier, higher-weighted match was blended down because the query matched a later word of it. With the stock
CUSTOMblender (coefficient 1,:373-375) only the x10 scaling of weights with |w| < 10 (:268-270, #11193) can reorder hits that way; aCUSTOMsubclass that overridescalculateCoefficient, asCUSTOM's javadoc asks (:74), with a position coefficient is hit like the position blenders (executed:[lake/950, my lake/828]for the lake example withnum=2). - The copy must arrive after the set is full. Hits arrive in raw-weight order and, for equal raw weights, in the suggester index's document order (
AnalyzingInfixSuggester.java:166, 739), so with tied weights the input order matters: the no-weight-field example reordered to {the apple, the apple, the big apple, a big red apple} returns the right[the apple/9, the big apple/8](executed). A rebuild from input in another order can change whether, and which, suggestion is lost (reading). The lake example has no tie apart from the identical pair. - Once the set holds
numentries an eviction is followed by a refill from the next distinct hit, so at most one of the correct topnumof the fetched hits is missing: with at leastnumdistinct suggestions fetched, the list hasnumornum-1entries, andnum=1is never affected (code reading and two small models of the method, not a Lucene run).
Default constructor, StandardAnalyzer without stop words, DocumentDictionary, on main, 10.5.2 and 9.12.3 with and without assertions: {the lake 1000, lake 950, lake 950, my lake 920} gives [lake/950, my lake/828] for num=2; without my lake, [lake/950]; with no weight field, {the apple, the big apple, the apple, a big red apple} gives [the apple/9, a big red apple/7] instead of [the apple/9, the big apple/8] for num=2 (every weight 0 becomes 10, so the blended values are 9, 8 and 7). Without the repeated entry the answer is right.
Exposure and likelihood362 words
- Who. Users of
BlendedInfixSuggester(@lucene.experimental,BlendedInfixSuggester.java:54). It is opt-in, but its default constructor and settings are affected, and so are all three position blenders (POSITION_LINEAR,POSITION_RECIPROCAL,POSITION_EXPONENTIAL_RECIPROCAL; the last one only in the finder's exhaustive and random scopes). The stockCUSTOMblender (nocalculateCoefficientoverride) is hit only through the x10 scaling of weights with |w| < 10; aCUSTOMsubclass with a position coefficient is hit like the position blenders (executed). - What it takes. A suggestion text that repeats with weights that blend to the same value and with equal or no payloads: the same weight always does, and nearby weights can too (1001 and 1000 both give 900 at word 1). Repeats with equal weights are the ordinary result of a
DocumentDictionaryover a field whose values repeat across documents (product names, titles, places, tags), with a repeating weight field or with none: "If the weight field is not defined, the value of the weight is0" (DocumentDictionary.java:41-42). Plus a lookup for which a higher-weighted match is blended down below the repeated one (the normal case for infix matches such asthe lakeforlake), with the copy arriving after the set is full. - Scale. None: three entries suffice. Each affected lookup returns at most one suggestion too few (
num-1), or a weaker suggestion in place of a stronger one it fetched. It reproduced in every recorded run (the same 3 of 4 tests failed in 20 randomized repetitions and in 12 other runs with their own root seeds), and nothing is logged or thrown; the index is not changed. With tied raw weights the input order decides whether, and which, suggestion is lost. - Likelihood: plausible. Short prefixes with more matches than
numare the normal autocomplete case, and one missing or substituted entry is easy to overlook, which fits the absence of any diagnosed report since 2014. - Not affected: dictionaries in which no two entries share the text and the payload (or both lack one), for example entries with unique payloads;
num=1; and lookups in which every copy arrives while the set still has room.
The test shows that a default BlendedInfixSuggester drops a distinct suggestion when a duplicate arrives while its result set is full: boundedTreeAdd evicts the lowest result before TreeSet.add rejects the duplicate.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.suggest.analyzing;

import java.io.StringReader;
import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.standard.StandardAnalyzer;
import org.apache.lucene.search.suggest.FileDictionary;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestBlendedInfixDuplicateEviction extends LuceneTestCase {

  public void testDuplicateEvictsDistinctSuggestion() throws Exception {
    String entries = "the lake\t1000\nlake\t950\nlake\t950\nmy lake\t920\n";
    try (Directory dir = newDirectory();
        Analyzer a = new StandardAnalyzer();
        BlendedInfixSuggester suggester = new BlendedInfixSuggester(dir, a)) {
      suggester.build(new FileDictionary(new StringReader(entries)));
      // num=3 gives [lake/950, the lake/900, my lake/828]; expected its top 2, actual: my lake 2nd
      assertEquals("[lake/950, the lake/900]", suggester.lookup("lake", false, 2).toString());
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-700/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/suggest/build/libs/lucene-suggest-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.suggest.analyzing.TestBlendedInfixDuplicateEviction
- Expected vs actual
- For {the lake:1000, lake:950, lake:950, my lake:920},
lookup("lake", false, 2)should be the top 2 of the num=3 result,[lake/950, the lake/900]; actual[lake/950, my lake/828], with-eaand-da.
More files, environment, full output36 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: expected:<[lake/950, [the lake/900]]> but was:<[lake/950, [my lake/828]]>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.search.suggest.analyzing.TestBlendedInfixDuplicateEviction.testDuplicateEvictsDistinctSuggestion(TestBlendedInfixDuplicateEviction.java:35)- Identical suggestions are merged on purpose (the LUCENE-6680 test); losing a different one is not:
the lakewas fetched and outranks the returnedmy lake. testRequiresMoreandtestSuggesterCountForAllLookupsassert top-numselection and exact counts when enough matches were fetched.- No contract forbids repeated entries, and
DocumentDictionarydocuments weight 0 for every entry when there is no weight field.
The full argument265 words
- Contract. The class javadoc: the suggester "transforms the weight after search to take into account the position of the searched term into the indexed text ... it increases the number of elements searched and applies the ponderation after" (
BlendedInfixSuggester.java:48-55);BlenderTypedocuments the formulas, for exampleweight*(1 - 0.10*position)(:76). The bound is commented "we reduce the num to the one initially requested" (:226) andboundedTreeAddis documented as "Add an element to the tree respecting a size limit" (:287-293): a bounded top-numcollector. - Tests.
testRequiresMore(TestBlendedInfixSuggester.java:198) asserts top-numselection by blended weight inside the fetch window and exact sizes 2 and 3;testSuggesterCountForAllLookups(:340, from SOLR-7865) assertssize() == numon every lookup path. The dedup test (:278) looks up withnum=10and at most 2 distinct results (:465), so its set never fills. No test or javadoc describes a duplicate evicting another suggestion. - History. Upstream fixed earlier losses or miscounts of BlendedInfix results as bugs: a LUCENE-5354 follow-up (
20461c90103, 2014: a comparator that collapsed distinct results), LUCENE-6680 (#7738, "don't lose a suggestion that differs only in payload from another suggestion", 5.3.0) and SOLR-7865 (too many results). None changedboundedTreeAdd. - Legal input. No contract forbids repeated entries (
Dictionary,InputIterator,DocumentDictionary), andDocumentDictionary.java:41-42documents weight 0 when the weight field is missing, which makes equal weights for repeated names the normal case. - The fix keeps the intended part. With the guard, identical suggestions are still merged and the LUCENE-6680 test passes.
The devil's-advocate check257 words
The strongest case for "works as designed" (the independent reproduction, the intended-behaviour check and the cross-model reviews built it; the cross-model reviews rated it moderate, the independent reproduction and the intended-behaviour check rejected it without a rating): Lookup documents num only as the "maximum number of results to return" (Lookup.java:190, 206, 219); the numFactor window already makes the blended top-num approximate (testRequiresMore shows a small numFactor missing a result); merging duplicates is intended; on #7397 (LUCENE-6336) a reply says DocumentDictionary "suggests documents, not terms" and another that whether a suggester dedups "is really up to each impl", and @mikemccand proposed deduplicating once, in a dictionary wrapper at indexing time; an order-dependent streaming collector could be called implementation-defined; the class is @lucene.experimental. For the 3-entry case there is even a consistent reading: take the blended top 2 hits (lake, lake), then merge them into one.
Why it fails: the 4-entry case fits no ranking rule. Dedup-then-top-2 gives [lake/950, the lake/900], top-2-then-dedup gives [lake/950], and the code returns [lake/950, my lake/828], a suggestion ranked below one it fetched and dropped; the answer depends on the order in which hits arrive. All 4 hits are inside the fetch window of 20, "maximum" does not cover replacing a better result with a worse one, and @lucene.experimental is about API stability. Build-time dedup is a sound workaround and maintainers may prefer it as a feature, but it does not make the collector's answer right for input the dictionaries accept. Verdict: not intended, a defect.
Recommended A: skip a duplicate before evicting
In boundedTreeAdd, return early when the set already holds the result (results.contains(result)), so a duplicate is merged without evicting anything. The repro passes 4 of 4, upstream TestBlendedInfixSuggester 9 of 9, and the whole suggest module passes (240 tests, 0 failures, 7 skipped by their own markers).
if (results.contains(result)) {
  // a duplicate (same weight, text and payload) is collapsed; it must not evict another result
  return;
}
All options and trade-offs3 options · 658 words
Options A and B were built and checked in a scratch worktree at a9779ef3c193 (removed after the runs); C is a workaround for released versions.
The finder's guard, +5 lines at the top of boundedTreeAdd. Every other path of the method is unchanged.
if (results.contains(result)) {
  // a duplicate (same weight, text and payload) is collapsed; it must not evict another result
  return;
}
Trade-offs
- Identical suggestions are still merged; a non-duplicate behaves exactly as before.
- Cost: one extra
TreeSetlookup, O(lognum) on a set of at mostnumentries, per fetched hit (up tonum * numFactorhits per lookup); not benchmarked.
What the checks validated
- This doc's repro: 3 of 4 fail on stock, 4 of 4 pass with the fix (gradle with assertions on; the repro runner with -ea and -da).
- Upstream
TestBlendedInfixSuggester: 9 of 9, including the LUCENE-6680 dedup test. - All of
:lucene:suggest:test: 240 tests (236 upstream + 4 new), 0 failures, 7 skipped (6@Ignore, 1@Nightly), with assertions off (two runs) and with-Ptests.asserts=true(one run, added in the check resolution: the first module run passed no flag, and for its seed the build picks assertions off);:lucene:suggest:checkGoogleJavaFormatand:lucene:suggest:check -x test(ecjLint, forbiddenApis) pass with the fix and the new test. - Earlier checks: the finder's, the reproducers', the cross-model reviewers' and the audit's tests pass with the same guard (the adjudication re-ran the independent reproduction's), and the finder's exhaustive scope finds 0 mismatches.
Uses TreeSet.add's return value instead of a separate lookup.
if (results.size() >= num) {
  // add first: only a result that was really added (not a collapsed duplicate) evicts the lowest
  if (results.first().value < result.value && results.add(result)) {
    results.pollFirst();
  }
  return;
}
results.add(result);
Trade-offs
- Same results as A in every case by code reading, including the rule that an equal value does not replace an earlier hit, and no extra lookup; slightly less obvious to read.
- A plainer "add, then trim to
num" (suggested by a cross-model review) also fixes the bug but changes ties: a later hit with the same blended value could evict an earlier one by text order (reading, not run).
What the checks validated
- This doc's repro 4 of 4 (gradle; the repro runner with -ea and -da); all of
:lucene:suggest:test, 240 tests, 0 failures, 7 skipped (assertions on); the fact check ran the whole module again with-Ptests.asserts=false: 240 tests, 0 failures, 7 skipped.
Collapse the entries that share the text and the payload (or that both have none) into one before build, for example in a wrapping InputIterator. Removing only exact (text, weight, payload) repeats is not enough: the independent reproduction's input {the big apple 1100, x apple 1001, x apple 1000} has none, yet returns [x apple/900] for num=2, because 1001 and 1000 both blend to 900.
Trade-offs
- The merged entry needs one weight (for example the maximum, or an average as @janhoy suggested on #7397) and, if contexts are used, a rule for them (for example their union); that choice is the application's. On #7397, @mikemccand proposed such a dedup dictionary wrapper and deduplicating once at indexing time, so maintainers may also see build-time dedup as a feature to add. Giving each entry a unique payload also avoids the eviction (code reading), but then repeated texts are no longer merged and appear more than once.
What the checks validated
- The independent reproduction's input collapsed by hand to {the big apple 1100, x apple 1001} returns the right
[x apple/900, the big apple/880](main, -ea and -da), and the repro's control, the 4-document input without the repeatedlake, returns the right answer. No wrapper was written or run.
Downstream, Solr's BlendedInfixLookupFactory with a DocumentDictionaryFactory and no weight or payload field is exactly the trigger configuration (read, not run in Solr).
An AI tool compared the stock suggesters with reference models written from their javadoc. While writing the model it noticed the evict-then-add order, then checked every dictionary of 1 to 4 entries over 3 texts and 3 weights: 456 too-few and 288 wrong-ranking results per position blender, none with the fix. No model checker or prover was used.
The method in full160 words
Method: bounded-exhaustive translation validation (the hunt's "semi-formal" tier), a hunt unit (cross-implementation differential of the suggest lookups), 2026-10-27, main a9779ef3c193.
- The reference for this class, written from its javadoc: take the fetched
num * numFactorhits, score them by the documentedBlenderTypeformulas, collapse identical results and return the topnum. - The hypothesis came from reading
boundedTreeAddwhile writing that reference. The finder then added scope B2: every sequence of 1 to 4 entries over the texts {a, "b a", "c a"} and the weights {10, 100, 1000}, duplicates allowed (7,380 dictionaries). The stock jar gave 456 too-few and 288 wrong-top-N mismatches for each of the three position blenders, and 0 with the fix shadowed in. A random scope of 100,000 dictionaries also hit it in all fourBlenderTypes,CUSTOMthrough the small-weight x10 scaling. - A JUnit repro on the public API confirmed it on main, 10.5.2 and 9.12.3. No model checker, SMT solver or prover was used.
No prior report found in more than 200 queries over GitHub, JIRA, the Lucene and Solr lists, downstream projects and the web, plus the changed files of all 409 open PRs (2026-10-27). The closest item, #7738 (LUCENE-6680), fixed a different part of the same dedup.
Searches4 searches
No report of this mechanism was found; the registry's novelty is "new". Two items overlap partly: #7397 (duplicates and short lists after a dedup step, an under-fetch effect in AnalyzingInfixSuggester) and an unanswered 2019 Solr user thread (fewer suggestions than requested with BlendedInfixLookupFactory over a no-weight dictionary; its details point to under-fetch, but this bug cannot be ruled out as one contributor). The adjudication, the prior-report follow-up and the cross-model fact check flagged them under the rule that a partial overlap counts as "known".
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; downstream repositories; dev@, java-user@, issues@, commits@; the LUCENE JIRA archive; the web | 2026-10-27 | 3 runs of a scripted prior-report search: 48 issue/PR, 9 commit, 6 downstream, 60 mailing-list and 12 JIRA queries, 6 web queries answered (identifiers such as boundedTreeAdd and LookUpComparator, duplicate handling, blending and ranking) | no report; boundedTreeAdd has 0 hits in issues, PRs and JIRA |
| GitHub by hand (apache/lucene, apache/lucene-solr, apache/solr, apache/lucenenet, Elasticsearch, OpenSearch, all of GitHub) | 2026-10-27 | 37 searches in all states plus 2 code searches for a copy with a duplicate guard; the changed-file lists of all 409 open apache/lucene PRs | of the open PRs that touch the file, #13948 and #16847 change only the doc-value reads in createResults and #16911 is the branch_10x decommission that empties that branch; the Lucene.NET port and one downstream copy carry the same logic, unreported |
| SOLR and LUCENE JIRA; solr-user@ and users@solr | 2026-10-27 | 10 JQL queries (4 SOLR issues read in full); 12 list queries, 13 threads read | two unanswered user threads (2019, 2021) report fewer suggestions than requested; their details point to under-fetch, but this bug cannot be ruled out as one contributor to the 2019 report (flagged as a partial overlap) |
| Related items (read) | 2026-10-27 | the comment threads of #7738, #7397, #6418, #9390, #11193 and SOLR-7865 | different mechanisms: #7738 changed the comparator, #7397 is under-fetch in AnalyzingInfixSuggester, SOLR-7865 too many results, #9390 and #11193 small-weight scaling |
Introduced with the class itself by LUCENE-5354 (fb5fd910780, 2014) and first released in 4.7.0. All 19 releases run, from 4.7.0 to 10.5.2, and main are affected; 4.6.1 has no such class. Not fixed upstream.
Versions tested6 rows
Introduced by LUCENE-5354 "Blended score in AnalyzingInfixSuggester" (issue #6418), the commit that added the class: fb5fd910780 on trunk and 89a9302d5a7 on branch_4x, 2014-01-09 (a JIRA patch committed by @mikemccand; no pull request). Both ingredients came with it: the evict-then-add order and the comparator that treats equal text and value as equal. git log -L on boundedTreeAdd lists only this commit and the LUCENE-9570 reformat (2cbf261032d, 2021); the method is identical after whitespace normalization in all 110 local release tags that contain the class.
- In 4.7.0-5.3.1 and 5.4.0 the 3-argument
lookupalso over-fetched (SOLR-7865), which hides the small repro on that path but not the eviction: with 20 or 200 distinct suggestions plus one duplicate, one fewer comes back, withoutthe lake. The 4-argumentlookupshows the small-case output in every executed release. - Before 5.3.0 the comparator ignored payloads, so payload-only variants also counted as duplicates (reading). LUCENE-6680 (#7738, 5.3.0) narrowed the trigger to equal payloads; LUCENE-8343 (#9390, 8.0.0) added weight 0 -> 1 and the x10 scaling, a second route to equal blended values.
- Not fixed: unchanged on upstream main
a95c754ee003,branch_10xandbranch_10_6.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's repro 3 of 4 fail with -ea and -da (gradle and the repro runner); the finder's 3 of 4 |
| 10.5.2, 9.12.3 | affected | this doc's repro 3 of 4 fail (10.5.2 -ea, 9.12.3 -da); the finder's, the independent reproduction's, the cross-model review's and the intended-behaviour check's tests fail too |
| 10.0.0, 9.0.0, 8.11.4, 8.0.0, 7.7.3, 6.6.6, 6.0.0, 5.5.5, 5.4.1, 5.3.2 | affected | the history harness: [lake/950] (3 documents) and [lake/950, my lake/828] (4 documents) through both the 4-argument and the 3-argument lookup |
| 5.4.0, 5.3.1, 5.0.0, 4.10.4, 4.8.0, 4.7.2, 4.7.0 | small case hidden on one path | the 4-argument lookup gives the same output; the 3-argument lookup over-fetches (SOLR-7865), and with 20 or 200 distinct suggestions plus one duplicate it returns one fewer |
| 4.6.1 | no such class | the harness does not compile: no BlendedInfixSuggester |
| main + fix A | fix | every repro passes; the whole suggest module passes |
The finder's exhaustive check, independent reproducers, reviews by a model of another family and a fourth audit reproduced it with their own tests; an adjudication and a registry re-run repeated earlier tests with fresh seeds: confirmed, high confidence.
Checks and verdicts430 words
Each check wrote and ran its own test unless noted; the adjudication and the registry re-run repeated earlier tests with fresh seeds.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Exhaustive scope: 456 too-few and 288 wrong-top-N per position blender, 0 with the fix. JUnit fails 3 of 4 on main (-ea, -da), 10.5.2 and 9.12.3; 60 of 80 in 20 randomized repetitions under one root seed. |
| cross-model review, refute lens (OpenAI GPT-5.6) | real, high | Own test fails 2 of 4 (-ea, -da), controls pass; with the guard 4 of 4 and upstream TestBlendedInfixSuggester 9 of 9. Intended-behaviour argument: moderate. Ran on main ea57360912ed, whose BlendedInfixSuggester.java is identical. |
| Independent reproducer | real | Own test fails 5 of 8 on main, 10.5.2 and 9.12.3 (-ea, -da); widened the trigger to raw weights 1001 and 1000 and confirmed the CUSTOM sub-case; 8 of 8 with the guard (its guard is not an independent design). |
| Cross-model review, intended lens (OpenAI GPT-5.6) | real, high | Own test fails 2 of 5 on main (-ea, -da), 10.5.2 and 9.12.3, passes with the fix; suggested add-then-trim as an alternative. Ran on main ea57360912ed; the cross-model review step re-ran its test and the finder's on a9779ef3c193 (2 of 5 and 3 of 4 fail, -ea and -da; pass with the fix). |
| Intended-behaviour devil's advocate | real | Own DocumentDictionary test (with and without a weight field) fails 3 of 3 on main (-ea, -da), 10.5.2 and 9.12.3; passes with the fix. Built the strongest intended case and showed why it fails. |
| adjudication | confirmed, high | Re-ran the independent reproduction's test (5 of 8 fail, -ea and -da) and the intended-behaviour check's (3 of 3) with new seeds; the independent reproduction's passes 8 of 8 with the fix. |
| registry re-run and fourth audit | keep | The finder's repro on a clean checkout: 3 of 4 fail (-ea, -da), 4 of 4 with the fix. The audit's own DocumentDictionary test: [apple/480, green apple/270] instead of [apple/480, red apple/450], passes with the guard. |
| this doc's runs | reproduced; fixes A and B validated | The doc's own test on main, 10.5.2 and 9.12.3 and through gradle; both fixes against the whole suggest module. |
| check resolution (this doc) | scope checks added | Three new tests on main (-ea, -da): the no-weight-field input with the copy first returns the right answer (input order matters); a CUSTOM subclass with a position coefficient returns [lake/950, my lake/828]; the independent reproduction's 1001/1000 input collapsed on the text returns the right answer. With fix A all 3 pass. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 470 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,347 words
- Registry title
- BlendedInfixSuggester loses a distinct suggestion when a duplicate entry arrives while its result set is full: boundedTreeAdd evicts the lowest result before TreeSet.add rejects the duplicate, so lookup returns num-1 suggestions, or a lower-ranked fetched suggestion in place of a higher-ranked one
- Area
- suggest / analyzing: BlendedInfixSuggester result collection
- Priority
- Medium, rank 50: The opt-in BlendedInfixSuggester deterministically returns fewer than n suggestions, or a lower-ranked one, when the dictionary repeats a text with the same weight and the result set is full.
- Impact class
- silent wrong results
- Impact note
- Applications that use BlendedInfixSuggester (the default constructor or any position BlenderType; CUSTOM only when the separate small-weight x10 scaling reorders hits) and feed it two entries that compare equal (same text, same blended long weight, no or equal payloads), for example a DocumentDictionary over documents that repeat a suggestion text with the same weight or with no weight field (documented weight 0), get num-1 suggestions, or a lower-ranked suggestion instead of a higher-ranked fetched one, on every lookup where a later copy of the duplicate blends above the lowest collected result; no scale is needed, entries with unique per-entry payloads are not affected, and only the returned list is wrong (the suggester index is unchanged).
- Summary
- You build a BlendedInfixSuggester with its default settings (POSITION_LINEAR, numFactor 10) from {the lake:1000, lake:950, lake:950, my lake:920} and call lookup("lake", false, 2); blending gives lake 950, the lake 900 and my lake 828, num=3 returns [lake/950, the lake/900, my lake/828], so you expect [lake/950, the lake/900]. Instead you get [lake/950, my lake/828], and without 'my lake' only [lake/950]. When the bounded result set is full, boundedTreeAdd (BlendedInfixSuggester.java:294-306) removes the lowest result with pollFirst() before it calls results.add(result), and that add does nothing for the second 'lake' because LookUpComparator (:383-407) already holds an equal element, so 'the lake' is lost and a later, lower-ranked hit takes its slot.
- Introduced
- fb5fd910780d5862101cbd5f49f343b40eeca025 (trunk, svn r1556952) and 89a9302d5a743aca276621ba04196c1fc01d14a2 (branch_4x, r1556954): LUCENE-5354 'add new BlendedInfixSuggester' (issue #6418; a JIRA patch committed by mikemccand; Subversion era, no pull request). Both ingredients arrived in this commit: the evict-then-add order of boundedTreeAdd and a comparator under which equal text and value compare as 0; git log -L on boundedTreeAdd lists only this commit and the 2021 LUCENE-9570 reformat (2cbf261032d). Later changes narrowed or widened the trigger without touching boundedTreeAdd: LUCENE-6680 (#7738, 05363e169d9, 5.3.0) made the comparator also compare payloads, and LUCENE-8343 (#9390) added the small-weight x10 scaling [read: full-history clone; executed: 4.6.1 has no such class, 4.7.0 is affected] (2014-01-09)
- First affected version
- 4.7.0 [exec] (the class first shipped in 4.7.0; 4.6.1 has no BlendedInfixSuggester [exec])
- Affected versions
- Every release from 4.7.0 to 10.5.2 and main a9779ef3c193 [exec on 4.7.0, 4.7.2, 4.8.0, 4.10.4, 5.0.0, 5.3.1, 5.3.2, 5.4.0, 5.4.1, 5.5.5, 6.0.0, 6.6.6, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main with the follow-up's history harness (main also with -da); the finder's JUnit fails on 9.1.0, 9.12.3, 10.5.2 and main; the independent reproduction's, the cross-model review's and the intended-behaviour check's own tests fail on 10.5.2 and 9.12.3]; boundedTreeAdd is identical after whitespace normalization in all 110 local release tags that contain the class (8.9.0-8.11.3 are not tagged locally and are inferred) [read]. In 4.7.0-5.3.1 and 5.4.0 the 3-argument lookup also over-fetched (SOLR-7865, cap num*numFactor or num*numFactor^2), which hides the small repro on that path but not the eviction: with K = 20 or 200 distinct suggestions plus one duplicate, K-1 come back [exec]. Not fixed: upstream main a95c754ee003 (2026-10-26), branch_10x and branch_10_6 are unchanged, so 10.6.0 (released 2026-10-29 from branch_10_6) is affected too, and no open PR changes boundedTreeAdd [read].
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; a fix PR is open upstream.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (searched 2026-10-27, read-only; the prior-report record, verdict new): three scripted prior-report searches (48 GitHub issue/PR, 9 commit, 6 downstream, 60 mailing-list and 12 JIRA-archive queries, 6 web queries answered), 37 manual GitHub searches (apache/lucene in all states, apache/lucene-solr, apache/solr, apache/lucenenet, Elasticsearch, OpenSearch, all of GitHub, commits) plus 2 code searches for a copy with a duplicate guard, the changed-file lists of all 409 open apache/lucene PRs, 10 JQL queries with 4 SOLR issues read in full, 12 Solr user-list queries with 13 threads read, and 7 web queries. 'boundedTreeAdd' has 0 hits in GitHub issues and PRs and in JIRA. Related, not this bug: #7738 (LUCENE-6680, fixed in 5.3.0) made the comparator keep suggestions that differ only in payload and did not change boundedTreeAdd (its test uses num=10 with 2 inputs, so the set never fills); #7397 (LUCENE-6336, open) is about AnalyzingInfixSuggester returning duplicates, and one 2016 comment warns that a dedup step after the fetch can leave fewer than N results (the under-fetch effect, a different mechanism and class); SOLR-7865 (too many results); #9390 and the open #11193 (small-weight scaling, one route into this bug); #6418 (the introducing issue, 15 comments, nothing on eviction). Two unanswered Solr user threads (2019, 2021) report fewer suggestions than requested with BlendedInfixLookupFactory; their details do not fit this bug (below, novelty_note). Open PRs #13948, #16847 and #16911 touch the file but not boundedTreeAdd. The Lucene.NET port and a downstream copy (FoundationDB/fdb-record-layer#1616) carry the same logic with no report. Gaps: inline PR review comments are not searchable; some planned web queries were throttled (their terms were covered by other queries). Update 2026-11-02: #16911 (open when searched) merged 2026-10-29 as 48cf3f515d6, which emptied branch_10x to a README tombstone (10.6 is the last 10.x minor; 10.x fixes go to branch_10_6); it fixes nothing here.
- Lucene commit tested
- main
a9779ef3c193(commit 2026-10-26; tested 2026-10-27) on OpenJDK 25.0.3, Linux aarch64: this doc's JUnit repro through the repro runner with -ea and -da (also 20 randomized repetitions) and through gradle in a scratch worktree, stock and with fixes A and B, plus the whole suggest module with each fix (removed after the runs); the same repro on the 10.5.2 and 9.12.3 jars (SHA-1 checked against Maven Central); the history step's harness on 4.6.1 (no such class) and 19 releases from 4.7.0 to 10.5.2 and main.
- Finding record
a Lucene main checkout lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/BlendedInfixSuggester.java:48-55 (class javadoc: transforms the weight after search, applies the ponderation after; @lucene.experimental at :54), :72-84 (BlenderType formulas), :87-91 (default constructor: POSITION_LINEAR, DEFAULT_NUM_FACTOR), :64 (DEFAULT_NUM_FACTOR = 10), :214-285 (createResults: TreeSet with LOOKUP_COMP, actualNum = num / numFactor, weight 0 -> 1 and x10 small-weight scaling, boundedTreeAdd per hit), :294-306 (boundedTreeAdd: pollFirst() then results.add(result)), :383-407 (LookUpComparator: value, then key, then payload); identical in Lucene main ea57360912eda Lucene main checkout lucene/suggest/src/java/org/apache/lucene/search/suggest/Lookup.java:190, :206, :219 ('@param num maximum number of results to return'); DocumentDictionary.java:41-42 ('If the weight field is not defined, the value of the weight is 0'); lucene/suggest/src/test/.../TestBlendedInfixSuggester.java:198 (testRequiresMore), :278 (testBlendedInfixSuggesterDedupsOnWeightTitleAndPayload, LUCENE-6680), :340 (testSuggesterCountForAllLookups)
- The finding in 30 seconds
a Lucene main checkout lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/BlendedInfixSuggester.java:72-84, 191-200, 214-285, 287-306, 383-407a Lucene main checkout lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/AnalyzingInfixSuggester.java:166, 739-745a Lucene main checkout lucene/suggest/src/test/org/apache/lucene/search/suggest/analyzing/TestBlendedInfixSuggester.java:278
- Who is affected
a Lucene main checkout lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/BlendedInfixSuggester.java:54, 86-91, 265-270; lucene/suggest/src/java/org/apache/lucene/search/suggest/DocumentDictionary.java:41-42
- Why it looks unintended
a Lucene main checkout lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/BlendedInfixSuggester.java:48-55, 76, 226, 287-293; lucene/suggest/src/java/org/apache/lucene/search/suggest/Lookup.java:190, 206, 219; lucene/suggest/src/java/org/apache/lucene/search/suggest/DocumentDictionary.java:41-42a Lucene main checkout lucene/suggest/src/test/org/apache/lucene/search/suggest/analyzing/TestBlendedInfixSuggester.java:198, 278, 340, 465
- TestBlendedInfixDuplicateEviction.java (JUnit test):
repro/LFV-700/src/org/apache/lucene/search/suggest/analyzing/TestBlendedInfixDuplicateEviction.java(38 lines)
A summary diagram (PNG), produced separately from this text from its own probe runs of the lake example. An independent diagram check compared every value, API name and line number on screen with the code and re-ran the probe; the diagram was re-rendered after it (labels on lines 299 and 305 no longer hidden by the line highlight, the code caption corrected). The alt text was checked against the final PNG.
assets/LFV-700/bug.png(470 KB)