Every language analyzer ships a stopwords.txt and exposes it through the static getDefaultStopSet(). The files mark comments with #. Three analyzers read their file with a loader overload that keeps every line, so their comment lines (a header, a bibliography, English glosses) become stop-word entries.
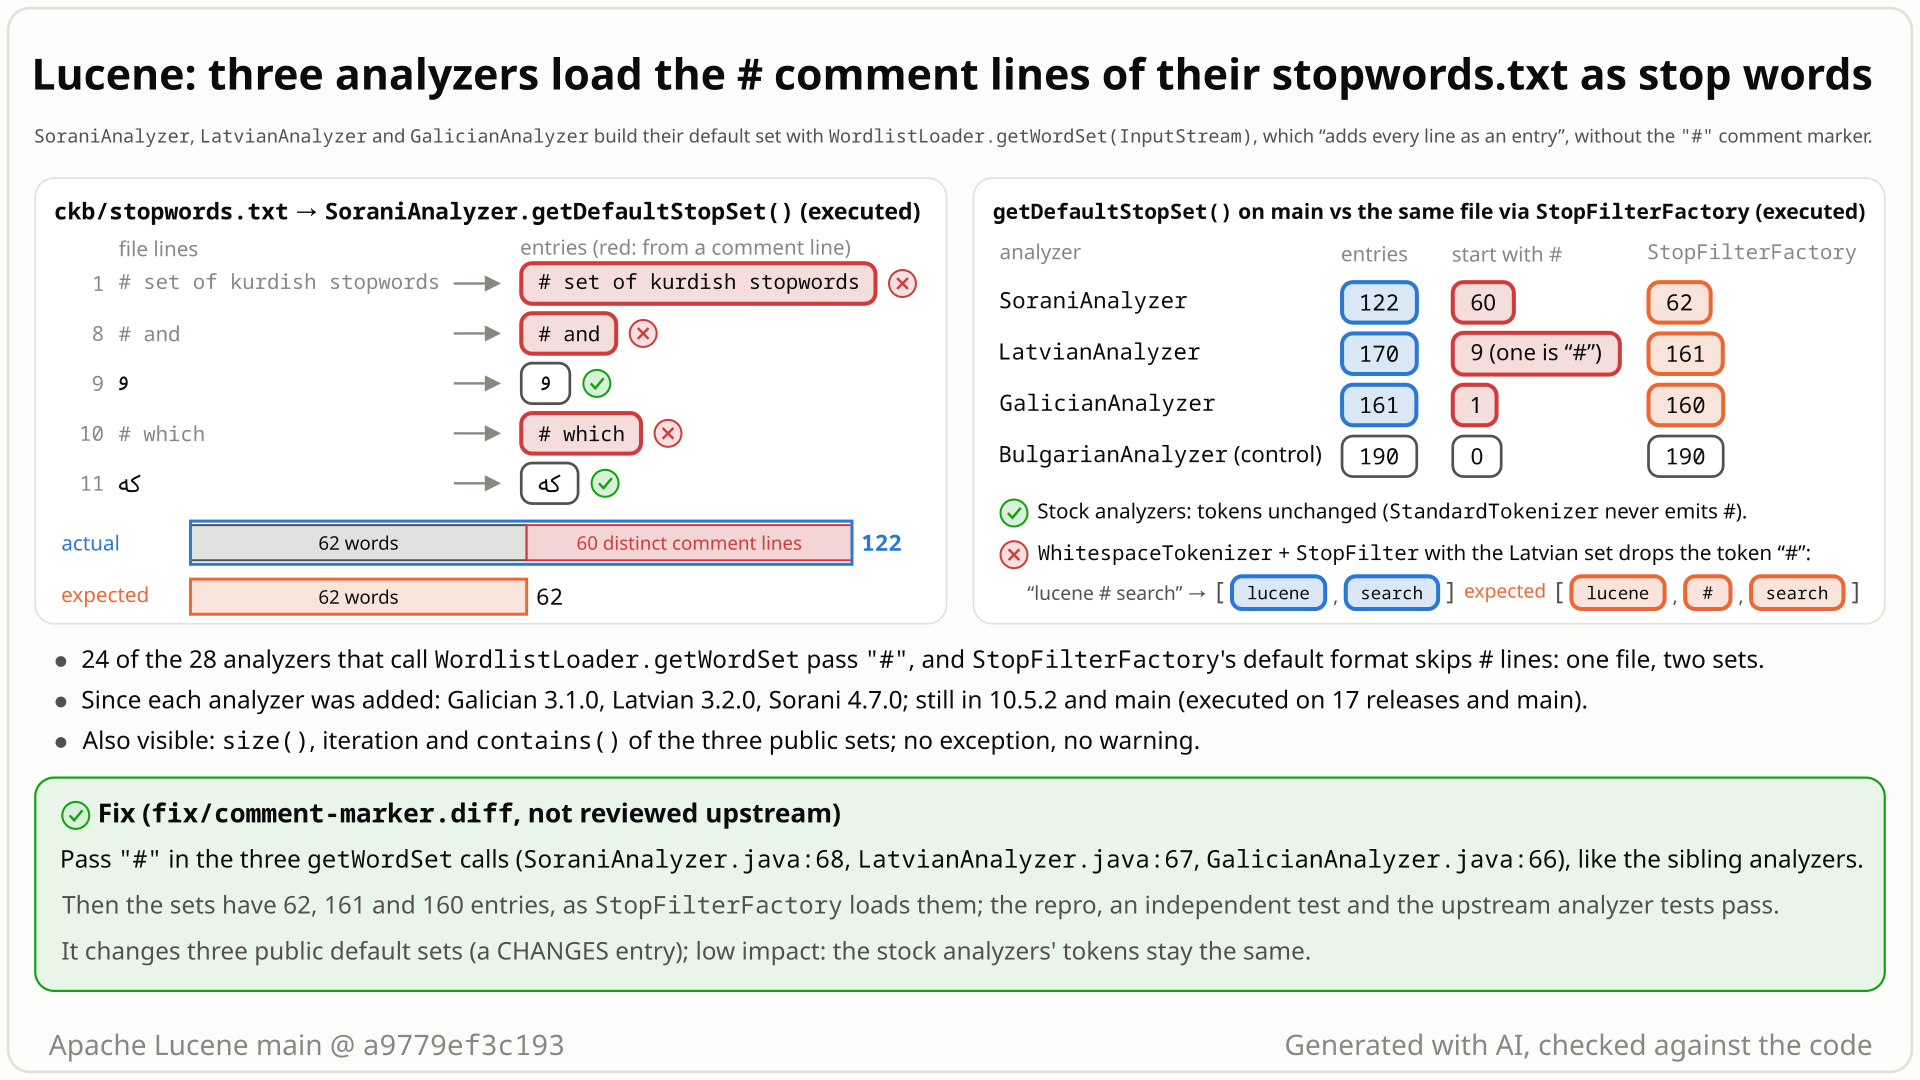
# header and gloss lines are kept by getWordSet(InputStream), so 60 of the 122 entries are comments where the comment marker would give the 62 words. The summary card shows all three analyzers, the reused Latvian set dropping #, and the fix. Select the still to open it at full size. Generated with AI, checked against the code.- Call
LatvianAnalyzer.getDefaultStopSet(), "the default stop words set", built from the "File containing default Latvian stopwords". That file holds 161 distinct stop words and 9 comment lines starting with#, such as# Conjunctionsand a bare#. - You expect the 161 words. Lucene's own
StopFilterFactoryreads the same file as 161 entries, and 24 other analyzers pass the#comment marker for their files. - You get 170 entries: the 9 comment lines are in the set. The analyzer loads its file with
WordlistLoader.getWordSet(InputStream), which "adds every line as an entry", not with the overload that takes the"#"marker. - Sorani is worse: 60 of 122 entries are comments (
# set of kurdish stopwords,# and, ...); Galician has 1 of 161 (# galican stopwords). Every release since 3.1.0 has it. - The stock analyzers' tokens are unchanged:
StandardTokenizernever emits#or a token with a space. Reused in another chain the set bites:WhitespaceTokenizer+StopFilter(LatvianAnalyzer.getDefaultStopSet())turnslucene # searchinto[lucene, search].
Anyone who calls getDefaultStopSet() on these three analyzers: size(), iteration and contains() include comment text, and the set differs from what StopFilterFactory loads from the same file. Searching with the stock analyzers is not affected. Tokens are dropped only when a set is reused with another tokenizer, such as a lone # with the Latvian set and WhitespaceTokenizer.
Mechanism, terms and numbers561 words
SoraniAnalyzer, LatvianAnalyzer and GalicianAnalyzer build their public default stop set from a bundled stopwords.txt with WordlistLoader.getWordSet(InputStream), the overload that "adds every line as an entry" (WordlistLoader.java:80-90), and pass no comment marker (SoraniAnalyzer.java:65-68, LatvianAnalyzer.java:64-67, GalicianAnalyzer.java:63-66). Their files mark comments with #, so the header, bibliography, category and English-gloss lines become entries: 60 of the 122 entries of SoraniAnalyzer.getDefaultStopSet(), 9 of 170 for Latvian (including a bare #) and 1 of 161 for Galician. 24 of the 28 analyzers that call getWordSet pass "#", and Lucene's own StopFilterFactory loads the same three files to 62, 161 and 160 entries, so one bundled file gives two different sets inside Lucene. The stock analyzers' tokens do not change (StandardTokenizer never emits # or a token with a space); the visible effects are the sets' size(), iteration and contains(), and dropped tokens when a set is reused with another tokenizer (with WhitespaceTokenizer the Latvian set removes a standalone #). Each analyzer has had it since it was added (Galician 3.1.0, Latvian 3.2.0, Sorani 4.7.0), through 10.5.2 and main. The fix is to pass "#" in the three calls.
- Stop words: frequent words ("and", "of") that an analyzer removes from the token stream. Each language analyzer bundles a list as a resource
stopwords.txt, loads it once into aCharArraySetand returns it from the public staticgetDefaultStopSet(); itsStopFilterremoves every token that is in the set. - The file format: one word per line; a line that starts with
#is a comment.StopFilterFactory's default "wordset" format documents exactly this ("allows whole line comments beginning with the \"#\" character",StopFilterFactory.java:52-55). WordlistLoader(@lucene.internal) has two families ofgetWordSetoverloads: without a comment marker, it "adds every line as an entry" (:80-90, and "Every line ... should contain only one word"); with one, it "adds every non-comment line" (:148-160), dropping lines that start with the marker.
SoraniAnalyzer.java:65-68,LatvianAnalyzer.java:64-67andGalicianAnalyzer.java:63-66callWordlistLoader.getWordSet(IOUtils.requireResourceNonNull(getResourceAsStream("stopwords.txt"), ...)): no marker.BulgarianAnalyzer.java:71-75and 23 other analyzers make the same call with"#"as a second argument; SmartChinese passes"//". These three are the only analyzers that pass nothing.- The three files have
#lines: Sorani 69 (a 6-line header, then English glosses and category headings:# and,# which,# demonstratives, ...), Latvian 9 (a header with a bare#on line 4, and the headings# prepositions,# Conjunctions,# Particles,# modal verbs,# verbs), Galician 1 (# galican stopwords). - The loader trims each line and adds it, so every comment line becomes an entry. Sorani's 69 lines give 60 distinct entries because some glosses repeat.
- The stock chains tokenize with
StandardTokenizerbefore theStopFilter(SoraniAnalyzer.java:114-118,LatvianAnalyzer.java:112-114,GalicianAnalyzer.java:111-113). No token contains a space or is#, so no comment entry ever matches there.
| analyzer | getDefaultStopSet() entries | entries that start with # | the same file via StopFilterFactory |
|---|---|---|---|
SoraniAnalyzer | 122 | 60 | 62 |
LatvianAnalyzer | 170 | 9 (one is the bare #) | 161 |
GalicianAnalyzer | 161 | 1 | 160 |
BulgarianAnalyzer (control, passes "#") | 190 | 0 | 190 |
Nothing is only in the factory set: the default sets are the real words plus the comments.
Exposure and likelihood254 words
- Who sees it. Every caller of the public static
getDefaultStopSet()ofSoraniAnalyzer,LatvianAnalyzerorGalicianAnalyzer; no setting is needed. Code that lists, exports, counts, merges or displays default stop words gets the comments. The same entries come back fromgetStopwordSet()(StopwordAnalyzerBase.java:41-43) of an analyzer built with the default constructor, which copies the default set. - One file, two sets. Loading the analyzer's own
stopwords.txtthroughStopFilterFactory(for example in aCustomAnalyzer) gives 62, 161 and 160 entries;getDefaultStopSet()gives 122, 170 and 161. - Dropped tokens only on reuse. With a tokenizer that can emit
#, the Latvian set removes standalone#tokens:WhitespaceTokenizer+StopFilteronlucene # searchgives[lucene, search]. WithKeywordTokenizera whole field equal to a comment line is dropped:KeywordTokenizer+StopFilter(SoraniAnalyzer.getDefaultStopSet())on# andgives[]on main and[# and]with the fix (one executed probe, assertions on and off). - Not affected. The stock analyzers: with the default set and with the comment-free set they give the same tokens over 139 Sorani, 175 Latvian and 164 Galician inputs (every line of each file plus
#,# andandlucene # search); the stockLatvianAnalyzergives[lucen, search]forlucene # searcheither way. Analyzers built with your own stop set. The 24 sibling analyzers. - Scale. Low: public sets that contain comment lines, deterministic, in every release that has these analyzers. No report was found in the sources searched on 2026-10-27, 12 to 15 years after the analyzers were added.
The test shows that SoraniAnalyzer, LatvianAnalyzer and GalicianAnalyzer.getDefaultStopSet() contain the '#' comment lines of their bundled stopwords.txt as stop words.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.ckb;

import org.apache.lucene.analysis.CharArraySet;
import org.apache.lucene.analysis.gl.GalicianAnalyzer;
import org.apache.lucene.analysis.lv.LatvianAnalyzer;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestDefaultStopSetCommentLines extends LuceneTestCase {

  public void testNoCommentLinesInDefaultStopSets() {
    // expected: no entry starts with '#' (the '#' lines of the bundled stopwords.txt are comments)
    assertEquals(
        "Sorani 0, Latvian 0, Galician 0",
        "Sorani " + comments(SoraniAnalyzer.getDefaultStopSet())
            + ", Latvian " + comments(LatvianAnalyzer.getDefaultStopSet())
            + ", Galician " + comments(GalicianAnalyzer.getDefaultStopSet()));
  }

  private static int comments(CharArraySet set) {
    int n = 0;
    for (Object entry : set) {
      if (new String((char[]) entry).startsWith("#")) {
        n++;
      }
    }
    return n;
  }
}
# in a copy of this finding's repro folder (repro/LFV-703/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.ckb.TestDefaultStopSetCommentLines
- Expected vs actual
- Expected no entry starting with '#'; actual 60, 9 and 1 such entries (
expected:<Sorani [0, Latvian 0, Galician 0]> but was:<Sorani [60, Latvian 9, Galician 1]>), with-eaand-da.
More files, environment, full output42 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: expected:<Sorani [0, Latvian 0, Galician 0]> but was:<Sorani [60, Latvian 9, Galician 1]>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.analysis.ckb.TestDefaultStopSetCommentLines.testNoCommentLinesInDefaultStopSets(TestDefaultStopSetCommentLines.java:28)- The javadoc promises "the default stop words set" from a "File containing default ... stopwords"; the
#lines are headers and glosses. - 24 of the 28 analyzers that call
getWordSetpass"#";StopFilterFactoryreads these very files as 62, 161 and 160 words. - Upstream fixed the analogous inert entry, an empty string from blank lines, as a bug (#12291, #12299).
The full argument310 words
- The analyzers' contract.
SoraniAnalyzer.java:43,LatvianAnalyzer.java:42,GalicianAnalyzer.java:41:DEFAULT_STOPWORD_FILEis the "File containing default Kurdish/Latvian/Galician stopwords";:47,:46,:45:getDefaultStopSet()"Returns an unmodifiable instance of the default stop words set". - The loader's precondition. The overload they call requires "Every line of the Reader should contain only one word" (
WordlistLoader.java:80-82); the comment lines are prose. - The file format.
StopFilterFactory's default "wordset" format "allows whole line comments beginning with the \"#\" character" (StopFilterFactory.java:52-55);TestWordlistLoader.testComments(:39-45) asserts that the comment-aware overload drops#comment. - History. The comment-aware overload existed when each analyzer was added, and same-era siblings used it (in 3.1.0 Bulgarian, Armenian, Basque and Catalan passed
"#"). The same file was also read as commented on the factory path: the Sorani commit shipped a byte-identical copy as the Solr example'slang/stopwords_ckb.txt, loaded byStopFilterFactory, where the#lines are comments; byte-identical Galician and Latvian copies (stopwords_gl.txt,stopwords_lv.txt) came later from the same author in SOLR-3097/SOLR-3105 (2012, first released in 3.6.0), also loaded byStopFilterFactory. The adding issues (LUCENE-2842, LUCENE-3016, LUCENE-5379), CHANGES and MIGRATE say nothing about comment entries; later refactors of the calls were mechanical, and their commit messages do not mention comments. - No test asserts a
#entry.TestSoraniAnalyzer,TestLatvianAnalyzerandTestGalicianAnalyzercheck analysis output only, and agit grepover every test tree finds no test that asserts a#entry in a default set. - Precedent. In #12291 a committer wrote "I think the stoplist loader already ignores comment lines, but, does not ignore empty lines"; the fix PR #12299 is listed as
GITHUB#12291under Bug Fixes in 9.7.0 (lucene/CHANGES.txt:3553). It cuts both ways: that fix changedWordlistLoaderfor every caller, which a blank entry allows, while a#-leading line can be real data for the no-comment overload.
The devil's-advocate check193 words
The strongest case for "intended" (rated moderate by the independent reproducer and the cross-model reviews; the others gave no strength rating): the loader does exactly what its javadoc says; getDefaultStopSet() does not promise that every entry is a word; the calls are 12 to 15 years old and survived several refactors; the entries are inert in the stock chains; changing a public default set has a compatibility cost (the Thai stop-list change ran through a migration note, #16718/#16770).
Why it fails: the question is which overload the analyzers pick, not whether the loader works. Every sibling with the same file format picks the comment-aware one, which existed each time; the files are documented as stop-word files and Lucene's own factory path reads their # lines as comments; mechanical refactors are not acceptance; and "no effect on stock output" is a severity argument, not an intent argument, as #12299 shows. The rebuttal does not make the set's format an explicit contract, and changing a public set has a real compatibility cost. Verdict: not intended, low impact (the executed checks establish the behaviour, not the intent). A maintainer may still file the fix under Improvements.
Recommended A. Pass "#" in the three getWordSet calls
Pass the "#" comment marker in the three WordlistLoader.getWordSet calls, as the 24 sibling analyzers that pass "#" do (+6/-3). The sets become 62, 161 and 160 entries, equal to StopFilterFactory's. Validated: both repro classes pass, and the module's 1,909 tests and static checks pass; the stock analyzers' tokens do not change. It needs a CHANGES line.
             WordlistLoader.getWordSet(
                 IOUtils.requireResourceNonNull(
                     SoraniAnalyzer.class.getResourceAsStream(DEFAULT_STOPWORD_FILE),
-                    DEFAULT_STOPWORD_FILE));
+                    DEFAULT_STOPWORD_FILE),
+                "#");
All options and trade-offs4 options · 599 words
Option A was validated through gradle; B and C are alternatives a maintainer might raise, D is a complement.
The same three-line change in SoraniAnalyzer.java, LatvianAnalyzer.java and GalicianAnalyzer.java; the call then reads exactly like BulgarianAnalyzer.java:71-75. A regression test: the repro above, or the comment-entry check added to each analyzer's own test class.
             WordlistLoader.getWordSet(
                 IOUtils.requireResourceNonNull(
                     SoraniAnalyzer.class.getResourceAsStream(DEFAULT_STOPWORD_FILE),
-                    DEFAULT_STOPWORD_FILE));
+                    DEFAULT_STOPWORD_FILE),
+                "#");
Trade-offs
- Changes three public default sets: they lose 60, 9 and 1 entries and then equal what
StopFilterFactoryloads; no real word is lost. - The stock analyzers' tokens stay the same, so indexes built with them need no reindex (executed on 478 inputs; beyond them by reasoning: every comment entry contains a space or is a bare
#, whichStandardTokenizernever emits). - Custom chains that reuse a default set with a tokenizer that can emit
#(or, withKeywordTokenizer, a whole comment line such as# and) keep those tokens after the fix. The CHANGES line should say so; a maintainer may file it under Bug Fixes (as #12299) or Improvements.
What the checks validated
- Scratch worktree at
a9779ef3c193, gradle, JDK 25.0.3, seed DEADBEEF::lucene:analysis:common:testwith both repro classes added passes with assertions on: 341 classes, 1,924 tests, 0 failures, 18 skipped. That is the module's 1,909 upstream tests (among themTestSoraniAnalyzer7,TestLatvianAnalyzer4,TestGalicianAnalyzer4,TestBulgarianAnalyzer7) plus the 15 repro tests, which fail 10 of 15 on stock main. - The same with assertions off: 341 classes, 1,924 tests, 0 failures, 18 skipped.
- Static checks:
:lucene:analysis:common:check -x testwith the fix (repro classes removed) passes:checkGoogleJavaFormat,ecjLint,forbiddenApis,checkLicenses(error-prone is skipped in this build). - With the standalone runner (fix as shadow classes): the 4-test class 4 of 4 and the independent reproducer's 11 of 11 pass; the cross-model reviewers' own suites and the 15 upstream Sorani, Latvian and Galician tests pass.
Gives the same sets as A without touching code.
Trade-offs
- Loses the provenance: the Latvian source paper, the Sorani references and the English gloss above every Sorani word.
- Breaks the convention of every other bundled
#-commented file and leaves the overload trap for the next edit. - Not run.
Fixes all callers at once inside WordlistLoader.
Trade-offs
- Changes the documented "adds every line as an entry" behaviour for every caller, including
StopwordAnalyzerBase.loadStopwordSet(Path|Reader)(StopwordAnalyzerBase.java:70-89), which loads user stop files: a real entry that starts with#would vanish. - A maintainer may note that #12299 did change the loader for every caller; a blank entry has no plausible meaning, while a
#-leading entry can be real data for this overload. - Not run.
Assert for every analyzer with a bundled #-commented stopwords.txt that getDefaultStopSet() has no entry starting with #, or equals the StopFilterFactory load of the same file. No such Lucene unit test was written. The hunt ran related checks: its harness ran every entry of 47 analyzers' default sets (9,538 entries) through the analyzer's own chain and found comment survivors only in these three (8 for Latvian, whose bare # does not survive StandardTokenizer), and a loader and format audit found them to be the only #-commented files loaded without a marker.
Trade-offs
- Catches the next analyzer that picks the wrong overload; adds one test class.
- Not run as a Lucene test.
By code reading only, Elasticsearch exposes these three sets as the stop-word presets _sorani_, _latvian_ and _galician_, usable with any tokenizer, and the Lucene.NET port has the same three loader calls.
A bounded-exhaustive check ran every entry of every bundled default stop set (47 analyzers, 9,538 entries) through its own analyzer and sorted the entries that do not act as stop words by cause. All comment-text entries came from these three analyzers, the only #-commented files loaded without a comment marker.
The method in full144 words
Method: bounded-exhaustive check of bundled data (the study's "semi-formal" tier), hunt unit "bundled word lists", stock main a9779ef3c193, 2026-10-27.
- Every entry of every default stop set reachable through a public static accessor of 47 analyzers (9,538 entries) was analyzed alone through its own default analyzer, plus title- and upper-case variants (25,467 checks). Each entry that the analyzer did not remove was classified by cause.
- Class "comment": Sorani 60, Latvian 8, Galician 1 (Latvian's ninth comment entry, the bare
#, is removed byStandardTokenizerbefore the check). No other analyzer had any. - A loader and format audit in the same unit found the ckb, lv and gl files to be the only
#-commented bundled files loaded without a comment marker. - An AI finder then wrote the public-API test and traced the cause; independent AI tools reproduced and judged it (see the checks).
No prior report: 103 tool queries plus manual searches of GitHub, JIRA, the mailing lists and the web (2026-10-27). Related only: #12291/#12299 (blank lines loaded as an empty stop word, fixed as a bug in 9.7.0) and LUCENE-5211 (snowball | comments loaded through StopFilterFactory).
Searches5 searches
No issue, PR, list post, JIRA entry or downstream report describes these three analyzers loading # comment lines into getDefaultStopSet(), and no open PR touches the three calls or files.
| Where | When | How | Found |
|---|---|---|---|
| scripted prior-report search | 2026-10-27 | 103 queries: GitHub issues, PRs and commits, downstream repositories, the dev, java-user, issues and commits lists, the JIRA archive, 6 web queries | 800 distinct hits, 0 high; none reports this bug |
| GitHub (manual) | 2026-10-27 | 18 searches over apache/lucene, Elasticsearch, OpenSearch, Lucene.NET and Solr; the file lists of all 409 open apache/lucene PRs | no report; no open PR touches the three calls or files |
| JIRA archive and mailing lists | 2026-10-27 | LUCENE, SOLR and LUCENENET; LUCENE-2842, LUCENE-3016, LUCENE-5379 and SOLR-1860 read; every java-user mail of May 2023 | no report |
| Related items (read) | 2026-10-27 | #12291/#12299, LUCENE-5211/#6275, #6291, #11866 | blank lines as an empty stop word (fixed as a bug, the precedent); snowball comments through the factory (fixed by docs); open: unify formats; open: modifiable default sets |
| Web | 2026-10-27 | web search and another contributor's public review of these language analyzers, searched in full | no mention |
In each analyzer since it was added: Galician 3.1.0 (LUCENE-2842, 2011), Latvian 3.2.0 (LUCENE-3016, 2011), Sorani 4.7.0 (LUCENE-5379, 2014). No later change passed "#". Affected on all 17 releases run, 3.1.0 to 10.5.2, and on main.
Versions tested7 rows
Introduced by the commits that added each analyzer, all by the same author: Galician c7cfe0b8cc5 (branch_3x; trunk 61872be09df), 2011-01-06; Latvian df3e3d73511 (trunk c3f63316390), 2011-04-14; Sorani a670b8d5b22 (branch_4x; trunk 2140f4368ad), 2014-01-04. Each loaded its #-commented file with a no-comment overload although the comment-aware one existed in the same tree.
Later refactors (LUCENE-2564, LUCENE-5560, LUCENE-5859, LUCENE-9570, and LUCENE-10335 cc342ea7407, which gave the call today's form) kept the overload; "#" occurs 0 times in any version of the three hunks. The only change in the sets' contents: in 9.7.0 #12299 stopped loading the empty string from blank lines, so Sorani went from 123 to 122 entries; the comments stayed. Upstream main a95c754ee003 (2026-10-26) still has the three calls, and the as-fetched origin/branch_10x (1309534296e, 2026-10-24) has the same three analyzer files (read, not run). 8.8.2 to 8.11.3 are not tagged in the history clone (inferred from 8.8.1 and 8.11.4); the probes on 3.0.3 to 4.7.0 ran on the published release jars.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the 4-test class 3 of 4 and the 11-test class 7 of 11 fail (gradle and runner, assertions on and off) |
| 9.7.0, 9.12.3, 10.0.0, 10.5.2 | affected | Galician 1 of 161, Latvian 9 of 170, Sorani 60 of 122 (probe); the 4-test class fails on 9.12.3, 10.0.0 and 10.5.2 |
| 4.7.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.6.0 | affected | Galician 1, Latvian 9, Sorani 60 of 123 (probe); 9.1.0 also fails the 4-test class |
| 3.2.0, 3.6.2, 4.0.0, 4.6.1 | Galician, Latvian | Galician 1 of 161, Latvian 9 of 170; no Sorani analyzer yet |
| 3.1.0 | Galician | Galician 1 of 161; no Latvian or Sorani analyzer yet |
| 3.0.3 | no API | none of the three analyzers exists |
| main with fix A | fixed | both repro classes pass; the module's 1,909 tests pass with assertions on and off |
An independent reproducer, a devil's advocate and an adjudication found it real; two executed reviews by another model family (OpenAI GPT-5.6) agreed. A credibility audit kept it. This doc re-ran both repro classes through gradle on main and validated the fix with the module's full test suite.
Checks and verdicts342 words
Each check wrote or ran its own tests against stock jars. The cross-model reviews ran on main ea57360912ed, whose analysis sources and WordlistLoader.java equal a9779ef3c193; the intended reviewer's tests were re-run on a9779ef3c193 (with a factory-path test and the finder's test); the refute reviewer's tests ran on ea57360912ed, 10.5.2 and 9.12.3.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Exhaustive check over 47 analyzers; the 4-test JUnit fails 3 of 4 on main (on and off), 10.5.2 and 9.12.3; passes with the fix; the 15 upstream Sorani, Latvian and Galician tests pass with it. |
| refute review (OpenAI GPT-5.6) | real, high | Own membership and reuse tests fail on main (on and off), 10.5.2 and 9.12.3; the Latvian set with WhitespaceTokenizer drops #; with the fix both suites and 15 upstream tests pass. Intended argument moderate. |
| Independent reproducer | real | Own 11-test class from the claim only: 7 of 11 fail on main (on and off), 10.5.2 and 9.12.3; 4 controls pass, including unchanged stock-analyzer tokens; 11 of 11 with its own fix. |
| Intended review (OpenAI GPT-5.6) | real, high | Built the works-as-designed case and rated it moderate; its contract test fails 1 of 2 on a9779ef3c193 (the Bulgarian control passes) and passes with the fix. |
| Devil's advocate | real | High confidence that loading the comment lines is not intended, impact low; CustomAnalyzer + StopFilterFactory on the same files gives 62, 161 and 160 entries on main and 10.5.2. |
| adjudication | confirmed, high | Re-ran with new seeds: the 11-test class 7 of 11 fail (assertions on), the 4-test class 3 of 4 (off). |
| credibility audit | keep | Own probe on main (assertions off): the same counts; the stock LatvianAnalyzer gives [lucen, search], the reused set [lucene, search]. Expects a maintainer might file the fix as an improvement. |
| this doc (gradle) | reproduced; fix validated | Stock main: 15 repro tests, 10 fail, assertions on and off. With fix A: 1,924 module tests, 0 failures, assertions on and off; the static checks pass. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 450 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,353 words
- Registry title
- SoraniAnalyzer, LatvianAnalyzer and GalicianAnalyzer load the '#' comment lines of their bundled stopwords.txt as stop words: 60 of the 122 entries of SoraniAnalyzer.getDefaultStopSet(), 9 of 170 for Latvian (including a bare '#') and 1 of 161 for Galician are comment text
- Area
- analysis-common / language analyzers (default stop sets of SoraniAnalyzer, LatvianAnalyzer and GalicianAnalyzer; choice of WordlistLoader overload)
- Priority
- Low, rank 429: The Sorani, Latvian and Galician default stop sets contain '#' comment lines but the stock analyzers' tokens do not change, so it is a minor defect placed after the output-changing stop-list rows LFV-677 and LFV-672.
- Impact class
- minor
- Impact note
- Every caller of the public static getDefaultStopSet() of SoraniAnalyzer, LatvianAnalyzer or GalicianAnalyzer gets the comment entries (stock call, no setting, no scale), but the stock analyzers' token output does not change, because every comment entry except Latvian's bare '#' contains a space and StandardTokenizer never emits '#'; the visible effects are wrong size(), iteration and contains() results of those three public sets, and dropped tokens only when an application reuses a set with another tokenizer (with WhitespaceTokenizer the Latvian set removes a standalone '#' token).
- Summary
- You call SoraniAnalyzer.getDefaultStopSet(), LatvianAnalyzer.getDefaultStopSet() or GalicianAnalyzer.getDefaultStopSet(), documented as 'the default stop words set' built from the analyzer's bundled 'File containing default Kurdish/Latvian/Galician stopwords', and expect the stop words of that file; its '#' lines are comments, the format that about two dozen sibling analyzers load with the '#' comment marker and that StopFilterFactory's default 'wordset' format skips. Instead the three analyzers load the file with WordlistLoader.getWordSet(InputStream), which 'adds every line as an entry', so 60 of Sorani's 122 entries, 9 of Latvian's 170 (including a bare '#') and 1 of Galician's 161 are comment text such as '# set of kurdish stopwords', '# and' or '# galican stopwords'. The stock analyzers' tokens do not change, but code that lists, counts or reuses these sets sees the comments, and with a WhitespaceTokenizer the Latvian set removes a standalone '#' token ('lucene # search' gives [lucene, search]).
- Introduced
- One introducing commit per analyzer, each the commit that added the analyzer, all three by rmuir [read: git log -L over each loader hunk and git show in the full-history clone; the string "#" occurs 0 times in any version of the three hunks]: GalicianAnalyzer c7cfe0b8cc5525acb0ef5f515dc6b09d3412cb94 (branch_3x; trunk 61872be09dfd), LUCENE-2842 'add Galician analyzer' (migrated as apache/lucene#3916), first release 3.1.0; LatvianAnalyzer df3e3d735118 (branch_3x; trunk c3f63316390d), LUCENE-3016 (#4090), first release 3.2.0; SoraniAnalyzer a670b8d5b229 (branch_4x; trunk 2140f4368ade), LUCENE-5379 (#6442), first release 4.7.0. Each loaded its '#'-commented file with a no-comment WordlistLoader overload although the comment-aware overload existed in the same tree; later refactors (LUCENE-2564, LUCENE-5560, LUCENE-5859, LUCENE-9570, LUCENE-10335 cc342ea7407c, which gave today's getWordSet(IOUtils.requireResourceNonNull(getResourceAsStream(...))) form) kept the no-comment overload (2011-01-06 (Galician); 2011-04-14 (Latvian); 2014-01-04 (Sorani))
- First affected version
- 3.1.0 [exec] (GalicianAnalyzer; LatvianAnalyzer from 3.2.0 [exec], SoraniAnalyzer from 4.7.0 [exec]; 3.0.3 has none of the three analyzers [exec])
- Affected versions
- Every release that contains one of the three analyzers, 3.1.0 to 10.5.2, and main a9779ef3c193, with -ea and -da [exec: version-independent reflection probe on 3.1.0, 3.2.0, 3.6.2, 4.0.0, 4.6.1, 4.7.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.6.0, 9.7.0, 9.12.3, 10.0.0, 10.5.2 and main (-ea and -da): Galician 1 of 161, Latvian 9 of 170 including a bare '#', Sorani 60 of 123 before 9.7.0 and 60 of 122 from 9.7.0 on (the extra entry was the empty string from blank lines, removed by GITHUB#12291/#12299); the Bulgarian control has 0 comment entries everywhere; the finder's JUnit fails 3 of 4 on 9.1.0, 9.12.3, 10.0.0, 10.5.2 and main; the independent reproduction's test fails 7 of 11 on 10.5.2, 9.12.3 and main]. All 131 release tags from 3.1 to 10.5.2 in the history clone read the same way [read]; 8.8.2-8.11.3 are not tagged there (inferred from 8.8.1 [read] and 8.11.4 [exec]); 4.0.0-alpha/-beta by tag containment only. Not fixed: upstream main a95c754ee003 (2026-10-26) still has the three no-comment calls [read through the GitHub contents API, 2026-10-27]; branch_10x was not checked.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (searched 2026-10-27, read-only; the prior-report record, verdict new): a scripted prior-report search with 103 queries over GitHub issues, PRs and commits, downstream repositories, the Lucene lists and the JIRA archive (800 distinct hits, 0 high); 18 own GitHub searches on apache/lucene, Elasticsearch, OpenSearch, Lucene.NET and Solr; the file lists of all 409 open apache/lucene PRs; JIRA archive queries on LUCENENET, SOLR and LUCENE with LUCENE-2842, LUCENE-3016, LUCENE-5379 and SOLR-1860 read; the java-user thread behind #12291; web searches and a full keyword search of another contributor's public review of these language analyzers (mediawiki.org, Galician, Latvian and Sorani sections). No issue, PR, list post, JIRA entry or downstream report describes these three analyzers loading '#' comment lines into getDefaultStopSet(), and no open PR touches the three loader calls or files. Related only: #12291/#12299 (blank lines of SmartChineseAnalyzer's file loaded as an empty stop word; fixed in WordlistLoader in 9.7.0 under Bug Fixes; a committer there wrote 'I think the stoplist loader already ignores comment lines'), LUCENE-5211/#6275 ('|' comments of snowball-format files loaded as words through StopFilterFactory without format=snowball; resolved by documentation), #6291 (open: unifying stopword formats) and #11866 (open: modifiable default sets; uses SoraniAnalyzer only as an example). The Lucene.NET port has the same no-comment calls, unreported. Not fixed: upstream main a95c754ee003 (2026-10-26). Gaps: GitHub search pages are capped at 50 hits (one broad query was truncated from 91 to 50); private reports are not searchable.
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26) through gradle in a scratch worktree (2026-10-28) and through the standalone JUnit runner (2026-10-27), with assertions on and off; the release jars 10.5.2, 10.0.0, 9.12.3 and 9.1.0 with the finder's test (10.5.2 and 9.12.3 also with the independent reproducer's test); a reflection probe on 3.0.3 to 10.5.2 (18 releases). The fix was validated in the scratch worktree with the module's whole test suite (1,924 tests) and its static checks.
- Finding record
a Lucene main checkout lucene/analysis/common/src/java/org/apache/lucene/analysis/ckb/SoraniAnalyzer.java:38 (@since 4.10.0; CHANGES.txt lists LUCENE-5379 under 4.7.0), :43-53 (DEFAULT_STOPWORD_FILE 'File containing default Kurdish stopwords', getDefaultStopSet javadoc 'Returns an unmodifiable instance of the default stop words set'), :65-68 (getWordSet(InputStream), no comment marker); lv/LatvianAnalyzer.java:64-67 and gl/GalicianAnalyzer.java:63-66 (same call); bg/BulgarianAnalyzer.java:71-75 (sibling passing "#"); lucene/core/src/java/org/apache/lucene/analysis/WordlistLoader.java:33 (@lucene.internal), :80-90 (getWordSet(InputStream): 'adds every line as an entry', 'Every line of the Reader should contain only one word'), :149-160 (getWordSet(InputStream, String comment): 'adds every non-comment line'); lucene/analysis/common/src/java/org/apache/lucene/analysis/core/StopFilterFactory.java:53 (wordset format 'allows whole line comments beginning with the "#" character'); resources ckb/stopwords.txt (69 '#' lines), lv/stopwords.txt (9 '#' lines, line 4 a bare '#'), gl/stopwords.txt (line 1 '# galican stopwords'); identical in Lucene main ea57360912edupstream main a95c754ee003 (2026-10-26), read-only GitHub contents API on 2026-10-27: SoraniAnalyzer.java:65-68, LatvianAnalyzer.java:64-67, GalicianAnalyzer.java:63-66 unchanged
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/ckb/SoraniAnalyzer.java:43-53, 63-74, 114-118; lv/LatvianAnalyzer.java:42-52, 62-73, 112-114; gl/GalicianAnalyzer.java:41-51, 61-72, 111-113 (read at a9779ef3c193)lucene/core/src/java/org/apache/lucene/analysis/WordlistLoader.java:33 (@lucene.internal), :52-63, :80-90, :117-131, :148-160lucene/analysis/common/src/java/org/apache/lucene/analysis/bg/BulgarianAnalyzer.java:70-75; core/StopFilterFactory.java:52-55lucene/analysis/common/src/resources/org/apache/lucene/analysis/ckb/stopwords.txt (69 '#' lines), lv/stopwords.txt:1-5, 40, 63, 103, 159, gl/stopwords.txt:1
- Who is affected
lucene/core/src/java/org/apache/lucene/analysis/StopwordAnalyzerBase.java:41-43, 50-55; ckb/SoraniAnalyzer.java:79, lv/LatvianAnalyzer.java:78, gl/GalicianAnalyzer.java:77 (default constructor passes the default set)
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/ckb/SoraniAnalyzer.java:43-51; lv/LatvianAnalyzer.java:42-50; gl/GalicianAnalyzer.java:41-49lucene/core/src/java/org/apache/lucene/analysis/WordlistLoader.java:80-90; lucene/core/src/test/org/apache/lucene/analysis/TestWordlistLoader.java:39-45; lucene/analysis/common/src/java/org/apache/lucene/analysis/core/StopFilterFactory.java:52-55lucene/CHANGES.txt:3550-3553 (9.7.0 Bug Fixes: GITHUB#12291)
- Suggested fix
lucene/core/src/java/org/apache/lucene/analysis/StopwordAnalyzerBase.java:63-89 (option C)
- History
a Lucene clone: git rev-parse origin/branch_10x:<the three analyzer files> equals main a9779ef3c193 (read 2026-10-28); lv/stopwords.txt and WordlistLoader.java differ only in trailing whitespace and a pattern-matching cast
- TestDefaultStopSetCommentLines.java (JUnit test):
repro/LFV-703/src/org/apache/lucene/analysis/ckb/TestDefaultStopSetCommentLines.java(44 lines)
A light, step-by-step picture of the Sorani example and a summary card, made in parallel with this doc. Its numbers come from an executed probe on main a9779ef3c193, stock and with the fix; the PNG is the summary card.
assets/LFV-703/bug.png(450 KB)