Inside wiki markup, WikipediaTokenizer makes word tokens only of letters, digits and Hangul. The Chinese and Japanese characters there (its CJ class) are skipped, although the same text outside markup becomes one token per character.
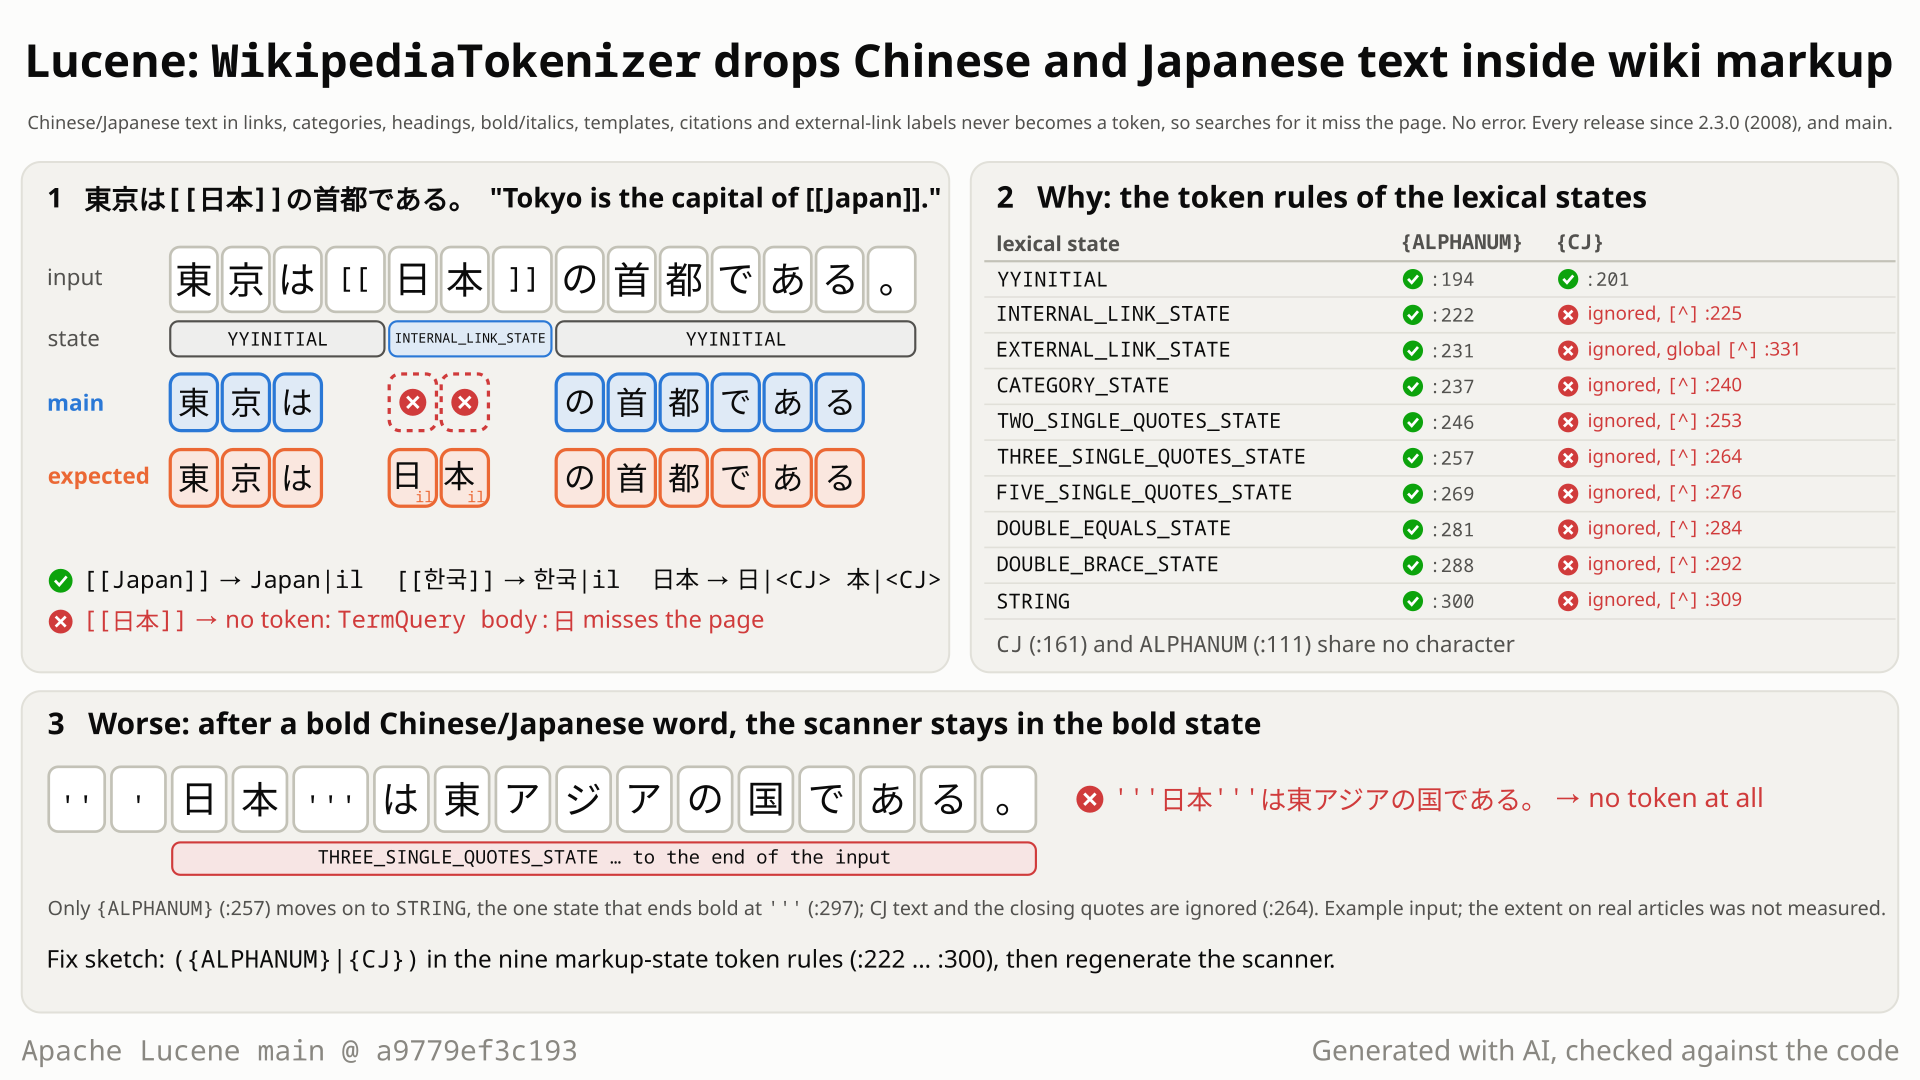
東京は[[日本]]の首都である。 is scanned: the link text falls into a markup state with no rule for Chinese or Japanese characters, so 日本 is skipped; and how a bold title keeps the scanner in the bold state. Select the still to open it at full size. Generated with AI, checked against the code.- Index the Japanese sentence
東京は[[日本]]の首都である。("Tokyo is the capital of [[Japan]].") withnew WikipediaTokenizer(). In English the same sentence gives 6 tokens, the link word typedil:Japan|il. - You expect 11 tokens, one per Han or kana character, as the sentence without the link brackets gives (
<CJ>tokens), with 日 and 本 typedil. - You get 9: 東 京 は の 首 都 で あ る. The link text 日本 is gone, so
TermQuery(body:日)finds 1 of 3 test documents, only the one without markup. Categories, headings, bold, italics, templates,<ref>citations and external-link labels lose their Chinese and Japanese text the same way; Latin and Korean text in them is kept. - Why: the grammar emits Chinese/Japanese characters (class
CJ) only in plain text. Each of the nine markup states has one word-token rule, for letters, digits and Hangul (ALPHANUM), none forCJ, and skips what no rule matches; the two classes share no character. With a bold title,'''東京'''は[[日本]]の首都である。, the scanner also misses the closing''': only 6 of 11 Han and kana characters survive. - No error, in all three output modes. Adding
{CJ}to the nine markup-state token rules and regenerating the scanner keeps all 11 characters, typedilandbwhere they sit in markup; the module's 1,923 tests pass.
Applications that index Chinese or Japanese wiki text with WikipediaTokenizer (opt-in, @lucene.experimental, in analysis-common): the default constructor, the wikipedia factory with default settings, or any output mode. Ordinary markup triggers it: links, categories, headings, bold, italics, templates, citations. Searches for that text miss the page; existing indexes need a reindex after a fix.
Mechanism, terms and numbers901 words
WikipediaTokenizer tokenizes plain Chinese and Japanese text (one <CJ> token per character of its CJ class), and it tokenizes Latin and Korean text inside wiki markup with the markup's type ([[Japan]] gives Japan|il, [[한국]] gives 한국|il). But the Chinese and Japanese characters inside markup (the grammar's CJ class: Han, Hiragana, Katakana and a few other ranges) are skipped without an error: [[日本]], [[Category:日本]], == 歴史 ==, {{日本}} and <ref>日本</ref> give no token, [http://example.org 日本] gives only the URL, and x ''日本'' y gives x and y, with y typed bold. In 東京は[[日本]]の首都である。 9 of its 11 Han and kana characters become tokens; with the title in bold, a common pattern in MediaWiki lead sentences, only 6 of 11, and a search for 東京 or 日本 misses the page. The grammar's only rule that emits these characters ({CJ}) is for plain text, while each of the nine markup lexical states has one word-token rule, for {ALPHANUM}, and skips what no rule matches, and CJ shares no character with ALPHANUM. All three output modes are affected. It dates from the tokenizer's first commit (LUCENE-1103, 2008; first release 2.3.0) and is in every release up to 10.5.2 and on main. Adding {CJ} to the nine per-state token rules and regenerating the scanner with the build's own task fixes it: the repro, an exact-token test and the whole analysis-common test suite pass, with and without assertions.
- Lexical state: the tokenizer's scanner is generated from a JFlex grammar,
WikipediaTokenizerImpl.jflex, and reads in one mode at a time. Plain text isYYINITIAL;[[,[[Category:,[,'',==,{{and<ref>switch to a markup state (:208-214), and each state has its own token rules. A character that matches no token rule of the current state is skipped. ALPHANUMandCJ: the grammar's word classes.ALPHANUMis letters (a hard-coded list that ends at U+1FFF, plus U+FFA0-FFDC), digits, and Hangul syllables and jamo (:111,:154-158).CJis Hiragana, Katakana, Bopomofo, Hangul compatibility jamo, CJK ideographs, part of the CJK Compatibility block (U+3300-337F) and halfwidth Katakana (:161). They share no character.- Markup types: text inside markup is typed with the markup:
il(internal link),c(category),handsh(headings),i,b,bi(italics, bold, both),ci(template, citation),eluandel(external-link URL and label). Plain CJ text is typed<CJ>, one character per token.
- The only
CJtoken rule is<YYINITIAL>{CJ}(WikipediaTokenizerImpl.jflex:201). - Each of the nine markup states has one word-token rule, for
{ALPHANUM}(:222,:231,:237,:246,:257,:269,:281,:288,:300), and an ignore rule for what no rule matches ([^], or for external links the global ignore rule at:331). The only other rules there that return a token, the external-link URL (:230) andSTRING's|(:307), cannot match a CJ character. So every CJ character inside markup is skipped. - The
{ALPHANUM}rule also moves the scanner on. In bold, only a word movesTHREE_SINGLE_QUOTES_STATEtoSTRING(:257), the one state that recognises the closing'''(:297). After a bold CJ title the scanner stays in the bold state, which it leaves only on a Latin word or a link opener (:259-261), and keeps skipping the plain text after it:'''日本'''は東アジアの国である。gives no token at all. Inx ''日本'' ythe closing''is read as a bold opener, soyis typedb. - The loss happens in the scanner, so the
UNTOKENIZED_ONLYandBOTHmodes have nothing to collapse.reset()returns the scanner toYYINITIAL(WikipediaTokenizer.java:318-324), so the next value starts clean.
Scope. "Chinese and Japanese" here means the CJ class. Some Han characters are outside it: 々 (U+3005), 〇 (U+3007) and supplementary-plane Han are lost in plain text too (時々 gives only 時), which is a separate limit of the hard-coded classes, not this bug; fix A does not change it.
| input | WikipediaTokenizer on main | with the fix |
|---|---|---|
東京は日本の首都である。 (plain text) | 11 <CJ> tokens | unchanged |
東京は[[日本]]の首都である。 | 9 tokens, 日本 lost | 11 tokens, 日 and 本 typed il |
'''東京'''は[[日本]]の首都である。 | 6 tokens: の 首 都 で あ る | 11 tokens: 東 京 typed b, は, 日 本 typed il, ... |
Tokyo is the capital of [[Japan]]. | 6 tokens, Japan typed il | unchanged |
[[日本]], [[Category:日本]], == 歴史 ==, === 歴史 ===, {{日本}}, <ref>日本</ref> | no token | 2 tokens each: il, c, h, sh, ci, ci |
x ''日本'' y, x '''東京''' y | x, y typed b | x, 2 tokens typed i or b, y |
[http://example.org 日本] | the URL only | the URL, then 日 and 本 typed el |
[[한국]] == 한국 == x '''한국''' y | all kept | unchanged |
Search over three documents, the plain sentence, the one with the link and the one with the bold title: TermQuery(body:日) and PhraseQuery(body:"日 本") find 1 of 3 on main (3 of 3 with the fix), and PhraseQuery(body:"東 京") 2 of 3. With UNTOKENIZED_ONLY or BOTH and every markup type untokenized, [[日本]] and == 歴史 == still give no token.
Exposure and likelihood293 words
- Who is hit. Users of
WikipediaTokenizerfromanalysis-common: its public constructors, or the SPI namewikipedia(WikipediaTokenizerFactory.java:41), whose javadoc shows a Solr schema example (:28-33). No Lucene analyzer uses it, and it is@lucene.experimental(WikipediaTokenizer.java:40). Within that use no special setting is needed: the default constructor and the factory default (TOKENS_ONLY,WikipediaTokenizerFactory.java:52) are affected, and so areUNTOKENIZED_ONLYandBOTH. - What triggers it. Chinese or Japanese text in links, categories, headings, bold, italics, templates,
<ref>citations or external-link labels. A bold title in the first sentence, a common MediaWiki pattern, also loses the plain text after it up to the next link or Latin word. No large input or unusual character is needed. Korean (Hangul syllables) is kept; Hangul compatibility jamo, which the grammar puts inCJ, are lost. - What goes wrong. The lost words are not in the field's terms, so term and phrase queries on them miss the page (only positive queries were run). Silent and deterministic: no exception, the stored value keeps the text, the same with
-eaand-da. - How much. In the example sentence 2 of 11 Han and kana characters, with a bold title 5 of 11. On a synthetic three-paragraph article with a bold title, 51 of 51 Chinese/Japanese characters were lost. Real articles were not measured.
- Not more than that. A 1,350,000-character input with 400,000 CJ characters inside markup tokenized in 68-113 ms with no exception (no benchmark or memory study); other fields and documents are not affected, because
reset()returns the scanner to its initial state. - Long-lived. Every release since 2.3.0 (2008). A fix changes the tokens of values with CJ text inside markup only, so existing indexes need a reindex.
The test shows that WikipediaTokenizer drops Chinese/Japanese text inside wiki markup: the internal link [[日本]] gives no token, while [[Japan]] gives Japan.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.wikipedia;

import java.io.StringReader;
import org.apache.lucene.analysis.tokenattributes.CharTermAttribute;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestWikipediaTokenizerLinkCjk extends LuceneTestCase {

  public void testCjkInsideInternalLink() throws Exception {
    StringBuilder terms = new StringBuilder();
    try (WikipediaTokenizer tokenizer = new WikipediaTokenizer()) {
      tokenizer.setReader(new StringReader("[[日本]]"));
      CharTermAttribute term = tokenizer.addAttribute(CharTermAttribute.class);
      tokenizer.reset();
      while (tokenizer.incrementToken()) {
        terms.append(term);
      }
      tokenizer.end();
    }
    // expected: the link text 日本 is tokenized, as [[Japan]] gives Japan; actual: no token at all
    assertEquals("日本", terms.toString());
  }
}
# in a copy of this finding's repro folder (repro/LFV-708/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.wikipedia.TestWikipediaTokenizerLinkCjk
- Expected vs actual
- Expected the terms to spell
日本; actual no token at all (expected:<[日本]> but was:<[]>), with-eaand-da.
More files, environment, full output32 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: expected:<[日本]> but was:<[]>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.analysis.wikipedia.TestWikipediaTokenizerLinkCjk.testCjkInsideInternalLink(TestWikipediaTokenizerLinkCjk.java:37)- The class is "aware of Wikipedia syntax" and tokenizes plain Chinese/Japanese as
<CJ>; its tests expect markup text as typed tokens. - Latin, Korean and the other token classes keep their text inside the same markup; only
CJis skipped. - Nothing records the loss as a decision, and no commit since 2008 has added a
{CJ}rule to a markup state.
The full argument301 words
- The class's purpose. "Extension of StandardTokenizer that is aware of Wikipedia syntax" (
WikipediaTokenizer.java:35-38). The grammar treats Chinese/Japanese as a token type in plain text (WikipediaTokenizerImpl.jflex:201, type<CJ>atWikipediaTokenizer.java:85); theCJandKOREANmacros and the{CJ}rule were copied from StandardTokenizer's grammar of the time. - Markup content is meant to become typed tokens. Upstream
testHandwritten(TestWikipediaTokenizer.java:66-285) andtestLinks(:315-340) assert that link, category, italics, bold, heading, citation and external-link text comes out typedil,c,i,b,h,ci,el. Those tests are ASCII-only; neither upstream test file contains a CJK character. - Only CJ disappears. Latin and Korean inside all ten markup constructs are kept (the tested forms), and so are the letters and digits of the
APOSTROPHE,ACRONYM,COMPANY,EMAIL,HOSTandNUMtoken classes (split intoALPHANUMpieces). - No sign it was decided. The nine states got their
{ALPHANUM}rules in the tokenizer's first commit (f715fc60317, LUCENE-1103);git log -S'{CJ}'on the grammar finds only that commit, and later edits of these lines (position increments, LUCENE-1133's counters, explicitbreak;, LUCENE-5357's[^]) never touched CJ. LUCENE-1103's description and comments never mention CJK, Chinese, Japanese or scripts. - Keep the claim precise. The contract is implied (purpose, upstream tests, consistency with Latin, Korean and plain-text CJ), not quoted. The mistyping of following words is not CJ-specific:
x '''!!!''' y zalready givesy|b z|b, with or without the fix; only the loss of text is. - Maintainers may prefer a bigger change. In LUCENE-6993 (#8050), sarowe wrote that "Performing an effective upgrade would probably mean cloning the current StandardTokenizer and then re-layering the wiki syntax". Maintainers may prefer such a rewrite, or deprecation, to a local fix.
The devil's-advocate check216 words
Strongest case for "intended" (the independent reproduction: moderate-to-weak; the cross-model reviews: moderate): the javadoc says the tokenizer "is based off of the Wikipedia tutorial ... but it may not be complete" and marks it @lucene.experimental (WikipediaTokenizer.java:36-40); its author tested it only on the English Wikipedia dump ("I have only tested it with the benchmarking EnwikiDocMaker wikipedia stuff", LUCENE-1103); the grammar's own design sketch defines every markup body as ALPHANUM runs (//INTERNAL_LINK = "["{2}({ALPHANUM}+{WHITESPACE}*)+"]"{2}, WikipediaTokenizerImpl.jflex:334-343) with an ignore catch-all in every state; and the tokenizer is little maintained (LUCENE-6993 kept it on Unicode 3.0; it carries @IgnoreRandomChains(reason = "TODO: it seems to mess up offsets!?"), WikipediaTokenizer.java:42).
Why it fails: "may not be complete" is about which Wikipedia syntax is recognised, and here the syntax is recognised and the text inside it thrown away; @lucene.experimental warns that the API or grammar may change (LUCENE-1135); the sketch's ALPHANUM includes KOREAN, so the design keeps non-Latin text inside markup, and nothing explains dropping only Chinese and Japanese; LUCENE-6993 is about the Unicode version of the character data, not about which rules each state has. Verdict: not intended, a defect (the intended-behaviour check, the adjudication and the audit). Expect maintainers may still file the change as an improvement to an experimental, English-tested tokenizer.
Recommended A: give the nine markup states a CJ token rule
In the nine markup-state token rules, match ({ALPHANUM}|{CJ}) instead of {ALPHANUM} (9 grammar lines), then regenerate the scanner with the build's task. CJ inside markup becomes one token per character with the markup's type ([[日本]] gives 日|il 本|il). The repro, an exact-token test and the module's 1,923 tests pass.
 <INTERNAL_LINK_STATE>{
-  {ALPHANUM} {yybegin(INTERNAL_LINK_STATE); numWikiTokensSeen++; return currentTokType;}
+  ({ALPHANUM}|{CJ}) {yybegin(INTERNAL_LINK_STATE); numWikiTokensSeen++; return currentTokType;}
 ...
 <THREE_SINGLE_QUOTES_STATE>{
-  {ALPHANUM} {yybegin(STRING); numWikiTokensSeen++; return currentTokType;}
+  ({ALPHANUM}|{CJ}) {yybegin(STRING); numWikiTokensSeen++; return currentTokType;}
 ...
 // the same change in the other seven states (9 rules in all), then:
 ./gradlew :lucene:analysis:common:regenerateWikipediaTokenizer
All options and trade-offs3 options · 949 words
Option A was validated in a scratch worktree at a9779ef3c193 (OpenJDK 25.0.3): grammar edit, ./gradlew :lucene:analysis:common:regenerateWikipediaTokenizer, then the repro, an exact-token test, the whole analysis-common test suite and its static checks, with and without assertions. Options B and C were not run. The fix was not benchmarked. Until a fix ships there is no workaround within WikipediaTokenizer's options: StandardTokenizer keeps all the text (<IDEOGRAPHIC>, <HIRAGANA> tokens) but loses the markup types and also indexes markup keywords such as Category. The sibling defect in the same grammar (the hard-coded LETTER/DIGIT ranges, which lose letters such as µ, ª, º and fullwidth digits in plain text) is separate: neither fix fixes the other.
In each of the nine per-state token rules (WikipediaTokenizerImpl.jflex:222, :231, :237, :246, :257, :269, :281, :288, :300), match ({ALPHANUM}|{CJ}) instead of {ALPHANUM}, with the same action, and regenerate the scanner with ./gradlew :lucene:analysis:common:regenerateWikipediaTokenizer, which also rewrites the checksum file src/generated/checksums/regenerateWikipediaTokenizer.json. 9 grammar lines; the generated WikipediaTokenizerImpl.java changes in about 380 lines of tables.
The result: Chinese/Japanese inside markup becomes one token per character typed with the markup's type, as plain CJ text is one <CJ> token per character (== 歴史 == gives 歴|h 史|h, [[Category:日本]] 日|c 本|c). Because CJ now fires the same action as ALPHANUM, the state transitions happen too: '''東京'''は[[日本]]の首都である。 keeps all 11 Han and kana characters (東|b 京|b, は as <CJ>, 日|il 本|il, then の首都である), and in x ''日本'' y the y is <ALPHANUM> again. Offsets are per character with position increment 1; the first external-link label token shares the URL's position, as Japan does in [http://example.org Japan]. The untokenized modes work: UNTOKENIZED_ONLY with il gives 日本|il [2,4) for [[日本]] and 東京 Tokyo|il [2,10) for [[東京 Tokyo]]; BOTH gives the collapsed token, then 日 (increment 0) and 本. Plain text and Latin and Korean inside markup are unchanged.
 <INTERNAL_LINK_STATE>{
-  {ALPHANUM} {yybegin(INTERNAL_LINK_STATE); numWikiTokensSeen++; return currentTokType;}
+  ({ALPHANUM}|{CJ}) {yybegin(INTERNAL_LINK_STATE); numWikiTokensSeen++; return currentTokType;}
 ...
 <THREE_SINGLE_QUOTES_STATE>{
-  {ALPHANUM} {yybegin(STRING); numWikiTokensSeen++; return currentTokType;}
+  ({ALPHANUM}|{CJ}) {yybegin(STRING); numWikiTokensSeen++; return currentTokType;}
 ...
 // the same change in the other seven states (9 rules in all), then:
 ./gradlew :lucene:analysis:common:regenerateWikipediaTokenizer
Trade-offs
- Token changes beyond the lost text.
CJshares no character with any macro the nine states use (ALPHANUM,HOST,P, the markup delimiters), so the new alternative matches only characters that today fall to an ignore rule. But the state changes and counters it now triggers also change tokens main already emits in the same value:x ''日本'' ygivesy|<ALPHANUM>instead ofy|b; in[http://example.org 日本 Japan]the label tokenJapangets position increment 1 instead of 0; andUNTOKENIZED_ONLYturns[[東京 Tokyo]]fromTokyo|il [5,10)into東京 Tokyo|il [2,10). Inputs without CJ characters inside markup are unchanged; the module's tests agree. Existing indexes need a reindex. - CJ inside markup gets the markup type (
il,c,h,b, ...), not<CJ>. That matches what the tokenizer does for Latin and Korean and lets the untokenized modes collapse it, but a filter that selects<CJ>tokens will not see these (option B is the other way). - Also covered: Hangul compatibility jamo, the part of the CJK Compatibility block in
CJ(U+3300-337F) and halfwidth Katakana ([[ㄱㄴ]]gives ㄱ|il ㄴ|il). Not covered: characters outsideCJ, such as 々, 〇 and supplementary-plane Han, which are lost in plain text too. - Not covered, pre-existing: bold or italics whose content is neither
ALPHANUMnorCJ(x '''!!!''' y z) still type the following wordsb; the hard-codedLETTER/DIGITranges (the sibling defect) are untouched. - No benchmark was run.
- Maintainers may prefer a rewrite on top of the current
StandardTokenizer, or deprecation (see "Why it is not intended").
What the checks validated
- The gradle regenerate task ran cleanly and updated the checksum file.
- The repro: 8 of 9 fail on stock, 9 of 9 pass with the fix (gradle and the repro runner,
-eaand-da). The finder's repro passes 8 of 8 and the independent reproduction's test 17 of 17 with the regenerated scanner. - An exact-token test (
TestWikipediaTokenizerCjkInMarkupTokens, 5 tests: tokens, offsets, types and position increments for the link sentence, the bold-title sentence, italics, an external-link label and the two untokenized modes): 5 of 5 pass with the fix (-eaand-da), 5 of 5 fail on stock. :lucene:analysis:common:test, the whole module with both new tests: 341 suites, 1,923 tests, 0 failed, 18 skipped, with assertions on (seed 5EED0708) and off (seed 5EED0709); upstreamTestWikipediaTokenizer8 of 8 andTestWikipediaTokenizerFactory6 of 6. Stock with both new tests: 13 failed, all in the new tests.:lucene:analysis:common:check -x test(format, ecjLint, forbiddenApis, every regenerate checksum check) passes;analysis.testsTestBugInSomething(itstestCuriousWikipediaStringuses WikipediaTokenizer): 0 failed.
Add per-state rules that return the CJ type but make the same transition as ALPHANUM (for example THREE_SINGLE_QUOTES_STATE to STRING). Not run.
Trade-offs
Keeps the plain-text type, but loses the markup information that is the class's purpose, and the untokenized modes would not collapse these tokens with the rest of the link (they collapse runs of one token type, WikipediaTokenizer.java:228-230, :273-275). More rules to get right.
One macro change. Not run.
Trade-offs
It also changes plain text: a run of CJ characters would become one <ALPHANUM> token instead of one <CJ> token per character, and runs mixed with Latin letters would merge.
Search applications that offer the wikipedia tokenizer factory (its javadoc shows a Solr schema) lose the same text on Chinese and Japanese wikis; StandardTokenizer keeps it, without the markup types.
A content-coverage sweep tokenized every string of length 1 to 3 over a 107-character alphabet (1,236,599 strings) and checked that every letter or digit lies in some token. WikipediaTokenizer lost Han and kana letters after ''; a probe of the markup constructs and a read of the grammar's states gave the cause. No formal tool was involved.
The method in full186 words
Method: bounded-exhaustive content-coverage sweep of the stock jar (the hunt's semi-formal tier).
- The sweep (2026-10-27, main
a9779ef3c193). A hunt unit on letters lost by tokenizers ran every string of length 1-3 over a 107-character alphabet, 1,236,599 strings per tokenizer configuration, with the oracle "every letter or digit of the input lies in some token". For WikipediaTokenizer it reported Han, Kana and Hangul compatibility-jamo letters lost after''(for example''一). - Root cause. A probe over the markup constructs showed the same loss in links, categories, headings, templates, citations and external-link labels, and a read of the grammar's lexical states found the missing
{CJ}rules. The finder reduced it to a public-API JUnit. - Checks. Claude verifiers wrote their own tests (the independent reproduction: 17 tests with an index check and a regenerated-scanner fix check; the intended-behaviour check: a devil's advocate who found the bold-title case). Review records by a model from another family (OpenAI GPT-5.6, executed mode) wrote and ran their own tests: both "real, high". An adjudication re-ran the independent reproduction's test with a fresh seed, and an independent audit ran its own probe.
No report found (2026-10-27: 51 tool queries over Lucene, Solr, Elasticsearch and OpenSearch issues, PRs, commits, lists and JIRA; all 21 WikipediaTokenizer issues; the file lists of the 409 open PRs; web and Q&A). Nearest: open #2218 (bold/italics inside a word) and #8050 (Unicode 3.0 data).
Searches5 searches
Novelty new: no issue, PR, JIRA ticket, list thread, downstream issue or Q&A post describes WikipediaTokenizer dropping Chinese or Japanese text inside wiki markup, and no open PR's changed-file list touches the wikipedia package or any .jflex file (four lists truncated at 100 files were checked by PR title). Closest items, none this bug: open #2218 / LUCENE-1141 (bold/italics inside a word, '''F'''oo, split into two tokens); #8050 / LUCENE-6993 and #3149 / LUCENE-2073 (the Unicode 3.0 character data, the sibling defect's area); open #5706 / LUCENE-4641 (offsets, the reason for @IgnoreRandomChains); #2210 / LUCENE-1133 (added the untokenized modes); Stack Overflow 16899373 (the English-only Category: keyword; its answer says the tokenizer "should support and index all languages"). Gaps: GitHub search does not cover attachments or code; JIRA and the lists by keyword only; ports such as Lucene.NET only through the global GitHub search; private security reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| scripted prior-report search | 2026-10-27 | 51 queries over apache/lucene issues, PRs and commits, the Solr, Elasticsearch and OpenSearch repositories, the dev@, java-user@, issues@ and commits@ lists and the JIRA archive | 151 hits, 0 high; every medium hit read, none this bug |
| GitHub (manual) | 2026-10-27 | all 21 WikipediaTokenizer issues read by title; CJK, Chinese, Japanese, unicode, link, category and WikipediaTokenizerImpl variants; downstream repositories and a global search | #2218, #8050, #3149, #5706, #2210; none about CJK text in markup |
| Open PRs | 2026-10-27 | changed files of all 409 open apache/lucene PRs | none touches the wikipedia package or any .jflex file; four lists truncated at 100 files (#365, #13949, #16847, #16911) were checked by title |
| JIRA, mailing lists, web and Q&A | 2026-10-27 | LUCENE-1103, -1133, -1141, -1161, -4641 and -7855 read in full; SOLR searches; three java-user threads; seven web searches (English and Chinese); the Stack Exchange API | usage questions and Stack Overflow 16899373 (a different limitation) |
| Verifiers' own searches | 2026-10-27 | The independent reproduction (39 tool queries) and the intended-behaviour check (29 tool queries plus gh searches) | 0 high hits |
Present since the tokenizer's first commit (f715fc60317, LUCENE-1103, 2008-01-04; first release 2.3.0). Probes lose the text on 19 releases from 2.3.0 to 10.5.2 and on main, with identical output; no commit has added a {CJ} rule to a markup state. Not fixed upstream.
Versions tested7 rows
Introduced by f715fc6031704bc1a3566044bb80a1a050b917ca, "LUCENE-1103", Grant Ingersoll, 2008-01-04 (SVN r608852, from a patch on LUCENE-1103 "WikipediaTokenizer", now GitHub #2180; no PR). The commit created the tokenizer in contrib/wikipedia: it copied ALPHANUM, KOREAN, CJ and the <YYINITIAL>{CJ} rule from StandardTokenizer's grammar and gave the nine new markup states {ALPHANUM} token rules only. Not a regression.
Later edits of these lines (b18f6ae9592 position increments, 305c47f5005 LUCENE-1133, ec2b654231e LUCENE-3477, d516948bbde LUCENE-5357) kept CJ ignored; git log -S'{CJ}' on the grammar finds only the introducing commit. Upstream main a95c754ee00 (2026-10-26) has the same grammar.
Limits: 2.3.2 and 2.4.0 have no artifact on Maven Central and were not run; other point releases carry the same grammar by reading (all 141 release tags that contain it).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this page's JUnit fails 8 of 9 with -ea and -da; the finder's 7 of 8; the independent reproduction's 14 of 17 |
| 10.5.2, 9.12.3 | affected | this page's JUnit fails 8 of 9 (-da); the probe loses 9 of 9 markup cases with -ea and -da |
| 10.0.0, 9.0.0, 8.11.4, 7.7.3, 6.6.6, 5.5.5, 5.0.0 | affected | the probe loses 9 of 9 markup cases, 6 of 6 controls kept |
| 4.10.4, 4.0.0, 3.6.2, 3.1.0, 3.0.3, 2.9.4, 2.9.0 | affected | the probe (era-specific API) loses 9 of 9 |
| 2.4.1, 2.3.1, 2.3.0 | first affected | the probe loses 9 of 9; 2.3.0 is the first release with the tokenizer |
| 2.2.0 | no API | WikipediaTokenizer does not exist (compile error; no artifact) |
| main with fix A | fix | the repro 9 of 9 and the exact-token test 5 of 5 pass (-ea and -da); analysis-common 1,923 tests, 0 failed |
Reproduced by the finder, independent verifiers with their own tests, cross-model reviews by OpenAI GPT-5.6 that ran their own tests (both real, high), an adjudication with a fresh seed and an independent audit, all with and without assertions.
Checks and verdicts359 words
Each check worked from the code and its own runs. This page's runs added a new repro, the gradle-regenerated fix, an exact-token test, gradle runs of the whole analysis-common module and a token and search probe in all three output modes.
| Check | Verdict | What it found |
|---|---|---|
| Finder's sweep and JUnit | candidate | The coverage sweep lost Han and kana letters after ''; the JUnit fails 7 of 8 on main with -ea and -da, on 10.5.2 and on 9.12.3. |
| Cross-model review, refute lens (OpenAI GPT-5.6, executed) | real (high) | Its own test (eight markup forms around one Han character) fails on main with -ea and -da, with three seeds and over 3 iterations, and on 10.5.2; its controls pass. Intended argument: moderate. |
| Independent reproducer | real | Own 17-test JUnit fails 14 of 17 on main (-ea, -da), 10.5.2 and 9.12.3; main() probe fails on 8.11.4 and 6.6.6; the regenerated-scanner fix passes everything, upstream TestWikipediaTokenizer 8 of 8. |
| Cross-model review, intended lens (OpenAI GPT-5.6, executed) | real (high) | Its test pins the loss on main, 10.5.2 and 9.12.3, also in UNTOKENIZED_ONLY and BOTH; StandardTokenizer keeps the same text. Re-run on a9779ef3c193. |
| Intended-behaviour devil's advocate | real | No intended argument survives; every other token class keeps its text inside markup; found the bold-title case (51 of 51 CJ characters lost on a synthetic article). |
| Adjudication | confirmed, high | Re-ran the independent reproduction's JUnit with seed 1D6E0001: 14 of 17 fail with -ea and with -da, controls pass. |
| History | since 2.3.0 | 19 releases and main executed, identical output; 2.2.0 has no tokenizer. |
| Security screen | none | Confined to the value being tokenized (executed probe, -ea and -da); no SECURITY.md guarantee involved. |
| Credibility audit | keep | Finder's JUnit 7 of 8 with -ea and -da and new seeds; own probe with new inputs (template, link label, bold lead). |
| This page's runs | fails 8 of 9 on main, 10.5.2, 9.12.3; fix A passes | The repro runner and gradle, -ea and -da; the scanner regenerated by gradle; the whole analysis-common module and its static checks with the fix and an exact-token test; token and search probes. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 439 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,223 words
- Registry title
- WikipediaTokenizer silently drops Chinese and Japanese text inside wiki markup (links, categories, headings, bold/italics, templates, citations, external-link labels): its grammar has a CJ token rule only for plain text, and every markup state matches ALPHANUM only
- Area
- analysis-common / wikipedia: WikipediaTokenizer (JFlex grammar lexical states, WikipediaTokenizerImpl.jflex)
- Priority
- Low, rank 304: Only Chinese or Japanese wiki text through the opt-in experimental WikipediaTokenizer is affected.
- Impact class
- silent wrong results
- Impact note
- Hits only applications that index Chinese or Japanese wiki text with the opt-in, @lucene.experimental WikipediaTokenizer (constructed directly or through the 'wikipedia' tokenizer factory; no Lucene analyzer uses it), with its default settings and in all three output modes: the text of links, categories, headings, bold/italics, templates, citations and external-link labels never reaches the index, so searches for those words miss the page, and a bold Chinese/Japanese lead word ('''日本'''は...) also drops the plain sentence after it; no scale is needed, nothing throws, and Latin and Korean text in the same markup is kept.
- Summary
- You tokenize Chinese or Japanese wiki text with WikipediaTokenizer, for example '[[日本]]', '[[Category:日本]]', '== 日本 ==' or "x '''東京''' y", and expect the text inside the markup to become tokens, as it does for Latin and Korean text in the same markup ('[[Japan]]', '[[한국]]') and for Chinese/Japanese plain text ('日本' gives 日|<CJ> and 本|<CJ>). Instead every Chinese/Japanese character inside markup is skipped without an error: '[[日本]]', '[[Category:日本]]', '== 日本 ==' and '<ref>日本</ref>' give no token at all, '[http://example.org 日本]' gives only the URL, and "x '''東京''' y" gives x and y, with y typed bold. The cause is the grammar: its only CJ token rule is for plain text (WikipediaTokenizerImpl.jflex:201), while all nine markup lexical states have a token rule for ALPHANUM only and ignore every other character (:219-309), and the CJ character class is disjoint from ALPHANUM.
- Introduced
- f715fc6031704bc1a3566044bb80a1a050b917ca (LUCENE-1103 'WikipediaTokenizer', migrated as GitHub #2180; Subversion r608852 from a JIRA patch, no pull request; committed by gsingers): the new contrib/wikipedia grammar copied the <YYINITIAL>{CJ} rule from StandardTokenizer's grammar and gave its nine new markup lexical states token rules for {ALPHANUM} only. No later commit added a {CJ} rule to a markup state: git log -S'{CJ}' on the grammar finds only this commit, and the later edits of these lines (b18f6ae9592 LUCENE-1103 position increments, 305c47f5005 LUCENE-1133, ec2b654231e LUCENE-3477, d516948bbde LUCENE-5357 '. | {WHITESPACE}' -> '[^]', af831d28105 LUCENE-10239 JFlex upgrade) all keep CJ ignored [read: git log and git blame in the full-history clone; executed: 2.3.0 is affected and 2.2.0 has no WikipediaTokenizer] (2008-01-04)
- First affected version
- 2.3.0 [exec] (released 2008-01-23; the tokenizer did not exist before: 2.2.0 has no WikipediaTokenizer [exec: compile error])
- Affected versions
- Every release from 2.3.0 through 10.5.2 and main a9779ef3c193 [exec: the version-portable history probe loses 9 of 9 markup cases with its controls passing on 2.3.0, 2.3.1, 2.4.1, 2.9.0, 2.9.4, 3.0.3, 3.1.0, 3.6.2, 4.0.0, 4.10.4, 5.0.0, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main (also with -da on 9.12.3, 10.5.2 and main); the finder's JUnit fails 7 of 8 on main (-ea and -da), 10.5.2 and 9.12.3; the independent reproduction's JUnit fails 14 of 17 on main, 10.5.2 and 9.12.3 (each with -ea and -da)]. By reading, all 141 release tags that contain the grammar have the single <YYINITIAL>{CJ} rule and the ALPHANUM-only state rules. Not executed: 2.3.2 and 2.4.0 (no artifact of the wikipedia module on Maven Central) and the other point releases (same grammar by reading). Not fixed: upstream main a95c754ee00 (2026-10-26) has the same grammar, and no open PR touches the wikipedia package or any .jflex file [read].
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (the prior-report record verdict new, searched 2026-10-27, read-only): a scripted prior-report search (51 queries over GitHub issues, PRs and commits, the Elasticsearch, OpenSearch and Solr repositories, the dev, java-user, issues and commits lists and the JIRA archive; 151 hits, 0 high, every medium hit read), manual GitHub searches (all 21 WikipediaTokenizer issues read by title; CJK, Chinese, Japanese, unicode, link and category variants; WikipediaTokenizerImpl; global GitHub), the changed-file lists of all 409 open apache/lucene PRs (none touches the wikipedia package or any .jflex file), JIRA (LUCENE-1103, -1133, -1141, -1161, -4641 and -7855 read in full; SOLR searches), three java-user threads, seven web searches (English and Chinese) and the Stack Exchange API, plus the independent reproduction's and the intended-behaviour check's own searches (0 high hits). Closest items, none of them this bug: open #2218 (LUCENE-1141, splitting at bold/italics inside a word), #3149 (LUCENE-2073) and #8050 (LUCENE-6993) about the tokenizer's hard-coded Unicode 3.0 character data (the sibling candidate's area), open #5706 (LUCENE-4641, offsets, the reason for @IgnoreRandomChains), #2210 (LUCENE-1133, the untokenized output modes) and Stack Overflow 16899373 (the English-only 'Category:' keyword). Not fixed: upstream main a95c754ee00 (2026-10-26). Gaps: GitHub search does not cover attachments or code; JIRA and the lists were searched by keyword only; ports such as Lucene.NET only through the global GitHub search.
- Lucene commit tested
- main
a9779ef3c193(2026-10-27) on OpenJDK 25.0.3, Linux aarch64: this page's JUnit through the repro runner with -ea and -da and through gradle in a scratch worktree (stock and fixed; the worktree was removed after the runs); the whole analysis-common test suite and its static checks with the fix; the 10.5.2 and 9.12.3 release jars; version probes on 19 releases from 2.3.0 to 10.5.2 (history step).
- Finding record
a Lucene main checkout lucene/analysis/common/src/java/org/apache/lucene/analysis/wikipedia/WikipediaTokenizerImpl.jflex:111 (ALPHANUM = ({LETTER}|{DIGIT}|{KOREAN})+), :154 (LETTER, hard-coded ranges ending at \u1fff plus \uffa0-\uffdc), :158 (KOREAN), :161 (CJ = \u3040-\u318f ... \u3400-\u4dbf \u4e00-\u9fff \uf900-\ufaff \uff65-\uff9f), :194-201 (YYINITIAL token rules; :201 '<YYINITIAL>{CJ}' is the only CJ rule), :216 (YYINITIAL ignore rule), :219-309 (INTERNAL_LINK_STATE :222, EXTERNAL_LINK_STATE :231, CATEGORY_STATE :237, TWO_SINGLE_QUOTES_STATE :246, THREE_SINGLE_QUOTES_STATE :257, FIVE_SINGLE_QUOTES_STATE :269, DOUBLE_EQUALS_STATE :281, DOUBLE_BRACE_STATE :288, STRING :300: {ALPHANUM} token rules, each state with a '[^]' ignore rule), :331 (global '[^] | {TAGS}' ignore rule); WikipediaTokenizer.java:35-41 (class javadoc 'Extension of StandardTokenizer that is aware of Wikipedia syntax ... but it may not be complete', @lucene.experimental, @IgnoreRandomChains), :85 (token type '<CJ>'), :136 and :146 (public constructors), :318-320 (reset calls scanner.yyreset); WikipediaTokenizerFactory.java:41 (NAME = "wikipedia"), :52 (default tokenOutput TOKENS_ONLY); lucene/analysis/common/src/resources/META-INF/services/org.apache.lucene.analysis.TokenizerFactory:28; grep -rl WikipediaTokenizer --include='*.java' lucene (no non-test caller outside the wikipedia package and module-info.java)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/wikipedia/WikipediaTokenizerImpl.jflex:111, 154-161, 201, 208-214, 219-310, 331lucene/analysis/common/src/java/org/apache/lucene/analysis/wikipedia/WikipediaTokenizer.java:85 (<CJ>), 180-212 (incrementToken), 318-324 (reset)
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/wikipedia/WikipediaTokenizer.java:35-42 (javadoc, @lucene.experimental, @IgnoreRandomChains), :136, 146, 158 (constructors)lucene/analysis/common/src/java/org/apache/lucene/analysis/wikipedia/WikipediaTokenizerFactory.java:28-33, 41, 52lucene/analysis/common/src/resources/META-INF/services/org.apache.lucene.analysis.TokenizerFactory:28grep -rl WikipediaTokenizer --include='*.java' lucene (only the wikipedia package, its tests, module-info.java and analysis.tests TestBugInSomething)
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/wikipedia/WikipediaTokenizer.java:35-42, 85lucene/analysis/common/src/java/org/apache/lucene/analysis/wikipedia/WikipediaTokenizerImpl.jflex:201, 219-310, 334-343lucene/analysis/common/src/test/org/apache/lucene/analysis/wikipedia/TestWikipediaTokenizer.java:66-285 (testHandwritten), 315-340 (testLinks); grep for CJK characters in the two upstream test files: none
- Suggested fix
lucene/analysis/common/src/java/org/apache/lucene/analysis/wikipedia/WikipediaTokenizerImpl.jflex:111-178 (macros used by the nine states), 222-300lucene/analysis/common/src/java/org/apache/lucene/analysis/wikipedia/WikipediaTokenizer.java:228-230, 273-275 (collapse by token type)
- TestWikipediaTokenizerLinkCjk.java (JUnit test):
repro/LFV-708/src/org/apache/lucene/analysis/wikipedia/TestWikipediaTokenizerLinkCjk.java(39 lines)
assets/LFV-708/bug.png(439 KB)