Each word in a nori dictionary has a left and a right context id; the tokenizer adds a matrix cost for each pair of neighbouring words. Each id is stored in a 14-bit field and read back as a signed short, so only 0 to 8191 round-trip. The builder checks that limit for the left id only.
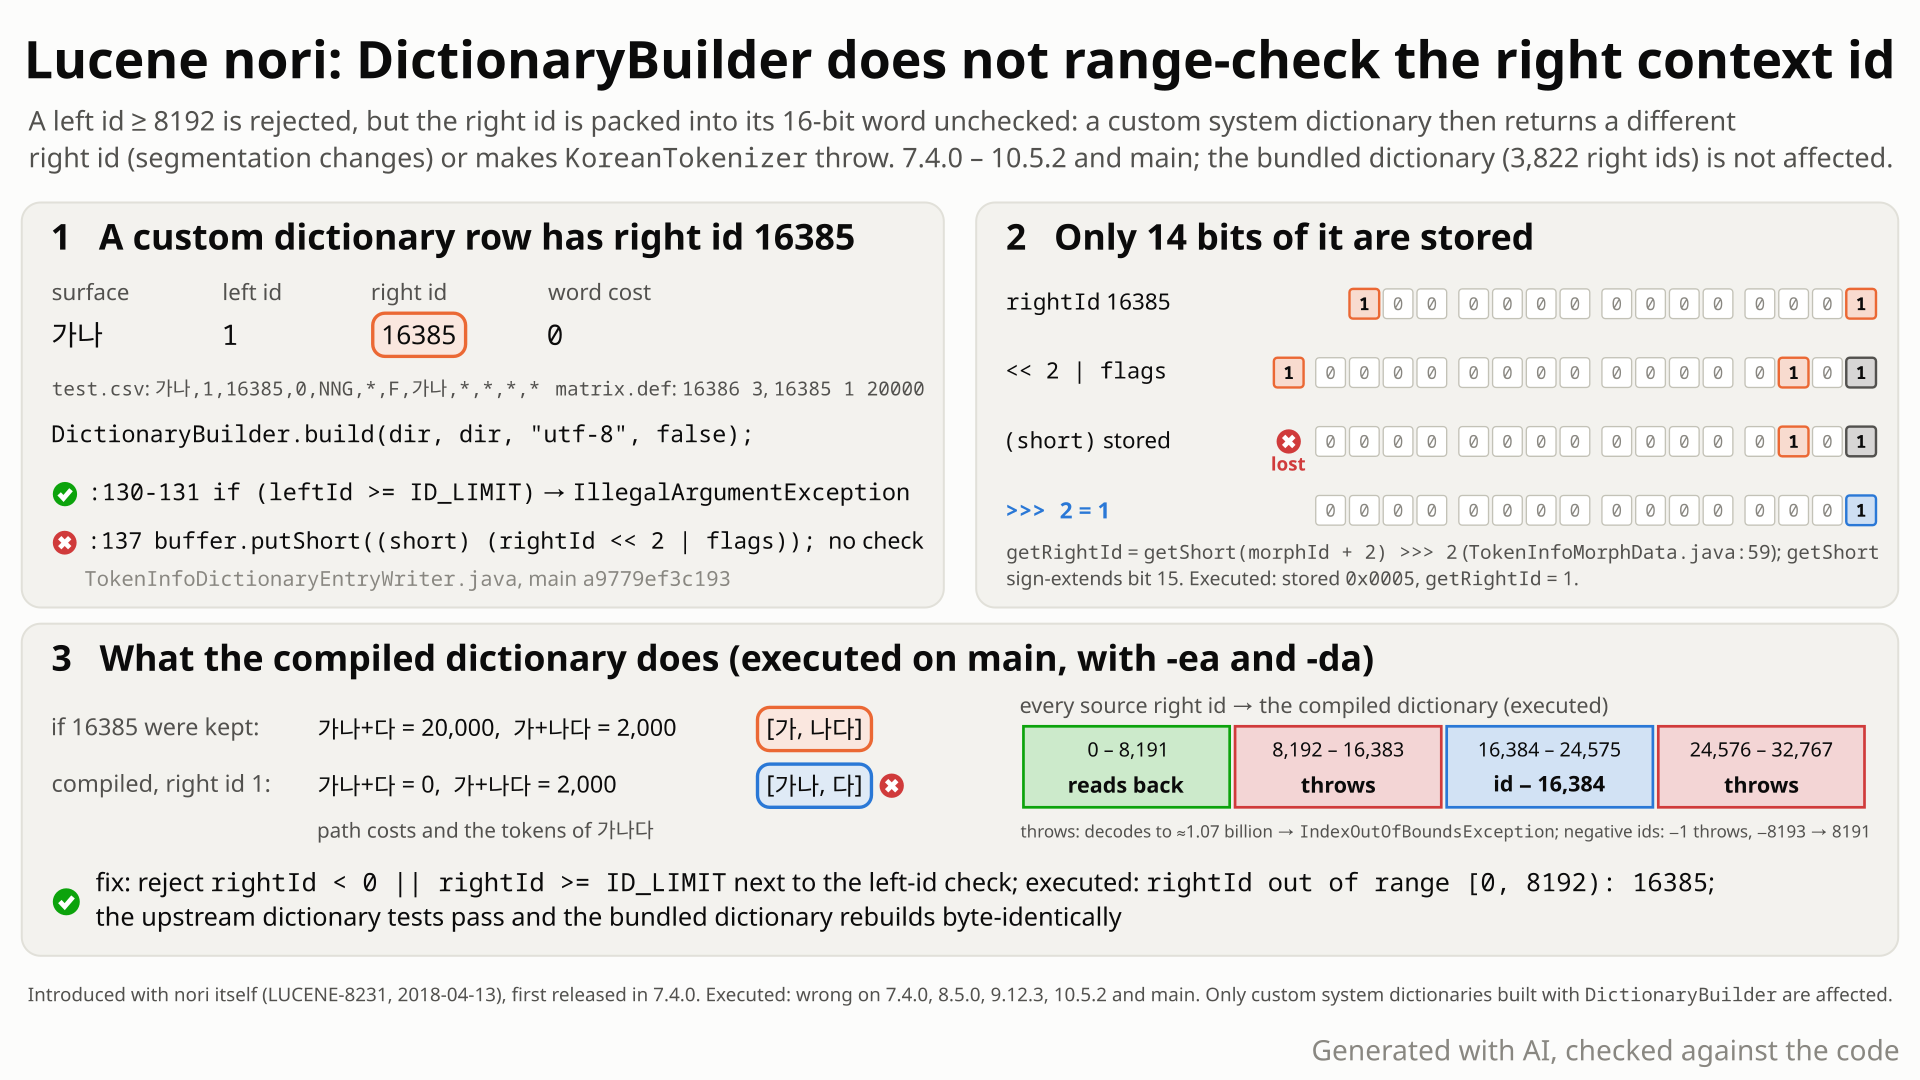
가나다 is split [가나, 다], not [가, 나다]. Ids 8192-16383 and 24576-32767 read back as about 1.07 billion and make the tokenizer throw; negative ids wrap the same way. Then the three-line fix. Select the still to open it at full size. Generated with AI, checked against the code.- You compile your own Korean dictionary with nori's
DictionaryBuilderfrom MeCab-format files. Every word has a left and a right context id, andmatrix.defgives the cost of each word pair by those ids. One row gives the word가나right id 16385; the matrix declares 16,386 right ids and makes any word after가나cost 20000. - You expect the build to reject the row, as it rejects a left id of 8192 (
leftId >= 8192: 8192), or the dictionary to return right id 16385, so that가나다is split[가, 나다](cost 2000). - The build succeeds. The right id is packed into a 14-bit field with no check (
TokenInfoDictionaryEntryWriter.java:137); 16385 needs 15 bits, so it reads back as 1. The tokenizer uses the costs of right id 1 and outputs[가나, 다]. - A right id from 8192 to 16383 or from 24576 to 32767 reads back as about 1.07 billion: the build still succeeds, and tokenizing any text with that word throws
IndexOutOfBoundsException. A negative id has one of the two outcomes (-1 throws; -8193 silently becomes 8191). The bundled dictionary (3,822 right ids) and the defaultKoreanAnalyzerare not affected.
Applications that compile their own nori system dictionary with DictionaryBuilder and load it through the custom-dictionary KoreanTokenizer constructor, when the source has a right id of 8192 or more or below 0. Ids 16384-24575 (and some negative ids) silently change segmentation; the other out-of-range ids make tokenization throw. The bundled dictionary and default analyzer are unaffected.
Mechanism, terms and numbers666 words
Nori's DictionaryBuilder compiles a custom Korean system dictionary from MeCab-format sources; the custom-dictionary KoreanTokenizer constructor is documented as the entry point for such dictionaries (@lucene.experimental). Each entry stores its left and its right context id shifted left by 2 in a 16-bit field (TokenInfoDictionaryEntryWriter.java:136-137), so each id gets a 14-bit field; the reader decodes it from a sign-extended short (TokenInfoMorphData.java:54, :59), so only 0 to 8191 round-trip. The builder rejects leftId >= 8192 with IllegalArgumentException (:130-132) but writes the right id unchecked (:137). Right ids 16384 to 24575 come back as id - 16384 (16385 becomes 1), which silently changes connection costs and segmentation (가나다 becomes [가나, 다] instead of [가, 나다] in the repro); right ids 8192 to 16383 and 24576 to 32767 come back as about 1.07 billion, and tokenizing text with the word throws IndexOutOfBoundsException from ConnectionCosts.get; a negative id has one of the two outcomes (-1 throws, -8193 becomes 8191). Word rows and unk.def rows go through the same writer. The bundled dictionary (3,822 right ids) and the default analyzer are not affected. Present since nori's first commit (7.4.0) and reproduced on every release tried up to 10.5.2 and main; a three-line IllegalArgumentException next to the left-id check fixes it, and the bundled dictionary rebuilds byte-identically with it.
- System dictionary: compiled by
DictionaryBuilder.build(Path, Path, String, boolean)(ko/dict/DictionaryBuilder.java:24-28, public) from MeCab-format word rows (*.csv),unk.def,char.defandmatrix.def; loaded with thePathconstructors ofTokenInfoDictionary,UnknownDictionaryandConnectionCostsand passed to the custom-dictionaryKoreanTokenizerconstructor, "an entry point for users that want to construct custom language models that can be used as input to {@link DictionaryBuilder}" (ko/KoreanTokenizer.java:138-152,@lucene.experimental). - Context ids:
matrix.defgives the cost of each (right id of a word, left id of the next word) pair. The tokenizer addscosts.get(lastRightID, leftID)between words (morph/Viterbi.java:471) andcosts.get(lastRightID, 0)at the end of input (:389), and keeps the cheapest path.
putEntryparses both ids withShort.parseShort(TokenInfoDictionaryEntryWriter.java:63-64), so 32768 and above already fail (withNumberFormatException).if (leftId >= ID_LIMIT) throw new IllegalArgumentException(...)(:130-132,ID_LIMIT = 8192at:33); there is no such check for the right id.buffer.putShort((short) (rightId << 2 | flags))(:137): bits 0-13 of the id survive; bit 13 (8192) lands in the sign bit and bit 14 (16384) is cut off.getRightIdisbuffer.getShort(morphId + 2) >>> 2(TokenInfoMorphData.java:58-60) on the sign-extended short: 16385 reads back as 1, 8192 as 1,073,733,632, -1 as 1,073,741,823.- So 0 to 8191 round-trip; 8192 to 16383 are written intact and only the signed read loses them (an unsigned read,
(getShort(...) & 0xffff) >>> 2, as kuromoji's reader does with its 3 flag bits atja/dict/TokenInfoMorphData.java:72,:77, returns them exactly); 16384 and above lose bit 14 on write. A negative id behaves like its value modulo 16384 (-8193 like 8191, -1 like 16383). ConnectionCosts.getreadsbuffer.getShort((backwardId * forwardSize + forwardId) * 2)(morph/ConnectionCosts.java:61-64) from a bounds-checked direct buffer: a wrapped id reads another id's costs; a huge id throwsIndexOutOfBoundsException.TokenInfoDictionaryWriter(:30) andUnknownDictionaryWriter(:35) both use this entry writer, sounk.defrows are affected too.
| source right id | read back | tokenizing the word |
|---|---|---|
| 1, 8191 | 1, 8191 | [가나] |
| 8192, 12000, 16383 | 1,073,733,632; 1,073,737,440; 1,073,741,823 | IndexOutOfBoundsException |
| 16384, 16385, 20000, 24575 | 0, 1, 3616, 8191 | [가나], with the costs of the wrong id |
| 24576, 32767 | 1,073,733,632; 1,073,741,823 | IndexOutOfBoundsException |
| -1, -8192 | 1,073,741,823; 1,073,733,632 | IndexOutOfBoundsException |
| -8193, -12000, -16384 | 8191, 4384, 0 | [가나], with the costs of the wrong id |
| -16385, -24576 | 1,073,741,823; 1,073,733,632 | IndexOutOfBoundsException |
| -24577, -32768 | 8191, 0 | [가나], with the costs of the wrong id |
| 32768 | build fails (NumberFormatException) | |
| left id 8192 (control) | build fails (IllegalArgumentException: leftId >= 8192: 8192) |
Exposure and likelihood287 words
- Who is exposed. Builders of custom or retrained nori system dictionaries. Before 8.5.0 such a dictionary could only be used by putting its files on the classpath ahead of the nori jar; from 8.5.0 the custom-dictionary constructor is the public path. User dictionaries do not go through this writer (
UserDictionaryuses fixed right ids,UserDictionary.java:41-45). - Default vs opt-in. Opt-in. The bundled dictionary has 3,822 right ids and 2,693 left ids (read from its
ConnectionCosts.datheader), so the defaultKoreanTokenizerandKoreanAnalyzernever reach the bug. - What the damage looks like. Right ids 16384 to 24575, and negative ids from -16384 to -8193 or from -32768 to -24577: the dictionary builds and loads, and every connection cost after the word comes from another id's row, so segmentation (and the indexed terms) can change with no error. Right ids 8192 to 16383 and 24576 to 32767, and negative ids from -8192 to -1 or from -24576 to -16385: the build still succeeds, and the failure comes later, wherever the tokenizer runs, as a bare
IndexOutOfBoundsExceptionthat does not name the dictionary row. - How likely. Rare, and contrived for the silent effect alone. MeCab context ids are dense (0 to N-1). A model with 8,193 to 16,384 right ids only crashes; a model big enough to reach the silent band also has ids in the crash band, so its user most likely sees the exception first. Larger MeCab models exist: an open kuromoji UniDic PR (#12517) shows Japanese context ids above 15,000. The documented searches found no prior report (2026-10-27, best effort).
- Scale and modes. One row reproduces it; assertions on and off behave the same (there is no assert either). The fix runs only at build time.
The test shows that nori's DictionaryBuilder accepts a lexicon row with right context id 16385 (it rejects a left id of 8192) and the compiled dictionary reads it back wrapped to 14 bits.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.ko.dict;

import java.nio.file.Files;
import java.nio.file.Path;
import org.apache.lucene.analysis.morph.BinaryDictionary;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.IntsRef;

public class TestNoriBuilderRightIdLimit extends LuceneTestCase {

  public void testRightId16385() throws Exception {
    Path dir = createTempDir();
    Files.writeString(dir.resolve("test.csv"), "가나,1,16385,100,NNG,*,F,가나,*,*,*,*\n");
    Files.writeString(dir.resolve("char.def"), "DEFAULT 0 1 0\n");
    Files.writeString(dir.resolve("unk.def"), "DEFAULT,1,1,0,SY,*,*,*,*,*,*,*\n");
    Files.writeString(dir.resolve("matrix.def"), "16386 2\n");
    try {
      DictionaryBuilder.build(dir, dir, "utf-8", false);
    } catch (IllegalArgumentException e) {
      return;
    }
    String base = TokenInfoDictionary.class.getName().replace('.', '/');
    TokenInfoDictionary dict =
        new TokenInfoDictionary(
            dir.resolve(base + BinaryDictionary.TARGETMAP_FILENAME_SUFFIX),
            dir.resolve(base + BinaryDictionary.POSDICT_FILENAME_SUFFIX),
            dir.resolve(base + BinaryDictionary.DICT_FILENAME_SUFFIX),
            dir.resolve(base + TokenInfoDictionary.FST_FILENAME_SUFFIX));
    IntsRef ids = new IntsRef();
    dict.lookupWordIds(0, ids);
    // expected: the row is rejected or right id 16385 reads back; actual: it reads back as 1
    assertEquals(16385, dict.getRightId(ids.ints[ids.offset]));
  }
}
# in a copy of this finding's repro folder (repro/LFV-710/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/analysis/nori/build/libs/lucene-analysis-nori-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.ko.dict.TestNoriBuilderRightIdLimit
# the module(s) analysis-nori also need their third-party runtime jars
- Expected vs actual
- Expected the build to reject the row or
getRightIdto return 16385; actual 1 (expected:<16385> but was:<1>), with-eaand-da.
More files, environment, full output34 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<16385> but was:<1>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:647)
       org.junit.Assert.assertEquals(Assert.java:633)
org.apache.lucene.analysis.ko.dict.TestNoriBuilderRightIdLimit.testRightId16385(TestNoriBuilderRightIdLimit.java:48)- Both ids use the same 14-bit packing, and the builder already rejects an overlarge left id; upstream
testPutExceptionexpects// id too largeto fail but sets both ids to 8192. - In LUCENE-8816 committers asked for exceptions on "leftID (and rightID)", "since we would get garbage".
- The right-id bound was lost when the code was ported from kuromoji.
The full argument314 words
- The builder's own rule. Both ids are written as
(short) (id << 2 | bits)(TokenInfoDictionaryEntryWriter.java:136-137) and decoded asgetShort(...) >>> 2(TokenInfoMorphData.java:54,:59); with that signed read only 0 to 8191 round-trip, and the builder enforces that limit (ID_LIMIT,:33) for the left id (:130-132). No javadoc, CHANGES or MIGRATE entry states an id range, and nothing says an id may wrap. - Upstream tests.
TestTokenInfoDictionary.testPutException(:92-99):// id too largeexpectsnewDictionary("HANGUL,8192,8192,1,NNG,*,*,*,*,*,*,*")to throw; with both ids at 8192 only the left check is exercised.testPut(:45-64) uses ids 5000 with a1 1matrix, so the tests rely on there being no check againstmatrix.def. - What the committers said. #9860 (LUCENE-8816, kuromoji), @msokolov: "we restrict incoming leftID (and rightID) to be <4096 ... change the asserts there to be IllegalArgumentException so they are raised whenever the tool is run, since we would get garbage if this limit is exceeded, and (I think) nothing else will catch it"; @rmuir: "The use of assert was laziness on my part: we should treat it as technical debt and fix it"; @mocobeta: "change the all assertions to some Exceptions so that users can figure out the problem with their customized dictionary". #9947 (LUCENE-8904), which added nori's left-id exception, notes "left context ID == right context ID / Nori : can be different / Kuromoji : always same".
- History. Kuromoji's writer had
assert leftId == rightId; assert leftId < 4096;, so its bound covered both ids. Nori's first commit (e851b89cbeb, LUCENE-8231) dropped the equality, because nori's ids differ, and kept onlyassert leftId < 8192; LUCENE-8904 (2ac5fb668a8on master; backport70854dc1efbin 8.3.0) turned that into today's exception and added nothing for the right id. Kuromoji today checksleftId != rightIdbefore its limit (ja/dict/TokenInfoDictionaryEntryWriter.java:117-122).
The devil's-advocate check210 words
The case for intended behaviour (the intended-behaviour check and the adjudication: weak to moderate; the cross-model fact check: moderate): DictionaryBuilder is a lightly validating, @lucene.experimental build tool for trusted input; it never checks ids against matrix.def; and in #9860 @mocobeta wrote "There is another possibility that users give large values to leftIDs (and rightIDs) in their customized dictionary by hand, however I don't think we should take care about that."
Why it fails: that remark is about whether to support larger ids, and the same comment asks for exceptions so users can find the problem in their dictionary. The limit here is the builder's own ID_LIMIT, the range its format reads back correctly, which only the builder can enforce and which it already enforces for the other id stored the same way. The outcome is not a clear error but a dictionary that silently means something else, or crashes later. What the case gets right: the reach is narrow. Also, 8192 is a limit of the signed read, not of the stored bits, so maintainers may prefer to support 8192 to 16383 with an unsigned read (the second fix option) instead of rejecting them; ids of 16384 and more and negative ids need the check either way.
Recommended Reject a right id outside [0, 8192) at build time
Reject a right id outside [0, 8192) with IllegalArgumentException, next to the existing left-id check (+3 lines in TokenInfoDictionaryEntryWriter.java), and add two cases to testPutException. The new tests and the whole nori module (14 suites, 93 tests) pass with assertions on and off, and the bundled dictionary rebuilds byte-identically.
    if (leftId >= ID_LIMIT) {
      throw new IllegalArgumentException("leftId >= " + ID_LIMIT + ": " + leftId);
    }
+   if (rightId < 0 || rightId >= ID_LIMIT) {
+     throw new IllegalArgumentException("rightId out of range [0, " + ID_LIMIT + "): " + rightId);
+   }
All options and trade-offs4 options · 658 words
Keep the fix to the builder's own limit (ID_LIMIT), or read the field unsigned (the second option). A check against the matrix.def dimensions is a separate, wider gap that the upstream testPut would trip. Side observation: a negative left id already fails the build, but with IndexOutOfBoundsException: Index -1 out of bounds for length 0 from the part-of-speech table (TokenInfoDictionaryEntryWriter.java:94-101), before the left check at :130 is reached; moving both checks right after the parse would give it a clear message too (not run).
Add the check after the left-id check in TokenInfoDictionaryEntryWriter.putEntry (:130-132), and two right-id-only cases to TestTokenInfoDictionary.testPutException. The finder's fix; the lower bound was added after the cross-model review.
    if (leftId >= ID_LIMIT) {
      throw new IllegalArgumentException("leftId >= " + ID_LIMIT + ": " + leftId);
    }
+   if (rightId < 0 || rightId >= ID_LIMIT) {
+     throw new IllegalArgumentException("rightId out of range [0, " + ID_LIMIT + "): " + rightId);
+   }
Trade-offs
- Build time only: no cost at analysis time.
- A dictionary in the silent band that seems to work today stops building; it was already compiled wrong.
- Covers word rows and
unk.defrows (one writer). It does not check ids againstmatrix.def. - It also rejects 8192 to 16383, which the stored field holds and only the signed read loses; the unsigned-read option would accept them instead.
What the checks validated
- Scratch worktree at
a9779ef3c193, gradle, JDK 25: on stock the new test fails 4 of 6 (assertions on, seed 0B1D0710, and off, seed 0B1D0711) and the extendedtestPutExceptionfails; with the fix,org.apache.lucene.analysis.ko.dict.*: 5 suites, 20 tests, 0 failures, assertions on and off; the whole:lucene:analysis:nori:test: 14 suites, 93 tests, 4 skipped, 0 failures, assertions on and off;checkGoogleJavaFormatpasses. - Standalone runner with the fix shadowed: 6 of 6 (
-ea,-da); the probe rejects the 11 out-of-range ids from -8192 to 32767 withIllegalArgumentExceptionand still builds 1 and 8191. - Earlier: the bundled mecab-ko-dic 2.1.1 rebuilt with the fix is byte-identical (9 files); the finder's test 4 of 4, the independent reproduction's 7 of 7, the cross-model reviewers' tests, and the upstream
TestTokenInfoDictionary+TestUnknownDictionary6 of 6 pass.
Ids 8192 to 16383 are written intact; only the signed read loses them. Read (buffer.getShort(...) & 0xffff) >>> 2 in getLeftId and getRightId (TokenInfoMorphData.java:54, :59), as kuromoji's reader does with its 3 flag bits (ja/dict/TokenInfoMorphData.java:72, :77), and raise ID_LIMIT to 16384. Evaluated with the same Java expressions, not with Lucene: this read returns every id in [0, 16383] exactly and, below 8192, the same value as today, so existing dictionaries read back the same and the on-disk layout does not change. The first option's check is still needed with the new limit: 16384 and above lose bit 14 on write, and a negative id would read back as id mod 16384 (-1 as 16383). Not run in Lucene.
Trade-offs
Supports larger models instead of rejecting them, so it is closer to a feature. A dictionary that uses the new range is misread by older Lucene versions. The cost matrix is right ids x left ids shorts in one direct buffer (morph/ConnectionCosts.java:46-49), about 88 MB for 16,384 x 2,693. Ids beyond 16383 need a wider field and a DictionaryConstants.VERSION bump.
Not run.
Trade-offs
Catches more broken sources, but the upstream testPut (ids 5000 with a 1 1 matrix) would fail, and it is a separate, wider gap.
A bounds check in getRightId or ConnectionCosts.get. Not run.
Trade-offs
Adds work on the analysis hot path and cannot detect the silent band, where the decoded id (16385 -> 1) is valid.
Lucene treats dictionary sources as trusted configuration; a product that compiles system dictionaries supplied by its own users should check right ids (0 to 8191) itself until a fix ships.
An AI finder was checking that the bundled nori dictionary decodes back to its mecab-ko-dic source (12.7 million checks), which cannot show this bug because every bundled id is below 8192. Reading the encoding, the finder saw that the left id is range-checked and the right id is not, and confirmed it with a tiny custom dictionary.
The method in full124 words
Method: bounded-exhaustive translation validation on the stock jars, then code reading (the study's "semi-formal" tier). A hunt unit, "CJK compiled-dictionary source round trip", 2026-10-27.
- The harness compared every field of every entry of the shipped nori dictionary with its mecab-ko-dic 2.1.1 source row, with assertions on and off: 12,723,657 checks, clean apart from compound rows of another hunt bug and reading rows that are harmless by construction.
- Reading the encoding of each checked field showed the asymmetry: an explicit 8192 limit for the left id and none for the right id, packed the same way.
- The hypothesis was turned into a public-API JUnit that builds a tiny custom dictionary with
DictionaryBuilder; independent AI tools then reproduced, reviewed and judged it (see the checks).
No prior report found (best-effort search, 2026-10-27): 51 tool queries and 30 manual GitHub searches over issues, PRs, commits, JIRA, four mailing lists, downstream projects and the web, plus all 409 open PRs. Related threads added the left-id check (LUCENE-8904) and discussed kuromoji's id limits (LUCENE-8816), never nori's right id.
Searches5 searches
Nothing reports the unchecked right id, the wrapped id or the exception. TokenInfoDictionaryEntryWriter.java is byte-identical on upstream main a95c754ee003 (2026-10-26), branch_10x and branch_10_6; no open PR touches it.
Related, not the same bug: #9947 / LUCENE-8904 and lucene-solr #767 (added the left-id check); #9860 / LUCENE-8816 (open; kuromoji id limits, "garbage if this limit is exceeded"; kuromoji enforces left == right); #9906 / LUCENE-8863 (kuromoji counterpart); #10293 / LUCENE-9253 (the custom-dictionary constructor); #9278 / LUCENE-8231 (introduced nori); #740 / LUCENE-10393 and #9861 / LUCENE-8817 (builder unification); #12517 (open kuromoji UniDic PR, context ids above 8192); SOLR-12655 (a user building nori from an edited mecab-ko-dic, a different error); #9649 / LUCENE-8603 and #13427 (user-dictionary right ids, other code).
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene, apache/lucene-solr, downstream search servers) | 2026-10-27 | 16 issue/PR, 3 commit and 2 downstream queries with a scripted prior-report search; 30 manual searches (right id, rightId, right context, ID_LIMIT, the writer class, IndexOutOfBoundsException with ConnectionCosts, Viterbi or KoreanTokenizer, unk.def, matrix.def); a title sweep of 85 nori/Korean items | no report; related items listed above |
| Open PRs | 2026-10-27 | the changed files of all 409 open apache/lucene PRs | none touches TokenInfoDictionaryEntryWriter.java |
| Mailing lists and JIRA | 2026-10-27 | 20 tool queries over dev@, java-user@, issues@ and commits@, and 15 manual queries over dev@, java-user@ and issues@; 4 tool and 6 manual JQL queries | no report |
| Web | 2026-10-27 | 6 tool queries and 2 manual queries, one in Korean | no report |
| The finder's own run | 2026-10-27 | 43 queries (GitHub, commits, lists, JIRA) | no report |
Present since nori's first commit (e851b89cbeb, LUCENE-8231, 2018), first released in 7.4.0; the line never changed. It reproduces on every release run from 7.4.0 to 10.5.2 and on main. The fully public path (the custom-dictionary constructor) exists from 8.5.0.
Versions tested7 rows
Introduced by e851b89cbeb1 (master, 2018-04-13, LUCENE-8231 "Add a new analysis module (nori) similar to Kuromoji but to handle Korean"; JIRA patch workflow, now #9278) and its same-day branch_7x backport 8651fbaa8bc6, shipped in 7.4.0. The original put() had only assert leftId < 8192; the kuromoji code it was ported from asserted leftId == rightId and leftId < 4096. Later changes near the check, none of which fixed it: LUCENE-8904 (2ac5fb668a8 on master, first released in 9.0.0; its branch_8x backport 70854dc1efb shipped in 8.3.0) turned the left-id assert into the exception; LUCENE-8934 (8.3.0) put DictionaryBuilder in the jar; LUCENE-9253 (8.5.0) added the public custom-dictionary constructor; LUCENE-10400 (9.1.0) the Path constructors; LUCENE-10393 and LUCENE-10475 (10.0.0) moved the writer to its current name. On 7.4.0-8.2.0 the left id is also only assert-checked. Not a regression; never fixed.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the brief's test 4 of 6 fail (gradle and the standalone runner, assertions on and off) |
| 10.5.2 | affected | the brief's test 4 of 6 fail (assertions on and off); the finder's test 3 of 4 |
| 9.12.3, 9.1.0, 10.0.0 | affected | the finder's JUnit (9.x variant on 9.x) 3 of 4 fail; the independent reproduction's 4 of 7 on 9.12.3 |
| 8.5.0, 8.11.4, 9.0.0 | affected | public-API JUnit (ResourceScheme constructors) 3 of 4 fail |
| 7.4.0, 8.3.0 | affected | history driver: 16385 reads back as 1, segmentation changes, 8192 crashes tokenization; on 7.4.0 with -da a left id of 8192 is accepted too |
| 7.3.1 | no nori module | no nori artifact for 7.3.1 |
| main + fix | not affected | all repros pass; the nori module's 14 suites, 93 tests, 0 failed |
An independent reproducer, a devil's advocate, an adjudication and reviews by another model family (all ran their own tests) found it real; the adjudication confirmed it with high confidence. A registry re-run, a credibility audit and this doc's runs reproduced it with new seeds.
Checks and verdicts465 words
Every check wrote or ran its own test against the stock jars, with assertions on and off unless noted. The cross-model reviews ran on main ea57360912ed, whose lucene/analysis/nori is identical to a9779ef3c193.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Public-API JUnit fails 3 of 4 on main (-ea, -da), 10.5.2 and 9.12.3; with the fix 4 of 4 pass; the bundled dictionary rebuilds byte-identically. |
| cross-model review, refute lens | real (high) | An independent reviewer from another model family (OpenAI GPT-5.6) ran its own test: right id 8192 decodes as 1073733632 and tokenizing throws; controls pass; it passes with the fix. It noted that negative right ids are accepted too, which the fix now rejects. |
| Independent reproducer | real | Own 7-test JUnit with a MeCab-consistent matrix fails 4 of 7 on main (-ea, -da), 10.5.2 and 9.12.3; its 3 controls pass; 7 of 7 with the fix. |
| Cross-model review, intended lens | real (high) | OpenAI GPT-5.6: the intended-behaviour argument is weak; its contract test fails 2 of 3 on main and passes 3 of 3 with the fix. |
| Devil's advocate | real | Own test fails 3 of 4 on main and 10.5.2: right ids 32767 and -1 are accepted, and an unk.def row with right id 16385 reads back as 1. |
| adjudication | confirmed (high) | Re-ran the independent reproduction's test with new seeds: 4 of 7 fail with -ea and -da, 7 of 7 pass with the fix. Class: silent wrong results. |
| registry re-run and audit | kept; score lowered | The finder's test fails 3 of 4 with fresh seeds (-ea, -da) and passes with the fix; the audit kept the class and lowered the likelihood for the silent effect. |
| fact check of this doc | bug, repro and fix confirmed; wording fixed | Re-ran the gradle repro in a fresh worktree (4 of 6 fail, assertions on and off and a random seed), the fix (the nori module's 93 tests pass) and a probe of its own over 20 right ids. It found 2 low and 4 trivial wording errors, chiefly that only some negative ids throw; all six are fixed. |
| cross-model fact check | real; wording corrected | OpenAI GPT-5.6, reading the code and the saved runs: the bug is real, and the 8192 limit comes from the signed read, not from the stored bits (8192 to 16383 are written intact). That correction, the negative-id bands, a commit/release pairing and an overclaim are fixed, and the unsigned read is now a fix option. |
| this doc's runs | reproduced; fix validated | The paste-ready test fails 4 of 6 on main (gradle and standalone, -ea, -da) and 10.5.2; with the fix the nori module's 93 tests pass. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 474 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,470 words
- Registry title
- Nori's DictionaryBuilder rejects a left context id of 8192 or more but silently accepts such a right context id, which does not round-trip through the compiled format, so the compiled dictionary returns a wrapped right id (changing segmentation) or makes KoreanTokenizer throw IndexOutOfBoundsException
- Area
- analysis / nori system dictionary builder (DictionaryBuilder, TokenInfoDictionaryEntryWriter; custom system dictionaries)
- Priority
- Low, rank 523: Nori's DictionaryBuilder silently wraps right context ids of 8192 or more only for an opt-in custom system dictionary far larger than any known Korean model, which is rarer than LFV-459, so it follows that kuromoji/nori rare-input row.
- Impact class
- silent wrong results
- Impact note
- Hits only applications that compile their own nori system dictionary with the public DictionaryBuilder and load it through the @lucene.experimental custom-dictionary KoreanTokenizer constructor (opt-in), and only when the source uses a right context id of 8192 or more (or a negative one): ids in [16384, 24575] silently wrap to id - 16384 and change connection costs and segmentation, while ids in [8192, 16383] and [24576, 32767] make tokenizing any text that contains the word throw IndexOutOfBoundsException, and a negative id has one of the two outcomes (it behaves like its value mod 16384: -1 throws, -8193 silently reads back as 8191); the bundled mecab-ko-dic 2.1.1 (3,822 right ids), and so the default KoreanTokenizer and KoreanAnalyzer, are not affected; no scale needed, deterministic with -ea and -da, every release 7.4.0 to 10.6.0 (10.6.0 by reading) and main.
- Summary
- You compile a custom nori system dictionary with DictionaryBuilder from MeCab-format sources in which a lexicon row (or an unk.def row) has right context id 16385, with a matrix.def that declares 16386 right ids, and expect the row either to be rejected, as a left id of 8192 is ('leftId >= 8192'), or to read back as 16385. Instead the builder accepts it and packs the id into a 14-bit field without any check (TokenInfoDictionaryEntryWriter.java:137), so Dictionary.getRightId returns 1 and KoreanTokenizer uses the connection costs of right id 1: in the repro '가나다' is split [가나, 다] instead of [가, 나다]. A right id in [8192, 16383] decodes to about 1.07 billion, and tokenizing any text that contains the word throws IndexOutOfBoundsException from ConnectionCosts.get.
- Introduced
- e851b89cbeb1f55edc0f2c1276e2ae812eca2643 (LUCENE-8231 'Add a new analysis module (nori) similar to Kuromoji but to handle Korean', by jimczi; JIRA patch workflow, no pull request; the issue is now apache/lucene#9278) and its same-day branch_7x backport 8651fbaa8bc65fdfec397ad4e7ebe2b5acf78d7b, which shipped in 7.4.0 [read: git blame of TokenInfoDictionaryEntryWriter.java:137 on main a9779ef3c193 points at e851b89cbeb1; the original put() had 'assert leftId < 8192; // there are still unused bits' and the unchecked right-id write; the Kuromoji writer it was ported from asserted leftId == rightId and leftId < 4096, which bounded both ids, and the port dropped the equality because nori's ids differ; LUCENE-8904 (#9947; 2ac5fb668a8 master, 70854dc1efb branch_8x; 8.3.0) turned the left-id assert into today's IllegalArgumentException and added nothing for the right id; git log --all -G over lucene/analysis/nori finds no commit that ever added a right-id bound]. Not a regression: the gap dates from the module's first commit (2018-04-13)
- First affected version
- 7.4.0 [exec] (nori's first release; 7.3.1 has no nori module [exec: no artifact on Maven Central]). Reach by version: 7.4.0-8.2.0 ship the builder only as a source-release tool, and a custom dictionary can be loaded only by putting it on the classpath ahead of the jar; 8.3.0 puts DictionaryBuilder in the jar (LUCENE-8934); 8.5.0 adds the public custom-dictionary KoreanTokenizer constructor (LUCENE-9253), the first fully public path
- Affected versions
- Every release from 7.4.0 through 10.5.2 (latest 9.x 9.12.3), 10.6.0 (by reading) and main a9779ef3c193; never fixed. [exec] fails on 7.4.0 (-ea and -da; history driver with the 7.4.0 source-release builder; there the left id is also only assert-checked, so with -da a left id of 8192 is accepted too), 8.3.0 (-ea and -da; history driver), 8.5.0 (-ea and -da), 8.11.4, 9.0.0 (-ea and -da), 9.1.0, 9.12.3 (-ea and -da), 10.0.0, 10.5.2 (-ea and -da) and main (-ea and -da): from 8.5.0 on a public-API JUnit variant fails 3 of 4 with its left-id control passing; the independent reproduction's test fails 4 of 7 on main, 10.5.2 and 9.12.3. [read] every local release tag from 7.4.0 to 8.8.1 and from 9.0.0 to 10.5.2 has the unchecked write; 8.8.2-8.11.3 are not tagged locally (between 8.8.1 [read] and 8.11.4 [exec], both affected). TokenInfoDictionaryEntryWriter.java is byte-identical on upstream main a95c754ee003 (2026-10-26), branch_10x and branch_10_6, and no open PR touches it. All runs on JDK 25, aarch64
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: code reading
- Upstream and prior reports
- none found (2026-10-27, plus the finder's run and its gh checks, read-only; the prior-report record, verdict new): a scripted prior-report search with 51 queries (152 distinct hits, 0 high) over apache/lucene issues, PRs and commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web; 30 manual GitHub searches (apache/lucene, apache/lucene-solr, Elasticsearch, OpenSearch, Solr); a GraphQL title sweep of 85 nori/Korean items and the changed files of all 409 open apache/lucene PRs; 6 JQL and 15 mailing-list queries; the finder's own 43-query run. Related, not this bug: #9947 / LUCENE-8904 and lucene-solr#767 (added today's left-id check; the description says nori's left and right ids 'can be different'; nobody mentions the right id), #9860 / LUCENE-8816 (open, kuromoji: committers agreed that id-limit asserts should become exceptions because overlarge ids give 'garbage'; kuromoji enforces leftId == rightId, so the thread never identifies nori's unchecked right id), #9906 / LUCENE-8863 (kuromoji counterpart), #10293 / LUCENE-9253 (added the custom-dictionary KoreanTokenizer constructor), #9278 / LUCENE-8231 (introduced nori), #740 / LUCENE-10393 and #9861 / LUCENE-8817 (builder unification), #12517 (open kuromoji UniDic PR; shows MeCab dictionaries with context ids above 8192), SOLR-12655 (a user building nori from an edited mecab-ko-dic; a different error), #9649 / LUCENE-8603 and #13427 (user-dictionary right ids, other code). Not fixed: TokenInfoDictionaryEntryWriter.java is byte-identical on upstream main a95c754ee003, branch_10x and branch_10_6, and no open PR touches it. Gaps: lexical, first-page GitHub search under a shared rate limit; Korean forums covered only by general web search; private trackers not visible
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-28) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the 10.5.2 release jars (the brief's test, assertions on and off). Earlier runs of the hunt, its checks and the version-history runs (2026-10-27): 7.4.0, 8.3.0, 8.5.0, 8.11.4, 9.0.0, 9.1.0, 9.12.3, 10.0.0, 10.5.2 and main; 7.3.1 has no nori module. Fix A was validated in the scratch worktree (the new test, the dictionary suites and the whole nori module with assertions on and off,checkGoogleJavaFormat) and earlier by rebuilding the bundled dictionary (byte-identical). Only Linux aarch64 with JDK 25 was run.
- Finding record
lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/dict/TokenInfoDictionaryEntryWriter.java:33 (at a9779ef3c193) (ID_LIMIT = 8192), :63-64 (left and right id parsed with Short.parseShort), :130-132 (only leftId >= ID_LIMIT rejected), :136-137 (putShort((short) (leftId << 2 | posType.ordinal())) and putShort((short) (rightId << 2 | flags)), no right-id check); TokenInfoMorphData.java:53-60 (getLeftId and getRightId decode getShort(..) >>> 2 of a sign-extended short); TokenInfoDictionaryWriter.java:30 and UnknownDictionaryWriter.java:35 (both use TokenInfoDictionaryEntryWriter); DictionaryBuilder.java:24-28 (public class, public static build(Path, Path, String, boolean)); ko/KoreanTokenizer.java:138-152 (custom-dictionary constructor, 'an entry point for users that want to construct custom language models that can be used as input to DictionaryBuilder', @lucene.experimental); lucene/analysis/common/src/java/org/apache/lucene/analysis/morph/ConnectionCosts.java:61-64 (get indexes the matrix buffer with the decoded id); morph/Viterbi.java:389 (end-of-input cost costs.get(lastRightID, 0)); lucene/analysis/nori/src/test/org/apache/lucene/analysis/ko/dict/TestTokenInfoDictionary.java:95-98 (testPutException '// id too large' with left = right = 8192)
- The finding in 30 seconds
lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/dict/TokenInfoDictionaryEntryWriter.java:33, (at a9779ef3c193) :62-64, :130-137lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/dict/TokenInfoMorphData.java:53-60; (at a9779ef3c193) lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/dict/TokenInfoMorphData.java:71-78 (at a9779ef3c193) (masked read)lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/dict/TokenInfoDictionaryWriter.java:30; (at a9779ef3c193) lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/dict/UnknownDictionaryWriter.java:35 (at a9779ef3c193)lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/dict/DictionaryBuilder.java:24-28; (at a9779ef3c193) lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/KoreanTokenizer.java:138-154 (at a9779ef3c193)lucene/analysis/common/src/java/org/apache/lucene/analysis/morph/ConnectionCosts.java:33-64; (at a9779ef3c193) morph/Viterbi.java:389, :471, :530-538
- Who is affected
lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/dict/UserDictionary.java:40-45; (at a9779ef3c193) lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/KoreanTokenizer.java:138-152 (at a9779ef3c193)
- Why it looks unintended
lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/dict/TokenInfoDictionaryEntryWriter.java:130-137; (at a9779ef3c193) lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/dict/TokenInfoMorphData.java:54, (at a9779ef3c193) :59lucene/analysis/nori/src/test/org/apache/lucene/analysis/ko/dict/TestTokenInfoDictionary.java:45-64, (at a9779ef3c193) :80, :92-99lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/dict/TokenInfoDictionaryEntryWriter.java:117-122 (at a9779ef3c193)
- Suggested fix
lucene/analysis/common/src/java/org/apache/lucene/analysis/morph/ConnectionCosts.java:46-49; (at a9779ef3c193) lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/dict/TokenInfoDictionaryEntryWriter.java:94-101 (at a9779ef3c193)
- TestNoriBuilderRightIdLimit.java (JUnit test):
repro/LFV-710/src/org/apache/lucene/analysis/ko/dict/TestNoriBuilderRightIdLimit.java(50 lines)
A light, step-by-step picture of the repro (the row, the bits, the two segmentations, every right id of 8192 or more, the fix), made in parallel with this doc from the code at a9779ef3c193 and executed runs. The caption and alt text were written from the same executed values; check them against the final frames.
assets/LFV-710/bug.png(474 KB)