One affix rule, one word and a 3-letter input are enough: a replacement that ends the word leaves an empty second part, and Lucene looks that empty part up.
- A Hunspell dictionary can allow compounds: words marked with the COMPOUNDFLAG (here
C) may be joined, and each part needs at least COMPOUNDMIN letters (default 3). To check a word, Lucene tries every break position and looks up both parts. CHECKCOMPOUNDPATTERN endchars begincharsforbids compounds whose first part ends with endchars and whose second part begins with beginchars. An optional third field, the replacement, allows a simplified spelling instead: witho b z,foo+barmay be writtenfozar.- To check a simplified form, Lucene writes the replacement back as endchars + beginchars (
fozarbecomesfoobar), puts the break right after endchars and checks both parts as usual.
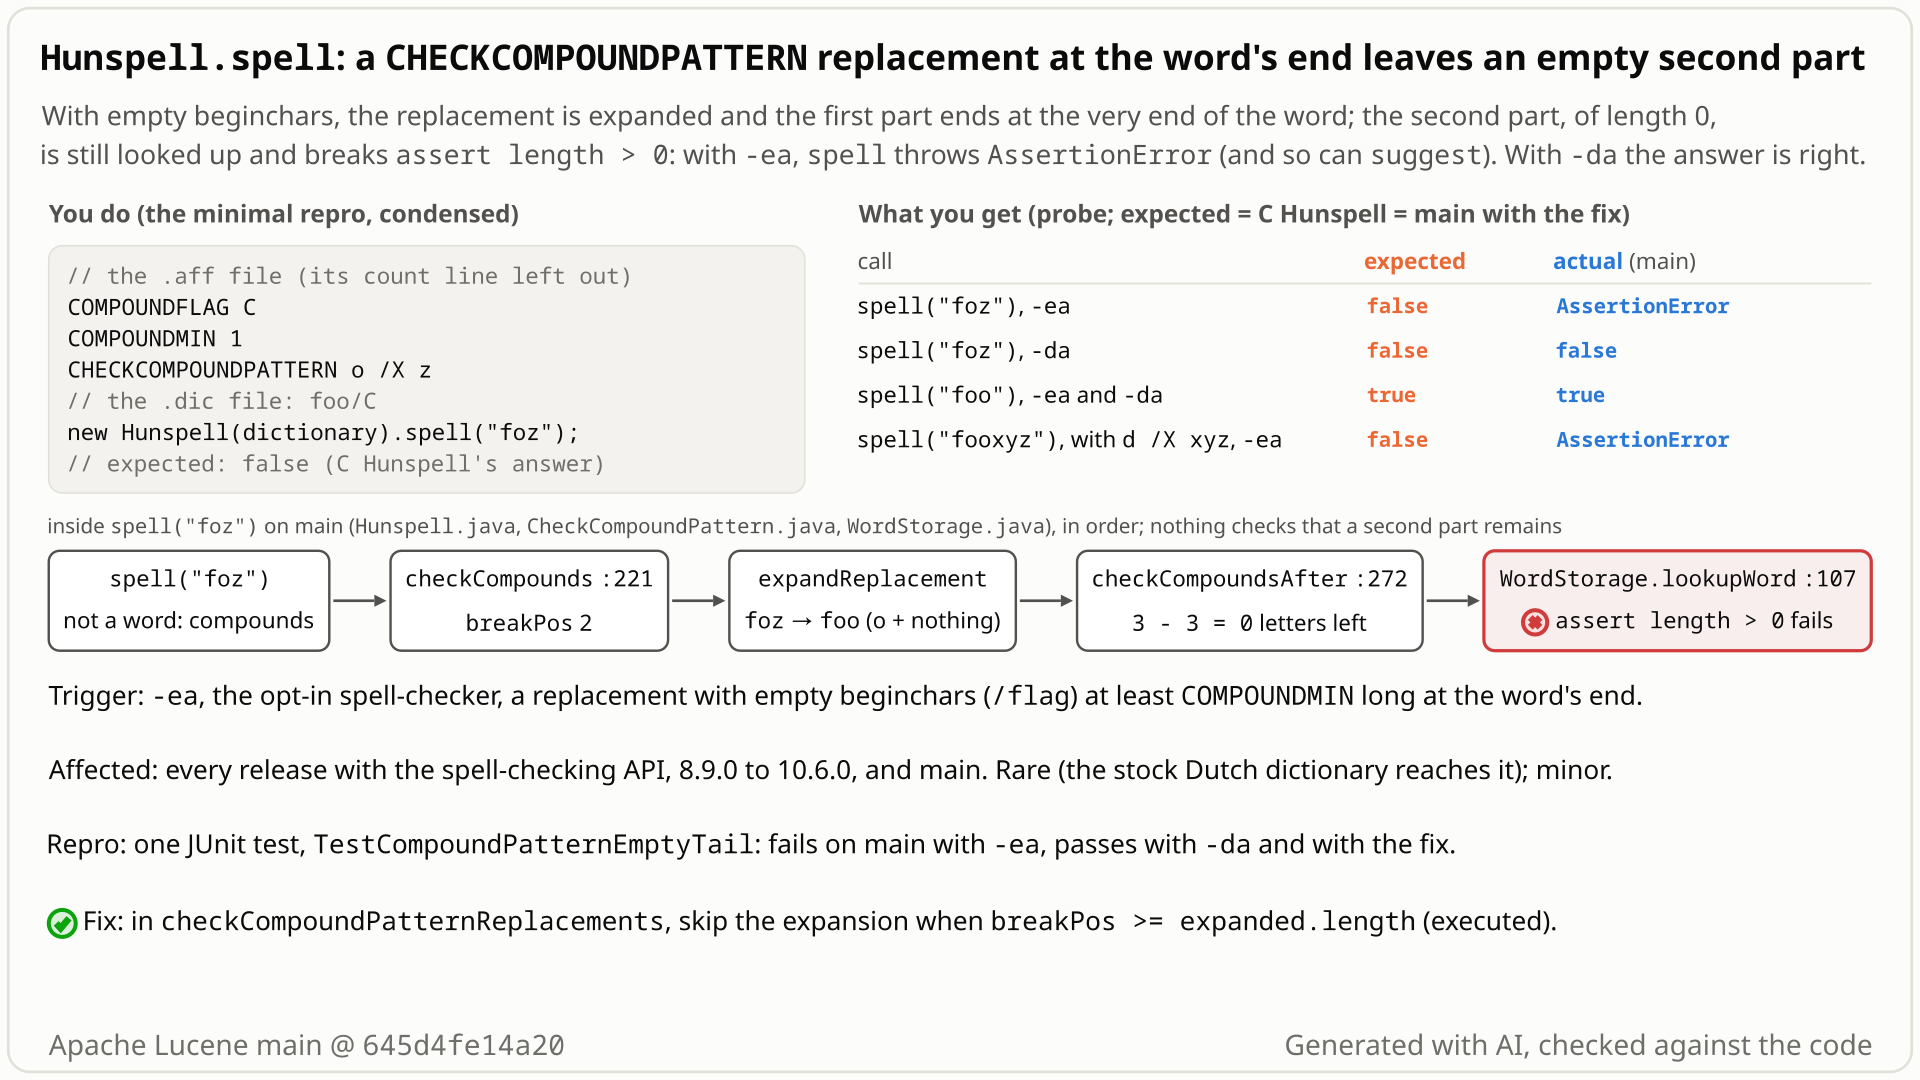
foz: the final z is turned back into o, giving foo; the break falls after letter 3 of 3, so the second part is empty and its lookup trips assert length > 0. Select the still to open it at full size. Generated with AI, checked against the code.- Give the rule empty beginchars:
CHECKCOMPOUNDPATTERN o /X z(/Xmeans no letters, flag X, as hunspell(5) allows), so anothat ends the first part, followed by nothing, may be writtenz. AddCOMPOUNDFLAG C,COMPOUNDMIN 1and one word,foo/C, then callspell("foz"). - You expect
false:fozwould befooplus an empty second word. C Hunspell 1.7.2 answers false, and so does Lucene with assertions off. - With assertions on,
spellthrowsAssertionError. Lucene turns the finalzback intoo, getsfoo(3 letters), breaks after letter 3 and looks up the 0 letters left. The word lookup begins withassert length > 0. suggest()hits it too. Every release with the spell-checker, 8.9.0 to 10.6.0, and main are affected, but only runs with assertions on. No surveyed public dictionary uses such a replacement on purpose, but the stock Dutch dictionary has one by accident (a trailing# commentread as the replacement#):spell("huis#")throws too.
Applications that call the opt-in Hunspell spell-checker (spell, suggest) with assertions on (typically test runs) and a dictionary with a CHECKCOMPOUNDPATTERN replacement whose beginchars are empty. No surveyed public dictionary uses one on purpose, but the stock Dutch one has one by accident, so spell("huis#") throws. Analysis never runs this code. With assertions off, the repro gets C Hunspell's answer.
Mechanism, terms and numbers810 words
CHECKCOMPOUNDPATTERN endchars[/flag] beginchars[/flag] [replacement] (hunspell(5)) can carry a replacement, a simplified compound form in which the replacement letters stand for the boundary endchars|beginchars. When Lucene's Hunspell checks a compound it tries every break position, and at each one checkCompoundPatternReplacements (Hunspell.java:249-267) rewrites a matching replacement into endchars + beginchars (CheckCompoundPattern.java:94-103) and puts the break right after endchars (Hunspell.java:255). It never checks that anything is left after the break. With empty beginchars (written /X) and a replacement at the end of the word nothing is, so checkCompoundsAfter looks up a second part of length 0 (:272-275) and breaks assert length > 0 in WordStorage.lookupWord (WordStorage.java:106-107). With dictionary foo/C, COMPOUNDFLAG C, COMPOUNDMIN 1 and CHECKCOMPOUNDPATTERN o /X z, spell("foz") throws AssertionError with assertions on; with them off the empty lookup finds nothing and the answer is the correct false, which C Hunspell 1.7.2 also gives. suggest() goes through the same code. The stock LibreOffice Dutch dictionary reaches it too: a trailing # comment on a pattern with empty beginchars is parsed as the replacement #, so spell("huis#") throws with assertions on (with them off the answers match C Hunspell 1.7.2). The missing check came with CHECKCOMPOUNDPATTERN support (LUCENE-9717, 2021) and the assertion with LUCENE-9825 (2021); all 42 releases from 8.9.0 to 10.6.0 and main fail with assertions on. A one-line guard fixes it.
- endchars / beginchars: the letters a CHECKCOMPOUNDPATTERN rule expects at the end of the first part and the start of the second. Each may carry a flag after
/;/Xalone means no letters, flagX. A flagless empty field cannot be written: the parser splits the line on whitespace (CheckCompoundPattern.java:32), soo zwould makezthe beginchars. - Replacement: the optional fourth field (
CheckCompoundPattern.java:45), the simplified spelling of the boundary. hunspell(5): "The optional replacement parameter allows simplified compound form."
checkCompounds(CharsRef, ...)(Hunspell.java:213-247) triesbreakPosfrom COMPOUNDMIN up toword.length - COMPOUNDMIN(:220-221), so on the regular path both parts have at least COMPOUNDMIN letters. At every position it also callscheckCompoundPatternReplacements(:241).checkCompoundPatternReplacements(:249-267) callsexpandReplacement(word, pos)(:252), which, if the replacement matches atpos, returns the word with the replacement rewritten asendChars + beginChars(CheckCompoundPattern.java:94-103). The break is set topos + pattern.endLength()(Hunspell.java:255), the first part is looked up (:256-257) and, if found,checkCompoundsAfterchecks the rest (:259-260).- At the first boundary (the call on the whole word, offset 0, as in the repro) the second part has
|beginChars|letters plus whatever followed the replacement, so it is empty exactly when beginchars are empty and the replacement ends the word. Nothing checks for that. (At later boundaries of a multi-part compound, stockexpandReplacementreturns the whole word with offset 0, the sibling bug LFV-377, so the earlier parts count as the remainder and the empty lookup does not happen there.) checkCompoundsAfter(:269-286) setsremainingLength = word.length - breakPos(:272), here 0, and callsfindStemwith it (:274-275):Stemmer.doStem(Stemmer.java:227-229),Dictionary.lookupWord(Dictionary.java:283-285), thenWordStorage.lookupWord, whose first line isassert length > 0;(WordStorage.java:106-107).- With assertions off the zero-length lookup finds no entry, the compound attempt fails and
spellreturnsfalse. The readword[offset + length - 1](WordStorage.java:118) stays in bounds because the break offset is at least 1 (COMPOUNDMIN is at least 1,Dictionary.java:438).
foz has 3 letters and COMPOUNDMIN is 1, so the loop tries breaks 1 and 2 (limit 3 - 1 + 1 = 3). At 1: f is no word and z does not start at position 1. At 2: fo is no word; then z matches at position 2, the expanded word is fo + o + (nothing) = foo, the break is 2 + 1 = 3, foo (flag C) is accepted as the first part, and the second part has 3 - 3 = 0 letters.
COMPOUNDMIN. A replacement starts at a break position, at most word.length - COMPOUNDMIN, so one that ends the word has at least COMPOUNDMIN letters. With the default 3 the trigger needs a 3-letter replacement: CHECKCOMPOUNDPATTERN d /X xyz with food/C and fooxyz fires it, while o /X z does not.
suggest(). Suggester checks candidates with a Hunspell whose findStem it overrides (Suggester.java:198-208), so the same path runs: suggest("fooxyz") and suggest("fozz") throw the same AssertionError with assertions on; with them off suggest("fozz") returns [foo].
Not reached by analysis. Stemmer and HunspellStemFilter, used inside analyzers, contain no compound-pattern checks; checkCompoundPatternReplacements and checkCompoundsAfter exist only in Hunspell.java.
Exposure and likelihood461 words
- Who is hit. Code that calls
Hunspell.spellorHunspell.suggest(modulelucene/analysis/common) and runs with assertions enabled and loads a dictionary with a CHECKCOMPOUNDPATTERN replacement whose beginchars are empty (on purpose, or by accident as in the Dutch dictionaries below) and checks a word that ends with that replacement (at least COMPOUNDMIN letters long). Assertions are typically on in test runs; Lucene's own build enables them for about 75% of test seeds. - What happens. A deterministic
AssertionError(anError, not anException) out ofspellorsuggestinstead of an answer. With assertions off the repro, and the Dutch words below, get the same answers as C Hunspell 1.7.2 (the FULLSTRIP side case below is the exception). - Default vs opt-in. An opt-in API whose behaviour depends on the dictionary; assertions are off by default in the JVM. Stemming and analysis do not reach this code. No scale is needed: a 3-letter word.
- How likely. Rare. No surveyed dictionary uses the replacement field on purpose, but two of the 191 public
.afffiles surveyed by the hunt (the LibreOffice dictionaries and wooorm/dictionaries at the commits Lucene's regression build pins,lucene/analysis/common/build.gradle:146-153), the two Dutch ones, end some CHECKCOMPOUNDPATTERN lines with a# comment(36 lines in LibreOfficenl_NL, 42 in wooormnl). Lucene's parser takes the fourth whitespace-separated field as the replacement (CheckCompoundPattern.java:32,:45), as C Hunspell 1.7.2 does, so#becomes the replacement. One such line innl_NL(line 659, and four in wooormnl) has empty beginchars:CHECKCOMPOUNDPATTERN /Xf /Xf # moeder-dochter etc, andnl_NL'sCOMPOUNDMIN 0is raised to 1 (Dictionary.java:438). With the stocknl_NLdictionary,spell("huis#"),"boek#","water#"and"moeder#"(a compound-begin word followed by#) throw the sameAssertionErrorwith assertions on (main;huis#andboek#also on 10.6.0). With them off Lucene answers huis# false, boek# true, water# true, moeder# false, exactly as C Hunspell 1.7.2 does; with fix A nothing throws and the answers stay the same. It still needs a#at the end of the checked word (#is not in the DutchWORDCHARS) and assertions on. Lucene's replacement fixtures all have non-empty beginchars, and neither Lucene's nor C Hunspell 1.7.2's fixtures combine a replacement with empty beginchars. - A side case, not claimed. With FULLSTRIP and a suffix that strips a whole root (for example
SFX S y 0 .withy/CSX), the empty second part is read as that root minus the suffix, and Lucene with assertions off returnstrueforfoz(main; a similar variant also on 10.5.2). C Hunspell 1.7.2 says false there but 1.3.2 says true, so no wrong production answer is claimed; with the guard Lucene answers false, like 1.7.2.
One JUnit test, one method: a four-line affix file, one word and spell("foz"). Public API only, deterministic, single thread, about 2 s. It fails with assertions on and passes with them off, which is the bug.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.hunspell;

import java.io.ByteArrayInputStream;
import java.nio.charset.StandardCharsets;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestCompoundPatternEmptyTail extends LuceneTestCase {

  public void testReplacementAtWordEnd() throws Exception {
    String aff =
        "COMPOUNDFLAG C\nCOMPOUNDMIN 1\nCHECKCOMPOUNDPATTERN 1\nCHECKCOMPOUNDPATTERN o /X z\n";
    String dic = "1\nfoo/C\n";
    Dictionary dictionary =
        new Dictionary(
            new ByteBuffersDirectory(),
            "dict",
            new ByteArrayInputStream(aff.getBytes(StandardCharsets.UTF_8)),
            new ByteArrayInputStream(dic.getBytes(StandardCharsets.UTF_8)));
    // expected false (C Hunspell's answer); actual (-ea): AssertionError in WordStorage.lookupWord
    assertFalse(new Hunspell(dictionary).spell("foz"));
  }
}
cp TestCompoundPatternEmptyTail.java $LUCENE/lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/
cd $LUCENE && ./gradlew :lucene:analysis:common:test --tests org.apache.lucene.analysis.hunspell.TestCompoundPatternEmptyTail -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off: -Ptests.asserts=false instead (the test then passes: spell("foz") is false)
- Expected
spell("foz")returnsfalse, as C Hunspell 1.7.2 and Lucene with assertions off answer.- Observed
java.lang.AssertionErroratWordStorage.lookupWord(WordStorage.java:107), reached fromcheckCompoundPatternReplacements, with assertions on.
More files, environment, full output292 words
The test sits in org.apache.lucene.analysis.hunspell, next to TestSpellChecking, by Lucene test convention; it uses only public API: Dictionary(Directory, String, InputStream, InputStream), Hunspell(Dictionary), Hunspell.spell(String) and ByteBuffersDirectory. It calls no random(), so the outcome does not depend on the seed.
Not shown by this one test, executed by the verifiers from the same root cause: suggest(), the default-COMPOUNDMIN form (CHECKCOMPOUNDPATTERN d /X xyz, fooxyz), and the stock Dutch dictionary case (spell("huis#"), see Who is affected), which needs a dictionary download.
As the regression test: the same test unchanged, for example as a new method of TestSpellChecking. It could also be written as a fixture set for doTest (.aff, .dic, .wrong), the form all 53 test methods of TestSpellChecking use. It fails on stock main with assertions on and passes with fix A with assertions on and off (gradle); :lucene:analysis:common:check -x test passes with fix A and this test in place.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); this test also fails on 10.5.2 and 10.6.0; every release from 8.9.0 to 10.6.0 is affected with assertions on |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
cp TestCompoundPatternEmptyTail.java $LUCENE/lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/
cd $LUCENE && ./gradlew :lucene:analysis:common:test --tests org.apache.lucene.analysis.hunspell.TestCompoundPatternEmptyTail -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off: -Ptests.asserts=false instead (the test then passes: spell("foz") is false)
# gradle, main 645d4fe14a20, -Ptests.seed=DEADBEEF -Ptests.asserts=true (with =false the test passes; the same on 10.5.2 and 10.6.0)
TestCompoundPatternEmptyTail > testReplacementAtWordEnd FAILED
    java.lang.AssertionError
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:1CA89FF644B60EBF]:0)
        at org.apache.lucene.analysis.hunspell.WordStorage.lookupWord(WordStorage.java:107)
        at org.apache.lucene.analysis.hunspell.Dictionary.lookupWord(Dictionary.java:284)
        at org.apache.lucene.analysis.hunspell.Stemmer.doStem(Stemmer.java:229)
        at org.apache.lucene.analysis.hunspell.Hunspell.findStem(Hunspell.java:169)
        at org.apache.lucene.analysis.hunspell.Hunspell.checkCompoundsAfter(Hunspell.java:275)
        at org.apache.lucene.analysis.hunspell.Hunspell.checkCompoundPatternReplacements(Hunspell.java:260)
        at org.apache.lucene.analysis.hunspell.Hunspell.checkCompounds(Hunspell.java:241)
        at org.apache.lucene.analysis.hunspell.Hunspell.checkCompounds(Hunspell.java:157)
        at org.apache.lucene.analysis.hunspell.Hunspell.spellClean(Hunspell.java:100)
        at org.apache.lucene.analysis.hunspell.Hunspell.spell(Hunspell.java:86)
        at org.apache.lucene.analysis.hunspell.TestCompoundPatternEmptyTail.testReplacementAtWordEnd(TestCompoundPatternEmptyTail.java:37)

:lucene:analysis:common:test (FAILURE): 1 test, 1  failure

# C Hunspell 1.7.2 on the same dictionary: foz 0 (rejected), foo 1 (accepted)assert length > 0is Lucene's own internal rule, added with guards that keep empty words out of the lookup; Lucene's own compound code breaks it.- Upstream fixed the same assertion, reached from another caller, as a bug (LUCENE-9833, #10872).
- The input is legal: hunspell(5) shows empty beginchars written
/flag, Lucene parses the rule, and C Hunspell answers false.
The full argument290 words
- The contract is a boolean.
spellpromises "whether the given word's spelling is considered correct according to Hunspell rules" (Hunspell.java:71-73) and documents no exception. - The precondition is internal. LUCENE-9825 (
4842e0c9cab, 2021) addedassert length > 0toWordStorage.lookupWordtogether with zero-length guards in other callers:if (length == 0) returninStemmer.stem(today inStemmer.analyze, whichstemcalls,Stemmer.java:90-92) andif (word.length() == 1) return;inModifyingSuggester.tryRemovingChar(todayModifyingSuggester.java:296-297). In that PR's review the author wrote "We don't accept empty words for lookup anymore". - A related precedent. LUCENE-9833 (#10872, "Hunspell: AssertionError in WordStorage.lookupWord", PR #13; released in 8.9.0 and 9.0.0) is the same assertion reached from
ModifyingSuggester.tryRep, where a REP candidate with a leading space split into an empty word part. Maintainers guarded that caller (the candidate is trimmed) and kept the assertion. That is an analogy, not proof of what this rule combination should do. The repro fails on every release that contains that fix. - Every other split keeps both parts non-empty (
Hunspell.java:220-221); only the replacement path can make an empty part. - The input is legal. hunspell(5) gives the syntax
CHECKCOMPOUNDPATTERN endchars[/flag] beginchars[/flag] [replacement]and the exampleCHECKCOMPOUNDPATTERN 0/x /y(empty beginchars with a flag). Lucene's parser accepts the line (Dictionary.java:458-464), Lucene's own fixtureonlyincompound2.affuses empty beginchars (0/B /A), and the class javadoc's list of unsupported features (Hunspell.java:35-44) does not mention it. C Hunspell 1.7.2 parses the test's dictionary and answers false; 1.3.2 also answers false on the hunt's two-root variant (foo/C,bar/C). - Never tested. No Lucene fixture combines a replacement with empty beginchars (
checkcompoundpattern2.aff,checkcompoundpattern3.aff), nor, per the devil's advocate, do Hunspell 1.7.2's own fixtures.
The devil's-advocate check206 words
The strongest case for "intended" (the cross-model reviews in the hunt rated it weak, the 2026-11-01 re-review moderate; the cross-model fact check called it strong as a "noise / won't-fix" case and moderate as deliberate design): assertions are debug checks, and production gets C Hunspell's answer for the repro and the Dutch words checked; a 2026-10-29 audit classed it as assertion-only; no dictionary uses the combination on purpose, and it is untested in both Lucene and C Hunspell; the dictionary is trusted configuration; the Hunspell javadoc does not promise full compatibility with C Hunspell. The FULLSTRIP side case gives a different assertions-off answer, but the two C Hunspell versions disagree there.
Why it fails as an "intended" argument: nothing documents the combination as unsupported, and the broken invariant is internal to Lucene; a stock dictionary that Lucene's own regression build pins reaches it with an ordinary word plus #; maintainers guarded the same assertion at another caller rather than accept it; and the guard is one comparison that only drops candidates whose second part would be empty (the hunspell tests pass; in the FULLSTRIP side case it turns true into C Hunspell 1.7.2's false). Verdict: not intended; a missing bound check of low impact.
Recommended A. Skip a replacement that leaves no second part
In checkCompoundPatternReplacements, skip a replacement whose break falls at the end of the expanded word: if (breakPos >= expanded.length) continue;. Validated: the repro passes with assertions on and off, and the hunspell tests and the module's static checks pass.
         int breakPos = pos + pattern.endLength();
+        if (breakPos >= expanded.length) {
+          continue; // the replacement ends the word: no second part
+        }
         Root<CharsRef> stem =
             findStem(expanded.chars, expanded.offset, breakPos, originalCase, context);
All options and trade-offs4 options · 491 words
Fix A was run through gradle in a scratch worktree of 645d4fe14a20; B, C and D are alternatives, not tested.
One guard in checkCompoundPatternReplacements (Hunspell.java:255), right after the break is computed.
         int breakPos = pos + pattern.endLength();
+        if (breakPos >= expanded.length) {
+          continue; // the replacement ends the word: no second part
+        }
         Root<CharsRef> stem =
             findStem(expanded.chars, expanded.offset, breakPos, originalCase, context);
Trade-offs
- It only drops candidates whose second part would be empty. In the recorded FULLSTRIP side case that changes Lucene's assertions-off answer from
truetofalse, like C Hunspell 1.7.2 (1.3.2 saystrue); with the stock Dutch dictionary it keeps the answers Lucene and C Hunspell 1.7.2 already give. - Sibling bug LFV-377 (
expandReplacementat later compound boundaries) is a separate fix; with its fix alone this failure remains, with both the tests pass. On stock code the guard only matters at the first boundary: at later ones the expanded word still carries the earlier parts, so its second part is never empty and the guard compares in a different frame. After LFV-377's fix the expanded word is relative to the current part, and the guard compares in the same frame.
What the checks validated
- Gradle in a scratch worktree of
645d4fe14a20(2026-11-01): the repro fails on stock main with-Ptests.asserts=trueand passes with=false; with A it passes with both. - With A and the repro in place:
TestSpellChecking53 tests, 0 failures; the wholeorg.apache.lucene.analysis.hunspelltest package with assertions on, 47 classes, 159 tests, 0 failures, 13 skipped (TestPerformance,TestAllDictionariesandTestHunspellRepositoryTestCasesneed external dictionary checkouts;TestAllDictionaries.testMaxPrologueNeededis also@Ignored);:lucene:analysis:common:check -x test(google-java-format, ecj lint, forbidden APIs) passes. - Earlier, the same guard: the finder's one-test class (two control assertions plus
foz) and the 146 tests of Lucene's hunspell test classes ona9779ef3c193; an independent 5-test class 5/5; the cross-model reviewer's own tests; the devil's advocate's probes; the guard shadowed onto the645d4fe14a20jars.
Use expanded.length - breakPos < dictionary.compoundMin as the skip condition, like the regular loop.
Trade-offs
Changes which simplified forms are accepted when the second part is short; hunspell(5) itself notes that COMPOUNDMIN "doesn't work correctly with the compound word alternation", so the right bound is unclear. Suggested by the devil's advocate; not tested; needs C Hunspell comparisons.
if (remainingLength == 0) return false; in checkCompoundsAfter, right after remainingLength is computed (Hunspell.java:272).
Trade-offs
Protects every caller that builds an empty tail, but hides where it came from. Not tested.
Replace the assertion with an early return null.
Trade-offs
Not recommended: it removes the check LUCENE-9825 added on purpose and LUCENE-9833 kept, so other callers' mistakes would go unnoticed.
Search indexing and query analysis are not affected, because HunspellStemFilter never runs this code; only applications that expose the spell-checker with such a dictionary (the stock Dutch one included) and run with assertions on would see the error.
Non-formal: differential testing of Lucene's spell-checker against C Hunspell 1.7.2 over grammar-generated compounding dictionaries. Lucene threw AssertionError on 24 generated dictionaries; one was minimised by script and by hand to the one-test repro.
The method in full155 words
Method: non-formal (cross-implementation differential testing). A hunt unit generated small synthetic compounding dictionaries from a grammar (CHECKCOMPOUNDPATTERN with and without replacements, empty endchars or beginchars written with flags), spell-checked every word of up to 6 letters over a 3-letter alphabet plus 2- and 3-part concatenations with both Lucene and C Hunspell 1.7.2, and compared the answers. Lucene ran with the fix sketches of two already-known hunspell bugs applied, so that their differences would not drown new ones; the failure then reproduced on the stock jar.
Lucene threw AssertionError on one generated dictionary and on 23 more from further seeds. A minimiser and hand reduction turned one into a public-API JUnit test. It was then reviewed by a reviewer from another model family (OpenAI GPT-5.6) in the hunt and again on 2026-11-01, reproduced independently, argued against by an intended-behaviour devil's advocate, judged, traced through history, audited and cut to the one-test repro, re-verified on 645d4fe14a20.
No prior report found in GitHub issues, PRs and commits (including all 409 open PRs), the JIRA archive, the Lucene lists, downstream projects, other Hunspell implementations or the web (2026-10-27, refreshed 2026-11-01). Closest: LUCENE-9833 (#10872), the same assertion from another caller, fixed in 8.9.0 and 9.0.0. Not fixed upstream.
Searches5 searches
Closest items, none a report of this bug: #10872 (LUCENE-9833, the same assertion from ModifyingSuggester.tryRep, fixed at that caller; released in 8.9.0 and 9.0.0); apache/lucene-solr#2459 (LUCENE-9825, which added the assertion and guards in other callers); #10756 / apache/lucene-solr#2280 (LUCENE-9717, the feature; no discussion of an empty remainder); #10814 (LUCENE-9775, the last change to expandReplacement, origin of the sibling LFV-377); #16919 (merged 2026-10-28; its only hunspell change is in AffixCondition.java); #16422 (open, Dictionary.java only). In other implementations, helix-editor/spellbook#12 is a boundary-index crash in CHECKCOMPOUNDPATTERN in a Rust port, with a different trigger. Limits: keyword search cannot exclude a report worded without these terms; GitHub search does not index PR review comments (the relevant reviews were read directly); private channels are not visible. The stock Dutch dictionary trigger was found after these searches; no search targeted it.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene and apache/lucene-solr issues, PRs and commits; Elasticsearch, OpenSearch, Solr, Lucene.NET | 2026-10-27, 2026-11-01 | scripted prior-report searches (16 GitHub, 3 commit and 2 downstream queries per run) and 79 manual GitHub GraphQL searches: class, method and file names, symptoms, directive names, LUCENE-9717/9825/9833 | no report; LUCENE-9833 (#10872) is the same assertion from another caller |
| Open PRs | 2026-11-01 | touched files of all 409 open apache/lucene PRs, plus full file lists of the 3 PRs with more than 100 files | only #16422 touches the hunspell package (Dictionary.java) |
| Mailing lists, JIRA archive, web | 2026-10-27, 2026-11-01 | dev@, java-user@, issues@ and commits@ (20 queries per run plus 24 direct queries); 4 JIRA-archive queries per run; 12 web queries | only unrelated Hunspell threads |
| Other Hunspell implementations | 2026-11-01 | native Hunspell, nuspell, spylls and spellbook issue trackers | spellbook#12, a different boundary crash in a Rust port |
| Upstream code | 2026-11-01 | commits to the hunspell package since 2026-10-20 on main and branch_10_6; current file contents | not fixed: the same lines on main f815e679bf6c and branch_10_6 |
The missing check came with CHECKCOMPOUNDPATTERN support (LUCENE-9717, d0ae2bd2b9c, 2021-02-03) and was silent until LUCENE-9825 (4842e0c9cab, 2021-03-05) added the assertion. Every release with the spell-checking API fails with assertions on: 42 of 42 from 8.9.0 to 10.6.0, and main.
Versions tested8 rows
Root cause d0ae2bd2b9c "LUCENE-9717: Hunspell: support CHECKCOMPOUNDPATTERN (#2280)" (Peter Gromov, 2021-02-03; issue #10756) added checkCompoundPatternReplacements with breakPos = pos + pattern.endLength() and remainingLength = word.length - breakPos in checkCompoundsAfter; git blame -w -M -C -C still attributes both lines to it. The lookup of that time was an FST that found nothing for an empty word; with one probe line assert length > 0 added, that commit reaches the zero-length lookup and its parent does not.
Made visible by 4842e0c9cab "LUCENE-9825: Hunspell: reverse the "words" trie for faster word lookup/suggestions" (same author, 2021-03-05), which added WordStorage.lookupWord with assert length > 0; merged to main as f5012a4cdaf (2021-03-10). Both reached branch_8x together in c6b964a1157 (LUCENE-9687, 2021-05-28), first released in 8.9.0. Not a regression of a released version.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | minimal repro fails with assertions on and passes with them off (gradle and standalone); passes with fix A |
| 10.5.2, 10.6.0 | affected | minimal repro fails with assertions on, passes with them off (release jars, re-run 2026-11-01) |
| 8.9.0 | first affected | fails with assertions on (WordStorage.lookupWord:96 through checkCompoundPatternReplacements), returns false with them off |
| 8.10.0-8.11.4, 9.0.0-9.12.3, 10.0.0-10.5.1 | affected | fail with assertions on (all 42 releases from 8.9.0 to 10.6.0 executed); 9.0.0 returns false with them off |
| 8.8.0, 8.8.1, 8.8.2 | no API | no Hunspell / SpellChecker class |
d0ae2bd2b9c (LUCENE-9717) vs parent 6509a3003cf | silent | both pass; with a length probe the commit reaches the zero-length lookup, its parent does not |
4842e0c9cab (LUCENE-9825) vs parent 99a4bbf3a0a | bisect | the commit fails with assertions on; its parent passes |
upstream main f815e679bf6c, branch_10_6 | read | the same lines (2026-11-01) |
Confirmed with high confidence: the finder, an independent reproducer, reviews by a reviewer from another model family (OpenAI GPT-5.6), an intended-behaviour devil's advocate, an adjudication, a history step, a re-verification and fact checks on 645d4fe14a20 all found it real; the reviews in the hunt rated the intended argument weak, the 2026-11-01 re-review moderate.
Checks and verdicts368 words
Everyone agrees on the root cause, the one-line guard and the low impact: for the repro and the Dutch words checked, a failure only with assertions on, with C Hunspell's answer when they are off.
| Check | Verdict | What it found |
|---|---|---|
| finder | reproduced | Differential testing against C Hunspell 1.7.2; the JUnit fails with assertions on on main, 10.5.2 and 9.12.3, passes with them off and with the guard. |
| cross-model review, refute lens (OpenAI GPT-5.6, 2026-10-27) | real, high | Own test fails with assertions on and passes with them off; root cause agreed; intended argument weak. |
| independent reproducer | real | Own 5-test class: 3 fail with assertions on (foz, the default-COMPOUNDMIN fooxyz, suggest("fooxyz")), 2 controls pass, all pass with them off; C Hunspell 1.3.2 and 1.7.2 answer false; the LFV-377 fix alone leaves it. |
| cross-model review, intended lens (OpenAI GPT-5.6, 2026-10-27) | real, high | Own tests fail with assertions on and pass with them off and with the guard; intended argument weak. |
| intended-behaviour devil's advocate | real, high | Found the LUCENE-9825 guards and the LUCENE-9833 precedent, the COMPOUNDMIN and /flag preconditions, suggest("fozz") and the FULLSTRIP side case. |
| adjudication | confirmed, high | Re-ran the finder's repro (fails with assertions on, passes with them off) and the independent test (3 of 5 fail); impact minor. |
| cross-model re-review, refute lens (OpenAI GPT-5.6, 2026-11-01) | real, high | Own test fails with assertions on and passes with them off (its test re-run on 645d4fe14a20); intended argument moderate: "normal -da deployments return the correct false result, making this low-priority assertion noise rather than a production correctness failure". |
| history and re-verification | still reproduces | 42 of 42 releases fail with assertions on; on 2026-11-01 the one-test repro fails on 645d4fe14a20, 10.5.2 and 10.6.0 with assertions on and passes with them off; fix A validated with gradle. |
| fact checks (2026-11-01) | real; wider trigger | An independent fact check re-ran the repro (standalone and gradle; main, 10.5.2, 10.6.0) and fix A, and found that the stock Dutch dictionary reaches the assertion (spell("huis#")); a cross-model fact check (OpenAI GPT-5.6) found the bug real as described and asked for narrower wording. Their corrections are applied. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 405 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,305 words
- Registry title
- Hunspell spell() and suggest() throw AssertionError under -ea when a word ends with a CHECKCOMPOUNDPATTERN replacement whose beginchars are empty, because the compound check looks up a zero-length second part
- Area
- analysis / hunspell (Hunspell.spell and suggest compound checking, CHECKCOMPOUNDPATTERN replacements)
- Priority
- Low, rank 1179: This released AssertionError fires only under -ea and only for a CHECKCOMPOUNDPATTERN replacement with empty beginchars that only the stock Dutch dictionaries carry, by accident.
- Impact class
- minor
- Impact note
- Only applications that call the opt-in Hunspell spell-checker (Hunspell.spell, and suggest, which re-checks candidates the same way) with JVM assertions enabled (-ea, typically a test suite) and a dictionary that combines a CHECKCOMPOUNDPATTERN replacement with empty beginchars (written '/flag'; no surveyed public dictionary uses the replacement field on purpose, but the two Dutch ones, LibreOffice nl_NL and wooorm nl, end some CHECKCOMPOUNDPATTERN lines with a '# comment' that Lucene parses as the replacement '#', and nl_NL line 659 has empty beginchars, so with the stock nl_NL dictionary spell("huis#") throws the same AssertionError under -ea) are hit, for words that end with a replacement at least COMPOUNDMIN (default 3) long: the call throws java.lang.AssertionError instead of answering; with -da (production) the repro dictionaries get the correct answer false, stemming and analysis (HunspellStemFilter) never reach this code, no scale is needed, and every release from 8.9.0 to 10.6.0 has it (all executed).
- Summary
- You load a Hunspell dictionary with a compound rule such as 'CHECKCOMPOUNDPATTERN o /X z' (a simplified compound form whose second part may begin with anything: hunspell(5) allows empty beginchars with a flag and an optional replacement) and call Hunspell.spell("foz"), and expect true or false; C Hunspell 1.3.2 and 1.7.2 both say false. Instead, with assertions enabled, spell() and suggest() throw java.lang.AssertionError from WordStorage.lookupWord ('assert length > 0'). The cause: checkCompoundPatternReplacements expands the final 'z' to 'o' plus empty beginchars and puts the break right after 'foo', but never checks that a second part remains, so checkCompoundsAfter looks up a second part of length 0; with -da that lookup finds nothing and spell() returns false for the repro.
- Introduced
- d0ae2bd2b9c9, LUCENE-9717 'Hunspell: support CHECKCOMPOUNDPATTERN' (apache/lucene-solr#2280, by donnerpeter; issue apache/lucene#10756), the root cause: it added checkCompoundPatternReplacements ('int breakPos = pos + pattern.endLength()') and 'remainingLength = word.length - breakPos' in checkCompoundsAfter with no check that a second part remains [read: git blame -w -M -C -C still attributes both lines to it] [exec: the hunspell sources of that commit, with one added 'assert length > 0' probe line in Dictionary.lookupWord, reach the zero-length lookup; its parent 6509a3003cf with the same probe does not]. Silent at that commit, because the FST lookup returns no entry for an empty word. Made visible as an AssertionError by LUCENE-9825 (4842e0c9cab, 2021-03-05, by donnerpeter, apache/lucene-solr#2459, issue apache/lucene#10864), which added WordStorage.lookupWord with 'assert length > 0' and reached main through the merge f5012a4cdaf (apache/lucene#2, 2021-03-10) [exec: f5012a4cdaf fails, 44833dc5751 just before it passes]. Reached 8.x through the branch_8x backport c6b964a1157 (apache/lucene-solr#2499, LUCENE-9687). Both steps predate every release, so it is not a regression of a released version (2021-02-03 (root cause, silent); 2021-03-10 (AssertionError visible on main); 2021-05-28 (8.x backport with both))
- First affected version
- 8.9.0 [exec] (the first release with the spell-checking API, through the 8.x backport; 8.8.2 has no Hunspell class [exec]); on the main line 9.0.0 [exec]
- Affected versions
- every release that has the spell-checking API: 8.9.0, 8.10.0, 8.10.1, 8.11.0 - 8.11.4, 9.0.0 - 9.12.3 and 10.0.0 - 10.6.0 (42 releases), all executed with -ea and all failing [exec], and main a9779ef3c193 and 645d4fe14a20 [exec]; with -da every executed run (8.9.0, 9.0.0, 10.5.2, 10.6.0, main) returns the correct false for the repro [exec]. Not affected: 8.8.2 and older (no spell-checking API) [exec 8.8.2]. Not fixed upstream: checkCompoundPatternReplacements is unchanged and lookupWord still asserts length > 0 on upstream main a95c754ee003, branch_10x and branch_10_6 (2026-10-27) [read]. All runs on Linux aarch64 with JDK 25
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal
- Upstream and prior reports
- none found (2026-10-27, read-only, 178 queries: three scripted prior-report searches over GitHub issues, PRs and commits, downstream repositories (Elasticsearch, OpenSearch, Solr, Lucene.NET), the dev@, java-user@, issues@ and commits@ lists, JIRA and the web; 45 manual GitHub GraphQL searches, including a listing of all 218 apache/lucene items that mention hunspell and the native Hunspell, nuspell and spylls projects; the touched files of all 410 open apache/lucene PRs; local git history; 16 hits judged, none the same bug; the independent reproduction's and the intended-behaviour check's searches agree). Closest items: #10872 (LUCENE-9833, PR #13, fixed in 9.0.0), the same AssertionError in WordStorage.lookupWord reached from another caller (ModifyingSuggester.tryRep with an empty REP candidate) and fixed at that caller only, a precedent and not this bug (the repro fails on every release that contains that fix); apache/lucene-solr#2459 (LUCENE-9825), which added the assert together with zero-length guards in Stemmer and ModifyingSuggester (the author's review note: 'We don't accept empty words for lookup anymore') but not in this caller; #10756 (LUCENE-9717, apache/lucene-solr#2280), the feature, with no review discussion and no fixture that combines a replacement with empty beginchars; #16422, the only open PR in the hunspell package apart from the branch_10x decommission #16911 (Dictionary.java only). Not fixed upstream. Update 2026-11-02: #16911 (open when searched) merged 2026-10-29 as 48cf3f515d6, which emptied branch_10x to a README tombstone (10.6 is the last 10.x minor; 10.x fixes go to branch_10_6); it fixes nothing here.
- Lucene commit tested
- main
645d4fe14a20(gradle: the minimal repro with-Ptests.asserts=trueand=false, stock and with fix A; with fix A,TestSpellChecking, the wholeorg.apache.lucene.analysis.hunspelltest package and:lucene:analysis:common:check -x test; standalone runs with assertions on and off, and fix A shadowed onto the main jars), the 10.5.2 and 10.6.0 release jars (SHA-1 checked; assertions on and off), and, by the hunt, its verifiers and the history step, maina9779ef3c193andea57360912ed, all 42 releases from 8.9.0 to 10.6.0 with assertions on, 8.8.0-8.8.2 (no spell-checking API), and the commits6509a3003cf,d0ae2bd2b9c,44833dc5751,99a4bbf3a0a,4842e0c9cabandf5012a4cdaf. References: C Hunspell 1.7.2 (re-run on the test's dictionary) and 1.3.2. Upstream mainf815e679bf6candbranch_10_691eaab4fb298have the same lines (read, 2026-11-01).
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Hunspell.java at a9779ef3c193: :71-74 spell javadoc ('@return whether the given word's spelling is considered correct according to Hunspell rules'), :213-247 checkCompounds (:220-221 the break loop keeps both parts at least compoundMin long, :241 the call into the replacement path), :249-267 checkCompoundPatternReplacements (:255 breakPos = pos + pattern.endLength(), no remainder check), :269-286 checkCompoundsAfter (:272 remainingLength = word.length - breakPos, :275 findStem)lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/CheckCompoundPattern.java at a9779ef3c193: :29-45 constructor (split on whitespace, beginChars empty when the field is '/flag', replacement = parts[3]), :94-103 expandReplacement (prefix + endChars + beginChars + rest, null without a replacement)lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/WordStorage.java at a9779ef3c193: :106-107 lookupWord 'assert length > 0'
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Hunspell.java:71-73, :150-161, :163-184, :213-247, :249-267, :269-286 (at 645d4fe14a20)lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/CheckCompoundPattern.java:29-46, :94-107 (at 645d4fe14a20)lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/WordStorage.java:106-118; lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Dictionary.java:283-285, :438 (at 645d4fe14a20)lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Stemmer.java:227-229; lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Suggester.java:198-208 (at 645d4fe14a20)lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/checkcompoundpattern2.aff:5, checkcompoundpattern2.good:2 (fozar) (at 645d4fe14a20)
- Who is affected
lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/checkcompoundpattern2.aff:5-6, checkcompoundpattern3.aff:5 (at 645d4fe14a20)build-tools/build-infra/src/main/java/org/apache/lucene/gradle/plugins/java/TestsAndRandomizationPlugin.java:240-248 (at 645d4fe14a20)
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Hunspell.java:35-44, :71-73, :220-221; lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Dictionary.java:458-464 (at 645d4fe14a20)lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Stemmer.java:90-92; lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/ModifyingSuggester.java:296-297 (at 645d4fe14a20)lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/onlyincompound2.aff:11-12, checkcompoundpattern2.aff, checkcompoundpattern3.aff (at 645d4fe14a20)
- TestCompoundPatternEmptyTail.java (JUnit, one test):
repro/LFV-713/src/org/apache/lucene/analysis/hunspell/TestCompoundPatternEmptyTail.java(39 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and the repro's input and output.
assets/LFV-713/bug.png(405 KB)