Nori stores a word's part of speech in a table with one slot per left context id, a number many words share. When two dictionary rows share an id but carry different tags, the builder only asserts that they agree, then overwrites the slot, so all words on that id get the tag of the row written last.
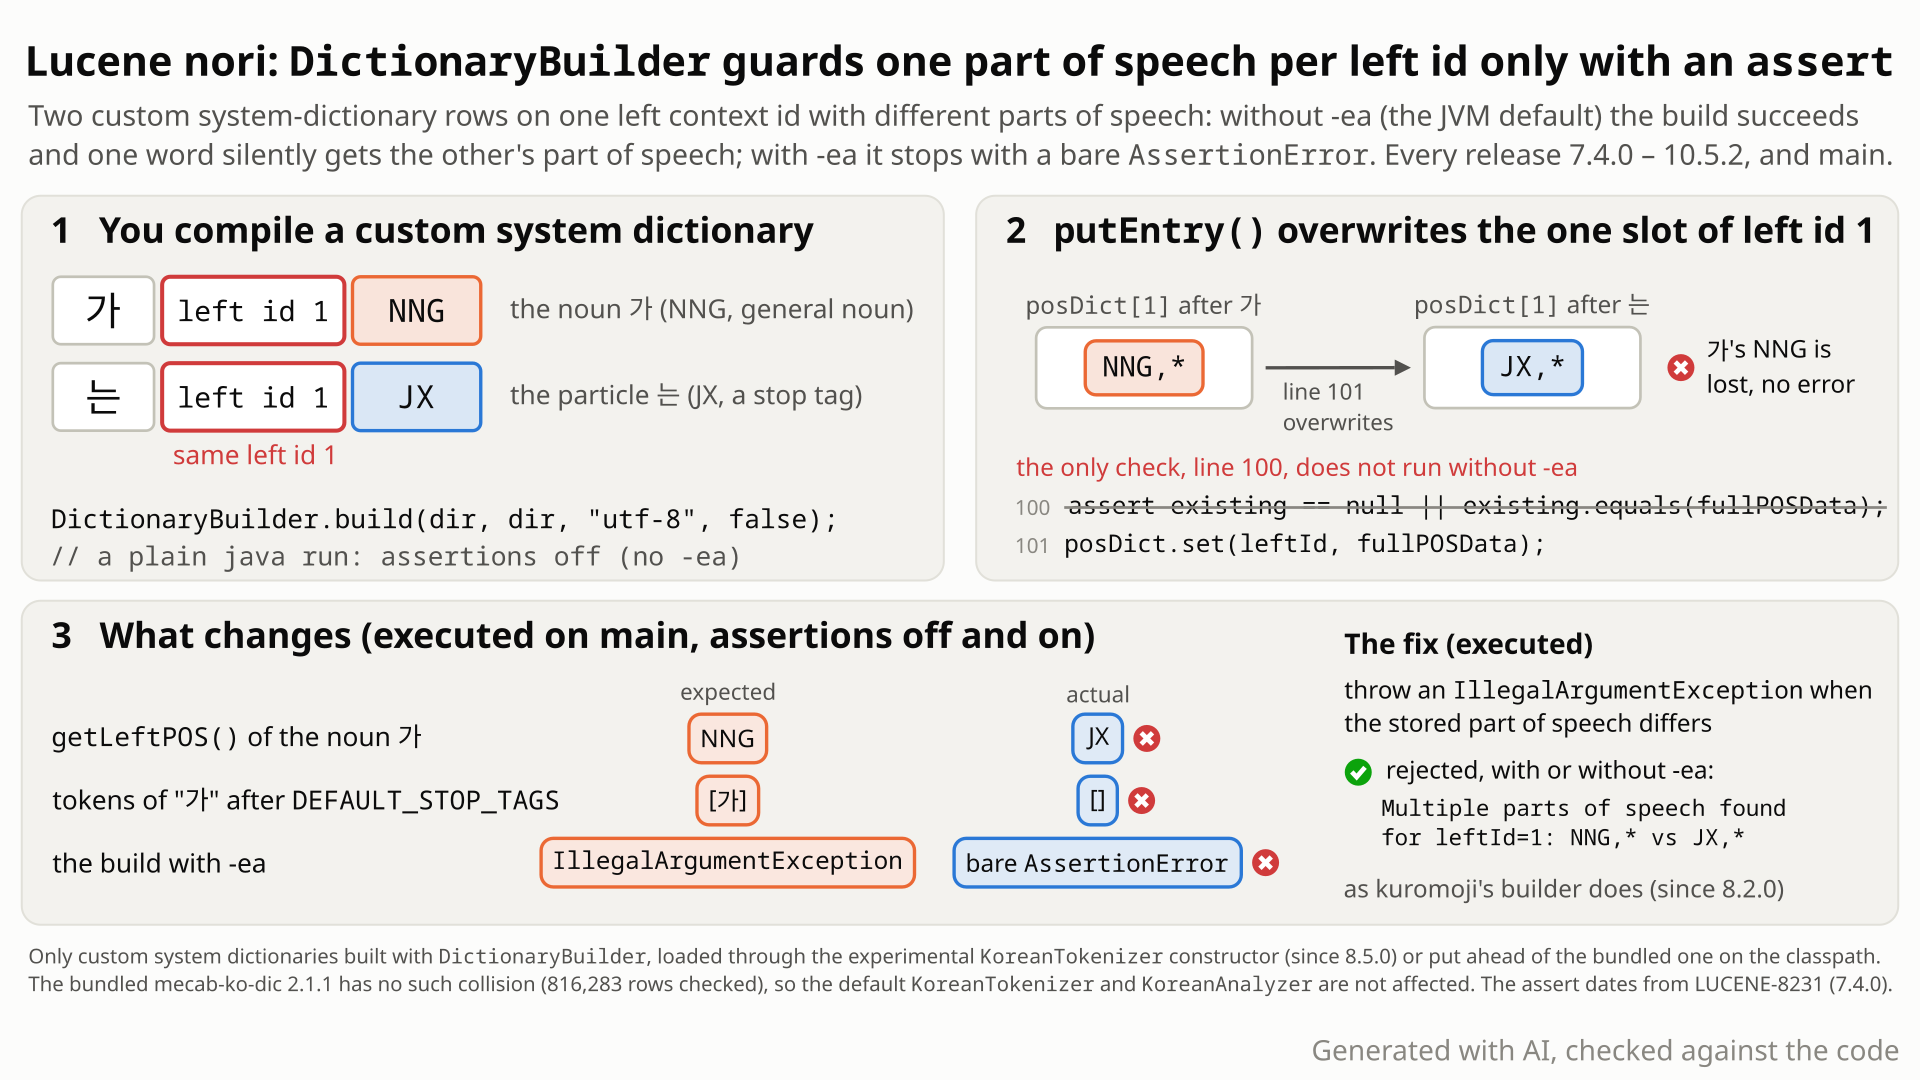
- You compile your own nori system dictionary with
DictionaryBuilderfrom two rows that share left context id 1: the noun 가 (tag NNG) and the topic particle 는 (tag JX). You load it intoKoreanTokenizerand filter withKoreanPartOfSpeechStopFilterand its default stop tags. - The compiled format keeps one part of speech per left id, not per word, so it cannot hold both. You expect the builder to reject the source, as kuromoji's builder does ("Multiple entries found for leftID"), or else each word to keep its own tag.
- With assertions off (the JVM default) the build succeeds. The only check is
assert existing == null || existing.equals(fullPOSData)(TokenInfoDictionaryEntryWriter.java:100); the next line overwrites the slot, so it keeps JX from 는, the row that sorts last by surface. - The noun 가 now reports left POS JX, and JX is a default stop tag: tokenizing
가gives 0 tokens instead of[가]. With the tags swapped (a particle on a noun's id), the particle is kept instead. - With
-eathe build stops with a bareAssertionErrorat that line, naming neither the id nor the rows. The bundled dictionary has no such collision in its 816,283 rows, so the defaultKoreanAnalyzeris unaffected.
Applications that compile a custom system dictionary with DictionaryBuilder and load it into KoreanTokenizer (via the experimental constructor since 8.5.0, or ahead of the bundled one on the classpath), when two rows share a left id but differ in part of speech. The bundled dictionary and KoreanAnalyzer are unaffected. Silently, nouns vanish from the index or particles get indexed.
Mechanism, terms and numbers681 words
Nori's compiled system dictionary stores a word's left part of speech in a table indexed by left context id (posDict), not per word: TokenInfoMorphData.getLeftPOS returns posDict[getLeftId(morphId)] (TokenInfoMorphData.java:73-76). When the public DictionaryBuilder writes a row, TokenInfoDictionaryEntryWriter.putEntry compares the row's part of speech and semantic class with what the slot already holds only through assert existing == null || existing.equals(fullPOSData) (TokenInfoDictionaryEntryWriter.java:100) and then overwrites the slot (:101). With assertions off, the JVM default and how the project's own regenerate task runs the builder, a source in which two rows share a left id but have different parts of speech builds without error, and every word on that id reports the part of speech of the row that sorts last by surface. In the repro the noun 가 (NNG) shares left id 1 with the topic particle 는 (JX): 가 reports JX, and KoreanPartOfSpeechStopFilter with DEFAULT_STOP_TAGS drops it (0 tokens instead of [가]); with -ea the build stops with a bare AssertionError. Kuromoji's builder throws IllegalArgumentException("Multiple entries found for leftID=") for the same case since LUCENE-8863; LUCENE-8904, "the Nori version" of that change, converted nori's neighbouring builder asserts but left this one. Only custom system dictionaries are affected (loaded through the @lucene.experimental custom-dictionary KoreanTokenizer constructor since 8.5.0; the release sweep reached older releases by putting the compiled files ahead of the bundled dictionary on the classpath): the bundled mecab-ko-dic 2.1.1 has no colliding left id, so the default KoreanTokenizer and KoreanAnalyzer are not. Every release from 7.4.0 to 10.6.0 (10.6.0 by reading) and main has it. The recommended fix replaces the assert with an IllegalArgumentException that compares only the part of speech, the one value the format stores.
- System dictionary source: MeCab-format CSV rows, 12 columns: surface, left id, right id, cost, part of speech, semantic class, coda flag, reading, type (
*, Compound, Inflect, Preanalysis), first and last part of speech, expression (TokenInfoDictionaryEntryWriter.java:39-60).DictionaryBuilder.build(inputDir, outputDir, encoding, normalize)compiles it (DictionaryBuilder.java:23-39). - Left context id: the id that the connection-cost matrix uses for the word's left side. Many words share one id.
posDict: the compiled table that maps a left id to one part of speech.getLeftPOSreads it (TokenInfoMorphData.java:73-76), andgetRightPOSreturns the same value for plain and compound words and words with a single part of speech (:78-87).KoreanPartOfSpeechStopFilter: removes a token whose left part of speech is a stop tag (KoreanPartOfSpeechStopFilter.java:91-95);DEFAULT_STOP_TAGScontains the particles (JX among them,:52) and not the nouns.
- The builder sorts all rows by surface with a stable sort (
TokenInfoDictionaryBuilder.java:89-90) and writes them in that order. 가 (U+AC00) comes before 는 (U+B294). - For each row,
putEntrybuildsfullPOSData = leftPOS.name() + "," + semantic class(TokenInfoDictionaryEntryWriter.java:98), checks it against the slot withassert existing == null || existing.equals(fullPOSData)(:100) and sets the slot (:101). Row 가 sets slot 1 toNNG,*; row 는 overwrites it withJX,*. writePosDictwrites one byte per left id, the part of speech only (:174-189).- At analysis time 가 reports JX, and the default stop tags remove it. The same tag also feeds the tokenizer's space penalty (
Viterbi.java:344-346; read, not run). - With
-ea, the assert fires insideDictionaryBuilder.buildwith no message. Lucene's gradle test task turns assertions on for about 75% of seeds unless-Ptests.assertsis given, so pass-Ptests.asserts=falseto see the silent result.
| source rows (left id) | build, assertions off | 가 reports | 가 after DEFAULT_STOP_TAGS | build, assertions on |
|---|---|---|---|---|
| 가 NNG (1), 는 JX (1) | accepted | JX | [] | AssertionError at :100 |
| 가 NNG (1), 는 JX (4), control | accepted | NNG | [가] | not run with these rows (no shared id); the independent reproducer's distinct-id control passes with -ea |
| 가 JKS (4), 나무 NNG (4) | accepted | 가 reports NNG | [가], a particle kept | AssertionError |
| with the fix: 가 NNG (1), 는 JX (1) | IllegalArgumentException: Multiple parts of speech found for leftId=1: NNG,* vs JX,* | - | - | same |
Exposure and likelihood341 words
- Who is exposed. Code that calls
DictionaryBuilder(in the jar since 8.3.0) and loads the result through thePathconstructors and the custom-dictionaryKoreanTokenizerconstructor (8.5.0+,@lucene.experimental), whose javadoc says it "provides an entry point for users that want to construct custom language models that can be used as input to {@link DictionaryBuilder}" (KoreanTokenizer.java:138-152). Before 8.5.0 there is no such constructor; the release sweep loaded the compiled files by putting them ahead of the bundled dictionary on the classpath.KoreanTokenizerFactorytakes only a user dictionary, so factory-configured chains cannot load a custom system dictionary. - Not exposed. The bundled mecab-ko-dic 2.1.1: 0 left ids with more than one part of speech over all 816,283 rows, so the default
KoreanTokenizerandKoreanAnalyzerare clean. The user dictionary uses a fixed left id and tag (UserMorphData.java:25-26,:62-63). - What the damage looks like. Silent with assertions off: every word on the shared id reports the tag of the row that sorts last by surface. With the default stop tags a noun disappears from the index (the repro) or a particle is indexed (the reverse case). With
-ea, a bareAssertionErrorthat names neither the id nor the rows. - Why assertions are usually off. The JVM default, and the project's own
regeneratetask runs the builder throughjavaexecwith only-Xmx1G(lucene/analysis/nori/build.gradle:34-42). - How likely. Rare. In mecab-ko-dic's own tooling the left context is the part of speech and semantic class (its
rewrite.defandleft-id.def), so a collision usually needs hand-assigned or copied ids; what other dictionary compilers emit was not surveyed. One path through its conventions exists:Preanalysisrows whose first-POS column is*with semantic class 지명 map to the wildcard left id 1, while nori takes their tag from column 4, which can differ (two such rows, NNG and NNP: the NNG word reports NNP). In the bundled data all 7 such rows are NNP. No public report was found in the documented searches. - Scale. Two rows reproduce it; deterministic; no size or timing factor.
The test shows that nori's DictionaryBuilder checks a left-id/part-of-speech collision (가 NNG and 는 JX on left id 1) only with a Java assert: with -da the build succeeds and 가 silently gets the part of speech of the last row written.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.ko.dict;

import java.nio.charset.StandardCharsets;
import java.nio.file.Files;
import java.nio.file.Path;
import java.util.List;
import org.apache.lucene.analysis.ko.POS;
import org.apache.lucene.analysis.morph.BinaryDictionary;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.IntsRef;

public class TestNoriBuilderLeftIdPosCollision extends LuceneTestCase {

  private static Path file(Path dir, String suffix) {
    return dir.resolve(TokenInfoDictionary.class.getName().replace('.', '/') + suffix);
  }

  public void testEachWordKeepsItsPartOfSpeech() throws Exception {
    Path dir = createTempDir();
    Files.write(
        dir.resolve("test.csv"),
        List.of("가,1,1,0,NNG,*,F,가,*,*,*,*", "는,1,1,0,JX,*,T,는,*,*,*,*"),
        StandardCharsets.UTF_8);
    Files.write(dir.resolve("char.def"), List.of("DEFAULT 0 1 0"));
    Files.write(dir.resolve("unk.def"), List.of("DEFAULT,2,2,10000,SY,*,*,*,*,*,*,*"));
    Files.write(dir.resolve("matrix.def"), List.of("3 3"));
    try {
      DictionaryBuilder.build(dir, dir, "utf-8", false);
    } catch (IllegalArgumentException rejected) {
      return;
    }
    TokenInfoDictionary dict =
        new TokenInfoDictionary(
            file(dir, BinaryDictionary.TARGETMAP_FILENAME_SUFFIX),
            file(dir, BinaryDictionary.POSDICT_FILENAME_SUFFIX),
            file(dir, BinaryDictionary.DICT_FILENAME_SUFFIX),
            file(dir, TokenInfoDictionary.FST_FILENAME_SUFFIX));
    IntsRef ids = new IntsRef();
    dict.lookupWordIds(0, ids);
    // expected: an IllegalArgumentException from build, or 가 (source id 0) keeps NNG; actual: JX
    assertEquals(POS.Tag.NNG, dict.getMorphAttributes().getLeftPOS(ids.ints[ids.offset]));
  }
}
# in a copy of this finding's repro folder (repro/LFV-717/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/analysis/nori/build/libs/lucene-analysis-nori-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.ko.dict.TestNoriBuilderLeftIdPosCollision
# the module(s) analysis-nori also need their third-party runtime jars
- Expected vs actual
- Expected: an IllegalArgumentException from DictionaryBuilder.build, or 가 keeps NNG. Actual: with -da
expected:<NNG> but was:<JX>; with -ea a bare AssertionError at TokenInfoDictionaryEntryWriter.putEntry:100.
More files, environment, full output32 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError
       org.apache.lucene.analysis.ko.dict.TokenInfoDictionaryEntryWriter.putEntry(TokenInfoDictionaryEntryWriter.java:100)
       org.apache.lucene.analysis.morph.BinaryDictionaryWriter.put(BinaryDictionaryWriter.java:48)
       org.apache.lucene.analysis.ko.dict.TokenInfoDictionaryBuilder.buildDictionary(TokenInfoDictionaryBuilder.java:105)
       org.apache.lucene.analysis.ko.dict.TokenInfoDictionaryBuilder.build(TokenInfoDictionaryBuilder.java:56)
       org.apache.lucene.analysis.ko.dict.DictionaryBuilder.build(DictionaryBuilder.java:31)
org.apache.lucene.analysis.ko.dict.TestNoriBuilderLeftIdPosCollision.testEachWordKeepsItsPartOfSpeech(TestNoriBuilderLeftIdPosCollision.java:44)- The assert shows that the authors treated a collision as invalid input; no javadoc documents a silent last-writer-wins.
- Kuromoji's builder throws
IllegalArgumentExceptionfor this exact case since LUCENE-8863; LUCENE-8904, "the Nori version" of that change, converted nori's neighbouring asserts but not this one. KoreanTokenizerdocuments customDictionaryBuilderdictionaries as a supported entry point.
The full argument285 words
- Contract. No javadoc states the one-part-of-speech-per-left-id rule or what the builder does with a source that breaks it (
DictionaryBuilderhas a one-line javadoc, "Tool to build dictionaries."). The assert shows that the authors treat the collision as an error, not as something to merge.KoMorphData.getLeftPOSis documented to return the left part of speech "of specified word" (KoMorphData.java:34-39); here it returns another word's. - Neighbouring checks are exceptions. In the same method the left-id limit and the POS-type checks throw
IllegalArgumentException(TokenInfoDictionaryEntryWriter.java:130-135); kuromoji's writer throws for this very case (ja/dict/TokenInfoDictionaryEntryWriter.java:129-133, still marked// TODO: test me). - History. LUCENE-8863 (
4502065f036, 2019, #9906, 8.2.0) turned kuromoji's identical assert into the exception. LUCENE-8904 (2ac5fb668a8, 2019, #9947, 8.3.0): "It is the Nori version of @msokolov's #9906. ... 1) Improve exception handling ... Overall, it is the same as #9906." Its diff converted the left-id limit, POS-type, word-order, source-id-order and posDict-format asserts; this one stayed without discussion (otherputEntryinput asserts stayed too, so it was not singled out). - Maintainers on builder asserts. In #9860 (LUCENE-8816, about kuromoji), @rmuir: "the various
asserts in the current tooling should be fixed to be realifstatements+exception messages" and "The use of assert was laziness on my part: we should treat it as technical debt and fix it"; @mocobeta asked to "change the all assertions to some Exceptions so that users can figure out the problem with their customized dictionary". - Supported path. The custom-dictionary
KoreanTokenizerconstructor (KoreanTokenizer.java:138-152,@lucene.experimental) namesDictionaryBuilderoutput as its input. - Tests. No nori or kuromoji test builds a left-id collision;
TestTokenInfoDictionary.testPutExceptioncovers only too few columns and too large an id (:92-99).
The devil's-advocate check227 words
The strongest "intended" case (rated moderate by the cross-model reviews and the adjudication; the devil's-advocate verifier built it too and rejected it, without a rating): one part of speech per left id is a deliberate format choice. In LUCENE-8231 (#9278) @jimczi wrote "The semantic class + POS is unique per leftId so this could also save 1 byte in the binary dictionary" and then "added a POS dict that maps the left id and the part of speech tag". Read that way, the assert is a developer precondition on mecab-ko-dic-shaped data and a colliding custom source is garbage in, garbage out; DictionaryBuilder states no input contract, the custom-dictionary constructor is experimental, and the open kuromoji UniDic PR #12517 would relax kuromoji's check rather than enforce it.
Why it fails: the format choice is fine, but silently overwriting the slot is documented nowhere; the project turned the identical kuromoji line into an exception, set out to do the same for nori, and its maintainers called builder asserts technical debt; KoreanTokenizer documents custom dictionaries as an entry point. Relaxing the rule, as #12517 does for kuromoji, would mean storing the tag per entry, not overwriting it. Verdict: a defect (adjudication: confirmed, medium). What the counter-case gets right: the reach is narrow and the impact low, so it reads best as a missing input check, a hardening fix like LUCENE-8904.
Recommended Throw when the stored part of speech differs (POS-only check)
Replace the assert at TokenInfoDictionaryEntryWriter.java:100 with an IllegalArgumentException when the stored part of speech differs, comparing the part of speech only, the one value the format stores. The repro and two TestTokenInfoDictionary test changes pass, the nori module runs 90 tests with 0 failures (4 skipped) with assertions on and off, and the bundled dictionary rebuilds byte-identical.
     String existing = posDict.get(leftId);
-    assert existing == null || existing.equals(fullPOSData);
+    // only the part of speech is stored per left id (see writePosDict), so all entries that share
+    // a left id must have the same part of speech; the semantic class may differ
+    if (existing != null && existing.startsWith(leftPOS.name() + ",") == false) {
+      throw new IllegalArgumentException(
+          "Multiple parts of speech found for leftId="
+              + leftId
+              + ": "
+              + existing
+              + " vs "
+              + fullPOSData);
+    }
     posDict.set(leftId, fullPOSData);
All options and trade-offs4 options · 671 words
Option A keeps the format and turns the silent overwrite into a clear build error; option B lifts the restriction instead and is the larger change. Do not copy kuromoji's check literally (option C): it also compares the semantic class, which the format drops. Whatever is chosen, extend TestTokenInfoDictionary.testPutException with the collision, as the validated diff does.
Throw when the stored part of speech differs (POS-only check) (validated by the checks) (recommended)
+11/-1 in TokenInfoDictionaryEntryWriter.java (the finder's logic, formatted with applyGoogleJavaFormat, its one-line comment rewritten as two lines), plus two tests in the existing TestTokenInfoDictionary: testPutException gains the 가 NNG / 는 JX collision with expectThrows(IllegalArgumentException.class, ...) and a check that the message names leftId=1; the new testPutSameLeftIdDifferentSemanticClass builds 서울 NNP,지명 and 철수 NNP,인명 on left id 1 and asserts NNP for both.
     String existing = posDict.get(leftId);
-    assert existing == null || existing.equals(fullPOSData);
+    // only the part of speech is stored per left id (see writePosDict), so all entries that share
+    // a left id must have the same part of speech; the semantic class may differ
+    if (existing != null && existing.startsWith(leftPOS.name() + ",") == false) {
+      throw new IllegalArgumentException(
+          "Multiple parts of speech found for leftId="
+              + leftId
+              + ": "
+              + existing
+              + " vs "
+              + fullPOSData);
+    }
     posDict.set(leftId, fullPOSData);
Trade-offs
- A custom source that built "successfully" before, with wrong tags, now fails to build with a message naming the id and both values: the intended behaviour change, worth a CHANGES entry.
- Keeps the one-part-of-speech-per-left-id restriction rather than lifting it; no format change, nothing on the analysis hot path (the check runs only while building).
startsWith(leftPOS.name() + ",")is exact because tag names contain no comma; a reviewer may prefer to keep thePOS.Tagper left id in a separate list.
What the checks validated
- Scratch worktree at
a9779ef3c193, gradle, JDK 25: on stock, the repro and the two test changes (7 tests) fail 4 of 7 with assertions on (the 2 repro tests, the extendedtestPutExceptionand the newtestPutSameLeftIdDifferentSemanticClass, each a bareAssertionErrorat:100) and 3 of 7 with assertions off (the semantic-class test passes there); with the fix, 7 of 7 pass both ways. - With the fix: the whole
:lucene:analysis:nori:test, 14 suites, 90 tests, 0 failures, 4 skipped (3@Nightly, 1@Ignore), with assertions on and off;:lucene:analysis:nori:checkGoogleJavaFormatpasses. - The bundled mecab-ko-dic 2.1.1 rebuilt with the fix,
-eaand-da: all 9 resource files byte-identical to the shipped ones. - Earlier, with the finder's copy of the same logic: the independent reproducer's test 5 of 5, the cross-model reviewers' tests, upstream
TestTokenInfoDictionaryandTestUnknownDictionary6 of 6; the release-sweep driver rejects the colliding source and still builds the control.
Write the left part of speech into each entry instead of the per-left-id table, so rows that share a left id may differ. Not run.
Trade-offs
Lifts the restriction, the direction the open kuromoji UniDic PR #12517 takes for kuromoji. But it changes the binary format (a format version bump and a rebuild of every dictionary), adds a byte to entries and touches TokenInfoMorphData, and no known nori dictionary needs it. Bigger than a bug fix; could follow option A.
if (existing != null && existing.equals(fullPOSData) == false) throw new IllegalArgumentException(...).
Trade-offs
Compares the semantic class too, which writePosDict discards, so it would reject rows with one tag and different semantic classes that the format stores correctly. Today's assert already does that with -ea: two NNP rows with semantic classes 지명 and 인명 fail with AssertionError under -ea and build correctly under -da, and testPutSameLeftIdDifferentSemanticClass fails on stock with assertions on.
A javadoc note on DictionaryBuilder that rows sharing a left id must share a part of speech.
Trade-offs
Changes nothing for a build without -ea, which stays silent.
A product that compiles nori system dictionaries from rows its users supply cannot rely on DictionaryBuilder to reject conflicting rows today, and should check them itself.
A bounded-exhaustive round trip of the bundled nori dictionary against its source found the shipped data clean (no left id with two parts of speech in 816,283 rows); reading how that table is written then showed that an assert is the only guard, and a JUnit with a two-row custom dictionary witnessed it.
The method in full143 words
Method: bounded-exhaustive translation validation, then a targeted JUnit (the hunt's "semi-formal" tier). A hunt unit, "CJK compiled-dictionary source round trip", lead 9.1 of the unit plan (builder asserts as the only guard on the source data), 2026-10-27.
- The finder rebuilt the bundled mecab-ko-dic 2.1.1 with
-ea: no builder assert fired and the resources were byte-identical to the shipped ones. - A round-trip harness compared the shipped nori resources with the source over all 816,283 lexicon rows on the stock jars: 0 left ids with more than one part of speech, so the bundled dictionary is unaffected.
- Reading how
posDictis written showed that the only guard against such a collision is the assert atTokenInfoDictionaryEntryWriter.java:100; the finder then wrote the two-row JUnit (found 2026-10-27). - Independent AI tools and reviews by another model family then reproduced, challenged and judged it (see the checks).
No prior report found (best-effort search, 2026-10-27): 152 logged queries and two runs of a scripted prior-report search over GitHub issues, PRs and commits, downstream projects, the mailing lists, JIRA and the web, plus all 409 open PRs. The nearest items are precedents: the same fix in kuromoji (LUCENE-8863) and nori's partial conversion of builder asserts (LUCENE-8904).
Searches4 searches
Nothing found reports that the check is assert-only or that a build without -ea gives words another row's part of speech. Upstream main a95c754ee003 (2026-10-26), branch_10x and branch_10_6 still have the assert; no open PR changes it (#16911 only deletes branch_10x).
Related, not the same bug: #9947 / LUCENE-8904 (closed; converted nori's other builder asserts, left this one without discussion); #9906 / LUCENE-8863 (closed; the same fix in kuromoji); #9860 / LUCENE-8816 (open; the general agreement that builder asserts should be exceptions, about kuromoji's builder tooling; the thread also discusses nori, but no comment names nori's builder asserts or this check); #9278 / LUCENE-8231 (the design note on one part of speech per left id); #12517 (open kuromoji UniDic PR that stops throwing on kuromoji's check, a counter-signal for a throwing fix); jimczi/nori#1 (a 2018 builder AssertionError at a different assert).
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene, apache/lucene-solr) | 2026-10-27 | 152 logged queries and 21 hits judged, plus two runs of a scripted prior-report search (43 and 51 queries; the second: 16 GitHub, 3 commit, 2 downstream, 20 list, 4 JIRA, 6 web, 171 distinct hits, 0 rated high, every medium hit read) | no report; precedents #9947, #9906, #9860, #9278, #12517 |
| Open PRs | 2026-10-27 | the changed files of all 409 open apache/lucene PRs | none changes the assert; #16911 deletes branch_10x |
| Mailing lists and JIRA | 2026-10-27 | dev@, java-user@ and issues@ (30 manual queries plus 20 through the tool, which also covered commits@); JIRA queries | only LUCENE-8231/8816/8817/8863/8904 traffic; no report |
| Downstream projects and the web | 2026-10-27 | downstream issue trackers (three issues read, others screened by title) and 9 web queries, one in Korean | no report |
Present since nori's first commit e851b89cbeb (LUCENE-8231, 2018-04-13), first released in 7.4.0, and never fixed. A uniform build-then-load driver reproduces it on 20 releases from 7.4.0 to 10.5.2 and on main, each with a passing control.
Versions tested7 rows
Introduced by e851b89cbeb "LUCENE-8231: Add a new analysis module (nori) similar to Kuromoji but to handle Korean" (Jim Ferenczi, 2018-04-13; branch_7x 8651fbaa8bc the same day; JIRA patch workflow, no PR; now issue #9278). CHANGES lists it under 7.4.0. The line was moved but never changed: LUCENE-8904 (2ac5fb668a8, 8.3.0) left it, LUCENE-8934 (2c0d8996cf9, 8.3.0) put the builder into the jar, LUCENE-9253 (8.5.0) added the custom-dictionary constructor, LUCENE-10400 (9.1.0) the public Path constructors, and LUCENE-10393 / LUCENE-10475 (10.0.0) renamed and moved the writer. In 7.4.0-8.2.0 the builder shipped only as source, and its ant build-dict target (which ant regenerate runs) enables assertions (build.xml:77-96 at 7.4.0), so on that path a collision crashed the build; from 8.3.0 a call without -ea is silent. The sweep's load phase puts the compiled files ahead of the nori jar on the classpath so the default KoreanTokenizer() loads them, a harness technique that works on every release; a constructor for a custom system dictionary exists only from 8.5.0. Read sweep: every release tag from 7.4.0 to 10.5.2 (58 tags) has the assert-only check; 67 releases in total, 7.3.1 has no nori. Not a regression.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the repro fails 2 of 2 through gradle and the standalone runner, assertions on and off; the driver: noun reports JX and is dropped |
| 10.0.0, 10.5.2 | affected | the JUnit fails 2 of 2 (-ea and -da); the driver: 가 -> [가/JX], dropped |
| 9.0.0, 9.1.0, 9.12.3 | affected | the driver: 가 -> [가/J], dropped; the 9.x JUnit fails 2 of 2 on 9.1.0 and 9.12.3 |
| 8.3.0, 8.4.1, 8.5.0, 8.8.2, 8.9.0, 8.10.0, 8.10.1, 8.11.0-8.11.4 | affected | the driver: -da build accepted, -ea AssertionError, 가 -> [가/J], dropped |
| 7.4.0, 7.7.3, 8.2.0 | tool sources | builder compiled from the tag's unmodified tool sources: -da accepted, 가 dropped; -ea AssertionError (the ant build-dict target enables -ea) |
| 7.3.1 | API absent | no nori module |
| main + fix | not affected | the colliding source is rejected with IllegalArgumentException; the control builds; the nori module runs 90 tests with 0 failures (4 skipped) |
An independent reproducer, a devil's advocate, an adjudication and reviews by another model family (which ran their own tests) all found it real; the adjudication confirmed it with medium confidence and low severity. A registry re-run, an audit and this doc's fix validation reproduced it with new seeds.
Checks and verdicts365 words
Every check wrote or ran its own test against the stock jars, with assertions on and off unless noted.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Two-row JUnit fails 2 of 2 on main (-da wrong tag and dropped noun; -ea AssertionError), 10.5.2 and 9.12.3; with the fix 2 of 2 pass and upstream dictionary tests 6 of 6. |
| cross-model review, refute lens | real (high) | An independent reviewer from another model family (OpenAI GPT-5.6) wrote its own test (a VV row and a JKO row on one left id): fails with -da and -ea, controls pass, the fix passes; rated the by-design argument moderate. |
| Independent reproducer | real | Own 5-test JUnit in both directions fails 3 of 5 on main, 10.5.2 and 9.12.3 with -ea and -da; controls pass; 5 of 5 with the fix; found that the assert also rejects same-tag rows with different semantic classes. |
| Cross-model review, intended lens | real (high) | OpenAI GPT-5.6: its own test fails on main and 10.5.2, its 9.x test on 9.12.3, its fix test passes 3 of 3; the cross-model review step re-ran these and the finder's test on a9779ef3c193 with the same results. |
| Devil's advocate | real | Built the strongest by-design case (the format choice in LUCENE-8231) and showed why it fails; found the mecab-ko-dic wildcard-left-id path. |
| adjudication | confirmed (medium) | Re-ran the independent reproduction's test with new seeds (3 of 5 fail, -ea and -da; 5 of 5 with the fix); class silent wrong results, severity low. |
| registry re-run and audit | keep | The finder's test fails 2 of 2 with -da and -ea and passes with the fix (fresh seeds, twice); the independent reproduction's test fails 3 of 5 and passes 5 of 5 with the fix. |
| security assessment | none | The trigger is the operator's own dictionary source, trusted configuration under Lucene's threat model. |
| doc fix validation | fix validated | Gradle in a scratch worktree: stock fails, the fix passes the repro and the two test changes, and the nori module runs 90 tests with 0 failures (4 skipped), with assertions on and off; format check passes; bundled dictionary rebuilds byte-identical. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 445 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,528 words
- Registry title
- Nori's DictionaryBuilder checks that rows sharing a left context id have the same part of speech only with a Java assert, so with assertions off a custom system dictionary silently gives those words the part of speech of another row and KoreanPartOfSpeechStopFilter drops or keeps them wrongly
- Area
- analysis / nori system dictionary builder (DictionaryBuilder, TokenInfoDictionaryEntryWriter; custom system dictionaries)
- Priority
- Low, rank 522: Nori's DictionaryBuilder checks for left-id part-of-speech collisions only with an assert, which matters only for custom dictionaries with hand-assigned ids.
- Impact class
- silent wrong results
- Impact note
- Hits only applications that compile their own nori system dictionary with the public DictionaryBuilder and load it through the @lucene.experimental custom-dictionary KoreanTokenizer constructor (opt-in), and only when two source rows share a left context id but carry different parts of speech: with assertions off (the JVM default, and how the build's own regenerate task runs) the build succeeds, every word on that left id reports the part of speech of the row written last in surface-sorted order, and KoreanPartOfSpeechStopFilter with DEFAULT_STOP_TAGS then drops a noun or keeps a particle, while with -ea the build stops with a bare AssertionError; the bundled mecab-ko-dic 2.1.1 has no such collision (all 816,283 rows checked), so the default KoreanTokenizer and KoreanAnalyzer are not affected; no scale needed, deterministic, every release 7.4.0 to 10.6.0 (10.6.0 by reading) and main.
- Summary
- You compile a custom nori system dictionary with DictionaryBuilder from MeCab-format rows in which the noun 가 (NNG) and the particle 는 (JX) share left context id 1, and expect the builder either to reject the source (the compiled format keeps only one part of speech per left id, and kuromoji's builder throws 'Multiple entries found for leftID' for the same case) or each word to keep its own part of speech. Instead, with assertions off, the builder overwrites the single slot for left id 1 with the part of speech of the row it writes last, because the only check is an assert (TokenInfoDictionaryEntryWriter.java:100): 가 then reports left POS JX, and KoreanTokenizer followed by KoreanPartOfSpeechStopFilter with DEFAULT_STOP_TAGS returns no token instead of [가]. With -ea the build fails with a bare AssertionError rather than an IllegalArgumentException that names the problem.
- Introduced
- e851b89cbeb1f55edc0f2c1276e2ae812eca2643 (LUCENE-8231 'Nori, a Korean analyzer based on mecab-ko-dic', by jimczi; JIRA patch workflow, no pull request; the issue is now apache/lucene#9278) and its same-day branch_7x backport 8651fbaa8bc65fdfec397ad4e7ebe2b5acf78d7b, which shipped in 7.4.0 [read: git log -S 'existing.equals(fullPOSData)' -- lucene/analysis and git blame -w -M -C at the study base attribute today's TokenInfoDictionaryEntryWriter.java:98-100 to e851b89cbeb, across the rename from ko/util/BinaryDictionaryWriter.java; LUCENE-8904 (2ac5fb668a8, 8.3.0) converted nori's other builder asserts to exceptions but left this one; kuromoji's identical assert became an IllegalArgumentException in LUCENE-8863 (4502065f036, 8.2.0)]. Not a regression: the assert-only check dates from the module's first commit (2018-04-13)
- First affected version
- 7.4.0 [exec] (nori's first release; 7.3.1 has no nori module [exec: no artifact on Maven Central, no lucene/analysis/nori in the tag]). Reach by version: 7.4.0-8.2.0 ship the builder only as source (src/tools), and the documented ant build-dict target ran it with assertions on, so on that path a collision failed with AssertionError instead of silently [read]; 8.3.0 puts DictionaryBuilder in the jar (LUCENE-8934), where a call without -ea is silent; 8.5.0 adds the public custom-dictionary KoreanTokenizer constructor (LUCENE-9253); from 9.0.0 the project's gradle regenerate task runs the builder with only -Xmx1G, assertions off [read]
- Affected versions
- Every release from 7.4.0 through 10.5.2 (67 releases; latest 9.x 9.12.3), 10.6.0 (by reading) and main a9779ef3c193; never fixed. [exec] the uniform history sweep (release DictionaryBuilder.main builds a two-row colliding source, then the default KoreanTokenizer loads it from the classpath and DEFAULT_STOP_TAGS is applied) fails on 20 releases and main: 7.4.0, 7.7.3 and 8.2.0 (builder compiled from the tag's unmodified tool sources), 8.3.0, 8.4.1, 8.5.0, 8.8.2, 8.9.0, 8.10.0, 8.10.1, 8.11.0-8.11.4, 9.0.0, 9.1.0, 9.12.3, 10.0.0, 10.5.2 and main (-da build accepted, the noun reports the particle's tag J or JX and is dropped; -ea build stops with AssertionError), each with a passing distinct-left-id control; the public-API JUnit fails 2 of 2 with -ea and -da on 9.1.0, 9.12.3 (9.x variant), 10.0.0, 10.5.2 and main; the independent reproduction's test fails 3 of 5 on 10.5.2 and 9.12.3 (-ea and -da). [read] every release tag from 7.4.0 to 10.5.2 in the history clone (58 tags) has the assert-only check; 8.8.2-8.11.4 are not tagged locally and were executed instead. TokenInfoDictionaryEntryWriter.java is unchanged on upstream main a95c754ee003 (2026-10-26), branch_10x and branch_10_6, and lucene/analysis/nori is identical at ea57360912ed. All runs on JDK 25, aarch64
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal
- Upstream and prior reports
- none found (2026-10-27, plus the finder's scripted prior-report search with 43 queries, read-only; the prior-report record, verdict new, confidence high): 152 logged queries and 21 hits judged, a second scripted prior-report search with 51 queries (16 GitHub, 3 commit, 2 downstream, 20 list, 4 JIRA, 6 web; 171 distinct hits, 0 high, every medium hit read), the changed files of all 409 open apache/lucene PRs, the dev@, java-user@ and issues@ lists (30 manual queries), JIRA and 9 web queries (one in Korean). Related, not this bug: #9947 / LUCENE-8904 (closed; 'the Nori version of #9906', converted nori's left-id limit, POS-type, ordering and posDict-format asserts to exceptions but left this one, with no discussion of it), #9906 / LUCENE-8863 (closed, kuromoji: the identical assert became IllegalArgumentException 'Multiple entries found for leftID'), #9860 / LUCENE-8816 (open, kuromoji: committers agreed that builder asserts should become exceptions so users of customized dictionaries see the problem; nori and this check are not named), #9278 / LUCENE-8231 (design note 'The semantic class + POS is unique per leftId', said of mecab-ko-dic), #12517 (open kuromoji UniDic PR that stops throwing on the kuromoji check, predecessor apache/lucene-solr#935; a counter-signal for a throwing fix), jimczi/nori#1 (2018 nori builder AssertionError at a different assert, by its line numbers). Not fixed: the assert is on upstream main a95c754ee003, branch_10x and branch_10_6, and no open PR changes it (#16911 only deletes branch_10x). Gaps: lexical, rate-limited first-page GitHub search; private trackers not visible. Update 2026-11-02: #16911 (open when searched) merged 2026-10-29 as 48cf3f515d6, which emptied branch_10x to a README tombstone (10.6 is the last 10.x minor; 10.x fixes go to branch_10_6); it fixes nothing here.
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26) through gradle in a scratch worktree with assertions on and off (2026-10-28), and through the standalone JUnit runner (2026-10-27 and 2026-10-28, including a registry re-run and an audit with fresh seeds); the 10.5.2 and 9.12.3 release jars (JUnit); a version-independent two-phase driver on 7.4.0, 7.7.3, 8.2.0, 8.3.0, 8.4.1, 8.5.0, 8.8.2, 8.9.0, 8.10.0, 8.10.1, 8.11.0-8.11.4, 9.0.0, 9.1.0, 9.12.3, 10.0.0, 10.5.2 and main (2026-10-27);lucene/analysis/noriis identical atea57360912ed, where the cross-model reviews ran. The recommended fix was validated in the scratch worktree: the repro and two upstream-style test changes (one extended test, one new test), the whole nori module (90 tests: 0 failures, 4 skipped) with assertions on and off,checkGoogleJavaFormat, and a byte-for-byte rebuild of the bundled dictionary.
- Finding record
lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/dict/TokenInfoDictionaryEntryWriter.java:94-101 (at a9779ef3c193) (posDict filled per left id; fullPOSData = leftPOS + ',' + semantic class; 'assert existing == null || existing.equals(fullPOSData)' at :100; posDict.set overwrites at :101) and :176-189 (writePosDict writes one POS byte per left id); dict/TokenInfoMorphData.java:74-75 (getLeftPOS returns posDict[getLeftId(morphId)]); dict/TokenInfoDictionaryBuilder.java:89-90 (stable sort by surface before writing, so the last row is last in surface order); dict/DictionaryBuilder.java:23-28 (public class 'Tool to build dictionaries.', public static build); ko/KoreanTokenizer.java:138-152 (custom-dictionary constructor, 'an entry point for users that want to construct custom language models that can be used as input to DictionaryBuilder', @lucene.experimental); ko/KoreanPartOfSpeechStopFilter.java:92-94 (accept tests getLeftPOS); lucene/analysis/nori/build.gradle:34-39 (regenerate javaexec with jvmArgs '-Xmx1G' only); lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/dict/TokenInfoDictionaryEntryWriter.java:129-133 (kuromoji throws IllegalArgumentException 'Multiple entries found for leftID=' for the same condition)
- The finding in 30 seconds
lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/dict/TokenInfoDictionaryEntryWriter.java:39-60 (at a9779ef3c193) (columns), :67-77 (left POS choice), :93-101 (posDict check and overwrite), :174-189 (writePosDict)lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/dict/TokenInfoMorphData.java:73-87; (at a9779ef3c193) dict/TokenInfoDictionaryBuilder.java:89-90, :100-124; dict/DictionaryBuilder.java:23-39lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/KoreanPartOfSpeechStopFilter.java:36-68, (at a9779ef3c193) :91-95; Viterbi.java:343-346Lucene main a9779ef3c193 build-tools/build-infra/src/main/java/org/apache/lucene/gradle/plugins/java/TestsAndRandomizationPlugin.java:240-249 (tests.asserts default: on for about 75% of seeds)
- Who is affected
lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/KoreanTokenizer.java:138-162; (at a9779ef3c193) KoreanTokenizerFactory.java:44-57, :73-74; dict/UserMorphData.java:25-26, :62-63lucene/analysis/nori/build.gradle:34-42 (at a9779ef3c193) (regenerate javaexec, jvmArgs '-Xmx1G' only)
- Why it looks unintended
lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/dict/DictionaryBuilder.java:23; (at a9779ef3c193) dict/KoMorphData.java:34-39; lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/dict/TokenInfoDictionaryEntryWriter.java:100, :130-135; KoreanTokenizer.java:138-152lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/dict/TokenInfoDictionaryEntryWriter.java:129-133 (at a9779ef3c193)lucene/analysis/nori/src/test/org/apache/lucene/analysis/ko/dict/TestTokenInfoDictionary.java:92-99 (at a9779ef3c193)
- Suggested fix
lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/dict/TokenInfoDictionaryEntryWriter.java:174-189 (at a9779ef3c193) (writePosDict stores the POS byte only)
- History
lucene/CHANGES.txt:7393 (at a9779ef3c193) (LUCENE-8231 under 7.4.0, heading :7322), :5946 (LUCENE-9253 under 8.5.0, heading :5882)
- TestNoriBuilderLeftIdPosCollision.java (JUnit test):
repro/LFV-717/src/org/apache/lucene/analysis/ko/dict/TestNoriBuilderLeftIdPosCollision.java(59 lines)
A light, step-by-step picture of the repro (the two rows, the shared slot, the overwrite and the dropped noun), made in parallel with this doc from the executed runs on main a9779ef3c193 and the code.
assets/LFV-717/bug.png(445 KB)