Words files for these factories come in two formats: wordset (the default, one word per line, # comments) and snowball (several words per line, | comments). Only wordset skips a leading byte order mark.
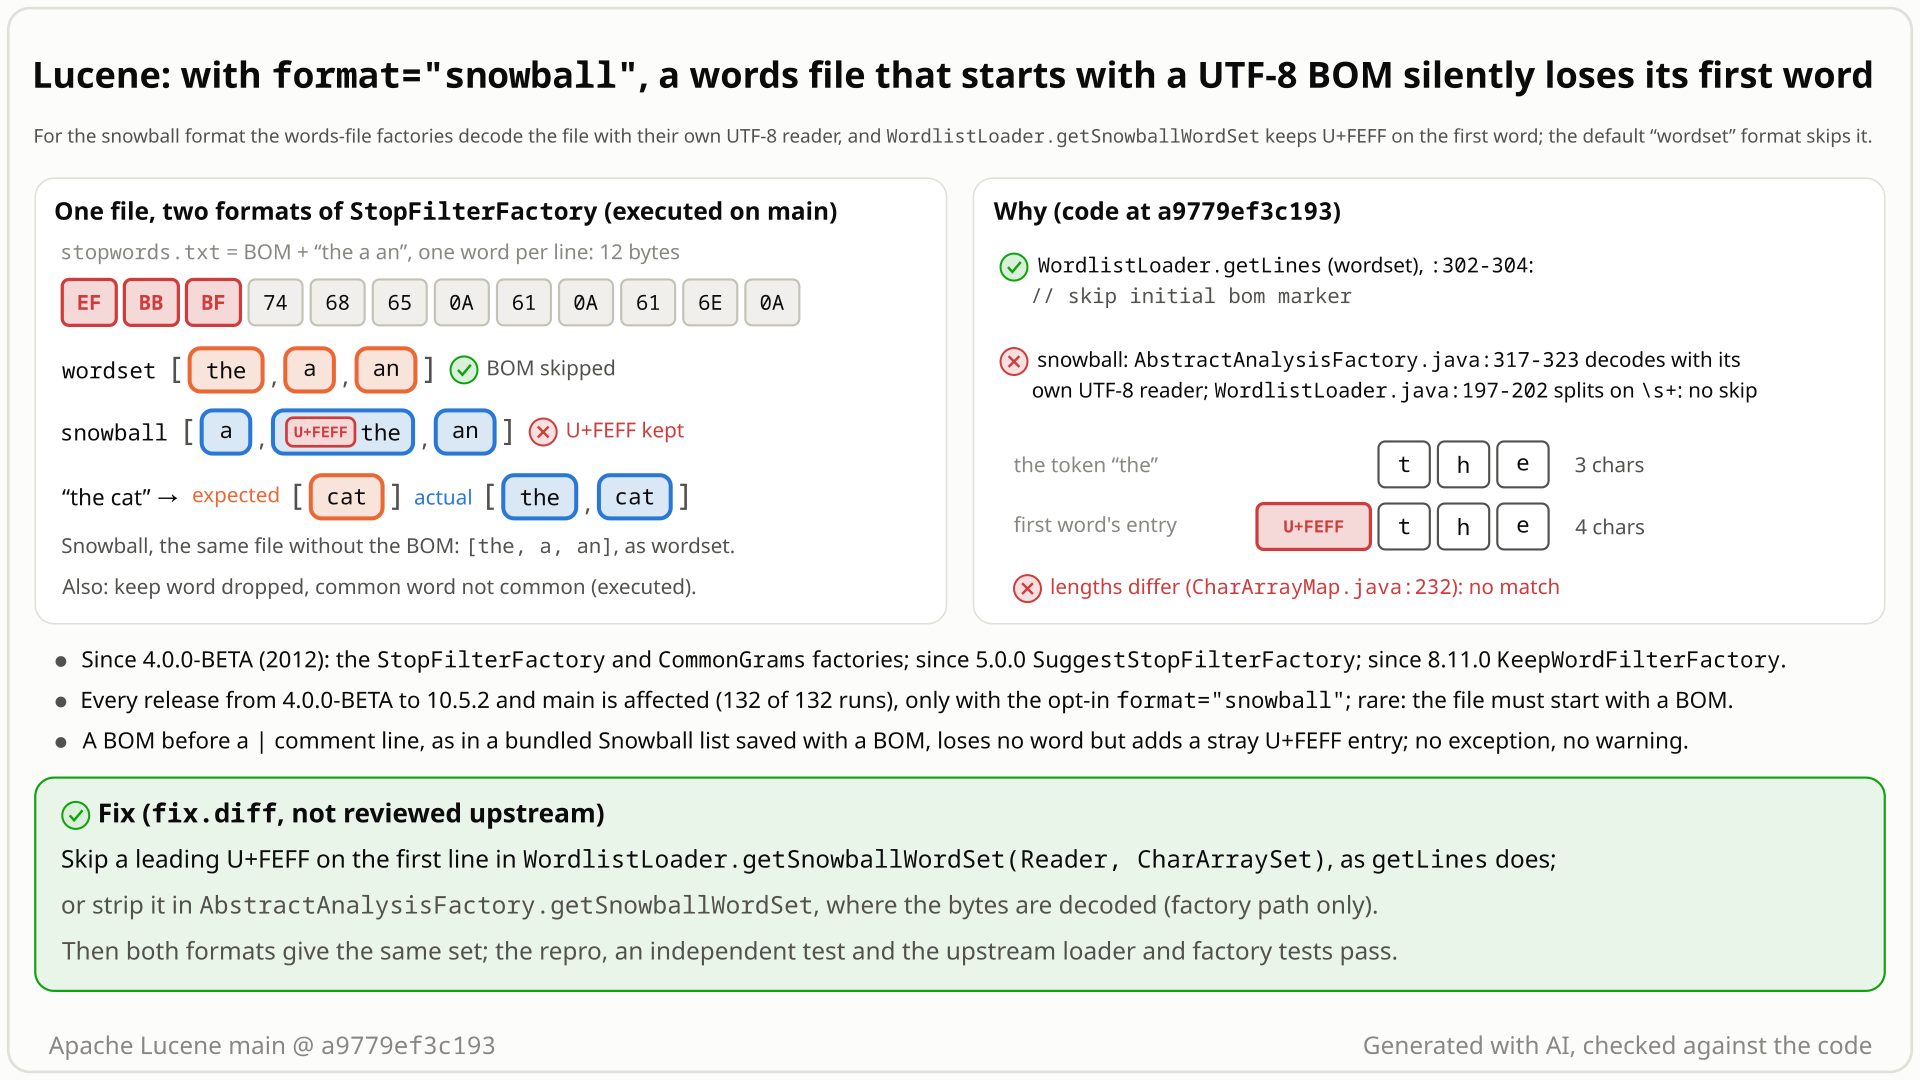
EF BB BF then the, a, an one per line, read in both formats: wordset gives [the, a, an], snowball gives [a, \uFEFFthe, an], so the cat keeps the. Select the still to open it at full size. Generated with AI, checked against the code.- You save
stopwords.txtwiththe,a,an, one per line, in an editor that writes UTF-8 with a byte order mark: 12 bytes that start withEF BB BF, which decode to the invisible character U+FEFF. One word per line is valid in both formats. - With the default
format="wordset",StopFilterFactoryloads[the, a, an]andthe catbecomes[cat]. You switch toformat="snowball"(several words per line,|comments) and expect the same set. - You get
[a, \uFEFFthe, an]: the mark is glued tothe, sothe catstays[the, cat]. No error, and the printed set looks right, because U+FEFF is invisible. - Why: the
wordsetloader drops a leading U+FEFF ("skip initial bom marker"). The snowball path decodes the file itself and splits on whitespace, and U+FEFF is not whitespace. - Same with the other factories: with keep words
apple,banana,KeepWordFilterFactoryturnsapple cherry bananainto[banana]; the common-grams and suggest-stop factories lose their first word too. A file that starts with a|comment loses no word: the bundled English list re-saved with a mark loads 175 entries instead of 174, the extra one\uFEFF.
Users who give StopFilterFactory, KeepWordFilterFactory, CommonGramsFilterFactory, CommonGramsQueryFilterFactory or SuggestStopFilterFactory their own words file with the opt-in format="snowball", saved with a byte order mark and starting with a word. Built-in analyzers are not affected: no bundled list has a mark. Deterministic, any index size, no error.
Mechanism, terms and numbers683 words
StopFilterFactory, KeepWordFilterFactory, CommonGramsFilterFactory, CommonGramsQueryFilterFactory and SuggestStopFilterFactory read a words file in one of two formats: wordset, the default (one word per line, # comments), or the opt-in snowball (several words per line, | comments). Some editors save UTF-8 with a byte order mark, the bytes EF BB BF, which decode to U+FEFF. The wordset loader drops a leading U+FEFF, on purpose since 2010 (SOLR-1865). The snowball path does not: the factory decodes the file with its own reader and the parser splits on \s+, which does not match U+FEFF, so the mark stays glued to the first word. A file <BOM>the a an | articles gives the stop set [a, \uFEFFthe, an], and the cat is analyzed to [the, cat] instead of [cat]. The first keep word, common word and suggest stop word are lost the same way; when the first line is a comment or blank, or the mark is followed by a space or tab, the words survive and the set gains a stray \uFEFF entry. No error is raised. The snowball path has skipped no mark since it was added (SOLR-1860, 2012), so every Lucene release from 4.0.0-BETA to 10.5.2 and main is affected. Skipping one leading U+FEFF where the factory decodes the file fixes it.
- Words file: the
wordsparameter ofStopFilterFactory,KeepWordFilterFactory,CommonGramsFilterFactory,CommonGramsQueryFilterFactoryandSuggestStopFilterFactory;formatsays "how thewordsfile will be parsed" (AbstractWordsFileFilterFactory.java:38-54). - Byte order mark (BOM): the bytes
EF BB BFthat some editors write at the start of a UTF-8 file. Java's UTF-8 decoder keeps them as the character U+FEFF, which is invisible when printed.
wordsetgoes throughAbstractAnalysisFactory.getWordSetandWordlistLoader.getLines, which decodes the bytes itself and drops a leading U+FEFF from each line it reads while no word has been added yet (lines.isEmpty()), so a BOM at the start of the file is skipped:// skip initial bom marker(WordlistLoader.java:297-314,:302-304).snowballgoes throughAbstractAnalysisFactory.getSnowballWordSet, documented as the "same as getWordSet(ResourceLoader, String, boolean), except the input is in snowball format" (AbstractAnalysisFactory.java:304-307). It builds its own strict UTF-8InputStreamReader(:317-322) and hands it toWordlistLoader.getSnowballWordSet(Reader, CharArraySet)(:323).- That parser cuts each line at
|and splits it on\s+(WordlistLoader.java:193-207).\smatches ASCII whitespace only, so the first piece of the first line is\uFEFFthe; when the first line is a comment or blank, or the mark is followed by a space or tab, the piece is\uFEFFalone and becomes an entry of its own while the word survives (<BOM> the a angives[the, a, an, \uFEFF]). - The factory loops over a comma-separated
wordslist (AbstractAnalysisFactory.java:316-325), so every file's own mark is kept.
| factory, words file | format="snowball" | format="wordset" |
|---|---|---|
StopFilterFactory, the, a, an | [a, \uFEFFthe, an]; the cat -> [the, cat] | [the, a, an]; the cat -> [cat] |
KeepWordFilterFactory, apple, banana | apple cherry banana -> [banana] | apple cherry banana -> [apple, banana] |
CommonGramsFilterFactory, the | [\uFEFFthe]; the cat -> [the, cat] | [the]; the cat -> [the, the_cat, cat] |
CommonGramsQueryFilterFactory, the | the cat -> [the, cat] | the cat -> [the_cat] |
SuggestStopFilterFactory, the, a, an | [a, \uFEFFthe, an] | [the, a, an] |
StopFilterFactory, a comment line (articles after the bar), then the a an | [the, a, an, \uFEFF]: one stray entry | (not a wordset file) |
bundled english_stop.txt re-saved with a mark | 175 entries instead of 174, the extra one \uFEFF | (not run) |
StopFilterFactory, a space or a tab after the mark, then the a an | [the, a, an, \uFEFF]: one stray entry | (not a wordset file) |
Without the mark, snowball gives the wordset column in the first five rows. The internal WordlistLoader.getSnowballWordSet overloads that the built-in language analyzers use keep a mark too, but none of the 147 bundled resource files starts with one.
Exposure and likelihood304 words
- Who is exposed. Applications that configure one of the five factories with an explicit
wordsfile andformat="snowball": directly, throughCustomAnalyzer, or through a search server's schema (the factories' javadoc examples are schema snippets). The default format iswordset, so it is opt-in. - What it takes. A words file saved as UTF-8 with a byte order mark, which the 2010 CHANGES entry that introduced the skip describes as "often created by editors such as Windows Notepad", and a word on its first line.
- What happens. A stop word is indexed and searched like any other word; a keep word's tokens are dropped; a common word forms no bigrams; a suggest stop word is not treated as one. With a comment or blank first line, or a space or tab after the mark, no word is lost and the set gains a
\uFEFFentry. Nothing fails, and a printed set looks right because U+FEFF is invisible. - Scale. Deterministic and independent of index size. The wrong set is used for every document and query analyzed with that analyzer, so any text that contains the affected word is analyzed differently. Indexes built with the wrong set keep their terms until reindexed.
- Built-in analyzers. Not affected: all 15 bundled Snowball lists start with a
| From https://snowballstem.org/...comment line, and none of the 147 bundled resource files starts withEF BB BF. A copy re-saved with a mark loses no word and only gains the stray entry. - Versions. Every release from 4.0.0-BETA to 10.5.2 and main;
SuggestStopFilterFactoryfrom 5.0.0, when it was added, andKeepWordFilterFactoryfrom 8.11.0, when it got theformatparameter. - How likely. Rare: it needs the opt-in format, a file saved with a mark and a word on the first line, and the searches found no prior report (see "Prior reports").
The test shows that StopFilterFactory with format="snowball" keeps a leading UTF-8 byte order mark on the first word of the words file (the default "wordset" format skips it).
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.core;

import java.util.HashMap;
import java.util.Map;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.StringMockResourceLoader;

public class TestSnowballStopWordsBom extends LuceneTestCase {

  public void testLeadingBomIsSkipped() throws Exception {
    StopFilterFactory f =
        new StopFilterFactory(new HashMap<>(Map.of("words", "stop.txt", "format", "snowball")));
    f.inform(new StringMockResourceLoader("\uFEFFthe\n"));
    // expected "the" (the default wordset format skips a BOM); actual: the BOM stays on "the"
    assertTrue(
        "expected [the], actual " + f.getStopWords().toString().replace("\uFEFF", "\\uFEFF"),
        f.getStopWords().contains("the"));
  }
}
# in a copy of this finding's repro folder (repro/LFV-718/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.core.TestSnowballStopWordsBom
- Expected vs actual
- Expected the stop set
[the]for the file\uFEFFthe\n; actual[\uFEFFthe], so "the" is not a stop word, with-eaand-da.
More files, environment, full output33 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected [the], actual [\uFEFFthe]
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.assertTrue(Assert.java:42)
org.apache.lucene.analysis.core.TestSnowballStopWordsBom.testLeadingBomIsSkipped(TestSnowballStopWordsBom.java:31)formatis documented as how onewordsfile is parsed, the snowball loader as the "same as getWordSet ... except the input is in snowball format";getWordSetskips the mark.- The default words-file loader has skipped a leading mark on purpose since 2010; the snowball path (2012) never got it.
- Nothing says snowball files must not carry a mark.
The full argument277 words
- One parameter, two parse modes of the same file.
format"defines how thewordsfile will be parsed", withwordsetandsnowballas the two values; neither says the file must not carry a mark (AbstractWordsFileFilterFactory.java:38-54,StopFilterFactory.java:44-60). A file with one word per line is valid in both formats, yet the same marked file gives[the, and]in one and[\uFEFFthe, and]in the other. - Documented as the same loader except for the format.
AbstractAnalysisFactory.java:304-307: "same as getWordSet(ResourceLoader, String, boolean), except the input is in snowball format". The mark belongs to the encoding, not to either format, and on this path Lucene's own code does the decoding. - Deliberate in the default loader. SOLR-1865 (2010) added the skip with the CHANGES entry "SolrResourceLoader.getLines ignores Byte Order Markers (BOMs) at the beginning of input files, these are often created by editors such as Windows Notepad"; LUCENE-4257 moved it into
WordlistLoader.getLines. LUCENE-5505 did the same for hunspell dictionaries ("HunspellStemFilter ignores BOM markers in dictionaries"). In 2010, rmuir listed that the Solr stopword loading code "ignores BOM markers" among the reasons it was better than Lucene's own loader. It is not a rule of every Lucene resource loader: the same hunt saw other loaders keep a mark. - An omission. The snowball factory path came two years after the rule (SOLR-1860, 2012) with its own reader, and its tests use a file without a mark. No test, javadoc, CHANGES entry or issue says snowball files must not carry one; in the tests of core, analysis-common and suggest, the only input that starts with a mark is hunspell's (core's
TestStandardAnalyzerlists U+FEFF only as a word-break format character).
The devil's-advocate check306 words
The checkers built the strongest case for "intended": (a) read literally, the snowball grammar names only whitespace and | comments, so U+FEFF is part of the first word; (b) WordlistLoader is @lucene.internal, and its generic getWordSet(Reader) keeps a mark too; (c) the wordset skip is a code comment plus a CHANGES entry, not javadoc; (d) committers have said that, used directly, "the stopword file parser does not care about encodings at all" (uschindler, 2010) and that a mark in a Reader means "your conversion from bytes is screwed up somewhere before" (dweiss, 2017, reviewing a char-filter mapping that deleted U+FEFF from analysis input: an analogy, not a remark on resource files); (e) in the 2010 user-list thread behind the skip, rmuir answered "No." to whether a marked file is a bug, and then: "we can ignore them for the first line of the file to be more user-friendly"; SOLR-1865 is typed Improvement, and users can simply save the file without a mark.
Why we think it fails: (a) to (c) describe the internal parser; the user-facing contract is the factory's format parameter, whose two values are documented as parse modes of the same file, and the factory itself turns the bytes into chars, so by the reasoning of (d) the factory is where the mark should go (the recommended fix). (e) was about whether to handle marks at all; in the same thread Yonik Seeley called it "a Java bug" and added "we should fix if it's practical to do so, rather than passing the buck", the default words-file loader then skipped them, and snowball is the only words-file format of these factories that does not. The literal reading (a) stays arguable. Expect "improvement, not bug" as an answer. Every checker rejected the works-as-designed case; the cross-model reviews rated it moderate, the devil's advocate weak.
Recommended B. Skip the mark where the factory decodes the file (AbstractAnalysisFactory)
Skip one leading U+FEFF where the factory decodes each words file (AbstractAnalysisFactory.getSnowballWordSet), as the wordset loader already does: read one char through a BufferedReader and reset unless it is U+FEFF. Validated: the repro, the factory suites and the whole analysis-common module pass, and so does :lucene:core:check.
-        try (Reader reader = new InputStreamReader(loader.openResource(file.trim()), decoder); ) {
+        try (BufferedReader reader =
+            new BufferedReader(new InputStreamReader(loader.openResource(file.trim()), decoder))) {
+          // skip initial bom marker, as the wordset format does (WordlistLoader.getLines)
+          reader.mark(1);
+          if (reader.read() != '\uFEFF') {
+            reader.reset();
+          }
           WordlistLoader.getSnowballWordSet(reader, words);
         }
All options and trade-offs3 options · 823 words
Options B and A were each applied in a scratch worktree of main a9779ef3c193 and run through gradle with assertions on and off; the worktree was removed afterwards. Option C was not run.
B. Skip the mark where the factory decodes the file (AbstractAnalysisFactory) (validated by the checks) (recommended)
In AbstractAnalysisFactory.getSnowballWordSet (AbstractAnalysisFactory.java:322), wrap the decoding reader in a BufferedReader, read one char and reset() unless it is U+FEFF, then parse as before. WordlistLoader.getSnowballWordSet reuses a reader that is already a BufferedReader, so nothing is buffered twice.
What it changes. Only the factory path used by the five factories: one U+FEFF at the very start of each file is dropped, the case getLines covers for wordset (unlike getLines, it does not look at later lines). Files without a mark are read unchanged; an empty file still gives no words; malformed UTF-8 still fails with the same MalformedInputException (checked with a copy of this reader setup on the stock jars). The internal WordlistLoader API and the built-in analyzers are untouched.
-        try (Reader reader = new InputStreamReader(loader.openResource(file.trim()), decoder); ) {
+        try (BufferedReader reader =
+            new BufferedReader(new InputStreamReader(loader.openResource(file.trim()), decoder))) {
+          // skip initial bom marker, as the wordset format does (WordlistLoader.getLines)
+          reader.mark(1);
+          if (reader.read() != '\uFEFF') {
+            reader.reset();
+          }
           WordlistLoader.getSnowballWordSet(reader, words);
         }
Trade-offs
- Fixes the factory path only: a caller of the internal
WordlistLoader.getSnowballWordSet(Reader)who passes a Reader that still carries the mark gets the glued word, which matches the committers' view that the Reader-level parser is encoding-agnostic. - The parser's try-with-resources and the factory's both close the same
BufferedReader; the secondclose()does nothing. - About 6 lines plus an import change (
BufferedReaderin, the unusedReaderout). - Indexes built with the wrong set keep their terms until reindexed. No CHANGES entry is drafted.
What the checks validated
- Gradle in a scratch worktree of main
a9779ef3c193, assertions on and off: the 4-test repro passes (stock: 3 of 4 fail), and so do the upstreamTestStopFilterFactory,TestKeepFilterFactory,TestCommonGramsFilterFactoryandTestCommonGramsQueryFilterFactory(3, 2, 4 and 4 tests: 17 with the repro, 0 failures, each way). TestWordlistLoader(4 tests) andTestSuggestStopFilterFactory(3 tests) pass.- All of
:lucene:analysis:common:testwith assertions on: 340 classes, 1,913 tests (the repro included), 18 skipped, 0 failures. :lucene:core:check -x testpasses (google-java-format, ecjLint, forbiddenApis).- Shadowed into the repro harness: the independent 9-test suite, which covers the stop, keep-word, common-grams and suggest-stop factories, the comment-line case and the same-set-in-both-formats check, passes 9 of 9 with assertions on and off (stock: 7 of 9 fail), and the on-disk test through
CustomAnalyzer.builder(Path)passes 5 of 5.
In WordlistLoader.getSnowballWordSet(Reader, CharArraySet) (WordlistLoader.java:193-207), drop a leading U+FEFF from the first line, as getLines does for a mark at the start of a file (:302-304). This is the three-line fix (plus a comment) every checker ran.
+      boolean first = true;
       while ((line = br.readLine()) != null) {
+        // skip initial bom marker, as getLines does
+        if (first && line.length() > 0 && line.charAt(0) == '\uFEFF') line = line.substring(1);
+        first = false;
Trade-offs
Also covers the internal getSnowballWordSet(Reader) and getSnowballWordSet(InputStream[, Charset]) overloads, harmless today because no bundled list has a mark. But it changes an @lucene.internal Reader-level parser that committers have called encoding-agnostic, and a Reader whose text really starts with U+FEFF (ZERO WIDTH NO-BREAK SPACE) loses it.
What the checks validated
- Gradle in a scratch worktree of main
a9779ef3c193, assertions on and off: the repro and the four upstream factory suites pass (17 tests, 0 failures, each way);TestWordlistLoader(4 tests) andTestSuggestStopFilterFactory(3 tests) pass; all of:lucene:analysis:common:test: 340 classes, 1,913 tests, 18 skipped, 0 failures (this includes the analysis-common analyzers that load a bundled Snowball list through the changed parser; the Ukrainian analyzer in the morfologik module, which also calls it, was not run);:lucene:core:check -x testpasses. - Earlier, shadowed into the repro harness by every checker: the repro 4 of 4, the independent suite 9 of 9; in the hunt's bounded-exhaustive check, a run that shadowed this fix together with a fix for an unrelated finding drops the snowball mismatches with a mark from 43,380 to 0. The fact check of this doc ran the on-disk test with this fix: 5 of 5 pass.
A shared helper that opens a resource as UTF-8 and drops one leading U+FEFF, used wherever a factory decodes a resource file itself.
Trade-offs
Would also fix the same pattern in other loaders (the ICU tokenizer's rule files are a separate confirmed report; the hunt's probe also saw it in the synonym and the Japanese and Korean user-dictionary loaders, not verified independently), so it suits a single "BOM in resource files" issue; it touches several modules and needs its own tests. Not drafted.
Search servers that build analyzers from these factories inherit it whenever an operator edits a snowball-format words file in an editor that adds a byte order mark.
A bounded-exhaustive check of the real factories: every words file of 1 to 3 lines over a small alphabet, each line-end style, with and without a leading byte order mark, compared with reference parsers from the javadoc (plus one unstated rule: drop a leading mark). All 43,380 snowball files with a mark differed; the same files in wordset, none.
The method in full215 words
- Method (semi-formal): bounded-exhaustive translation validation of the resource-file formats that analysis factories load, on the stock main jars, in the hunt's unit on factory resource-file formats. Every words file of 1 to 3 lines over a per-format line alphabet, with LF, CRLF or CR line ends, with and without a trailing line end, with and without a leading mark, with
ignoreCaseon and off, loaded throughStopFilterFactoryfrom an in-memoryResourceLoader. - Oracle: independent reference parsers written from the format javadoc, without
BufferedReader,trimorsplit, plus one rule no javadoc states: both drop one leading mark first (dropBom), taken from the default format's behaviour. - Signal. Snowball with a mark: all 43,380 generated files differ (28,548 with ASCII whitespace only, 14,832 with other whitespace, compared with the ASCII-whitespace reading that the same files without a mark match). Wordset with a mark, and snowball without one: 0 of those 43,380. Two-file lists: 35 of 35 for snowball, 0 of 35 for wordset. In a run that shadowed the parser fix together with a fix for an unrelated finding, every snowball class with a mark drops to 0.
- The finder then traced it to the separate reader of the snowball path and wrote the public-API JUnit; independent checkers followed (see "Independent checks").
No prior report found (searched 2026-10-27: GitHub issues, PRs and commits, JIRA, the Lucene and Solr lists, downstream trackers, the web and all 410 open PRs). Closest: SOLR-1865 (2010), which made the default format skip the mark.
Searches6 searches
Two 2010 committer remarks anticipated the general gap before the snowball factory path existed (2012): on SOLR-1860, rmuir wrote "how long till a lucene user complains about UTF-8 bom markers in their stoplists", and on LUCENE-2510 that the Solr loader "ignores BOM markers". Neither reports a failure or was followed up, so they count as context, not as a report; if such a remark counts as discussion of the same bug, the novelty becomes "known". Gaps: GitHub search returns at most 50 hits per query, JIRA text search is fuzzy ("BOM" also matches bill-of-materials issues, checked by hand), one web query was throttled, and private reports cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| scripted prior-report search (four runs) | 2026-10-27 | 95, 79, 48 and 45 queries: GitHub issues, PRs and commits, downstream repositories, the dev, java-user, issues, commits, solr-user and general lists, the JIRA archive | no report |
| GitHub (manual) | 2026-10-27 | 37 searches on apache/lucene, apache/solr, Elasticsearch and OpenSearch (13 of them in the last three); the changed-file lists of all 410 open apache/lucene PRs | no report; no open PR touches WordlistLoader, AbstractAnalysisFactory, AbstractWordsFileFilterFactory or the five factories |
| JIRA (LUCENE, SOLR) | 2026-10-27 | 10 queries; SOLR-1860, SOLR-1865, SOLR-5157, SOLR-2713, SOLR-5234 and LUCENE-8231 read in full | only SOLR-1865 (the default format, fixed 2010) |
| Mailing lists | 2026-10-27 | 15 queries over the Lucene and Solr lists; threads read | only the 2010 solr-user thread "Is this a bug of the RessourceLoader?" behind SOLR-1865 |
| Web | 2026-10-27 | 14 web queries, one throttled (the 13 downstream searches on apache/solr, Elasticsearch and OpenSearch are counted under GitHub) | no report |
| Closest items (read) | 2026-10-27 | full threads | SOLR-1865 (precedent), SOLR-1860 (added the format), #3584 / LUCENE-2510, #8836 / LUCENE-7785 (where BOM removal belongs, said of a char-filter mapping), #6275 / LUCENE-5211, #6291 / LUCENE-5227 (open: unify stopword formats), #3282 / LUCENE-2206, #12291 / PR #12299, #6568 / LUCENE-5505 |
Introduced with the snowball format itself, SOLR-1860 (c880ef06478, 2012-02-05), which read the file with its own reader; in Lucene's jars since 4.0.0-BETA. A probe shows it on 132 of 132 targets from 4.0.0-BETA to 10.5.2 and main. Not fixed upstream.
Versions tested6 rows
Introduced by SOLR-1860 "support snowball format in stoplists" (JIRA "improve stopwords list handling"), by rmuir: trunk c880ef06478 and branch_3x 1a752ccc41f, both 2012-02-05, no PR. It added getSnowballWordSet(ResourceLoader, String, boolean) to Solr's factory base class with its own UTF-8 reader and wired it into the stop and common-grams factories. The default format's line loader had skipped a leading mark since SOLR-1865 (f3c25f02d58, 2010-05-08).
Into Lucene's jars. LUCENE-2510 / LUCENE-4044 moved the factory base class (2012-05-08, 0bad718d589) and the stop and common-grams factories (branch_4x 2012-07-25, 677846e6a0f; trunk 142d3c788fa); LUCENE-4257 moved getLines, skip included, into WordlistLoader the next day. First release 4.0.0-BETA (2012-08-10), first GA 4.0.0. SuggestStopFilterFactory (LUCENE-5820) joined in 5.0.0, KeepWordFilterFactory got format in 8.11.0 (LUCENE-10008). Outside Lucene's jars the same code first shipped in Solr 3.6.0 (read).
Not fixed upstream. Later commits to either method are moves, clean-ups and API changes (among them LUCENE-2564, LUCENE-4877, LUCENE-10003 and LUCENE-10349); none adds BOM handling. The cited files are unchanged through upstream main c5ab3e57b9ba (2026-10-28).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the JUnit fails 3 of 4 through gradle (assertions on and off); the independent suite 7 of 9, over the stop, keep-word, common-grams and suggest-stop factories |
| 10.5.2, 9.12.3 | affected | the JUnit fails 3 of 4; the independent suite 7 of 9; the on-disk test on 10.5.2 2 of 5 |
| 8.11.4 | affected | an 8.x port of the independent suite (package names only) fails 7 of 9 |
| 4.0.0-BETA and all 130 releases from 4.0.0 to 10.5.2 | affected | reflection probe: snowball on the marked file gives [\uFEFFthe, and], both controls [and, the] |
| 3.6.2, 4.0.0-ALPHA | API absent | no Lucene factory with format yet (the factories were still in Solr) |
fix B on main a9779ef3c193 | not affected | the JUnit, the four factory suites, TestWordlistLoader, TestSuggestStopFilterFactory and all 1,913 analysis-common tests pass; fix A gives the same |
An independent reproducer, reviews by a reviewer from another model family, a devil's advocate with a real file on disk, an adjudication and a credibility audit all judged it real and re-ran it on main; this doc re-ran it through gradle and validated two fixes.
Checks and verdicts496 words
The cross-model reviews ran on main ea57360912ed, whose core analysis, analysis-common and suggest sources equal a9779ef3c193; the second review's tests were re-run on a9779ef3c193. Every other check ran on a9779ef3c193.
| Check | Verdict | What it found |
|---|---|---|
| Cross-model refute review | real (high) | An independent reviewer from another model family (OpenAI GPT-5.6), executed: its own raw-byte test reproduces with assertions on and off and 3 iterations, both controls pass, and it passes with the fix. Strongest counter-argument (moderate): @lucene.internal and the literal grammar. |
| Independent reproducer | real | Own 9-test public-API suite with a raw-byte ResourceLoader: 7 of 9 fail on main (assertions on and off), 10.5.2 and 9.12.3, and its 8.x port (package names only) on 8.11.4; executed all four factory families and the comment case; deterministic (21 of 27 with 3 iterations); its own fix passes 9 of 9. |
| Works-as-designed review | real (high) | The same OpenAI GPT-5.6 reviewer with an intended-behaviour lens, executed: intended argument moderate; its desired-behaviour test fails on main, 10.5.2 and 9.12.3 and passes with the fix; the upstream TestWordlistLoader, TestStopFilterFactory and TestSuggestStopFilterFactory pass with the fix. |
| Intended-behaviour devil's advocate | real (high) | Intended argument weak. Writes a real marked file to disk and loads it through CustomAnalyzer.builder(Path): 2 of 5 fail on main and 10.5.2 (stop and common grams), 3 controls pass. |
| Adjudication | confirmed (high) | Re-ran the independent reproduction's suite with new seeds (7 of 9 fail, assertions on and off), the JUnit (3 of 4) and the fix check (9 of 9 pass). |
| Credibility audit | keep | Re-ran the JUnit with assertions off (3 of 4 fail) and the on-disk test (2 of 5), re-read the code, and corrected the reading of the 2010 user-list thread ("No." to whether a marked file is a bug). |
| Fix validation (this doc) | fixes B and A pass | Gradle in a scratch worktree of a9779ef3c193, seed DEADBEEF: stock, the JUnit fails 3 of 4 with assertions on and off and passes :lucene:analysis:common:check -x test; with fix B and, separately, fix A it passes 4 of 4, as do the four factory suites (13 tests), TestWordlistLoader (4), TestSuggestStopFilterFactory (3) and all of :lucene:analysis:common:test (1,913 tests), and :lucene:core:check -x test passes. Fix B shadowed into the harness: the independent suite 9 of 9 (assertions on and off), the on-disk test 5 of 5. |
| Fact checks and diagram check (this doc) | holds; text fixed | An independent fact check re-ran the gradle repro (3 of 4 fail, assertions on and off), both fixes (4 of 4) and the diagram probe, and ran the on-disk test with fix A (5 of 5). A second fact check by the GPT-5.6 reviewer (read-only, effort high) and a check of every diagram frame followed. They found no error in the bug, its mechanism, its history or the fixes; the wording and labelling corrections they asked for are made, one finding is rejected with its reason. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 437 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,471 words
- Registry title
- With format="snowball", StopFilterFactory, KeepWordFilterFactory, CommonGramsFilterFactory and SuggestStopFilterFactory keep a leading UTF-8 byte order mark glued to the first word of the words file, so that word silently stops matching, while the default "wordset" format of the same factories strips the mark
- Area
- core + analysis-common + suggest / words-file factories (format="snowball" loader: AbstractAnalysisFactory.getSnowballWordSet, WordlistLoader.getSnowballWordSet)
- Priority
- Low, rank 502: With the opt-in format="snowball" and a words file that starts with a BOM, the first word silently stops matching, but the bundled lists lose no word.
- Impact class
- silent wrong results
- Impact note
- Users who configure one of these factories with the opt-in format="snowball" and a words file that an editor saved with a UTF-8 byte order mark, and whose first line starts with a word, silently lose that word (a stop word is kept in the index, a keep word's tokens are dropped, a common word is not treated as common); a file that starts with a '|' comment line, as every bundled Snowball list does, loses no word and only gains a stray U+FEFF entry; no scale is needed and no error is raised.
- Summary
- You configure StopFilterFactory (or KeepWordFilterFactory, CommonGramsFilterFactory, CommonGramsQueryFilterFactory or SuggestStopFilterFactory) with format="snowball" and a UTF-8 words file that begins with a byte order mark, and expect the same words that the default "wordset" format reads from such a file, because that format skips a leading BOM (WordlistLoader.getLines, 'skip initial bom marker', a rule recorded in SOLR-1865). Instead the snowball loader keeps the invisible U+FEFF glued to the first word, so the set holds "\uFEFFthe" instead of "the" (getStopWords() = [a, \uFEFFthe, an]): StopFilter no longer removes 'the', KeepWordFilter drops the tokens of the first keep word, CommonGrams does not treat it as common, and a BOM before a comment or blank first line adds a stray "\uFEFF" entry. No error is raised.
- Introduced
- c880ef064789401f1351af56755ea165b3e04444 (SOLR-1860 'support snowball format in stoplists', trunk r1240784, rmuir) with its branch_3x twin 1a752ccc41f38c92d3cbf82f6341fb1d9a378cd3 (r1240791). It added the factory method getSnowballWordSet(ResourceLoader, String, boolean) (then in Solr's BaseTokenStreamFactory), which decodes each words file with its own UTF-8 InputStreamReader and passes it to WordlistLoader.getSnowballWordSet(Reader, CharArraySet). The default format went through ResourceLoader.getLines, which had skipped a leading BOM since SOLR-1865 (f3c25f02d58, 2010-05-08). The code reached Lucene's own jars through the factory migration LUCENE-2510/LUCENE-4044: the base class on 2012-05-08 (0bad718d589) and StopFilterFactory, CommonGramsFilterFactory and CommonGramsQueryFilterFactory on branch_4x on 2012-07-25 (677846e6a0f, r1365673, uschindler; trunk 142d3c788fa). [read: git history in the full-history clone; the boundary is executed: 3.6.2 and 4.0.0-ALPHA have no Lucene factory with format=snowball, 4.0.0-BETA is affected] (2012-02-05 (SOLR-1860 commit; the code reached Lucene's own jars on branch_4x on 2012-07-25))
- First affected version
- 4.0.0-BETA [exec] (tagged 2012-08-10), the first Lucene release whose jars contain a factory with format=snowball; first GA release 4.0.0 [exec] (tagged 2012-10-11). 3.6.2 and 4.0.0-ALPHA do not have the API [exec]. Outside Lucene's artifacts the same code first shipped in Solr 3.6.0 [read].
- Affected versions
- Every Lucene release from 4.0.0-BETA to 10.5.2: 4.0.0-BETA plus all 130 x.y.z releases from 4.0.0 to 10.5.2 (every 4.x, 5.x, 6.x, 7.x, 8.x, 9.x and 10.x release in Maven Central), and main a9779ef3c193 [exec, 132 of 132 runs BUG, controls pass in all]. Not fixed upstream (no later commit touches either loader, including the 2 commits after a9779ef3c193 [read]). Factory reach grew over time [exec]: StopFilterFactory, CommonGramsFilterFactory (and CommonGramsQueryFilterFactory, subclass, [read]) from 4.0.0-BETA; SuggestStopFilterFactory from 5.0.0 (LUCENE-5820); KeepWordFilterFactory from 8.11.0 (LUCENE-10008, which gave it the format parameter).
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (searched 2026-10-27, read-only; the prior-report record, verdict new): four scripted prior-report searches (95, 79, 48 and 45 queries over GitHub issues, PRs and commits, downstream repositories, the dev, java-user, issues, commits, solr-user and general lists and the JIRA archive); 37 manual GitHub searches on apache/lucene, apache/solr, Elasticsearch and OpenSearch; the file lists of all 410 open apache/lucene PRs; 10 JIRA queries on the LUCENE and SOLR projects with SOLR-1860, SOLR-1865, SOLR-5157, SOLR-2713, SOLR-5234 and LUCENE-8231 read in full; 15 list-archive queries; 14 web queries. No issue, PR, JIRA ticket, list post, commit or downstream report describes a BOM kept by the snowball format of the words-file factories, and no open PR touches the fix site. Related only: SOLR-1865 (2010, BOM skip added to getLines, the default format's loader; the precedent), the 2010 solr-user thread 'Is this a bug of the RessourceLoader?' that led to it, SOLR-1860 (added format=snowball in 2012; a 2010 comment by rmuir there anticipated BOM complaints about WordListLoader stoplists), #3584 / LUCENE-2510 (2010 comment that the Solr stopword loading code 'ignores BOM markers'), #5327 / LUCENE-4257 (moved getLines into WordlistLoader, snowball path untouched), #6275 / LUCENE-5211 (format docs), #6291 / LUCENE-5227 (open: unify stopword formats), #6568 / LUCENE-5505 (hunspell ignores BOMs) and #8836 / LUCENE-7785 (dweiss: a BOM in a Reader means the byte-to-char step is wrong). Not fixed: upstream main a95c754ee003 (2026-10-26). Gaps: GitHub search returns at most 50 hits per query; JIRA text search is fuzzy (BOM also matches Maven bill-of-materials issues, checked by hand); one web query was throttled; private reports are not searchable.
- Lucene commit tested
- main
a9779ef3c193(2026-10-26) through gradle in a scratch worktree (removed afterwards), seed DEADBEEF: the 4-test JUnit with assertions on and off (stock: 3 of 4 fail) and:lucene:analysis:common:check -x testwith it added; fix B and fix A, each with the JUnit, the four factory suites,TestWordlistLoader,TestSuggestStopFilterFactory, all of:lucene:analysis:common:testand:lucene:core:check -x test. Through the repro harness: the JUnit on main (assertions on and off), 10.5.2 and 9.12.3; an independent 9-test suite on main, 10.5.2, 9.12.3 and (as an 8.x port) 8.11.4, and on main with fix B shadowed; an on-disk test on main and 10.5.2, and with fix B and with fix A; a probe of every factory on main, and a probe of a mark before a space or tab and of fix B's reader on malformed UTF-8; a reflection probe on 4.0.0-BETA, all 130 releases from 4.0.0 to 10.5.2 and main. The cross-model reviews ran onea57360912ed, whose core analysis, analysis-common and suggest sources are identical. OpenJDK 25.0.3, Linux aarch64.
- Finding record
a Lucene main checkout lucene/core/src/java/org/apache/lucene/analysis/WordlistLoader.java:178-207 (getSnowballWordSet(Reader, CharArraySet) javadoc and body: split on \s+ and '|' comments, no BOM check), :297-314 (getLines, '// skip initial bom marker' at :302-304); lucene/core/src/java/org/apache/lucene/analysis/AbstractAnalysisFactory.java:283-297 (getWordSet through getLines), :299-302 (getLines, UTF-8), :304-328 (getSnowballWordSet: javadoc 'same as getWordSet(ResourceLoader, String, boolean), except the input is in snowball format', its own UTF-8 InputStreamReader at :322); lucene/analysis/common/src/java/org/apache/lucene/analysis/en/AbstractWordsFileFilterFactory.java:38-53 ('format defines how the words file will be parsed'; wordset and snowball), :84-91 (inform); lucene/analysis/common/src/java/org/apache/lucene/analysis/core/StopFilterFactory.java:44-58 (same javadoc); lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/SuggestStopFilterFactory.java:49-63, :105-108 (same loader); identical in Lucene main ea57360912ed and in upstream main a95c754ee003 (a Lucene clone, git diff empty)a Lucene main checkout lucene/analysis/common/src/resources/org/apache/lucene/analysis/snowball/*_stop.txt (all 15 bundled Snowball lists start with a '| From https://snowballstem.org/...' comment line; read with head in the registration check)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/analysis/WordlistLoader.java:178-207 (getSnowballWordSet javadoc and body), :297-314 (getLines; BOM skip :302-304), :33 (@lucene.internal) @ a9779ef3c193lucene/core/src/java/org/apache/lucene/analysis/AbstractAnalysisFactory.java:279-302 (getWordSet, getLines), :304-328 (getSnowballWordSet; javadoc :304-307; decoder :317-321; InputStreamReader :322; loop :316-325) @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/en/AbstractWordsFileFilterFactory.java:38-54 (format javadoc), :85-102 (inform) @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/commongrams/CommonGramsQueryFilterFactory.java:37 @ a9779ef3c193git ls-files 'lucene/**/src/resources/**' at a9779ef3c193 with head -c3: 147 files, none starts with EF BB BF (checked 2026-10-28)
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/core/StopFilterFactory.java:29-36 (schema example), :44-60 (format javadoc) @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/en/AbstractWordsFileFilterFactory.java:76 (default format wordset) @ a9779ef3c193lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/SuggestStopFilterFactory.java:49-65, :105-108 @ a9779ef3c193lucene/analysis/common/src/resources/org/apache/lucene/analysis/snowball/*_stop.txt (15 files, first byte '|'; head -c3 over all 147 tracked files under lucene/**/src/resources: no EF BB BF, checked 2026-10-28)
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/en/AbstractWordsFileFilterFactory.java:38-54 @ a9779ef3c193; lucene/analysis/common/src/java/org/apache/lucene/analysis/core/StopFilterFactory.java:44-60 @ a9779ef3c193lucene/core/src/java/org/apache/lucene/analysis/AbstractAnalysisFactory.java:304-307 @ a9779ef3c193lucene/core/src/java/org/apache/lucene/analysis/WordlistLoader.java:178-192 (snowball grammar), :302-304 (skip) @ a9779ef3c193lucene/CHANGES.txt:12554-12555 (LUCENE-5505) @ a9779ef3c193; lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Dictionary.java:351-352grep -i FEFF over the tests of lucene/core, lucene/analysis/common and lucene/suggest at a9779ef3c193: hunspell TestDictionary.java:307-308 (input starting with U+FEFF) and core TestStandardAnalyzer.java:50 (0xFEFF in a list of word-break format characters)
- Suggested fix
lucene/core/src/java/org/apache/lucene/analysis/WordlistLoader.java:193-207, :302-304, :316-318 (getBufferedReader) @ a9779ef3c193lucene/core/src/java/org/apache/lucene/analysis/AbstractAnalysisFactory.java:316-325 @ a9779ef3c193lucene/analysis/morfologik/src/java/org/apache/lucene/analysis/uk/UkrainianMorfologikAnalyzer.java:86 (WordlistLoader.getSnowballWordSet caller outside analysis-common) @ a9779ef3c193
- History
a Lucene clone: git diff --stat a9779ef3c193 c5ab3e57b9ba over WordlistLoader, AbstractAnalysisFactory, AbstractWordsFileFilterFactory, StopFilterFactory, KeepWordFilterFactory, the common-grams factories and SuggestStopFilterFactory: empty (5 commits, checked 2026-10-28)
- TestSnowballStopWordsBom.java (JUnit test):
repro/LFV-718/src/org/apache/lucene/analysis/core/TestSnowballStopWordsBom.java(35 lines)
Every element on screen was checked against the code at a9779ef3c193, the registry row and a probe executed for the diagram.
assets/LFV-718/bug.png(437 KB)