A custom ICU rule file saved with a UTF-8 byte order mark: the mark ends up inside the first rule.
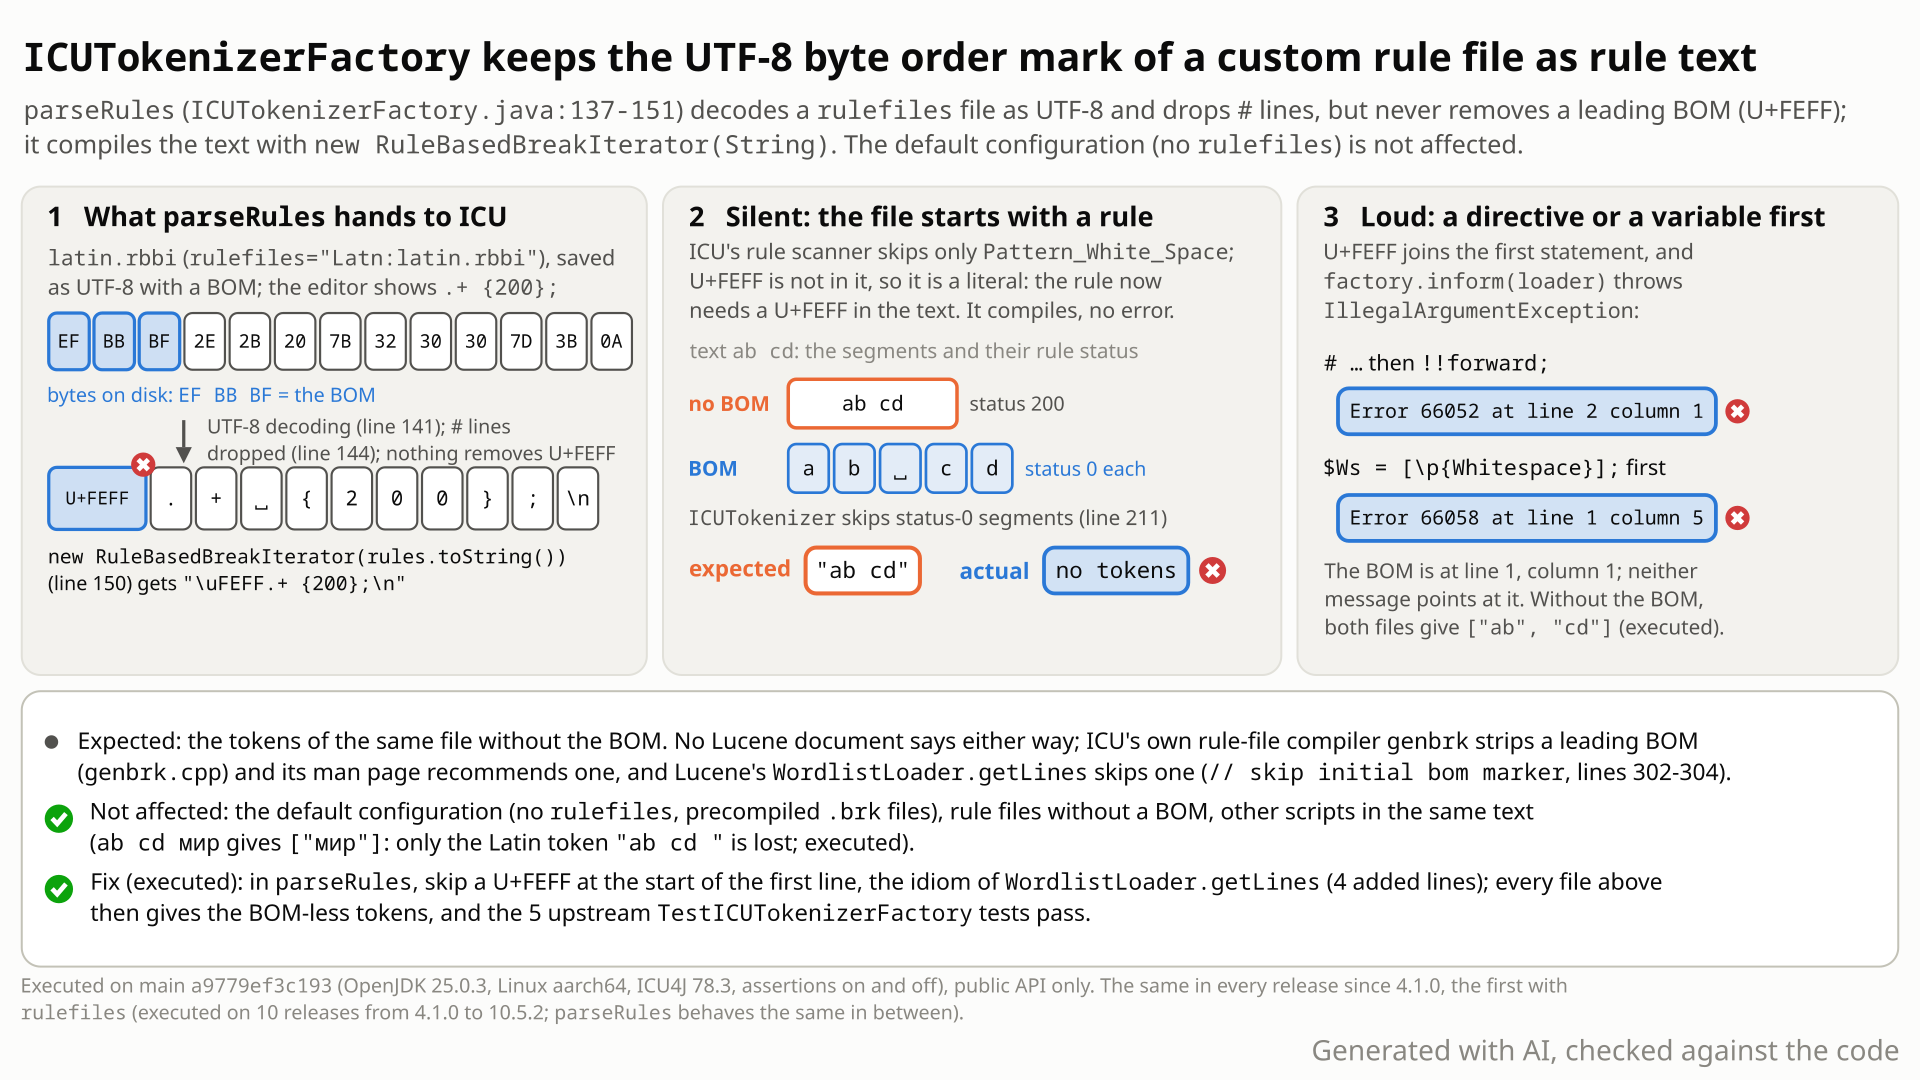
- You tailor one script with your own rule file:
rulefiles="Latn:keyword.rbbi", where the file holds the single rule.+ {200};(all Latin text is one token). Your editor saves it as UTF-8 with a byte order mark (BOM): 3 invisible bytes,EF BB BF, at the start. ICU's own rule-file compiler,genbrk, accepts and recommends that. - You expect the same tokens as from the file without the BOM:
ab cdgives one token,[ab cd]. - You get 0 tokens and no error. Lucene decodes the BOM to the character U+FEFF and hands it to ICU as the first character of the first rule, so that rule only matches text that starts with U+FEFF. The tokenizer drops every piece of text with rule status 0, which is what text that no rule matched gets.
- Lucene's own test file
KeywordTokenizer.rbbi(comment lines, then.+ {200};) with a BOM loses the Cyrillic and Thai tokens of its upstream test: 4 tokens instead of 6. With a second rule after the first, only the first rule's tokens vanish:ab 12 cdgives[12]instead of[ab] [12] [cd]. - A file that starts with a
!!directive fails instead: Lucene'sLatin-break-only-on-whitespace.rbbiwith a BOM throwsIllegalArgumentException: Error 66052 at line 20 column 1, an ICU syntax error that points at line 20, while the cause sits invisibly on line 1.
Only applications that set rulefiles (custom per-script ICU rules) and save a rule file as UTF-8 with a BOM, as editors such as Windows Notepad often do. The default configuration is unaffected. A file that starts with a rule silently loses that rule's tokens; one that starts with a directive fails at setup. Rare: no report found since 4.1.0.
Mechanism, terms and numbers745 words
ICUTokenizerFactory's rulefiles argument replaces the break rules of one script with a rule file of your own. parseRules reads that file as UTF-8, blanks the lines that start with # and passes the text to ICU's new RuleBasedBreakIterator(String), but it never removes a leading byte order mark. ICU's string API treats U+FEFF as an ordinary literal character, so the BOM becomes part of the file's first statement. If that statement is a rule, it compiles but can no longer match: the one-rule file .+ {200}; gives no token for ab cd, and Lucene's own test file KeywordTokenizer.rbbi with a BOM drops the Cyrillic and Thai tokens (4 tokens instead of 6), with no error. If it is a !! directive, ICU throws Error 66052 at line 20 column 1 (a rule syntax error) for Lucene's Latin-break-only-on-whitespace.rbbi, pointing away from the invisible cause on line 1. ICU's own compiler for this file format, genbrk, strips a BOM and its man page recommends one; Lucene's word-list and hunspell readers skip it too. Present since rulefiles arrived in 4.1.0 (SOLR-4123, 2012). Skipping a U+FEFF at the start of the first line fixes it; the whole ICU module passes with that change.
rulefiles: an argument ofICUTokenizerFactory(ICU analysis module) that replaces the break rules of one script with your own ICU rule file, for examplerulefiles="Latn:my.Latin.rules.rbbi".- Rule status: each ICU rule ends with a number such as
{200}; text a rule matches gets that status.ICUTokenizeremits only pieces with a non-zero status and skips status-0 pieces (ICUTokenizer.java:209-213). - Byte order mark (BOM): the 3 bytes
EF BB BFthat many editors write at the start of a UTF-8 file. Decoded, it is the character U+FEFF.
informcallsparseRulesonce per script entry of therulefilesmap (ICUTokenizerFactory.java:108-135, the call at:119; a repeated script overwrites the earlier pair,:86-95).parseRulesreads the file withIOUtils.getDecodingReader(stream, UTF_8)(:141). Java's UTF-8 decoder keeps a leading BOM as U+FEFF.line.startsWith("#")is false forU+FEFF# ..., so the negated testif (!line.startsWith("#"))(:144) is true and the first line is kept instead of blanked. Lines are joined with\n, so line numbers stay as in the file (:147).new RuleBasedBreakIterator(rules.toString())(:150). ICU's rule scanner skips onlyPattern_White_Space; U+FEFF is not in that set, so it is a literal character. ICU still reads the rest of a#line as a comment, so U+FEFF joins the first statement, after any comment lines.- First statement is a rule (
.+ {200};): it compiles as "U+FEFF, then.+". Ordinary text has no U+FEFF, so the rule does not match it and ICU falls back to breaking after each character with status 0. Directly in ICU4J:.+ {200};onab cdgives its first boundary at 5 with status 200; with U+FEFF in front, at 1 with status 0. The tokenizer skips all of it. No error. - First statement is a directive or a variable definition:
U+FEFF !!forward;is ICU error 66052 (U_BRK_RULE_SYNTAX), reported at the start of the directive (Lucene's two files: line 20 or 44, column 1, after their comment lines);U+FEFF $Var = ...;reads as a use of an undefined variable, error 66058, reported just past the variable name (the independent reproduction's$Wsfile: line 1, column 5; with$Whitespace, column 13). Neither message names the invisible character at line 1, column 1.
| rule file | without BOM | with BOM |
|---|---|---|
.+ {200};, text ab cd | [ab cd] | no tokens, no error |
[\p{Letter}]+ {200}; then [\p{Number}]+ {100};, text ab 12 cd | [ab] [12] [cd] | [12] |
Lucene's KeywordTokenizer.rbbi for Cyrillic and Thai, upstream test text | 6 tokens | 4 tokens: [Some] [English] [More] [English] |
Lucene's Latin-break-only-on-whitespace.rbbi (!!forward; on line 20) | 2 tokens | Error 66052 at line 20 column 1 |
Lucene's Latin-dont-break-on-hyphens.rbbi (!!chain; on line 44) | 2 tokens | Error 66052 at line 44 column 1 |
The independent reproduction's file whose first line is $Ws = [\p{Whitespace}]; | [ab] [cd] | Error 66058 at line 1 column 5 (just past the variable name) |
The default configuration (no rulefiles) loads precompiled Default.brk and MyanmarSyllable.brk (DefaultICUTokenizerConfig.java:81-84, :147) and never runs parseRules; none of Lucene's five checked-in .rbbi files starts with a BOM (the build-time sources Default.rbbi and MyanmarSyllable.rbbi, and the three test files).
Exposure and likelihood274 words
- Who is exposed. Applications that opt in to custom per-script rules:
ICUTokenizerFactorywithrulefiles, directly, through theicuSPI name, or through a search server schema built on it (the factory javadoc shows such a schema). - What it takes. One custom rule file saved as UTF-8 with a BOM. Editors such as Windows Notepad often write one (the SOLR-1865 change note says so), and ICU's
genbrk(1)man page recommends one. - Silent case. The first statement is a rule, the shape of Lucene's
KeywordTokenizer.rbbi: no error; text that only the first rule covers gets no tokens. With a one-rule file that is all text of the script, which is then not indexed and cannot be found; an index built that way needs reindexing after the fix. - Loud case. The first statement is a
!!directive or a variable definition, the shape of two of Lucene's three test rule files: the analyzer fails to build with an ICU syntax error whose position points at that statement (a directive's line, or just past a variable's name), not at the invisible BOM at line 1, column 1. ICU's own rule guide calls stray literals "surprisingly hard to recognize and debug". - Scale. Deterministic: the rules are compiled once, when the analyzer is built, whatever the index size. Which tokens are lost depends on the text and on which rules cover it.
- How likely. Rare (registry: rare, priority low): opt-in, needs the BOM, a file that starts with a directive or a variable fails loudly (two of Lucene's three test files have that shape), and no report was found in the searched public sources since 4.1.0 (January 2013).
The test shows that ICUTokenizerFactory keeps a UTF-8 byte order mark at the start of a rulefiles rule file as rule text: the file <BOM>.+ {200}; loads without error, then the Latin text is dropped.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.icu.segmentation;

import java.io.StringReader;
import java.util.ArrayList;
import java.util.HashMap;
import java.util.List;
import java.util.Map;
import org.apache.lucene.analysis.Tokenizer;
import org.apache.lucene.analysis.tokenattributes.CharTermAttribute;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.StringMockResourceLoader;

public class TestICUTokenizerFactoryRuleFileBom extends LuceneTestCase {

  public void testRuleFileWithUtf8Bom() throws Exception {
    ICUTokenizerFactory factory =
        new ICUTokenizerFactory(new HashMap<>(Map.of("rulefiles", "Latn:latin.rbbi")));
    factory.inform(new StringMockResourceLoader("\uFEFF.+ {200};\n"));
    List<String> tokens = new ArrayList<>();
    try (Tokenizer tokenizer = factory.create()) {
      CharTermAttribute term = tokenizer.addAttribute(CharTermAttribute.class);
      tokenizer.setReader(new StringReader("ab cd"));
      tokenizer.reset();
      while (tokenizer.incrementToken()) {
        tokens.add(term.toString());
      }
      tokenizer.end();
    }
    // same tokens as for the file without the BOM; actual: none (the BOM became rule text)
    assertEquals(List.of("ab cd"), tokens);
  }
}
# in a copy of this finding's repro folder (repro/LFV-719/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/analysis/icu/build/libs/lucene-analysis-icu-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.icu.segmentation.TestICUTokenizerFactoryRuleFileBom
# the module(s) analysis-icu also need their third-party runtime jars
- Expected vs actual
- Expected
[ab cd]forab cd(as without the BOM); actual[](expected:<[ab cd]> but was:<[]>), with-eaand-da; passes when parseRules skips a leading U+FEFF.
More files, environment, full output35 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<[ab cd]> but was:<[]>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:120)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.analysis.icu.segmentation.TestICUTokenizerFactoryRuleFileBom.testRuleFileWithUtf8Bom(TestICUTokenizerFactoryRuleFileBom.java:46)- ICU's own rule-file compiler,
genbrk, strips a leading BOM; its man page recommends saving rule files "in UTF-8 with the BOM". - Lucene's word-list and hunspell readers skip a leading BOM; this reader never did, and no document or test covers its behaviour.
- Lucene's own
KeywordTokenizer.rbbiwith a BOM loses the Cyrillic and Thai tokens its upstream test asserts.
The full argument252 words
- The factory owns the file reading. It turns bytes into a String and already pre-processes the file (blanking
#lines) before handing a String to ICU (ICUTokenizerFactory.java:137-151). ICU maintainers place the encoding signature in the file reader, not the string API (ICU-21907, open:genbrk"detects and honors a BOM"; "the rbbi API for building from rules takes a UnicodeString. The code page stuff is in the genbrk tool"). - ICU's reader for this file format strips the BOM.
genbrk.cppcallsucnv_detectUnicodeSignatureand skips the signature (ruleSourceC += signatureLength); its man page (CAVEATS) says "it is recommended that you write this file in UTF-8 with the BOM". (The man page's sentence that a BOM-less file is read in the operating system's codepage is stale: the code assumes UTF-8.) - Lucene's other resource readers skip it.
WordlistLoader.getLines("skip initial bom marker",WordlistLoader.java:302-304, SOLR-1865, 2010) and the hunspellDictionary(Dictionary.java:246,:351-352; LUCENE-5505, listed under "Bug fixes" in 4.8.0).parseRules(2012, more than two years later) never adopted it. - Nothing documents or tests the current behaviour. The javadoc says only that rule files "are compiled by the ICU RuleBasedBreakIterator" and links ICU's syntax page (
ICUTokenizerFactory.java:49-52), which says nothing about encodings. SOLR-4123's 21 JIRA comments never discuss encoding, no later commit on the file mentions a BOM, and all five checked-in.rbbifiles are BOM-free. - Classification is open. No Lucene document promises BOM handling for rule files, so upstream may call the fix an improvement: SOLR-1865 was typed Improvement.
The devil's-advocate check268 words
An independent reviewer from another model family (OpenAI GPT-5.6), refute lens, executed, without network access: "not real, high", although it reproduced the silent no-token outcome. (a) The javadoc delegates the format to ICU, and RuleBasedBreakIterator(String) treats U+FEFF as a literal by design; Java's UTF-8 decoder keeps it on purpose. (b) Lucene's build-time RBBIRuleCompiler.getRules keeps a BOM the same way. (c) BOM skipping in WordlistLoader and hunspell is component-specific, and Lucene bans BOMs in its own source tree (SOLR-9295, #12937). (d) In 2010 a committer answered "No." to "should we consider that a bug?" about BOMs in Solr's resource files.
Why it fails: (a) the factory reads a file, and ICU's own file reader for this format strips the BOM; the reviewer did not have ICU's genbrk source or man page, and the same reviewer family, given the genbrk man page's CAVEATS section, rated the case real (high), intended-behaviour argument moderate. (b) RBBIRuleCompiler compiles only Lucene's own BOM-free files at build time. (c) The source-tree ban is repository hygiene, not a rule for users' files. (d) That remark predates rule files by more than two years, and the same reply went on: "we can ignore them for the first line of the file to be more user-friendly. I'll open an issue" (SOLR-1865); in 2014 the same slip in hunspell went under "Bug fixes". Two points stand: rule files are trusted configuration, and ICU-2003 (2002, Won't Fix) declined to make ICU's own rule parsers ignore such characters; both fit fixing it in Lucene's file reader (ICU-21907) but keep the classification open. What survives is the bug-or-improvement classification, not the defect.
Recommended Skip a BOM at the start of the first line (recommended, validated)
In ICUTokenizerFactory.parseRules, drop a U+FEFF at the start of the first line before the # comment check, the idiom WordlistLoader.getLines already uses (+6 lines). The 3 new tests pass, and so do the ICU module's 161 tests and its static checks.
    String line = null;
    boolean firstLine = true;
    while ((line = reader.readLine()) != null) {
      // skip initial bom marker
      if (firstLine && line.length() > 0 && line.charAt(0) == '\uFEFF') {
        line = line.substring(1);
      }
      firstLine = false;
      if (!line.startsWith("#")) {
        rules.append(line);
      }
All options and trade-offs4 options · 483 words
One fix was applied in a scratch worktree of a9779ef3c193 and run with gradle, assertions on and off; the worktree was removed afterwards. The other options were not run.
Before the # test, remove a U+FEFF at position 0 of the first line. The first comment line is then blanked as intended, and every other line, and so every line number in ICU's error messages, stays as in the file. Same idiom as WordlistLoader.getLines:302-304, with braces; the hunt's sketch is the same change on one line.
    String line = null;
    boolean firstLine = true;
    while ((line = reader.readLine()) != null) {
      // skip initial bom marker
      if (firstLine && line.length() > 0 && line.charAt(0) == '\uFEFF') {
        line = line.substring(1);
      }
      firstLine = false;
      if (!line.startsWith("#")) {
        rules.append(line);
      }
Trade-offs
Only a U+FEFF at the very start of the file is removed; one later in the file, a legitimate literal, is untouched. A file that deliberately began its first rule with a literal U+FEFF would change meaning; ICU's own genbrk strips that character too. Scope: a UTF-8 BOM only (the factory decodes strictly as UTF-8, so UTF-16 files stay unsupported); a file that holds only a BOM was not tested. No CHANGES entry is drafted.
What the checks validated
- The 3 new tests and the 5 upstream
TestICUTokenizerFactorytests pass, assertions on and off (stock: the 3 new tests fail). - All of
:lucene:analysis:icu:test, assertions on: 17 classes, 161 tests, 10 skipped, 0 failures. :lucene:analysis:icu:check -x testpasses with the new test in place (google-java-format, ecjLint and forbiddenApis on main, test and tools sources, checkLicenses).- The public-API probe with the patched classes: every BOM file gives exactly the tokens of its BOM-less copy, including the two-rule file and
Latin-dont-break-on-hyphens.rbbi. - Earlier, in the repro harness with the hunt's one-line version: the finder's repro 3/3, the reproducer's 10/10, the devil's advocate's 6/6 and the version-independent check on main pass.
if (rules.length() > 0 && rules.charAt(0) == '\uFEFF') rules.deleteCharAt(0); before compiling.
Trade-offs
One line. Lucene would no longer blank the first line, but ICU reads # ... as a comment anyway, so the result should be the same; not executed.
Throw an IllegalArgumentException naming the file and the byte order mark.
Trade-offs
Nothing is lost silently and the message is precise, but it refuses a file that ICU's own tool accepts and recommends.
Use one small helper here and in the snowball word-set loader, the synonym file parsers and the Kuromoji and Nori user dictionaries, which keep a BOM the same way.
Trade-offs
Fixes the whole class at once but touches several modules; worth raising if upstream wants one issue.
Two downstream search servers' ICU plugins have their own copy of this rule-file reader with the same pattern, so a Lucene fix would not reach them.
A bounded enumeration ran the same rule through the tokenizer in 9 file layouts (line ends, comments, blank lines, a leading BOM) and 8 spellings of the rulefiles argument, each compared with the plain file, plus a default-configuration control: 18 checks, 2 mismatches, both with a BOM. The idea came from a sibling BOM bug in a word-list loader.
The method in full158 words
Method (semi-formal): bounded enumeration in a hunt unit on analysis-factory resource file formats, on the stock main jar.
- The harness tried 8 spellings of the
rulefilesargument and 9 layouts of the same rule file: with and without a final newline, LF and CRLF line ends, comment lines, indented and trailing comments, blank lines, and a leading BOM. Each was checked through the tokenizer against the tokens of the plain BOM-less file, plus one default-configuration control: 18 checks, 2 mismatches, both BOM files (.+ {200};, alone and after a#line). - The hypothesis came from extending the unit's earlier finding, a BOM kept by the snowball word-set loader (LFV-718), to the other resource readers that do not go through
WordlistLoader.getLines. - The finder reduced it to a public-API JUnit test; no model checker, solver or proof was involved. Writing this doc, a probe added the two-rule case, which shows that only the first rule is broken.
No prior report found in GitHub issues, PRs and all 410 open PRs, Lucene, Solr and ICU JIRA, the Lucene and Solr mailing lists or the web (searched 2026-10-27). SOLR-1865 and LUCENE-5505 fixed the same slip in other readers.
Searches5 searches
No report of this defect was found. The nearest items fixed the same slip at other fix sites or discuss BOM handling in ICU itself.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene), downstream repos, Lucene mailing lists, LUCENE JIRA archive | 2026-10-27 | a scripted prior-report search, two runs: 44 GitHub, 6 commit, 6 downstream, 36 list (dev@, java-user@, issues@, commits@) and 9 JIRA queries, plus 8 web queries | 201 and 648 distinct hits, none about this bug |
| GitHub (apache/lucene, apache/solr, two downstream search servers) | 2026-10-27 | 27 manual issue and PR searches | no BOM or rule-file encoding report |
| Open apache/lucene PRs | 2026-10-27 | changed files of all 410 open PRs | only #16911 (branch_10x decommission) touches the file |
| SOLR, LUCENE and ICU JIRA; Solr and Lucene lists | 2026-10-27 | 8 SOLR/LUCENE and 5 ICU JQL queries, 25 list queries (the web searches are the 8 queries counted above) | SOLR-4123 (origin, no encoding discussion); ICU-21907 (BOM handling belongs to the file reader); ICU-2003 (2002, Won't Fix); none reports this bug |
| Related, at other fix sites | 2026-10-27 | read | SOLR-1865 (word-list loader, Improvement), #6568 / LUCENE-5505 (hunspell, Bug); #12937 and SOLR-9295 are source-tree hygiene |
Introduced with the rulefiles feature (SOLR-4123, 2012-12-03), first released in 4.1.0, unchanged since and not fixed on main. Every executed release from 4.1.0 to 10.5.2 is affected; 4.0.0 has no such feature.
Versions tested6 rows
Introduced by SOLR-4123 "ICUTokenizerFactory - per-script RBBI customization" (JIRA, Improvement; Subversion era, no PR): trunk 6024e1465e0 and the branch_4x merge 9a23a0799e5, both 2012-12-03, committed by Steve Rowe; the 4.1.0 change note credits Shawn Heisey, Robert Muir and Steve Rowe. It added rulefiles and parseRules with no BOM handling. Later commits only changed the charset constant (LUCENE-5560, 2014) and the formatting (LUCENE-9570, 2021).
Not a regression and not tied to an ICU4J version (the bundled 49.1, 53.1, 54.1, 56.1, 62.1, 68.2, 74.2, 77.1 and 78.3 behave the same). In the history clone's release tags the whitespace-normalized parseRules body has three forms, none of which changes behaviour: 4.1.0 to 4.7.2, 4.8.0 to 8.8.1 (charset constant) and 9.0.0 to 10.5.2 (reformat). The clone has no tags for 8.8.2 to 8.11.4; 8.11.4 was executed, and the releases not executed are inferred to be affected from the unchanged code. Upstream main c5ab3e57b9b (2026-10-28) has the same ICU module as a9779ef3c193, with no BOM handling.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | new test 3/3 fail (gradle, -ea and -da); finder's 2/3, reproducer's 4/10 fail; ICU4J 78.3 |
| 10.0.0, 10.5.2 | affected | finder's JUnit 2/3 fail; version-independent check fails with both outcomes; ICU4J 74.2, 77.1 |
| 9.0.0, 9.12.3 | affected | both outcomes; ICU4J 68.2, 74.2 |
| 4.1.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.11.4 | affected | both outcomes (version-independent public-API check); ICU4J 49.1 to 62.1 |
| 4.0.0 | no feature | the factory ignores rulefiles and never opens the file |
| main with the fix | fix | every BOM file tokenizes like its BOM-less copy |
A finder, an independent reproducer, an intended-behaviour devil's advocate, cross-model reviews (OpenAI GPT-5.6) and an adjudication: confirmed, medium confidence on the bug-or-improvement framing, not on the defect. One review said not real; it lacked ICU's rule-file documentation.
Checks and verdicts213 words
Every check except the refute review returned real; all of them reproduced the behaviour.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Public-API JUnit fails 2 of 3 on main (-ea, -da), 10.5.2 and 9.12.3; passes with its fix sketch, with the 5 upstream factory tests. |
| refute review (OpenAI GPT-5.6) | not real (high) | Reproduced the silent no-token outcome but argued there is no BOM promise; ran without network access and without ICU's genbrk documentation. |
| intended review (OpenAI GPT-5.6) | real (high) | Given ICU's genbrk CAVEATS: intended-behaviour argument moderate; root cause and fix agree. |
| independent reproducer | real | Own raw-byte JUnit fails 4 of 10 on main, 10.5.2 and 9.12.3; ICU4J mechanism control; 10 of 10 with the fix. |
| root-cause review (OpenAI GPT-5.6) | real (high) | Instrumentation shows U+FEFF as the first code point handed to ICU; the fix fixes it. |
| devil's advocate | real (medium) | BOM copies of the three upstream fixtures fail 3 of 6; intended-behaviour argument weak-to-moderate. |
| adjudication | confirmed (medium) | Re-ran the reproducer's and the finder's tests with assertions on and off, and the fix. |
| registry re-run, audit and this doc | keep | Re-runs fail on main and pass with the fix; this doc's gradle validation and the two-rule probe. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 522 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,459 words
- Registry title
- ICUTokenizerFactory keeps the UTF-8 byte order mark at the start of a custom per-script rule file (rulefiles) as rule text, so the file either fails with a misleading ICU syntax error or loads without error and the tokenizer then emits no tokens for that script (every release since 4.1.0)
- Area
- analysis / ICU (ICUTokenizerFactory per-script rule files: rulefiles, parseRules)
- Priority
- Low, rank 503: This is the same kept-BOM slip in ICUTokenizerFactory's opt-in custom rule files, where most such files fail loudly and only a file that starts with a rule silently loses tokens.
- Impact class
- silent wrong results
- Impact note
- Only applications that opt in to custom per-script ICU rule files (the rulefiles argument of ICUTokenizerFactory, analysis-icu module) and save such a file as UTF-8 with a byte order mark are hit, at analyzer setup: a file whose first statement is a rule (for example '.+ {200};', alone or after '#' comment lines, the shape of Lucene's own test file KeywordTokenizer.rbbi) compiles without error and every token of that script is then silently dropped, while a file that starts with a '!!' directive or a variable definition is rejected with an IllegalArgumentException whose position does not point at the BOM; the default configuration (no rulefiles) is not affected, no scale is needed, and it is the same with -ea and -da in every release from 4.1.0 to 10.5.2 [exec] and, by reading, 10.6.0.
- Summary
- You configure ICUTokenizerFactory with rulefiles="Latn:latin.rbbi" and a rule file saved as UTF-8 with a byte order mark (BOM), as editors such as Windows Notepad often write and as ICU's own rule-file compiler genbrk accepts (it strips the BOM, and its man page recommends one), and expect the same tokens as with the same file without the BOM. Instead ICUTokenizerFactory.parseRules decodes the BOM to U+FEFF and passes it to ICU's RuleBasedBreakIterator(String) as rule text: a file that starts with the rule '.+ {200};' (alone or after '#' comment lines) compiles with U+FEFF as a literal prefix of that rule, so 'ab cd' gives no tokens at all instead of ['ab cd'], and a file that starts with a comment and '!!forward;' (the shape of Lucene's Latin-break-only-on-whitespace.rbbi) fails with 'IllegalArgumentException: Error 66052 at line 2 column 1'. Nothing on disk is corrupted, but in the silent case all text of the tailored script disappears from the analyzed output with no error.
- Introduced
- 6024e1465e02 (svn trunk r1416617, 2012-12-03, by sarowe), SOLR-4123 'Add per-script customizability to ICUTokenizerFactory via rule files in the ICU RuleBasedBreakIterator format' (Subversion and JIRA era, no PR; none of the 21 JIRA comments mentions a BOM or the file encoding); merged to branch_4x the same day as 9a23a0799e5e (r1416629), the commit that shipped in 4.1.0. It added the rulefiles argument and parseRules, which reads the file through a UTF-8 decoding reader, drops '#' lines and never removes a leading U+FEFF [read: git log -S parseRules, git blame -w -M -C -C, git log -L in the full-history clone] [exec: 4.0.0 ignores rulefiles, 4.1.0 fails]. Later commits on parseRules changed no behaviour (2f8192f3c5a, LUCENE-5560, 2014, charset constant; 7f8b7ffbcad, LUCENE-9570, 2021, reformatting), and git log --all -G 'FEFF|bom' on the file finds no commit. Not a regression and not tied to an ICU4J version (2012-12-03)
- First affected version
- 4.1.0 [exec] (the first release with rulefiles; 4.0.0 has no inform(ResourceLoader) in this factory, ignores the argument and never opens the file [exec])
- Affected versions
- Every release from 4.1.0 to 10.5.2, 10.6.0 (by reading) and main a9779ef3c193; never fixed. [exec] the follow-up's portable public-API check fails with both outcomes on 4.1.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main (BOM-less controls give the custom-rule tokens everywhere) and passes on main with the fix shadowed; the finder's JUnit fails 2 of 3 on 9.12.3, 10.0.0, 10.5.2 and main (-ea and -da on main); the independent reproduction's JUnit fails 4 of 10 on main (-ea and -da), 10.5.2 (-ea and -da) and 9.12.3 (-ea); a separate test fails on main (-ea and -da), 10.5.2 and 9.12.3; the intended-behaviour check's probe fails 3 of 6 on main (-ea and -da) and 10.5.2. The bundled ICU4J versions from 49.1 to 78.3 all behave the same. [read] the normalized parseRules body is identical in every release tag of the history clone from 4.1.0 to 8.8.1 and from 9.0.0 to 10.5.2 (8.9-8.11 are untagged there; 8.11.4 was executed). Not fixed upstream: ICUTokenizerFactory.java has no BOM handling on upstream main a95c754ee003, branch_10x 1309534296e or branch_10_6 2763db11b0a, and lucene/analysis/icu is unchanged between a9779ef3c193 and a95c754ee003 (local fetch of 2026-10-26, read 2026-10-27). Not affected: 4.0.0 and older (no rulefiles feature). All runs on Linux aarch64 with JDK 25
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that disputed it (the adjudication ruled it real), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal
- Upstream and prior reports
- none found (2026-10-27, completed, read-only; the prior-report record verdict new): two scripted prior-report searches (44 GitHub issue and PR, 6 commit, 6 downstream, 36 mailing-list over dev@, java-user@, issues@ and commits@, and 9 JIRA-archive queries, plus 8 ingested web queries; 201 and 648 distinct hits, 0 high), 27 manual GitHub searches on apache/lucene, apache/solr, Elasticsearch and OpenSearch, the changed files of all 410 open apache/lucene PRs (only #16911, the branch_10x decommission, touches ICUTokenizerFactory.java), 8 SOLR and LUCENE and 5 ICU JIRA queries, 25 list queries (solr-user@, users@solr, dev@solr, dev@lucene, java-user@), 10 web queries and the git history; the independent reproduction's and the intended-behaviour check's own searches agree. No report of a BOM in an ICU rule file, of the misleading 'Error 66052', or of a script losing its tokens because of it. Related, not this bug: SOLR-1865 (BOM skip in the line loader that became WordlistLoader.getLines, typed Improvement) and #6568 / LUCENE-5505 (hunspell BOM, typed Bug, listed under Bug fixes), precedents at other fix sites; ICU-21907 (open), where ICU maintainers say genbrk 'detects and honors a BOM' and that the RuleBasedBreakIterator API takes a string, placing BOM handling in the file reader; ICU-2003 (Won't Fix, duplicate of ICU-1997, 2002), an ICU-side request that rule parsers ignore format characters such as a leftover BOM; SOLR-4123 (origin of the code, no encoding discussion); #7747 / LUCENE-6689 (open, names rulefiles, unrelated WordDelimiterFilter problem); #12937 and SOLR-9295 (BOM hygiene of Lucene's own source tree, not user files). Two downstream projects carry their own copies of parseRules with the same pattern and no BOM report. Not fixed upstream (main a95c754ee003, branch_10x, branch_10_6, read).
- Lucene commit tested
- main
a9779ef3c193(2026-10-26) through gradle in a scratch worktree: a new 3-test class with the 5 upstreamTestICUTokenizerFactorytests, assertions on and off (stock: 3 of 8 fail; with the recommended fix: 0), the fix with all of:lucene:analysis:icu:test(17 classes, 161 tests, 10 skipped, 0 failures) and:lucene:analysis:icu:check -x test; the worktree was removed afterwards. A public-API probe on the stock main jars and with the patched classes. The hunt's repros on main (-ea,-da), 9.12.3, 10.0.0 and 10.5.2, and its version-independent check on 4.0.0 (no such feature), 4.1.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main; OpenJDK 25.0.3, Linux aarch64.
- Finding record
lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/segmentation/ICUTokenizerFactory.java:49-52 (rule files 'compiled by the ICU RuleBasedBreakIterator', link to the syntax page), :54-66 (rulefiles format), :86-95 (rulefiles parsing), :108-135 (inform), :137-151 (parseRules: UTF-8 decoding reader, '#' lines dropped, no BOM skip)lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/segmentation/ICUTokenizer.java:208-213 (segments with rule status 0 are skipped); DefaultICUTokenizerConfig.java:82-84, :147 (the default configuration loads precompiled .brk files)lucene/core/src/java/org/apache/lucene/analysis/WordlistLoader.java:302-304 ('skip initial bom marker' in getLines)SECURITY.md ('Other out-of-scope reports': configuration values are trusted as given; 'In-scope reports')a Lucene clone origin/main a95c754ee00, origin/branch_10x 1309534296e, origin/branch_10_6 2763db11b0a: ICUTokenizerFactory.java has no FEFF or BOM handling; git diff a9779ef3c193 origin/main -- lucene/analysis/icu is empty (read 2026-10-27)
- The finding in 30 seconds
lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/segmentation/ICUTokenizerFactory.java:86-95, :108-135, :137-151 (main a9779ef3c193)lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/segmentation/ICUTokenizer.java:209-213 (status-0 segments skipped)lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/segmentation/DefaultICUTokenizerConfig.java:81-84, :147 (default path: precompiled .brk)javap -constants on ICU4J 78.3 com.ibm.icu.text.RBBIRuleBuilder: U_BRK_RULE_SYNTAX = 66052, U_BRK_UNDEFINED_VARIABLE = 66058 [exec]
- Who is affected
lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/segmentation/ICUTokenizerFactory.java:49-66 (javadoc, schema example)
- Why it looks unintended
lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/segmentation/ICUTokenizerFactory.java:49-52, :137-151lucene/core/src/java/org/apache/lucene/analysis/WordlistLoader.java:302-304lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Dictionary.java:246, :351-352lucene/CHANGES.txt:12543-12555 (4.8.0 Bug fixes, LUCENE-5505)lucene/analysis/icu/src/tools/java/org/apache/lucene/analysis/icu/RBBIRuleCompiler.java:46-60
- Suggested fix
lucene/core/src/java/org/apache/lucene/analysis/WordlistLoader.java:302-304
- History
lucene/CHANGES.txt:14654-14656 (4.1.0, SOLR-4123 credits)a Lucene clone: git diff a9779ef3c193 origin/main (c5ab3e57b9b, 2026-10-28) -- lucene/analysis/icu is empty; no FEFF or BOM in ICUTokenizerFactory.java there [read]
- TestICUTokenizerFactoryRuleFileBom.java (JUnit test):
repro/LFV-719/src/org/apache/lucene/analysis/icu/segmentation/TestICUTokenizerFactoryRuleFileBom.java(48 lines)
assets/LFV-719/bug.png(522 KB)