ICUTokenizer cuts each script run into pieces with a rule file and gives each piece a status; pieces with status 0, such as spaces, are skipped. In syllable mode, Myanmar runs use MyanmarSyllable.rbbi, which gives a status only to syllables and numbers.
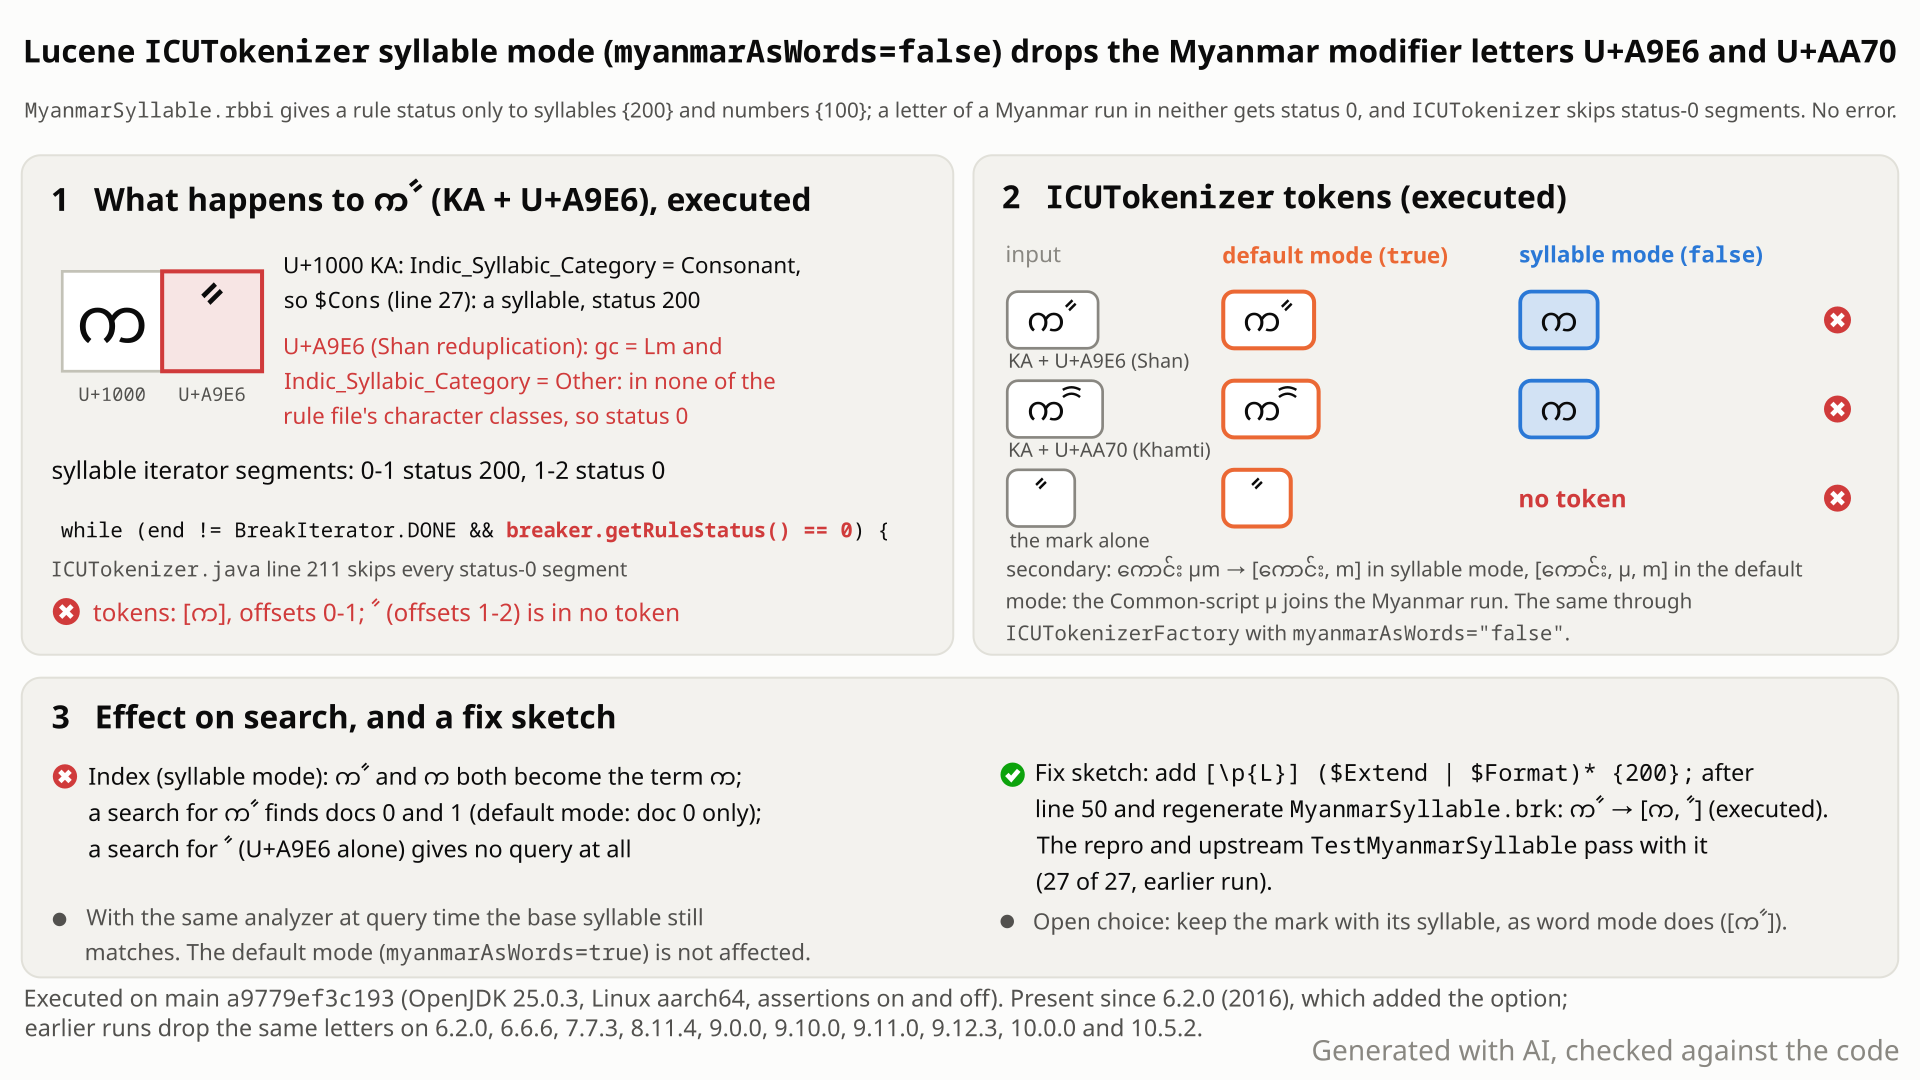
ICUTokenizer skips it, and ကꧦ is tokenized as [က]; then the effect on search and a one-line fix sketch. Select the still to open it at full size. Generated with AI, checked against the code.- Turn on syllable mode for Myanmar-script text:
new DefaultICUTokenizerConfig(true, false), or theicufactory withmyanmarAsWords="false". Burmese text splits into syllables as documented: သက်ဝင်လှုပ်ရှားစေပြီး gives 6 syllables. - Analyze ကꧦ: the consonant က (KA, U+1000) followed by ꧦ (U+A9E6, the Shan reduplication mark, a letter). You expect the mark to be kept, as the default mode, ICU's own word iterator and StandardTokenizer keep it:
[ကꧦ]. - You get
[က]: the mark is gone, with no error. The Khamti mark ꩰ (U+AA70) is lost the same way (ကꩰ gives[က]), and ꧦ on its own gives no token at all. - Search changes too. The documents ကꧦ and က are both indexed as the one term က, so a search for ကꧦ matches 2 of 2 documents (the default mode: 1 of 2), and a search for ꧦ has no terms and finds nothing.
- Why: the rule file gives a token status only to syllables that start with a consonant, consonant placeholder or independent vowel, and to numbers. ꧦ and ꩰ are the only Myanmar letters that are neither, so their piece gets status 0, and
ICUTokenizerskips it like a space.
Applications that choose the ICU module's non-default syllable mode (DefaultICUTokenizerConfig(.., false), or myanmarAsWords="false" on the icu factory, for example in a Solr schema) and index Shan or Khamti text with these marks. ကꧦ and က become one term, a lone mark cannot be found, and the token offsets leave it out. Rare; the default mode is unaffected.
Mechanism, terms and numbers701 words
ICUTokenizer splits text into script runs and cuts each run with a break iterator; every piece gets a rule status, and pieces with status 0 (spaces, punctuation) are skipped (ICUTokenizer.java:209-214). With myanmarAsWords=false (the constructor DefaultICUTokenizerConfig(cjkAsWords, false) or the icu factory option; default true), Myanmar runs go to Lucene's rule file MyanmarSyllable.rbbi (DefaultICUTokenizerConfig.java:115-120), documented only as "it will be tokenized as syllables" (:97-98). That file has two status rules: syllables built on a consonant, consonant placeholder or independent vowel {200} (MyanmarSyllable.rbbi:21-27, :44-50) and numbers {100} (:53).
U+A9E6 MYANMAR MODIFIER LETTER SHAN REDUPLICATION and U+AA70 MYANMAR MODIFIER LETTER KHAMTI REDUPLICATION (gc=Lm, Indic_Syllabic_Category Other) are the only two Script=Myanmar letters that are not syllable bases, so they get status 0 and vanish: ကꧦ → [က], ကꩰ → [က], ꧦ → []. The default mode gives [ကꧦ], [ကꩰ], [ꧦ], and so do StandardTokenizer and ICU's root word iterator. In an index, ကꧦ and က become one term, so a same-analyzer search for ကꧦ matches both documents and a search for the mark alone has no terms; the token offsets leave it out. Secondary: a Common-script letter written after Myanmar text is dropped the same way (ကောင်း µm → [ကောင်း, m]).
It arrived with the option in 6.2.0 (LUCENE-7393, which restored unchanged the 3.1-4.10.4 default rules, which already dropped U+AA70) and reproduces on every release run from 6.2.0 to 10.5.2 and on main. A rule change validated in a scratch worktree (rules regenerated with regenerateRbbi, :lucene:analysis:icu:check and all module tests pass) keeps every letter; the recommended variant attaches the marks to their syllable, as the default mode does.
- Syllable mode:
myanmarAsWords=false, throughnew DefaultICUTokenizerConfig(cjkAsWords, false)or theicufactory (ICUTokenizerFactory.java:97, default true).getBreakIterator(UScript.MYANMAR)then returns the iterator compiled fromMyanmarSyllable.rbbiinstead ofDefault.brk(DefaultICUTokenizerConfig.java:83-84,:115-120). - Rule status: the number a break-iterator rule assigns to the piece it matches.
ICUTokenizerskips every piece with status 0, "skipping over non-tokens (rule status 0)" (ICUTokenizer.java:209-214). - ꧦ U+A9E6 MYANMAR MODIFIER LETTER SHAN REDUPLICATION and ꩰ U+AA70 MYANMAR MODIFIER LETTER KHAMTI REDUPLICATION: Script=Myanmar, gc=Lm (modifier letter), Indic_Syllabic_Category Other, Word_Break Other. By their names, they mark reduplication in Shan and Khamti writing, as ๆ does in Thai.
MyanmarSyllable.rbbi:27defines the syllable base$Consas Indic_Syllabic_Category Consonant, Consonant_Placeholder or Vowel_Independent;:44-47build a syllable from a base plus marks;:50gives it{200}, and:53gives numbers{100}. No other rule has a status.- ꧦ and ꩰ are not bases, and not
$Extendor$Format, so they cannot attach to the syllable before them. Their piece gets status 0. ICUTokenizerskips it, like a space: ကꧦ →[က].- They are the only two such Myanmar letters: an independent sweep of all 120 Script=Myanmar letters (alone and after KA) finds exactly these two lost in syllable mode and kept in the default mode.
- Secondary: the script iterator keeps a Common-script character after Myanmar text (even after a space) in the Myanmar run, so µ in ကောင်း µm reaches the syllable rules and gets status 0 too.
- Not letters, but lost the same way: the five Myanmar-script symbols U+109E, U+109F (Shan), U+AA77, U+AA78 and U+AA79 (Aiton) (gc=So) are kept by the default mode and dropped by syllable mode: က႞ →
[က႞]and[က]. Neither fix below keeps them (their catch-all covers letters only).
| input | default mode | syllable mode (main) | syllable, recommended fix |
|---|---|---|---|
| ကꧦ (KA + U+A9E6) | ကꧦ | က | ကꧦ |
| ကꩰ (KA + U+AA70) | ကꩰ | က | ကꩰ |
| ၵꧦ (SHAN KA + U+A9E6) | ၵꧦ | ၵ | ၵꧦ |
| ꩠꩰ (KHAMTI GA + U+AA70) | ꩠꩰ | ꩠ | ꩠꩰ |
| ꧦ alone | ꧦ | (none) | ꧦ |
| ကောင်း µm (secondary) | ကောင်း, µ, m | ကောင်း, m | ကောင်း, µ, m |
| သက်ဝင်လှုပ်ရှားစေပြီး (control) | 4 words | 6 syllables | 6 syllables |
Search, documents ကꧦ and က, same analyzer at query time: the default mode finds 1 of 2 for ကꧦ and 1 of 2 for က; syllable mode on main finds 2 of 2 for both (the query becomes body:က) and builds no query for ꧦ; the recommended fix gives the default mode's counts.
Exposure and likelihood289 words
- Who is exposed. Java code that builds
ICUTokenizerwithDefaultICUTokenizerConfig(cjkAsWords, false), and schemas that setmyanmarAsWords="false"onICUTokenizerFactory(SPI nameicu; Solr's reference guide documents the option). A factoryrulefilesentry for Myanmar (Mymr:...) replaces the syllable rules, so applications with their own Myanmar rule file get what their rules say. - Not exposed. The default
ICUTokenizer()and the factory default (myanmarAsWords=true). Elasticsearch and OpenSearch hard-codeDefaultICUTokenizerConfig(true, true)in theiricu_tokenizer. - What triggers it. Any text with U+A9E6 or U+AA70, every time, with assertions on or off. Ordinary Burmese prose seldom has them; how often Shan and Khamti text uses them was not measured, so the registry rates it rare. Secondary: a Common-script letter such as µ written after Myanmar text.
- What the damage looks like. Silent: no exception, valid index. The marks are never indexed; a text made only of marks gives no token; ကꧦ and က share one term, so a same-analyzer search for ကꧦ also matches every plain က document (2 of 2 instead of 1 of 2), a precision loss; a query for the mark alone analyzes to nothing, so it builds no query clause; the token offsets leave the mark out, so a highlighter that uses them cannot cover it (no highlighter was run).
- Not affected. Other tokens, other values on the same reused tokenizer, cost: 1,200,000-character values tokenize in 53-135 ms, about the same as a control.
- Reindex. Fields analyzed before a fix lack the mark-bearing terms. After fix B a query for ကꧦ analyzes to the term ကꧦ (stock: က), so it no longer matches documents indexed before the fix as က, and an index with old and new segments answers inconsistently: reindex the affected fields.
The test shows that ICUTokenizer in Myanmar syllable mode (DefaultICUTokenizerConfig(true, false)) silently drops U+A9E6 MYANMAR MODIFIER LETTER SHAN REDUPLICATION, which word mode keeps.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.icu.segmentation;

import java.io.StringReader;
import org.apache.lucene.analysis.Tokenizer;
import org.apache.lucene.analysis.tokenattributes.CharTermAttribute;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestMyanmarSyllableModifierLetter extends LuceneTestCase {

  public void testShanReduplicationMarkIsKept() throws Exception {
    Tokenizer t = new ICUTokenizer(new DefaultICUTokenizerConfig(true, false));
    CharTermAttribute term = t.addAttribute(CharTermAttribute.class);
    t.setReader(new StringReader("\u1000\uA9E6"));
    StringBuilder tokens = new StringBuilder();
    t.reset();
    while (t.incrementToken()) {
      tokens.append(term);
    }
    t.end();
    t.close();
    // expected: the tokens keep U+A9E6, as word mode does ([\u1000\uA9E6]); actual: only [\u1000]
    assertEquals("\u1000\uA9E6", tokens.toString());
  }
}
# in a copy of this finding's repro folder (repro/LFV-720/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/analysis/icu/build/libs/lucene-analysis-icu-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.icu.segmentation.TestMyanmarSyllableModifierLetter
# the module(s) analysis-icu also need their third-party runtime jars
- Expected vs actual
- Expected the tokens of KA + U+A9E6 (
\u1000\uA9E6) to contain both letters; actual only KA (expected:<က[ꧦ]> but was:<က[]>), with-eaand-da.
More files, environment, full output32 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: expected:<က[ꧦ]> but was:<က[]>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.analysis.icu.segmentation.TestMyanmarSyllableModifierLetter.testShanReduplicationMarkIsKept(TestMyanmarSyllableModifierLetter.java:38)- The only contract says syllable mode changes how Myanmar text is split ("it will be tokenized as syllables",
DefaultICUTokenizerConfig.java:97-98), not that letters are dropped. - The default mode, ICU's root iterator and StandardTokenizer keep these marks, as Lucene keeps the similar Thai, Lao and Khmer repetition marks.
- The rules' admitted imperfections (#8446) concern where syllables split; nothing found accepts losing letters.
The full argument296 words
- The contract.
@param myanmarAsWords"true if Myanmar text should undergo dictionary-based segmentation, otherwise it will be tokenized as syllables" (DefaultICUTokenizerConfig.java:97-98). CHANGES 6.2.0: "Add ICUTokenizer option to parse Myanmar text as syllables instead of words ... This allows for the previous tokenization used before Lucene 5" (lucene/CHANGES.txt:9052-9054). The rule file: "Parses Myanmar text, with syllable as token." (MyanmarSyllable.rbbi:18). All describe how the text is split. That every letter stays in some token is implied, not stated. - Status 0 means "not a token".
ICUTokenizerskips "non-tokens (rule status 0)" (ICUTokenizer.java:209), the status that spaces and punctuation get; ꧦ and ꩰ are letters. - In scope. The rules do tokenize Shan and Khamti consonants (U+1075 SHAN KA, U+A9E0, U+AA60 KHAMTI GA are ISC Consonant), so Shan and Khamti text is text the mode is meant for.
- References. The default mode, ICU's root word iterator (status 200) and StandardTokenizer keep ကꧦ as one token. The Thai, Lao and Khmer repetition marks ๆ, ໆ, ៗ (gc=Lm, ISC Other, Line_Break SA, the same profile) are kept by the default
ICUTokenizer, StandardTokenizer and ThaiTokenizer. - Tests.
TestMyanmarSyllable(21 tests) is the only dedicated syllable-mode test and covers Burmese syllable categories only.TestRandomChainsalso picksmyanmarAsWordsat random (TestRandomChains.java:496-499), but checks only consistency, so it cannot see a dropped letter. No test inlucene/analysiscontains U+A9E6 or U+AA70. - History. The rules came from LUCENE-2414 (3.1, the default until 4.10.4), were removed by LUCENE-5995 (5.0) and restored unchanged by LUCENE-7393 (6.2.0). #13239 (9.11.0) rewrote
$Conswithout discussing coverage, so the rules are not frozen. U+A9E6 was added in Unicode 7.0 (2014), after the rules were written. In 2010 (#3243) a different tokenizer dropped Lao and Myanmar letters; committers treated it as a defect and fixed it.
The devil's-advocate check211 words
The strongest "intended" case (the devil's-advocate verifier and the cross-model lenses rate it moderate; the independent reproducer weak to moderate): the option exists to restore the pre-5.0 tokenization, and 4.10.4 drops U+AA70 and µ the same way (U+A9E6 is not assigned in its ICU version), so it restores the old behaviour faithfully, drop included; the rules' author called them informal and "not perfect", with "no rules for rarer cases", and TestMyanmarSyllable says the algorithm cannot handle some special cases; status 0 is skipped by design; both classes are @lucene.experimental; and for µ, attaching a Common character to the preceding script's run is the script iterator's intended heuristic (#10793).
Why it fails for the two marks: nothing documents a drop; the admitted imperfections concern syllable structure ("syllable chaining, great sa"), which mis-splits text but does not lose it; the legacy match shows the gap is old, not wanted; the rules were rewritten in 9.11.0; and every other Lucene path keeps these marks and the analogous Thai, Lao and Khmer marks. Verdict: a defect (adjudication: confirmed, medium). What the counter-case gets right: the µ sub-case rests on run assignment upstream defends, so it stays a secondary remark, and a maintainer may call the whole thing a known limitation of best-effort legacy rules.
Recommended Attach the modifier letters to the syllable, and keep any other letter (B)
Recommended: in MyanmarSyllable.rbbi, let a syllable end with the two Myanmar modifier letters and add a catch-all rule that makes any other letter its own token, then regenerate MyanmarSyllable.brk with regenerateRbbi. Syllable mode then matches the default mode (ကꧦ → [ကꧦ]). Validated: the new test, :lucene:analysis:icu:check and all module tests pass.
+# U+A9E6 and U+AA70, the Shan and Khamti reduplication marks
+$ModifierLetter = [[:Script=Myanmar:] & [:General_Category=Modifier_Letter:]];
 ...
-$MyanmarSyllableEx = $ConsEx ($Virama $ConsEx)? ($AsatEx)*;
+$MyanmarSyllableEx = $ConsEx ($Virama $ConsEx)? ($AsatEx)* ($ModifierLetter ($Extend | $Format)*)*;
 ...
 !!forward;
 $MyanmarJoinedSyllableEx {200};
+# any other letter of a Myanmar run is a token of its own
+[\p{L}] ($Extend | $Format)* {200};
All options and trade-offs4 options · 956 words
MyanmarSyllable.brk is generated: edit MyanmarSyllable.rbbi, run ./gradlew :lucene:analysis:icu:regenerateRbbi (it rewrites the .brk files and src/generated/checksums/regenerateRbbi.json; check verifies the checksums). Default.brk comes out byte-identical. Both fixes keep the Burmese syllables of TestMyanmarSyllable unchanged. Neither keeps the five Myanmar symbols U+109E, U+109F, U+AA77, U+AA78 and U+AA79 (gc=So), which syllable mode also drops (their catch-all covers letters only). Not covered by either (a side observation, not claimed): since #13239 the syllable rules emit -, NBSP, – and × as tokens (they are ISC Consonant_Placeholder), for example က-က → [က, -, က].
Attach the modifier letters to the syllable, and keep any other letter (B) (validated by the checks) (recommended)
In MyanmarSyllable.rbbi, one new letter class, one changed line and one new rule (+5/-1 with comments, +3/-1 without), then regenerateRbbi. A syllable may end with U+A9E6 or U+AA70 ($ModifierLetter, derived from Unicode properties: exactly these two in ICU4J 78.3), and a new rule gives any other letter of the run its own {200} token. Syllable mode then gives the default mode's tokens for every input with the marks: ကꧦ → [ကꧦ], ကꧦꧦ → [ကꧦꧦ], ꧦ → [ꧦ]; ကောင်း µm → [ကောင်း, µ, m]. Search counts match the default mode (ကꧦ 1 of 2, က 1 of 2).
+# U+A9E6 and U+AA70, the Shan and Khamti reduplication marks
+$ModifierLetter = [[:Script=Myanmar:] & [:General_Category=Modifier_Letter:]];
 ...
-$MyanmarSyllableEx = $ConsEx ($Virama $ConsEx)? ($AsatEx)*;
+$MyanmarSyllableEx = $ConsEx ($Virama $ConsEx)? ($AsatEx)* ($ModifierLetter ($Extend | $Format)*)*;
 ...
 !!forward;
 $MyanmarJoinedSyllableEx {200};
+# any other letter of a Myanmar run is a token of its own
+[\p{L}] ($Extend | $Format)* {200};
Trade-offs
- Same tokens as the default mode, ICU's root iterator and StandardTokenizer for the marks; ကꧦ becomes a term distinct from က, so a syllable query for က no longer finds ကꧦ (as in the default mode).
- The catch-all makes each other letter a single-letter token: ကောင်း µµ gives
[ကောင်း, µ, µ]where the default mode gives[ကောင်း, µµ]. It is not limited to Myanmar letters:[\p{L}]applies to every letter the script iterator puts in a Myanmar run (Common and Inherited letters such as µ), a wider change than the two marks that maintainers may want to scope. - The marks attach only after a recognised syllable. After a number or a Common-script letter they fall to the catch-all and become their own token: ၁ꧦ (MYANMAR DIGIT ONE + U+A9E6) →
[၁, ꧦ], 1ꧦ →[1, ꧦ], µꧦ →[µ, ꧦ], where the default mode gives[၁ꧦ],[1ꧦ],[µꧦ](stock syllable mode:[၁],[1], no token). - Changes analysis output for syllable-mode users: a CHANGES line and a reindex note (old and new terms do not match each other). The compiled rules grow by 5,600 bytes, loaded once per JVM; tokenizing speed with the fix was not measured.
What the checks validated
- Gradle, JDK 25, scratch worktree at
a9779ef3c193: on stock the new test fails 4 of 6;regenerateRbbirewroteMyanmarSyllable.brk(13,896 to 19,496 bytes) and the checksum file, and leftDefault.brkunchanged. :lucene:analysis:icu:checkpasses: the checksum check, checkGoogleJavaFormat, ecjLint, forbiddenApis, checkLicenses and all module tests: 17 suites, 164 tests, 0 failed (the 6 new tests and 148 upstream tests,TestMyanmarSyllable21 of 21; the 10 tests ofTestICUTokenizerCJKare@AwaitsFix).- The module tests pass with assertions off (164 tests, 0 failed).
- Nightly mode: the finder's and the independent reproducer's tests, the new test,
TestMyanmarSyllableand a random-data check of syllable mode (checkRandomDataplus 2,000 × the test multiplier, so at least 2,000, random Myanmar-heavy strings throughcheckAnalysisConsistency): 40 tests, 0 failed. - The regenerated
.brkgives the same tokens as the rules compiled at runtime (12 inputs), and the standalone runner passes the new test 6 of 6 with it, assertions on and off.
Add [\p{L}] ($Extend | $Format)* {200}; after the syllable rule (MyanmarSyllable.rbbi:50), then regenerateRbbi (+2/-0 with its comment). The finder's fix; its regenerated .brk (19,136 bytes) is byte-identical to the finder's compiled file. ကꧦ → [က, ꧦ], ꧦ → [ꧦ], ကောင်း µm → [ကောင်း, µ, m]. Search: ကꧦ as a phrase matches 1 of 2, as a boolean query 2 of 2 (through the shared က), ꧦ 1 of 2.
 !!forward;
 $MyanmarJoinedSyllableEx {200};
+# any other letter of a Myanmar run is a token of its own
+[\p{L}] ($Extend | $Format)* {200};
Trade-offs
The smallest change, and syllable-level recall for က is kept. But the mark after a syllable becomes a separate token, unlike every other Lucene path, so text with marks gets a frequent one-letter term ꧦ that the default mode produces only for a lone mark. Same reindex note.
What the checks validated
Gradle, scratch worktree: :lucene:analysis:icu:check passes (164 tests, 0 failed, the same checks), and in nightly mode the finder's, the independent reproducer's and the new test, TestMyanmarSyllable and the random-data check: 40 tests, 0 failed. The module tests with assertions off were run with option B only.
myanmarAsWords="false" rulefiles="Mymr:MyanmarSyllableFixed.rbbi" on the icu factory, with a copy of MyanmarSyllable.rbbi plus fix B (or A); the factory compiles it at runtime (ICUTokenizerFactory.java:119, :137-151). Executed in the probe with both rule files: the fixed tokens. Or use the default myanmarAsWords=true, which keeps the marks.
Trade-offs
No Lucene change, but each application must carry its own rule file and keep it in sync with the shipped rules.
Not run.
Trade-offs
Changes no indexed terms, but leaves a mode that silently loses letters of the script it is for.
Elasticsearch and OpenSearch hard-code myanmarAsWords=true in their icu_tokenizer, so their users cannot reach this mode; Solr documents myanmarAsWords on solr.ICUTokenizerFactory, so a Solr schema can.
Semi-formal: a bounded-exhaustive sweep ran the stock tokenizers over 823 letter classes in many contexts and every string of up to 3 characters on a 107-character alphabet, checking that every letter or digit lands in some token. Letters lost only with myanmarAsWords=false formed this bug; an AI tool traced it to the rule file and wrote the JUnit.
The method in full144 words
Method: bounded-exhaustive content-coverage sweep on the stock main jars (the study's "semi-formal" tier), hunt unit "tokenizer content-coverage sweep", 2026-10-27. No model checker, SMT solver or proof produced the signal.
- The harness ran the tokenizer configurations, among them
ICUTokenizerwithmyanmarAsWords=false, over 823 letter-class representatives alone, in runs and in pairs with 107 context characters (3 orders), and over every string of length 1-3 on the 107 characters. Oracle: every letter or digit of the input lies inside some token. - The class is the misses that occur only with
myanmarAsWords=false, for example U+A9E6 alone. - An AI finder then probed the tokens in both modes, recompiled
MyanmarSyllable.rbbiwith ICU4J (the stock rules compile byte-identically to the shipped.brk) with one added rule, which isolated the root cause, and wrote the public-API JUnit; independent AI tools reproduced, reviewed and judged it (see the checks).
No prior report found in the sources searched (2026-10-27; gaps listed in the brief): 148 prior-report tool queries plus manual searches over GitHub issues, PRs and commits, JIRA, four mailing lists, downstream projects and the web, and all 409 open PRs. Closest: the change that added the option (#8446) and an open run-assignment issue (#10793), neither about lost letters.
Searches4 searches
Nothing reports that syllable mode drops letters. No open PR changes the rule file except #16911, which removes branch_10x; none of the 6 upstream main commits after a9779ef3c193 (up to 645d4fe14a2, 2026-10-28) touches analysis-icu.
Related, not the same bug: #8446 / LUCENE-7393 (added the option and restored the rules; concedes imperfect splitting of rare syllable structures); #10793 / LUCENE-9754 (open: Common characters after whitespace take the previous run's script, which causes an extra split under the default rules; context for the µ case only); #3243 / LUCENE-2167 (2010: a different tokenizer dropped Lao and Myanmar letters, fixed); #3489 / LUCENE-2414 (the original rules); #13239 (rewrote $Cons without discussing coverage).
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene) | 2026-10-27 | two runs of the hunt's prior-report tool (53 and 43 queries), the finder's (11) and the devil's advocate's (41); manual searches for MyanmarSyllable, TestMyanmarSyllable, Shan, myanmar in comments, syllable issues, ICUTokenizer with U+00B5, ruleStatus and Common script | no report; 0 high hits, every medium hit read |
| Open PRs and the rule file's history | 2026-10-27 | all 409 open apache/lucene PRs listed, the changed files of the 23 labelled analysis or naming ICU or tokenizers read; history of the rule file and its test on main, branch_10x and branch_10_5 | only #16911 (decommissions branch_10x) touches the rule file |
| JIRA and mailing lists | 2026-10-27 | LUCENE and SOLR projects (LUCENE-7393 and LUCENE-9754 read in full, five more grepped); dev@, java-user@, issues@ and commits@ | no report |
| Downstream and the web | 2026-10-27 | Elasticsearch, OpenSearch, Solr and Lucene.NET; web searches; the Stack Exchange API | no report; Elasticsearch and OpenSearch cannot select the mode |
Present since the option was added: LUCENE-7393 (#8446), committed 2016-07-28, first released in 6.2.0; not a regression, because it restored the 3.1-4.10.4 default rules, which already drop U+AA70 and µ the same way (U+A9E6 was not yet assigned in their Unicode version). Ten releases from 6.2.0 to 10.5.2 and main were run; all drop the marks.
Versions tested7 rows
Introduced by 5d88b242057 (branch_6x, shipped in 6.2.0) and 58f0fbd3767 (master, first released in 7.0.0), "LUCENE-7393: restore old myanmar syllable tokenization as an option", 2016-07-28, a JIRA patch with no PR. It restored, unchanged apart from whitespace, the Myanmar.rbbi rules of LUCENE-2414 (2010; 5abbf3429cf on trunk, shipped in 3.1 through the backport a1602caf91e), which were the default Myanmar tokenization in 3.1-4.10.4 until LUCENE-5995 (7a50635bc4c, 5.0) removed them. #13239 (54a2e11434d on main, first released in 10.0.0; the branch_9x backport 56d4578b253 shipped in 9.11.0) redefined $Cons and left the outcome unchanged; #14820 (53acee98589) changed whitespace only. Never fixed. The versions below are a sample: the release tags in the history clone (it lacks 8.8.2 and 8.9.0-8.11.4) hold only two versions of the rule file, both run, but 8 compiled .brk binaries, two of which (7.0.0-7.3.1, 7.4.0) were not run.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the brief's test 4 of 6 fail (gradle and the standalone runner, assertions on and off) |
| 10.5.2, 9.12.3 | affected | the brief's test 4 of 6 fail; the finder's 4 of 6; the independent reproducer's 5 of 5 |
| 10.0.0, 9.11.0, 9.10.0 | affected | the finder's JUnit 4 of 6 fail; the probe drops the marks (9.11.0 is the first release with the #13239 rules) |
| 6.2.0, 6.6.6, 7.7.3, 8.11.4, 9.0.0 | affected | the version-neutral probe drops U+A9E6, U+AA70 and µ through the constructor and the factory; the default mode keeps them |
| 6.1.0, 5.0.0 | API absent | no syllable option (6.1.0's factory rejects myanmarAsWords as an unknown parameter); the default mode keeps every letter |
| 4.10.4, 3.1.0 | precursor | the same rules are the default and drop U+AA70 and µ (U+A9E6 is unassigned in their ICU versions) |
| main + fix B or fix A | not affected | all repros pass; :lucene:analysis:icu:check 164 tests, 0 failed |
An independent reproducer, a devil's advocate, an adjudication and a later audit confirmed it with their own runs on main, assertions on and off. Two executed reviews by another model family (OpenAI GPT-5.6) found it real with high confidence and rated the works-as-intended case moderate.
Checks and verdicts403 words
Every check wrote or ran its own test against the stock jars, with assertions on and off unless noted.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | JUnit fails 4 of 6 on main (-ea, -da), 10.5.2 and 9.12.3; with the one-rule fix it passes, and so do the 21 upstream TestMyanmarSyllable tests. |
| cross-model review, refute lens | real (high) | An independent reviewer from another model family (OpenAI GPT-5.6), executed on ea57360912ed (analysis code identical to a9779ef3c193): its own test fails 4 of 6 (-ea), also on 10.5.2 and 9.12.3; a status probe shows status 0 for each lost piece; with the fix its test, TestMyanmarSyllable and the segmentation package pass. U+A9E6/U+AA70 decisive, µ weaker. |
| Independent reproducer | real | Own 5-test JUnit fails 5 of 5 on main, 10.5.2 and 9.12.3; its sweep of all 120 Script=Myanmar letters finds exactly U+A9E6 and U+AA70 lost; the shipped .brk is byte-identical to the recompiled rules. |
| Cross-model review, intended lens | real (high) | OpenAI GPT-5.6: intended-behaviour case moderate and rejected; its expectation test fails on main and passes with the fix; re-run on a9779ef3c193. |
| Devil's advocate | real | Real for U+A9E6/U+AA70, µ weaker; ran 4.10.4 (same drop by default) and 10.5.2, and checked the Thai, Lao and Khmer repetition marks. |
| adjudication | confirmed (medium) | Re-ran the independent reproduction's test with new seeds: 5 of 5 fail (-ea, -da), 5 of 5 pass with the fix. |
| security assessment | none | Loss confined to the value being tokenized; no exception, hang or cost blow-up; outside Lucene's SECURITY.md scope. |
| registry re-run and audit | keep | The finder's test re-run on a clean a9779ef3c193 with new seeds: 4 of 6 fail (-ea, -da); passes with the fix. |
| brief runs | reproduced | The brief's test through gradle (main) and the standalone runner (main, 10.5.2, 9.12.3); fixes B and A validated with the regenerated rules. |
| fact checks of this doc | reproduced; corrections applied | Independent fact checks (one by another model family, OpenAI GPT-5.6) checked every claim against the code at a9779ef3c193 and the runs. One re-ran the gradle repro (4 of 6 fail with assertions on and off), the standalone runner on main, 10.5.2 and 9.12.3, its own probe, and fix B (27 of 27 pass). Their corrections (a diff line count, the test-coverage claim, commit and release attributions, wording) are applied. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 476 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,552 words
- Registry title
- ICUTokenizer with myanmarAsWords=false silently drops the Myanmar modifier letters U+A9E6 and U+AA70 (Shan and Khamti reduplication, as in 'ကꧦ'), and Common-script letters such as MICRO SIGN that fall into a Myanmar run, because MyanmarSyllable.rbbi gives a token status only to syllables and numbers
- Area
- analysis / ICU (DefaultICUTokenizerConfig syllable rules MyanmarSyllable.rbbi / MyanmarSyllable.brk, used for Myanmar text when myanmarAsWords=false; ICUTokenizerFactory 'icu' with myanmarAsWords="false")
- Priority
- Low, rank 517: ICUTokenizer's non-default myanmarAsWords=false mode silently drops single rare modifier letters while the base syllable stays searchable, a runtime rare-input loss.
- Impact class
- silent wrong results
- Impact note
- Hits only applications that chose the non-default syllable mode of the opt-in ICU module (new DefaultICUTokenizerConfig(cjkAsWords, false), or ICUTokenizerFactory with myanmarAsWords="false"; the default mode keeps these letters) and that tokenize Shan or Khamti text with U+A9E6 or U+AA70, or Myanmar text followed by a Common-script letter such as µ: the letter is missing from the index with no error, so 'KA + U+A9E6' and 'KA' become the same term (lower precision; with the same analyzer at query time the base syllable still matches), a mark on its own gives no token and cannot be searched, and offsets and highlighting skip it; no scale is needed.
- Summary
- You tokenize Myanmar-script text with ICUTokenizer in syllable mode (new DefaultICUTokenizerConfig(true, false), or ICUTokenizerFactory with myanmarAsWords="false"), whose only documented effect is that Myanmar text 'will be tokenized as syllables', and expect every letter to end up in some token, as in the default mode, where 'ကꧦ' (KA + U+A9E6 MYANMAR MODIFIER LETTER SHAN REDUPLICATION) gives [ကꧦ] and 'ကꩰ' (KA + U+AA70 MYANMAR MODIFIER LETTER KHAMTI REDUPLICATION) gives [ကꩰ]. Instead syllable mode gives [က] for both, a mark on its own gives no token, and 'ကောင်း µm' gives [ကောင်း, m] (the space and µ are Common script, so the script iterator keeps them in the Myanmar run), all without an error. The cause is the rule file: MyanmarSyllable.rbbi gives a non-zero rule status only to syllables built on a consonant, consonant placeholder or independent vowel ({200}) and to numbers ({100}), and ICUTokenizer skips every segment with status 0.
- Introduced
- 5d88b242057177410a90a2ea74b07d6e25b4ac84 (branch_6x, first released in 6.2.0); the same change on master is 58f0fbd3767af649da1d47ea62f6f35b1ae28c19 (first released in 7.0.0). LUCENE-7393 = GitHub #8446 'restore old myanmar syllable tokenization as an option', by rmuir, committed from a JIRA patch with no pull request. It added the option and restored, unchanged apart from whitespace, the Myanmar.rbbi rules of LUCENE-2414 (5abbf3429cf, 2010, first in 3.1), which were the default Myanmar tokenization in 3.1-4.10.4 and dropped the same letters until LUCENE-5995 (7a50635bc4c, 5.0) removed them. #13239 (54a2e11434d / 56d4578b253, 9.11.0) redefined $Cons through Indic_Syllabic_Category and left the outcome unchanged, because U+A9E6 and U+AA70 are gc=Lm and ISC=Other. Not a regression of the option [read: git log and git blame in the full-history clone; exec: 6.1.0 has no option, 6.2.0 fails] (2016-07-28 (5d88b242057 and 58f0fbd3767; the 6.2.0 tag commit is dated 2016-08-20))
- First affected version
- 6.2.0 [exec] (the first release with myanmarAsWords; 6.1.0 [exec] has no DefaultICUTokenizerConfig(boolean, boolean) constructor and its factory rejects myanmarAsWords=false as an unknown parameter)
- Affected versions
- Every release from 6.2.0 through 10.5.2 and main a9779ef3c193 (unreleased 11.0) [exec: a version-portable main() probe drops U+A9E6, U+AA70 and MICRO SIGN in syllable mode, through both the config constructor and the factory option, with the default-mode control keeping all three, on 6.2.0, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.10.0, 9.11.0, 9.12.3, 10.0.0, 10.5.2 and main; the candidate JUnit fails 4 of 6 on 9.10.0, 9.11.0, 9.12.3, 10.0.0, 10.5.2 and main (-ea and -da); the independent reproduction's JUnit fails 5 of 5 on main (-ea and -da), 10.5.2 and 9.12.3]. By reading, the rule file has two versions with the same status rules, the original (6.2.0-9.10.0) and the #13239 rewrite (9.11.0-10.5.2), and both were executed. Precursor on a different API path: the same rules were the default Myanmar tokenization in 3.1 through 4.10.4 and drop U+AA70 and MICRO SIGN the same way [exec: 3.1.0 and 4.10.4 with the default ICUTokenizer; U+A9E6 is unassigned in their ICU versions]; 5.0.0 to 6.1.0 have neither the rules nor the option [exec: 5.0.0, 6.1.0]. Not fixed: the two upstream main commits after a9779ef3c193 (a95c754ee003, ffa9d816eeb4) touch no analysis-icu file, and no open PR changes the rule file (only #16911, which deletes branch_10x) [read].
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (the prior-report record verdict new, searched 2026-10-27, read-only): two scripted prior-report searches (53 and 43 queries over GitHub issues, PRs and commits, downstream repositories, the dev, java-user, issues and commits lists and the JIRA archive; 188 and 67 distinct hits, 0 high, every medium hit read), plus the finder's run (11 queries, 0 high) and the intended-behaviour check's (41 queries, 0 high); manual apache/lucene searches (MyanmarSyllable, TestMyanmarSyllable, Shan, myanmar in comments, syllable issues, ICUTokenizer with U+00B5, ruleStatus or Common script); the history of the rule file and its test on main, branch_10x and branch_10_5; all 409 open apache/lucene PRs listed and the changed files of the 23 labelled module:analysis or naming ICU or tokenizers read (only #16911, which decommissions branch_10x, touches the rule file); JIRA (LUCENE and SOLR; LUCENE-7393 and LUCENE-9754 read in full, five more grepped); the lists; downstream repositories (Elasticsearch and OpenSearch hard-code myanmarAsWords=true; Solr documents the option); web searches and the Stack Exchange API. Nearest items, none a report of this bug: #8446 (LUCENE-7393, added the option and restored the rules; rmuir said the rules 'are not perfect' and have 'no rules for rarer cases', about syllable splitting, not lost letters), open #10793 (LUCENE-9754: Common characters after whitespace take the previous run's script, which causes an extra split under the default rules; the same run assignment routes MICRO SIGN into the Myanmar run in the secondary case, but nothing is lost there and its proposed fixes would at most hide that case), #3243 (LUCENE-2167, 2010: a different tokenizer dropped Lao/Myanmar letters, treated as a defect and fixed), #3489 (LUCENE-2414, the original rules) and #13239 (rewrote $Cons without discussing letter coverage). Not fixed: upstream main after a9779ef3c193 changes no analysis-icu file. Gaps: GitHub's search rate limit (403s retried after a 60 s back-off); Stack Overflow only through its public API; the ICU project's tracker was not searched (the defect is in Lucene's rule file). Update 2026-11-02: #16911 (open when searched) merged 2026-10-29 as 48cf3f515d6, which emptied branch_10x to a README tombstone (10.6 is the last 10.x minor; 10.x fixes go to branch_10_6); it fixes nothing here.
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-28) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the 10.5.2 and 9.12.3 release jars with the same test; a version-neutral probe on 6.2.0, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.10.0, 9.11.0, 9.12.3, 10.0.0 and 10.5.2, and the finder's JUnit on 9.10.0, 9.11.0, 9.12.3, 10.0.0 and 10.5.2 (all affected; 6.1.0 has no option; with their default rules 3.1.0 and 4.10.4 drop U+AA70 and µ, U+A9E6 being unassigned there) (2026-10-27). Both fixes were validated in the scratch worktree withMyanmarSyllable.brkregenerated by the build'sregenerateRbbitask: the new test,:lucene:analysis:icu:check(164 tests, 148 of them upstream tests that ran, plus format, lint, forbidden-API and checksum checks), the module tests with assertions off (fix B), and in nightly mode the finder's and the independent reproducer's tests plus a random-data check.
- Finding record
a Lucene main checkout lucene/analysis/icu/src/data/uax29/MyanmarSyllable.rbbi:18 ('Parses Myanmar text, with syllable as token'), :21-27 ($Consonant, $ConsonantPlaceholder, $VowelIndependent via Indic_Syllabic_Category; $Cons), :44-47 (syllable structure), :50 ('$MyanmarJoinedSyllableEx {200};'), :53 (numeric rule {100}); lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/segmentation/ICUTokenizer.java:31-38 (class javadoc 'Breaks text into words according to UAX #29', @lucene.experimental), :209-213 (incrementTokenBuffer skips segments with rule status 0); DefaultICUTokenizerConfig.java:97-98 (javadoc: myanmarAsWords 'true if Myanmar text should undergo dictionary-based segmentation, otherwise it will be tokenized as syllables'), :115-120 (UScript.MYANMAR -> myanmarSyllableIterator when myanmarAsWords is false); ICUTokenizerFactory.java:97 (myanmarAsWords defaults to true), :112 and :122 (passed to DefaultICUTokenizerConfig); lucene/analysis/icu/src/test/org/apache/lucene/analysis/icu/segmentation/TestMyanmarSyllable.java (21 tests, Burmese syllable categories only)
- The finding in 30 seconds
lucene/analysis/icu/src/data/uax29/MyanmarSyllable.rbbi:18, (at a9779ef3c193) :21-27, :44-50, :53lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/segmentation/ICUTokenizer.java:209-214; (at a9779ef3c193) DefaultICUTokenizerConfig.java:83-84, :97-98, :115-120; ICUTokenizerFactory.java:97
- Who is affected
lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/segmentation/ICUTokenizerFactory.java:86-97, (at a9779ef3c193) :119-131; DefaultICUTokenizerConfig.java:115-120
- Why it looks unintended
lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/segmentation/DefaultICUTokenizerConfig.java:97-98; (at a9779ef3c193) ICUTokenizer.java:31-32, :209-214; lucene/analysis/icu/src/data/uax29/MyanmarSyllable.rbbi:18, :21-27lucene/CHANGES.txt:9052-9054 (at a9779ef3c193) (under 6.2.0, heading :8925)lucene/analysis/icu/src/test/org/apache/lucene/analysis/icu/segmentation/TestMyanmarSyllable.java:37, (at a9779ef3c193) :60-61; lucene/analysis.tests/src/test/org/apache/lucene/analysis/tests/TestRandomChains.java:496-499
- Suggested fix
lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/segmentation/ICUTokenizerFactory.java:119, (at a9779ef3c193) :137-151; lucene/analysis/icu/build.gradle:137-164 (regenerateRbbi)
- History
lucene/CHANGES.txt:9052-9054 (at a9779ef3c193) (under 6.2.0)
- TestMyanmarSyllableModifierLetter.java (JUnit test):
repro/LFV-720/src/org/apache/lucene/analysis/icu/segmentation/TestMyanmarSyllableModifierLetter.java(40 lines)
Made in parallel with this doc from executed probes on main a9779ef3c193, stock and with the finder's one-line fix (fix A) compiled into MyanmarSyllable.brk. The picture shows fix A, which makes the mark its own token ([က, ꧦ]); the recommended fix B attaches it instead ([ကꧦ]). The stock tokens and search counts in the picture are the same as in this doc's probe.
assets/LFV-720/bug.png(476 KB)