COMPOUNDWORDMAX n caps the number of words in a compound. Lucene counts a compound's parts only from the second part on, so a cap of 1 never fires: two-word compounds pass, three-word ones are still rejected. Caps of 2 or more are exact.
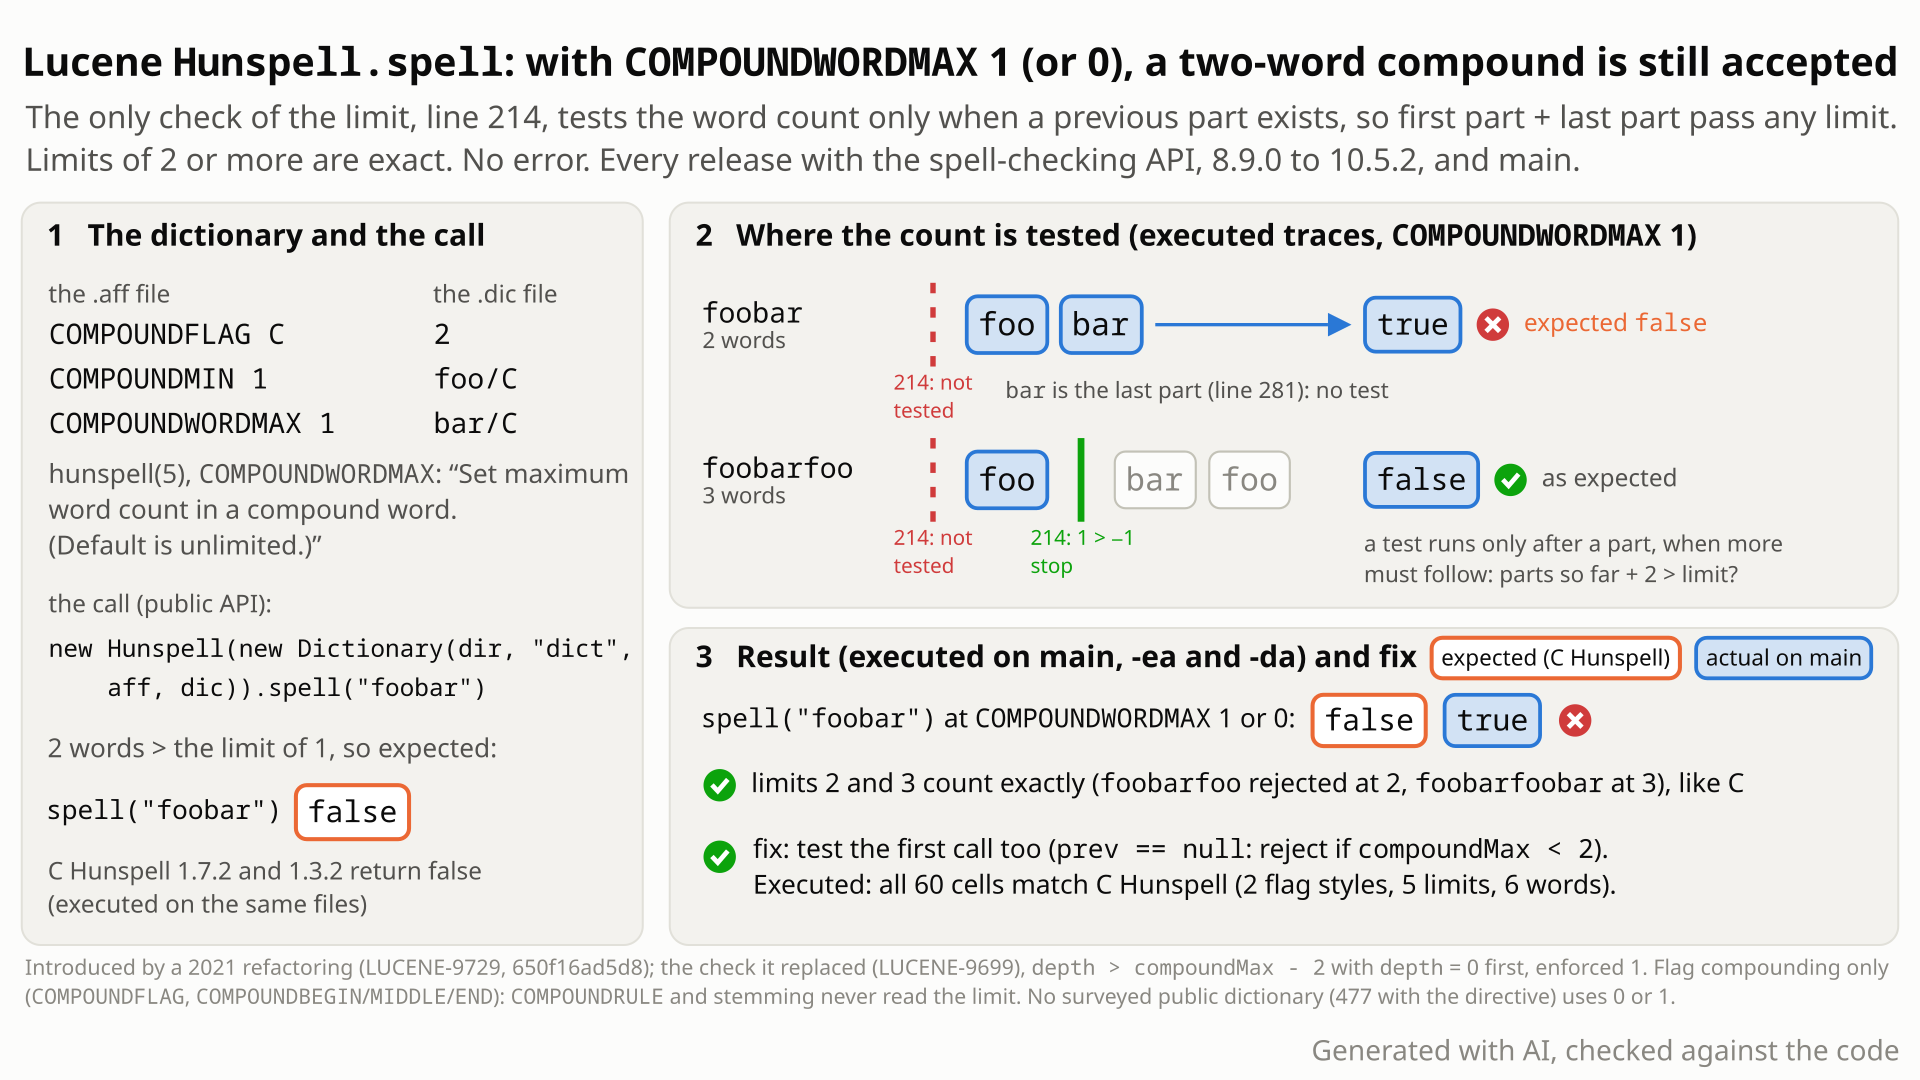
COMPOUNDWORDMAX 1: Lucene splits foobar into foo and bar, never counts the first part, and accepts the compound; C Hunspell counts both parts and rejects it. Select the still to open it at full size. Generated with AI, checked against the code.- You load a dictionary with
COMPOUNDFLAG C,COMPOUNDMIN 1and the wordsfoo/Candbar/C, sofoobaris a two-word compound. WithCOMPOUNDWORDMAX 2, Lucene acceptsfoobarand rejects the three-wordfoobarfoo, as it should. - You set
COMPOUNDWORDMAX 1(at most one word per compound) and callspell("foobar"). You expectfalse: C Hunspell 1.3.2 and 1.7.2 return false. - Instead Lucene returns
true. It still rejectsfoobarfoo, so only two-word compounds slip through.COMPOUNDWORDMAX 0andCOMPOUNDBEGIN/COMPOUNDENDcompounds behave the same. - Why: the count check at the top of
checkCompounds(Hunspell.java:214) runs only when there is a previous part. Nothing counts the first part, andcheckCompoundsAfteraccepts first part + last part without a check, so a limit of 1 never fires. - The original code (LUCENE-9699) rejected every flag compound at 1; a refactoring a week later dropped that check, before any release. No public dictionary found uses 0 or 1.
Applications that use Lucene's opt-in Hunspell spell checker (Hunspell.spell, suggest) with a dictionary that combines compound flags with COMPOUNDWORDMAX 1 or 0. None of 477 public .aff files with the directive uses those values, so the reach is small. Lucene's stemming (Stemmer, HunspellStemFilter) is unchanged; code that calls spell or suggest in its own pipeline sees the bug.
Mechanism, terms and numbers647 words
COMPOUNDWORDMAX n in a Hunspell affix file caps how many words a compound may have (hunspell(5): "Set maximum word count in a compound word"). Lucene's spell checker checks the cap only before it adds a third or later part: the check at the top of checkCompounds (Hunspell.java:214 on main a9779ef3c193) is skipped when there is no previous part, and checkCompoundsAfter (:269-286) accepts the first part plus a last part without counting. For a cap of 2 or more that is exact, but a cap of 1 never fires for a two-word compound. So with COMPOUNDFLAG C, COMPOUNDMIN 1, COMPOUNDWORDMAX 1 and the words foo/C, bar/C, spell("foobar") returns true, while C Hunspell 1.3.2 and 1.7.2 return false. COMPOUNDWORDMAX 0 (which the parser clamps to 1) and COMPOUNDBEGIN/COMPOUNDEND compounding behave the same; three or more words are still rejected. The code that added the directive (LUCENE-9699) rejected every flag compound at 1; the LUCENE-9729 refactoring dropped the first-part check before any release, so every release with the spell-checking API, 8.9.0 to 10.5.2, is affected. The reach is small: none of 477 public .aff files with the directive uses 0 or 1, and Lucene's stemming is not affected.
- Flag compound: a word Lucene accepts because its parts carry
COMPOUNDFLAG, orCOMPOUNDBEGIN/COMPOUNDMIDDLE/COMPOUNDEND.COMPOUNDMINis the shortest allowed part (default 3). COMPOUNDWORDMAX n: hunspell(5) "Set maximum word count in a compound word. (Default is unlimited.)". Lucene parses it asMath.max(1, n)(Dictionary.java:439), so 0 acts as 1; the default isInteger.MAX_VALUE(:152).
foobaris not a dictionary word, socheckCompounds(char[], ...)(Hunspell.java:150-161) takes the flag path and callscheckCompounds(word, originalCase, null)(:157): no previous part.- That method starts with the only word-count check in the package's production code (
:214):if (prev != null && prev.index > dictionary.compoundMax - 2) return false;.previs null, so nothing is checked. foois found as a first part and wrapped in aCompoundPartwithindex1 (:372);checkCompoundsAfteris called (:234-236).checkCompoundsAfter(:269-286) findsbaras a valid last part and returnstrue(:276-281). It checks forbidden words, CHECKCOMPOUNDDUP, FORCEUCASE andmayCompound, but not the count.- Only when the rest is not a valid last part does it recurse with
prev=foo(:285); then1 > 1 - 2rejects a third part.
So for a limit n >= 2 the check rejects exactly the (n+1)-th part, and for n = 1 the second, last part is never counted.
In compound_check the second word is accepted only if (cpdwordmax == -1) || (wordnum + 1 < cpdwordmax) (1.7.2 affixmgr.cxx:1928 and :2067; the same condition in compound_check_morph at :2516 and :2655), with wordnum 0 at the first call (hunspell.cxx:895). So 0 and 1 reject every two-word flag compound, unless the Hungarian COMPOUNDSYLLABLE escape on the same line applies, which Lucene does not implement.
COMPOUNDWORDMAX | word | parts | C Hunspell 1.7.2 | Lucene main |
|---|---|---|---|---|
| 2 | foobar | 2 | true | true |
| 2 | foobarfoo | 3 | false | false |
| 1 | foo | 1 | true | true |
| 1 | foobar | 2 | false | true |
| 1 | foobarfoo | 3 | false | false |
Over grids with both flag styles, limits absent, 0, 1, 2 and 3, and words of 1 to 4 parts, Lucene and C disagree only on the two-word compound at 0 and 1 (70 cells against C 1.7.2: 4 mismatches; 48 comparisons against C 1.3.2: 6). C 1.7.2 and 1.3.2 both reject the exact foobar at 0 and 1 and accept it at 2, in both flag styles. suggest() uses the same check: at limit 1 it offered the over-limit compound northstar for the typo northstarr (not compared with C's suggestions).
Exposure and likelihood277 words
- Who is hit. Callers of
Hunspell.spellandHunspell.suggest(lucene-analysis-common) with a dictionary that uses flag compounding and setsCOMPOUNDWORDMAX 1or0. The checker is opt-in: the application loads a dictionary of its choice, and no default analyzer uses it. - What they get.
spellsays "correct" for every two-word flag compound the dictionary can build, which is exactly what the author tried to forbid;suggestcan offer such compounds. No exception, the same result with assertions on and off, deterministic, no scale needed. - How likely. Low. The setting is self-contradictory (declare compound flags, then allow one word per compound). A code search found 477 public
.afffiles withCOMPOUNDWORDMAX, none with 0 or 1 (values: 4 in 227 files, 2 in 148, 10 in 71, 3 in 20, 100 in 7, 7 in 4); it covers only what the search indexes. A maintainer who sets 1 to switch flag compounding off without removing the flags would hit it; no such dictionary is known. - Not affected. Limits of 2 or more and the default (unlimited); three or more words at 1;
COMPOUNDRULEcompounds (compoundMaxis never consulted there, and C Hunspell 1.3.2 also accepts two rule parts at 1); Lucene's stemming:Stemmerstems only simple words (Stemmer.java:94-103) andHunspellStemFiltercalls it (HunspellStemFilter.java:108-114), so it never splits compounds ("No roots are returned for compound words",Hunspell.java:300). Code that callsspellorsuggestin its own indexing or query pipeline does see the bug. - Severity. A spell-check verdict error in an opt-in component for an unusual setting: impact minor, likelihood contrived, priority low. Best framed as a small consistency and C-parity fix.
The test shows that with COMPOUNDFLAG C, COMPOUNDMIN 1, COMPOUNDWORDMAX 1 and the words foo/C, bar/C, Hunspell.spell("foobar") accepts the 2-word compound.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.hunspell;

import java.io.ByteArrayInputStream;
import java.nio.charset.StandardCharsets;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestCompoundWordMaxOne extends LuceneTestCase {

  public void testTwoWordCompoundAtMaxOne() throws Exception {
    String aff = "COMPOUNDFLAG C\nCOMPOUNDMIN 1\nCOMPOUNDWORDMAX 1\n";
    String dic = "2\nfoo/C\nbar/C\n";
    Dictionary dictionary =
        new Dictionary(
            new ByteBuffersDirectory(),
            "dict",
            new ByteArrayInputStream(aff.getBytes(StandardCharsets.UTF_8)),
            new ByteArrayInputStream(dic.getBytes(StandardCharsets.UTF_8)));
    // hunspell(5): COMPOUNDWORDMAX = maximum word count in a compound; expected false, actual true
    assertFalse(
        "COMPOUNDWORDMAX 1: spell(\"foobar\") (2 words) expected false, was true",
        new Hunspell(dictionary).spell("foobar"));
  }
}
# in a copy of this finding's repro folder (repro/LFV-724/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.hunspell.TestCompoundWordMaxOne
- Expected vs actual
- Expected: false (hunspell(5): COMPOUNDWORDMAX is the maximum word count in a compound; C Hunspell rejects it); actual (-ea and -da): true, because checkCompounds never counts the first part.
More files, environment, full output39 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: COMPOUNDWORDMAX 1: spell("foobar") (2 words) expected false, was true
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.assertTrue(Assert.java:42)
       org.junit.Assert.assertFalse(Assert.java:65)
org.apache.lucene.analysis.hunspell.TestCompoundWordMaxOne.testTwoWordCompoundAtMaxOne(TestCompoundWordMaxOne.java:36)- hunspell(5): "Set maximum word count in a compound word." C Hunspell 1.3.2 and 1.7.2 reject
foobarat 1 and at 0. - Lucene enforces limits of 2 and 3 exactly, and at 1 it still rejects three words.
- The original LUCENE-9699 code rejected every flag compound at 1; the LUCENE-9729 refactoring dropped that check without discussion.
The full argument416 words
- The format defines a word count. hunspell(5) of C Hunspell 1.7.2: "COMPOUNDWORDMAX number: Set maximum word count in a compound word. (Default is unlimited.)". A two-word compound exceeds a maximum of 1.
- Lucene aims at Hunspell behaviour. The class javadoc says the class "can be used in place of native Hunspell for many languages for spell-checking and suggesting purposes" (
Hunspell.java:35-36). The promise is qualified ("Note that not all languages are supported yet. For example:" Hungarian, non-BMP characters, PHONE;:36-44); the list is not exhaustive, but none of its entries covers a compound word limit.spellreturns "whether the given word's spelling is considered correct according to Hunspell rules" (:72). - Lucene is inconsistent with itself. At 2,
foobaris accepted andfoobarfoorejected (this doc's control test, the independent reproducer and the devil's advocate); at 3, three parts are accepted and four rejected (the last two); at 1, three words are rejected. Only the two-word case at 1 (and 0) differs. - C Hunspell rejects it. 1.3.2 and 1.7.2 reject
foobarat 1 and at 0 and accept it at 2, in both flag styles; a second 1.7.2 build (a Linux distribution package) agrees at 1 and 2. This followswordnum + 1 < cpdwordmaxwithwordnum0 at the first part; the rule's HungarianCOMPOUNDSYLLABLEescape is not set in these dictionaries. - The original code enforced 1. LUCENE-9699 (
a176308aa63, 2021-01-27, apache/lucene-solr#2248, issue #10738) added the directive withif (depth > dictionary.compoundMax - 2) return false;, run with depth 0 at the first part, so a limit of 1 rejected every flag compound (COMPOUNDRULEcompounds were checked first, on a path without a limit). LUCENE-9729 (650f16ad5d8, 2021-02-05, apache/lucene-solr#2300, issue #10768, "Hunspell: support CHECKCOMPOUNDREP flags") replaced the depth counter by theCompoundPartchain and wrote the current guard;prev != nullis the null guard thatprev.indexneeds. The PR body, its single review comment (about CheckCompoundPattern offsets) and the issue never mention COMPOUNDWORDMAX. Commit-level runs: the parent16764f16010enforces 1,650f16ad5d8does not. - Not a listed divergence. Lucene's test over C Hunspell's own test cases names the cases it expects to fail,
TestHunspellRepositoryTestCases.EXPECTED_FAILURES(hu, morph, opentaal_keepcase, nepali, utf8_nonbmp, phone). That is an exception set for one test corpus, not a full catalogue of accepted differences; this case is not in it. Lucene's tests use COMPOUNDWORDMAX only with the value 2, as a parse check (forgivable-errors.aff,TestDictionary.testForgivableErrors); no test exercises the limit inspell.
The devil's-advocate check271 words
The strongest case for "intended": (a) a limit of 1 is degenerate, because a compound has at least two words and an author who wants none would not declare a compound flag; (b) hunspell(5) presents COMPOUNDWORDMAX among the options for the Hungarian "6-3" rule (with COMPOUNDSYLLABLE, COMPOUNDROOT and SYLLABLENUM), and Lucene does not support Hungarian; C's count condition itself has a COMPOUNDSYLLABLE escape; (c) the Math.max(1, n) clamp could suggest that values below 2 were never meant to limit anything; (d) on the COMPOUNDRULE path C Hunspell 1.3.2 and Lucene both accept two parts at 1; (e) Lucene's parity promise is qualified ("for many languages", exceptions given "for example"), and every release has behaved this way.
Why it fails: (a) is about impact, not intent, and is reflected in the "minor" rating; the directive takes any number and the man page gives no lower bound. (b) Lucene parses and enforces COMPOUNDWORDMAX for every dictionary, and the trigger uses no Hungarian option. (c) The clamp came with LUCENE-9699, whose check did enforce 1 (0 and 1 behaved alike, as in C), so it never meant "no limit". (d) This report is about flag compounds only, where C enforces the limit and Lucene enforces it for 2 and 3. (e) A qualified promise does not make a silently lost check intended; the change came in a refactoring that never discussed the limit. Every reviewer rated the intended argument weak as a case that today's result is correct; the cross-model fact check rated it moderate as a "won't fix / very low priority" argument, so keep the issue small. Verdict: not intended, a defect.
Recommended Check the limit for the first part too
Check the limit for the first part too: in checkCompounds, if (prev == null ? compoundMax < 2 : prev.index > compoundMax - 2) return false;. Then 0 and 1 reject every flag compound, as in C. Validated: the repro passes, and the lucene/analysis/common tests run 1,913 tests with 0 failures (18 skipped).
   private boolean checkCompounds(CharsRef word, WordCase originalCase, CompoundPart prev) {
-    if (prev != null && prev.index > dictionary.compoundMax - 2) return false;
+    if (prev == null ? dictionary.compoundMax < 2 : prev.index > dictionary.compoundMax - 2) {
+      return false;
+    }
All options and trade-offs3 options · 550 words
One fix (A, the finder's one-line change) was applied in a scratch worktree at a9779ef3c193 and run through gradle, and shadowed onto the stock jars for every other repro of the hunt. B and C are alternatives that were not run.
Hunspell.java only, +3/-1. With no previous part, the compound being built has at least two words, so it is allowed only if compoundMax >= 2. This restores the LUCENE-9699 behaviour (depth > compoundMax - 2 with depth 0) and matches C's wordnum + 1 < cpdwordmax with wordnum 0; later parts are unchanged. The check runs before the CHECKCOMPOUNDPATTERN replacements, so they are limited the same way. The COMPOUNDRULE path is untouched, and for 0 and 1 the Math.max(1, n) clamp needs no change. Open point, negative values: C treats -1 as "unlimited" (atoi, affixmgr.cxx:129, :1928), Lucene clamps every value below 1 to 1 (Dictionary.java:439). Executed: at -1, C 1.7.2 and 1.3.2 accept every compound, main accepts two words but rejects three, and with the fix every flag compound is rejected; at -2 the fix matches C. No surveyed dictionary uses a negative value; mapping -1 to unlimited would need its own decision and test.
   private boolean checkCompounds(CharsRef word, WordCase originalCase, CompoundPart prev) {
-    if (prev != null && prev.index > dictionary.compoundMax - 2) return false;
+    if (prev == null ? dictionary.compoundMax < 2 : prev.index > dictionary.compoundMax - 2) {
+      return false;
+    }
Trade-offs
One comparison per top-level call; no benchmark was run. Dictionaries with COMPOUNDWORDMAX 0 or 1 and compound flags stop accepting two-word compounds, which is what the directive says and what C Hunspell does.
What the checks validated
- Stock main
a9779ef3c193, gradle: the repro fails 3 of 4 (the claim tests) with assertions on and off. - With the fix, gradle: the repro passes 4 of 4 with assertions on and off; the whole
lucene/analysis/commontest task with assertions on, repro included, runs 340 classes, 1,913 tests, 0 failures, 18 skipped (the hunspell package: 47 classes, 162 tests, 13 skipped, becauseTestAllDictionaries,TestHunspellRepositoryTestCasesandTestPerformanceneed external dictionaries;TestSpellChecking, 53 tests, passes);checkGoogleJavaFormat,ecjLint,forbiddenApisMainandforbiddenApisTestpass with fix and test in place. - Classpath runner with the fix shadowed: this doc's test 4 of 4; the finder's test; the independent reproducer's 8 of 8; a 70-cell grid against C Hunspell 1.7.2 with 0 mismatches; 810
.good/.wrongexpectations over 53 upstream dictionaries unchanged; a separate, narrower JUnit 4 class-path run of Lucene's hunspell test classes (all butTestHunspellRepositoryTestCases) passes 146 tests, a count not comparable with gradle's. - Not run: the full Lucene suite, the external-dictionary suites, a benchmark.
Before accepting the last root (Hunspell.java:276-281), require prev.index + 1 <= compoundMax.
Trade-offs
Same effect, but it splits the limit check across two methods, and CHECKCOMPOUNDPATTERN replacements reach checkCompoundsAfter too. Not run.
Add && dictionary.compoundMax >= 2 to the flag-path condition in checkCompounds(char[], ...) (Hunspell.java:156).
Trade-offs
Smallest reasoning about the degenerate value, but it leaves the misleading first-part gap in the guard at :214. Not run.
Downstream token filters built on HunspellStemFilter are not affected; only code that calls Lucene's spell-checking API (Hunspell.spell, suggest) with such a dictionary gets the wrong verdict.
Differential testing of Lucene's Hunspell.spell against C Hunspell 1.7.2 on generated compounding dictionaries with COMPOUNDWORDMAX 1, 2 and 3: all 11 disagreements were two-word compounds at limit 1, and limits 2 and 3 never disagreed. The case was then minimized into a public-API JUnit on the stock jar.
The method in full147 words
Method: cross-implementation differential testing (not a formal method). A grammar generated small synthetic compounding dictionaries, with COMPOUNDWORDMAX drawn from {1, 2, 3}, and compared the stock jar's Hunspell.spell with C Hunspell 1.7.2 on the generated words.
- 11 disagreements came out (9 dictionaries of one seed, 2 of another), all with
COMPOUNDWORDMAX 1and a two-part compound; limits 2 and 3 never disagreed. - The finder minimized them to the foo/bar dictionary, wrote a public-API JUnit, ran it on main (
-ea,-da), 10.5.2 and 9.12.3, and checked C Hunspell 1.7.2 (a build from the release source, with the hunt's test hooks off, and a Linux distribution build) on the same files. - Before submitting, an independent reviewer from another model family (OpenAI GPT-5.6) tried to refute the claim with its own test; it agreed, and pointed out that the original LUCENE-9699 code enforced a limit of 1.
No prior report found (2026-10-27): 129 query records over GitHub issues, PRs and commits, JIRA, the dev@, java-user@, issues@ and commits@ lists, downstream projects and the web, plus a listing of all 410 open PRs and the changed files of the 16 analysis PRs. Not fixed upstream.
Searches3 searches
Closest items, none the same bug: #10768 (LUCENE-9729, the introducing change), #10738 (LUCENE-9699, which added the directive and enforced 1), #10726 (LUCENE-9687, the umbrella issue, with its 8.x backport apache/lucene-solr#2499), open #16422 (a stale Dictionary.java parse refactor that keeps the clamp) and #16911 (deletes the branch_10x tree). An outside spell checker (BarMal/Serenity#1198) read Lucene's Hunspell.java while implementing COMPOUNDWORDMAX and does not mention a limit of 1. Limits: keyword searches cannot prove absence, private channels are not visible, and open PRs outside the 16 analysis PRs, or opened after the 2026-10-27 listing, were not inspected file by file.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; downstream repositories (Elasticsearch, OpenSearch, Solr); dev@, java-user@, issues@ and commits@; JIRA; the web | 2026-10-27 | a scripted prior-report search, two runs, 110 records (57 and 53; run B's 6 web queries only planned, as they overlap run A's) (identifiers such as COMPOUNDWORDMAX, compoundMax, checkCompounds, CompoundPart; symptom phrases) | no report; repo:apache/lucene COMPOUNDWORDMAX 0 results; COMPOUNDWORDMAX 0 mails on dev@, java-user@ and issues@ (9 commit-diff mails on commits@); JIRA 0 |
| GitHub, the web and git history (manual) | 2026-10-27 | 19 records (14 GitHub and git-history, 5 web searches), among them a listing of all 410 open apache/lucene PRs and the file lists of the 16 analysis PRs | of the 16 analysis PRs only #16422 and #16911 touch hunspell sources; neither changes the check on main (#16911 deletes the branch_10x tree) |
| earlier independent searches | 2026-10-27 | Verifiers' own prior-art runs (9 and 43 queries) | no report |
Introduced by LUCENE-9729 (650f16ad5d8, 2021-02-05), a refactoring that dropped the first-part check LUCENE-9699 had added a week earlier; both predate any release. First released in 8.9.0 through the 8.x backport; fails on every release tested from 8.9.0 to 10.5.2 and on main. Not fixed upstream.
Versions tested9 rows
Introduced by 650f16ad5d8 "LUCENE-9729: Hunspell: support CHECKCOMPOUNDREP flags (#2300)" (@donnerpeter, 2021-02-05, issue #10768), in its refactoring sub-commit f78cc2563024 (2021-02-03). It replaced if (depth > dictionary.compoundMax - 2) return false; (from LUCENE-9699, a176308aa63, 2021-01-27, with depth 0 at the first part) by if (prev != null && prev.index > dictionary.compoundMax - 2) return false;, which skips the first part. The code reached 8.x through the backport apache/lucene-solr#2499 (LUCENE-9687, merged 2021-05-28). Since both the feature and the regression predate every release, no release ever enforced a limit of 1.
Versions not executed are covered by reading: the guard line is byte-identical in all 33 release tags from 9.0.0 to 10.5.2, and the bytecode of every 8.x jar with the API (8.9.0, 8.10.0, 8.10.1, 8.11.0 to 8.11.4) has the same guard; of these only 8.9.0 and 8.11.4 were run. Commit-level runs compile each commit's hunspell sources over the 9.0.0 jars; they are not full builds. Hunspell.java:214 is unchanged on upstream main a95c754ee003 (2026-10-26) and c5ab3e57b9ba (2026-10-28).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's JUnit fails 3 of 4 through gradle, assertions on and off; the finder's and the reproducer's tests fail with -ea and -da |
| 10.0.0, 10.5.2 | affected | the finder's test fails; this doc's JUnit fails 3 of 4 on 10.5.2 |
| 9.0.0, 9.1.0, 9.12.3 | main line from 9.0.0 | the finder's test fails |
| 8.9.0, 8.11.4 | first release | the finder's test (pre-9.1 import) fails |
| 8.10.0, 8.10.1, 8.11.0 to 8.11.3 | by bytecode | not run; javap shows the same guard in each jar |
| 8.8.2 | no spell-checking API | the repro does not compile (no Hunspell class) |
a176308aa63, 9d45dfe776a, parent 16764f16010 (commit-level) | before the change | a limit of 1 is enforced (a176308aa63: COMPOUNDBEGIN/END path only; COMPOUNDFLAG support came later) |
650f16ad5d8 (commit-level) | introducing commit | fails on the COMPOUNDFLAG and the COMPOUNDBEGIN/END path |
| main + recommended fix | not affected | this doc's JUnit passes 4 of 4; every other repro of the hunt passes |
An independent reproducer and an intended-behaviour devil's advocate reproduced it with their own tests and C Hunspell runs; two executed reviews by a model from another family (OpenAI GPT-5.6) rated it real; an adjudication and a credibility audit re-ran it; this doc's gradle runs reproduce it on a9779ef3c193 and validate the fix; independent fact checks re-checked every claim.
Checks and verdicts469 words
Every check reproduced the defect and agreed on the root cause; none found a convincing "intended" argument. The impact was rated minor throughout.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Differential against C Hunspell 1.7.2, then a 1-test JUnit: fails on main (-ea, -da), 10.5.2 and 9.12.3; C 1.7.2 (two builds) rejects foobar at 1; the fix passes. |
| cross-model review, refute lens (OpenAI GPT-5.6) | real, high; intended argument weak | Reproduced with its own words, -da too; the max-2 control passes; the fix passes, and TestSpellChecking (53 tests) passes with it; pointed out that LUCENE-9699 enforced 1. |
| independent reproducer | real | Own JUnit (3 claim tests, 5 controls) fails 3 of 8 on main (-ea, -da), 10.5.2, 9.12.3 and 9.0.0; C 1.3.2: 48 comparisons, only the 6 two-word cells at 0 and 1 differ; its own equivalent fix passes 8 of 8. |
| cross-model review, intended lens (OpenAI GPT-5.6) | real, high; intended argument weak | Own test fails 2 of 2 on main, 10.5.2 and 9.12.3 and passes with the fix; 810 upstream expectations unchanged with the fix; scoped the claim to flag compounding. |
| intended-behaviour devil's advocate | real, impact low | 70-cell grid against C 1.7.2: 4 mismatches on main, 9.0.0, 8.11.4 and 8.9.0, 0 with the fix; surveyed 477 public .aff files (none uses 0 or 1); widened the affected versions to 8.9.0. |
| adjudication | confirmed, high; impact minor | Re-ran the independent reproduction's JUnit (3 of 8 fail with -ea and -da, 8 of 8 pass with the fix) and native C Hunspell 1.3.2. |
| registry re-run and credibility audit | keep | Re-ran on a9779ef3c193 the finder's test (fails with -ea and -da; passes with the fix shadowed, -ea) and the independent reproducer's test (fails 3 of 8 with -ea; passes 8 of 8 with the fix shadowed, -ea and -da); re-read the root cause, the C rule and the history. |
| this doc | reproduced; fix validated | New 4-test JUnit: 3 of 4 fail through gradle (assertions on and off) and through the runner on main and 10.5.2; with the fix 4 of 4 pass and the analysis-common tests and lint checks pass. |
| independent fact check | holds after one count fix | Re-ran this doc's gradle command (3 of 4 fail, assertions on and off), the fix (4 of 4; TestSpellChecking 53 and TestDictionary 16 pass), the runner on main, 10.5.2, 9.1.0 and 8.9.0, and C Hunspell 1.7.2 and 1.3.2 on the exact dictionaries; re-read every cited line, the history and upstream main. Found one wrong prior-art split (fixed). |
| cross-model fact check (OpenAI GPT-5.6) | real; brief substantially sound | Read-only review against saved sources and logs: bug, root cause, fix and the security verdict (not security-sensitive) hold; its wording corrections, overclaims and caveats (negative values, the narrower 146-test run, internal labels) are resolved. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 468 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,207 words
- Registry title
- Hunspell spell() accepts two-word flag-based compounds (COMPOUNDFLAG or COMPOUNDBEGIN/END) when COMPOUNDWORDMAX is 1 (or 0, which the parser clamps to 1), because the word-count check skips the first compound part
- Area
- analysis / hunspell (Hunspell.spell compound checking, COMPOUNDWORDMAX)
- Priority
- Low, rank 468: Only the opt-in Hunspell spell() verdict is wrong, only with a self-contradictory COMPOUNDWORDMAX 0 or 1 that no public dictionary uses, and stemming is unaffected.
- Impact class
- minor
- Impact note
- Only applications that call the opt-in Hunspell spell-checker (Hunspell.spell; suggest builds on the same check) with a dictionary that uses flag-based compounding (COMPOUNDFLAG or COMPOUNDBEGIN/MIDDLE/END) and sets COMPOUNDWORDMAX to 0 or 1 (none of the 477 public .aff files with this directive found by a code search does) are hit, and only for two-word compounds: spell() returns true where C Hunspell returns false; limits of 2 or more, and compounds of 3 or more words at a limit of 1, are handled correctly, -ea and -da behave the same, stemming and analysis (HunspellStemFilter) never read the limit, no scale is needed, and every release from 8.9.0 to 10.5.2 has it.
- Summary
- You load a Hunspell dictionary with 'COMPOUNDFLAG C', 'COMPOUNDMIN 1', 'COMPOUNDWORDMAX 1' and the words foo/C and bar/C, call Hunspell.spell("foobar"), and expect false: hunspell(5) defines COMPOUNDWORDMAX as the maximum word count in a compound, and C Hunspell 1.3.2 and 1.7.2 reject foobar. Instead Lucene returns true, with and without -ea; COMPOUNDWORDMAX 0, which the parser clamps to 1, behaves the same, while with COMPOUNDWORDMAX 2 Lucene correctly accepts foobar and rejects foobarfoo. The cause: checkCompounds counts parts only when a previous part exists ('prev != null && prev.index > compoundMax - 2'), so the first part is never counted and checkCompoundsAfter accepts first part + last part at any limit; the original LUCENE-9699 check, which did enforce a limit of 1, was lost in a 2021 refactoring (LUCENE-9729).
- Introduced
- 650f16ad5d8e, LUCENE-9729 'Hunspell: support CHECKCOMPOUNDREP flags' (apache/lucene-solr#2300, by donnerpeter; issue apache/lucene#10768), in the PR's refactoring sub-commit f78cc2563024 'LUCENE-9729: [Hunspell] refactoring': it replaced 'if (depth > dictionary.compoundMax - 2) return false;' (depth 0 at the first part, so COMPOUNDWORDMAX 1 rejected every compound, as written by LUCENE-9699 a176308aa63, apache/lucene-solr#2248, issue apache/lucene#10738) with 'if (prev != null && prev.index > dictionary.compoundMax - 2) return false;', which skips the first part [read: git show 650f16ad5d8 in the history clone] [exec: the hunspell sources of a176308aa63, 9d45dfe776a and the parent 16764f16010, compiled over the 9.0.0 jars, enforce the limit of 1; those of 650f16ad5d8 fail the repro on both the COMPOUNDFLAG and the COMPOUNDBEGIN/END path]. Reached 8.x through the backport apache/lucene-solr#2499 (LUCENE-9687, merged 2021-05-28). Both the feature and the regression predate every release, so no release ever enforced COMPOUNDWORDMAX 1 and it is not a regression of a released version (2021-02-05 (main line; the sub-commit is dated 2021-02-03); 2021-05-28 (8.x backport))
- First affected version
- 8.9.0 [exec] (the first release with the spell-checking API, through the 8.x backport; 8.8.2 has no Hunspell class [exec]); on the main line 9.0.0 [exec]
- Affected versions
- every release that has the spell-checking API: 8.9.0 - 8.11.4, 9.0.0 - 9.12.3 and 10.0.0 - 10.5.2, and main a9779ef3c193. Executed and failing: 8.9.0, 8.11.4, 9.0.0, 9.1.0, 9.12.3, 10.0.0, 10.5.2 (-ea and -da) and main (-ea and -da) [exec, follow-up]; the independent reproduction and the intended-behaviour check independently executed 8.9.0, 8.11.4, 9.0.0, 9.12.3 and 10.5.2 with their own tests [exec]. The other releases [read]: the guard line is byte-identical in all 33 release tags from 9.0.0 to 10.5.2, and the 8.9.0 bytecode (javap) has the same guard. Not affected: 8.8.2 and older (no spell-checking API) [exec 8.8.2]. Not fixed upstream: Hunspell.java:214 is unchanged on upstream main a95c754ee003 (2026-10-26) and no open PR changes it [read]. All runs on Linux aarch64 with JDK 25
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal
- Upstream and prior reports
- none found (2026-10-27, completed, read-only, the prior-report record verdict new, 129 query records: scripted prior-report searches A and B (110 records, 57 and 53, over GitHub issues, PRs and commits, downstream repositories (Elasticsearch, OpenSearch, Solr), the dev@, java-user@, issues@ and commits@ lists, JIRA and the web; run B's 6 web queries only planned) plus 19 manual records (14 GitHub and git-history, 5 web), among them a listing of all 410 open apache/lucene PRs and the file lists of the 16 analysis PRs; the earlier independent reproduction (9 queries) and the intended-behaviour check (43 queries) scripted prior-report searches agree; 15 hits judged, none the same bug). repo:apache/lucene COMPOUNDWORDMAX gives 0 results; COMPOUNDWORDMAX on dev@, java-user@ and issues@ gives 0 mails (commits@: 9 commit-diff mails only); JIRA COMPOUNDWORDMAX and compoundMax give 0. Closest items: #10768 (LUCENE-9729, apache/lucene-solr#2300, 650f16ad5d8), the introducing change, whose only review comment is about CheckCompoundPattern offsets; #10738 (LUCENE-9699, apache/lucene-solr#2248), which added COMPOUNDWORDMAX with a check that did enforce 1; #10726 (LUCENE-9687, the umbrella issue, and its 8.x backport apache/lucene-solr#2499); open PRs #16422 (stale Dictionary.java parse refactor that keeps the clamp) and #16911 (branch_10x decommission), neither a fix. Not fixed upstream: Hunspell.java:214 unchanged on upstream main a95c754ee003 (2026-10-26).
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26): the compact JUnit through gradle in a clean checkout with the test copied in, stock and with the recommended fix, assertions on and off, plus the wholelucene/analysis/commontest task and its lint checks with the fix; through the hunt's classpath runner the same JUnit on main (-ea,-da), with the fix shadowed, and on the 10.5.2 release jars (2026-10-28); independent fact checks re-ran the gradle repro, the fix and C Hunspell. Hunt runs on maina9779ef3c193andea57360912ed(identical hunspell package), on 7 releases from 8.9.0 to 10.5.2 and at 4 commits around the change; C Hunspell 1.3.2 and 1.7.2 on the same dictionaries.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Hunspell.java at a9779ef3c193: :34-47 class javadoc ('can be used in place of native Hunspell for many languages'), :71-74 spell javadoc ('whether the given word's spelling is considered correct according to Hunspell rules'), :213-214 checkCompounds count check ('prev != null && prev.index > dictionary.compoundMax - 2'), :269-286 checkCompoundsAfter (last part accepted without a count check), :372 CompoundPart index (1 for the first part)lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Dictionary.java at a9779ef3c193: :152 compoundMax default Integer.MAX_VALUE, :439 'COMPOUNDWORDMAX' parsed as Math.max(1, n); grep: compoundMax is read only at Hunspell.java:214
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Hunspell.java (lines 150-161, 213-247, 269-286, 372)lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Dictionary.java (lines 152, 439)
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Hunspell.java (line 300); grep: in production code compoundMax is read only at line 214 (the test TestDictionary.java:184 asserts the parsed value)lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Stemmer.java (lines 94-103); lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/HunspellStemFilter.java (lines 108-114)
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Hunspell.java (lines 35-44, 72)lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/TestHunspellRepositoryTestCases.java (lines 38-46); lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/TestDictionary.java (lines 180-184); lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/forgivable-errors.aff (line 4)
- Diagrams
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Hunspell.java (line 214)
- TestCompoundWordMaxOne.java (JUnit test):
repro/LFV-724/src/org/apache/lucene/analysis/hunspell/TestCompoundWordMaxOne.java(40 lines)
assets/LFV-724/bug.png(468 KB)