Hunspell dictionaries build compounds with compound flags or with COMPOUNDRULE patterns. Entries can also carry restrictions such as KEEPCASE or FORCEUCASE. Lucene enforces those restrictions on flag compounds and skips them on rule compounds.
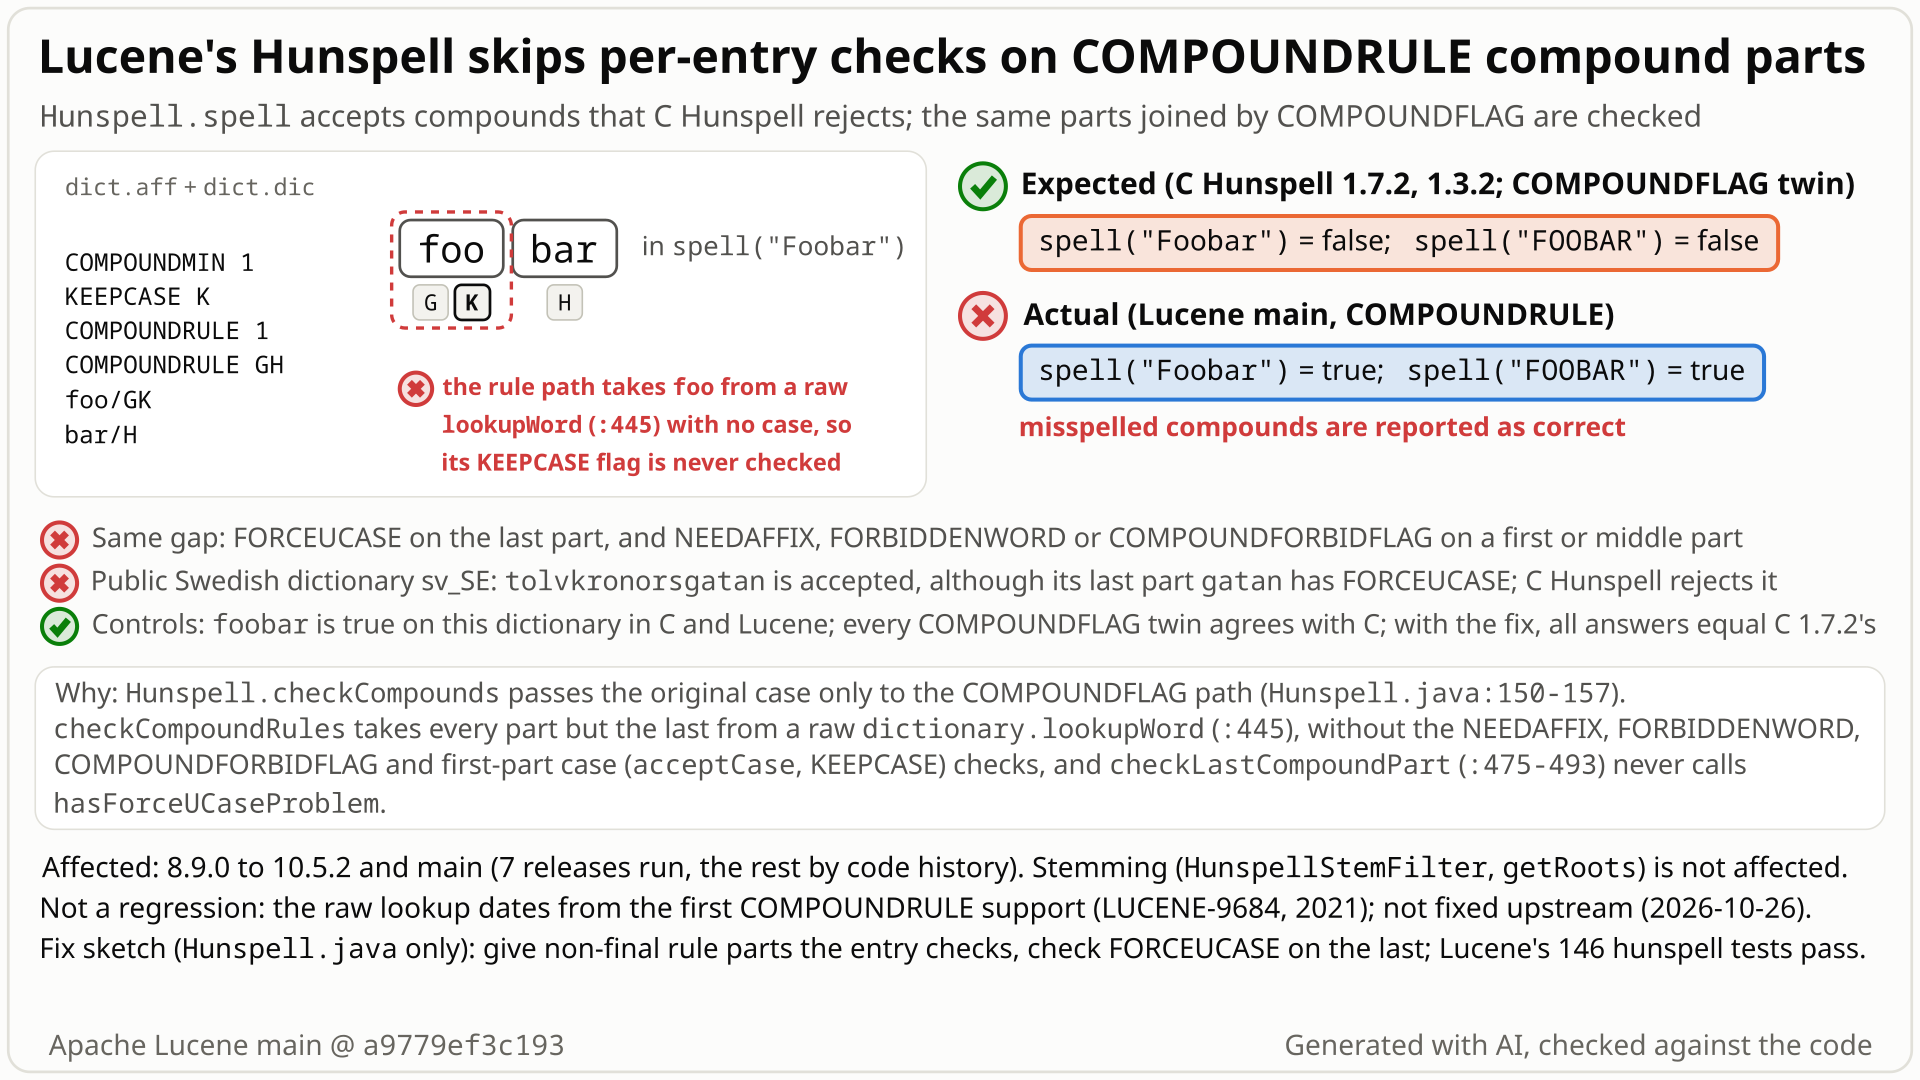
foo/GK and bar/H joined by COMPOUNDRULE GH. Lucene retries Foobar as foobar with the original case, but only the flag path checks foo's case; the rule path takes foo raw from the dictionary and accepts Foobar and FOOBAR, which C Hunspell rejects. Select the still to open it at full size. Generated with AI, checked against the code.- You load the public Swedish dictionary sv_SE and call
spell("tolvkronorsgatan"). A compound rule builds it fromtolv(twelve),kronorsandgatan("the street"), and the dictionary marksgatanFORCEUCASE: a compound that ends in it is a street name and must be capitalized. - You expect
false: C Hunspell 1.3.2 and 1.7.2 reject it and accept the capitalizedTolvkronorsgatan, and Lucene itself rejectsstorgatan, which the dictionary builds with compound flags instead of a rule. - Instead
spellreturnstrue. Lucene checks a rule compound's parts only against the rule: the first and middle parts are raw dictionary lookups (Hunspell.java:445), and the last part never gets the FORCEUCASE check (:475-493) that flag compounds get (:279). - The same on tiny dictionaries with
COMPOUNDRULE GHandbar/H: withfoo/GK(KEEPCASE) Lucene acceptsFoobarandFOOBAR; withfoo/GN(NEEDAFFIX),foo/GW(FORBIDDENWORD) orfoo/GF(COMPOUNDFORBIDFLAG) it acceptsfoobar. C Hunspell 1.7.2 rejects all of them, and so does Lucene when the same words are joined byCOMPOUNDFLAG. - No error, with assertions on or off; it fails on every release tested from 8.9.0 to 10.5.2 (7 releases) and on main.
suggest()offers such words too:Foobarfor the typoFoobarr, where C Hunspell suggestsfoobar.
Applications that use Lucene's opt-in Hunspell spell checker (Hunspell.spell, suggest) with a COMPOUNDRULE dictionary whose rule entries also carry one of these flags. On the Swedish sv_SE dictionary, lower-case rule compounds that must be capitalized are accepted (run for words ending in gatan, sverige and afrika); the other flags show on synthetic dictionaries only. Stemming, indexing and search are unchanged.
Mechanism, terms and numbers897 words
A Hunspell dictionary can build compound words with compound flags (COMPOUNDFLAG, COMPOUNDBEGIN, ...) or with COMPOUNDRULE patterns over flags. Its entries can also carry restrictions: KEEPCASE, FORCEUCASE, NEEDAFFIX, FORBIDDENWORD and COMPOUNDFORBIDFLAG. Lucene's Hunspell.spell applies these restrictions to the parts of flag compounds but not to the parts of rule compounds: checkCompoundRules (Hunspell.java:437-464 on main a9779ef3c193) takes every non-final part straight from dictionary.lookupWord (:445), and checkLastCompoundPart (:475-493) never applies the FORCEUCASE check. So spell() accepts compounds that C Hunspell 1.7.2 rejects (1.3.2 too, except the COMPOUNDFORBIDFLAG case): on the public Swedish dictionary sv_SE, lower-case rule compounds such as tolvkronorsgatan; on small dictionaries, a KEEPCASE first part in capitalized or upper case and a NEEDAFFIX, FORBIDDENWORD or COMPOUNDFORBIDFLAG entry as a first part (NEEDAFFIX also as a middle part). suggest() offers such words as corrections (run for the KEEPCASE and FORCEUCASE cases). Nothing throws, assertions on and off give the same result, and it fails on all 7 releases run from 8.9.0, the first with the spell-checking API, to 10.5.2; the main-line history shows only refactors of this code in between. Stemming (HunspellStemFilter, getRoots) is not.
- Flag compound: a compound accepted through
COMPOUNDFLAGorCOMPOUNDBEGIN/COMPOUNDMIDDLE/COMPOUNDEND: every part carries a compound flag. - Rule compound: a compound accepted because a
COMPOUNDRULEpattern over flags matches its parts, for exampleCOMPOUNDRULE GH(aGword, then anHword) orGH*(then any number ofHwords). - Per-entry flags (hunspell(5) of C Hunspell 1.7.2):
KEEPCASE"Forbid uppercased and capitalized forms of words signed with KEEPCASE flags";FORCEUCASE"Last word part of a compound with flag FORCEUCASE forces capitalization of the whole compound word" (the manual's example is the Dutch "straat", street);NEEDAFFIX"virtual stems in the dictionary, words only valid when affixed. Except, if the dictionary word has a homonym or a zero affix";FORBIDDENWORD"forbidden word form";COMPOUNDFORBIDFLAG"Dictionary words with this flag are removed from the beginning and middle of compound words".
- The word as typed matches nothing (
Foois not in the dictionary), sospellretries the lower-case variantfoobarand remembers that the original was title case (Hunspell.java:95-110on maina9779ef3c193). checkCompounds(:150-161) tries the rule path first, without the original case:checkCompoundRules(wordChars, 0, length, new ArrayList<>())(:152). Only the flag path gets it (:157).checkCompoundRules(:437-464) splits the word and takes the first part's entries straight from the dictionary,IntsRef forms = dictionary.lookupWord(wordChars, offset, breakPos);(:445); middle parts come from the same line in the recursion (:454). Nothing looks at KEEPCASE, NEEDAFFIX, FORBIDDENWORD or COMPOUNDFORBIDFLAG.checkLastCompoundPart(:475-493) looks the last part up throughStemmer.doStem(:490), which skips NEEDAFFIX entries (Stemmer.java:234-236), but its callback (:481-489) only matches the rules and never callshasForceUCaseProblem.GHmatches, sospellreturnstrue.
| check | flag path | rule path |
|---|---|---|
| case of the first part (KEEPCASE) | findStem with the original case, acceptCase (:163-198) | none (:152) |
| NEEDAFFIX, COMPOUNDFORBIDFLAG on first / middle parts | Stemmer.doStem (Stemmer.java:234-240) | none, raw lookup (:445) |
| FORBIDDENWORD on first / middle parts | :232 | none (:445) |
| FORCEUCASE on the last part | hasForceUCaseProblem (:279, :288-292) | none (:481-489) |
The FORBIDDENWORD and COMPOUNDFORBIDFLAG middle-part rows were also executed (fact check: foobarbaz with bar/HW or bar/HF is accepted by stock Lucene and rejected by C 1.7.2 and by the fix).
| flag | word | C Hunspell 1.7.2 | Lucene, same words as a flag compound | Lucene, rule compound |
|---|---|---|---|---|
| KEEPCASE, first part | Foobar, FOOBAR | false, false | false, false | true, true |
FORCEUCASE, last part (tolv/2 kronors/3 gatan/cY, rule 23Y) | tolvkronorsgatan | false | false | true |
| NEEDAFFIX, first part | foobar | false | false | true |
NEEDAFFIX, middle part (foo/G bar/HN baz/H, rule GH*) | foobarbaz | false | - | true |
| FORBIDDENWORD, first part | foobar | false | false | true |
| COMPOUNDFORBIDFLAG, first part | foobar | false | false | true |
C 1.3.2 agrees except COMPOUNDFORBIDFLAG, which it ignores on dictionary words in both modes. The rule path is also inconsistent with itself: in the GH* dictionary the NEEDAFFIX entry bar is rejected as the last part (foobazbar false) and accepted in the middle (foobarbaz true).
Real dictionary (sv_SE). FORCEUCASE c and the rule 4?5?4?23U*Y; 13 entries carry both c and Y, the dictionary's COMPOUNDEND flag, which its rules reuse as their last flag (afrika, danmark, europa, finland, gatan, gränd, holmen, norge, quist, qvist, själland, sverige, tyskland); gatan/AcYZ also has Z = ONLYINCOMPOUND. Lucene accepts tolvkronorsgatan and treveckorssverige; C 1.3.2 and 1.7.2 reject both and accept the capitalized forms, which Lucene accepts too; both reject the flag compound storgatan. Lower-case compounds ending in three of the 13 were run (afrika, gatan, sverige); the other ten were not. These words are built from the dictionary's rules, not taken from a corpus.
Not part of the claim (C and Lucene agree): KEEPCASE on a middle or last rule part, and FORBIDDENWORD on the last rule part, are accepted by both. The claim is per-flag parity with C Hunspell, not "rule and flag compounds always agree".
Exposure and likelihood256 words
- Who is hit. Code that calls
Hunspell.spellorHunspell.suggest(lucene-analysis-common) with a dictionary that usesCOMPOUNDRULEand whose rule-flagged entries also carry KEEPCASE, FORCEUCASE, NEEDAFFIX, FORBIDDENWORD or COMPOUNDFORBIDFLAG. The spell checker is opt-in, with a dictionary the application chooses; no default analyzer uses it. - What they get.
spellsays "correct" for words the dictionary forbids;suggestcan offer them as corrections (Foobarrgives[Foobar], C 1.7.2 suggestsfoobar;tolvkronorsgaatangives[tolvkronorsgatan], C suggests nothing). Only these KEEPCASE and FORCEUCASE cases were run forsuggest(). Silent, deterministic, the same with assertions on and off; no scale needed. - Real dictionary. sv_SE has 13 entries that are both FORCEUCASE and rule-final (
gatan,gränd,holmenand place names such assverige). Lower-case numeral rule compounds ending in three of them (gatan,sverige,afrika) were run and are accepted; the other ten were not run. How often such words occur in real text was not measured. Two more public dictionaries declare some of these flags next toCOMPOUNDRULE; whether their rule entries carry them was not checked: Galiciangl_ES(LibreOffice collection:NEEDAFFIX,KEEPCASE, 3 rules) and Dutchnl(wooorm/dictionaries collection:KEEPCASE,FORCEUCASE,FORBIDDENWORD, 37 numeral rules; the LibreOfficenl_NLcopy has noCOMPOUNDRULE). - Not affected.
HunspellStemFilterandgetRoots: "No roots are returned for compound words" (Hunspell.java:300), so index-time and query-time analysis do not change. - Severity. A spell-check verdict error in an opt-in component: silent wrong results, likelihood rare.
The test shows that Hunspell.spell ignores FORCEUCASE on the last part of a COMPOUNDRULE compound: dictionary COMPOUNDMIN 1, FORCEUCASE U, COMPOUNDRULE GH, entries foo/G bar/HU.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.hunspell;

import java.io.ByteArrayInputStream;
import java.nio.charset.StandardCharsets;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestCompoundRuleForceUCase extends LuceneTestCase {

  public void testForceUCaseLastRulePart() throws Exception {
    String aff = "COMPOUNDMIN 1\nFORCEUCASE U\nCOMPOUNDRULE 1\nCOMPOUNDRULE GH\n";
    String dic = "2\nfoo/G\nbar/HU\n";
    Dictionary dictionary =
        new Dictionary(
            new ByteBuffersDirectory(),
            "dict",
            new ByteArrayInputStream(aff.getBytes(StandardCharsets.UTF_8)),
            new ByteArrayInputStream(dic.getBytes(StandardCharsets.UTF_8)));
    // expected false (last part bar is FORCEUCASE: compound must be capitalized), actual true
    assertFalse(
        "spell(\"foobar\") expected false, was true", new Hunspell(dictionary).spell("foobar"));
  }
}
# in a copy of this finding's repro folder (repro/LFV-731/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.hunspell.TestCompoundRuleForceUCase
- Expected vs actual
- Expected (hunspell(5) FORCEUCASE forces capitalization of the whole compound; C Hunspell rejects it):
spell("foobar")is false. Actual: true (spell("foobar") expected false, was true).
More files, environment, full output35 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: spell("foobar") expected false, was true
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.assertTrue(Assert.java:42)
       org.junit.Assert.assertFalse(Assert.java:65)
org.apache.lucene.analysis.hunspell.TestCompoundRuleForceUCase.testForceUCaseLastRulePart(TestCompoundRuleForceUCase.java:36)- hunspell(5) defines KEEPCASE, FORCEUCASE, NEEDAFFIX and COMPOUNDFORBIDFLAG with no compound-flag-only exception; C Hunspell enforces them on rule compounds.
- Lucene says
Hunspell"can be used in place of native Hunspell for many languages" and enforces these flags on flag compounds (keepcase.wrong). - The rule path contradicts itself: it rejects a NEEDAFFIX entry as the last part, accepts it in the middle.
The full argument406 words
- The format. hunspell(5) of C Hunspell 1.7.2 (
man/hunspell.5): KEEPCASE (:561-566) "Forbid uppercased and capitalized forms of words signed with KEEPCASE flags"; FORCEUCASE (:496-500) "Last word part of a compound with flag FORCEUCASE forces capitalization of the whole compound word"; NEEDAFFIX (:582-584) "words only valid when affixed. Except, if the dictionary word has a homonym or a zero affix" (an unflagged homonym is a valid word; C 1.7.2,doStemand the fix skip only the flagged homonym); COMPOUNDFORBIDFLAG (:452-455) "Dictionary words with this flag are removed from the beginning and middle of compound words". None is limited to flag compounds. FORBIDDENWORD (:552-556, "This flag signs forbidden word form. Because affixed forms are also forbidden, we can subtract a subset from set of the accepted affixed and compound words") is the weakest: the text forbids whole word forms, compounds included, but does not name compound parts, so it rests on C's behaviour and Lucene's own flag path. - Lucene's documentation (Hunspell-rule semantics, broad compatibility). "This class can be used in place of native Hunspell for many languages for spell-checking and suggesting purposes" (
Hunspell.java:35-36); its list of unsupported cases (Hungarian, non-BMP characters, PHONE;:39-44) does not cover this.spellreturns "whether the given word's spelling is considered correct according to Hunspell rules" (:72). - C Hunspell. Two 1.7.2 builds reject every claimed word on the same dictionaries, and 1.3.2 every one except the COMPOUNDFORBIDFLAG case, which 1.3.2 ignores on dictionary words in both kinds of compound (executed). In 1.7.2's
compound_check, rule mode skips NEEDAFFIX homonyms, breaks on a FORBIDDENWORD or NEEDAFFIX first word, skips COMPOUNDFORBIDFLAG words and checks FORCEUCASE before returning a rule match;spell()applies KEEPCASE to the returned first part (read). Nuspell'scheck_compound_with_ruleshas the same checks (read only). - Lucene's own tests.
keepcase.wronglistsUnitvvandUNITVV(a KEEPCASE first part of a flag compound) andforceucase.wronglistsfoobaz. No fixture combinesCOMPOUNDRULEwith KEEPCASE, FORCEUCASE or NEEDAFFIX. - History. LUCENE-9684 (
d7968130c3f, apache/lucene-solr#2228) added the raw lookup; its PR says "I've reimplemented Hunspell's logic". LUCENE-9710 (9d45dfe776a) implemented FORCEUCASE on the flag path only; LUCENE-9776 (4b3fb1e0659) moved only the last rule part todoStem, for inflection; LUCENE-9785 (31a64927a46, "Like Hunspell does") kept the case check on the first part of flag compounds. No commit, test or comment says rule compounds skip these checks.
The devil's-advocate check171 words
Strongest case, rated weak by every reviewer: hunspell(5) Note III says "COMPOUNDRULE flags work completely separately from the compounding mechanisms using COMPOUNDFLAG, COMPOUNDBEGIN, etc. compound flags. (Use these flags on different entries for words)." Lucene documents compatibility only "for many languages", no fixture pins this behaviour, and sv_SE reuses its COMPOUNDMIDDLE/COMPOUNDEND flags as rule flags against that note.
Why it fails: Note III is about which compound flags a rule matches, not about per-entry flags such as KEEPCASE or NEEDAFFIX, and FORCEUCASE is defined for any compound. C Hunspell 1.7.2 (and 1.3.2 for all but COMPOUNDFORBIDFLAG) and Nuspell apply the checks in rule mode, Lucene's rule path already applies NEEDAFFIX to the last part, and the synthetic repros reuse no flags and still fail, so it is not a misuse. A note in the manual's BREAK entry ("COMPOUNDRULE handles only the suffixation of the last word part") explains why non-final parts are not affix-stripped, not why their entry flags are ignored; the recommended fix keeps the raw lookup. Verdict: a defect.
Recommended Give the rule parts the flag path's entry checks
Give rule-compound parts the checks flag-compound parts already get: pass the original case into checkCompoundRules, drop NEEDAFFIX, FORBIDDENWORD and COMPOUNDFORBIDFLAG entries from first and middle parts, case-check the first part (KEEPCASE), and skip last-part readings with a FORCEUCASE problem. Validated: the repro passes and the analysis-common tests run 1,915 tests with 0 failures (18 skipped).
All options and trade-offs3 options · 776 words
One fix (A, the finder's) was applied in a scratch worktree at a9779ef3c193 and run through gradle, and shadowed onto the stock jars for every other repro of the hunt. B and C are alternatives that were not run.
Hunspell.java only, +43/-7. checkCompounds passes originalCase to checkCompoundRules (and on through the recursion). A new compoundRulePartForms wraps the raw lookupWord for non-final parts and drops each entry (homonym) with NEEDAFFIX, FORBIDDENWORD or COMPOUNDFORBIDFLAG on its own and, for the first part, entries acceptCase refuses for the word's original case (KEEPCASE). The checkLastCompoundPart callback skips readings for which hasForceUCaseProblem holds (new int entryId overload). The raw lookup stays, so non-final parts are still never affix-stripped.
--- checkCompounds (Hunspell.java:152)
-        && checkCompoundRules(wordChars, 0, length, new ArrayList<>())) {
+        && checkCompoundRules(wordChars, 0, length, new ArrayList<>(), originalCase)) {
--- checkCompoundRules (Hunspell.java:445)
-      IntsRef forms = dictionary.lookupWord(wordChars, offset, breakPos);
+      IntsRef forms =
+          compoundRulePartForms(wordChars, offset, breakPos, words.isEmpty() ? originalCase : null);
--- new: compoundRulePartForms keeps an entry of lookupWord(...) only if
+      !hasFlag(entryId, needaffix) && !hasFlag(entryId, forbiddenword)
+          && !hasFlag(entryId, compoundForbid)
+          && acceptCase(originalCase, entryId, new CharsRef(wordChars, offset, length))
--- checkLastCompoundPart callback (Hunspell.java:481)
+          if (hasForceUCaseProblem(formID, originalCase, wordChars)) {
+            return true;
+          }
Trade-offs
- One extra pass over the homonyms of each candidate part and a small
IntsRefper matched part; no benchmark was run. - Homonyms need a stated rule. The fix filters every entry on its own. C 1.7.2 decides by the homonym listed first in the
.dic(affixmgr.cxx:1671-1696,:1747-1756) and Lucene's flag path by the first homonym in Lucene's sorted entry order (Stemmer.java:237-240,Hunspell.java:163-184,:232). In a probe on 32 small dictionaries (foo/Gplus a flaggedfoo), the fix acceptsfoobar/Foobarwith a COMPOUNDFORBIDFLAG, FORBIDDENWORD or KEEPCASE homonym in every order; C rejects them when the flagged homonym is listed first, and the flag path when it sorts first. NEEDAFFIX homonyms are skipped one by one everywhere. Homonym order already separates Lucene from C on plain words (FORBIDDENWORDfoo), so the PR should state its rule and add a homonym test;fix.diff's helper javadoc holds for single entries only. acceptCasealso drops Lucene's hidden case-variant entries (the capitalized copies Lucene adds for mixed-case words and for all-caps words with flags,Dictionary.java:1062-1064, like Hunspell's ONLYUPCASE entries) from middle rule parts, and from the first part unless the word is title or upper case, as the flag path already does (Hunspell.java:166,:186-198); no test covers that case.- Forbidden compounds stop being accepted and suggested. A dictionary that relied on the old behaviour relied on something C Hunspell does not do.
- For the PR, the repro can become fixture files in Lucene's style (
.aff/.dic/.good/.wrong, run byTestSpellChecking), one per flag, plus a.sugcase.
What the checks validated
- Stock main
a9779ef3c193, gradle: the repro fails 6 of 6 with assertions on and off. - With the fix, gradle: the repro passes 6 of 6 with assertions on and off; the whole
lucene/analysis/commontest task with assertions on, repro included, runs 340 classes, 1,915 tests, 0 failures, 18 skipped (the hunspell package: 47 classes, 164 tests, 13 skipped, becauseTestAllDictionaries,TestHunspellRepositoryTestCasesandTestPerformanceneed external dictionaries);ecjLint,checkGoogleJavaFormatandforbiddenApispass with the test in place. - With the fix shadowed onto the stock jars: the finder's test 4 of 4, the independent reproducer's test 5 of 5, the second cross-model reviewer's normative test 4 of 4, the credibility audit's 11-dictionary differential (all 99 words agree with C 1.7.2), the sv_SE words (all 8 agree with C 1.7.2) and the
suggest()probe (suggestions now match C 1.7.2's). In the hunt, Lucene's 146 hunspell tests and a sweep over 25 upstream compound fixture families pass with the fix. - Not run: the full Lucene suite, the external-dictionary suites (
TestAllDictionaries,TestHunspellRepositoryTestCases), a benchmark.
Use COMPOUND_BEGIN / COMPOUND_MIDDLE contexts so NEEDAFFIX and COMPOUNDFORBIDFLAG are filtered by the stemmer.
Trade-offs
Not run. doStem also strips affixes, so first and middle parts would start matching inflected forms, which hunspell(5) says COMPOUNDRULE does not handle ("handles only the suffixation of the last word part"); it would need a roots-only mode and still needs the case and FORBIDDENWORD checks.
Only the checkLastCompoundPart hunk of the recommended fix: the one manifestation with real-dictionary evidence (sv_SE).
Trade-offs
Not run. Smallest change, but leaves the KEEPCASE, NEEDAFFIX, FORBIDDENWORD and COMPOUNDFORBIDFLAG manifestations.
Downstream token filters built on HunspellStemFilter are not affected; only code that calls Lucene's spell-checking API (Hunspell.spell, suggest) gets the wrong verdicts.
Differential testing of Lucene's Hunspell.spell against C Hunspell 1.7.2 on generated compounding dictionaries; minimizing the disagreeing dictionaries gave KEEPCASE, FORCEUCASE, NEEDAFFIX, FORBIDDENWORD and COMPOUNDFORBIDFLAG clusters on one code path, checkCompoundRules. A public-API JUnit then reproduced it on the stock jar.
The method in full192 words
Method: cross-implementation differential testing (the hunt's non-formal tier).
- Inputs: seeded, grammar-generated synthetic dictionaries with one or two compounding directives (COMPOUNDFLAG, COMPOUNDBEGIN/END, COMPOUNDRULE) plus modifiers such as KEEPCASE, FORCEUCASE, NEEDAFFIX, FORBIDDENWORD and COMPOUNDFORBIDFLAG, 1-4 short roots, and every short word over the roots' letters plus 2-3-part concatenations.
- Lucene's
spell()andgetRoots()(public API, stock jar) were compared with C Hunspell 1.7.2 built from the pristine source; every disagreement was re-checked on a Linux distribution build of 1.7.2. - Greedy one-element-at-a-time minimization of the disagreeing dictionaries gave KEEPCASE (4 dictionaries), FORCEUCASE, NEEDAFFIX, FORBIDDENWORD and COMPOUNDFORBIDFLAG (4) clusters, all on the same code path; the root cause was then read in
Hunspell.checkCompoundRules. - Found 2026-10-27 on main
a9779ef3c193; then checked by an independent reproducer, an intended-behaviour devil's advocate (which showed that hunspell(5) documents COMPOUNDFORBIDFLAG for dictionary words, making it the fifth asserted manifestation, and found the sv_SE case), two executed reviews by a model from another family (OpenAI GPT-5.6), an adjudication, a history and prior-report follow-up, a security screen and a credibility audit. This doc added the compact JUnit, the gradle runs, the fix validation, C runs on the repro's dictionaries and thesuggest()probe.
No prior report found (2026-10-27): three runs with 153 queries over GitHub, JIRA, the lists and the web, 25 manual searches, all 218 apache/lucene items that mention hunspell, downstream projects, C Hunspell and nuspell, and the changed files of all 410 open PRs. Nothing upstream fixes it.
Searches3 searches
Verdict new: no report by anyone. The closest items are the changes that built the rule path (LUCENE-9684 #10723, LUCENE-9776 #10815), LUCENE-9785 (#10824), which keeps the first-part case check on flag compounds, and flag-path-only fixes. 14 of 18 planned web queries were throttled; keyword search cannot prove absence, and private channels cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; downstream repositories; dev@, java-user@, issues@ and commits@ lists; JIRA; the web | 2026-10-27 | a scripted prior-report search, three query variants (identifiers; symptoms; languages and downstream), 153 queries | no report; closest: #10723, #10815, #10824 |
| apache/lucene, apache/lucene-solr, Elasticsearch, OpenSearch, Solr, Lucene.NET, hunspell/hunspell, nuspell, all of GitHub | 2026-10-27 | 25 manual searches (each flag name alone, hunspell compound terms); all 218 apache/lucene items that mention hunspell; 48 issue and PR reads; file lists of all 410 open PRs | no report; flag-path-only fixes #10749, #10814, #10802, #12220; open #16421/#16422 and #16911 do not touch the fix site; BarMal/Serenity#1276 says Lucene reproduced its COMPOUNDRULE fixtures |
| JIRA, lists.apache.org, the web | 2026-10-27 | 5 JIRA, 15 list and 4 web queries (14 more web queries throttled) | only closed 2021 feature issues and OpenNLP's own Hunspell work |
Present since COMPOUNDRULE support landed, LUCENE-9684 (d7968130c3f, 2021); the FORCEUCASE form since LUCENE-9710 (9d45dfe776a), both before any release. First released in 8.9.0 through the 8.x backport; fails on every release tested (7, from 8.9.0 to 10.5.2) and on main; the releases in between by code history. Not fixed upstream.
Versions tested8 rows
Introduced by d7968130c3f (LUCENE-9684 "Hunspell: support COMPOUNDRULE", apache/lucene-solr#2228, 2021-01-22, issue #10723): checkCompoundRules looked up every part with a raw lookupWord; git blame of Hunspell.java:445 on main still points to it. 9d45dfe776a (LUCENE-9710, 2021-02-01) implemented FORCEUCASE on the flag path only, which is where the FORCEUCASE form starts. 4b3fb1e0659 (LUCENE-9776, 2021-02-19) moved only the last rule part to doStem, which fixed NEEDAFFIX there and nowhere else. Reached 8.x through the backport c6b964a1157 (apache/lucene-solr#2499, merged 2021-05-28): 8.9.0 is the first release with the spell-checking API. Later main-line changes to both methods are refactors and performance work (af97c5ef379, d537013e708, a454388b80e, ab453b9541a). Hunspell.java and Stemmer.java are unchanged on upstream main a95c754ee003 since ab453b9541ad (2025-02-27).
The commit-level probe compiles each commit's hunspell package over the 9.0.0 jars (not full builds); its last commit column (4b3fb1e0659) equals the 8.9.0 and 9.0.0 release columns on all 14 probes.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the compact JUnit fails 6 of 6 through gradle, assertions on and off; the finder's, the reproducer's and the reviewers' tests fail with -ea and -da |
| 10.0.0, 10.5.2 | affected | the finder's test fails 4 of 4; the compact JUnit fails 6 of 6 on 10.5.2 |
| 9.0.0, 9.1.0, 9.12.3 | main line from 9.0.0 | the finder's test fails 4 of 4; the compact JUnit fails 6 of 6 on 9.1.0 and 9.12.3 |
| 8.9.0, 8.11.4 | first release | the finder's test (pre-9.1 import) fails 4 of 4 |
| 8.8.2 | no spell-checking API | the repro does not compile (no Hunspell class) |
d7968130c3f vs its parent (commit probe) | introducing commit | the parent has no COMPOUNDRULE support; d7968130c3f accepts the KEEPCASE, NEEDAFFIX and FORBIDDENWORD first-part cases while its simple-word controls are correct |
9d45dfe776a, 4b3fb1e0659 (commit probe) | later changes | FORCEUCASE implemented on the flag path only; NEEDAFFIX fixed on the last rule part only |
| main + recommended fix | not affected | the compact JUnit passes 6 of 6; every other repro of the hunt passes |
An independent reproducer and an intended-behaviour devil's advocate reproduced it with their own tests and C Hunspell runs; two executed reviews by a model from another family (OpenAI GPT-5.6) rated it real; an adjudication and a credibility audit re-ran it; this doc's gradle runs reproduce it on a9779ef3c193 and validate the fix.
Checks and verdicts433 words
Every executing check wrote or re-ran its own JUnit on stock main; every control passed, and C Hunspell rejected the claimed words in every check that ran it.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Differential against C Hunspell 1.7.2, then the 4-test JUnit: fails on main (-ea, -da), 10.5.2 and 9.12.3; C 1.7.2 (two builds) rejects the same words on twin dictionaries; the fix passes. |
| cross-model review, refute lens (OpenAI GPT-5.6) | real, high; intended argument weak | Own 5-test JUnit fails 4 of 5 (the fifth is a control) on main ea57360912ed (identical hunspell package); an earlier 3-test version (2 failing) repeated over 3 iterations with assertions on and off; passes with the fix; a sweep over 25 upstream compound fixture families passes stock and with the fix. |
| independent reproducer | real | Own JUnit with other words and flags fails 5 of 5 on main (-ea, -da), 10.5.2 and 9.12.3; C 1.3.2 and 1.7.2 reject every claimed word; found that a FORBIDDENWORD last part is accepted by C too. |
| cross-model review, intended lens (OpenAI GPT-5.6) | real, high; intended argument weak | Normative JUnit fails 4 of 4 and passes with the fix; a separate run re-ran it on a9779ef3c193 (-ea and -da). |
| intended-behaviour devil's advocate | real, high | Read the matching checks in C 1.7.2, Hunspell master and Nuspell; showed that hunspell(5) documents COMPOUNDFORBIDFLAG for dictionary words, which made it the fifth asserted manifestation; found the sv_SE case (tolvkronorsgatan accepted by Lucene, rejected by C 1.7.2). |
| adjudication | confirmed, high | Re-ran the independent reproduction's JUnit: 5 of 5 fail with -ea and -da, 5 of 5 pass with the fix. |
| credibility audit | keep | Own 11-dictionary differential against C 1.7.2: 6 rule dictionaries with only false accepts, all 5 flag twins agree; sv_SE confirmed against C 1.3.2 and 1.7.2; found that C 1.3.2 ignores COMPOUNDFORBIDFLAG on dictionary words. |
| this doc | reproduced; fix validated | Compact JUnit fails 6 of 6 through gradle on stock (assertions on and off) and passes with the fix; analysis-common: 1,915 tests, 0 failures with the fix; C 1.7.2 (two builds) and 1.3.2 on its 11 dictionaries; suggest() shown affected and fixed. |
| fact checks of this doc (independent, and a model from another family, OpenAI GPT-5.6) | sound; wording fixed | The independent check re-ran the final test file on main, 10.5.2, 9.12.3 and 9.1.0 and with the fix, every table cell, sv_SE and C Hunspell; the cross-model check read the code, logs and sources. One citation gap and several overclaims were fixed, and a homonym probe was added for the fix. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 516 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,350 words
- Registry title
- Hunspell spell() skips the per-entry checks on COMPOUNDRULE compound parts, so it accepts compounds that C Hunspell rejects: a KEEPCASE first part in capitalized or upper case, a FORCEUCASE last part in lower case, and a NEEDAFFIX or FORBIDDENWORD entry as a first or middle part
- Area
- analysis / hunspell (Hunspell.spell compound checking, COMPOUNDRULE)
- Priority
- Low, rank 458: The opt-in Hunspell spell-checker accepts COMPOUNDRULE compounds that C Hunspell rejects, a spelling-verdict error that one real public dictionary (sv_SE) hits.
- Impact class
- silent wrong results
- Impact note
- Only applications that call the opt-in Hunspell spell-checker (Hunspell.spell; suggest() validates its candidates with the same check but was not executed) with a COMPOUNDRULE dictionary whose rule-flagged entries also carry KEEPCASE, FORCEUCASE, NEEDAFFIX, FORBIDDENWORD or COMPOUNDFORBIDFLAG are hit: spell() returns true for misspelled compounds that C Hunspell rejects, with no exception, the same with -ea and -da and with no scale needed; the public sv_SE dictionary shows it for FORCEUCASE (lower-case numeral rule compounds that end in one of its 13 FORCEUCASE entries, such as tolvkronorsgatan), the other flags are shown only on synthetic dictionaries, stemming and analysis (HunspellStemFilter, getRoots) are not affected, and every release from 8.9.0 to 10.5.2 has it.
- Summary
- You load a Hunspell dictionary that joins foo/G and bar/H by 'COMPOUNDRULE GH', give foo or bar one of the per-entry flags KEEPCASE, FORCEUCASE, NEEDAFFIX or FORBIDDENWORD, call Hunspell.spell, and expect the answer C Hunspell 1.3.2 and 1.7.2 give (and Lucene itself gives when the same parts are joined by COMPOUNDFLAG): Foobar and FOOBAR rejected when foo is KEEPCASE, foobar rejected when bar is FORCEUCASE, and foobar rejected when foo is a NEEDAFFIX virtual stem or a FORBIDDENWORD entry. Instead spell() returns true in all four cases, with and without -ea, in every release since 8.9.0; on the public Swedish dictionary sv_SE it accepts lower-case rule compounds such as tolvkronorsgatan that the dictionary's FORCEUCASE flag and C Hunspell reject. The cause: checkCompoundRules takes every non-final part as a raw dictionary.lookupWord result, without the NEEDAFFIX, FORBIDDENWORD, COMPOUNDFORBIDFLAG and first-part case (KEEPCASE) filters, and checkLastCompoundPart never applies the FORCEUCASE check (hasForceUCaseProblem) that the COMPOUNDFLAG path uses.
- Introduced
- d7968130c3f5, LUCENE-9684 'Hunspell: support COMPOUNDRULE' (apache/lucene-solr#2228, by donnerpeter; issue apache/lucene#10723): it added checkCompoundRules with raw dictionary.lookupWord lookups for the parts and no case argument; git blame on main still points Hunspell.java:445 to it [read: git blame and git show in the history clone] [exec: commit-level probe, the hunspell package of each commit compiled over the 9.0.0 jars: the parent cf5db8d6513 has no COMPOUNDRULE support; d7968130c3f accepts the KEEPCASE-first, NEEDAFFIX-first, NEEDAFFIX-last and FORBIDDENWORD-first rule compounds while its simple-word KEEPCASE/NEEDAFFIX/FORBIDDENWORD controls are correct]. The FORCEUCASE form starts at 9d45dfe776a (LUCENE-9710, apache/lucene-solr#2272), which implemented FORCEUCASE on the COMPOUNDFLAG path only (before it Lucene ignored FORCEUCASE everywhere); 4b3fb1e0659 (LUCENE-9776, apache/lucene-solr#2397) moved only the last rule part to Stemmer.doStem, which fixed NEEDAFFIX for the last part only [exec: commit-level probe]. Reached 8.x through the backport c6b964a1157 (apache/lucene-solr#2499, LUCENE-9687, merged 2021-05-28). Present since the feature's first commit, before any release; not a regression (2021-01-22 (main line, d7968130c3f); 2021-02-01 for the FORCEUCASE form (9d45dfe776a); 2021-05-28 (8.x backport))
- First affected version
- 8.9.0 [exec] (the first release with the spell-checking API, through the 8.x backport; 8.8.2 has no Hunspell class [exec]); on the main line 9.0.0 [exec]
- Affected versions
- every release that has the spell-checking API: 8.9.0 - 8.11.4, 9.0.0 - 9.12.3 and 10.0.0 - 10.5.2, and main a9779ef3c193. Executed and failing 4 of 4 (the four claim assertions; no control fails): 8.9.0, 8.11.4, 9.0.0, 9.1.0, 9.12.3, 10.0.0, 10.5.2 and main (-ea and -da) [exec, follow-up; 8.x and 9.0.0 with the same test importing the pre-9.1 LuceneTestCase package]; the independent reproduction independently executed main, 10.5.2 and 9.12.3 with its own test, and the cross-model reviews executed 10.5.2 and 9.12.3 [exec]. The other releases [read]: after 4b3fb1e0659, git log -L on checkCompoundRules and checkLastCompoundPart shows only refactors and performance changes (af97c5ef379, d537013e708, a454388b80e, ab453b9541a). Not affected: 8.8.2 and older (no spell-checking API) [exec 8.8.2]. Not fixed upstream: Hunspell.java and Stemmer.java last changed in ab453b9541ad (2025-02-27) on upstream main a95c754ee003 (2026-10-26), and no open PR touches them [read]. All runs on Linux aarch64 with JDK 25
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal
- Upstream and prior reports
- none found (2026-10-27, read-only, the prior-report record verdict new: 3 scripted prior-report searches with 153 queries over GitHub issues, PRs and commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, JIRA and the web, plus 25 own GitHub searches (all 218 apache/lucene items that mention hunspell, each flag name alone, apache/lucene-solr, Elasticsearch, OpenSearch, Solr, Lucene.NET, hunspell/hunspell, nuspell, all of GitHub), 48 issue and PR reads, a listing of all 410 open apache/lucene PRs with their file lists, 15 list queries, 5 JIRA queries and 4 web queries; 22 hits judged, none the same bug; the finder's and the intended-behaviour check's (51 queries) earlier searches agree). Closest items: #10723 (LUCENE-9684, apache/lucene-solr#2228), the introducing change, whose PR says Hunspell's logic was reimplemented and whose reviewer said they did not verify it against Hunspell; #10815 (LUCENE-9776, apache/lucene-solr#2397), which moved only the last rule part to Stemmer.doStem; #10824 (LUCENE-9785, 'Like Hunspell does'), which keeps the case check on the first COMPOUNDFLAG part only; #10749 (LUCENE-9710), #10814 (LUCENE-9775), #10802 (LUCENE-9763) and #12220, fixes on the COMPOUNDFLAG path only; open #16421/#16422 (Dictionary.java directive-parsing refactor) and #16911 (branch_10x decommission), neither a fix. Not fixed upstream: Hunspell.java and Stemmer.java unchanged since ab453b9541ad (2025-02-27) on upstream main a95c754ee003 (2026-10-26). Gap: 14 of 18 planned web queries were not run because the search service throttled.
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26): the compact JUnit through gradle in a scratch worktree created clean at that commit, stock and with the recommended fix, assertions on and off, plus thelucene/analysis/commontest task and its lint checks with the fix; through the hunt's classpath runner, the final JUnit on 10.5.2, 9.12.3 and 9.1.0 (-ea) and main (-ea,-da, re-run by the fact check), and asuggest()probe stock and with the fix shadowed; C Hunspell 1.7.2 (pristine source build and a Linux distribution build) and 1.3.2 on every dictionary of the repro, and a homonym probe on 32 small dictionaries (2026-10-28). Hunt runs on maina9779ef3c193andea57360912ed(identical hunspell package), on 7 releases from 8.9.0 to 10.5.2 (-ea), and a commit-level probe over 10 commits; the public sv_SE dictionary against C 1.3.2 and 1.7.2.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Hunspell.java at a9779ef3c193: :34-47 class javadoc ('can be used in place of native Hunspell for many languages'), :71-74 spell javadoc ('considered correct according to Hunspell rules'), :150-161 checkCompounds (originalCase passed only to the COMPOUNDFLAG path), :163-184 findStem with acceptCase, :186-198 acceptCase (KEEPCASE), :213-247 and :269-286 the COMPOUNDFLAG path (forbiddenword checks at :232 and :277, hasForceUCaseProblem at :279), :288-292 hasForceUCaseProblem, :437-464 checkCompoundRules (raw dictionary.lookupWord at :445), :475-493 checkLastCompoundPart (Stemmer.doStem, no FORCEUCASE check)lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Stemmer.java at a9779ef3c193: :227-243 doStem (NEEDAFFIX entries skipped; COMPOUNDFORBIDFLAG roots refused only in COMPOUND_BEGIN/MIDDLE)lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/keepcase.aff, keepcase.dic (uni/ZC with COMPOUNDFLAG C) and keepcase.wrong (Unitvv, UNITVV): Lucene's own fixture rejects a KEEPCASE first part of a COMPOUNDFLAG compound in capitalized and upper case
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Hunspell.java (lines 95-110, 150-198, 232, 279, 288-292, 437-493 at a9779ef3c193)lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Stemmer.java (lines 227-243)
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Hunspell.java (line 300)
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Hunspell.java (lines 35-44, 72)lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/keepcase.aff, keepcase.dic, keepcase.wrong (lines 10-11), forceucase.aff, forceucase.dic, forceucase.wrong
- TestCompoundRuleForceUCase.java (JUnit test):
repro/LFV-731/src/org/apache/lucene/analysis/hunspell/TestCompoundRuleForceUCase.java(39 lines)
The diagram uses the KEEPCASE dictionary as its main example and ends with the sv_SE FORCEUCASE case; the compact repro covers all five flags.
assets/LFV-731/bug.png(516 KB)