Same class, same mu, two constructors, two answers to "how common is this word in the index?": IndriDirichletSimilarity() uses Indri's cf / |C|; IndriDirichletSimilarity(float mu) sets only mu (IndriDirichletSimilarity.java:54-56) and silently inherits LMSimilarity's default, (cf + 1) / (|C| + 1) (LMSimilarity.java:56-58).
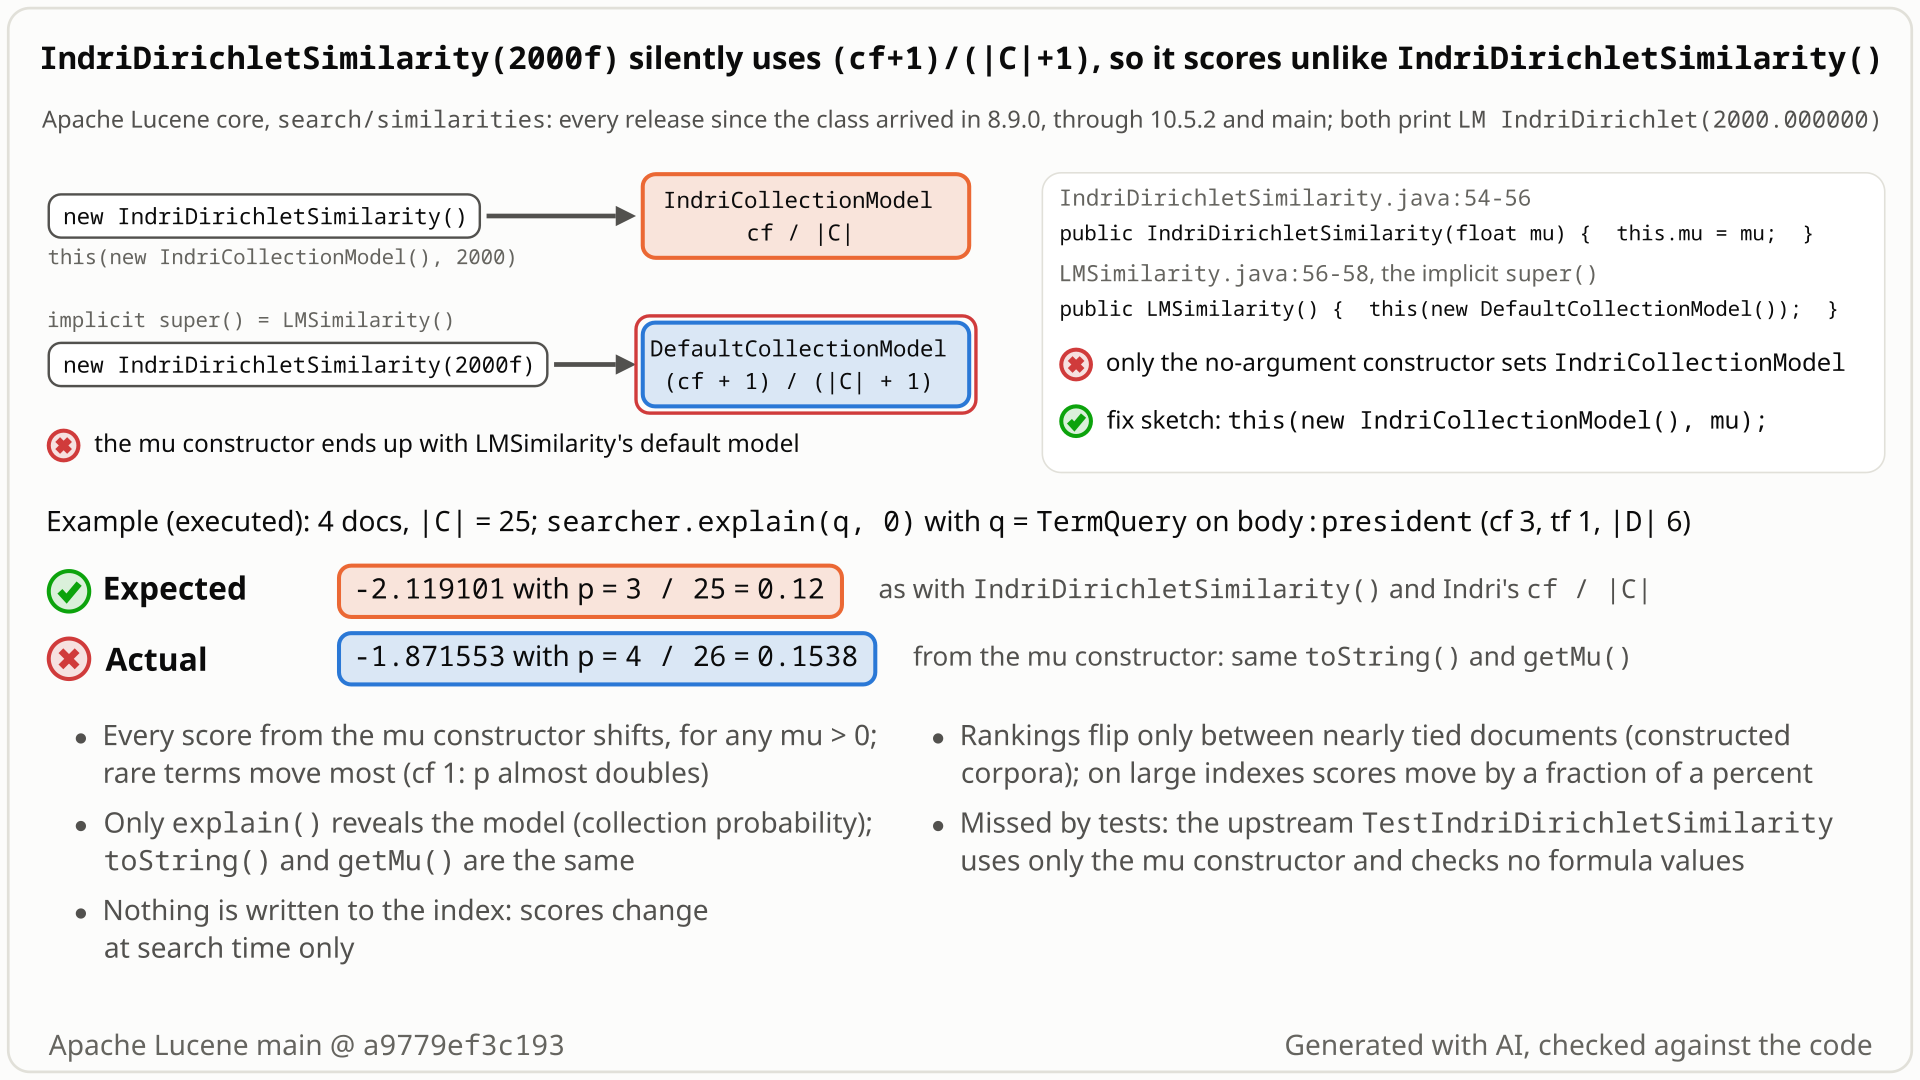
IndriDirichletSimilarity() counts "president" as 3/25 of the collection and scores doc 0 -2.119101; IndriDirichletSimilarity(2000f) counts it as 4/26 and scores -1.871553, while both print the same name. Select the still to open it at full size. Generated with AI, checked against the code.- You index 4 short documents, 25 tokens in all; the word "president" occurs 3 times. You score them with
new IndriDirichletSimilarity(2000f)because you want Indri's Dirichlet smoothing with mu = 2000. - You expect exactly what
new IndriDirichletSimilarity()gives, which is documented as using "the default mu value of 2000". Both printLM IndriDirichlet(2000.000000). Doc 0 should score log((1 + 2000 x 3/25) / (6 + 2000)) = -2.119101. - You get -1.871553. The one-argument constructor passes no collection model, so the parent class's default applies: "president" counts as 4/26 = 0.154 of the collection instead of 3/25 = 0.12.
explain()shows 0.15384616 as "collection probability". - Every positive mu does this (at mu = 0 the model drops out of the formula). With mu = 3 the document with "george" (one occurrence) scores -1.8718022, while Indri's formula gives -1.9661129; for a word that occurs once the collection probability nearly doubles, 2/26 instead of 1/25.
- No error and nothing in the name tells you. The shift is about mu / |C|, so it is large on small indexes and tiny on big ones: 0.02% of the score at 1.3 million tokens; in a synthetic audit of 1,984 queries no top hit changed. Every release since 8.9.0 has it.
Applications that pick IndriDirichletSimilarity (opt-in, not the default) and set mu through the one-argument constructor, on every release since 8.9.0. For any mu > 0 every score and explain() is shifted. The shift is about mu / |C|: large on small indexes, tiny on big ones; in a synthetic audit no top hit and no top-10 set changed.
Mechanism, terms and numbers586 words
IndriDirichletSimilarity implements "Bayesian smoothing using Dirichlet priors as implemented in the Indri Search engine": a document's score for a term is log((tf + mu * p(w|C)) / (|D| + mu)), where the collection probability p(w|C) comes from a CollectionModel. The class ships its own IndriCollectionModel, cf / |C|, and the no-argument constructor, documented as "the default mu value of 2000", uses it. The one-argument constructor IndriDirichletSimilarity(float mu) only assigns mu, so Java inserts super(), and LMSimilarity() installs DefaultCollectionModel, (cf + 1) / (|C| + 1). So new IndriDirichletSimilarity(2000f) and new IndriDirichletSimilarity() have the same mu and print the same LM IndriDirichlet(2000.000000), but score differently: on a 4-document index of 25 tokens, "president" (cf 3) gets p(w|C) = 4/26 instead of 3/25, and doc 0 scores -1.871553 instead of -2.119101. Any positive mu is affected (at mu = 0 the model drops out of the formula): every score and explain() is shifted, and close documents can swap places; on large indexes the shift is a fraction of a percent. Nothing throws and nothing is written to the index. Every release since 8.9.0, the first with the class, is affected.
- Dirichlet smoothing (Indri): a document's score for a term is log((tf + mu * p(w|C)) / (|D| + mu)), where tf is the term's count in the document, |D| the document length, mu the smoothing strength and p(w|C) the collection probability: how common the term is in the whole field.
- Collection model: the strategy object of
LMSimilaritythat computes p(w|C). Two exist here:IndriCollectionModel, cf / |C| (Indri's estimate: occurrences of the term divided by all tokens of the field), andLMSimilarity.DefaultCollectionModel, (cf + 1) / (|C| + 1).
IndriDirichletSimilarityhas five constructors (IndriDirichletSimilarity.java:40-66). The three that take aCollectionModelpass it on.IndriDirichletSimilarity()isthis(new IndriCollectionModel(), 2000)(:64-66).IndriDirichletSimilarity(float mu)is{ this.mu = mu; }(:54-56): nothis(...)orsuper(...), so the compiler insertssuper().LMSimilarity()isthis(new DefaultCollectionModel()), "Creates a new instance with the default collection language model" (LMSimilarity.java:55-58).DefaultCollectionModelreturns(totalTermFreq + 1) / (numberOfFieldTokens + 1)(:150-152);IndriCollectionModelreturnstotalTermFreq / numberOfFieldTokens(IndriDirichletSimilarity.java:111-113).LMSimilarity.fillBasicStatsstores the model's value once per term (LMSimilarity.java:68-73) andscore()uses it for every document (IndriDirichletSimilarity.java:69-72);explain()prints it as "collection probability" (LMSimilarity.java:75-80).- Both models return
getName()= null andgetName()of the similarity prints only mu (IndriDirichletSimilarity.java:96-99), so both constructors givetoString()=LM IndriDirichlet(2000.000000).
(cf + 1)/(|C| + 1) - cf/|C| = (|C| - cf) / (|C| (|C| + 1)), about 1/|C|. So the numerator tf + mu * p(w|C) grows by about mu / |C|: from 241 to 308.7 in the 25-token example (mu 2000), but only by 0.0015 at 1.3 million tokens. The relative change of p(w|C) is about 1/cf, so rare terms move most when the shift matters at all. The shift vanishes at mu = 0, where the term mu * p(w|C) is 0 under both models (one of the upstream test's cases), and when cf = |C|, where both models give 1.
Three related javadoc slips: IndriCollectionModel's javadoc says "divided by the total number of tokens + 1" but the code adds nothing (IndriDirichletSimilarity.java:101-104); LMSimilarity's class javadoc describes DefaultCollectionModel without its +1 (LMSimilarity.java:33-35); and DefaultCollectionModel's own javadoc names only the +1 in the denominator (LMSimilarity.java:140-143).
Exposure and likelihood342 words
- Who is hit. Users of
IndriDirichletSimilarity(float mu), the natural way to tune mu, installed withIndexSearcher#setSimilarity. Any positive mu, assertions on and off. The upstreamTestIndriDirichletSimilarityitself only uses this constructor. - Effect. For mu > 0, scores and
explain()differ from Indri's cf / |C| estimate, which the class description implies, and fromIndriDirichletSimilarity()with the same mu (except in the degenerate case cf = |C|). The set of matching documents does not change. - How likely a ranking change is. A credibility audit ran 1,984 random 2- and 3-term
BooleanQueryqueries over 5 synthetic corpora (1,458 to 1,309,450 tokens, mu 2000): no top hit changed, no top-10 set changed, one top-10 order changed. The largest relative score change was 0.019% at 1.3 million tokens and 0.5% to 6.8% on the small corpora. The audit sorted its top-10 lists fromWeight#scorerscores, not fromIndexSearcher#search, and synthetic corpora say nothing about real workloads. The ranking flips the checkers built are on tiny constructed corpora: in 26 of 146 swept 4-document indexes (130 to 3,030 tokens) two close documents, ranks 3 and 4 of 4, swapped places (scores read throughWeight#scorer, the count printed, not asserted); in one 3-document index of 35 tokens the top hit ofIndexSearcher#searchchanged. They show that flips can happen, not how often. - Where it shows on each release. Since 10.3.0 a plain top-k
TermQuerysearch under this similarity returns no hits at all, a separate bug (LFV-190, negative scores dropped byBatchScoreBulkScorer). So on 10.3.0 to 10.5.2 and main the wrong values show inexplain(),Scorer-level use and multi-clauseBooleanQuerysearch; on 8.9.0 to 10.2.x also in plain search (on 10.2.2,search(TermQuery("president"), 10)returns doc 0 at -2.119101 with the no-argument constructor and -1.871553 with(2000f)). This bug survives a fix of LFV-190 and of open PR #463. - Not reached. The case where the shift would be large, the smoothing score of an absent term in
IndriAndQuery, is not reached forTermQueryclauses on main (the audit, by reading).
The test shows that new IndriDirichletSimilarity(2000f) scores differently from new IndriDirichletSimilarity() (documented as mu = 2000), because the mu-only constructor falls back to LMSimilarity's (cf+1)/(|C|+1) collection model instead of IndriCollectionModel's cf/|C|.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.similarities;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.Term;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.Query;
import org.apache.lucene.search.TermQuery;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestIndriDirichletMuConstructor extends LuceneTestCase {

  public void testExplicitDefaultMuScoresLikeDefaultConstructor() throws Exception {
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
        Document doc = new Document();
        doc.add(new TextField("body", "a b", Field.Store.NO));
        w.addDocument(doc);
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        IndexSearcher searcher = new IndexSearcher(reader);
        Query q = new TermQuery(new Term("body", "a"));
        searcher.setSimilarity(new IndriDirichletSimilarity());
        float defaultMu = searcher.explain(q, 0).getValue().floatValue();
        searcher.setSimilarity(new IndriDirichletSimilarity(2000f));
        float explicitMu = searcher.explain(q, 0).getValue().floatValue();
        // () means mu=2000: expected p(a|C)=cf/|C|=1/2 for both; (2000f) uses (cf+1)/(|C|+1)=2/3
        assertEquals(defaultMu, explicitMu, 0f);
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-744/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.similarities.TestIndriDirichletMuConstructor
- Expected vs actual
- Expected equal explain() scores for term
ain the one-document indexa b; actualexpected:<-0.6931472> but was:<-0.4057149>(-ea and -da).
More files, environment, full output34 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<-0.6931472> but was:<-0.4057149>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:577)
       org.junit.Assert.assertEquals(Assert.java:701)
org.apache.lucene.search.similarities.TestIndriDirichletMuConstructor.testExplicitDefaultMuScoresLikeDefaultConstructor(TestIndriDirichletMuConstructor.java:50)- Class javadoc: "as implemented in the Indri Search engine" (implying cf / |C|); the no-argument constructor is documented only as "the default mu value of 2000".
- Nothing in code, tests, CHANGES or reviews says a chosen mu should switch the model; the upstream test asserts no scores.
- The sibling
LMDirichletSimilarity()isthis(2000): one model for both.
The full argument385 words
- Contract (implied, not word for word). Class javadoc: "Bayesian smoothing using Dirichlet priors as implemented in the Indri Search engine" (
IndriDirichletSimilarity.java:23-25); CHANGES for LUCENE-9537: "the IndriDirichletSimilarity from the academic Indri search engine" (lucene/CHANGES.txt:5346-5347). The class javadoc writes the formula with an unspecified P(t|C) (:27-30), so cf / |C| is implied, not stated. Indri computes cf / |C| for a term that occurs in the collection (a checker read it in the Indri source, and the fact check re-read it), which is whatIndriCollectionModeldoes; for a term that never occurs Indri uses 1 / (2|C|), which Lucene'sTermStatsnever allows, and Indri's own default mu is 2500. The no-argument constructor is documented only as "the default mu value of 2000" (:63). - The sibling keeps one model.
LMDirichletSimilarity, whose constructor signatures this class mirrors, hasLMDirichletSimilarity() { this(2000); }(LMDirichletSimilarity.java:71-73). OnlyIndriDirichletSimilarityswitched its no-argument constructor to another model. - No intent for the difference. The PR that added the class (apache/lucene-solr#2097, 10 conversation and 28 inline review comments) and LUCENE-9537 (#10577, 20 comments) never mention the collection model or the constructors. #13845 added the discountOverlaps constructor and discussed only that flag, not Indri. None of them says that choosing a mu should also switch the collection model.
- The upstream test does not pin it.
TestIndriDirichletSimilaritybuilds onlynew IndriDirichletSimilarity(mu)with a random mu (:48), asserts generic properties, no values, and passes with the fix. - The +1's original reason does not apply. LUCENE-3430 (2011) added the +1 in the numerator because SpanQueries sometimes scored terms with ttf = 0 (the +1 in the denominator dates from the first
LMSimilarity, LUCENE-2959). On mainTermStatsandFieldStatsreject zero counts (TermStats.java:77-80,FieldStats.java:102-104), and the no-argument constructor already uses cf / |C| on every input. That removes the zero-count reason; it does not rule out that a maintainer sees the +1 as deliberate smoothing. - Before the port (a checker's reading of third-party code): in the class author's own projects, Lucindri (release 1.1, 2020) and IndriLuceneImpl, the same constructor bodies sat on a base class whose default model is cf / |C|, so both constructors gave Indri's estimate. Rebasing the class on
LMSimilaritychanged the mu constructor's meaning silently. Nobody upstream has said so.
The devil's-advocate check185 words
The strongest case for "works as written" (built by the devil's advocate; the cross-model reviews rated it moderate): by Java's rules the mu-only constructor inherits LMSimilarity's documented default model, its javadoc promises only mu, the constructor signatures mirror LMDirichletSimilarity's, the (cf + 1)/(|C| + 1) default is a deliberate Lucene choice, LMSimilarity is @lucene.experimental (IndriDirichletSimilarity itself carries no marker), and the upstream test has always run the mu constructor.
Why it fails: it explains the mechanism but not why new IndriDirichletSimilarity() and new IndriDirichletSimilarity(2000f) should differ. The LMDirichletSimilarity precedent points the other way (all its model-less constructors share one model, and it claims no Indri fidelity), the +1's reason does not apply on main, the test asserts no values, and the author's original code gave cf / |C| on both paths. Verdict: not intended, but the contract is implied; a maintainer may answer with a javadoc note or another API change (deprecating the mu-only overload, naming the model in toString()) because a code fix changes scores for current users; the fix below is one reasonable resolution, not the only one.
Recommended The mu constructor uses IndriCollectionModel (validated)
Make the one-argument constructor delegate to this(new IndriCollectionModel(), mu), one line, and correct two javadoc comments about the +1 (a third can be added). The new test, every similarity test class and TestIndriAndQuery (28 classes, 123 tests) and :lucene:core:check -x test pass. It changes scores for current users of that constructor, so it needs a CHANGES entry.
  /** Instantiates the similarity with the provided μ parameter. */
  public IndriDirichletSimilarity(float mu) {
-    this.mu = mu;
+    this(new IndriCollectionModel(), mu);
  }
 ...
   * Models {@code p(w|C)} as the number of occurrences of the term in the collection, divided by
-   * the total number of tokens {@code + 1}.
+   * the total number of tokens.
All options and trade-offs3 options · 465 words
One option was built and validated with gradle; a documentation-only alternative was not run.
IndriDirichletSimilarity(float mu) becomes this(new IndriCollectionModel(), mu), like the no-argument constructor. In the same change, IndriCollectionModel's javadoc drops the "+ 1" it does not compute, and LMSimilarity's class javadoc states DefaultCollectionModel's +1. A third slip is not in the validated diff: DefaultCollectionModel's own javadoc (LMSimilarity.java:140-143) leaves out its numerator +1, a one-line javadoc edit you may add. Suggested CHANGES entry: "IndriDirichletSimilarity(float mu) now uses IndriCollectionModel, like the no-argument constructor. It used LMSimilarity's DefaultCollectionModel, (cf+1)/(|C|+1), so it scored differently from IndriDirichletSimilarity() with the same mu."
  /** Instantiates the similarity with the provided μ parameter. */
  public IndriDirichletSimilarity(float mu) {
-    this.mu = mu;
+    this(new IndriCollectionModel(), mu);
  }
 ...
   * Models {@code p(w|C)} as the number of occurrences of the term in the collection, divided by
-   * the total number of tokens {@code + 1}.
+   * the total number of tokens.
Trade-offs
Scores of current IndriDirichletSimilarity(float) users with mu > 0 change, toward Indri's formula and toward IndriDirichletSimilarity(). Indexes need no change: the model is applied at search time. No material cost change is expected (one model object per similarity, the same arithmetic per score); not benchmarked. A maintainer may want it on main only. Open PR #463 edits score() a few lines away, so the two may conflict textually.
What the checks validated
- Scratch worktree at
a9779ef3c193, gradle, JDK 25: the new test 3 of 3 with assertions on and off;TestIndriDirichletSimilarity2 of 2 andTestIndriAndQuery2 of 2; 140 of 140 over 20 iterations of the three. - Every class in
org.apache.lucene.search.similaritiesplusTestIndri*: 28 classes, 123 tests, 0 failures.:lucene:core:check -x test(google-java-format, ecjLint, forbiddenApis) and:lucene:core:renderJavadocpass. - Standalone runner with the patched class shadowed: the checker's ranking test passes (both constructors rank doc1 first); the independent reproducer's claim tests pass and only its diagnostic, which asserts the old behaviour, flips.
- Not run: the whole core suite (on main only
TestIndriDirichletSimilaritycalls the mu constructor).
Keep the code. Say in the mu constructor's javadoc that it uses LMSimilarity.DefaultCollectionModel, (cf+1)/(|C|+1), and that new IndriDirichletSimilarity(new IndriCollectionModel(), mu) gives Indri's estimate; fix the three javadoc slips. Optionally give IndriCollectionModel a non-null getName() so toString() tells the two apart.
Trade-offs
No score change for anyone, but new IndriDirichletSimilarity() and new IndriDirichletSimilarity(2000f) still differ, and without the naming change they still print the same name. The naming change alters toString() output.
Both constructors would then use DefaultCollectionModel, as in LMDirichletSimilarity.
Trade-offs
Removes the inconsistency but abandons the class's documented Indri estimate and changes scores for users of the default constructor (by reading; not run).
Solr and OpenSearch have no Indri code and Elasticsearch documents no Indri similarity, so the exposure is applications that build Lucene's IndriDirichletSimilarity themselves; the Lucindri project ships its own copy of the class.
Semi-formal: a bounded-exhaustive check scored every 1- to 4-token document over a 3-letter alphabet (120 documents) with TermQuery and compared each score with the Indri formula. IndriDirichletSimilarity(3f) missed it in all 1,080 checks while the no-argument version matched for unboosted queries, which led to the constructor.
The method in full146 words
Method: bounded-exhaustive translation validation of scoring components against their documented formulas (hunt unit "scoring components vs documented formulas", harness part B1, 2026-10-27, main a9779ef3c193).
- The harness indexed every document of 1 to 4 tokens over a 3-letter alphabet (120 documents, including a 4-byte and a 3-byte letter), scored each
TermQueryhit throughWeight#scorer, and compared it with log((tf + mu * cf/|C|) / (|D| + mu)). IndriDirichletSimilarity()matched for unboosted queries (its remaining mismatches are boosted queries, whose boostscore()ignores, which open PR #463 also changes).IndriDirichletSimilarity(3f)mismatched in all 1,080 of its formula checks.- Reading the code traced that to the constructor. The finder then wrote the public-API JUnit, checked it on 10.5.2 and 9.12.3, and validated the one-line fix with the upstream Indri tests.
- Tier: semi-formal (a bounded-exhaustive check of the real jar against exact semantics); it proves nothing beyond its bounds.
No prior report found (searched 2026-10-27): GitHub issues, PRs and commits, the files of all 408 open PRs, JIRA, the mailing lists, downstream projects and the web, 147 queries. The issue and PR that added the class never discuss the collection model; open PR #463 edits the same file (the boost in score()), not the constructors.
Searches5 searches
Verdict new, confidence high but not certain.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; downstream repositories | 2026-10-27 | two runs of a scripted prior-report search (identifiers; formula and symptom terms) plus 23 GitHub GraphQL searches over apache/lucene, apache/lucene-solr, apache/solr, Elasticsearch, OpenSearch, the Lucindri repositories and all of GitHub; upstream file history on 4 branches | no report; #10577 / apache/lucene-solr#2097 added the class without discussing the model; #13845 added the discountOverlaps constructor; #11194, #8530, #6909 are other Indri or LM questions |
| Open apache/lucene PRs | 2026-10-27 | the changed files of all 408 open PRs | only #463 (LUCENE-10157, Stale) touches the file; it changes score() to apply the boost, not the constructors |
| dev@, java-user@, issues@, commits@, the Solr lists, general@; JIRA | 2026-10-27 | 40 list queries through the tool and 11 direct list searches; 8 tool and 6 manual JIRA queries | no report; LUCENE-3220 (2011) is where LMSimilarity was developed (committed under LUCENE-2959 with the +1 in the denominator); the +1 in the numerator came with LUCENE-3430 |
| Web | 2026-10-27 | 5 searches | javadoc mirrors, PR #463, the separate Lucindri project; no report |
| Upstream re-check | 2026-10-27 | GitHub API: commits to IndriDirichletSimilarity.java on main; issue search "IndriDirichletSimilarity"; open PRs matching "Indri" | at upstream main HEAD f7bcc0abd816 the file's last commit is still 378ca8d1bbf3 (#15573, javadoc markup, 2026-01-15); no issue; #463 is the only open PR |
As old as the class: LUCENE-9537 added it on 2021-01-29 (9cc5c9b7983, backport a6125fb9385), first released in 8.9.0. Every release run, from 8.9.0 to 10.5.2, and main fail with identical values; 8.8.2 has no such class. Never fixed upstream.
Versions tested6 rows
Introduced by LUCENE-9537 "Add Indri Search Engine Functionality to Lucene" (issue #10577; PR apache/lucene-solr#2097 by cammiemw, merged by mikemccand): main 9cc5c9b7983 and branch_8x a6125fb9385, both 2021-01-29, with the same file. The PR's first commit (087d9d2a07c, 2020-11-24) already has these constructors. Later changes kept the mu constructor: LUCENE-9864 (@Override), #13845 (discountOverlaps constructor, 9.12.1 and 10.0.0), #15573 (javadoc markup). DefaultCollectionModel's numerator +1 dates from LUCENE-3430 (156a5c89ee8, 2011), its denominator +1 from the first LMSimilarity (LUCENE-2959, cfaf91c7398, 2011).
Not run, same code by reading: the releases between the executed ones (file blobs e494bc9800d5, 9f708362bb5, b3994c5dc46, 91fb1395cb1 on main), branch_10x and branch_10_6. Not fixed: at upstream main HEAD f7bcc0abd816 (2026-10-27) the file is unchanged since 378ca8d1bbf3 (#15573).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's test fails 2 of 3 (gradle and standalone runner, assertions on and off); passes with the fix |
| 10.3.0 to 10.5.2 | affected | 10.5.2 run (assertions on and off): same values; plain top-k TermQuery search shows no hits there (separate bug), explain() and BooleanQuery show the shift |
| 10.2.2 | affected | probe: plain search returns doc 0 at -2.119101 vs -1.871553 for the two constructors |
| 8.9.0, 8.11.4, 9.0.0, 9.12.1, 9.12.3, 10.0.0 | affected | the hunt's JUnit fails 2 of 2 with bit-identical values; this doc's test also on 9.12.3 |
| 8.8.2 | API absent | no IndriDirichletSimilarity class (compile error); the class arrived in 8.9.0 |
| main with the one-line fix | root cause | every repro passes; 28 test classes pass |
Confirmed by an independent reproducer, a devil's advocate with its own ranking probe, a cross-model review (OpenAI GPT-5.6, read-only: real, medium), the adjudication, the release sweep and a credibility audit. A read-only refute review could not run code and called its own verdict procedural. This doc's test and fix ran with gradle on main a9779ef3c193.
Checks and verdicts402 words
Each executing check ran its own test or probe on the stock jars; the controls (an explicit IndriCollectionModel, the no-argument constructor) pass everywhere. Neither cross-model review could execute code (reading only); separate runs re-ran the hunt's JUnit.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Bounded-exhaustive check: IndriDirichletSimilarity(3f) missed the Indri formula in 1,080 of 1,080 checks. Public-API JUnit: 2 of 2 fail on main (assertions on and off), 10.5.2 and 9.12.3; the one-line fix passes it, TestIndriDirichletSimilarity over 20 iterations and TestIndriAndQuery. |
| cross-model review, refute lens | not real on procedure only, low | OpenAI GPT-5.6, read-only: could not run code, called its verdict not a substantive refutation, agreed with the root cause, inputs in contract, intended-behaviour argument moderate. A separate re-run on main failed 2 of 2. |
| independent reproducer | real | Own JUnit (4 documents, 16 tokens, hand-computed oracle): 2 of 5 fail on main (assertions on and off), 10.5.2 and 9.12.3; controls pass; a diagnostic shows the mu constructor equals an explicit DefaultCollectionModel. |
| cross-model review, intended lens | real, medium | OpenAI GPT-5.6, read-only: intended-behaviour argument moderate, root cause agreed. A separate execution check on main: explain() shows 1/30 vs 2/31, the names are equal, and two close documents of a 2-clause query (ranks 3 and 4 of 4) swap places in 26 of 146 swept indexes (scores read through Weight#scorer; the count is printed, not asserted). |
| devil's advocate | real, moderate-high | Re-ran the hunt's JUnit (main, 10.5.2, 9.12.3); own IndexSearcher#search probe gives a different top hit per constructor and passes with the fix; intent evidence from the author's pre-port code. |
| adjudication | confirmed, high | Re-ran the independent reproduction's test (assertions on: 2 of 5 fail, controls pass) and the hunt's test (assertions off: 2 of 2 fail) on main. |
| Follow-up and audit | history, prior art, security; impact 70 -> 60 | Release sweep 8.8.2 to main (8.8.2 has no class, all others affected); prior-report verdict new; security none. The credibility audit re-ran the JUnit with new seeds and found no top-hit change in 1,984 random queries, so likelihood rare. |
| this doc | re-run on a9779ef3c193 | New 3-test JUnit with gradle and the standalone runner (2 of 3 fail, assertions on and off, also on 10.5.2 and 9.12.3); explain() probe on main and 10.2.2; the fix validated against the new test, the similarity package, the Indri tests and the core checks. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 438 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,244 words
- Registry title
- IndriDirichletSimilarity(float mu) uses LMSimilarity's default (cf+1)/(|C|+1) collection model instead of IndriCollectionModel (cf/|C|), so new IndriDirichletSimilarity(2000f) scores differently from new IndriDirichletSimilarity() although both print the same name
- Area
- search / similarities (IndriDirichletSimilarity constructors and the LMSimilarity collection model)
- Priority
- Low, rank 274: An opt-in similarity whose score shift (about mu/|C|) almost never changes rankings on realistic collections.
- Impact class
- silent wrong results
- Impact note
- Applications that score with IndriDirichletSimilarity built through its mu-only constructor (a non-default similarity; any mu, any index size, -ea and -da, default codec and IndexWriterConfig) get every score computed with collection probability (cf+1)/(|C|+1) instead of Indri's cf/|C|, so scores and explain() differ from the Indri formula and from IndriDirichletSimilarity() with the same mu (most for rare terms: 2/(|C|+1) instead of 1/|C| at cf = 1) and multi-clause rankings can flip between close documents (constructed probes the cross-model review, the intended-behaviour check); on 10.3.0 and later a plain top-k TermQuery search under this similarity already returns no hits (LFV-190), so there the wrong values show in explain(), Scorer-level use and multi-clause BooleanQuery search, and in 8.9.0 to 10.2.x also through plain search; nothing is written to the index.
- Summary
- You install new IndriDirichletSimilarity(2000f) and expect the same similarity as new IndriDirichletSimilarity(), which is documented as using 'the default mu value of 2000', and Indri's Dirichlet smoothing log((tf + mu*cf/|C|)/(|D| + mu)) for any mu. Instead the mu-only constructor passes no collection model, so its implicit super() installs LMSimilarity's DefaultCollectionModel, (cf+1)/(|C|+1), while only the no-argument constructor installs the class's own IndriCollectionModel, cf/|C|. On a 25-token index the term 'president' (cf 3) scores -1.871553 instead of -2.119101 in the same document, although both instances print 'LM IndriDirichlet(2000.000000)'.
- Introduced
- 9cc5c9b7983cf181280e18819f8516dc16ccf1ef (main, 2021-01-29) and a6125fb938553fe2cd8cd035b8ffb329a7a1a288 (branch_8x backport, same day, same IndriDirichletSimilarity.java blob e494bc9800d5): LUCENE-9537 'Add Indri Search Engine Functionality to Lucene' (GitHub issue apache/lucene#10577, PR apache/lucene-solr#2097 by cammiemw, merged by mikemccand). The class was added with the mu-only constructor { this.mu = mu; } (implicit super() = LMSimilarity(), DefaultCollectionModel) and the no-argument constructor this(new IndriCollectionModel(), 2000); the same constructor set is already in the PR's first commit 087d9d2a07c (2020-11-24). [read: git blame and git log in the history clone, read-only GitHub API; exec: 8.8.2 has no such class, 8.9.0 fails]. DefaultCollectionModel's (cf+1)/(|C|+1) dates from LUCENE-3430 (156a5c89ee8, 2011-09-12) and is unchanged since. (2021-01-29 (main and branch_8x))
- First affected version
- 8.9.0 [exec] (the first release with IndriDirichletSimilarity; 8.8.2 has no such class, so the repro does not compile there [exec])
- Affected versions
- every release from 8.9.0 through 10.5.2 (the last release before 10.6.0), 10.6.0 (by reading) and main a9779ef3c193 (unreleased 11.0); never fixed. [exec] the finder's JUnit fails 2 of 2 with bit-identical values on 8.9.0, 8.11.4, 9.0.0, 9.12.1, 9.12.3, 10.0.0, 10.5.2 (-ea and -da) and main (-ea and -da); the independent reproduction's and the intended-behaviour check's tests also fail on 10.5.2 and 9.12.3. [read] the mu-only constructor is the same in every release in between (file blobs e494bc9800d5, 9f708362bb5 for 9.0.0 to 9.12.0, b3994c5dc46 for 9.12.1 to 10.5.2, 91fb1395cb1 on main; in the 8.9.0 and 9.0.0 jars IndriDirichletSimilarity(float) calls LMSimilarity.<init>()V); branch_10x and branch_10_6 have the 10.5.2 blob (not executed); upstream main f7bcc0abd816 (2026-10-27) has the main blob. Not affected: releases before 8.9.0 (no class). All runs with JDK 25 on aarch64.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check; also reached by code reading
- Upstream and prior reports
- none found (2026-10-27, read-only; the prior-report record, verdict new: 147 recorded queries, namely two scripted prior-report searches (A: identifiers, B: formula and symptom terms; 90 queries over apache/lucene GitHub issues, PRs and commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists and the JIRA archive) plus a re-read of the finder's run, and 57 manual searches and reads (23 GitHub GraphQL searches over apache/lucene, apache/lucene-solr, apache/solr, Elasticsearch, OpenSearch, the Lucindri repositories and all of GitHub; the changed files of all 408 open apache/lucene PRs; upstream file history on 4 branches; 11 direct mailing-list searches including the Solr lists and general@; 6 JIRA queries; 5 web searches); 10 hits read, none the same bug). Closest items, not reports: #463 (LUCENE-10157, open, Stale), the only open PR touching IndriDirichletSimilarity.java, which changes score() to apply the boost and not the constructors (a fix would sit a few lines away and could conflict textually); #10577 (LUCENE-9537) and apache/lucene-solr#2097, which added the class and never discuss the collection model or the constructors; #13845, which added the (CollectionModel, boolean, float) constructor and left the mu-only one unchanged; #11194 (LUCENE-10157); #8530 and #6909 (LMDirichletSimilarity formula and LM background scores, other classes); LUCENE-3220 (origin of LMSimilarity's +1 default model, 2011). Context, not a report: in Lucindri release 1.1 (ece369987a, 2020-06-18), the project the class was ported from, the same constructors sit on a base class whose default collection model is cf/|C|. Not fixed upstream: main f7bcc0abd816, branch_10x and branch_10_6 still have the mu-only constructor unchanged. Gaps: GitHub search reads one page per query and GitHub's search rate limit was exhausted at the start (a scripted prior-report search throttled and completed; manual searches used GraphQL); issue search does not index identifiers inside PR diffs (covered by the open-PR file scan); no Elasticsearch code search; list search is keyword-based; private channels cannot be searched.
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-27) with gradle in a scratch worktree and with the standalone JUnit runner, assertions on and off; the 10.5.2 and 9.12.3 release jars (this doc's test) and 10.2.2 (a print-only probe ofexplain()and plain search). The hunt's 2-test JUnit ran on 8.9.0, 8.11.4, 9.0.0, 9.12.1, 9.12.3, 10.0.0, 10.5.2 and main (8.8.2 has no such class). The recommended fix was validated in the scratch worktree: the new test, every similarity test class andTestIndriAndQuery(28 classes, 123 tests), 20 iterations of the Indri tests,:lucene:core:check -x testand the core javadoc build.
- Finding record
lucene/core/src/java/org/apache/lucene/search/similarities/IndriDirichletSimilarity.java:23-25 (class javadoc 'as implemented in the Indri Search engine'), :53-56 (mu-only constructor, implicit super()), :63-66 (no-argument constructor this(new IndriCollectionModel(), 2000), javadoc 'default mu value of 2000'), :96-99 (getName prints only mu), :101-113 (IndriCollectionModel ttf/sumTotalTermFreq; javadoc says '+ 1')lucene/core/src/java/org/apache/lucene/search/similarities/LMSimilarity.java:33-35 (class javadoc describes DefaultCollectionModel without the +1), :38 (@lucene.experimental), :55-58 (LMSimilarity() installs DefaultCollectionModel), :140-152 (DefaultCollectionModel (ttf + 1) / (sumTotalTermFreq + 1))lucene/core/src/java/org/apache/lucene/search/similarities/LMDirichletSimilarity.java:71-72 (sibling no-argument constructor is this(2000)); lucene/core/src/test/org/apache/lucene/search/similarities/TestIndriDirichletSimilarity.java:48 (upstream test uses only the mu constructor); lucene/core/src/test/org/apache/lucene/search/TestIndriAndQuery.java:41 (uses only the no-argument constructor); lucene/CHANGES.txt:5346-5347 (LUCENE-9537 entry)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/search/similarities/IndriDirichletSimilarity.java:23-25, 40-66, 69-72, 96-99, 101-119 (at a9779ef3c193)lucene/core/src/java/org/apache/lucene/search/similarities/LMSimilarity.java:33-35, 55-58, 68-73, 75-80, 97-105, 140-158 (at a9779ef3c193)
- Who is affected
lucene/core/src/test/org/apache/lucene/search/similarities/TestIndriDirichletSimilarity.java:48; lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:477
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/search/similarities/IndriDirichletSimilarity.java:23-25, 63; lucene/core/src/java/org/apache/lucene/search/similarities/LMDirichletSimilarity.java:71-73; lucene/core/src/java/org/apache/lucene/search/similarities/LMSimilarity.java:38lucene/CHANGES.txt:5339-5348; lucene/core/src/java/org/apache/lucene/search/TermStats.java:77-80; FieldStats.java:102-104lucene/core/src/java/org/apache/lucene/search/similarities/IndriDirichletSimilarity.java:27-30 (class-javadoc formula with P(t|C)); LMDirichletSimilarity.java:40-73 (mu check); SimilarityBase.java:38, Similarity.java:89 (@lucene.experimental)
- TestIndriDirichletMuConstructor.java (JUnit test):
repro/LFV-744/src/org/apache/lucene/search/similarities/TestIndriDirichletMuConstructor.java(54 lines)
A summary still, made from the same example (4 documents, 25 tokens, "president" with cf 3); see the diagram README for what each frame shows and its sources.
assets/LFV-744/bug.png(438 KB)