SoraniNormalizer deletes a char when Character.getType(s[i]) == Character.FORMAT (SoraniNormalizer.java:121). A format character outside the BMP is two chars, a surrogate pair, and each half alone has type SURROGATE, so nothing is deleted. The test is the whole Cf category, and every BMP format character, directional or not, is removed.
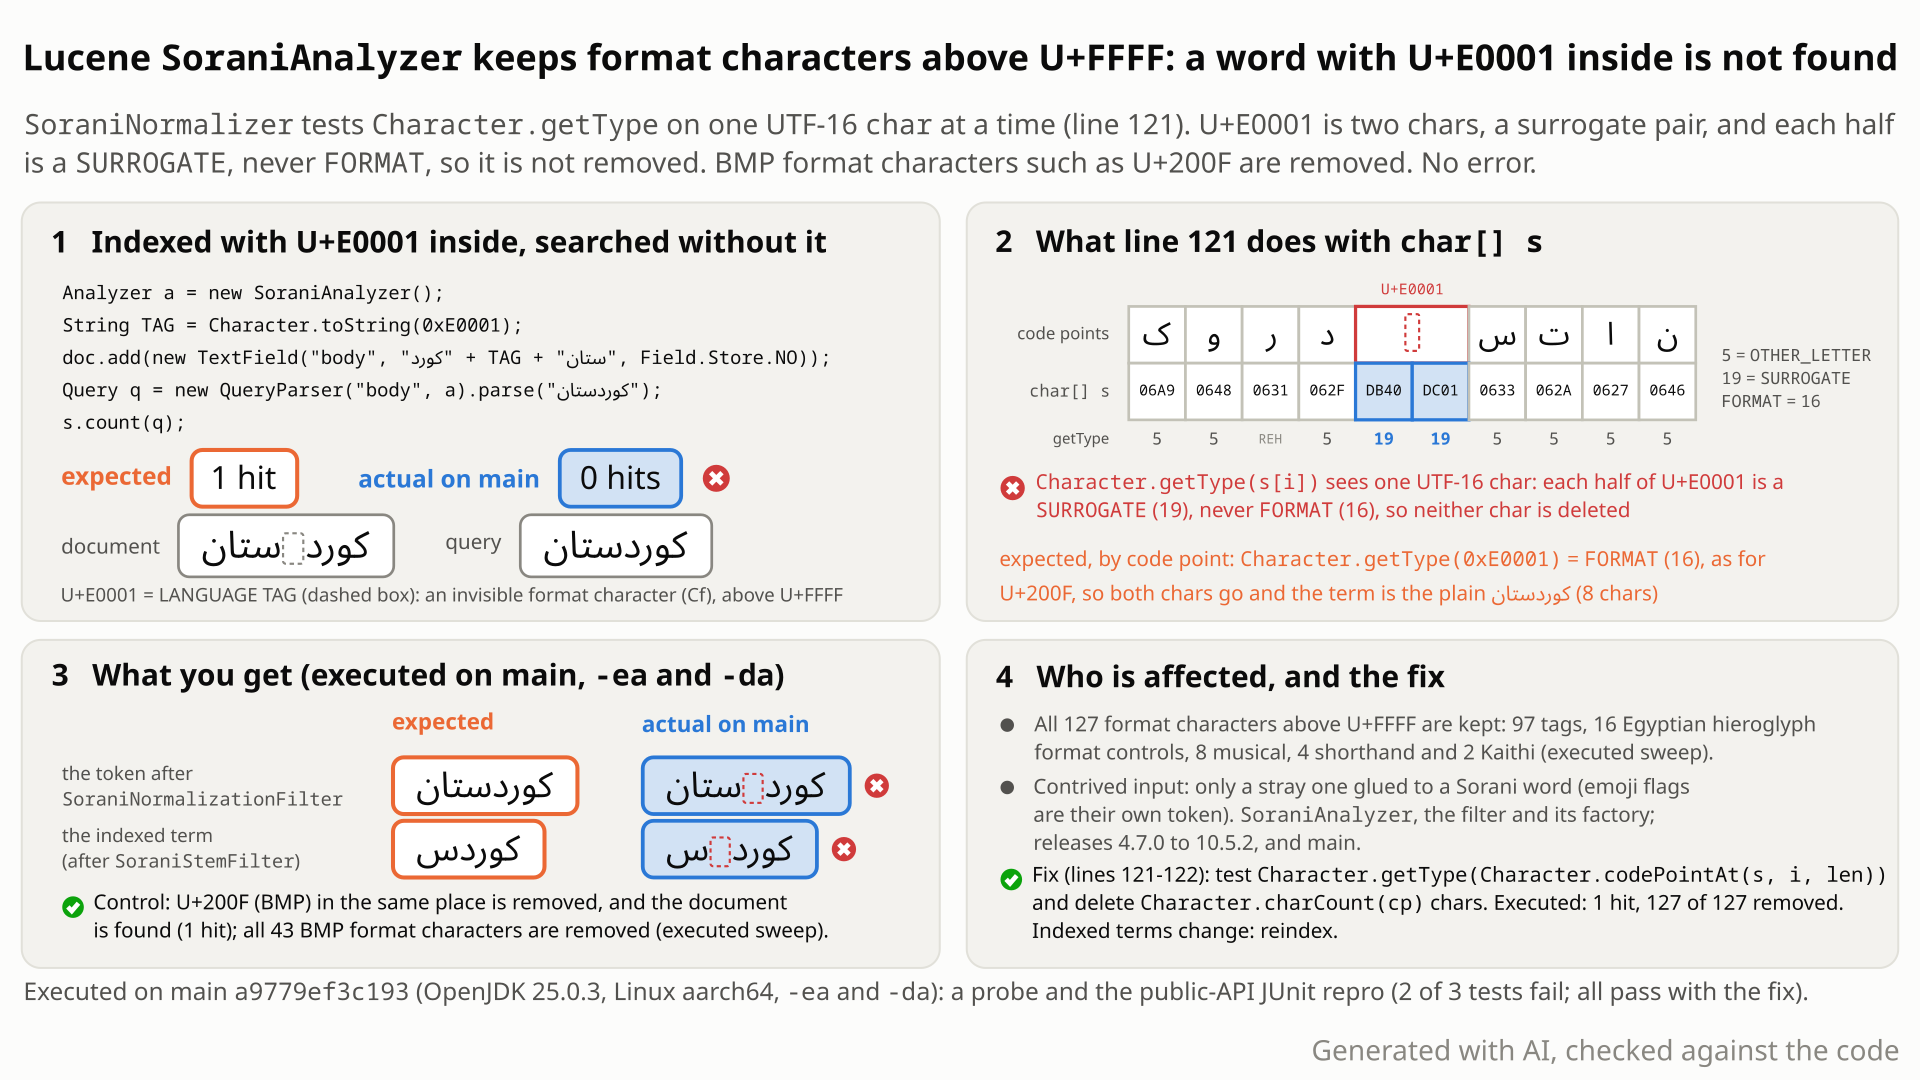
- You index کوردستان ("Kurdistan") three times with the default
SoraniAnalyzer, each copy with one invisible format character: the right-to-left mark U+200F inside the word, the language tag U+E0001 at the same spot, and U+E0001 at the end. - You search for the plain word through the same analyzer. You expect 3 hits: the normalizer's javadoc says formatting characters are removed, and it does remove the right-to-left mark.
- You get 1 hit. Java stores U+E0001 as two chars, U+DB40 U+DC01. The normalizer asks
Character.getTypeabout each char alone, which answers SURROGATE, never FORMAT, so neither is deleted and the indexed term keeps the character; at the end of the word it also blocks stemming. - All 43 format characters inside the BMP are removed, all 127 outside it are kept, and nothing throws with these inputs. Emoji flags, the best-known source of such characters, are tokenized on their own, so it takes stray or constructed input.
Fields analysed with the stock SoraniAnalyzer, SoraniNormalizationFilter or the soraniNormalization factory, at index and query time. It needs an invisible format character from outside the BMP glued to a Sorani word; emoji flags are tokenized on their own, so in practice only stray or constructed input hits it. Then it happens every time, with no error.
Mechanism, terms and numbers558 words
SoraniAnalyzer, SoraniNormalizationFilter and the soraniNormalization factory delete invisible formatting characters (Unicode general category Cf), as SoraniNormalizer's javadoc says: "Harakat, tatweel, and formatting characters such as directional controls are removed." The test reads one UTF-16 char at a time, Character.getType(s[i]) == Character.FORMAT (SoraniNormalizer.java:121). A format character outside the Basic Multilingual Plane (BMP), such as U+E0001 LANGUAGE TAG or a tag character U+E0020..U+E007F, is stored as a surrogate pair, and each half has type SURROGATE, so it is never deleted: all 43 BMP Cf code points are removed and all 127 supplementary ones (JDK 25) are kept. With the default SoraniAnalyzer, the word کوردستان with U+E0001 inside or at the end is not found by the plain word (1 of 3 documents found; the right-to-left-mark spelling is), and a trailing such character also blocks stemming. With these inputs nothing throws. Sorani letters and marks are all BMP characters, and emoji flags are tokenized separately, so only stray or constructed input hits it. The code is as old as the analyzer (4.7.0, 2014); testing the code point and deleting its chars fixes it.
- UTF-16 char: Java stores text as 16-bit
charvalues. Every Sorani letter and mark fits in one char: they are in the Basic Multilingual Plane (BMP). - Supplementary character: a code point above U+FFFF, stored as two chars, a surrogate pair. U+E0001 LANGUAGE TAG is the pair U+DB40 U+DC01. A surrogate alone is not a character; its general category is SURROGATE.
- Format character (Cf): an invisible character that affects layout or processing, such as the right-to-left mark U+200F, the soft hyphen U+00AD or the tag characters U+E0020..U+E007F.
Character.getType(int)returnsFORMATfor them; thecharoverload cannot, and its javadoc says it "cannot handle supplementary characters".
SoraniNormalizer.normalizewalks the term one char at a time and switches on the char: explicit cases fold letters and delete harakat, tatweel and ZWNJ (SoraniNormalizer.java:72-119).- Every other char reaches the
defaultbranch:if (Character.getType(s[i]) == Character.FORMAT) { len = delete(s, i, len); i--; }(:120-124). - For U+E0001 the two halves U+DB40 and U+DC01 arrive one by one;
getTypereturns SURROGATE (19) for each, not FORMAT (16), so neither is deleted and the character stays in the term. SoraniNormalizationFilter"applies {@link SoraniNormalizer}" (SoraniNormalizationFilter.java:24).SoraniAnalyzerruns it right afterStandardTokenizer, which keeps U+E0001 and U+E0067 inside the word token (word-break rule WB4), and again innormalize(SoraniAnalyzer.java:113-130).
X in کورد + X + ستان (filter after KeywordTokenizer) | category | SoraniNormalizationFilter |
|---|---|---|
| U+200F RLM, U+200E LRM, U+2066, U+00AD, U+FEFF | Cf, BMP | removed (correct) |
| U+E0001 LANGUAGE TAG | Cf, supplementary | kept |
| U+E0067 TAG LATIN SMALL LETTER G | Cf, supplementary | kept |
| U+1BCA0 SHORTHAND FORMAT LETTER OVERLAP | Cf, supplementary | kept |
| U+1D173 MUSICAL SYMBOL BEGIN BEAM | Cf, supplementary | kept |
With JDK 25 there are 43 Cf code points in the BMP, all removed (including non-directional ones such as U+00AD, U+0600..U+0605, U+200B, U+200D and U+FEFF), and 127 outside it, all kept: U+110BD, U+110CD, U+13430..U+1343F, U+1BCA0..U+1BCA3, U+1D173..U+1D17A, U+E0001 and U+E0020..U+E007F.
With the default SoraniAnalyzer the plain word and the right-to-left-mark spelling give the term [U+06A9 U+0648 U+0631 U+062F U+0633] (کوردس, after stemming); U+E0001 inside gives [U+06A9 U+0648 U+0631 U+062F U+E0001 U+0633], and U+E0001 at the end gives the unstemmed [U+06A9 U+0648 U+0631 U+062F U+0633 U+062A U+0627 U+0646 U+E0001].
Exposure and likelihood322 words
- Who is exposed. The stock
SoraniAnalyzerwith any constructor (indexing andnormalize), any chain withSoraniNormalizationFilter, and thesoraniNormalizationfactory (SoraniNormalizationFilterFactory.java:40; itsnormalizeis the same filter,:60-63). - What it takes. One of the 127 supplementary format characters inside or at the end of a word in a Sorani-analysed field. Sorani letters and marks are all BMP characters, so Sorani text has no need of them. The best-known real source, emoji subdivision flags (a black flag followed by tag characters), does not reach a Sorani word:
StandardTokenizeremits the flag as its own<EMOJI>token, with or without a space, and the word token stays clean and is stemmed. So it takes a bare stray tag character, a deprecated language tag or another exotic format control glued to a word: garbled or deliberately constructed input. - What changes for the user. The word with the character and the plain word become different terms, so a search for the plain word misses the document (1 of 3 found in the repro); a trailing such character also blocks stemming.
Analyzer.normalizekeeps the character too, so wildcard, prefix and fuzzy terms built from such text keep it (read from the query parser; not run end to end). - What does not happen. With the inputs run, no exception; the surrogate pair stays intact, so the term is valid UTF-16; other tokens, fields and documents are unaffected; the run time stays small (about 1,200,000 chars of such words in 67-137 ms; one input size, no scaling measured).
- Scale. Deterministic, with assertions on or off, at any index size.
- JDK dependence. The affected set follows the JDK's Unicode tables (127 with JDK 25); U+E0001 and the tag characters have been Cf since Unicode 3.1, so every JDK Lucene supports shows it. Only JDK 25 was run.
- How likely. Contrived for accidental hits; the documented searches found no report in the 12 years since 4.7.0.
The test shows that SoraniNormalizationFilter removes BMP format characters such as U+200F, but it keeps the format character U+E0001, which is outside the BMP, because SoraniNormalizer tests Character.getType on one UTF-16 char at a time.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.ckb;

import java.io.StringReader;
import org.apache.lucene.analysis.Tokenizer;
import org.apache.lucene.analysis.core.KeywordTokenizer;
import org.apache.lucene.tests.analysis.BaseTokenStreamTestCase;

public class TestSoraniNormalizationFilterSupplementaryFormatChar extends BaseTokenStreamTestCase {

  public void testRemovesFormatCharOutsideBmp() throws Exception {
    Tokenizer tokenizer = new KeywordTokenizer();
    tokenizer.setReader(
        new StringReader("\u06A9\u0648\u0631\u062F\uDB40\uDC01\u0633\u062A\u0627\u0646"));
    // expected: U+E0001, a format char like the removed U+200F, is removed; actual: it is kept
    assertTokenStreamContents(
        new SoraniNormalizationFilter(tokenizer),
        new String[] {"\u06A9\u0648\u0631\u062F\u0633\u062A\u0627\u0646"});
  }
}
# in a copy of this finding's repro folder (repro/LFV-752/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.ckb.TestSoraniNormalizationFilterSupplementaryFormatChar
- Expected vs actual
- Expected: \u06A9\u0648\u0631\u062F + U+E0001 + \u0633\u062A\u0627\u0646 becomes \u06A9\u0648\u0631\u062F\u0633\u062A\u0627\u0646. Actual (-ea and -da): U+E0001 stays in the term (the ComparisonFailure shows it as an invisible character inside
[]).
More files, environment, full output38 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
=> org.junit.ComparisonFailure: term 0 expected:<کورد[]ستان> but was:<کورد[]ستان>
org.junit.Assert.assertEquals(Assert.java:117)
org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:262)
org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:513)
org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:598)
org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:622)
org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:689)
org.apache.lucene.analysis.ckb.TestSoraniNormalizationFilterSupplementaryFormatChar.testRemovesFormatCharOutsideBmp(TestSoraniNormalizationFilterSupplementaryFormatChar.java:31)- The javadoc says formatting characters "such as directional controls" are removed; the code tests the whole Cf category and removes all 43 BMP ones.
- The public filter "applies {@link SoraniNormalizer}", public through 9.12.3; upstream's vocabulary test needs this branch for U+202E.
- The JDK says
getType(char)cannot handle supplementary characters; LUCENE-6914 fixed the same mistake inDecimalDigitFilter, in this chain.
The full argument295 words
- Contract. "Harakat, tatweel, and formatting characters such as directional controls are removed." (
SoraniNormalizer.java:33, unchanged since 4.7.0). Directional controls are an example; the code's criterion isCharacter.FORMAT, and every BMP Cf character is removed (ZWNJ by its own case, the other 42 by this branch), including the soft hyphen, ZWJ, the BOM and U+0600..U+0605. Only the UTF-16 encoding decides which Cf characters survive. - The contract is public.
SoraniNormalizationFilter: "A {@link TokenFilter} that applies {@link SoraniNormalizer} to normalize the orthography."SoraniNormalizerwas a public class from 4.7.0 through 9.12.3, and Lucene's javadoc builds document protected members (-protected;javadoc.access=protectedin the 4.x ant build), so the release javadoc builds included the sentence (build settings read, not the published pages); 10.0.0 made the class package-private (LUCENE-10561), changing only modifiers. - Nothing presents it as a choice. The only upstream test that reaches the
FORMATbranch isTestSoraniStemFilter.testVocabulary: 11 words of its Sorani vocabulary end in U+202E RIGHT-TO-LEFT OVERRIDE, a BMP format character no switch case matches, and their expected stems lack it, so upstream relies on this branch to remove a BMP directional control (with the branch disabled, that test fails; executed by the fact check). No upstream test uses a supplementary format character.TestSoraniNormalizationFilter.testRemovecovers tatweel, harakat and ZWNJ, all explicit cases. The issue that added the analyzer (#6442, LUCENE-5379) never mentions format or supplementary characters, and no comment, CHANGES or MIGRATE entry limits the removal to the BMP. - Precedent.
lucene/CHANGES.txt:8852: "LUCENE-6914: Fixed DecimalDigitFilter in case of supplementary code points."DecimalDigitFilterruns two filters after this one inSoraniAnalyzer. #2763 (LUCENE-1689, 2009) set the rule that "supplementary character support should be fixed for code that works with char/char[]", andTurkishLowerCaseFiltermakes the same kind of category test by code point.
The devil's-advocate check180 words
The strongest case for "intended" (the intended-behaviour check and the cross-model reviewers): this is a Sorani orthographic normalizer, Sorani text only needs BMP marks, the removal sentence sits on a package-private class, and keeping tag characters preserves emoji flags.
Why it fails: the code tests the general Cf category, not a list of Sorani marks, and already removes non-directional BMP Cf characters; the public filter links the class as what it applies, and the class was public with this javadoc through 9.x; there is no emoji-preservation intent, because the same branch already strips the BMP ZWJ from ZWJ emoji sequences ([U+1F468 U+200D U+1F469 U+200D U+1F467] becomes [U+1F468 U+1F469 U+1F467]), and flags survive only because their tags are supplementary; and the JDK documents that getType(char) cannot classify these characters. Every verifier rejected the argument, and the cross-model reviews rated it weak. What survives is plausibility, not intent: such input is rare, which lowers the priority but does not make the behaviour intended. No record states the 2014 authors' intent either way; changing indexed terms is the maintainers' compatibility call.
Recommended A: test the code point, delete all its chars
Test the code point and delete all its chars: Character.getType(Character.codePointAt(s, i, len)), then deleteN(s, i, len, Character.charCount(cp)) (SoraniNormalizer.java:121, +4/-2). The repro then passes, assertions on and off, and so does the whole analysis-common test task. Side effect: emoji subdivision flags fold to the bare black flag; affected fields need a reindex.
         default:
-          if (Character.getType(s[i]) == Character.FORMAT) {
-            len = delete(s, i, len);
+          final int cp = Character.codePointAt(s, i, len);
+          if (Character.getType(cp) == Character.FORMAT) {
+            len = deleteN(s, i, len, Character.charCount(cp));
             i--;
           }

+import static org.apache.lucene.analysis.util.StemmerUtil.deleteN;
All options and trade-offs3 options · 500 words
One fix was built and validated in a scratch worktree at a9779ef3c193; the hunt had already checked an equivalent version. Two alternatives are listed for the maintainers' discussion.
In the default branch, read the code point with Character.codePointAt(s, i, len), test Character.getType(int), and delete Character.charCount(cp) chars with the existing StemmerUtil.deleteN. BMP chars take the same path as before; a low surrogate of a kept supplementary character is looked at again on the next step, but alone it is SURROGATE, so nothing else changes.
         default:
-          if (Character.getType(s[i]) == Character.FORMAT) {
-            len = delete(s, i, len);
+          final int cp = Character.codePointAt(s, i, len);
+          if (Character.getType(cp) == Character.FORMAT) {
+            len = deleteN(s, i, len, Character.charCount(cp));
             i--;
           }

+import static org.apache.lucene.analysis.util.StemmerUtil.deleteN;
Trade-offs
- Changes output only for the 127 supplementary Cf code points.
- Emoji flags fold. Emoji subdivision-flag tokens (U+1F3F4, tag characters, U+E007F) lose their tags, so the Scotland and England flags both become the term U+1F3F4. The stock branch already folds ZWJ emoji sequences the same way (the family emoji loses its ZWJs), so the two become consistent, but a reviewer may raise it.
- Indexed terms change for text with these characters, so affected fields need reindexing; a CHANGES entry should say so.
- If the fix for LFV-668 (word-final HEH before a direction mark, same method) goes in too, its
isWordFinalhelper should read code points as well, or HEH followed by a supplementary format character keeps this bug there.
What the checks validated
- Stock main: the paste-ready test fails 3 of 4, assertions on and off; the 30 upstream Sorani tests pass.
- With fix A,
org.apache.lucene.analysis.ckb.*: 6 classes, 34 tests, 0 failures, assertions on and off. - With fix A, the whole
:lucene:analysis:common:testtask: 340 classes, 1,913 tests, 0 failures, 18 skipped (skips not examined). ecjLintMain,ecjLintTestandcheckGoogleJavaFormatof the module pass.- The standalone runner with the fixed class first on the classpath: the test passes on main with
-eaand-da, and so do the independent reproduction's test over all 127 supplementary Cf code points (4 of 4) and the finder's test (3 of 3). - The hunt's two equivalent sketches passed the finder's, the independent reproduction's and separate tests; 28 upstream Sorani tests pass with and without the finder's.
Exempt U+E0020..U+E007F (and perhaps U+E0001) from removal, so emoji flags keep their identity.
Trade-offs
Not built or run. It leaves up to 97 of the 127 supplementary Cf code points in Sorani words, contradicts the javadoc's general rule and is inconsistent with the ZWJ removal; only worth it if maintainers object to the flag folding.
A javadoc note that only BMP formatting characters are removed.
Trade-offs
Cheap, but contradicts the documented rule and the project's own fixes of char-wise analysis code (LUCENE-6914, LUCENE-1689) for no benefit.
Search servers built on Lucene that configure a Sorani field type with this filter, as the factory's javadoc example text_ckbnormal does, inherit the behaviour; whether an invisible character that changes a term matters beyond search quality, for example in a term-based word filter, depends on that product.
Semi-formal. A bytecode scan of the main jars listed every call of the char overloads of Character category tests, which cannot classify a supplementary character. SoraniNormalizer.normalize:121 was one, and the only FORMAT removal in the analysis modules; a probe with 7 BMP and 7 supplementary format characters, then a public-API JUnit, confirmed it.
The method in full141 words
Method: a bytecode call-site inventory (the hunt's semi-formal tier), in a hunt unit about supplementary-plane characters in parsers and char-wise filters. A scanner built on the JDK 25 ClassFile API read the 27 non-sandbox, non-test module jars of main a9779ef3c193 and listed every call of the char overloads of Character category tests (getType, isLetter, ...), which cannot classify a supplementary character. One row was SoraniNormalizer.normalize:121 Character.getType(C).
Code reading found it to be the only Character.FORMAT removal site in the analysis modules. A probe put 7 BMP Cf characters (U+200F, U+200E, U+202B, U+2066, U+FEFF, U+00AD, U+061C) and 7 supplementary ones (U+E0001, U+E0067, U+E007F, U+1BCA0, U+1D173, U+110BD, U+13430) into a Sorani word: all BMP ones were removed, none of the supplementary ones. A public-API JUnit on the stock main jars then confirmed it through SoraniNormalizationFilter and SoraniAnalyzer (found 2026-10-27).
No prior report found: a scripted prior-report search run (51 queries over GitHub, JIRA, mailing lists and the web), 31 manual GitHub searches, downstream trackers and the fuzzer feed on 2026-10-27, and a GitHub re-check on 2026-10-28. Nearest: a withdrawn fuzzer crash in the same method, a different symptom. Not fixed upstream.
Searches5 searches
No issue, PR, JIRA entry, mailing-list thread, downstream issue, fuzzer report or web page reports that SoraniNormalizer, SoraniNormalizationFilter or SoraniAnalyzer keeps format characters outside the BMP. The nearest items are context or precedent: #6442 (LUCENE-5379, which added the analyzer; nothing on format or supplementary characters), OSV-2025-253 (an OSS-Fuzz crash in the same method, reached from WordDelimiterGraphFilter, withdrawn 2026-10-01) and the java-user@ thread on scanner advisory sonatype-2025-002284 derived from it (maintainers dweiss and uschindler found it unactionable): both report an exception, while this bug throws nothing and returns a well-formed term. #2763 (LUCENE-1689) and #3259 (LUCENE-2183) are the 2009 umbrella rule for supplementary characters in char-based analysis code, resolved before the ckb package existed. LFV-668 is the hunt's own earlier finding on the same class, with a different root cause and fix.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene), web | 2026-10-27 | the scripted prior-report search (51 queries, 0 errors: 16 issue/PR, 3 commit, 2 downstream, 20 list, 4 JIRA, 6 web) and 31 manual GitHub searches (29 on apache/lucene, 2 on apache/lucenenet): class names, Character.getType, Character.FORMAT, format characters, tag characters, E0001, supplementary and surrogate phrasings, the advisory and OSV ids; issue #6442 read in full; the git history of ckb/ | no report; the finder's run (45 queries) and the intended-behaviour check's (75 hits, 0 high, 0 medium) agree |
| Fuzzer feed and mailing lists | 2026-10-27 | the OSV OSS-Fuzz feed for Lucene (14 entries) and the fuzzer sources; 16 list queries over dev@, java-user@, issues@ and commits@ besides the tool's 20 | OSV-2025-253 and the sonatype-2025-002284 thread: an exception in the same method, not this bug |
| Open PRs and JIRA archive | 2026-10-27 | a file scan of every open PR labelled module:analysis and of the open PRs touching ckb/; 6 JIRA queries | only #16911 touches ckb/ (it deletes the files on branch_10x); no JIRA report |
| Downstream trackers | 2026-10-27 | Elasticsearch, OpenSearch, Solr and the OSS-Fuzz repositories (7 searches) | only registrations of the filter and lists of analyzers |
| GitHub re-check | 2026-10-28 | 5 read-only queries (SoraniNormalizer, SoraniNormalizationFilter, SoraniAnalyzer, Sorani supplementary, Character.FORMAT supplementary; 3 more hit the rate limit) and the commits on the file | nothing new; the file's last upstream commit is from 2022 (visibility only) |
As old as the analyzer: added on 2014-01-04 by 2140f4368ade (LUCENE-5379) and its branch_4x twin a670b8d5b22, first released in 4.7.0. The logic has not changed since; 11 sampled releases from 4.7.0 to 10.5.2 and main reproduce it.
Versions tested7 rows
Introduced by 2140f4368ade (trunk, svn r1555359, 2014-01-04, "LUCENE-5379: Kurdish Analyzer", by rmuir; issue #6442) and the same-day branch_4x commit a670b8d5b22 (r1555360, identical file), which shipped in 4.7.0 (CHANGES: "LUCENE-5379: Add Analyzer for Kurdish. (Robert Muir)"). A JIRA patch, no PR. The char-wise test and the javadoc sentence were in the first version of the file; the four later commits are a licence-header move, a reformat, array syntax and the LUCENE-10561 visibility change (10.0.0). Not a regression. SoraniAnalyzer's @since 4.10.0 tag is wrong (the factory says 4.7.0, and 4.7.0 runs the analyzer). In 4.7.0 to 6.6.6 StandardTokenizer splits the word at U+1BCA0; U+E0001 and U+E0067 stay inside the word token in every release run. Upstream main still has the line (last commit on the file in 2022).
| Version or commit | Verdict | Result |
|---|---|---|
| 4.6.1 | no API | no Sorani analysis API (compile error) |
| 4.7.0 | affected | first release: U+E0001, U+E0067 and U+1BCA0 kept; the BMP controls removed |
| 4.10.4, 5.0.0, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0 | affected | the follow-up's cross-version main() harness reports the bug on each |
| 9.12.3, 10.0.0 | affected | the finder's JUnit fails 2 of 3; this doc's test fails 3 of 4 on 9.12.3 (-da) |
| 10.5.2 | affected | this doc's test: 4 run, 3 failed (-da), the same messages as main |
main a9779ef3c193 | affected | this doc's test: 3 of 4 fail through gradle and the JUnit runner, -ea and -da |
| main + fix A | fix | 34 of 34 Sorani tests and the whole analysis-common task pass |
The finder, an independent reproducer, an intended-behaviour devil's advocate, the adjudication, a registry re-run and a credibility audit all ran code and said real. Reviews from another model family (OpenAI GPT-5.6) could only read code; both agreed on the root cause. This doc validated the fix through gradle.
Checks and verdicts372 words
Every check ran on main a9779ef3c193 with JDK 25.0.3; the cross-model reviews read main ea57360912ed, where the relevant lines are identical. Neither cross-model review could execute code, so all execution evidence comes from Claude-family AI tools and separate runs.
| Check | Verdict | What it found |
|---|---|---|
| finder: bytecode scan, probe and JUnit | candidate | Scan row SoraniNormalizer.normalize:121; probe: 7 BMP Cf removed, 7 supplementary kept. The JUnit fails 2 of 3 on main (-ea, -da), 10.5.2 and 9.12.3; with the code-point fix 3 of 3 pass, and 28 upstream Sorani tests pass with and without it. |
| cross-model reviewer, refute lens (OpenAI GPT-5.6) | not real, for procedural reasons only (low) | Reading only: it could not run code, "not a substantive exoneration". Root cause agrees, inputs in contract, intended argument weak; a separate re-run failed 2 of 3. |
| Independent reproducer | real | Own 4-test JUnit fails 3 of 4 on main (-ea, -da), 10.5.2 and 9.12.3: all 127 supplementary Cf kept, 0 hits for the plain word with U+E0001, U+E0067, U+1BCA0 or U+1D173 inside (1 with U+200F); 4 of 4 with a code-point fix. |
| Cross-model reviewer, intended lens (OpenAI GPT-5.6) | real, medium | Reading only; intended argument weak. Separate re-runs and a separate probe fail on main (-ea, -da) and pass with the fix. |
| Intended-behaviour devil's advocate | real, high | All 43 BMP Cf removed and all 127 supplementary Cf kept on main, 10.5.2 and 9.12.3; StandardTokenizer keeps U+E0001 inside the word; built and rejected the "BMP-only by design" case. |
| adjudication | confirmed, high | New seed: the independent reproduction's test fails 3 of 4 with -ea and -da, 4 of 4 pass with the fix. |
| registry re-run and credibility audit | confirmed; likelihood lowered to contrived | Clean checkout: the finder's test fails 2 of 3 (-ea, -da) and passes with the fix; the audit's probe shows emoji flags form their own token, so accidental hits are contrived. |
| this doc | confirmed; fix validated | New format-clean test fails 3 of 4 through gradle (-ea, -da) and the runner (main, 10.5.2, 9.12.3); the fix passes it, the 30 upstream Sorani tests and the whole analysis-common task; a plain JDK count gives 43 BMP and 127 supplementary Cf code points. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 514 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,412 words
- Registry title
- SoraniNormalizer tests for format characters one UTF-16 char at a time, so format characters outside the BMP (U+E0001, the tag characters U+E0020..U+E007F, U+1BCA0..U+1BCA3, U+1D173..U+1D17A and others) are kept in the term, while BMP ones such as RLM and LRM are removed
- Area
- analysis-common / Sorani normalizer (SoraniNormalizer.normalize; SoraniNormalizationFilter, SoraniAnalyzer and the 'soraniNormalization' factory)
- Priority
- Low, rank 529: The stock SoraniAnalyzer keeps supplementary format characters, but only garbled or constructed input puts one inside a Sorani word, which is more contrived than the Adlam and Osage text behind LFV-533, so it closes the low surrogate-handling analysis rows.
- Impact class
- silent wrong results
- Impact note
- Search quality only, with no error: applications that analyze Sorani Kurdish text with SoraniAnalyzer (default constructor included), SoraniNormalizationFilter or the 'soraniNormalization' factory, on every release from 4.7.0 through 10.5.2 and on main, index and query a word that carries an invisible format character from outside the BMP (any of the 127 supplementary Cf code points of JDK 25, for example a tag character or U+E0001; StandardTokenizer keeps it inside the word token) as a different term from the same word without it, so a search for the plain word misses it, through the token stream and through Analyzer.normalize alike, and such a character at the end of a word also blocks stemming; no scale is needed, -ea and -da behave the same, such characters are very rare in real Sorani text, and because a fix changes indexed terms, affected fields need reindexing after it.
- Summary
- You analyze Sorani Kurdish text with the stock SoraniAnalyzer or SoraniNormalizationFilter. The normalizer's javadoc says formatting characters are removed, and it does remove BMP ones such as the right-to-left mark, so کورد + X + ستان should become کوردستان for any invisible format character X. Instead it calls Character.getType on one UTF-16 char at a time, so a format character outside the BMP (for example U+E0001 or a tag character), which Java stores as two surrogate chars, is never recognized: it stays in the term, and the word no longer matches the same word without it, with no error.
- Introduced
- 2140f4368ade00f1d3b6f2bb25ecaf257c639c3d (trunk, Subversion r1555359, 'LUCENE-5379: Kurdish Analyzer' by rmuir; JIRA LUCENE-5379, migrated as apache/lucene#6442; no PR, pre-GitHub) with its same-day branch_4x backport a670b8d5b22 (r1555360, identical SoraniNormalizer.java), the copy that shipped in 4.7.0 [read: git blame -w on main lines 33 and 120-125 and git log -L 120,125 in the history clone]: the char-wise 'Character.getType(s[i]) == Character.FORMAT' test and the javadoc sentence 'Harakat, tatweel, and formatting characters such as directional controls are removed.' were in the first version of the file. Not a regression: the four later commits on the file (813ca77250d LUCENE-7013 license header, 8ef6a0da568 LUCENE-9570 reformat, 8ac26737913 LUCENE-10003 array syntax, 694d797526a LUCENE-10561 package-private) leave this logic unchanged. (2014-01-04 (trunk and branch_4x; first released in 4.7.0))
- First affected version
- 4.7.0 [exec] (the first release with the org.apache.lucene.analysis.ckb package; the follow-up's 4.x-API main() repro reports the bug there: U+E0001, U+E0067 and U+1BCA0 are kept by SoraniNormalizationFilter while the BMP control U+200F, U+200E, U+2066 is removed). 4.6.1, the last release before it, has no Sorani analysis API [exec: the repro does not compile], so no release ever removed supplementary format characters.
- Affected versions
- Every release that ships the Sorani analysis API, 4.7.0 through 10.5.2, and main a9779ef3c193; not fixed. [exec] the follow-up's cross-version main() repro (4.x and 5.0+ API variants) reports the bug on 4.7.0, 4.10.4, 5.0.0, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 10.5.2 and main; the finder's JUnit fails 2 of 3 (its BMP control passes) on 9.12.3, 10.0.0 and 10.5.2 (-ea) and on main (-ea and -da); the independent reproduction's JUnit fails 3 of 4 on 9.12.3 and 10.5.2 (-ea) and on main (-ea and -da); the intended-behaviour check's probe keeps all 127 supplementary Cf code points and removes all 43 BMP Cf code points on 9.12.3 and 10.5.2 (-da) and on main (-ea and -da). [read] the code is unchanged since the introducing commit, so the releases between the sampled ones are affected by code reading; upstream main f7bcc0abd816 (2026-10-27) and branch_10x still have line 121 unchanged. All runs used JDK 25.0.3; the result does not depend on the JDK, because each half of a supplementary code point is a surrogate and never FORMAT.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal; also reached by code reading
- Upstream and prior reports
- none found (searched 2026-10-27, read-only; the prior-report record, verdict new, confidence high): a scripted prior-report search with 51 queries (16 GitHub issue/PR on apache/lucene, 3 commit, 2 downstream-repository, 20 mailing-list over dev@, java-user@, issues@ and commits@, 4 JIRA, 6 web; 0 errors), 31 manual apache/lucene searches (class names, Character.getType, Character.FORMAT, 'format characters', tag characters, E0001, supplementary and surrogate phrasings, the scanner-advisory and OSV ids), 7 downstream searches (Elasticsearch, OpenSearch, Solr, Lucene.NET, the OSS-Fuzz repositories), 6 JIRA queries, 16 list queries, the OSV OSS-Fuzz feed for Lucene, a file scan of every open PR labelled module:analysis, the introducing issue gh#6442 (LUCENE-5379; body and all 3 comments) and the full git history of ckb/; the finder's run (45 queries) and the intended-behaviour check's run (75 hits, 0 high, 0 medium) agree. No issue, PR, JIRA ticket, list thread, downstream issue, fuzzer report or web page reports that SoraniNormalizer keeps format characters outside the BMP. Related, not the same bug: OSV-2025-253 (OSS-Fuzz 407477665, QueryParserFuzzer: an exception inside SoraniNormalizer.normalize reached from WordDelimiterGraphFilter; published 2025-04-03, withdrawn 2026-10-01; exception class and input not public) and the java-user@ thread on scanner advisory sonatype-2025-002284 derived from it (2025-09-01; maintainers dweiss and uschindler found it unactionable): both report an exception, while this bug throws nothing and returns a well-formed term; gh#2763 (LUCENE-1689) and gh#3259 (LUCENE-2183), umbrella issues on supplementary characters in char-based analysis code, resolved before the ckb package existed. Not fixed upstream: main f7bcc0abd816 (2026-10-27) and branch_10x have line 121 unchanged, and no open PR fixes it.
- Lucene commit tested
- main
a9779ef3c193(gradle in a scratch worktree, assertions on and off, and the standalone JUnit runner); the release jars 10.5.2 and 9.12.3 (this doc's test); 4.6.1 to 10.0.0 sampled by the follow-up's cross-version harness; the fix on main (gradle: the Sorani test package and the whole:lucene:analysis:common:testtask, plus the module's lint and format checks). JDK 25.0.3 on Linux aarch64 only.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/ckb/SoraniNormalizer.java:21-35 (at a9779ef3c193) (class javadoc; :33 'Harakat, tatweel, and formatting characters such as directional controls are removed.'), :36 (package-private class), :120-124 (default branch: 'if (Character.getType(s[i]) == Character.FORMAT) { len = delete(s, i, len); i--; }', one UTF-16 unit)lucene/analysis/common/src/java/org/apache/lucene/analysis/ckb/SoraniNormalizationFilter.java:24 (at a9779ef3c193) ('A {@link TokenFilter} that applies {@link SoraniNormalizer} to normalize the orthography.'); SoraniNormalizationFilterFactory.java:40 (SPI name 'soraniNormalization'); SoraniAnalyzer.java:78 (default constructor), :114-117 (StandardTokenizer, SoraniNormalizationFilter, LowerCaseFilter, DecimalDigitFilter), :126 (normalize applies the same filter)lucene/CHANGES.txt:8852 (at a9779ef3c193) ('LUCENE-6914: Fixed DecimalDigitFilter in case of supplementary code points.'; precedent for treating the char-wise test as a bug in the same analyzer chain)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/ckb/SoraniNormalizer.java:21-35 (class javadoc; :33 the removal sentence), :72-128 (normalize; default branch :120-124, getType(char) at :121)lucene/analysis/common/src/java/org/apache/lucene/analysis/ckb/SoraniNormalizationFilter.java:24; lucene/analysis/common/src/java/org/apache/lucene/analysis/ckb/SoraniAnalyzer.java:113-121 (createComponents), :124-130 (normalize)JDK 25 src.zip java.base/java/lang/Character.java (getType(char) javadoc: 'cannot handle supplementary characters', points to getType(int))
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/ckb/SoraniAnalyzer.java:113-130; lucene/analysis/common/src/java/org/apache/lucene/analysis/ckb/SoraniNormalizationFilterFactory.java:40, :60-63
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/ckb/SoraniNormalizer.java:33; lucene/analysis/common/src/java/org/apache/lucene/analysis/ckb/SoraniNormalizationFilter.java:24a Lucene clone: releases/lucene/9.12.3 SoraniNormalizer.java:36 ('public class'), releases/lucene/10.0.0 :36 ('class'); releases/lucene-solr/4.7.0 SoraniNormalizer.java:31, :119a Lucene clone: releases/lucene/9.12.3 gradle/documentation/render-javadoc.gradle:330 (-protected); releases/lucene-solr/4.7.0 lucene/common-build.xml:166 (javadoc.access=protected)build-tools/build-infra/src/main/java/org/apache/lucene/gradle/plugins/java/RenderJavadocPlugin.java:464 (-protected); lucene/MIGRATE.md:939 (LUCENE-10561)lucene/analysis/common/src/test/org/apache/lucene/analysis/ckb/TestSoraniNormalizationFilter.java:84-96 (testRemove); lucene/analysis/common/src/test/org/apache/lucene/analysis/ckb/TestSoraniStemFilter.java:106-123 (testVocabulary; ckbtestdata.zip testdata.txt has 11 words ending in U+202E)lucene/CHANGES.txt:8852 (LUCENE-6914); lucene/analysis/common/src/java/org/apache/lucene/analysis/ckb/SoraniAnalyzer.java:117 (DecimalDigitFilter)lucene/analysis/common/src/java/org/apache/lucene/analysis/tr/TurkishLowerCaseFilter.java:55-60, :95-96 (codePointAt + getType(int))
- Suggested fix
lucene/analysis/common/src/java/org/apache/lucene/analysis/util/StemmerUtil.java:102-108 (deleteN)
- History
a Lucene clone: git tag --contains a670b8d5b22 (first release tag releases/lucene-solr/4.7.0); releases/lucene-solr/4.7.0 SoraniNormalizer.java:119lucene/CHANGES.txt:12736; lucene/analysis/common/src/java/org/apache/lucene/analysis/ckb/SoraniAnalyzer.java:38 (@since 4.10.0); lucene/analysis/common/src/java/org/apache/lucene/analysis/ckb/SoraniNormalizationFilterFactory.java:34 (@since 4.7.0)
- Diagrams
lucene/analysis/common/src/java/org/apache/lucene/analysis/ckb/SoraniNormalizer.java:120-124
- TestSoraniNormalizationFilterSupplementaryFormatChar.java (JUnit test):
repro/LFV-752/src/org/apache/lucene/analysis/ckb/TestSoraniNormalizationFilterSupplementaryFormatChar.java(35 lines)
A step-by-step picture made in parallel with this doc from the executed repro on main a9779ef3c193; every value drawn should come from the repro output and the source at that commit. The PNG is the final summary frame.
assets/LFV-752/bug.png(514 KB)