highlightWithoutSearcher passes the caller's text straight to the field highlighter. The only cut to maxLength is in the stored-field loader (LimitedStoredFieldVisitor), which only the searcher entry points use, and the re-analysis code that follows assumes "content is already truncated to maxLength".
UnifiedHighlighterturns a document's text into a short snippet with the query's matches marked, such as<b>Lucene</b> is here..maxLength(default 10,000 chars;withMaxLength(n)changes it) bounds how much text it looks at: "Content will be truncated to this size before highlighting." A match after it is not shown; the first passage comes back instead.- There are two ways in. The searcher entry points (
highlight,highlightFields) load each hit's stored field.highlightWithoutSearcher, on a highlighter built withbuilderWithoutSearcher, takes the text as aStringand re-analyzes it; no index is needed.
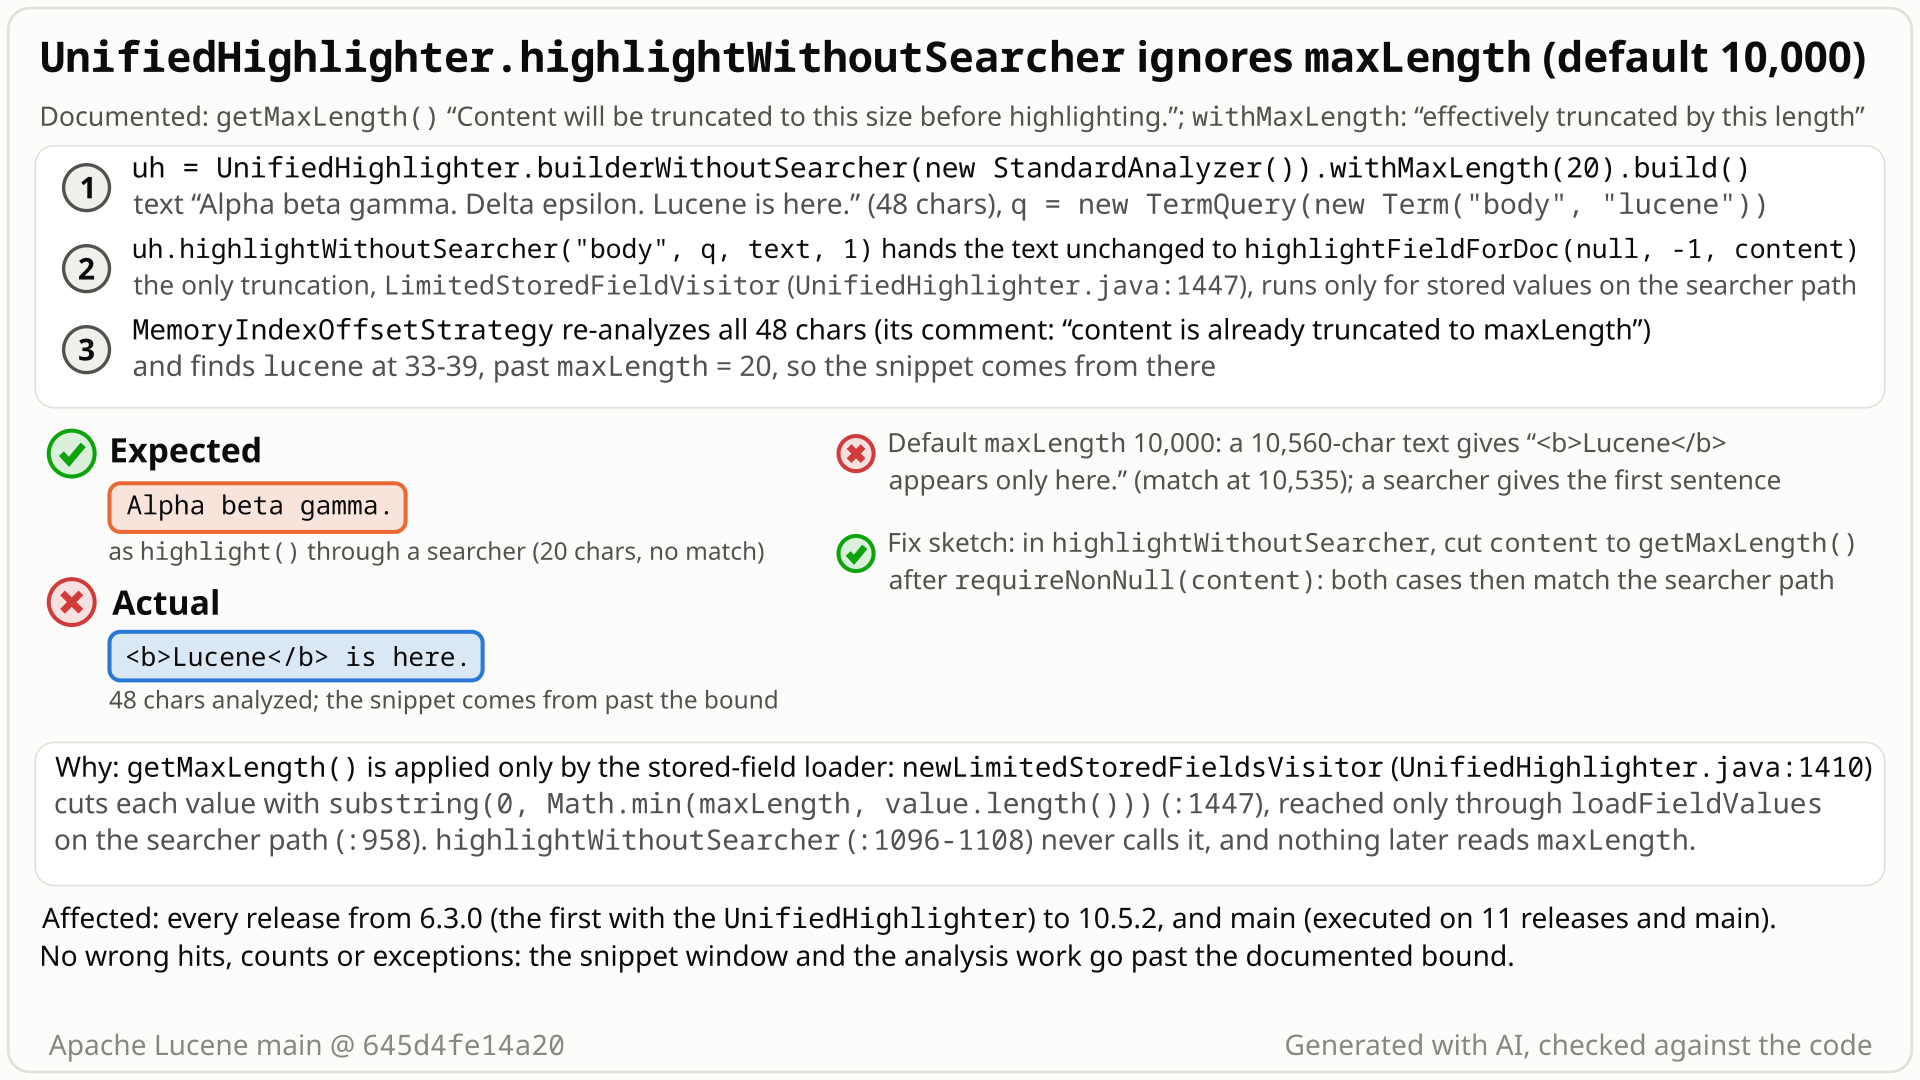
maxLength 20 on both paths: through a searcher the stored-field loader cuts it to 20 chars and the snippet is Alpha beta gamma. ; through highlightWithoutSearcher nothing cuts it, and the match at char 33 is highlighted. Select the still to open it at full size. Generated with AI, checked against the code.- You build a highlighter without an index,
UnifiedHighlighter.builderWithoutSearcher(analyzer).withMaxLength(20).build(), and callhighlightWithoutSearcher("body", query, text, 1)for the termluceneon the 48-char textAlpha beta gamma. Delta epsilon. Lucene is here.. Its only match starts at char 33. - You expect the text cut to its first 20 chars before highlighting, as
getMaxLength()documents: "Content will be truncated to this size before highlighting". The same text, query and option through an index and a searcher giveAlpha beta gamma., with no match. - Instead you get
<b>Lucene</b> is here.: all 48 chars were analyzed and the match past char 20 is highlighted, whilegetMaxLength()returns 20. - The default is skipped too: on a 10,527-char text whose only match is at char 10,512, the searcher path returns
Alpha beta gamma.andhighlightWithoutSearcherreturns<b>Lucene</b> is here.. - Why: the only cut is in the stored-field loader, which only the searcher entry points use.
highlightWithoutSearcherhands the caller'sStringstraight to the field highlighter, whose re-analysis code assumes "content is already truncated to maxLength".
Applications that call highlightWithoutSearcher with text longer than maxLength: any text over 10,000 chars by default. The snippet can come from past the bound, and the work grows with the whole text (58 ms for 1 million chars in one probe). Hits, counts and the searcher entry points are unaffected; the entry point itself is rarely used.
Mechanism, terms and numbers631 words
UnifiedHighlighter has a maxLength option, 10,000 chars by default, documented as "The maximum content size to process. Content will be truncated to this size before highlighting." With the default stored-field loader, the searcher entry points (highlight, highlightFields) cut the text while they load it. highlightWithoutSearcher, the entry point for a highlighter built with builderWithoutSearcher, takes the text from the caller and never cuts it: the whole text is analyzed, and a match or passage after maxLength can be returned. With withMaxLength(20), the 48-char text Alpha beta gamma. Delta epsilon. Lucene is here. gives <b>Lucene</b> is here. where the searcher path gives Alpha beta gamma. ; with the default, a match at char 10,512 of a 10,527-char text is highlighted. The work grows with the whole text (58 ms at 1 million chars and 217 ms at 4 million in one probe, against about 1 ms when the caller cuts it). Hits, counts and scores are correct, and no recorded run threw an exception. Present since the class was added in 6.3.0 (2016); a 4-line cut, with a javadoc sentence, passes the whole highlighter test suite.
maxLength:DEFAULT_MAX_LENGTH = 10000(UnifiedHighlighter.java:100).getMaxLength(): "The maximum content size to process. Content will be truncated to this size before highlighting. Typically snippets closer to the beginning of the document better summarize its content." (:596-603).Builder.withMaxLength: "The text to be highlight is effectively truncated by this length." (:354).builderWithoutSearcherreturns that sameBuilder(:453-455).- Searcher entry points: the public
highlight(:747,:766) andhighlightFields(:796,:828,:854) overloads, which all reach the protectedhighlightFieldsAsObjects(:890). It loads each hit's text withloadFieldValues(:958,:1382-1404); a subclass may override that loader. highlightWithoutSearcher(field, query, content, maxPassages)(:1096-1108): "Highlights text passed as a parameter. ... This use-case is more rare. Naturally, the mode of operation will be OffsetSource#ANALYSIS" (:1079-1081), that is, the text is re-analyzed. Its javadoc says nothing aboutmaxLength.
- On the searcher path, the default
loadFieldValuesreads stored fields throughnew LimitedStoredFieldVisitor(fields, MULTIVAL_SEP_CHAR, getMaxLength())(:1409-1410), which keepsvalue.substring(0, Math.min(maxLength, value.length()))(:1446-1447) and caps later values of a multi-valued field by the remaining budget (:1450-1465). The cut text goes tofieldHighlighter.highlightFieldForDoc(leafReader, docId, content.toString())(:987-988). highlightWithoutSearcherchecks that the searcher is null and thatcontentis not null, then callshighlightFieldForDoc(null, -1, content)with the caller's fullString(:1104-1107).- Nothing downstream cuts:
FieldHighlighterand the offset strategies never readmaxLength; the onlygetMaxLength()use in the class is the visitor above. - With the default flags, the re-analysis is done by
MemoryIndexOffsetStrategy(chosen at:1294-1302), whosegetOffsetsEnumsays "note: don't need LimitTokenOffsetFilter since content is already truncated to maxLength" (MemoryIndexOffsetStrategy.java:104). With phrases not position sensitive and both passage relevancy and weight matches off,TokenStreamOffsetStrategyre-analyzes the full text the same way (the fact check's probe ran both strategies: the same snippet). - The break iterator, the scorer and the formatter then see the whole text, so the best passage can lie after
maxLength, and the analysis work grows with the whole length.
case (term query lucene, MockAnalyzer) | through a searcher | highlightWithoutSearcher |
|---|---|---|
withMaxLength(20), Alpha beta gamma. Delta epsilon. Lucene is here. (48 chars, match at 33) | Alpha beta gamma. | <b>Lucene</b> is here. |
default 10,000, "Alpha beta gamma. " x 584 + "Lucene is here." (10,527 chars, match at 10,512) | Alpha beta gamma. | <b>Lucene</b> is here. |
control: withMaxLength(1000), the 48-char text | <b>Lucene</b> is here. (fact-check probe) | <b>Lucene</b> is here. |
Main 645d4fe14a20, assertions on and off; the same on the 10.5.2 and 10.0.0 jars.
Exposure and likelihood284 words
- Who is hit. Every caller of
highlightWithoutSearcher(a highlighter built withbuilderWithoutSearcher, or the deprecated constructor with a null searcher) whose text is longer thanmaxLength. With the default that is any text over 10,000 chars, such as a full article; with a smallwithMaxLengthalmost any text. Every such call skips the cut; the snippet differs when the chosen passage depends on text pastmaxLength. - Default vs opt-in. The entry point is opt-in and rare: its javadoc says "This use-case is more rare", the class is
@lucene.experimental, and Lucene itself has no non-test caller. Once used, the default bound is skipped with no option set. - Effect on the snippet. A match or passage after
maxLengthcan be returned where the searcher path returns the first passage. The snippet is valid text from the caller's own string. - Effect on the work. One probe (StandardAnalyzer, one
TermQuery, defaultmaxLength; time is the median of 5 calls, allocation the bytes the thread allocated in the last of them) measured 21 ms and 63.5 MiB for 100,000 chars, 58 ms and 635 MiB for 1,000,000 chars, and 217 ms and 2,538 MiB for 4,000,000 chars; about 1 ms and 6.4 MiB when the caller cuts the text to 10,000 first. Only these sizes, one analyzer and one query were measured: a sanity check on one machine, not a benchmark; the allocation is not retained memory. - Not affected. Hits, counts and scores; the searcher entry points with the default loader. No recorded run threw an exception or crashed, with assertions on or off.
- Why nobody noticed. The output is a plausible snippet, and the upstream tests call
highlightWithoutSearcheronly on short text.
The test shows that UnifiedHighlighter.highlightWithoutSearcher ignores maxLength: with withMaxLength(20) it still highlights a match at offset 33 of a 48-char text.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.uhighlight;

import org.apache.lucene.analysis.standard.StandardAnalyzer;
import org.apache.lucene.index.Term;
import org.apache.lucene.search.TermQuery;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestHighlightWithoutSearcherMaxLength extends LuceneTestCase {

  public void testMaxLength() throws Exception {
    try (StandardAnalyzer analyzer = new StandardAnalyzer()) {
      UnifiedHighlighter highlighter =
          UnifiedHighlighter.builderWithoutSearcher(analyzer).withMaxLength(20).build();
      // the only match, "Lucene", starts at offset 33, past maxLength 20
      Object snippet =
          highlighter.highlightWithoutSearcher(
              "body",
              new TermQuery(new Term("body", "lucene")),
              "Alpha beta gamma. Delta epsilon. Lucene is here.",
              1);
      assertFalse(
          "expected no match past maxLength 20, got: " + snippet,
          snippet.toString().contains("<b>Lucene</b>"));
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-756/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/highlighter/build/libs/lucene-highlighter-$V.jar
CP=$CP:$LUCENE/lucene/memory/build/libs/lucene-memory-$V.jar
CP=$CP:$LUCENE/lucene/queries/build/libs/lucene-queries-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.uhighlight.TestHighlightWithoutSearcherMaxLength
- Expected vs actual
- Expected: the text is cut to 20 chars before highlighting (getMaxLength javadoc), so there is no
<b>Lucene</b>; actual:<b>Lucene</b> is here., with-eaand-da.
More files, environment, full output40 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected no match past maxLength 20, got: <b>Lucene</b> is here.
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.assertTrue(Assert.java:42)
       org.junit.Assert.assertFalse(Assert.java:65)
org.apache.lucene.search.uhighlight.TestHighlightWithoutSearcherMaxLength.testMaxLength(TestHighlightWithoutSearcherMaxLength.java:37)- The option's javadoc has no exception: "Content will be truncated to this size before highlighting" (
getMaxLength);withMaxLengthsays the same on the Builder thatbuilderWithoutSearcherreturns. - The re-analysis code on this path relies on it ("content is already truncated to maxLength"), written in the same 2016 commit as the method.
- No test, javadoc or discussion exempts this path.
The full argument197 words
- The contract is unconditional.
getMaxLength(UnifiedHighlighter.java:596-603, wording from the original 2016 commit) andBuilder.withMaxLength(:354, added in #412 / LUCENE-10197, 2021) describe the text that is highlighted, with no exception for any entry point. ThehighlightWithoutSearcherjavadoc (:1078-1093) is silent onmaxLength. - The code relies on it on this exact path.
MemoryIndexOffsetStrategy.java:104("content is already truncated to maxLength") came in withhighlightWithoutSearcherin722e8271243(then inAnalysisOffsetStrategy; moved by LUCENE-7526). - The 2021 builder review used this combination. In #412 the
withMaxLengthwording was suggested in review by @dsmiley, and the PR author's example in the same review wasbuilderWithoutSearcher(indexAnalyzer).withMaxLength(100), with no remark that it has no effect. - Tests pin
maxLengthas visible on the searcher path.TestUnifiedHighlighterMTQ.testWithMaxLen(withMaxLength(25): "ask for 2 but we'll only get 1") andTestUnifiedHighlighter.testFormatWithMatchExceedingContentLength(withMaxLength(17)) assert snippets cut by it. The onlyhighlightWithoutSearchertests (TestUnifiedHighlighterReanalysis,TestLengthGoalBreakIterator,TestUnifiedHighlighterStrictPhrases.testMatchNoDocsQuery) use short text and the default. - Precedent.
maxLengthedge cases of the predecessor PostingsHighlighter were fixed as bugs: LUCENE-5166 (a term spanning the boundary) and LUCENE-5032 (multi-valued fields exceeding it). No CHANGES, MIGRATE or package entry exempts this path.
The devil's-advocate check220 words
The strongest case for "works as designed" (the intended-behaviour checker, and this hunt's own earlier triage, which had left it as a documentation gap): maxLength is a stored-value loading bound. It is enforced only in LimitedStoredFieldVisitor, whose javadoc says it "honors a max length to retrieve"; a subclass that overrides loadFieldValues also gets uncut text (executed: with a searcher and withMaxLength(20), an override returning the full text gives <b>Lucene</b> is here.); highlightWithoutSearcher loads nothing, its caller owns the String, its javadoc is silent, the class is experimental, and the behaviour has not changed in ten years, so a code change alters what existing callers get.
Why we still read it as a bug: the option's own javadoc describes the highlighted text, not loading; the module's code on this exact path assumes the cut (this shows that the documentation and the implementation disagree, not that the authors considered caller-supplied text and chose to cut it); the default 10,000 is skipped with stock settings, while the override case needs a user to replace the loader on purpose; and we found no doc, test or discussion that records the loading-only reading. Our reading: not intended. The reviewers rated the intended-behaviour case weak to moderate, so a maintainer may fairly prefer to document the gap; the fix section offers both.
Recommended Truncate in highlightWithoutSearcher (recommended, validated)
Cut content to getMaxLength() at the start of highlightWithoutSearcher, as the stored-field loader does, and say so in its javadoc (+6/-1). With it the repro passes and so does the whole highlighter test task (725 tests, assertions on and off). Callers who pass longer text today then get only its first maxLength chars highlighted, worth a CHANGES note.
Objects.requireNonNull(content, "content is required");
if (content.length() > getMaxLength()) {
  // like LimitedStoredFieldVisitor on the searcher path; the offset strategies rely on it
  content = content.substring(0, getMaxLength());
}
Set<Term> queryTerms = extractTerms(query);
All options and trade-offs3 options · 630 words
Two code fixes were applied in a scratch worktree of 645d4fe14a20 and tested with gradle; the documentation-only option was not run.
Four lines and one javadoc sentence in UnifiedHighlighter.java (the full patch):
--- a/lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java
+++ b/lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java
@@ -1078,7 +1078,8 @@ public class UnifiedHighlighter {
   /**
    * Highlights text passed as a parameter. This requires the {@link IndexSearcher} provided to this
    * highlighter is null. This use-case is more rare. Naturally, the mode of operation will be
-   * {@link OffsetSource#ANALYSIS}. The result of this method is whatever the {@link
+   * {@link OffsetSource#ANALYSIS}. As with stored values, {@code content} is truncated to {@link
+   * #getMaxLength()} before highlighting. The result of this method is whatever the {@link
    * PassageFormatter} returns. For the {@link DefaultPassageFormatter} and assuming {@code content}
    * has non-zero length, the result will be a non-null string -- so it's safe to call {@link
    * Object#toString()} on it in that case.
@@ -1102,6 +1103,10 @@ public class UnifiedHighlighter {
               + " without an IndexSearcher.");
     }
     Objects.requireNonNull(content, "content is required");
+    if (content.length() > getMaxLength()) {
+      // like LimitedStoredFieldVisitor on the searcher path; the offset strategies rely on it
+      content = content.substring(0, getMaxLength());
+    }
     Set<Term> queryTerms = extractTerms(query);
     return getFieldHighlighter(field, query, queryTerms, maxPassages)
         .highlightFieldForDoc(null, -1, content);
Objects.requireNonNull(content, "content is required");
if (content.length() > getMaxLength()) {
// like LimitedStoredFieldVisitor on the searcher path; the offset strategies rely on it
content = content.substring(0, getMaxLength());
}
Set<Term> queryTerms = extractTerms(query);Trade-offs
- Behaviour change for callers who pass more than
maxLengthchars today (10,000 by default) and rely on highlights beyond it; they would needwithMaxLength(...). - The cut is in UTF-16 units, like the searcher path's, so it can split a supplementary character; that is the separate bug LFV-775 (the same cut on the searcher path). One surrogate-safe helper can serve both sites.
getMaxLength()is overridable and is read twice; a local variable would read it once.- Not tested at the edges:
withMaxLength(0)(allowed), amaxLengthnearInteger.MAX_VALUE, an overriddengetMaxLength(), or a supplementary character at the cut.
What the checks validated
- The paste-ready test: 3 of 3 pass with gradle, assertions on and off, and 30 of 30 with 10 random seeds per method; also through the JUnit runner with the patched class.
- The whole
:lucene:highlighter:testtask with the test added: 35 classes, 725 tests, 0 failures, assertions on and off (seed DEADBEEF), includingTestUnifiedHighlighterReanalysis,TestLengthGoalBreakIteratorandTestUnifiedHighlighterStrictPhrases. :lucene:highlighter:check -x test(google-java-format, ecj lint, forbidden APIs) passes.- The hunt's version of the same cut (no javadoc) made the finder's, the reproducer's, the devil's advocate's and the history probe's tests pass.
A private truncateToMaxLength(String) applied in highlightWithoutSearcher and at the searcher path's highlightFieldForDoc call (UnifiedHighlighter.java:987-988), +8/-2. It also bounds text that a loadFieldValues override returns.
Trade-offs
A second behaviour change, for subclasses that override loadFieldValues (whose javadoc says "a subclass can change the source" and says nothing about maxLength); arguably a separate question. The upstream override test testCustomFieldValueSource uses short text and passes. Better as a follow-up to the recommended fix.
What the checks validated
- The whole highlighter test task with the paste-ready test: 35 classes, 725 tests, 0 failures (assertions on); format and ecj lint pass.
- The loader-override observation changes as intended: an override returning the full 48-char text with
withMaxLength(20)gives<b>Lucene</b> is here.on main andAlpha beta gamma.with this fix.
Say in the highlightWithoutSearcher, getMaxLength and withMaxLength javadocs that this entry point does not apply maxLength and the caller must cut content, and correct the comment in MemoryIndexOffsetStrategy.
Trade-offs
No behaviour change, but the default bound stays a no-op on this path, and getMaxLength() keeps reporting a value that has no effect there.
A service that relies on maxLength to bound highlighting of long untrusted text it passes to highlightWithoutSearcher gets no bound; cutting the text before the call restores it.
Code reading (non-formal). A hunt unit checked each documented UnifiedHighlighter option on each of its entry points and saw that maxLength is applied only by the stored-field loader, which highlightWithoutSearcher never calls. A JUnit comparing the same text through a searcher and without one confirmed it.
The method in full104 words
- Unit. An inventory of override hooks and accessors that can bypass documented behaviour. One leg crossed each documented option with the entry points (the public
highlightandhighlightFieldsoverloads, the protectedhighlightFieldsAsObjectsthey reach, andhighlightWithoutSearcher). - Signal. Code reading: the only
getMaxLength()use isnewLimitedStoredFieldsVisitor, reached only fromloadFieldValues, andhighlightWithoutSearchernever calls it. - Witness. A differential public-API JUnit (the same text, query and
maxLengththrough a searcher and without one) failed 1 of 1 on main with assertions on and off, and on 10.5.2 and 9.12.3; with the hunt's cut shadowed it passed (2026-10-27). - Independent checks followed (see "Independent checks").
No prior report found: 142 non-web tool queries, 45 by the finder and 47 manual searches over GitHub, JIRA, the mailing lists and the web, plus the changed files of all 408 open PRs (2026-10-27), re-checked on GitHub on 2026-10-29. Closest: #412 (LUCENE-10197), which wrote the withMaxLength javadoc.
Searches4 searches
No report of this defect was found. The nearest items introduced the method, the comment or the withMaxLength javadoc, or call highlightWithoutSearcher on short text for other bugs. Not fixed upstream: the method body is unchanged on main 645d4fe14a20, branch_10_6 and branch_10x (read 2026-10-29). Open tracking issue #16918 lists the deprecated constructor and setters, including setMaxLength, for removal in 11.0, so a fix may need a textual rebase. Gaps: keyword search only, GitHub's search rate limit (one re-check query hit the rate limit), one web query throttled, private channels not searchable, no downstream code search.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene, apache/lucene-solr), JIRA archive, mailing lists (dev@, java-user@, issues@, commits@), downstream repositories | 2026-10-27 | two runs of a scripted prior-report search, 142 non-web queries (60 GitHub issue/PR, 6 commit, 4 downstream, 64 mailing-list, 8 JIRA), plus the finder's run (45 queries) | no report |
| GitHub, lists.apache.org, JIRA, web (manual) | 2026-10-27 | 47 searches and reads: 27 GraphQL searches over apache/lucene, apache/lucene-solr, apache/solr, two downstream search engines and all of GitHub; 7 list searches; 4 JIRA REST queries; 6 web searches; upstream file history on 4 branches | related items only: #412 / #11234 (LUCENE-10197, the Builder and the withMaxLength javadoc), #8490 (LUCENE-7438, the method), #8577 (LUCENE-7526, the comment's move); #8768, #8820, #9538, #10135 use the method on short text for other bugs |
| Open PRs | 2026-10-27 | the changed-file lists of all 408 open apache/lucene PRs; the diffs of the 3 that touch UnifiedHighlighter.java | #12295, #13165, #16847 touch the file but not this method |
| GitHub issues and PRs (apache/lucene), re-check | 2026-10-29 | highlightWithoutSearcher, UnifiedHighlighter maxLength, withMaxLength | only the four older bugs above, nothing, and #412; a fourth query hit the rate limit. No log was saved; the fact check's same-day re-run gave the same results for the first two queries and hit the rate limit on the third |
Present since the class was added: 722e8271243 (LUCENE-7438, 2016-10-04), first released in 6.3.0. The method has never cut its input; the 2021 Builder (LUCENE-10197) added the withMaxLength javadoc without changing it. Executed on 11 releases from 6.3.0 to 10.5.2 and on main: all affected. Never fixed.
Versions tested7 rows
Introduced by 722e8271243 "LUCENE-7438: New UnifiedHighlighter" (2016-10-04, now GitHub issue #8490; proposed as apache/lucene-solr #79, closed without a GitHub merge and committed directly; branch_6x backport 4b6794368df). That commit added highlightWithoutSearcher passing content uncut, the getMaxLength javadoc, and the "content is already truncated to maxLength" comment, so this is not a regression. Later edits to the method (2e948fea300, LUCENE-7575; 6faa4f98e04, LUCENE-9570, a reformat) did not touch truncation. LUCENE-10197 (#412, b1b1a890d08 / a9f812c1cf9, 9.1.0) added the Builder, builderWithoutSearcher and the withMaxLength javadoc.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | this doc's test fails 2 of 3 (gradle and runner, assertions on and off); 20 of 30 with 10 random seeds |
| 10.5.2, 10.0.0 | affected | the same (this doc's test, runner) |
| 9.1.0, 9.12.3 | affected | the hunt's Builder-API JUnit (9.x variant) fails 1 of 1; this doc's test with only the 9.x accessor change fails 2 of 3 (fact check) |
| 6.3.0 to 9.0.0 | probe | a probe with the original setters fails on 6.3.0, 6.4.0, 6.6.6, 7.0.0, 7.7.3, 8.11.4 and 9.0.0: 48 chars and 1 match seen with maxLength 20; the searcher control sees 20 chars and 0 matches |
| 6.2.1 | no code | no uhighlight package |
branch_10_6, branch_10x | read | same method body (read, not executed) |
| main + the fix | not affected | the test 3 of 3 pass; the highlighter test task 725 tests, 0 failures |
The finder, an independent reproducer, an intended-behaviour devil's advocate, the adjudication and a credibility audit each ran a public-API test and said real. Reading-only reviews by another model family (OpenAI GPT-5.6) said real (medium) and not real (low: it had no run of its own). This doc re-ran it through gradle and validated two fixes.
Checks and verdicts436 words
The cross-model reviews could not run code; separate runs re-ran the finder's test, which failed on main in both; the intended lens's check also ran it with the fix, and it passed. Every other hunt check executed code on main a9779ef3c193; this doc's runs and its fact check used 645d4fe14a20.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Differential JUnit fails 1 of 1 on main (assertions on and off), 10.5.2 and 9.12.3; passes with the hunt's cut. |
| cross-model review, refute lens (OpenAI GPT-5.6) | not real on procedure only (low) | Could not run Java, and it may not vote real without a run of its own. It agreed with the root cause; its one contrary evidence item was that the class is @lucene.experimental, and it rated the loading-bound reading weak. A separate re-run failed 1 of 1. |
| independent reproducer | real | Own JUnit with a recording formatter: the formatter sees 48 chars (explicit 20) and 10,560 chars (default), with a match ending at 10,541; searcher controls pass; also 10.5.2, 9.12.3, 8.11.4 and 6.3.0; the fix passes 4 of 4. |
| cross-model review, intended lens (OpenAI GPT-5.6, reading only) | real (medium) | Works-as-designed argument weak; root cause agreed; inputs in contract. Separate runs fail on main and pass with the fix. |
| intended-behaviour devil's advocate | real (medium-high) | Built the loading-bound case and rejected it; the default-maxLength JUnit fails on main and 10.5.2; recorded that a loadFieldValues override also gets uncut text. |
| adjudication | confirmed (high) | Re-ran the independent reproduction's JUnit with a new seed on a clean checkout: 2 of 4 fail with assertions on and off, 4 of 4 pass with the fix. Impact must stay minor. |
| credibility audit | keep | Re-ran the finder's and the independent reproduction's tests with new seeds; code re-read; impact minor unchanged; a committer would take a code or a javadoc fix and push back on denial-of-service framing. |
| this doc | reproduced; fixes validated | Its own 3-test JUnit fails 2 of 3 on main 645d4fe14a20 (gradle, assertions on and off), 10.5.2 and 10.0.0; both code fixes pass the whole highlighter test task. |
| fact checks of this doc | bug holds; wording fixed | One check re-ran the test through gradle and the runner (main, 10.5.2, 10.0.0; 9.1.0 and 9.12.3 with the 9.x accessor change), both fixes over the whole highlighter test task, and a probe of the searcher-path control and of TokenStreamOffsetStrategy. A reading-only check by another model family (OpenAI GPT-5.6) re-read the code and logs. Both found the bug, mechanism and fixes correct, and found count and wording errors, now fixed. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 523 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,410 words
- Registry title
- UnifiedHighlighter.highlightWithoutSearcher ignores maxLength (the default 10,000 included): it analyzes and highlights the whole supplied text, although getMaxLength and Builder.withMaxLength document that content is truncated to maxLength before highlighting
- Area
- highlighter / UnifiedHighlighter (highlightWithoutSearcher entry point, maxLength option)
- Priority
- Low, rank 556: HighlightWithoutSearcher ignores the documented maxLength on a rarely used entry point and only produces a plausible snippet from past the bound plus extra work, so this display-only bug closes the UnifiedHighlighter output rows after LFV-599.
- Impact class
- minor
- Impact note
- Hits every application that calls the rarely used, @lucene.experimental UnifiedHighlighter.highlightWithoutSearcher (no searcher, re-analysis offsets) with text longer than maxLength, the default of 10,000 chars included: the whole text is analyzed, a match or passage after maxLength can be returned, and the work grows linearly with the full text length (one probe: about 55 ms and 635 MB of transient allocation per million chars, against about 1 ms when the caller truncates), but there are no wrong hits or counts, no crash and no exception, with -ea and -da alike; the searcher entry points truncate correctly [exec: main, 10.5.2, 10.0.0, 9.12.3, 9.1.0, 9.0.0, 8.11.4, 7.7.3, 7.0.0, 6.6.6, 6.4.0, 6.3.0].
- Summary
- You build a UnifiedHighlighter without a searcher (builderWithoutSearcher, optionally withMaxLength(20)) and call highlightWithoutSearcher on a text longer than maxLength, expecting the text to be cut to its first maxLength chars before highlighting, as getMaxLength ('Content will be truncated to this size before highlighting') and withMaxLength document and as the searcher entry points do. Instead the whole text is analyzed and highlighted: with maxLength 20, the 48-char text 'Alpha beta gamma. Delta epsilon. Lucene is here.' gives '<b>Lucene</b> is here.' (its only match is at offset 33) where the searcher path returns 'Alpha beta gamma. ', and with the default maxLength of 10,000 a match at char 10,541 of a 10,560-char text is highlighted. The only truncation lives in the stored-field loader (LimitedStoredFieldVisitor), which this entry point never calls, although the re-analysis strategy it uses relies on it ('content is already truncated to maxLength').
- Introduced
- 722e82712435ecf46c9868137d885484152f749b (LUCENE-7438 'New UnifiedHighlighter', GitHub issue #8490; proposed as apache/lucene-solr#79, which was closed without a GitHub merge, and committed directly; branch_6x backport 4b6794368df) [read: git log -S and git log -L of the method, git blame on main; exec: 6.2.1 has no uhighlight package, 6.3.0 is affected]: the method passes content untruncated since it was created, so this is not a regression. The same commit added the getMaxLength javadoc and the 'content is already truncated to maxLength' comment; LUCENE-10197 (#412, b1b1a890d08 / a9f812c1cf9, 9.1.0) later added the withMaxLength javadoc on the Builder that builderWithoutSearcher returns. Later edits to the method (2e948fea300 LUCENE-7575 SortedSet to Set, 6faa4f98e04 LUCENE-9570 formatting) did not touch truncation (2016-10-04)
- First affected version
- 6.3.0 [exec: the first release with UnifiedHighlighter; 6.2.1, the release before, has no org.apache.lucene.search.uhighlight package and the probe does not compile]; on the main line 7.0.0
- Affected versions
- Every release from 6.3.0 to 10.5.2, 10.6.0 (by reading), and main a9779ef3c193; never fixed (the method body is unchanged at upstream main f7bcc0abd816, branch_10x and branch_10_6; no open PR touches it; read 2026-10-27). [exec] a cross-version probe (original non-Builder API, recording PassageFormatter, searcher-path and large-maxLength controls) fails on 6.3.0 (-ea and -da), 6.4.0, 6.6.6, 7.0.0, 7.7.3, 8.11.4, 9.0.0, 9.1.0, 9.12.3, 10.0.0, 10.5.2 and main (-ea and -da); the finder's Builder-API JUnit fails on 9.1.0, 9.12.3, 10.0.0, 10.5.2 and main (-ea and -da); the independent reproduction's JUnit fails on 10.5.2 (-ea and -da), 9.12.3 and main, and its old-API main() on 8.11.4 and 6.3.0. Releases in between are affected by code identity [read]; 10.6.0 (released 2026-10-29) and the unreleased 10.7 branch were read, not executed.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (2026-10-27, read-only; the prior-report record, verdict new): two scripted prior-report searches with 142 non-web queries (60 GitHub issue/PR, 6 commit, 4 downstream-repository, 64 mailing-list queries over dev@, java-user@, issues@ and commits@, 8 JIRA-archive) plus the finder's run (45 queries); 47 manual searches and reads (27 GitHub GraphQL searches over apache/lucene, apache/lucene-solr, apache/solr, Elasticsearch, OpenSearch and all of GitHub; the changed files of all 408 open apache/lucene PRs and the diffs of the 3 that touch UnifiedHighlighter.java; upstream file history on 4 branches; 7 lists.apache.org searches; 4 JIRA REST queries; 6 web searches); every hit read in full, none the same bug. Closest items, context not reports: #412 / #11234 (LUCENE-10197, merged 2021) added builderWithoutSearcher and the withMaxLength javadoc ('effectively truncated by this length', suggested by dsmiley), and a review comment by apanimesh061 shows builderWithoutSearcher(...).withMaxLength(100) as an example, with no remark that the no-searcher path ignores it; #8490 (LUCENE-7438) introduced the method and the truncation comment; #8577 (LUCENE-7526) created MemoryIndexOffsetStrategy; #8768, #8820, #9538, #10135 use highlightWithoutSearcher on short text for other bugs. Not fixed upstream: UnifiedHighlighter.java last changed on main by 54283150a816 (#16255, 2026-06-14) and on branch_10x and branch_10_6 by c8b00d2ba72d (#15681), elsewhere; three open PRs touch the file elsewhere (#12295, #13165, #16847); #16918 (opened 2026-10-27) plans to remove the deprecated constructor and setters including setMaxLength, so a fix may need a textual rebase. Gaps: keyword-based search, GitHub's search rate limit, one web query throttled, private channels and security@ not searchable, no downstream code search
- Lucene commit tested
- main
645d4fe14a20(gradle in a scratch worktree with assertions on and off and 10 random seeds per test method, plus the standalone JUnit runner); the 10.5.2 and 10.0.0 release jars (this doc's test, runner); the hunt's runs on maina9779ef3c193, whose highlighter and memory sources equal645d4fe14a20, and on 6.3.0 to 10.5.2 (a public-API probe on 11 releases); the fact check's runs: this doc's test with only the 9.x accessor change on 9.1.0 and 9.12.3, and a probe of the searcher-path control and of theTokenStreamOffsetStrategyflags on645d4fe14a20; both fixes on main (gradle, the whole highlighter test task; the recommended one also with assertions off and with the module's check task without tests).
- Finding record
lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:94 (at a9779ef3c193) (@lucene.experimental), :100 (DEFAULT_MAX_LENGTH = 10000), :354 (Builder.withMaxLength javadoc: 'The text to be highlight is effectively truncated by this length.'), :596-603 (getMaxLength javadoc: 'The maximum content size to process. Content will be truncated to this size before highlighting.'), :1078-1093 (highlightWithoutSearcher javadoc: 'This use-case is more rare', mode ANALYSIS, silent on maxLength), :1096-1108 (highlightWithoutSearcher passes content to highlightFieldForDoc(null, -1, content) untruncated)lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:1410 (at a9779ef3c193) (newLimitedStoredFieldsVisitor: new LimitedStoredFieldVisitor(fields, MULTIVAL_SEP_CHAR, getMaxLength())), :1426-1447 (LimitedStoredFieldVisitor: value.substring(0, Math.min(maxLength, value.length())), the only truncation, reached only from loadFieldValues on the searcher path)lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/MemoryIndexOffsetStrategy.java:101-104 (at a9779ef3c193) (getOffsetsEnum: 'note: don't need LimitTokenOffsetFilter since content is already truncated to maxLength')SECURITY.md:38 (Untrusted query and analysis input: limits on untrusted input are the downstream application's job), :42 (configuration values are trusted), :50 (In-scope reports, not met)
- The finding in 30 seconds
lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:100 (at 645d4fe14a20) (DEFAULT_MAX_LENGTH), :354 (withMaxLength javadoc), :453-455 (builderWithoutSearcher), :596-603 (getMaxLength javadoc), :1078-1108 (highlightWithoutSearcher javadoc and body)lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:958, (at 645d4fe14a20) :987-988 (searcher path: loadFieldValues, highlightFieldForDoc), :1382-1404 (loadFieldValues), :1409-1410 (newLimitedStoredFieldsVisitor), :1446-1447, :1450-1465 (LimitedStoredFieldVisitor.stringField), :1294-1302 (getOffsetStrategy for ANALYSIS)lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/MemoryIndexOffsetStrategy.java:101-104 (at 645d4fe14a20) ('content is already truncated to maxLength'); lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/FieldHighlighter.java:73 (at 645d4fe14a20) (highlightFieldForDoc)
- Who is affected
lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:94 (at 645d4fe14a20) (@lucene.experimental), :1080 ('This use-case is more rare')lucene/highlighter/src/test/org/apache/lucene/search/uhighlight/TestUnifiedHighlighterReanalysis.java:34-54 (at 645d4fe14a20) (short text only)
- Why it looks unintended
lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:354, (at 645d4fe14a20) :596-603, :1078-1093, :1413-1418 (LimitedStoredFieldVisitor javadoc)lucene/highlighter/src/test/org/apache/lucene/search/uhighlight/TestUnifiedHighlighterMTQ.java:778-809 (at 645d4fe14a20) (testWithMaxLen); lucene/highlighter/src/test/org/apache/lucene/search/uhighlight/TestUnifiedHighlighter.java:214, :225-255 (testFormatWithMatchExceedingContentLength and its helper); lucene/highlighter/src/test/org/apache/lucene/search/uhighlight/TestUnifiedHighlighterReanalysis.java, TestLengthGoalBreakIterator.java:218-248, TestUnifiedHighlighterStrictPhrases.java:540-544lucene/CHANGES.txt:13345-13347 (at 645d4fe14a20) (LUCENE-5166), :13661-13663 (LUCENE-5032)
- Suggested fix
lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:1372-1381 (at 645d4fe14a20) (loadFieldValues javadoc); lucene/highlighter/src/test/org/apache/lucene/search/uhighlight/TestUnifiedHighlighter.java:707-756 (at 645d4fe14a20) (testCustomFieldValueSource)
- Prior reports
a Lucene clone origin/branch_10_6 4ae946e5a9b, origin/branch_10x 657014b3c57 (method body read 2026-10-29)GitHub search re-check 2026-10-29 (gh search issues --include-prs; gh issue view 16918), read-only
- History
a Lucene clone origin/branch_10_6, origin/branch_10x (read 2026-10-29)
- TestHighlightWithoutSearcherMaxLength.java (JUnit test):
repro/LFV-756/src/org/apache/lucene/search/uhighlight/TestHighlightWithoutSearcherMaxLength.java(42 lines)
Made in parallel with this doc from the code at main 645d4fe14a20 and the executed runs; every value drawn should come from the paste-ready test's output and the source at that commit.
assets/LFV-756/bug.png(523 KB)