Index sorting (IndexWriterConfig#setIndexSort) orders each new segment by a field's doc values when the segment is written. Since 7.5.0 addDocument rejects a sort field with the wrong doc-values type up front. A sort field with no doc values at all slips past that check and fails later, at flush.
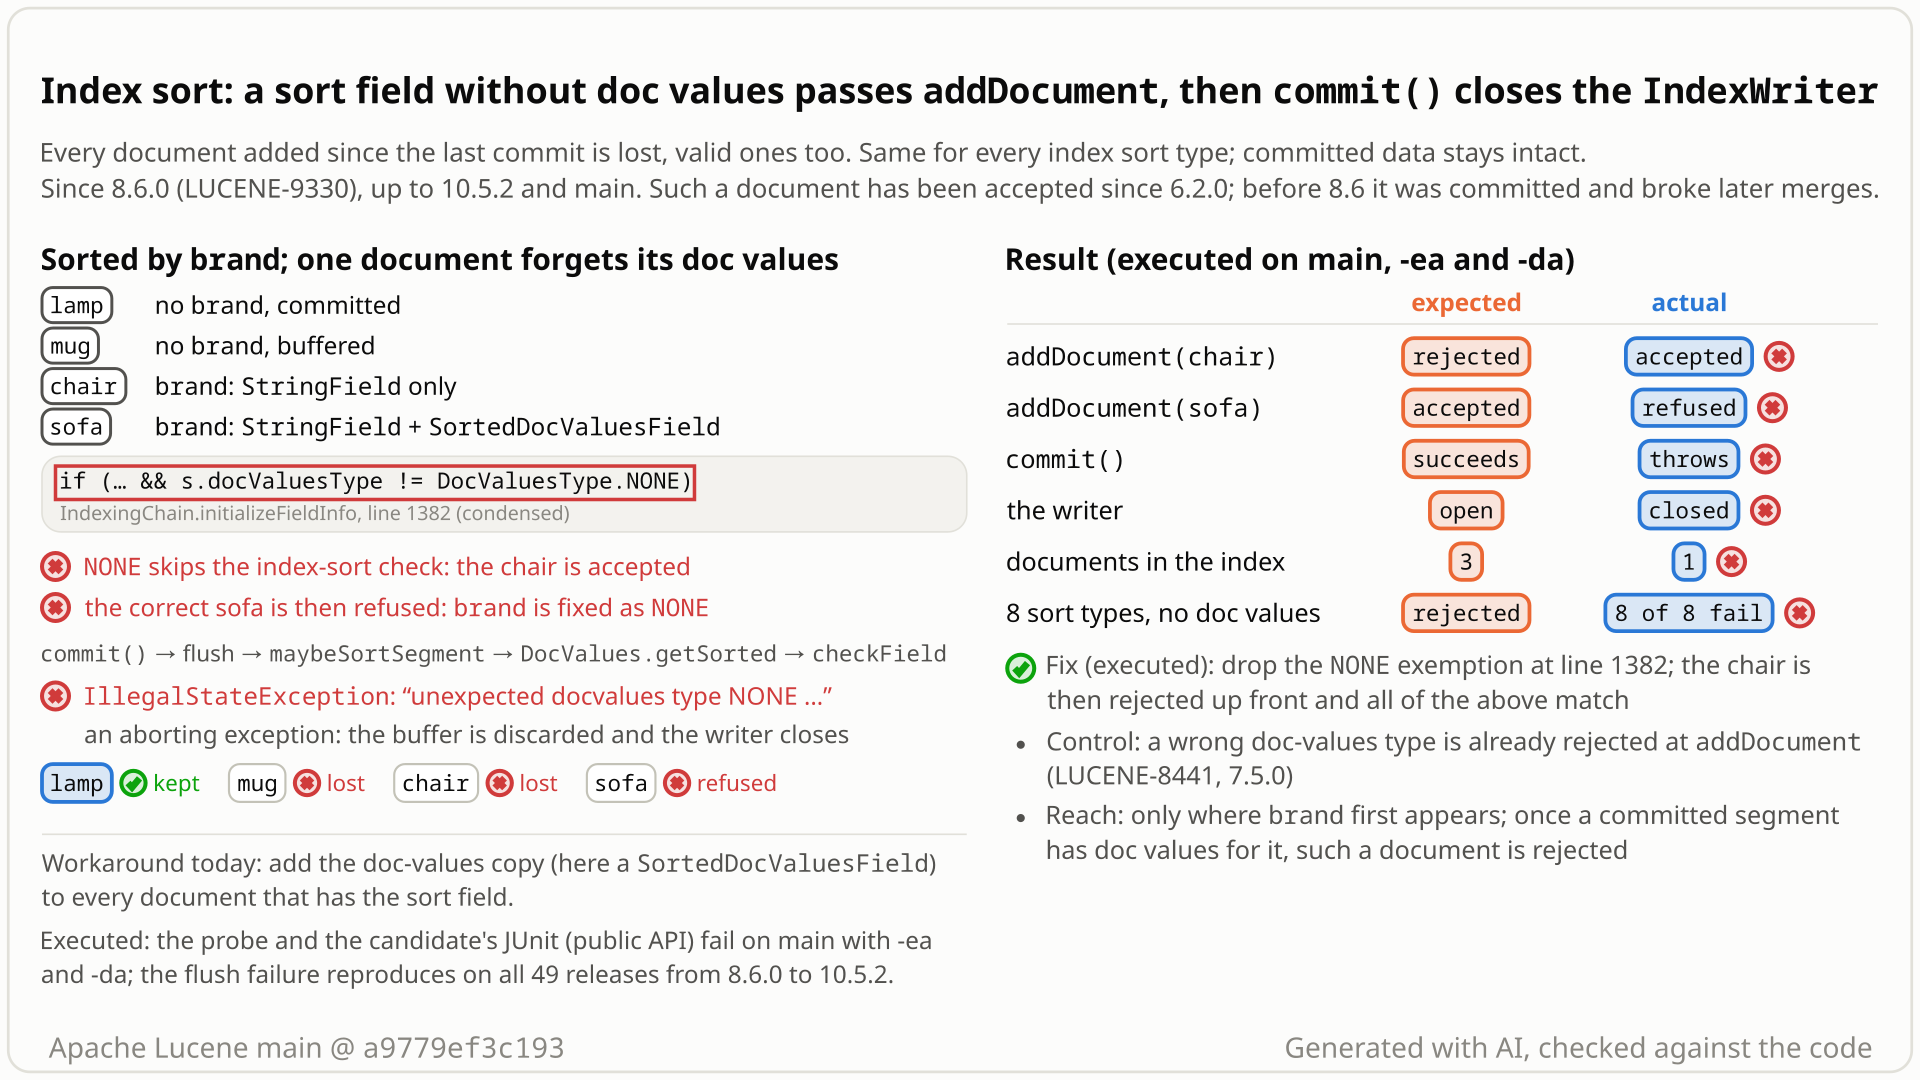
brand example: chair carries brand only as a StringField and passes addDocument, because the index-sort check skips doc-values type NONE; the commit's flush asks for brand's doc values, checkField throws, the writer closes and the buffered mug is lost. Expected against actual on main, and the executed fix. Select the still to open it at full size. Generated with AI, checked against the code.- Configure an index sort on
brand(SortField.Type.STRING). Addlamp, which has no brand, and commit; then addmug, also without a brand. 1 document is committed, 1 is buffered. - Add
chairwithbrandonly as aStringField, forgetting theSortedDocValuesFieldthat sorting reads. You expectaddDocumentto reject it, as it has rejected a sort field with the wrong doc-values type since 7.5.0. - Instead
chairis accepted, and a correctsofa(StringFieldplusSortedDocValuesField) is now rejected:chairfixed the field's schema as "no doc values". commit()throwsIllegalStateException: unexpected docvalues type NONE for field 'brand' (expected=SORTED)and closes the IndexWriter. The index still holds 1 document,lamp:mugis lost. A new writer starts clean.- Why:
addDocumentchecks a sort field's doc-values type only when the field has doc values. At flush the sorter reads it throughDocValues.getSorted, which throws for a field that exists without doc values, and an exception during flush closes the writer.
Applications that configure an index sort (opt-in) and give the sort field no doc values the first time it appears, for example only a StringField, a point or a stored field. Every built-in sort type and BinarySortField fail. It is a schema mistake, usually caught at the first flush, but it costs every uncommitted document; committed data stays intact.
Mechanism, terms and numbers801 words
Index sorting (IndexWriterConfig#setIndexSort) sorts each new segment by the sort field's doc values when the segment is flushed. Since LUCENE-8441 (7.5.0) addDocument rejects a sort field whose doc-values type does not fit the sort, and the writer stays usable. That check runs only when the field has doc values (IndexingChain#initializeFieldInfo, s.docValuesType != DocValuesType.NONE), so a document that indexes the sort field without doc values, for example only as a StringField, a point or a stored field, is accepted when it is the first document in the index with that field. From then on, correct documents for the field are rejected, because the field's schema says "no doc values". At the next flush the sorter reads the field through DocValues.getSorted / getNumeric / ..., which throws IllegalStateException: unexpected docvalues type NONE ... Re-index with correct docvalues type.; an exception during flush is aborting, so the IndexWriter closes with a tragic exception and every document added since the last commit is lost, valid ones included. Committed data stays intact and a new writer starts clean. Every built-in sort type and BinarySortField fail the same way, with assertions on or off. The flush failure dates from LUCENE-9330 (8.6.0); the missing check is older (6.2.0), with a different symptom before 8.6.0. Running the existing check for NONE too fixes it; the whole lucene/core test suite passes with that change.
- Index sort:
IndexWriterConfig#setIndexSort(Sort), "the Sort order to use for all (flushed and merged) segments" (IndexWriterConfig.java:504). The built-in sorters read the sort field's doc values, a per-document column: a STRING sort readsSortedDocValues, LONG/INT/FLOAT/DOUBLE readNumericDocValues(SortField.java:569-600). - A field without doc values: a
StringField, a point such asLongPoint, or aStoredFieldis indexed or stored but has doc-values typeNONE. A field used for both keyword search and sorting often needs twoFieldinstances; for a STRING sort, aStringFieldplus aSortedDocValuesField. - Flush: writing the buffered documents as a new segment (on
commit(), an NRT reopen, a full RAM buffer orclose()). An exception during flush is aborting: the IndexWriter closes itself with a tragic exception and rolls back to the last commit.
- When a field first appears in the in-memory segment,
IndexingChain#initializeFieldInfochecks it against the index sort withvalidateIndexSortDVType, but onlyif (indexWriterConfig.getIndexSort() != null && s.docValuesType != DocValuesType.NONE)(IndexingChain.java:1382-1385). The check would rejectNONE(IndexingChain.java:1675-1686); it is never asked. - At flush,
maybeSortSegmentbuilds each sorter's comparator on the flush-time doc-values reader (IndexingChain.java:283-294). That reader returns null for a field whose FieldInfo is not of the requested type (IndexingChain.java:209-218), and its field infos list the field with typeNONE(:244-247). - The sorter reads through
DocValues.getSorted(SortField.java:572-573; numeric sorts throughgetNumeric). It gets null and callscheckField, which throwsIllegalStateExceptionbecause the field exists (DocValues.java:213-230,:281-289). DocumentsWriterPerThread#flushtreats it as aborting and fires a tragic event (DocumentsWriterPerThread.java:585-602); the commit'sfinallyrolls the writer back (IndexWriter.java:3882-3883,:6098-6106).- Reach: since 9.0 a field has one schema per index. When the field already has doc values, a document without them does not close the writer. If a committed segment has them,
addDocumentrejects it (on 9.0-10.5.0 the commit then hits the separate #15125 NPE). If only the in-memory segment has them, it depends on the order of the earlier correct document's two instances: with theSortedDocValuesFieldfirst it is rejected; with theStringFieldfirst, the frozen-FieldType validation cache (#15886, 10.5.0;IndexingChain.java:621-637,:1876-1898) skips the check and the document is accepted as a missing value, on main and 10.5.2 (a separate finding, LFV-118). So this flush failure needs the document to be the first one in the index with the field (or the first afterIndexWriter.deleteAll()), and then later correct documents are rejected until the flush fails.
- The
brandexample (main, assertions on and off):lampcommitted,mugbuffered,chairwithbrandonly as aStringFieldaccepted;sofawithStringFieldplusSortedDocValuesFieldrejected ("Inconsistency of field data structures across documents for field [brand] ... doc values type: expected 'NONE', but it has 'SORTED'.");commit()throwsunexpected docvalues type NONE for field 'brand' (expected=SORTED);isOpen()false; a lateraddDocumentthrowsAlreadyClosedException; the index holds 1 document,lamp. A second writer then commitsmugandsofa: 3 documents. - The repro test: doc 0 committed, doc 1 buffered, doc 2 with
sortonly as aStringField(STRING sort) or aLongPoint(LONG sort): the commit throws, the writer closes, the index holds 1 document. - Executed for every built-in sort type (STRING, LONG, INT, FLOAT, DOUBLE,
SortedNumericSortField,SortedSetSortField) andBinarySortField.
Exposure and likelihood301 words
- Who is exposed. Applications with an index sort (the default
IndexWriterConfighas none) whose first document with the sort field indexes it without doc values: theSortedDocValuesField(orNumericDocValuesField, ...) next to theStringFieldor point is missing, or the field is only stored. Executed for STRING (StringField), LONG, INT, FLOAT and DOUBLE (points),SortedNumericSortField(StoredField),SortedSetSortField(StringField) andBinarySortField(StoredField). - What it costs. The writer closes with a tragic exception and every document since the last commit is lost, including documents accepted before the bad one; later calls throw
AlreadyClosedException. Committed segments are intact and a new writer starts clean. Until the flush, correct documents for the field are rejected too. - Default vs opt-in. Index sorting is opt-in. Codec, directory and assertions do not matter: the plain probe uses the default codec and
ByteBuffersDirectory, the JUnit tests the test framework's randomized codec and directory, and all fail with assertions on and off. - Scale. One document; deterministic at the first flush that contains it. In the repros that flush is a
commit(); an NRT reader open, a flush triggered insideaddDocumentorclose()runs the same code, so the failure would surface there instead (read, not executed). - How likely. Rare: a schema mistake that fails loudly with a clear message at the first flush, so it is usually caught in development, and no public report was found in the documented, best-effort search. The point is the disproportion: Lucene already rejects the neighbouring mistake, a wrong doc-values type, cleanly at
addDocument. - Before 8.6.0 (6.2.0 to 8.5.2, end of life) the document was also accepted, the segment was committed, and in the probes a later sorted search and
forceMerge(1)failed, the merge closing the writer in a later session too.
The test shows that with an index sort on sort, a document that has sort only as a StringField (no doc values) is accepted by addDocument, and the next commit throws and closes the IndexWriter (losing every uncommitted document).
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.StringField;
import org.apache.lucene.search.Sort;
import org.apache.lucene.search.SortField;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestIndexSortFieldWithoutDocValues extends LuceneTestCase {

  public void testSortFieldIndexedOnlyAsStringField() throws Exception {
    Sort sort = new Sort(new SortField("sort", SortField.Type.STRING));
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w = new IndexWriter(dir, new IndexWriterConfig().setIndexSort(sort))) {
      Document doc = new Document();
      doc.add(new StringField("sort", "x", Field.Store.NO));
      try {
        w.addDocument(doc);
      } catch (IllegalArgumentException rejectedUpFront) {
        return;
      }
      // expected: rejected by addDocument or committed; actual: commit throws and closes the writer
      try {
        w.commit();
      } catch (IllegalStateException e) {
        fail("accepted by addDocument, then commit threw " + e + "; writer open=" + w.isOpen());
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-760/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.index.TestIndexSortFieldWithoutDocValues
- Expected vs actual
- Expected
addDocumentto reject the document or the commit to succeed; actual on main:committhrowsIllegalStateException: unexpected docvalues type NONE for field 'sort' (expected=SORTED)andwriter open=false, with-eaand-da.
More files, environment, full output50 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: accepted by addDocument, then commit threw java.lang.IllegalStateException: unexpected docvalues type NONE for field 'sort' (expected=SORTED). Re-index with correct docvalues type.; writer open=false
       org.junit.Assert.fail(Assert.java:89)
org.apache.lucene.index.TestIndexSortFieldWithoutDocValues.testSortFieldIndexedOnlyAsStringField(TestIndexSortFieldWithoutDocValues.java:45)- Since 7.5.0 (LUCENE-8441)
addDocumentrejects a wrong doc-values type "instead of failing at commit time", not a missing one. - 6.5.0-8.5.2 skipped such a field at flush ("safe to ignore"); LUCENE-9330 removed that without discussing it.
setIndexSortnames no precondition; IndexWriter documents closing on an Error, a checkpoint disaster or a tragic flush failure (e.g. full disk), not a field type.
The full argument299 words
- Contract. LUCENE-8441, CHANGES 7.5.0: "IndexWriter now checks doc value type for index sort fields and fails the document if they are not compatible." Its issue (#9487), @jimczi: "Adding a doc value of the wrong type will now throw an exception when the document is indexed instead of failing at commit time."
setIndexSort: "Set the Sort order to use for all (flushed and merged) segments", nothing more. IndexWriter class javadoc: "if you hit an Error, or disaster strikes during a checkpoint then IndexWriter will close itself";getTragicException: closed "as a side-effect of a tragic exception, e.g. disk full while flushing a new segment". Here one document's field type triggers that tragic path. - Tests.
TestIndexSorting#testWrongSortFieldTypeasserts the up-frontIllegalArgumentExceptionfor 4 sort types times 3 wrong doc-values types, with no case without doc values; no test asserts the flush-time message. - History. From 6.5.0 (LUCENE-7579, flush-time sorting) to 8.5,
maybeSortSegmentskipped a sort field without doc values (// safe to ignore, sort field with no values or already seen before). LUCENE-9330 (#1440, 2020) replaced it with a sorter that reads throughDocValues.getX; neither the issue nor the PR mentions fields without doc values. LUCENE-8441 checked only where a document added doc values; before 9.0 a document without them simply had a missing value. LUCENE-9334 (9.0) moved the check and kept!= NONE, which now means "this field has no doc values in the schema". No built-in sorter can read such a field, which fits LUCENE-8441's broad CHANGES entry, though its issue speaks of "a doc value of the wrong type" and no commit records whetherNONEwas meant to be in scope. - Precedent. Upstream fixed a sibling failure in the same flush-time reader as a bug: #15125, "Handle inconsistent schema on flush with index sorts" (10.5.1).
The devil's-advocate check249 words
The strongest "intended" case: index sorting is doc-values based; DocValues.getX documents IllegalStateException "if field exists, but was not indexed with docvalues" and the message says what to do; since 9.0 the mistake is static and fails loudly at the first flush instead of silently giving an unsorted index; LUCENE-8441 spoke of a doc value "of the wrong type"; exceptions during flush are aborting by design.
Why it is weaker than it looks (our reading; the call is the maintainers'): that javadoc describes a reader-side helper, not a promise that the writer closes and drops other documents; the writer close arrived with a refactoring that removed an explicit "safe to ignore" branch, and neither its issue nor its PR discusses this case, so nothing records the close as a design decision; the NONE exemption dates from pre-9.0 schema rules, no built-in sorter can read such a field, and validateIndexSortDVType already handles NONE (a custom IndexSorter might cope with it); upstream treats a document-caused flush failure in this reader as a bug (#15125). What stands: it is a misconfiguration, caught early in practice, so the priority is low to medium. The adjudication confirmed it with medium confidence for that reason; the devil's advocate rated "not intended" medium-high. A read-only cross-model fact check rated "documented misuse" and "fix A is not the only right fix" moderate: maintainers could agree it is a bug and still choose another resolution, such as a check limited to built-in sorters, an explicit sorter contract, or documentation.
Recommended Run the index-sort doc-values check for fields without doc values too
Drop the s.docValuesType != DocValuesType.NONE condition in IndexingChain#initializeFieldInfo, so the existing index-sort check also runs for a field without doc values: addDocument then rejects the document with IllegalArgumentException and the writer stays open. The repro, the whole lucene/core suite (assertions on and off) and the other modules' tests whose own source configures an index sort pass with it.
     FieldSchema s = pf.schema;
-    if (indexWriterConfig.getIndexSort() != null && s.docValuesType != DocValuesType.NONE) {
+    // Also check a field without doc values (NONE): built-in index sorters cannot read it at flush.
+    if (indexWriterConfig.getIndexSort() != null) {
       final Sort indexSort = indexWriterConfig.getIndexSort();
       validateIndexSortDVType(indexSort, pf.fieldName, s.docValuesType);
     }
All options and trade-offs3 options · 657 words
The rejection uses the message style of testWrongSortFieldType ("SortField <string: \"sort\"> expected field [sort] to be SORTED but it is [NONE]"), and the other buffered documents are committed. Fields that are not sort fields still pass: the validation reader throws only for the field being validated. Until a fix ships, give every sort field doc values from its first document, or validate documents before addDocument; committed data is not affected, so no reindex is needed. Either way, add a case without doc values to testWrongSortFieldType (or the new test). Treating the field as missing is not recommended. Done only in the flush-time reader, the field would reach a committed segment, where merges and sorted searches read it through the same strict helpers. Done in DocValues.checkField, it would change every caller of DocValues.getX, which upstream declined in #11504.
Run the index-sort doc-values check for fields without doc values too (validated by the checks) (recommended)
IndexingChain.java:1382: one condition removed.
     FieldSchema s = pf.schema;
-    if (indexWriterConfig.getIndexSort() != null && s.docValuesType != DocValuesType.NONE) {
+    // Also check a field without doc values (NONE): built-in index sorters cannot read it at flush.
+    if (indexWriterConfig.getIndexSort() != null) {
       final Sort indexSort = indexWriterConfig.getIndexSort();
       validateIndexSortDVType(indexSort, pf.fieldName, s.docValuesType);
     }
Trade-offs
- The check now also runs for fields without doc values, once per field per in-memory segment and only when an index sort is configured; it builds comparators over
maxDoc0. Not benchmarked. - A custom
IndexSorterthat reads the field directly and copes with a missing value at flush would now see the document rejected. Built-in sorters cannot sort such a field anyway.
What the checks validated
- Scratch worktree of
a9779ef3c193, gradle, JDK 25: the new test fails 2 of 3 on stock with assertions on and off; with the fix, the new test plusTestIndexSorting,TestBinarySortField,TestSortingCodecReaderandTestIndexWriterpass (5 suites, 212 tests, 1 skipped); the whole:lucene:core:testpasses with assertions on (749 suites, 8,892 tests, 320 skipped, 0 failures) and off (326 skipped, 0 failures); every other module test whose own source callssetIndexSort(misc, highlighter, backward-codecs, sandbox: 9 suites, 165 tests) passes (17 more non-core classes that inherit index-sort cases from test-framework base classes were not run with the fix);:lucene:core:check -x test(google-java-format, ecj lint, forbidden APIs) passes. - Standalone runner with the fix shadowed: the new test 3 of 3 with assertions on and off; the session probe commits 3 documents. Earlier, the finder's equivalent sketch made the finder's test, the independent reproducer's 9 tests and its
BinarySortFieldtest pass, withTestIndexSortingandTestBinarySortField(87 tests) still green. - The code comment was reworded afterwards (comment only: "built-in index sorters cannot read it"). Re-checked with the reworded file: the diff applies to
a9779ef3c193and yields the patched source exactly; the new test passes 3 of 3 with assertions on and off; the session probe commits 3 documents;:lucene:core:check -x testpasses.
Two different changes. B1: only the flush-time reader treats a field with doc-values type NONE as having no values, as 6.5.0-8.5.2 did at flush. B2: DocValues.checkField becomes lenient for such a field.
Trade-offs
Not validated, not recommended (read, not executed). B1: the segment would be committed with the field still of type NONE, and merge-time sorting (SortField.java:569-600) and sorted search (TermOrdValComparator.java:165, NumericComparator.java:147, FieldComparator.java:273) read through DocValues.getX, so they would likely fail later, as on 6.2.0-8.5.2. B2: those reads would return empty values instead, but every caller of DocValues.getX would change; upstream kept checkField strict in #11504 (LUCENE-10468), where @jpountz asked: "But if it exists and is not indexed correctly, it's better to fail?"
Index the sort field with doc values from its first document (for example StringField plus SortedDocValuesField, or LongPoint plus NumericDocValuesField), or validate documents before addDocument.
Trade-offs
Avoids the failure; not a fix.
Products that let users choose an index sort and field mappings separately should check that every sort field has doc values before indexing; until a fix ships, that check is also the workaround.
An AI finder spotted it by reading the code while modelling BinarySortField's flush-time sort: the sort key is read through DocValues.getBinary, which throws for a field that exists without doc values. A direct probe and a public-API JUnit test confirmed it; the unit's bounded-exhaustive harness had missed it, because it always gave the sort field doc values or none.
The method in full140 words
Method: non-formal (code reading). The hunt unit modelled the flush-time sort for BinarySortField, whose key provider reads through DocValues.getBinary on the flush-time reader. Reading DocValues.checkField showed that it throws for a field that exists without doc values, and IndexingChain#initializeFieldInfo showed that such a field is never checked up front.
- A direct probe on main confirmed it for STRING, LONG and
BinarySortFieldsorts; a public-API JUnit test reproduced it with assertions on and off, and a version sweep on release jars located the change of symptom at 8.6.0. - The unit's bounded-exhaustive harness did not find it: its alphabet always indexed the sort field with doc values or not at all.
- Then an independent reproducer, read-only reviews by another model family (OpenAI GPT-5.6), a devil's advocate, an adjudication, the follow-up stages and an audit each checked it (see the checks below).
No prior report found (searched 2026-10-27): two runs of the prior-report tool over GitHub issues, PRs and commits, JIRA, four mailing lists and downstream projects, 87 more queries, the changed files of all 408 open PRs, and web searches. Related, not the same: #9487, #15125, #10794 and #11504.
Searches4 searches
Keyword search only; GitHub search was rate-limited at times (queries retried); private reports are not visible. Nearest items: #9487 (LUCENE-8441: the up-front type check this case slips past); #15125 (merged, 10.5.1: a sibling NPE in the same flush-time reader after a rejected document; its test never indexes the sort field without doc values); #10794 (LUCENE-9755, open: the same checkField exception at search time over pre-9.0 segments; no index sort, no writer close; different fix site); #11504 (LUCENE-10468: checkField kept strict); #10370 / lucene-solr#1440 (LUCENE-9330, the introducing change) and #10374 (LUCENE-9334); #16809, #16810, #16565 (other index-sort validation gaps, in doc-values updates); a 2026 Stack Overflow question (the same exception from SortingCodecReader on a stored-only field, reader side); a 2021 java-user thread ("index sorting requires doc values", a usage question).
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues and PRs (apache/lucene) | 2026-10-27 | the scripted prior-report search in two runs (54 issue and PR queries, for example "index sort" "unexpected docvalues type", setIndexSort StringField, "index sort" "AlreadyClosedException", "LUCENE-9330" regression, "BinarySortField" missing, plus class, method and symptom queries), the finder's 45 and the devil's advocate's 42 queries over all sources, and GitHub-wide searches for maybeSortSegment and the exception with index sort, flush, IndexSorter and MultiSorter | no report; the items listed above |
| Open PRs, branches and history | 2026-10-27 | the changed files of all 408 open PRs matched against the files involved (19 hits, patches grepped); commits on main up to f7bcc0abd81 and branch_10x; git log -S on validateIndexSortDVType and the removed 'safe to ignore' branch over the full history | no PR or commit changes the NONE guard, checkField or the flush-time reader |
| Mailing lists (dev@, java-user@, issues@, commits@) and JIRA | 2026-10-27 | 40 list queries and 8 JIRA-archive queries in the two tool runs | a 2021 java-user usage question; nothing about the writer closing |
| Downstream and the web | 2026-10-27 | 4 downstream queries (Elasticsearch, OpenSearch, Solr), 1 tool web query, 5 manual web queries, a Stack Exchange search | unrelated reports of the same exception text (search time, SortingCodecReader, the #15125 NPE) |
The flush failure comes from LUCENE-9330 (#1440, merged 2020-05-22), first released in 8.6.0; all 49 releases from 8.6.0 to 10.5.2 and main fail. The missing check is older: from 6.2.0 to 8.5.2 the bad segment was committed and later broke sorted search and merges. Not fixed upstream.
Versions tested7 rows
Flush symptom introduced by LUCENE-9330 "Make SortFields responsible for index sorting and serialization" (apache/lucene-solr#1440 by @romseygeek, issue #10370), merged 2020-05-22: de2bad90390 on master (first released in 9.0.0) and ad0cefb8ec2 on branch_8x (first released in 8.6.0). It removed 8.5's lenient branch (// safe to ignore, sort field with no values or already seen before) and made the flush read through DocValues.getX. The two commits were not built; the attribution rests on the release boundary and git log -S. The missing check is older: since LUCENE-6766 (6.2.0) such a document was always accepted; LUCENE-7579 (6.5.0) added flush-time sorting, which skipped the field; LUCENE-8441 (7.5.0) checked only fields with doc values; LUCENE-9334 (d03662c48bf, 9.0.0) moved the check and kept the NONE exemption. From 8.6.0 in the 8.x line the document also got through when the field already had doc values in a committed segment (executed on 8.6.0 and 8.11.4, inferred in between); since 9.0.0 that case is rejected at addDocument, so the flush failure needs the field's first appearance. Main f7bcc0abd81 and branch_10x have no change to this code (2026-10-27).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's test: 2 of 3 fail (gradle and the standalone runner, assertions on and off); commit throws, writer closed, 1 document left |
| 10.5.2 | affected | this doc's test: 2 of 3 fail, the same output; the session probe behaves as on main |
| 9.12.3, 9.1.0 | affected | this doc's test: 3 of 3 fail; the control fails with the separate #15125 NPE (fixed in 10.5.1) |
| 8.6.0 to 10.5.2 (49 releases) | release sweep | the follow-up's flush probe (assertions on): addDocument accepts, commit throws, writer closed (tragic), buffered documents lost |
| 7.5.0, 8.4.0 to 8.5.2 | older form | the follow-up's flush probe: the commit succeeds with all 3 documents; the segment keeps the field without doc values |
| 6.2.0, 6.4.0, 6.5.0, 7.0.0, 7.4.0, 7.5.0, 8.5.2 | older form | after-commit probe: the commit succeeds, then sorted search on the field throws, and forceMerge throws and closes the writer, also in a new session; CheckIndex not clean from 6.5.0 |
| fix (one condition) on main | not affected | addDocument rejects the document; every repro passes; the whole lucene/core suite passes |
An independent reproducer, a devil's advocate, an adjudication and an audit confirmed it with executed tests; read-only reviews by another model family agreed on the root cause, one giving a procedural "not real" because it could not run code. This doc's gradle runs reproduced it on main a9779ef3c193 and validated the fix.
Checks and verdicts389 words
Not done: a cross-model review that executes code (all reviews by the other model family ran read-only; separate runs re-ran the repro).
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Found by code reading; JUnit fails 2 of 2 on main with assertions on and off and on 10.5.2, 9.12.3 and 9.1.0; passes with the fix sketch, and 87 upstream index-sort tests still pass. |
| cross-model review, intended lens | real (medium) | An independent reviewer from another model family (OpenAI GPT-5.6), read-only: the intended argument is weak; a separate re-run failed 2 of 2. |
| independent reproducer | real | Own JUnit: all 7 built-in sort types fail on main (assertions on and off), 10.5.2 and 9.12.3, both controls pass on main; BinarySortField fails; 8.5.0 commits, 8.6.0 fails; a trigger-shape test narrowed the reach. |
| cross-model review, refute lens | not real (low, procedural) | OpenAI GPT-5.6, read-only: every shell call was denied, so "not reproduced" by construction; it agreed on the root cause and called the contract ambiguous; separate re-runs failed 2 of 2. |
| devil's advocate | real (medium-high) | Built the strongest intended case and showed why it fails; its probe fails on main, 10.5.2, 10.4.0 and 9.12.3; narrowed the reach to the field's first appearance. |
| adjudication | confirmed (medium) | Re-ran the finder's JUnit (2 of 2 fail) and the reproducer's (7 of 9 fail, the controls pass); class crash, severity Low to Medium; not a duplicate. |
| audit | keep | Re-ran the finder's JUnit with assertions off: 2 of 2 fail; with the fix shadowed, 2 of 2 pass. |
| this doc | reproduced | New 3-test class through gradle and the standalone runner on main a9779ef3c193 and three releases; session probe; fix validated with the whole lucene/core suite. |
| fact check | holds; 2 wording errors, fixed | A separate AI tool re-ran the gradle command (assertions on and off), the standalone runner on main, 10.5.2 and 9.12.3, the session probe and fix A (closest suites, whole lucene/core suite, check -x test). Its own reach probe found the field-order case now described in the reach paragraph. |
| cross-model fact check | real; wording findings resolved | An independent reviewer from another model family (OpenAI GPT-5.6), read-only: the bug and fix A hold; it corrected the reach, the pre-6.5 history, the fix comment and the option B discussion. Every finding is resolved. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 502 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,467 words
- Registry title
- With an index sort, a document whose sort field is indexed without doc values (for example only as a StringField) is accepted by addDocument, and the next flush throws IllegalStateException and closes the IndexWriter, losing every uncommitted document (since 8.6.0)
- Area
- index / index sorting (IndexingChain index-sort field validation and flush-time sort)
- Priority
- Low, rank 320: A loud tragic flush with a clear message, caused by an application schema mistake behind an opt-in index sort and usually caught in development.
- Impact class
- crash
- Impact note
- Hits applications that configure an index sort (opt-in) and index the sort field without doc values the first time it appears in the index, for example only as a StringField, a point field or a StoredField, with no committed segment and no earlier document in the in-memory segment giving the field doc values: addDocument accepts the document, later correct documents for that field are rejected with IllegalArgumentException because the bad document fixed the field's schema, and the next flush or commit throws IllegalStateException 'unexpected docvalues type NONE ... Re-index with correct docvalues type.', closes the IndexWriter as a tragic event and loses every document buffered since the last commit, valid ones included; default codec and directory, -ea and -da, ordinary scale, every built-in sort type plus BinarySortField [exec]; committed data stays intact and a new writer starts clean; released 8.6.0-10.6.0 (10.6.0 by reading).
- Summary
- You configure an index sort on a field, for example new Sort(new SortField("sort", SortField.Type.STRING)), and add a document that carries that field only as a StringField, without the SortedDocValuesField that sorting reads, before any committed document has the field. You expect addDocument to reject the document up front, as it has rejected a doc-values field of the wrong type since LUCENE-8441 (7.5.0), or the field to count as missing. Instead addDocument accepts it, and the next flush or commit throws IllegalStateException 'unexpected docvalues type NONE for field 'sort' (expected=SORTED). Re-index with correct docvalues type.' and closes the IndexWriter, so every document added since the last commit is lost.
- Introduced
- Flush-time symptom: LUCENE-9330 'Make SortFields responsible for index sorting and serialization' (apache/lucene-solr#1440 by romseygeek, issue #10370): master de2bad9039054af753bc2c847565f63f05f4fdd7 (first released in 9.0.0) and branch_8x ad0cefb8ec279e4fae0b104d487deb36ff2f9d27 (first released in 8.6.0). It replaced the 8.5 flush code, which skipped a sort field without a doc-values writer ('// safe to ignore, sort field with no values or already seen before'), with SortField#getIndexSorter reading through DocValues.getNumeric/getSorted/getBinary, whose checkField throws for a field whose FieldInfo has doc-values type NONE [exec: 8.5.2 commits the document, 8.6.0 fails; read: git log -S on the removed comment and on getDocValuesLeafReader; the two commits themselves were not built]. The missing up-front check is older [read, exec]: since index sorting moved into IndexWriterConfig (LUCENE-6766, 6.2.0) such a document has always been accepted; LUCENE-8441 (679b4aa71d2 on master, 276a851b054 on branch_7x, 7.5.0) validated only fields that carry doc values, and LUCENE-9334 (d03662c48bf, 9.0.0) moved that check into IndexingChain#initializeFieldInfo behind 's.docValuesType != DocValuesType.NONE'. (2020-05-22 (LUCENE-9330, master and branch_8x); the validation gap dates from 2016-05 (LUCENE-6766, 6.2.0))
- First affected version
- 8.6.0 for the flush-time writer close [exec]; 8.5.2, the last release before it, commits the document [exec]. The underlying validation gap is in every release since 6.2.0 [exec on 6.2.0, 6.4.0, 6.5.0, 7.0.0, 7.4.0, 7.5.0 and 8.5.2]: there the bad segment was committed, and then every sorted search on the field and every merge that included the segment threw, the merge closing the writer in later sessions too (CheckIndex reports the index as not clean from 6.5.0)
- Affected versions
- [exec] the flush symptom (document accepted, commit throws IllegalStateException, writer closed with a tragic exception, buffered documents lost) on all 49 releases from 8.6.0 to 10.5.2 (8.6.0-8.6.3, 8.7.0, 8.8.0-8.8.2, 8.9.0, 8.10.0-8.10.1, 8.11.0-8.11.4, every 9.x release 9.0.0-9.12.3, every 10.x release 10.0.0-10.5.2) and on main a9779ef3c193, with the version-portable flush probe (-ea); the candidate JUnit fails 2 of 2 on main (-ea and -da), 10.5.2, 9.12.3 and 9.1.0; the independent reproduction's JUnit fails for all 7 built-in sort types on main (-ea and -da), 10.5.2 and 9.12.3, and its BinarySortField test on main; the intended-behaviour check's probe fails on main, 10.5.2, 10.4.0 and 9.12.3. [exec] not affected at flush: 7.5.0 and 8.4.0-8.5.2 (the commit succeeds), but 6.2.0-8.5.2 have the older, persistent form described under first_affected_version. In 8.6.0-8.11.4 the document also gets through when the field already has doc values in a committed segment [exec]; from 9.0.0 only on the field's first appearance. Not fixed upstream: main 645d4fe14a2 [exec 2026-10-29: the candidate JUnit fails 2 of 2 with -ea and -da]; branch_10x 657014b3c57 and branch_10_6 4ae946e5a9b (10.6.0 RC1, released 2026-10-29) carry the same NONE guard at IndexingChain.java:1321 [read].
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (2026-10-27, read-only; the prior-report record, verdict new, confidence medium-high): two scripted prior-report searches (run 1: 30 GitHub issue and PR, 3 commit, 2 downstream, 20 mailing-list and 4 JIRA-archive queries, 337 distinct hits; run 2: 24, 3, 2, 20 and 4 queries plus 1 web query, 176 hits), the finder's 45-query and the intended-behaviour check's 42-query runs, global GitHub searches (maybeSortSegment; 'unexpected docvalues type NONE' with index sort, flush, IndexSorter or MultiSorter), the changed files of all 408 open apache/lucene PRs (19 touch related files; none changes the NONE guard, validateIndexSortDVType, DocValues.checkField or the flush-time handling), the commits on main and branch_10x for the files involved, git log -S in the full history, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and 5 manual web queries. Related, not the same bug: #9487 (LUCENE-8441, the up-front type check this case slips past, fixed in 7.5.0); #15125 (merged 2025-09-29, backports #16395/#16396, first released in 10.5.1: a sibling NPE in the same flush-time reader for a field left without a FieldInfo after a rejected document); #10794 (LUCENE-9755, open: the same checkField exception at search time over pre-9.0 segments with mixed doc-values presence; different path and fix site, no writer close); #11504 (LUCENE-10468: maintainers kept DocValues.checkField strict); #10370 and apache/lucene-solr#1440 (LUCENE-9330, the introducing change; no discussion of fields without doc values); #10374 (LUCENE-9334); #16809/#16810 and #16565 (other index-sort validation gaps); #16202 (adds BinarySortField); a 2026-01 Stack Overflow question showing the same exception when re-sorting an existing reader with SortingCodecReader on a StoredField-only sort field (reader side, no IndexWriter, treated as expected by the asker); a 2021 java-user thread ('index sorting requires doc values', usage question).
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-27) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the 10.5.2, 9.12.3 and 9.1.0 release jars. The follow-up's flush probe ran, with assertions on, on all 49 releases from 8.6.0 to 10.5.2 and on main, and older-form probes ran back to 6.2.0. Fix A was validated in the scratch worktree: the new test, the closest suites, the wholelucene/coresuite with assertions on and off, every other module test whose own source configures an index sort, and:lucene:core:check -x test.
- Finding record
lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:1381-1385 (initializeFieldInfo calls validateIndexSortDVType only when s.docValuesType != DocValuesType.NONE), :182-248 (flush-time doc-values reader returns null for a field without doc values), :251-299 (maybeSortSegment builds every sorter's comparator on that reader during flush), :1635 (validateIndexSortDVType)lucene/core/src/java/org/apache/lucene/index/DocValues.java:213-230 (checkField throws IllegalStateException 'unexpected docvalues type ... Re-index with correct docvalues type.' when the field exists with another doc-values type)lucene/core/src/java/org/apache/lucene/search/SortField.java:569-600, search/SortedNumericSortField.java, search/SortedSetSortField.java:178-186 and search/BinarySortField.java:159-161 (the index sorters read their values through DocValues.getSorted/getNumeric/getSortedNumeric/getSortedSet/getBinary)lucene/core/src/java/org/apache/lucene/index/IndexWriterConfig.java:504-516 (setIndexSort javadoc and code: no precondition on the sort fields' doc values) and index/IndexWriter.java:162-165 (class javadoc: IndexWriter closes itself on an Error or when disaster strikes during a checkpoint)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:209-218, 244-247, 251-299 (283-294), 301-305, 1382-1385, 1635-1727 (1675-1686)lucene/core/src/java/org/apache/lucene/index/DocValues.java:213-230, 272-289lucene/core/src/java/org/apache/lucene/search/SortField.java:569-600lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThread.java:585-602; IndexWriter.java:3882-3883, 6068-6084, 6098-6106; IndexWriterConfig.java:504-515
- Why it looks unintended
lucene/CHANGES.txt:7211-7212 (LUCENE-8441), :300 and :867 (GITHUB#15125)lucene/core/src/java/org/apache/lucene/index/IndexWriterConfig.java:504; IndexWriter.java:162-165; DocValues.java:272-280lucene/core/src/test/org/apache/lucene/index/TestIndexSorting.java:2851-2896lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:6108-6111 (getTragicException javadoc)
- Suggested fix
lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:1382-1385, 1635-1727 (1676, 1725)
- TestIndexSortFieldWithoutDocValues.java (JUnit test):
repro/LFV-760/src/org/apache/lucene/index/TestIndexSortFieldWithoutDocValues.java(49 lines)
A light summary card(what the user does, what should happen, inside addDocument, inside commit(), the aborting close, expected vs actual, the fix), made in parallel with this doc from an executed probe on main a9779ef3c193 (assertions on and off, and with the fix as a control).
assets/LFV-760/bug.png(502 KB)