RandomSamplingFacetsCollector counts facets on a random sample of about sampleSize hits, and amortizeFacetCounts divides each count by the sampling rate to estimate the real count. createManager runs one such collector per slice of a concurrent search and merges them; the merge reads each slice's sample where it needs the slice's hits.
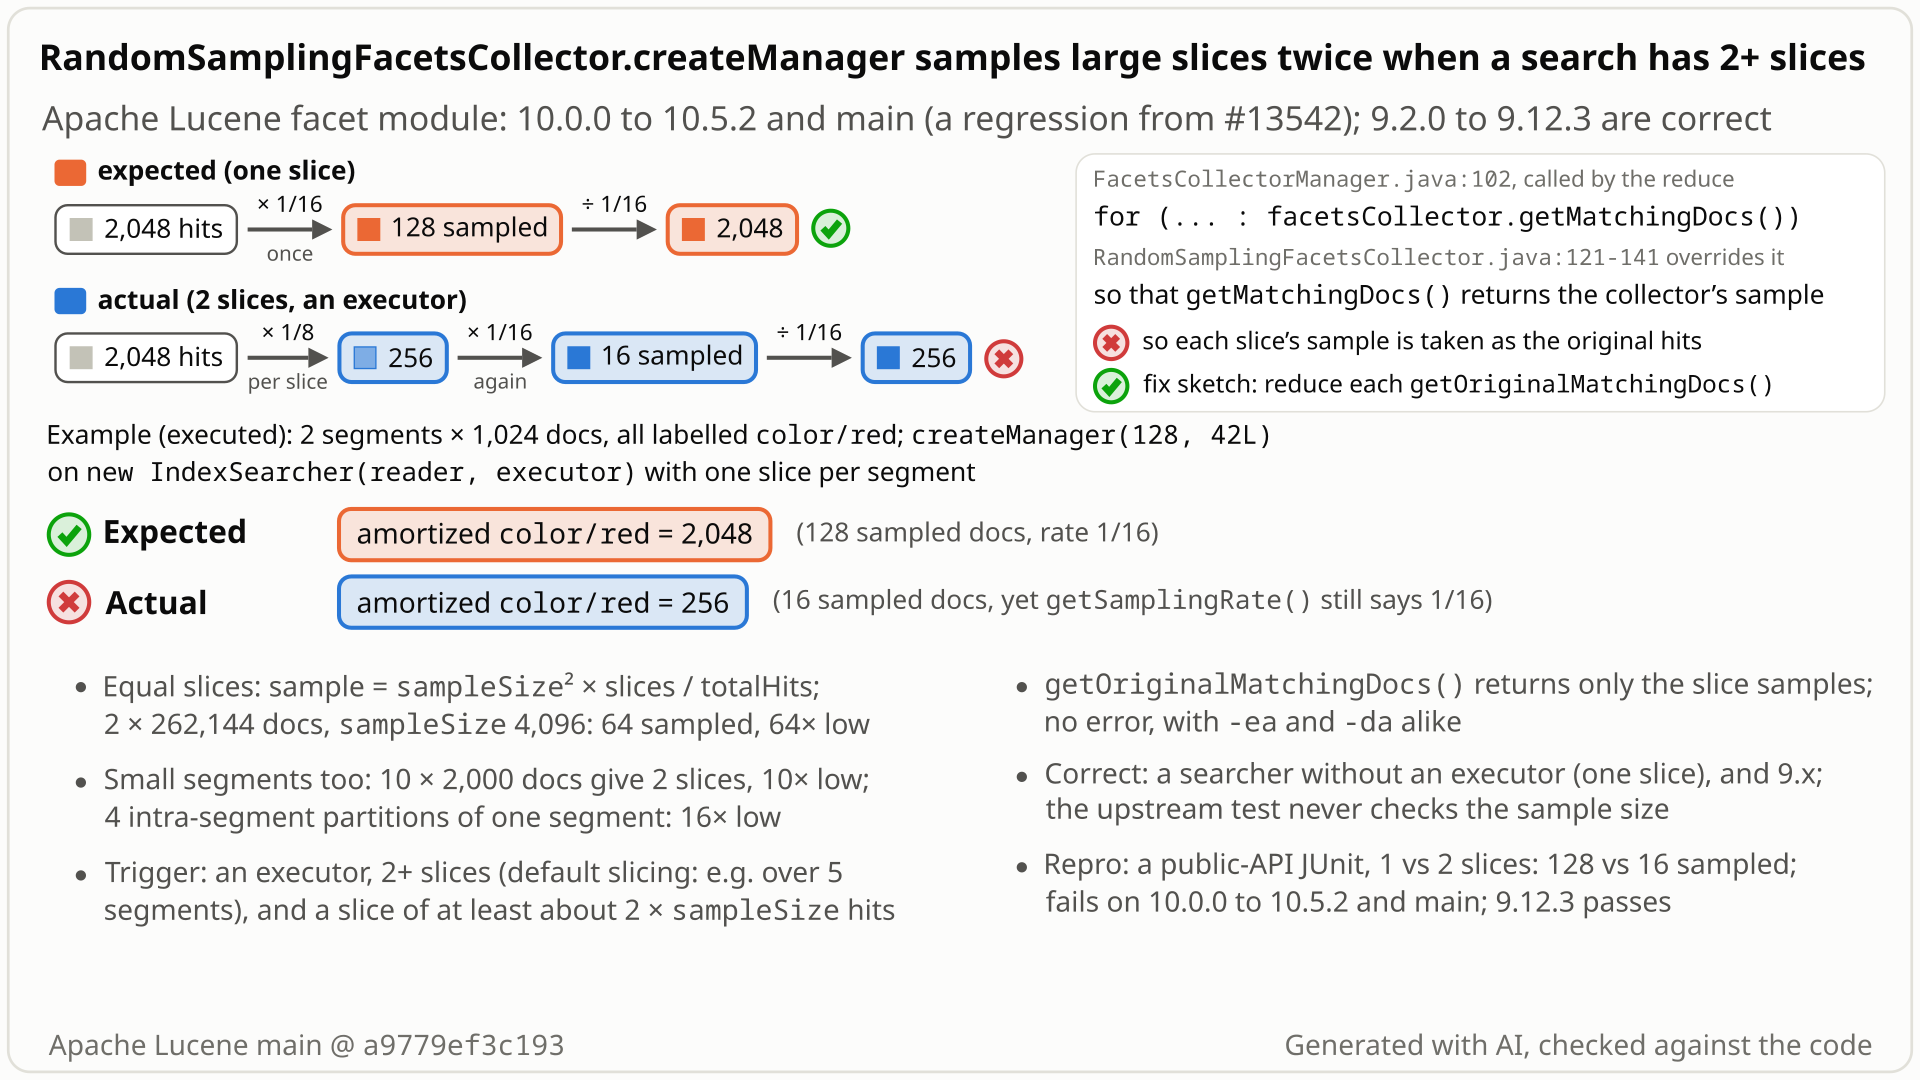
- Index 2,048 documents in 2 segments of 1,024, all with the facet label
color/red. Sample them withRandomSamplingFacetsCollector.createManager(128, 42L)on anIndexSearcherthat has an executor and one slice per segment. - You expect what a searcher without an executor (one slice) gives: 128 sampled hits,
getSamplingRate()1/16, andamortizeFacetCountsscalingredback to 2,048. - You get 16 sampled hits and an amortized count of 256, 8x too low, while
getSamplingRate()still says 1/16 andgetOriginalMatchingDocs()holds 256 hits instead of 2,048. No error. - Why: each slice already keeps its own sample, 128 of its 1,024 hits (1 in 8). The merge takes those 256 sampled hits for all the hits and samples them again at 1 in 16: 16 are left, an applied rate of 1/128.
- Default slicing does it too: 10 segments of 2,000 documents (2 slices of 5) with
sampleSize1,000 give 100 sampled and an amortized 2,000 instead of 1,000 and 20,000. Every release since 10.0.0; 9.x samples once.
Applications that sample facets through createManager on an IndexSearcher with an executor, when a search has 2 or more slices (default slicing: more than 5 segments, or 2 segments over 250,000 docs each; or intra-segment partitions) and a slice has at least about 2 x sampleSize hits. Those hits then count too little, by the slice's sampling ratio, silently.
Mechanism, terms and numbers877 words
RandomSamplingFacetsCollector counts facets on a random sample of about sampleSize hits when a query matches more, and amortizeFacetCounts divides the sampled counts by getSamplingRate() to estimate the real ones. Its createManager(sampleSize, seed) is the CollectorManager "for concurrent random sampling": on an IndexSearcher with an executor it gives each slice its own collector and merges them. Since #13542 (10.0.0) the merge builds the merged collector's original hits from each slice collector's getMatchingDocs(), which that class overrides to return the slice's own sample. The merged collector then samples those samples again, while getSamplingRate() reports only the second stage. The hits of every slice with at least about 2 x sampleSize hits are thinned twice, so a label's amortized count is low in proportion to its hits in such slices; with equal slices, as in every repro, the sample is sampleSize^2 x numSlices / totalHits and every count is low by exactly sliceHits / sampleSize (8x, 10x, 16x and 64x). Hits in smaller slices are sampled once and counted correctly. getOriginalMatchingDocs() returns the union of the per-slice samples instead of the original hits. Default slicing is enough (an index with more than 5 segments has 2 or more slices), and intra-segment partitions do it on one segment. No error is raised. A searcher without an executor (or whose search has one slice), and every 9.x release (where the merge read getOriginalMatchingDocs(), as the design asked), sample once. Merging each slice's original hits fixes it; the whole facet test suite passes.
- Facet sampling:
RandomSamplingFacetsCollector(sampleSize, seed)keeps aboutsampleSizehits when a query matches more: it walks the hits in bins of(int) (totalHits / sampleSize)and keeps one random hit per bin.getSamplingRate()issampleSize / totalHits.getMatchingDocs()returns the sample,getOriginalMatchingDocs()all hits. - Amortizing:
amortizeFacetCounts(result, config, searcher)divides each sampled count by the sampling rate (capped by the label's drill-down term docFreq) to estimate the real count. - Slices: an
IndexSearcherbuilt with an executor splits the index into slices and runs one collector per slice in parallel; aCollectorManagercreates the collectors and itsreducemerges them. Without an executor there is one slice. Default slicing gives each segment above 250,000 documents its own slice and groups the others, largest first, until a group has 5 segments or more than 250,000 documents (so a group can exceed 250,000); #13542 (10.0.0) added intra-segment partitions. createManager(sampleSize, seed): the sampler'sCollectorManager, documented as "a CollectorManager for concurrent random sampling through RandomSamplingFacetsCollector".
- Each slice gets its own
RandomSamplingFacetsCollector(RandomSamplingFacetsCollector.java:269-271). ItsgetMatchingDocs()is overridden: once the slice's hits exceedsampleSizeit samples them atsampleSize / sliceHitsand returns the sample, oneMatchingDocsper segment whosetotalHitsis copied from the original (:118-141,:209). The unsampled list isgetOriginalMatchingDocs()(:143-146). - With 2 or more collectors,
reducebuilds aReducedRandomSamplingFacetsCollector(:279-282) that fills its original hits fromFacetsCollectorManager.reduceMatchingDocs(facetsCollectors)(:291-292). That helper merges the partitions of one segment and reads each collector throughgetMatchingDocs()(FacetsCollectorManager.java:93-114, line 102): the slice samples. - When facet counting asks the merged collector for
getMatchingDocs(), it sums the copied totals (the real hit count), sets the rate tosampleSize / totalHitsand samples the union of the slice samples again (RandomSamplingFacetsCollector.java:125-140).getSamplingRate()returns this second rate only. amortizeFacetCountsdivides by that rate (:240), so the hits of each slice that the first stage thinned count too little, by that slice'ssliceHits / sampleSize. The first stage drops hits only when a slice has at least about 2 xsampleSizehits (bin size 2 or more,:164); a smaller slice's hits reach the merge whole, are sampled once and are counted correctly. An executed probe with one slice of 10,000 hits labelledcolor/xand one of 100 hits labelledcolor/y,sampleSize1,000, givesx1,010 instead of 10,000 andya correct 100; with the fix, 10,000 and 100.- Without an executor the searcher has one slice (
IndexSearcher.java:226-231),reducereturns that collector unchanged (RandomSamplingFacetsCollector.java:279-281), and the result is correct; so is any search whose leaves form one slice.
The numbers (every document labelled color/red, so the true count is the hit count; main, assertions on and off)
| index and slices | sampleSize | one slice: sampled / originals / amortized | several slices: sampled / originals / amortized |
|---|---|---|---|
| 2 segments x 1,024, one slice per segment (2 slices) | 128 | 128 / 2,048 / 2,048 | 16 / 256 / 256 (8x low) |
| 10 segments x 2,000, default slicing (2 slices) | 1,000 | 1,000 / 20,000 / 20,000 | 100 / 2,000 / 2,000 (10x low) |
| 1 segment of 65,536, 4 intra-segment partitions | 1,024 | 1,024 / 65,536 / 65,536 | 64 / 4,096 / 4,096 (16x low) |
| 2 segments x 262,144, default slicing (2 slices) | 4,096 | 4,096 / 524,288 / 524,288 | 64 sampled, amortized 8,192 (64x low) |
getSamplingRate() is the same in both columns (1/16, 0.05, 1/64, 1/128). The rate applied in the first row is 1/8 x 1/16 = 1/128. In every row (equal slices, integer ratios) the sample size equals sampleSize^2 x numSlices / totalHits; with unequal slices it does not (the probe above samples 110 hits where the formula gives 198).
Exposure and likelihood404 words
- Who is exposed. Applications that sample facets with
createManageron a searcher built with an executor, on queries whose hits far exceedsampleSize, which is when sampling is used. Taxonomy and sorted-set facet counts both read the merged collector'sgetMatchingDocs()(read); every repro that counted facets used sorted-set facets, and the taxonomy path was read, not run. - Default vs opt-in. Two opt-ins, facet sampling and an executor; after that, default slicing is enough (10 segments of 2,000 documents form 2 slices), and intra-segment partitions trigger it on one segment.
IndexSearcher.search(Query, Collector)is deprecated in favour of theCollectorManagerpath "due to its support for concurrency", socreateManageris the documented way to sample. The executor constructor is@lucene.experimental. - Scale. Deterministic: every sampled query on such a searcher whose search has 2 or more slices, one or more of them with at least about 2 x
sampleSizehits. A label's amortized count is low in proportion to its hits in those slices; with equal slices, as in every repro, every label is low by exactlysliceHits / sampleSize: 8x, 10x, 16x and 64x. The error grows with the slice size. Hits in smaller slices are counted correctly (executed probe: a label in a 10,000-hit slice amortizes to 1,010 instead of 10,000, one in a 100-hit slice to a correct 100). - Silent. No exception or log line.
getSamplingRate()andMatchingDocs.totalHitslook normal, and in these integer-ratio repros the result even looks self-consistent (sampled / originals equals the reported rate), because the "original hits" are already a sample. - Second broken promise. The class javadoc says "If you require the original set of hits, you can call getOriginalMatchingDocs()". On the merged collector it returns the slice samples (2,000 of 20,000), so the two-pass recipe of the facet user guide (the demo module's facet package overview: find the top facets on the sample, then count them exactly "over the entire matching document set") loses hits too.
- How likely. Plausible: deterministic once both opt-ins meet, but no report exists in the two years since 10.0.0, and no issue in the Elasticsearch, OpenSearch or Solr repositories mentions the collector.
- Not affected. Which documents match, top hits, exact (unsampled) facet counts and the index; searchers without an executor, and searches with one slice; hits in slices below about 2 x
sampleSizehits; queries with at mostsampleSizehits; 9.x. Nothing is stored wrong, so a fix needs no reindex.
The test shows that with two slices (one per segment), RandomSamplingFacetsCollector.createManager samples the hits twice: the reduce samples again the per-slice samples it reads through the overridden getMatchingDocs().
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.facet;

import java.util.List;
import org.apache.lucene.document.Document;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.LeafReaderContext;
import org.apache.lucene.index.NoMergePolicy;
import org.apache.lucene.search.DocIdSetIterator;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.MatchAllDocsQuery;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestSamplingManagerTwoSlices extends LuceneTestCase {

  public void testSampleSizeWithTwoSlices() throws Exception {
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w =
            new IndexWriter(dir, new IndexWriterConfig().setMergePolicy(NoMergePolicy.INSTANCE))) {
      for (int segment = 0; segment < 2; segment++) {
        for (int i = 0; i < 1024; i++) {
          w.addDocument(new Document());
        }
        w.flush();
      }
      try (DirectoryReader reader = DirectoryReader.open(w)) {
        IndexSearcher searcher =
            new IndexSearcher(reader, Runnable::run) {
              @Override
              protected LeafSlice[] slices(List<LeafReaderContext> leaves) {
                return slices(leaves, 1, 1, false);
              }
            };
        RandomSamplingFacetsCollector fc =
            searcher.search(
                MatchAllDocsQuery.INSTANCE, RandomSamplingFacetsCollector.createManager(128, 42));
        int sampled = 0;
        for (FacetsCollector.MatchingDocs md : fc.getMatchingDocs()) {
          for (DocIdSetIterator it = md.bits().iterator();
              it.nextDoc() != DocIdSetIterator.NO_MORE_DOCS; ) {
            sampled++;
          }
        }
        // expected 128 sampled hits (2048 hits at the reported rate 1/16, as with one slice); actual 16
        assertEquals("sampled hits at rate " + fc.getSamplingRate(), 128, sampled);
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-765/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/facet/build/libs/lucene-facet-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.facet.TestSamplingManagerTwoSlices
# the module(s) facet also need their third-party runtime jars
- Expected vs actual
- Expected: 128 sampled hits out of 2,048 (the reported rate 0.0625), as a one-slice search gives. Actual (-ea and -da): 16.
More files, environment, full output38 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: sampled hits at rate 0.0625 expected:<128> but was:<16>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:647)
org.apache.lucene.facet.TestSamplingManagerTwoSlices.testSampleSizeWithTwoSlices(TestSamplingManagerTwoSlices.java:64)- The javadoc fixes one ratio, "sampling size / totalN", and
getSamplingRate()"Returns the sampling rate that was used": it says 1/16, while 1/128 was applied. - The design (LUCENE-10484) says "the reduction should call getOriginalMatchingDocs instead of getMatchingDocs"; 9.x did, and samples once.
- #13542 changed that line to merge partitions of one segment; it never discusses sample size or rate.
The full argument339 words
- Contract. Constructor javadoc: "If the number of hits is greater than the size, sampling will be done using a sample ratio of sampling size / totalN" (
RandomSamplingFacetsCollector.java:97-100).getSamplingRate(): "Returns the sampling rate that was used" (:256). Class javadoc: the original hits throughgetOriginalMatchingDocs(), and amortized counts (:38-40).createManager: "a CollectorManager for concurrent random sampling through RandomSamplingFacetsCollector" (:261-264), the same sampler run concurrently. All four break once a search has 2 or more slices and one of them has at least about 2 xsampleSizehits. - Design. LUCENE-10484 (#11520, an issue migrated from JIRA, by @javanna): "the reduction should call getOriginalMatchingDocs instead of getMatchingDocs, which modifies the internal totalHits when called". Its implementation (#765:
7ed0f3d7adbon main, released in 9.2.0 as the branch_9x commitb0ecba4fb24) added each collector'sgetOriginalMatchingDocs(). - History. #13542 (@javanna, 2024-09-10, intra-segment concurrency) replaced that loop with the new shared helper
reduceMatchingDocs, so that partitions of one segment merge into oneMatchingDocs. Its PR body namescreateManageronly for that merge ("returned multiple MatchingDocs instances that pointed to the same LeafReaderContext"), and a 2024-07-22 comment by the author listsTestRandomSamplingFacetsCollector.testRandomSamplingamong the facet tests that failed before the facet code was adapted to partitions; no PR or review comment discusses sample size or rate. Every 9.x release, 9.2.0 to 9.12.3, samples once (executed). - Tests.
TestRandomSamplingFacetsCollectorstates the intended sample size ("10% of total docs, 20% of the hits", line 96) but asserts only a chi-square over segments andamortized == min(5 x sampled, numDocs / 10)(:133,:135-148). Neither checks the query-wide sample size or compares an amortized count with the true count; the amortized check divides by the merged collector's own rate, so it holds either way, and the test is not built to see this bug. - Effect size. 16 sampled hits where 128 were asked for, and 256 where 2,048 is the true count, is not sampling noise: the bias is deterministic and the reported rate is wrong.
The devil's-advocate check264 words
The strongest "works as designed" case: sampleSize is only "the preferred sample size"; the executor constructor and search(Query, CollectorManager) are @lucene.experimental; createManager never promises the result of one collector; reusing reduceMatchingDocs was deliberate, #13542 was reviewed, and its author saw TestRandomSamplingFacetsCollector fail during that work; FacetsCollector.getMatchingDocs() is documented as "the documents matched by the query", so the sampling override, not the helper, could be blamed; per-slice sampling could be read as a memory saving; the upstream test accepts the result.
Why it fails: the same javadoc sentence fixes the ratio, sampleSize / totalN, and getSamplingRate() reports a rate that was not applied, so the estimates are biased, not merely noisy. getOriginalMatchingDocs() stops returning the original hits. Whichever side is blamed, the sampler's own documented rate and original-hits contract break, and the design issue settled the reduce on getOriginalMatchingDocs exactly because getMatchingDocs is the sampling override ("which modifies the internal totalHits when called"). @lucene.experimental allows API change, not wrong results, and the deprecation of search(Query, Collector) sends users to exactly this path. The reuse was deliberate for the partition merge; nothing in the PR discusses the sample, and every 9.x release reduced the originals. Nor is per-slice sampling a memory saving: each slice collector holds its original hits until the reduce in either case, and each sampled segment is a new bit set of the segment's full size (RandomSamplingFacetsCollector.java:162). The upstream test never checks the sample size. Verdict: a regression (adjudication: confirmed, high; the reproducer, the intended-lens review and the devil's advocate: real; the cross-model reviews rated the intended case weak).
Recommended Reduce each slice's original hits
In ReducedRandomSamplingFacetsCollector, merge each slice's original hits instead of its sample: wrap each slice's getOriginalMatchingDocs() in a plain FacetsCollector and pass those to reduceMatchingDocs, which still merges partitions of one segment. The repro, upstream TestRandomSamplingFacetsCollector and the whole facet suite pass, assertions on and off.
      super(sampleSize, seed);
-      this.getOriginalMatchingDocs()
-          .addAll(FacetsCollectorManager.reduceMatchingDocs(facetsCollectors));
+      // Reduce the per-slice ORIGINAL hits: getMatchingDocs() of a slice collector returns that
+      // slice's own sample, and this collector samples the reduced hits again.
+      List<FacetsCollector> originals = new ArrayList<>(facetsCollectors.size());
+      for (RandomSamplingFacetsCollector fc : facetsCollectors) {
+        FacetsCollector original = new FacetsCollector(false);
+        original.getMatchingDocs().addAll(fc.getOriginalMatchingDocs());
+        originals.add(original);
+      }
+      this.getOriginalMatchingDocs().addAll(FacetsCollectorManager.reduceMatchingDocs(originals));
All options and trade-offs3 options · 706 words
Both validated fixes restore the one-slice numbers in every repro: the same sample sizes, rates and counts. Which documents a fixed seed picks can still differ from one slice, because the merge iterates a hash map of segments. Both were validated through gradle on main only (10.x was run with the release jars, without a fix), and neither was benchmarked. Workaround until a fix ships: run sampled facet collection on an IndexSearcher without an executor, which every test's control shows to be correct, or make sure the search has one slice, for which reduce returns the one collector unchanged (RandomSamplingFacetsCollector.java:279-281). The new test is a ready regression test. Open draft PR #16847 touches both files but not the merge. Only query-time results change; no reindex.
RandomSamplingFacetsCollector.java:291-292, the finder's sketch, +9/-2 lines in one file: wrap each slice's getOriginalMatchingDocs() in a plain FacetsCollector and give those to FacetsCollectorManager.reduceMatchingDocs, which keeps merging partitions of one segment.
      super(sampleSize, seed);
-      this.getOriginalMatchingDocs()
-          .addAll(FacetsCollectorManager.reduceMatchingDocs(facetsCollectors));
+      // Reduce the per-slice ORIGINAL hits: getMatchingDocs() of a slice collector returns that
+      // slice's own sample, and this collector samples the reduced hits again.
+      List<FacetsCollector> originals = new ArrayList<>(facetsCollectors.size());
+      for (RandomSamplingFacetsCollector fc : facetsCollectors) {
+        FacetsCollector original = new FacetsCollector(false);
+        original.getMatchingDocs().addAll(fc.getOriginalMatchingDocs());
+        originals.add(original);
+      }
+      this.getOriginalMatchingDocs().addAll(FacetsCollectorManager.reduceMatchingDocs(originals));
Trade-offs
- One throwaway
FacetsCollectorper slice. It relies onFacetsCollector.getMatchingDocs()returning its own mutable list, as the plainFacetsCollectorManagerreduce already does. - Side benefit: nothing asks the slice collectors for a sample any more, so the per-slice sampling work (a bit set per segment per slice) disappears.
- The merged collector samples once, with its bins running over the merged segments in hash-map order, as today.
What the checks validated
- Scratch worktree of
a9779ef3c193, gradle, JDK 25: the new test fails 3 of 3 on stock with assertions on and off; with the fix, the new test and upstreamTestRandomSamplingFacetsCollectorpass 4 of 4, on and off, andTestRandomSamplingFacetsCollectorpasses 20 of 20 iterations; the whole:lucene:facet:testpasses, 40 suites and 309 tests, 0 failures, with assertions on (7 skipped) and off (8 skipped);:lucene:facet:check -x test(google-java-format, ecj lint, forbidden-apis) passes. - Standalone runner with the fix shadowed: the new test 3 of 3 (
-ea,-da), printing the one-slice numbers for every several-slice search. The same sketch already passed the finder's, the independent reproducer's, the second verifier's and the devil's advocate's tests, the adjudication's re-run and upstreamTestRandomSamplingFacetsCollector(2 seeds).
+19/-3 lines over FacetsCollectorManager.java (+15/-2) and RandomSamplingFacetsCollector.java (+4/-1): an overload of the package-private helper that takes the accessor (the old signature delegates with FacetsCollector::getMatchingDocs), and the sampler's merge passing RandomSamplingFacetsCollector::getOriginalMatchingDocs.
   static Collection<FacetsCollector.MatchingDocs> reduceMatchingDocs(
       final Collection<? extends FacetsCollector> facetsCollectors) {
+    return reduceMatchingDocs(facetsCollectors, FacetsCollector::getMatchingDocs);
+  }
+
+  static <C extends FacetsCollector> Collection<FacetsCollector.MatchingDocs> reduceMatchingDocs(
+      final Collection<? extends C> facetsCollectors,
+      final Function<? super C, List<FacetsCollector.MatchingDocs>> matchingDocsOf) {
     ...
-    for (FacetsCollector facetsCollector : facetsCollectors) {
-      for (FacetsCollector.MatchingDocs matchingDocs : facetsCollector.getMatchingDocs()) {
+    for (C facetsCollector : facetsCollectors) {
+      for (FacetsCollector.MatchingDocs matchingDocs : matchingDocsOf.apply(facetsCollector)) {

   // RandomSamplingFacetsCollector, ReducedRandomSamplingFacetsCollector:
       this.getOriginalMatchingDocs()
-          .addAll(FacetsCollectorManager.reduceMatchingDocs(facetsCollectors));
+          .addAll(
+              FacetsCollectorManager.reduceMatchingDocs(
+                  facetsCollectors, RandomSamplingFacetsCollector::getOriginalMatchingDocs));
Trade-offs
- Makes the dependency explicit for any future subclass whose
getMatchingDocs()is not the collected set, and avoids fix A's per-slice wrapper collectors (it adds aFunctioncall per collector instead). - Touches the shared helper (package-private, so no public API change) instead of one file.
What the checks validated
- Same worktree, gradle: the new test and upstream
TestRandomSamplingFacetsCollectorpass 4 of 4; the whole:lucene:facet:testpasses, 40 suites and 309 tests, 0 failures (assertions on);:lucene:facet:check -x testpasses. - Standalone runner: the new test 3 of 3 (
-ea,-da), the finder's test 2 of 2, the independent reproducer's 3 of 3 and the devil's advocate's probe 1 of 1.
Putting back the 9.x loop over getOriginalMatchingDocs() restores the numbers for whole-segment slices, which shows the cause.
Trade-offs
It drops the partition merge #13542 needed: with intra-segment partitions the merged collector would again hold several MatchingDocs for one segment, the failure #13542 fixed. Not proposed.
Products that show or threshold sampled facet counts from a concurrent searcher (for example, hiding values below a minimum count) under-report them silently; which documents match, and the index, are unaffected.
Code reading. Checking which shared helpers call methods that subclasses override, an AI hunting AI tool saw that the merge step reads the sampling collector's overridden getMatchingDocs(), and git history showed that #13542 had replaced getOriginalMatchingDocs() there. A public-API JUnit comparing one slice with several confirmed it.
The method in full151 words
Method: code reading (the hunt's "non-formal" tier), a hunt unit ("override-hook and accessor-bypass inventory"), 2026-10-27, stock main jars.
- While checking each documented option on every entry path, here the sequential collector against the
CollectorManagerpath of the facet collectors, the hunting AI tool saw thatreduceMatchingDocscalls the overridable accessorgetMatchingDocs(), whichRandomSamplingFacetsCollectoroverrides to sample.git log -Son both spellings of the merge showed that #13542 replacedgetOriginalMatchingDocs()with that call. - It wrote a differential public-API JUnit (the same manager on a one-slice and a several-slice searcher) and a bounded matrix over the real classes (755 cells, 0 contradictions with the prediction derived from the code, on main and with the fix).
- Then independent AI tools reproduced, reviewed and judged it (see the checks); the devil's advocate added the
getOriginalMatchingDocs()symptom and the small-segment default-slicing trigger, and this doc's test combined the three triggers into one upstream-ready class.
No prior report found (2026-10-27): about 170 logged queries and checks over GitHub, four mailing lists, JIRA, downstream repositories and the web, plus the changed files of all 408 open PRs. Nearest: #13542, which introduced it, and LUCENE-10484 (#11520), whose design says the merge must use getOriginalMatchingDocs.
Searches4 searches
No issue, PR, review comment, commit, JIRA ticket, list thread, downstream report or web page found reports that createManager samples the slice samples a second time, that its several-slice sample is too small, or that its amortized counts come out low. Not fixed upstream: no commit touched RandomSamplingFacetsCollector.java since fafd6af004e on main, branch_10x or branch_10_5, and CHANGES.txt has no entry for a fix (it lists only LUCENE-5476, which added the sampler, LUCENE-10484 and GITHUB#13542; 2026-10-27).
Nearest items, none of them a report: #13542 (introduced it; its PR body names createManager only for the partition merge); #11520 / #765 (LUCENE-10484, the design and the correct first merge); open draft #16847 (long doc ids, touches both files, leaves the merge unchanged); #6539 (LUCENE-5476, the sequential sampler); #11041, #240, #13503, #12474, #13745, #13753 (CollectorManager migration and partition concurrency, no sampling). Gaps: keyword search only; inline review threads read in full only for #13542 and #765; private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene) | 2026-10-27 | two scripted prior-report search runs (51 queries each) plus the finder's (45), and 25 manual searches: class and method names (RandomSamplingFacetsCollector, createManager, reduceMatchingDocs, getOriginalMatchingDocs), symptoms and labels; 16 items read in full | no report; the items listed above |
| Open PRs | 2026-10-27 | 4 text searches; the changed files of all 408 open apache/lucene PRs, plus the full 438-file list of draft #16847 | #16847 is the only open PR that touches both files; it leaves the merge unchanged. #13334 touches FacetsCollectorManager.java only (a keepScores constructor), unrelated to sampling |
| Mailing lists and JIRA | 2026-10-27 | dev@, java-user@, issues@ and commits@ through the tool runs, plus 12 direct archive queries; the JIRA archive through the tool runs | no report; two java-user@ threads on sampling (2015, 2024) without concurrency |
| Downstream repositories and web | 2026-10-27 | Elasticsearch, OpenSearch, Solr, Lucene.NET and all of GitHub; 8 web searches | no report; no issue in Elasticsearch, OpenSearch or Solr mentions the collector |
Introduced by #13542 (fafd6af004e, merged 2024-09-10), first released in 10.0.0. All 12 releases from 10.0.0 to 10.5.2 and main fail; all 19 releases from 9.2.0, where createManager appeared, to 9.12.3 pass. Restoring only that hunk's old text makes the repro pass. Not fixed upstream.
Versions tested6 rows
A regression. createManager came with LUCENE-10484 (#765, 7ed0f3d7adb on main, 2022-04-05; first released in 9.2.0 through its branch_9x commit b0ecba4fb24), whose merge added each collector's getOriginalMatchingDocs(). Introduced by #13542 "Add support for intra-segment search concurrency" (@javanna, fafd6af004e, merged 2024-09-10 on main, not backported to branch_9x), which replaced that loop with FacetsCollectorManager.reduceMatchingDocs(facetsCollectors), a helper of the same commit that reads getMatchingDocs(). git blame gives RandomSamplingFacetsCollector.java:291-292 and FacetsCollectorManager.java:102 to that commit, and git tag --contains starts at 10.0.0. RandomSamplingFacetsCollector.java is the same blob in fafd6af004e, in all 12 10.x releases and at main. Not executed: the parent commit and fafd6af004e as full source builds (only the one hunk was swapped back).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's test: 3 of 3 fail (gradle and the standalone runner, assertions on and off); the one-slice controls are correct |
| 10.0.0, 10.1.0, 10.2.0, 10.2.1, 10.2.2, 10.3.0, 10.3.1, 10.3.2, 10.4.0, 10.5.0, 10.5.1, 10.5.2 | affected | the finder's test: 2 of 2 fail with identical numbers (-da too on 10.0.0 and 10.5.2); this doc's test: 3 of 3 fail on 10.5.2 and 10.0.0 |
| 9.2.0 to 9.12.3 (19 releases) | not affected | the 9.x variant of the finder's test passes 2 of 2 (-da too on 9.12.3): several slices give the one-slice sample |
| 9.1.0 | no API | createManager does not exist (compile error) |
| 10.0.0 and main with only the #13542 hunk restored | cause check | the finder's test passes 2 of 2 |
| main + fix A or fix B | not affected | every repro passes; upstream TestRandomSamplingFacetsCollector and the whole facet suite pass |
An independent reproducer, a devil's advocate and an adjudication found it real with their own executed tests; read-only reviews by another model family agreed on the root cause, one with a procedural "not real" because it could not run Java. The adjudication confirmed it with high confidence, and this doc's test reproduced it on main, 10.5.2 and 10.0.0.
Checks and verdicts541 words
Every check that ran code used stock jars with assertions on and off. The reviews by the other model family were read-only (they could not execute code); separate runs re-ran the finder's test for them, and it failed as claimed.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Public-API JUnit fails 2 of 2 on main (-ea, -da), 10.5.2 and 10.0.0; the 9.x variant passes on 9.12.3; the fix sketch passes; a 755-cell matrix over the real classes matches the prediction with and without the fix. |
| cross-model review, refute lens | not real (low, procedural) | OpenAI GPT-5.6, read-only: could not run Java and may not say real without its own run; agreed with the root cause and rated its own counter-argument weak; a separate re-run failed 2 of 2. |
| Independent reproducer | real | Own test in a foreign package: default slicing on 4 x 2^18 documents (64 sampled instead of 4,096) and 4 partitions of one segment (64 instead of 1,024); the control passes; 10.5.2 and 10.0.0 fail, 9.12.3 passes; the fix passes 3 of 3. |
| Cross-model review, intended lens | real (medium) | OpenAI GPT-5.6, read-only: the intended case is weak and the inputs are in contract; the verifier's own JUnit fails 2 of 2 on main and passes with the fix; corrected the claim that #13542 never names createManager. |
| Devil's advocate | real (high) | Rejected the preferred-size, experimental-API and deliberate-reuse case; found that getOriginalMatchingDocs() returns only the samples (2,000 of 20,000) and that default slicing on 10 small segments triggers it. |
| adjudication | confirmed (high) | Re-ran the independent reproduction's test with a new seed: 2 of 3 fail with -ea and -da, 3 of 3 pass with the fix; upstream TestRandomSamplingFacetsCollector passes with the fix (2 seeds). |
| security assessment | none | Application configuration triggers it; counts only go down, the sample stays a subset of the query's hits, and the work goes down, not up. |
| registry re-runs and audit | keep | Fresh seeds on main: the finder's test fails 2 of 2 (-ea, -da) and passes with the fix; the independent reproduction's fails 2 of 3 and passes 3 of 3 with the fix; a fourth independent re-run kept the score. |
| this doc's validation | reproduced, both fixes validated | New 3-test class: 3 of 3 fail on main (gradle and standalone, -ea and -da), 10.5.2 and 10.0.0; with fix A or B it passes, and so do upstream TestRandomSamplingFacetsCollector, the whole facet suite and :lucene:facet:check. |
| doc fact checks and diagram check | holds after wording fixes | An independent fact check re-ran the gradle repro (assertions on, off, random seed), the standalone runs on main, 10.5.2 and 10.0.0, both fixes and the facet suite, and found one overclaim, now fixed: with unequal slices only the hits of slices with at least about 2 x sampleSize hits are thinned (its probe). A read-only cross-model fact check and a pixel-level diagram check confirmed the mechanism, the numbers and the history; their wording corrections are applied. One suggestion was not taken: to mark the bug as known because the 2022 design issue states the rule this regression breaks (that issue predates the bug and reports no defect). |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 483 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,483 words
- Registry title
- RandomSamplingFacetsCollector.createManager samples the hits twice when a search has more than one slice: the reduce reads each slice's already-sampled getMatchingDocs() as its original hits, so the sample is far too small and every amortized facet count is biased low (regression from #13542, 10.0.0 onward)
- Area
- facet / sampling (RandomSamplingFacetsCollector.createManager reduce, FacetsCollectorManager.reduceMatchingDocs)
- Priority
- Medium, rank 168: Released 10.0 regression that silently makes amortized facet counts 8x to 64x too low on ordinary sampled queries once facet sampling meets an executor with two or more slices, which is worse than the single-opt-in, up-to-2x LFV-437, so it heads the facet-count rows just above LFV-303.
- Impact class
- silent wrong results
- Impact note
- Hits applications that opt in to facet sampling through RandomSamplingFacetsCollector.createManager on an IndexSearcher with an executor, on every sampled query whose search has 2 or more slices (or intra-segment partitions) with a slice of at least about 2 x sampleSize hits; default slicing gives 2 or more slices to any index with more than 5 segments or with several segments above 250,000 docs, so no extreme scale is needed: the sample shrinks to about sampleSize^2 x numSlices / totalHits, getSamplingRate() reports only the second-stage rate, and every amortized count comes out low by the hidden per-slice ratio (8x to 64x low in the repros), with no error, -ea and -da alike; a searcher without an executor uses one slice and is correct; every release from 10.0.0 to 10.5.2 and main [exec], 10.6.0 by reading, 9.12.3 correct [exec].
- Summary
- You count facets on a sample of a large result set with RandomSamplingFacetsCollector.createManager(sampleSize, seed) on an IndexSearcher that has an executor, and expect what a one-slice search gives: about sampleSize sampled hits, taken at the rate sampleSize / totalHits that getSamplingRate() reports, so that amortizeFacetCounts estimates the real counts. Instead, with two or more slices the reduce fills the reduced collector's original hits from FacetsCollectorManager.reduceMatchingDocs, which calls each slice collector's getMatchingDocs(), the accessor RandomSamplingFacetsCollector overrides to return that slice's sample; the reduced collector then samples those samples again. The sample shrinks to about sampleSize^2 x numSlices / totalHits and every amortized count is low by the per-slice ratio, with no error: 2 segments of 1,024 matching docs with sampleSize 128 and one slice per segment give 16 sampled hits and an amortized count of 256 instead of 128 and 2,048, and default slicing on 2 segments of 262,144 docs with sampleSize 4,096 gives 64 sampled hits and 8,192 instead of 4,096 and 524,288.
- Introduced
- fafd6af004e0c39582043b797555d6eeb9aa7638, apache/lucene#13542 'Add support for intra-segment search concurrency' (javanna; closes #9721; not backported to branch_9x): it replaced the reduce over each collector's getOriginalMatchingDocs() (7ed0f3d7adb, LUCENE-10484 / #765, first released in 9.2.0, correct) with FacetsCollectorManager.reduceMatchingDocs(facetsCollectors), a new helper of the same commit that loops over the overridable, sampled getMatchingDocs() [exec: release bracket 9.12.3 pass / 10.0.0 fail, and shadowing only that hunk back to the parent commit's text makes the repro pass on the 10.0.0 jars and on main; read: git blame of RandomSamplingFacetsCollector.java:291-292 and FacetsCollectorManager.java:102 on main, git log -S on both reduce spellings]. A regression; the parent commit itself was not built (2024-09-10)
- First affected version
- 10.0.0 [exec: fails with -ea and -da]; 9.12.3, the last 9.x release, is correct [exec: passes with -ea and -da]; createManager first shipped in 9.2.0 with a correct reduce [exec: all 19 releases 9.2.0..9.12.3 pass]; 9.1.0 has no createManager [exec: compile error]
- Affected versions
- Every release from 10.0.0 to 10.5.2, 10.6.0 (by reading), and main a9779ef3c193; not fixed upstream. [exec] The finder's repro fails with identical numbers on all 12 releases 10.0.0, 10.1.0, 10.2.0, 10.2.1, 10.2.2, 10.3.0, 10.3.1, 10.3.2, 10.4.0, 10.5.0, 10.5.1 and 10.5.2 (-da also on 10.0.0 and 10.5.2) and on main (-ea and -da); the independent reproduction's own test fails on 10.0.0, 10.5.2 and main; the intended-behaviour check's probe fails on 10.5.2 and main. Not affected [exec]: 9.2.0 through 9.12.3 (19 releases; the 9.x API variant gives the same sample for 2 slices as for one), and 9.1.0 and older (no createManager). [read] RandomSamplingFacetsCollector.java is the same blob (32cda39b013) in fafd6af004e, in all 12 10.x releases, on the branch_10x, branch_10_6 and branch_10_5 heads (refs fetched 2026-10-24) and at main a9779ef3c193; no commit has touched it since fafd6af004e on main, branch_10x or branch_10_5 (GitHub commit history read 2026-10-27), and CHANGES.txt on upstream main a95c754ee00 has no fix entry.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (2026-10-27, read-only; the prior-report record, verdict new): about 170 logged queries and checks: two scripted prior-report searches (51 queries each over GitHub issues and PRs, commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web) plus the finder's run (45 queries); 25 manual GitHub searches (apache/lucene, all of GitHub, Elasticsearch, OpenSearch, Solr, Lucene.NET); 4 open-PR text searches, a changed-file sweep of all 408 open apache/lucene PRs and the full 438-file list of draft #16847; the commit history of the three files on main, branch_10x and branch_10_5; CHANGES.txt; 12 direct lists.apache.org queries; 8 web searches; 16 issues, PRs and threads read in full; none reports the bug. Closest items, the cause and the design rather than reports: #13542 (javanna, merged 2024-09-10) introduced it; its PR body names 'RandomSampligFacetsCollector#createManager' only as returning several MatchingDocs per leaf, the reason for the partition merge, and no comment or review discusses sample size or rate; #11520 / #765 (LUCENE-10484, 2022) designed createManager and states 'the reduction should call getOriginalMatchingDocs instead of getMatchingDocs'; open draft #16847 touches both files for long doc ids but leaves the reduce unchanged; #6539 (LUCENE-5476) is the original sequential sampler; #13503, #12474, #13745, #13753 (facet and partition concurrency) never mention sampling. Not fixed upstream: no commit on RandomSamplingFacetsCollector.java since fafd6af004e on main, branch_10x or branch_10_5, and no CHANGES.txt entry. Gaps: keyword-based search; inline review threads read in full only for #13542 and #765; private channels not searchable
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-27) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the 10.5.2 and 10.0.0 release jars (this doc's test). The follow-up ran the finder's test on all 12 releases from 10.0.0 to 10.5.2 and its 9.x variant on all 19 releases from 9.2.0 to 9.12.3; the cross-model reviews readea57360912ed, whose facet module is identical. Both fixes were validated in the scratch worktree: this doc's test, upstreamTestRandomSamplingFacetsCollector(also 20 iterations with fix A), the wholelucene/facetsuite (assertions on and off with fix A, on with fix B) and:lucene:facet:check -x test.
- Finding record
lucene/facet/src/java/org/apache/lucene/facet/RandomSamplingFacetsCollector.java:32-41 (class javadoc: 'If you require the original set of hits, you can call getOriginalMatchingDocs()', amortizeFacetCounts), :94-102 (sampleSize javadoc: 'preferred sample size', 'a sample ratio of sampling size / totalN'), :111-141 (getMatchingDocs override returning the sample once totalHits > sampleSize), :143-146 (getOriginalMatchingDocs), :255-259 (getSamplingRate: 'the sampling rate that was used'), :261-285 (createManager: 'for concurrent random sampling'; reduce returns the single collector for one slice), :287-293 (ReducedRandomSamplingFacetsCollector fills its original docs from FacetsCollectorManager.reduceMatchingDocs(facetsCollectors)) @ a9779ef3c193lucene/facet/src/java/org/apache/lucene/facet/FacetsCollectorManager.java:93-113 (reduceMatchingDocs; line 102 iterates facetsCollector.getMatchingDocs()) @ a9779ef3c193lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:106-108 (MAX_DOCS_PER_SLICE 250,000, MAX_SEGMENTS_PER_SLICE 5), :226-231 (no executor: one slice over all leaves) @ a9779ef3c193upstream apache/lucene#13542, #11520, #765, #16847 (read-only, as cited in the prior-report record and)
- The finding in 30 seconds
lucene/facet/src/java/org/apache/lucene/facet/RandomSamplingFacetsCollector.java:118-146, :164, :209, :240, :269-282, :287-294 @ a9779ef3c193lucene/facet/src/java/org/apache/lucene/facet/FacetsCollectorManager.java:93-114 (line 102) @ a9779ef3c193lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:106, :108 (MAX_DOCS_PER_SLICE, MAX_SEGMENTS_PER_SLICE), :226-231 (no executor: one slice), :323-390 (slices; descending sort :351, group closes at :375 after docSum += maxDoc at :374) @ a9779ef3c193
- Who is affected
lucene/facet/src/java/org/apache/lucene/facet/taxonomy/FastTaxonomyFacetCounts.java:57; lucene/facet/src/java/org/apache/lucene/facet/sortedset/SortedSetDocValuesFacetCounts.java:75 @ a9779ef3c193lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:199-201 (@lucene.experimental executor constructor), :634-638 (deprecated search(Query, Collector)) @ a9779ef3c193lucene/MIGRATE.md:1050-1054 (LUCENE-10002)lucene/facet/src/java/org/apache/lucene/facet/RandomSamplingFacetsCollector.java:38 (getOriginalMatchingDocs promise) @ a9779ef3c193lucene/demo/src/java/org/apache/lucene/demo/facet/package-info.java:383-385 @ a9779ef3c193lucene/facet/src/java/org/apache/lucene/facet/RandomSamplingFacetsCollector.java:132-134 (no sampling at or below sampleSize), :164 (binSize), :279-281 (one collector returned as is) @ a9779ef3c193
- Why it looks unintended
lucene/facet/src/java/org/apache/lucene/facet/RandomSamplingFacetsCollector.java:38-40, :97-100, :256, :261-264 @ a9779ef3c193lucene/facet/src/test/org/apache/lucene/facet/TestRandomSamplingFacetsCollector.java:96, :133, :135-148 @ a9779ef3c193lucene/facet/src/java/org/apache/lucene/facet/FacetsCollector.java:76-79 (getMatchingDocs javadoc); lucene/facet/src/java/org/apache/lucene/facet/RandomSamplingFacetsCollector.java:162 (new FixedBitSet(maxdoc) per sampled segment) @ a9779ef3c193
- Suggested fix
lucene/facet/src/java/org/apache/lucene/facet/FacetsCollectorManager.java:82 (ReducedFacetsCollector adds to getMatchingDocs()), :100 and :113 (the merge returns HashMap values) @ a9779ef3c193lucene/facet/src/java/org/apache/lucene/facet/RandomSamplingFacetsCollector.java:279-281 (one collector returned unchanged: the one-slice workaround) @ a9779ef3c193upstream apache/lucene#13542 PR body item 2 (TestStringValueFacetCounts failures; read-only, 2026-10-27)
- Prior reports
lucene/CHANGES.txt:2315 (GITHUB#13542), :4203-4204 (LUCENE-10484), :12433 (LUCENE-5476) @ a9779ef3c193
- TestSamplingManagerTwoSlices.java (JUnit test):
repro/LFV-765/src/org/apache/lucene/facet/TestSamplingManagerTwoSlices.java(68 lines)
The PNG is the still.
assets/LFV-765/bug.png(483 KB)