matchhighlight's PassageSelector ends the passage of a value without matches, and cuts a match longer than the window, at from + window UTF-16 units. Its word adjuster then moves the end back to a word boundary, but when the first word is longer than the window there is none, so it keeps the raw end. Nothing checks for surrogate pairs.
- Java strings count UTF-16 units. Most characters take one; a supplementary character (mathematical bold letters such as 𝐋, Deseret, Adlam, CJK Extension B ideographs, emoji) takes two, a high half and a low half, called a surrogate pair. Either half alone is not text.
- matchhighlight's
FieldValueHighlighters.maxLeadingCharacters(n, ...)shows up to the firstnunits of a value;highlighted(n, ...)shows passages of up tonunits around matches. Both use aPassageSelectorwith aBreakIteratorShrinkingAdjuster. - The selector picks a raw window of
nunits, and the adjuster shrinks its edges to word boundaries. When a word is longer than the window, a cut inside the word is the accepted behaviour (upstream tests pin01234...for window 5).
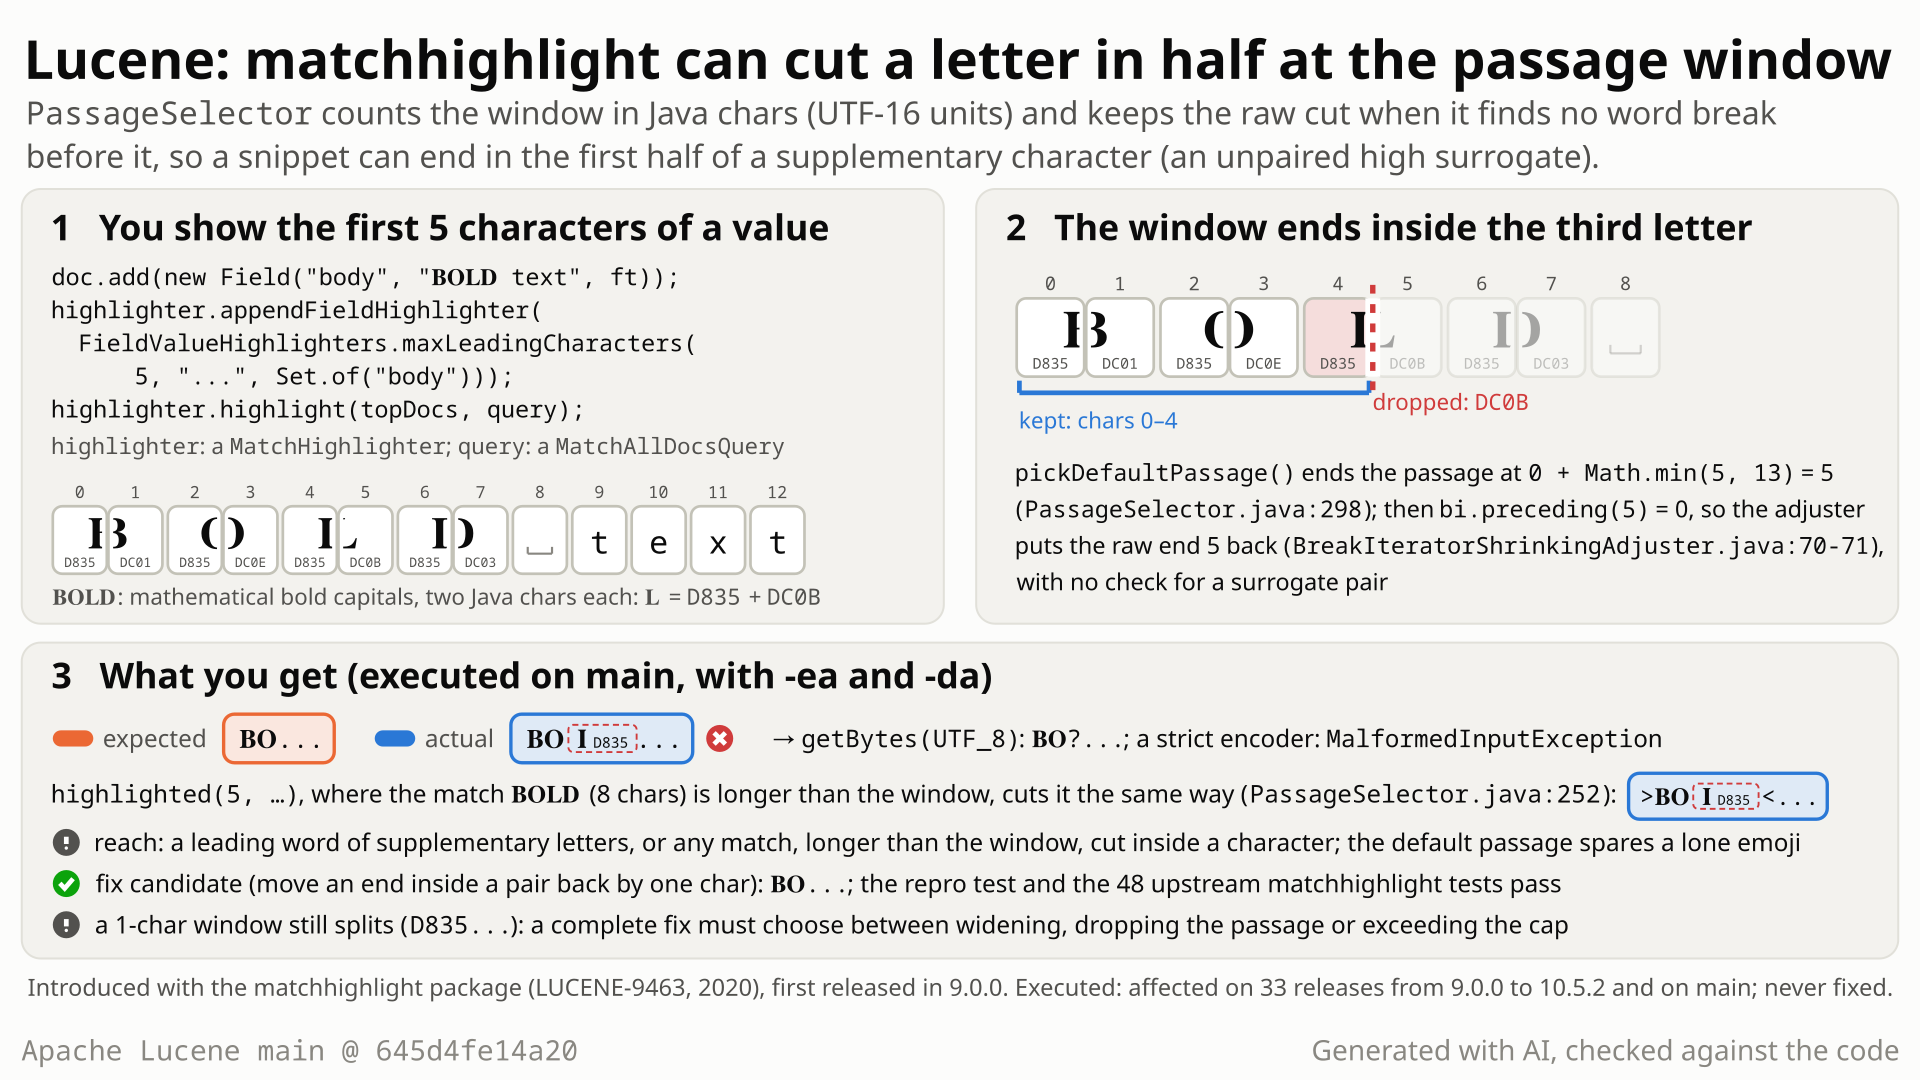
𝐁𝐎𝐋𝐃 text as UTF-16 units, the 5-unit window that ends between the two halves of 𝐋, and the snippet that ends in the lone first half; the fix ends the window before 𝐋. Select the still to open it at full size. Generated with AI, checked against the code.- You highlight the stored value
𝐁𝐎𝐋𝐃 textwith matchhighlight'sFieldValueHighlighters.maxLeadingCharacters(5, "...", fields). The bold letters are mathematical bold capitals, two UTF-16 units each, so the word takes units 0-7 and its third letter, 𝐋, units 4-5. - You expect at most 5 units of whole characters,
𝐁𝐎..., just as the ASCII valueboldtext textis cut inside its first word but between letters:boldt.... - The default passage is units [0, 5). The word adjuster finds no word boundary inside the bold word, so it keeps the raw end 5, which falls between the two halves of 𝐋.
- You get
𝐁𝐎\uD835..., with no error.getBytes(UTF_8)makes it𝐁𝐎?...and a strict UTF-8 encoder throwsMalformedInputException. Hits and scores are right. highlighted(5, ...)does the same to a match longer than the window: aTermQueryon the bold word gives>𝐁𝐎\uD835<....
Applications that build snippets with matchhighlight's FieldValueHighlighters (the default selector and adjuster) on text with supplementary characters: a first word of supplementary letters longer than the window, or one match longer than the window, with the cut mid-pair. Small windows such as 10 hit it easily. Hits and scores stay right; one character breaks.
Mechanism, terms and numbers690 words
matchhighlight's PassageSelector measures its passage window in UTF-16 units. The passage of a value without matches (what FieldValueHighlighters.maxLeadingCharacters shows) ends at from + window, and a match longer than the window (in highlighted) is cut at from + window. The default BreakIteratorShrinkingAdjuster then moves the end back to a word boundary, but when the first word is longer than the window there is none, so it keeps the raw end, and it never moves the end of a cut match. Nothing checks for surrogate pairs. When the raw cut falls between the two halves of a supplementary character, the snippet ends in a lone high surrogate: 𝐁𝐎𝐋𝐃 text (mathematical bold capitals, two units each) with window 5 gives 𝐁𝐎\uD835... and >𝐁𝐎\uD835<..., while the ASCII value boldtext text gives boldt... and >boldt<....
getBytes(UTF_8) turns the half into ?, and a strict UTF-8 encoder throws. Hits, scores and the other highlight positions are right. The reach through the default adjuster is narrow: a first word of supplementary letters longer than the window, or one match longer than the window, with the cut mid-pair; a single emoji between BMP text gets its own word boundaries, so the default passage does not cut it (inside a match longer than the window it can be cut). Present since 9.0.0 and never fixed. Moving such an edge to the character boundary fixes it, and the whole highlighter test task passes with that fix.
maxLeadingCharacters(n, ellipsis, fields): "Displays up to maxLeadingCharacters of the field's value, regardless of whether it contained highlights or not" (FieldValueHighlighters.java:52-55). It callsdefaultPassageSelector().pickBest(value, [], n, 1, valueRanges)(:68-70).highlighted(maxPassageWindow, maxPassages, formatter, fields): passages around matches (:88-115), the same selector, with the query's match offsets (:108-110).defaultPassageSelector():new PassageSelector(PassageSelector.DEFAULT_SCORER, new BreakIteratorShrinkingAdjuster())(:82-86); the adjuster usesBreakIterator.getWordInstance(Locale.ROOT)(BreakIteratorShrinkingAdjuster.java:30-32).- For a single-valued field
MatchHighlighterpasses the value and one range[0, length)(MatchHighlighter.java:260-266, withcontiguousFieldValueandcomputeValueRangesat:276-299), which is what the 4-argumentpickBestdoes (PassageSelector.java:67-74).
- Path 1, no matches. No marker enters the queue, so
pickDefaultPassageruns (PassageSelector.java:170-175) and returnsnew Passage(o.from, o.from + Math.min(maxCharacterWindow, o.length()), ...)(:293-299):[0, 5). - Path 2, a match longer than the window.
splitOrTruncateToWindowscuts the marker:if (to - from > maxPassageWindow) { to = from + maxPassageWindow; ... }(:251-254), so[0, 8)becomes[0, 5); the centred window around it (:128-141) is[0, 5)too. - The adjuster keeps the raw end. For the end it loops
to = bi.preceding(to)whiletois not a word boundary (BreakIteratorShrinkingAdjuster.java:63-69); when that reaches 0 it restores the raw end,if (to == 0) { to = passage.to; }(:70-72). Inside a word of supplementary lettersisBoundaryis false andpreceding()is 0 at every offset (an independent probe on a Deseret word). It then widens the passage to its markers' ends (:75-78), so a cut marker's end stays as well. - The formatter copies the range.
PassageFormatter.formatappendsvalue[from, to)(PassageFormatter.java:110-125) and the ellipsis when the passage ends before the value (:87-89):𝐁𝐎\uD835..., or>𝐁𝐎\uD835<...with markers. - No check. A case-insensitive grep of the package sources for
surrogate,codepointandcode pointfinds nothing, and the package history never had such a check.
Which windows split. In a run of two-unit characters starting at unit 0 every character starts at an even unit, so an odd window ends inside one and an even window does not (sweep over Deseret, mathematical bold and CJK Extension B words: every odd window shorter than the word splits).
Centred windows. The centred-window arithmetic (PassageSelector.java:128-141) can also put an edge inside a pair, and the adjuster restores a raw start edge too (BreakIteratorShrinkingAdjuster.java:56-58). With the default adjuster the sweep found no split from those lines; a PassageSelector without an adjuster (new PassageSelector(), as TestPassageSelector uses) keeps any raw edge.
Exposure and likelihood361 words
- Who is hit.
MatchHighlighterwithFieldValueHighlighters.maxLeadingCharactersorhighlighted, which use the defaultPassageSelectorandBreakIteratorShrinkingAdjuster, orPassageSelectorused directly. matchhighlight is an opt-in alternative to the UnifiedHighlighter; within it, the trigger is the ready-made default configuration, with the default codec, writer config and searcher. A code search found matchhighlight in none of Solr, Elasticsearch and OpenSearch; maintainers want to keep the package (#16820). - Which text. Path 1: the value starts with a word, as the JDK word iterator sees it, longer than the window and made of supplementary letters: mathematical "styled" letters as pasted into posts, Deseret, Adlam, Osage, or consecutive CJK Extension B ideographs, possibly mixed with BMP letters. Path 2: one match longer than the window, which also covers CJK text and emoji (a long match over Han text with U+20000 splits; a phrase match over
Hello 😀 worldwith window 7 gives>Hello \uD83D<...). The cut must land mid-pair: for a run of such characters that starts at an even unit, as a leading word does, any odd window; for a match it depends on where the match starts. - Not hit by the default passage (path 1). A single emoji or a single supplementary ideograph between BMP text: the word iterator puts boundaries around each one, so the adjuster moves the end off it. Inside a match longer than the window (path 2) it can still be cut.
- Window sizes. Small windows hit it easily: the upstream test uses
maxLeadingCharacters(10, ...), and a value that starts with the one word Hello + 𝐁𝐎𝐋𝐃 + world splits at window 10. Windows of 100 or more units need very long such words or matches. - Effect. One malformed character at the end of the snippet or of the cut match.
getBytes(UTF_8)gives?and a strict UTF-8 encoder throwsMalformedInputException(executed); other encoders may write U+FFFD or something else (not run). Hits, scores and the other highlight positions are right. - Scale and likelihood. One document, deterministic, assertions on and off. An accidental hit needs the little-used package, such a word or match and an unlucky window; no matching public report was found, and it is graded rare.
One test class with one method, public API only: the default selector that maxLeadingCharacters(5, ...) uses picks the passage of 𝐁𝐎𝐋𝐃 text for window 5, and the test asserts that it does not end between the two halves of a character. No index, no randomness, single thread; it fails with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.matchhighlight;

import java.util.List;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestMatchHighlightWindowSurrogatePair extends LuceneTestCase {

  public void testLeadingPassageDoesNotSplitSurrogatePair() {
    // "BOLD" in MATHEMATICAL BOLD CAPITAL letters (U+1D401 U+1D40E U+1D40B U+1D403, 2 units each)
    String value = "\uD835\uDC01\uD835\uDC0E\uD835\uDC0B\uD835\uDC03 text";
    Passage p =
        FieldValueHighlighters.defaultPassageSelector().pickBest(value, List.of(), 5, 1).get(0);
    assertFalse(
        "expected a passage ending on a code point boundary, actual: " + p,
        Character.isLowSurrogate(value.charAt(p.to)));
  }
}
cp $REPRO/TestMatchHighlightWindowSurrogatePair.java \
   $LUCENE/lucene/highlighter/src/test/org/apache/lucene/search/matchhighlight/
cd $LUCENE && ./gradlew :lucene:highlighter:test \
   --tests org.apache.lucene.search.matchhighlight.TestMatchHighlightWindowSurrogatePair -Ptests.asserts=true
# same failure with -Ptests.asserts=false; the test uses no randomness
- Expected
- A passage that ends on a character boundary, for example
[0, 4)(two whole letters), which the fix returns. - Observed
AssertionError: expected a passage ending on a code point boundary, actual: [[from=0, to=5], markers=[]]; unit 5 is the second half of 𝐋.
More files, environment, full output242 words
The test sits in org.apache.lucene.search.matchhighlight by upstream convention. It calls exactly what maxLeadingCharacters(5, ...) calls for a single-valued field and asserts only the claimed property, so a fix that moves the end back, or widens it to the end of the character, passes (a fix that drops the passage would make get(0) throw). tidy leaves it unchanged. It is also the suggested regression test.
Not asserted here (shown by the checks and the probe): the end-to-end snippets through MatchHighlighter (𝐁𝐎\uD835... and, for a long match with highlighted(5, ...), >𝐁𝐎\uD835<...), the ASCII control (boldt...), and what UTF-8 encoders do with the half character.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; 10.6.0 release jars: fails; 9.0.0 to 10.5.2: the hunt's end-to-end test fails on all 33 releases; with the fix: passes |
|---|---|
| jdk | OpenJDK 25.0.3 |
| os | Linux, aarch64 |
# stock main 645d4fe14a20, gradle, seed DEADBEEF (identical with -Ptests.asserts=false); abridged
TestMatchHighlightWindowSurrogatePair > testLeadingPassageDoesNotSplitSurrogatePair FAILED
    java.lang.AssertionError: expected a passage ending on a code point boundary, actual: [[from=0, to=5], markers=[]]
        at org.apache.lucene.search.matchhighlight.TestMatchHighlightWindowSurrogatePair.testLeadingPassageDoesNotSplitSurrogatePair(TestMatchHighlightWindowSurrogatePair.java:29)
BUILD FAILED

# 10.6.0 release jars, standalone, -ea and -da: the same AssertionError

# end to end (the hunt's test, MatchHighlighter + StandardAnalyzer; all 33 releases 9.0.0-10.5.2 and main)
testMaxLeadingCharacters: snippet has an unpaired surrogate at index 4: '\uD835\uDC01\uD835\uDC0E\uD835...' expected:<-1> but was:<4>
testHighlightedMatchLongerThanWindow: snippet has an unpaired surrogate at index 5: '>\uD835\uDC01\uD835\uDC0E\uD835<...' expected:<-1> but was:<5>

# with the fix (asserts true and false): passage [0, 4); 1 test, 0 failures- "Displays up to" n chars allows
𝐁𝐎...(4 of 5 units); the adjuster's job is "word boundaries", and unit 5 is not even a character boundary. - Upstream tests pin only ASCII cuts inside a word (
01234...); none accepts a split character, and all pass with the fix. - Lucene fixed half-surrogate output as a bug before: TruncateTokenFilter (#15900), SimpleHTMLEncoder (LUCENE-5191).
The full argument292 words
- The budget is "up to".
maxLeadingCharacters"Displays up to maxLeadingCharacters of the field's value" (FieldValueHighlighters.java:52-55).𝐁𝐎...(4 units) meets a 5-unit budget, which is what the fix returns; for any window of 2 or more units such an answer exists. No javadoc defines "characters" or promises whole code points, so the expectation is implied. - The adjuster's job. "A PassageAdjuster that adjusts the Passage range to word boundaries hinted by the given BreakIterator" (
BreakIteratorShrinkingAdjuster.java:22-25,{@link}markup removed). Its raw-end fallback (:70-72) handles a first word longer than the window; on ASCII it gives a cut between characters, which is all the tests pin. - Tests.
TestPassageSelector.noHighlightsexpects01234...for window 5 (:82-84) andhighlightLargerThanWindowexpects>0123<...for an 11-char marker and window 4 (:103-105); none has a supplementary character at the cut.randomizedSanityCheckuses random Unicode but checks only that nothing throws, that no passage is empty and that no empty marker><appears (:338-359); nothing about surrogate pairs. With the fix every matchhighlight test and the whole highlighter test task pass. - Ready to use.
MatchHighlighteris "An example highlighter that combines several lower-level utility classes in this package into a fully featured, ready-to-use component" (MatchHighlighter.java:38-39). - Precedents, fixed as bugs.
CHANGES.txt:1215-1217(10.5.0 Bug Fixes): "GITHUB#15899, GITHUB#15900: Improve TruncateTokenFilter to truncate on codepoints not chars and no longer produce half surrogates."CHANGES.txt:13362-13365(4.5.0 Bug Fixes; the olderHighlighterin the same highlighter module, not matchhighlight): "LUCENE-5191: SimpleHTMLEncoder in Highlighter module broke Unicode outside BMP because it encoded UTF-16 chars instead of codepoints."CHANGES.txt:7496-7497(7.4.0 Bug Fixes): "LUCENE-8325: Fixed the smartcn tokenizer to not split UTF-16 surrogate pairs." - History. Neither the introducing PR (apache/lucene-solr#1750) nor LUCENE-10135 (#11172 / #334) discusses code points.
The devil's-advocate check269 words
The strongest case for "intended" (verifiers and a cross-model review): the whole API works in UTF-16 offsets (OffsetRange, CharSequence), and "characters" naturally means Java chars; the upstream tests pin raw cuts; the raw-end fallback is deliberate; String#substring splits pairs too; the pipeline is pluggable (a custom PassageAdjuster, the protected pickDefaultPassage), and the no-argument PassageSelector() has no adjuster at all. On #15900 @uschindler first took exactly this position: "If it truncates tokens after n utf16 characters, so you may get half surrogates. That's expected. This is exactly the same like if you use String#substring(n,m) in your Java code" (2026-04-02).
Why it fails: the report keeps the UTF-16 budget and the mid-word cut and objects only to a cut inside one character; no javadoc, test or CHANGES entry accepts that; the trigger is the default configuration on well-formed text; and a whole-character answer within "up to N" exists for any window of 2 or more units. #15900 was merged under Bug Fixes, and the same day @uschindler wrote "The old variant produces incorrect tokens. That's right."; the concern Uwe Schindler kept was existing indexes ("you won't find the broken tokens anymore in an existing index"). Lucene did keep the char mode there, as an explicit legacy option ("This may split surrogate pairs.", TruncateTokenFilter.java:52-55; kept "for backwards compatibility", :64-66), so the precedent is a code-point-safe mode added as a bug fix, not a ban on char cuts. A snippet is computed at query time and never indexed, so the backwards-compatibility concern does not apply. An overridable hook does not make the default output intended.
Recommended Move a window edge or a match cut inside a pair to the character boundary (+32/-6 in PassageSelector.java)
In PassageSelector, move a window edge or a match cut that falls inside a two-unit character to the character boundary, never past the match. The repro passes, and so do the matchhighlight tests and the whole highlighter test task (723 tests). Gap: a 1-unit window still splits.
// pickDefaultPassage; the long-match cut and the centred window snap the same way
int end = o.from + Math.min(maxCharacterWindow, o.length());
int snapped = codePointStartAtOrBefore(value, end);
defaultPassages.add(new Passage(o.from, snapped > o.from ? snapped : end, Collections.emptyList()));

private static int codePointStartAtOrBefore(CharSequence value, int i) {
  if (i > 0 && i < value.length()
      && Character.isHighSurrogate(value.charAt(i - 1))
      && Character.isLowSurrogate(value.charAt(i))) {
    return i - 1;
  }
  return i;
}
All options and trade-offs4 options · 706 words
One fix was built and validated through gradle at 645d4fe14a20 (the hunt's fix, re-based and formatted). The other options are listed for comparison.
Move a window edge or a match cut inside a pair to the character boundary (+32/-6 in PassageSelector.java) (validated by the checks) (recommended)
Two small helpers check whether an offset falls between a high and a low surrogate. The default passage end moves back one unit (unless that empties the passage); a too-long match is cut one unit earlier (unless that empties it); the centred window's start moves forward and its end back, never past the marker it was built for. Excerpt:
// pickDefaultPassage; the long-match cut and the centred window snap the same way
int end = o.from + Math.min(maxCharacterWindow, o.length());
int snapped = codePointStartAtOrBefore(value, end);
defaultPassages.add(new Passage(o.from, snapped > o.from ? snapped : end, Collections.emptyList()));

private static int codePointStartAtOrBefore(CharSequence value, int i) {
  if (i > 0 && i < value.length()
      && Character.isHighSurrogate(value.charAt(i - 1))
      && Character.isLowSurrogate(value.charAt(i))) {
    return i - 1;
  }
  return i;
}
Trade-offs
- Known gap: a 1-unit window. When the window is smaller than one supplementary character, snapping back would empty the passage or the match, so the fix keeps the raw edge and still splits (a cross-model reviewer's 1-unit-window test fails with it). A complete fix must choose: widen to the whole character (exceeds the cap by one unit), drop the passage, or keep the split.
- The budget stays in UTF-16 units; output changes only where an edge fell inside a pair, where the passage or the cut match loses one unit at that edge. ASCII and the pinned mid-word cuts are unchanged.
- By construction (the selector snaps before any adjuster runs) it also covers a selector without an adjuster, or with a custom adjuster that keeps raw edges; not run separately. It does not stop a custom adjuster from moving an edge into a pair itself, and it does not snap caller-supplied
permittedPassageRangesor match offsets that already fall inside a pair (the 5-argumentpickBest). splitOrTruncateToWindowsis private, so giving it the value is no API change;pickDefaultPassageis protected, so a subclass that overrides it does not get the fix.- The paste-ready test covers path 1 only; path 2 is covered by the finder's end-to-end test (2 of 2 fail on stock, 0 of 2 with the patch).
- No benchmark was run; the extra work is two
charAtchecks per edge.
What the checks validated
- Scratch worktree at
645d4fe14a20, gradle--no-daemon, seed DEADBEEF unless noted:- stock, paste-ready test only: 1 test, 1 failure, assertions on and off;
- with the patch, the matchhighlight package (
TestPassageSelector,TestMatchHighlighter,TestMatchRegionRetrieverand the repro): 4 classes, 49 tests, 0 failures, assertions on and off; with-Ptests.iters=5(random seeds) 245 tests, 0 failures; - with the patch, the whole
:lucene:highlighter:testtask: 35 classes, 723 tests, 0 failures (assertions on); - the hunt's end-to-end test (both paths): 2 of 2 fail on stock, 0 of 2 with the patch;
ecjLintMain,ecjLintTest,checkGoogleJavaFormat,forbiddenApisMain,forbiddenApisTest: pass.
- Probe with the patch shadowed:
𝐁𝐎...and>𝐁𝐎<...for the bold value, both encode cleanly; the ASCII control staysboldt...and>boldt<.... - Earlier, on
a9779ef3c193: the hunt's and an independent reproducer's tests pass with it, and the 48 upstream matchhighlight tests pass (TestPassageSelectorwith three more seeds).
Make BreakIteratorShrinkingAdjuster move a restored raw edge (:56-58, :70-72) to a character boundary.
Trade-offs
Smaller, but misses the long-match path (the adjuster keeps the passage around its markers, :75-78, and the cut marker itself ends mid-pair) and a selector without an adjuster. Not run.
Measure maxPassageWindow / maxLeadingCharacters in code points instead of UTF-16 units.
Trade-offs
Changes the length of every snippet over supplementary text, against the UTF-16 offsets the whole API uses (OffsetRange, CharSequence); no upstream test covers non-BMP lengths either way, and none needs code points. Not run.
Wrap the FieldValueHighlighter and drop a lone high surrogate before the ellipsis or the end marker of each returned snippet.
Trade-offs
Hides the symptom in one application; shown for completeness. Not run.
What the half character does downstream depends on the application's encoder (in the probe getBytes(UTF_8) gave ? and a strict UTF-8 encoder threw), and a code search found matchhighlight in none of Solr, Elasticsearch and OpenSearch.
Semi-formal. While tabulating which Lucene length parameters are documented in "characters" but counted in UTF-16 units, the hunt ran matchhighlight on text whose ASCII letters were swapped for two-unit Deseret letters: the ASCII value was cut inside a word, its twin inside a character. A public-API test on the stock jars confirmed it.
The method in full155 words
- Signal. The hunt unit's table of documented length units lists the matchhighlight window (
maxPassageWindow,maxLeadingCharacters: named in characters, counted in UTF-16 units in the code). - Metamorphic probes. On the stock jars, a substitution that maps ASCII letters to supplementary letters (Deseret, two UTF-16 units each) should only rename text. For
maxLeadingCharacterson a value whose first word is longer than the window, the ASCII value was cut inside the word (the accepted behaviour) and its image inside a character; a second probe on Chinese text with a CJK Extension B ideograph showed the same forhighlighted()with a match longer than the window. - Bridge. Reading
PassageSelectorandBreakIteratorShrinkingAdjusterlocated the raw cut and the fallback; the finder wrote a public-API JUnit (mathematical bold, both paths) that fails on main, 10.5.2 and 9.12.3 and passes with the fix. It is not a product of the exhaustive harness the unit ran on the UnifiedHighlighter.
No issue, PR, JIRA entry, list mail or web page reports it (searched 2026-10-27, re-checked 2026-11-01). The nearest items are the same pattern fixed elsewhere (TruncateTokenFilter, SimpleHTMLEncoder). Upstream main still has both cut lines.
Searches3 searches
No report of this defect was found. The nearest items show the same pattern in other components, fixed as bugs, or are the origin of the code. Upstream main 2f424fd428da (2026-10-30) keeps both cut lines; the package last changed on 2026-06-14 (#16255, build tooling).
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene), JIRA archive, mailing lists (dev@, java-user@, issues@, commits@), downstream repositories, web | 2026-10-27 | two scripted prior-report search runs (91 and 51 queries), 16 own GitHub phrasings over Lucene, Solr, Elasticsearch and OpenSearch, the package history, git log -S for surrogate handling, full reads of every matchhighlight issue and PR from LUCENE-9439 to #15577, 10 web queries | 25 hits read, none the same bug; precedents only: #15899 / #15900 (TruncateTokenFilter), #6255 (LUCENE-5191), #9372 (LUCENE-8325); origin: #10503, #10504, #11172 / #334 |
| Open PRs | 2026-10-27 | the changed files of all 408 open apache/lucene PRs | #16 and #16847 touch matchhighlight, neither the window code |
| GitHub issues and PRs (apache/lucene), re-check | 2026-11-01 | PassageSelector surrogate, matchhighlight surrogate, maxLeadingCharacters, PassageSelector, BreakIteratorShrinkingAdjuster, highlight unpaired surrogate, match highlighter surrogate, highlighter surrogate pair, highlighter emoji, passage selector, LUCENE-10135 | nothing new: 0 results, or only the known #9448, #10479, #11172 and #334 |
Introduced with the package in 9.0.0 by LUCENE-9463 (150a8dacb59, merged 2020-08-14); the long-match path came with LUCENE-10135 (#334, 2021-09-30). Every release from 9.0.0 to 10.6.0 and main fails; 8.x has no matchhighlight. Not a regression, never fixed.
Versions tested7 rows
Introduced by 150a8dacb59 "LUCENE-9463: Query match region retrieval component, passage scoring and formatting (#1750)" (apache/lucene-solr#1750 by @dweiss, merged into master 2020-08-14; LUCENE-9463 is #10503): pickDefaultPassage with the raw end and the adjuster's raw-end fallback. The long-match cut came with 1bb45548320 "LUCENE-10135: Correct passage selector behavior for long matching snippets (#334)" (2021-09-30); before it such a match was dropped and the default passage split the pair instead, so #334 moved the case to a second path. The public FieldValueHighlighters / MatchHighlighter API came with e2f3f626ee4 (LUCENE-9464, apache/lucene-solr#1820). CHANGES.txt lists LUCENE-9463 and LUCENE-10135 under 9.0.0. From 9.0.0 to main PassageSelector changed only in priority-queue handling, a rename and a passage-count cap; BreakIteratorShrinkingAdjuster is byte-identical.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the paste-ready test fails (through gradle and standalone, assertions on and off) |
| 10.6.0 | affected | the paste-ready test fails, assertions on and off |
| 9.0.0 to 10.5.2 (33 releases) | affected | the hunt's end-to-end test fails 2 of 2 on every release (9.0.0 also with assertions off, old test-framework import) |
main a9779ef3c193 | affected | the hunt's test fails 2 of 2, assertions on and off |
150a8dacb59, 797cfbf4773, 1bb45548320 | commit probe | each commit's selector classes on the 9.0.0 jars split the pair (default passage; long match dropped, then cut) |
| 8.7.0, 8.11.4 | no API | no matchhighlight package (the test does not compile) |
| main + the fix | not affected | the paste-ready test, the matchhighlight tests and the whole highlighter test task pass |
The finder, an independent reproducer, a devil's advocate, the adjudication and a credibility audit each ran tests on the stock jars and found it real (minor). Read-only reviews by another model family (OpenAI GPT-5.6): real (medium), and not real only because it could not run code. This doc re-ran it through gradle.
Checks and verdicts309 words
Every check except the cross-model reviews executed code (the hunt's checks on main a9779ef3c193, this doc's on 645d4fe14a20).
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Public-API end-to-end JUnit (both paths): 2 of 2 fail on main (on and off), 10.5.2 and 9.12.3; pass with the fix; 48 upstream matchhighlight tests pass with it. |
| cross-model review, refute lens (OpenAI GPT-5.6, reading only) | not real (low), procedural | Could not run code, so its verdict is procedural; agreed with the root cause and that the inputs are legal, rated the intended argument moderate, flagged the 1-unit window. A separate run re-ran the test: 2 of 2 fail. |
| independent reproducer | real | Own JUnit (Deseret, mathematical bold, CJK Extension B, window sweep, ASCII control): 3 of 4 fail on main (on and off), 10.5.2 and 9.12.3; 4 of 4 pass with the fix; preceding() = 0 inside the leading word. |
| cross-model review, intended lens (OpenAI GPT-5.6, reading only) | real (medium) | Intended argument moderate; fix incomplete for the 1-unit window. A separate re-run: 2 of 2 fail on main, controls 5 of 5 pass. |
| intended-behaviour devil's advocate | real | Built the strongest "intended" case and found no document or test that accepts a split character; its reach probe narrowed the reach (single emoji or ideographs between BMP text are spared by the default passage, not inside a long match). |
| adjudication | confirmed (high), minor | Re-ran the independent reproduction's and the finder's tests on main; lowered the class from silent wrong results to minor. |
| credibility audit | confirmed | 2 of 2 fail with assertions on and off; the rating holds. |
| minimal repro and this doc | fails; fix validated | The one-method test fails on 645d4fe14a20 (gradle, on and off) and 10.6.0; with the fix the package tests, the whole highlighter module and lint pass. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 526 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,346 words
- Registry title
- matchhighlight PassageSelector can cut a passage or a truncated match between the two halves of a supplementary character, so FieldValueHighlighters.maxLeadingCharacters and highlighted return a snippet with an unpaired surrogate
- Area
- highlighter / matchhighlight: PassageSelector passage windows and long-match truncation, BreakIteratorShrinkingAdjuster (through FieldValueHighlighters.maxLeadingCharacters and highlighted)
- Priority
- Low, rank 1049: The little-used matchhighlight package can return a snippet ending in half a surrogate pair only for rare supplementary-letter words or over-long matches, a minor output defect.
- Impact class
- minor
- Impact note
- Hits applications that use the matchhighlight package's FieldValueHighlighters (the default PassageSelector with its BreakIteratorShrinkingAdjuster, on the default codec, IndexWriterConfig and searcher) on text with supplementary characters, when either the value's leading word, as the JDK word BreakIterator sees it, is a run of supplementary letters (mathematical bold or italic 'styled' letters, Deseret, Adlam, Osage, or consecutive CJK Extension B ideographs) longer than the window (maxLeadingCharacters, or the default passage of a value without matches), or a single match is longer than the window (highlighted), and the cut lands between the two halves of a character (for a word made only of such characters, any odd window); deterministic with -ea and -da and needs no scale; the effect is one malformed character at the end of the snippet or of the truncated match (an unpaired high surrogate, which a lenient encoder shows as U+FFFD or '?' and a strict one rejects), while hits, scores and the other highlight positions are right; a single emoji or supplementary ideograph between BMP text gets its own word boundaries and is not cut on the adjuster path, and small windows (such as 10) hit it much more easily than windows of 100 or more units.
- Summary
- You highlight a stored value with matchhighlight's FieldValueHighlighters, for example maxLeadingCharacters(5, '...', fields) on a value that starts with the word BOLD written in mathematical bold capitals (U+1D401 U+1D40E U+1D40B U+1D403, two UTF-16 units each), or highlighted(5, ...) with a term query that matches that word. You expect a snippet of whole characters within the 5-unit budget, for example the first two letters and '...', just as the ASCII value 'boldtext' is cut inside the word but between characters ('boldt...'). Instead the snippet ends with the first half of the third letter ('\uD835\uDC01\uD835\uDC0E\uD835...' and '>\uD835\uDC01\uD835\uDC0E\uD835<...'), because PassageSelector cuts windows and long matches at a raw UTF-16 offset and BreakIteratorShrinkingAdjuster keeps that raw edge when no word boundary fits in the window.
- Introduced
- 150a8dacb59712c731e66db1a56068326a0439f4 (LUCENE-9463, apache/lucene-solr#1750, issue apache/lucene#10503, merged into master only): it added PassageSelector, whose default passage ends at o.from + min(window, length) in UTF-16 units, and BreakIteratorShrinkingAdjuster, which puts the raw edge back when preceding() reaches 0; neither checks for a surrogate pair. The second path, truncating a match longer than the window at from + maxPassageWindow, came with 1bb4554832027e139b0890dc0784107697e05fe6 (LUCENE-10135, apache/lucene#334, 2021-09-30); before it such a match was dropped and the default passage split the pair instead, so #334 moved the case to a second path rather than creating it [read: git blame -w and git show in the history clone; exec: the six selector classes of 150a8dacb59, of #334's parent 797cfbf4773 and of 1bb45548320, shadowed onto the 9.0.0 jars, all split the pair (commit probe)] (2020-08-14 (#1750 merged); second path 2021-09-30 (#334 merged))
- First affected version
- 9.0.0 [exec: the finder's JUnit fails 2 of 2 with -ea and with -da, using a copy that imports the pre-9.1 test framework's LuceneTestCase], the first release with the matchhighlight package (CHANGES.txt lists LUCENE-9463 and LUCENE-10135 under 9.0.0); 8.x has no matchhighlight API (8.7.0 and 8.11.4: compile error, API absent [exec])
- Affected versions
- every release from 9.0.0 through 10.6.0 and main a9779ef3c193 and 645d4fe14a20, never fixed. [exec] the finder's JUnit fails 2 of 2 with identical output on all 33 releases from 9.0.0 to 10.5.2 (9.0.0 also with -da) and on main (-ea and -da); the independent reproduction's JUnit fails 3 of 4 on main (-ea and -da), 10.5.2 and 9.12.3; the one-method minimal repro fails on main 645d4fe14a20 through gradle and on the 10.6.0 release jars (SHA-1 checked against Maven Central), -ea and -da (2026-11-01). [read] upstream main (f7bcc0abd816, 2026-10-27), branch_10x and branch_10_5 have not changed the package's window code since; from 9.0.0 to main PassageSelector changed only in priority-queue handling, a rename and a passage-count cap, and BreakIteratorShrinkingAdjuster is byte-identical. Not affected: 8.x and older (no matchhighlight package). Releases were run on JDK 25.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal
- Upstream and prior reports
- none found (2026-10-27, read-only): two scripted prior-report searches (one of 91 queries: 40 GitHub issue and PR, 3 commit, 2 downstream-repository, 32 mailing-list over dev@, java-user@, issues@ and commits@, 8 JIRA, 6 web; the finder's 51), 16 own GitHub phrasings over apache/lucene, apache/solr, Elasticsearch and OpenSearch, the file lists of all 408 open apache/lucene PRs (only #16 and #16847 touch matchhighlight, neither the window code), the package's commit history on main, branch_10x and branch_10_5 (no fix), git log -S for surrogate or code-point handling in the package (none ever), full reads of every matchhighlight issue and PR from LUCENE-9439 to #15577 including apache/lucene-solr #1721, #1750, #1820, #1853 and #2127, and 10 web queries; 25 hits read, none the same bug. Closest items, not this bug: LUCENE-5191 (#6255, a highlighter HTML encoder broke text outside the BMP), #15899/#15900 (TruncateTokenFilter split surrogate pairs; fixed to cut on code points) and LUCENE-8325 (#9372, smartcn), all precedents only; #11172/#334 (LUCENE-10135) added the marker truncation with no Unicode discussion. Gaps: GitHub search tokenizes identifiers, list hits keep only their first 400 characters, private channels are not searchable
- Lucene commit tested
- main
645d4fe14a20(gradle in a scratch worktree: the paste-ready test with assertions on and off; with the fix the matchhighlight tests, assertions on and off and with-Ptests.iters=5, the whole highlighter test task, and the module's lint, format and forbidden-API checks; standalone JUnit runs and a snippet probe on stock and fixed code); the 10.6.0 release jars (the paste-ready test, assertions on and off); 9.0.0 to 10.5.2 (the finder's end-to-end test, all 33 releases). The hunt and its checks ran on maina9779ef3c193, whose highlighter module is identical to645d4fe14a20.
- Finding record
lucene/highlighter/src/java/org/apache/lucene/search/matchhighlight/PassageSelector.java:128-141 (at a9779ef3c193) (centred window in UTF-16 units), :251-254 (to = from + maxPassageWindow), :293-299 (default passage end o.from + Math.min(maxCharacterWindow, o.length()))lucene/highlighter/src/java/org/apache/lucene/search/matchhighlight/BreakIteratorShrinkingAdjuster.java:22-25 (at a9779ef3c193) (javadoc 'adjusts the Passage range to word boundaries'), :56-58 and :61-73 (raw edge restored when following()/preceding() fail or reach 0, :70-71), :75-78 (only widens to marker ends)lucene/highlighter/src/java/org/apache/lucene/search/matchhighlight/FieldValueHighlighters.java:53-54 (at a9779ef3c193) (maxLeadingCharacters 'Displays up to maxLeadingCharacters of the field's value'), :58 and :96 (both use defaultPassageSelector()), :83-86 (PassageSelector with BreakIteratorShrinkingAdjuster)
- The finding in 30 seconds
lucene/highlighter/src/java/org/apache/lucene/search/matchhighlight/FieldValueHighlighters.java:52-55, (at 645d4fe14a20) 56-80 (68-70), 82-86, 88-115 (108-110)lucene/highlighter/src/java/org/apache/lucene/search/matchhighlight/PassageSelector.java:67-74, (at 645d4fe14a20) 128-141, 170-175, 179-193, 251-254, 281-304 (293-299)lucene/highlighter/src/java/org/apache/lucene/search/matchhighlight/BreakIteratorShrinkingAdjuster.java:30-32, (at 645d4fe14a20) 46-59 (56-58), 61-73 (70-72), 75-78lucene/highlighter/src/java/org/apache/lucene/search/matchhighlight/PassageFormatter.java:87-89, (at 645d4fe14a20) 110-125; MatchHighlighter.java:260-266, 276-299
- Who is affected
lucene/highlighter/src/test/org/apache/lucene/search/matchhighlight/TestMatchHighlighter.java:199, (at 645d4fe14a20) 217 (maxLeadingCharacters(10, ...))
- Why it looks unintended
lucene/highlighter/src/java/org/apache/lucene/search/matchhighlight/FieldValueHighlighters.java:52-55; (at 645d4fe14a20) BreakIteratorShrinkingAdjuster.java:22-25, 70-72; MatchHighlighter.java:38-39lucene/highlighter/src/test/org/apache/lucene/search/matchhighlight/TestPassageSelector.java:82-84, (at 645d4fe14a20) 103-105, 297-298, 338-359lucene/CHANGES.txt:1175, (at 645d4fe14a20) 1215-1217, 7454, 7496-7497, 13320, 13362-13365GitHub apache/lucene#15900 comments by uschindler, 2026-04-02T08:28Z and 22:29Z (read-only gh api, 2026-11-01)lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/TruncateTokenFilter.java:34-37, (at 645d4fe14a20) 52-55, 64-66
- Suggested fix
lucene/highlighter/src/java/org/apache/lucene/search/matchhighlight/BreakIteratorShrinkingAdjuster.java:56-58, (at 645d4fe14a20) 70-72, 75-78
- Prior reports
gh search issues --repo apache/lucene --include-prs (2026-11-01, the queries listed); gh api repos/apache/lucene/commits?path=... and contents/...PassageSelector.java?ref=main (2026-11-01)
- History
lucene/CHANGES.txt:4797, (at 645d4fe14a20) 4816, 4833-4834
- TestMatchHighlightWindowSurrogatePair.java (one class, one method, public API):
repro/LFV-774/src/org/apache/lucene/search/matchhighlight/TestMatchHighlightWindowSurrogatePair.java(33 lines)
Made in parallel with this doc, from the code at 645d4fe14a20 and the executed runs.
assets/LFV-774/bug.png(526 KB)