LimitedStoredFieldVisitor.stringField keeps value.substring(0, Math.min(maxLength, value.length())) of the first value and Math.min(lengthBudget - 1, value.length()) units of each later value (UnifiedHighlighter.java:1446-1447, :1464). Neither checks whether the last kept unit is the first half of a surrogate pair, and all three executed offset sources (offsets in postings, term vectors, re-analysis) build the snippet from that text.
- Java strings count UTF-16 units. Most characters take one; a supplementary character (an emoji such as 😀 U+1F600, a CJK Extension B ideograph, a historic-script letter) takes two, a high half and a low half, called a surrogate pair. Either half alone is not text.
- The UnifiedHighlighter reads a stored value and keeps only its first
maxLengthunits (default 10,000, set withwithMaxLength), then picks passages in that prefix and marks the matches. - It finds match offsets in the postings, in term vectors, or by re-analysing the stored text (the default for a plain stored text field). All three work on the truncated text.
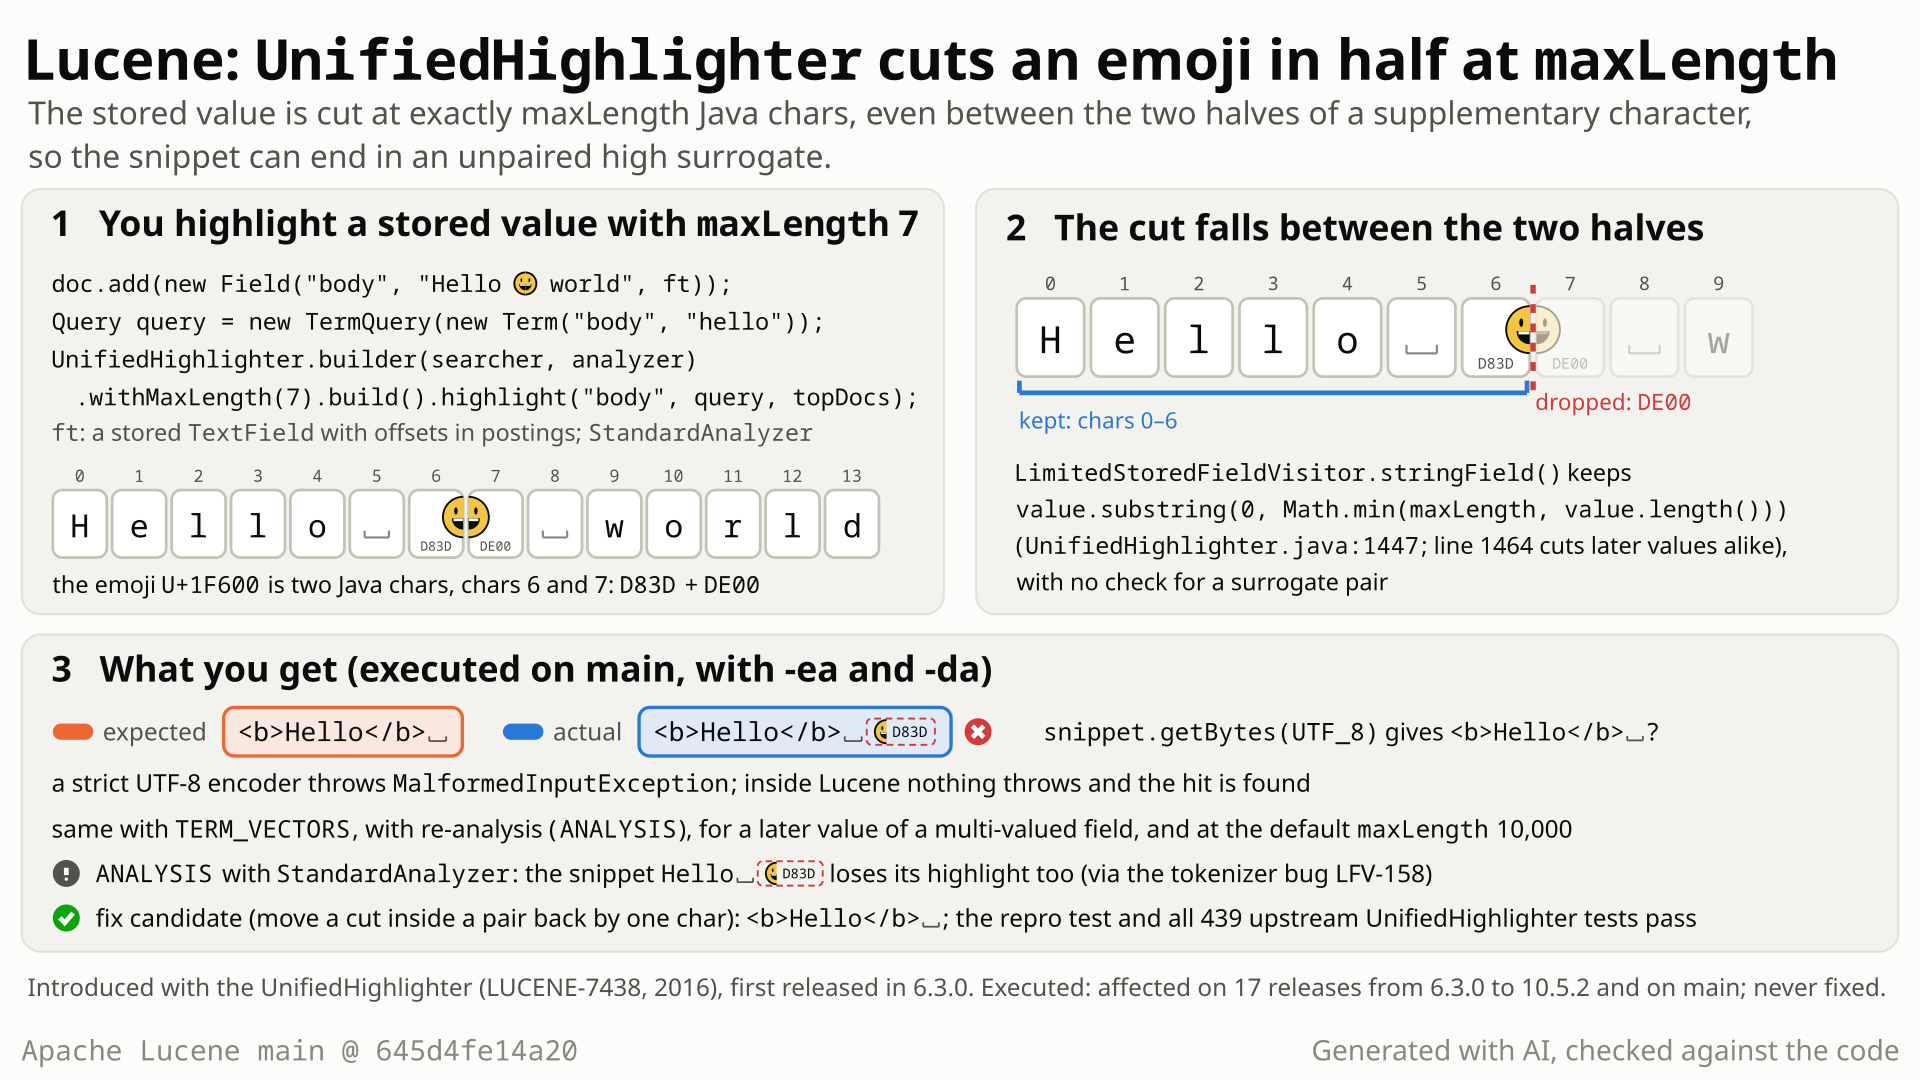
Hello 😀 world as UTF-16 units, the maxLength 7 cut between the two halves of the emoji, and the snippet that ends in the lone first half. Select the still to open it at full size. Generated with AI, checked against the code.- You index
Hello 😀 worldin a stored text field with offsets in postings, usingStandardAnalyzer. In Java the emoji is two UTF-16 units, at indexes 6 and 7. You searchhelloand highlight the hit withUnifiedHighlighter.builder(searcher, analyzer).withMaxLength(7). - You expect a snippet of whole characters:
<b>Hello</b>, which is whatmaxLength6 gives (maxLength8 gives<b>Hello</b> 😀). - The highlighter keeps exactly 7 units,
Helloplus the first half of the emoji, and builds the snippet from that text. - You get
<b>Hello</b> \uD83D, with no error.getBytes(UTF_8)turns it into<b>Hello</b> ?, and a strict UTF-8 encoder throwsMalformedInputException. Hits and scores are right. - The same happens with the default
maxLength10,000 when unit 9,999 of a value is the first half of such a character, with offsets in postings, term vectors or re-analysis, and at the budget edge of a later value of a multi-valued field.
Applications that highlight stored text with the UnifiedHighlighter, defaults included (offsets in postings, term vectors or re-analysis; any analyzer), when a value longer than maxLength has the first half of a supplementary character exactly at the cut and the chosen passage reaches it. Hits and scores stay right; the snippet ends in one broken character.
Mechanism, terms and numbers618 words
The UnifiedHighlighter highlights only the first maxLength characters of a stored value (10,000 by default). LimitedStoredFieldVisitor makes that cut in UTF-16 units and never checks whether it falls between the two halves of a supplementary character, such as an emoji, a CJK Extension B ideograph or a historic-script letter. When it does, the text to highlight ends in a lone high surrogate, and each executed offset source (offsets in postings, term vectors, re-analysis) returns it at the end of the snippet once the chosen passage reaches the cut: Hello 😀 world at maxLength 7 gives <b>Hello</b> \uD83D, while 6 and 8 give whole characters. getBytes(UTF_8) turns the half into ?, and a strict UTF-8 encoder throws. Hits and scores are right; on the re-analysis path with StandardAnalyzer a short value also loses its highlight, through a separate tokenizer bug. Present since 6.3.0 (2016); moving the cut back by one unit fixes it, and the whole highlighter test task (728 tests) passes with the fix.
maxLength: "The maximum content size to process. Content will be truncated to this size before highlighting" (UnifiedHighlighter.java:596-603);DEFAULT_MAX_LENGTH = 10000(:100);Builder.withMaxLength: "The text to be highlight is effectively truncated by this length" (:354). No unit is named; the cut counts Javachars.LimitedStoredFieldVisitor: the stored-field visitor that loads the text to highlight.loadFieldValuescreates it throughnewLimitedStoredFieldsVisitorwithgetMaxLength()(:1387,:1409-1411) and callsinit()per document (:1395). Values of a multi-valued field are joined with the separator U+0000.- Offset source:
POSTINGSwhen offsets are indexed (POSTINGS_WITH_TERM_VECTORSwhen term vectors are stored too),TERM_VECTORSwhen only term vectors are stored, elseANALYSIS, which re-analyzes the stored text (getOffsetSource,:696-709). For a multi-term or rewriting query a postings field is re-analyzed too (getOptimizedOffsetSource,:1268-1273).POSTINGS,TERM_VECTORSandANALYSISwere executed; all of them highlight the same loaded content (:958).
- First value:
values[currentField] = value.substring(0, Math.min(maxLength, value.length()))(:1446-1447). - Later value:
lengthBudget = maxLength - curValue.length()(:1450), then the separator andappend(value, 0, Math.min(lengthBudget - 1, value.length()))(:1463-1464);needsFieldstops oncecurVal.length() >= maxLength(:1475). - Neither cut looks at
Character.isHighSurrogate; the word "surrogate" does not occur in the highlighter's main sources. When unitend - 1is a high surrogate and unitendits low half, the content ends in the lone high half. - Everything after the cut works on whole tokens and break-iterator boundaries:
FieldHighlighterdrops a token that straddles the cut (FieldHighlighter.java:164-166) and clamps passage ends to the content length (:186). A passage that ends at the content end copies the half character out (DefaultPassageFormatter.append, "Appends original text to the response",DefaultPassageFormatter.java:101). This is about a well-formed stored value and the stock passage machinery:appendcopies chars as they are (:108-138), so it neither makes nor repairs a split.
case (WhitespaceAnalyzer, query hello unless noted) | maxLength | snippet on main |
|---|---|---|
| control, cut before the emoji | 6 | <b>hello</b> |
| control, cut after the emoji | 8 | <b>hello</b> 😀 |
| offsets in postings | 7 | <b>hello</b> \uD83D |
| term vectors with offsets | 7 | <b>hello</b> \uD83D |
| plain stored text field (re-analysis) | 7 | <b>hello</b> \uD83D |
second value world 😀 end after hello, query world | 13 | <b>world</b> \uD83D |
| default, emoji's first half at unit 9999 | 10000 | ends <b>hello</b> \uD83D |
Main 645d4fe14a20, assertions on and off; the same on the 10.5.2 and 9.12.3 jars. With StandardAnalyzer and offsets in postings the snippet is <b>Hello</b> \uD83D; getBytes(UTF_8) gives <b>Hello</b> ?, and a strict UTF-8 encoder throws MalformedInputException: Input length = 1.
Exposure and likelihood369 words
- Who is hit. Any UnifiedHighlighter use, defaults included: default
maxLength10,000, offsets in postings, term vectors or re-analysis (all three executed), any analyzer (the cut is made on the stored text, not on tokens), default writer and codec. One document is enough; no scale is needed. - Which text. A stored value longer than the budget that contains supplementary characters: emoji in user text, CJK Extension B and later ideographs, historic scripts, mathematical alphanumerics. The first half of such a character must be exactly the last kept unit (index
maxLength - 1of the first value, or the budget edge of a later value), and the chosen passage must reach the cut. Per truncated value the chance is roughly the share of units that start a supplementary character, so it is rare. - Effect. The snippet ends in one unpaired high surrogate. In the executed probe
getBytes(UTF_8)replaced it with?and a strict UTF-8 encoder threwMalformedInputException; other encoders may replace it differently (not run). The truncation itself does not change hits or scores. With offsets in postings or term vectors (and a term query) the matched word stays highlighted; on re-analysis with a JFlex analyzer a short truncated value can also lose its highlight, through a separate bug (next point). - Secondary symptom, through another bug. On the re-analysis path,
StandardAnalyzerand the other JFlex tokenizers drop the tokens of a text that ends in a lone high surrogate (a separately registered bug), so a short truncated value comes back with no highlight:Hello \uD83Dinstead of<b>Hello</b>. In the hunt's runs the long re-analyzed value at the defaultmaxLengthkept its highlight. Either fix removes the symptom here (both executed). With the test framework'sMockTokenizerthe same path throwsIllegalStateException(test-only). - Downstream (read, not executed). Solr's unified highlighting passes
hl.maxAnalyzedChars(default 51,200) tosetMaxLength, so it reaches the cut; Elasticsearch's unified highlighter loads values itself and callsFieldHighlighterdirectly, so it is likely not exposed; OpenSearch was not checked. - Why nobody noticed. One invisible or replaced character at the very end of a snippet, only when the cut lands inside a pair; the predecessor PostingsHighlighter had the same unchecked cut from 4.1.0 (2012) with no report.
The test shows that with offsets in postings, UnifiedHighlighter.withMaxLength(7) cuts the stored value "Hello U+1F600 world" between the two UTF-16 halves of the emoji, so the snippet ends in an unpaired high surrogate.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.uhighlight;

import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.standard.StandardAnalyzer;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.FieldType;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexOptions;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.Term;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.Query;
import org.apache.lucene.search.TermQuery;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.UnicodeUtil;

public class TestUnifiedHighlighterMaxLengthSurrogatePair extends LuceneTestCase {

  public void testFirstValueCutInsideSurrogatePair() throws Exception {
    Analyzer analyzer = new StandardAnalyzer();
    FieldType offsetsInPostings = new FieldType(TextField.TYPE_STORED);
    offsetsInPostings.setIndexOptions(IndexOptions.DOCS_AND_FREQS_AND_POSITIONS_AND_OFFSETS);
    try (Directory dir = newDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig(analyzer))) {
        Document doc = new Document();
        doc.add(new Field("body", "Hello \uD83D\uDE00 world", offsetsInPostings));
        w.addDocument(doc);
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        IndexSearcher searcher = new IndexSearcher(reader);
        Query query = new TermQuery(new Term("body", "hello"));
        String snippet =
            UnifiedHighlighter.builder(searcher, analyzer)
                .withMaxLength(7)
                .build()
                .highlight("body", query, searcher.search(query, 1))[0];

        // expected whole characters only (maxLength 6 gives "<b>Hello</b> "); actual ends in U+D83D
        assertTrue(
            "expected a well-formed snippet, but was: " + snippet.replace("\uD83D", "\\uD83D"),
            UnicodeUtil.validUTF16String(snippet));
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-775/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/highlighter/build/libs/lucene-highlighter-$V.jar
CP=$CP:$LUCENE/lucene/memory/build/libs/lucene-memory-$V.jar
CP=$CP:$LUCENE/lucene/queries/build/libs/lucene-queries-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.uhighlight.TestUnifiedHighlighterMaxLengthSurrogatePair
- Expected vs actual
- Expected a well-formed snippet (whole characters only; maxLength 6 gives
<b>Hello</b>). Actual:<b>Hello</b> \uD83D.
More files, environment, full output37 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected a well-formed snippet, but was: <b>Hello</b> \uD83D
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.assertTrue(Assert.java:42)
org.apache.lucene.search.uhighlight.TestUnifiedHighlighterMaxLengthSurrogatePair.testFirstValueCutInsideSurrogatePair(TestUnifiedHighlighterMaxLengthSurrogatePair.java:59)- A cut one unit earlier meets the same
maxLengthbudget, asmaxLength6 shows; the formatter promises "original text". - Lucene fixed the same pattern as a bug in TruncateTokenFilter ("no longer produce half surrogates", 10.5.0) and in this module's SimpleHTMLEncoder (4.5.0).
- No highlighter test accepts a split pair; the pinned mid-word cut passes with the fix.
The full argument223 words
- The budget is an upper bound, and the fix keeps it. "The maximum content size to process" (
UnifiedHighlighter.java:597) is met by a cut one unit earlier, which is whatmaxLength6 already produces. The fix keeps the UTF-16 unit ofmaxLength, and every test of the executed highlighter test task still passes (728 tests, assertions on and off). No javadoc promises well-formed snippets; the argument rests on the bound, the formatter's wording and the precedents. - The formatter's contract is original text.
DefaultPassageFormatter.append: "Appends original text to the response" (DefaultPassageFormatter.java:101). The stored value was well-formed; half a code point is not text in any encoding. - Precedents, fixed as bugs.
CHANGES.txt:1215-1217, 10.5.0 Bug Fixes: "GITHUB#15899, GITHUB#15900: Improve TruncateTokenFilter to truncate on codepoints not chars and no longer produce half surrogates." In this module,CHANGES.txt:13362-13364, 4.5.0 Bug Fixes: "LUCENE-5191: SimpleHTMLEncoder in Highlighter module broke Unicode outside BMP because it encoded UTF-16 chars instead of codepoints." Also LUCENE-8325 (smartcn) and LUCENE-3905 (test-framework truncation). - No highlighter test accepts a split pair. A source scan finds no highlighter test that combines supplementary characters with
maxLength. The pinned truncation tests (TestUnifiedHighlighter.java:194-223, LUCENE-5166) cut mid-word, which is still well-formed text, and they pass with the fix. Of the threads read, none accepts a cut inside a character for the highlighter.
The devil's-advocate check304 words
The strongest case for "intended": maxLength is documented as a plain size cut in chars, with no unit and no promise of code-point-safe output; upstream tests pin a cut inside a word; in LUCENE-5166 @mikemccand accepted truncated passages ("I'm not even sure it needs fixing. It ought to be rare-ish that a truncated passage is selected."); TruncateTokenFilter still ships a char mode documented with "This may split surrogate pairs" (TruncateTokenFilter.java:53-54, :61-62); the visitor is @lucene.internal and its factory method can be overridden. In #15900 @uschindler first called a half surrogate after a UTF-16 cut "expected", like String#substring. Later in that thread @uschindler agreed that "The old variant produces incorrect tokens", and added: "But when the search side also produces the same incorrect tokens it's not a big issue. Now we produce different tokens, so you won't find the broken tokens anymore in an existing index."
Why it fails: the accepted LUCENE-5166 behaviour is a cut mid-word, not mid-character, and nobody there discussed code points. TruncateTokenFilter's char mode remains as documented legacy behaviour, kept for backwards compatibility (TruncateTokenFilter.java:34-37, :61-67); the reason given in #15900 was existing indexes (Uwe Schindler's comment above), and the factory javadoc warns that moving to code points may require reindexing (TruncateTokenFilterFactory.java:32-37). The factory's default switched to code points from luceneMatchVersion 10.5.0 (:93-97), under Bug Fixes. The highlighter's snippet is computed at query time and not indexed, so that reason does not apply, and the highlighter documents no such caveat. An overridable internal hook does not make the default behaviour intended. The fix changes only the one case where the output is not text. The independent reproducer, the intended-lens cross-model review (it rated the intended argument "moderate"), the devil's advocate, the adjudication and the audit all concluded it is not intended.
Recommended Move a split cut back by one unit and mark the field as full (+22/-3)
Move a cut that falls between the two halves of a pair back by one unit, at both cut sites in LimitedStoredFieldVisitor.stringField, and mark the field as full so no later value is appended. The repro then passes, and so does the whole highlighter test task (728 tests), assertions on and off.
// both cut sites in stringField: end = endBeforeSplitPair(value, end); needsField stops once truncated
private int endBeforeSplitPair(String value, int end) {
  if (end > 0
      && end < value.length()
      && Character.isHighSurrogate(value.charAt(end - 1))
      && Character.isLowSurrogate(value.charAt(end))) {
    truncated[currentField] = true; // the budget is spent even though one unit is left
    return end - 1;
  }
  if (end < value.length()) {
    truncated[currentField] = true;
  }
  return end;
}
All options and trade-offs4 options · 681 words
Two fixes were built and validated through gradle at 645d4fe14a20: the recommended one (the hunt's fix) and a smaller variant that a probe showed to be weaker. The other options are listed for the discussion with maintainers.
Move a split cut back by one unit and mark the field as full (+22/-3) (validated by the checks) (recommended)
A helper used at both cut sites returns end - 1 when unit end - 1 is a high and unit end a low surrogate, and records in a per-field boolean[] (allocated in init()) that the field's budget is spent, also for an ordinary cut; needsField then stops loading further values of that field. The budget stays in UTF-16 units.
// both cut sites in stringField: end = endBeforeSplitPair(value, end); needsField stops once truncated
private int endBeforeSplitPair(String value, int end) {
  if (end > 0
      && end < value.length()
      && Character.isHighSurrogate(value.charAt(end - 1))
      && Character.isLowSurrogate(value.charAt(end))) {
    truncated[currentField] = true; // the budget is spent even though one unit is left
    return end - 1;
  }
  if (end < value.length()) {
    truncated[currentField] = true;
  }
  return end;
}
Trade-offs
- One small array per document. The helper both computes the cut and records state, which a reviewer may want split.
- A moved-back cut leaves the content one unit short of
maxLength; the flag is what keeps the visitor from appending a separator and an empty later value (see the smaller variant). - A PR could add the paste-ready test (or a shorter one) to
TestUnifiedHighlighter.
What the checks validated
- Scratch worktree at
645d4fe14a20, gradle: the paste-ready test fails 5 of 6 on stock main, assertions on and off, and 50 of 60 with-Ptests.iters=10; with the patch the whole:lucene:highlighter:testtask passes, 35 classes, 728 tests, 0 failures, assertions on and off (counting the 6 paste-ready tests and the upstream truncation tests), and 60 of 60 with-Ptests.iters=10. ecjLintMain,ecjLintTest,checkGoogleJavaFormat,forbiddenApisMainandforbiddenApisTestfor the module pass.- Probes with the patch: a two-valued field cut inside the emoji gives
<b>hello</b>and the no-match summaryhellofor 1 and 2 passages; withStandardAnalyzeron re-analysis the highlight comes back (<b>Hello</b>). - Earlier, on
a9779ef3c193: the finder's, the independent reproducer's and the devil's advocate's tests pass with it, the upstream mid-word cut control included, and the adjudication's re-run with a fresh seed (0 of 6 fail).
A static cutPoint(value, end) with the same pair check at both sites, and no new state.
Trade-offs
- The whole highlighter test task passes with it (728 tests, 0 failures) and all 6 paste-ready tests pass.
- After a moved-back cut the content is
maxLength - 1long, so the next value is still accepted and the U+0000 separator plus an empty value is appended (hello \u0000). Snippets stay right, but a two-passage no-match summary of that field returnshello \u0000, the separator NUL of a separately registered bug, instead ofhello. Stock does the same when a value ends exactly one unit before the budget, so this adds one more way into that bug.
What the checks validated
- Gradle at
645d4fe14a20: the whole highlighter test task with the paste-ready test, assertions on: 728 tests, 0 failures; the two probes above (runner); the encode probe, run by the fact check, gives the same clean<b>Hello</b>as the recommended fix for offsets in postings and for re-analysis withStandardAnalyzer.
Measure the budget in code points instead of chars.
Trade-offs
Would change the current UTF-16-unit behaviour, and with it the content size and output length for every text with supplementary characters; the javadoc does not define the unit, but existing snippet lengths would change. Nothing needs it. Not run.
Override newLimitedStoredFieldsVisitor (protected, @lucene.internal, UnifiedHighlighter.java:1409-1411) with a visitor that backs the cut off, or strip a trailing lone high surrogate from returned snippets.
Trade-offs
Every application has to know about it. Not run.
By code reading, Solr's unified highlighting passes hl.maxAnalyzedChars (default 51,200) as maxLength and so reaches this cut, while Elasticsearch loads values itself and likely does not; what one half character does downstream depends on the application's UTF-8 encoder (in the executed probe getBytes(UTF_8) gave ? and a strict encoder threw; other encoders were not run).
Semi-formal. A bounded-exhaustive metamorphic test ran the real highlighter on small texts and on copies whose letters and digits were mapped to supplementary-plane characters, requiring that no snippet contain an unpaired surrogate. It failed on its first run, for all three offset sources it covered, whenever maxLength fell inside a pair; reading the visitor located the cut.
The method in full214 words
- Harness. A translation-validation harness over the stock jars: 2,238 single-valued texts (all 1-3-token sequences over
a,b,ab,Ab,B1,1with space or.separators, and all 4-token sequences) and 1,764 two-valued documents;StandardAnalyzerandKeywordAnalyzer; fields with offsets in postings, term vectors and none (re-analysis); 49 and 35 queries of 11 kinds (term, boolean, phrase, slop, prefix, wildcard, regexp, fuzzy, range, span, intervals);maxLength10000 and 1-30; three mappings of letters and digits (Deseret and Adlam, Armenian and Adlam, and an all-BMP control, Georgian and Saurashtra). - Relations. "No snippet of a mapped text contains an unpaired surrogate" failed 2,202,831 times in 57,460,950 checks, always with the cut between the two halves of a character; the all-BMP control failed 0 times. Hits and scores never differed. With the cut on a code-point boundary every mapped snippet was the image of the original one, apart from 1,622 differences explained by two UTF-16-length heuristics that are not part of this report (the passage centre for phrase matches across a boundary, and PassageScorer's length weights for fuzzy matches).
- Bridge. Reading
LimitedStoredFieldVisitorwhile modelling the cut located the two lines; a public-API JUnit on the stock jars failed 5 of 5 on main, 10.5.2 and 9.12.3 and passed with the fix.
No prior report found in GitHub issues, PRs and commits, the JIRA archive, the mailing lists, downstream trackers or the web (2026-10-27, re-checked 2026-10-29), nor in the changed files of the 408 open PRs. Nearest: a 2019 downstream report of the same symptom from another highlighter. Not fixed upstream.
Searches4 searches
No report of this defect was found, for the UnifiedHighlighter or its predecessor PostingsHighlighter. The nearest items show the same pattern in other components, fixed as bugs, or other defects of the same cut. Upstream main 645d4fe14a20 (2026-10-28), branch_10x and branch_10_6 keep both cut lines (read).
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene), JIRA archive (LUCENE, SOLR), mailing lists (dev@, java-user@, issues@, commits@, Solr lists), downstream trackers, web | 2026-10-27 | a 61-query scripted prior-report search run, 38 direct GitHub searches over Lucene, Solr, Elasticsearch and OpenSearch, 13 JIRA and 70 list queries, git history; plus the finder's 51 and a verifier's 27 queries | 263 tool hits, 0 high and 17 medium overlap, all read: none is this bug; precedents only: #15899/#15900 (TruncateTokenFilter), #6255 (LUCENE-5191), #9372 (LUCENE-8325), LUCENE-3905; other defects of the predecessor's cut: #6096 (LUCENE-5032), #6230 (LUCENE-5166) |
| Open PRs | 2026-10-27 | the changed files of all 408 open apache/lucene PRs | 4 touch uhighlight; #12295 edits stringField only for an instanceof cast; none touches the cut lines |
| Downstream | 2026-10-27 | issue searches and code reading | elastic/elasticsearch#45771 (2019, closed): the same symptom from the FastVectorHighlighter on a short value; a maintainer said the unified highlighter handled that emoji |
| GitHub issues and PRs (apache/lucene), re-check | 2026-10-29 | UnifiedHighlighter surrogate, highlighter maxLength surrogate, highlight unpaired surrogate, UnifiedHighlighter emoji, LimitedStoredFieldVisitor; four more queries hit the search rate limit | nothing new (#8819 and #6096 are known non-matches); both cut lines unchanged on main, branch_10x and branch_10_6 |
Present since the UnifiedHighlighter was added (LUCENE-7438, released in 6.3.0, 2016); later commits kept the cut. Executed on 17 releases from 6.3.0 to 10.5.2 and on main: all affected; never fixed. The predecessor PostingsHighlighter had the same unchecked cut from 4.1.0 until its removal in 7.0.0.
Versions tested8 rows
Introduced with the class: LUCENE-7438 "New UnifiedHighlighter" (migrated as #8490; pull request apache/lucene-solr#79 by @Timothy055, closed without a GitHub merge; committed by @dsmiley on 2016-10-04 as 722e8271243 on master and the same-day branch_6x cherry-pick 4b6794368df, first released in 6.3.0). Not a regression. Later commits kept the arithmetic: LUCENE-8805 5a694ea26ff (signature), LUCENE-9570 6faa4f98e04 (reformat), #13085 8f759d5bf65 (append(value, 0, n) instead of substring, same characters), #15842 b59848c7049 (instanceof pattern). Lineage: PostingsHighlighter's append(value, 0, maxLength - builder.length()) (LUCENE-4290, 4.1.0, 2012, @rmuir; removed in 7.0.0 by LUCENE-7815).
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | this doc's test fails 5 of 6 (gradle and runner, assertions on and off) |
| 10.5.2, 9.12.3 | affected | the same (this doc's test, runner); the finder's JUnit fails 5 of 5 |
| 9.1.0, 10.0.0 | affected | the finder's JUnit fails 5 of 5; the probe 5 of 5 |
| 7.7.0 to 9.0.0 | probe | half surrogate in all 5 scenarios, controls clean (7.7.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0); with StandardAnalyzer the short re-analyzed value also loses its highlight |
| 6.3.0 to 7.6.0 | probe | half surrogate in all 5 scenarios, controls clean (6.3.0 with assertions on and off, 6.6.6, 7.0.0, 7.2.1-7.6.0); the re-analyzed highlight is kept |
| 6.2.1 | no API | no UnifiedHighlighter (the probe does not compile) |
| 4.1.0, 6.2.1, 6.3.0 (PostingsHighlighter) | predecessor | the same unchecked cut, 3 of 3 scenarios; the class was removed in 7.0.0, so this is lineage |
| main + the fix | not affected | all 6 pass; the whole highlighter test task passes (728 tests) |
The finder, an independent reproducer, a devil's advocate, the adjudication and a credibility audit each ran tests on the stock jars and said real; the audit lowered the impact to minor. Reading-only reviews by another model family (OpenAI GPT-5.6): real (medium), and not real only because it could not run code. This doc re-ran everything through gradle.
Checks and verdicts358 words
Every check except the cross-model reviews executed code (the hunt's checks on main a9779ef3c193, this doc's on 645d4fe14a20).
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | 5-test public-API JUnit with StandardAnalyzer: 5 of 5 fail on main (on and off), 10.5.2 and 9.12.3, pass with the fix; the exhaustive harness's 2,202,831 failures all have the cut inside a pair, the all-BMP control none. |
| cross-model review, refute lens (OpenAI GPT-5.6, reading only) | not real (low), procedural | Could not run code, so it could not say real; it agreed with the root cause, found the inputs in contract and called the static evidence strongly in favour of a defect. A separate run re-ran the repro: 5 of 5 fail. |
| independent reproducer | real | Own 6-test JUnit with controls at maxLength 6 and 8 and a WhitespaceAnalyzer case: 6 of 6 fail on main (on and off), 10.5.2 and 9.12.3; the MockTokenizer path throws; 0 of 6 with the fix. |
| cross-model review, intended lens (OpenAI GPT-5.6, reading only) | real (medium) | Rated the "exact UTF-16 budget" argument moderate and found that it fails; separate runs fail on main and 10.5.2 and pass with the fix. |
| intended-behaviour devil's advocate | real; not intended | Built the strongest intended case and showed why it fails; its intent test fails exactly the 3 cut-inside-pair cases of 6, a strict encoder throws, and the pinned mid-word cut stays well-formed with and without the fix. |
| adjudication | confirmed (high) | Re-ran the independent reproducer's test with a new seed: 6 of 6 fail, on and off; 0 of 6 with the fix. Low priority. |
| credibility audit | real; impact lowered to minor | Re-ran the finder's test: 5 of 5 fail, on and off. Graded display text only, like the sibling bug in the matchhighlight module. |
| this doc | repro and fix confirmed | Paste-ready test fails 5 of 6 through gradle (on and off; 50 of 60 with -Ptests.iters=10) and the runner (main, 10.5.2, 9.12.3); with the fix the whole highlighter test task passes (728 tests), on and off; probes showed why the smaller variant is not recommended. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 478 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,486 words
- Registry title
- UnifiedHighlighter cuts a stored value at maxLength UTF-16 units even between the two halves of a supplementary character (an emoji, a CJK Extension B ideograph), so the snippet can end in an unpaired high surrogate, for example '<b>Hello</b> \uD83D'
- Area
- highlighter / UnifiedHighlighter stored-value loading (LimitedStoredFieldVisitor maxLength cut)
- Priority
- Low, rank 555: The default UnifiedHighlighter maxLength cut can leave an unpaired high surrogate at the end of a snippet, which only affects display and needs a supplementary character exactly at the cut.
- Impact class
- minor
- Impact note
- Applications that highlight stored text with the UnifiedHighlighter in its default configuration (default maxLength 10,000; offsets in postings, term vectors and re-analysis (POSTINGS, TERM_VECTORS and ANALYSIS, all three executed); any analyzer; by code reading also Solr's unified highlighting, which passes hl.maxAnalyzedChars, default 51,200) get a snippet that ends in one unpaired high surrogate whenever a stored value is longer than the budget, the first half of a supplementary character sits exactly at the last kept unit (UTF-16 index maxLength-1 of the first value, or the per-value budget edge of a later value of a multi-valued field) and the chosen passage runs to the cut; encoding the snippet with getBytes(UTF_8) gives '?' and a strict UTF-8 encoder throws (other encoders not run), while hits and scores are never wrong and nothing throws inside Lucene's production code; on the ANALYSIS path with StandardAnalyzer a short truncated content also loses its highlight (through the registered LFV-158); no scale is needed; released since 6.3.0.
- Summary
- You store the value 'Hello U+1F600 world' (the emoji takes UTF-16 indexes 6 and 7), search for hello and highlight the hit with UnifiedHighlighter.builder(searcher, analyzer).withMaxLength(7), and expect a snippet made of whole characters, '<b>Hello</b> ', just as maxLength 6 gives '<b>Hello</b> ' and maxLength 8 gives the whole emoji. Instead LimitedStoredFieldVisitor keeps exactly 7 UTF-16 units, so the content and the snippet end with the first half of the emoji, '<b>Hello</b> \uD83D', which String.getBytes(UTF_8) turns into '<b>Hello</b> ?' and a strict UTF-8 encoder rejects. The same happens at the default maxLength 10,000 when a value's 10,000th unit is the first half of a supplementary character, and for a later value of a multi-valued field at its per-value budget.
- Introduced
- 722e82712435ecf46c9868137d885484152f749b (LUCENE-7438 'New UnifiedHighlighter', migrated as apache/lucene#8490, fix version 6.3; pull request apache/lucene-solr#79 by Timothy055, closed without a GitHub merge; committed by dsmiley on master, first released in 7.0.0) and its same-day branch_6x cherry-pick 4b6794368df373df1f68ccf27f7556914efeb95e, which first ships in 6.3.0: it added LimitedStoredFieldVisitor with both cut lines [read: git log -L on stringField, git blame of UnifiedHighlighter.java:1446-1447, 1450-1464 and 1474-1476, git log -S on both cut expressions; the later commits LUCENE-8805 5a694ea26ff (signature only), LUCENE-9570 6faa4f98e04 (formatting), #13085 8f759d5bf65 (append(value, 0, n) instead of substring, same characters) and #15842 b59848c7049 (instanceof pattern) kept the arithmetic; exec: 6.2.1 has no UnifiedHighlighter, 6.3.0 is affected]. Not a regression: the class had the defect in its first version. The same unchecked cut is older than the class: its predecessor PostingsHighlighter (LUCENE-4290, 6ac21f776c7 on branch_4x / f2d1557c5d1 on trunk, rmuir, 2012-12-11, first released in 4.1.0; removed in 7.0.0 by LUCENE-7815) cut with append(value, 0, maxLength - builder.length()) [exec on 4.1.0, 6.2.1 and 6.3.0]; that class is gone, so it is lineage, not part of this row. (2016-10-04 (LUCENE-7438); the predecessor PostingsHighlighter cut dates from 2012-12-11 (LUCENE-4290))
- First affected version
- 6.3.0 [exec, -ea and -da]: the first release with the UnifiedHighlighter (branch_6x cherry-pick 4b6794368df); 6.2.1 has no UnifiedHighlighter [exec: compile error, package org.apache.lucene.search.uhighlight does not exist]. Lineage only: PostingsHighlighter had the same cut from 4.1.0 until its removal in 7.0.0 [exec on 4.1.0, 6.2.1, 6.3.0; 4.0.0 has no postingshighlight package].
- Affected versions
- every release from 6.3.0 to 10.5.2 (all 87 releases: 6.3.0-6.6.6, 7.0.0-7.7.3, 8.0.0-8.11.4, 9.0.0-9.12.3, 10.0.0-10.5.2), 10.6.0 (by reading) and main a9779ef3c193 (unreleased 11.0); never fixed upstream. [exec] the follow-up's version-portable probe UhMaxLengthSurrogateHistoryProbe (constructor plus setMaxLength, NIOFSDirectory; the candidate's 5 scenarios plus 2 controls with the cut next to the emoji) is affected 5 of 5 on 6.3.0 (-ea and -da), 6.6.6, 7.0.0, 7.2.1, 7.3.0, 7.4.0, 7.5.0, 7.6.0, 7.7.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.1.0, 9.12.3, 10.0.0, 10.5.2 (-ea and -da) and main (-ea and -da), with both controls well-formed and highlighted on every version; the candidate JUnit (builder API, so 9.1.0 and later) fails 5 of 5 on 9.1.0, 9.12.3, 10.0.0, 10.5.2 and main (-ea and -da); the independent reproduction's JUnit fails 6 of 6 on main (-ea and -da), 10.5.2 and 9.12.3. [read] both cut lines and no surrogate handling at all 78 tagged releases from 6.3.0 to 10.5.2 in the history clone (8.8.2-8.11.3 are not tagged there; they lie between 8.8.1 [read] and 8.11.4 [exec]); upstream main a95c754ee003 (2026-10-26, the latest local fetch), branch_10x, branch_10_6 and branch_10_5 keep both lines (UnifiedHighlighter.java:1447 and :1464). The secondary lost-highlight symptom (a short re-analyzed value with StandardAnalyzer) appears only from 7.7.0 (7.6.0 keeps the highlight), which is LFV-158's boundary; the unpaired surrogate itself is present from 6.3.0 on.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-27, the prior-report record: a scripted prior-report search of 61 queries (20 GitHub issue/PR queries on apache/lucene, 3 commit, 2 downstream-repository, 24 mailing-list queries over dev@, java-user@, issues@ and commits@, 4 JIRA-archive, 7 of 8 web), 263 hits with 0 high and 17 medium overlap, every medium hit read; 38 direct GitHub searches over apache/lucene, apache/solr, elastic/elasticsearch and opensearch-project/OpenSearch; all 408 open apache/lucene PRs listed with their changed files (4 touch uhighlight, none the cut lines: #12295 changes only the instanceof cast in stringField, #13165, #16881 and #16851 are elsewhere); 13 LUCENE and SOLR JQL queries; 70 lists.apache.org queries over 7 lists; git history searches; plus the finder's run (51 queries) and the intended-behaviour check's run (27 queries); re-checked 2026-10-27 with 4 GitHub searches: nothing new); not fixed upstream (main a95c754ee003, branch_10x, branch_10_6 and branch_10_5 keep UnifiedHighlighter.java:1447 and :1464 [read]); nearest items, not reports of this bug: elastic/elasticsearch#45771 (2019, the same symptom, a lone high surrogate at the end of a highlight, from the FastVectorHighlighter's fragment boundary on a short value; a maintainer replied that the unified highlighter handled that emoji), #15899/#15900 (TruncateTokenFilter half surrogates, fixed in 10.5.0 under Bug Fixes), #6255 (LUCENE-5191, SimpleHTMLEncoder broke non-BMP characters in this module, fixed in 4.5), #9372 (LUCENE-8325, smartcn) and LUCENE-3905 (test-framework truncation), the same pattern in other components; #6096 (LUCENE-5032) and #6230 (LUCENE-5166), other defects of the predecessor PostingsHighlighter's maxLength cut, with no mention of surrogates; downstream reach [read, not executed]: Solr's UnifiedSolrHighlighter calls setMaxLength(hl.maxAnalyzedChars, default 51200), so Solr's unified highlighting goes through this cut; Elasticsearch's CustomUnifiedHighlighter loads the value itself and calls FieldHighlighter.highlightFieldForDoc directly, bypassing LimitedStoredFieldVisitor, so Elasticsearch is likely not exposed; OpenSearch was not checked
- Lucene commit tested
- main
645d4fe14a20(gradle in a scratch worktree: the paste-ready test with assertions on and off and with-Ptests.iters=10, the whole highlighter test task with each of the two fixes, the module's lint, format and forbidden-API checks; the standalone JUnit runner and four probes); the 10.5.2 and 9.12.3 release jars (this doc's test); 6.3.0 to 10.5.2 (the hunt's version-portable probe). The hunt and its checks ran on maina9779ef3c193, whose highlighter module is identical to645d4fe14a20.
- Finding record
lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:1446-1447 (first value: value.substring(0, Math.min(maxLength, value.length()))), :1464 (later values: append(value, 0, Math.min(lengthBudget - 1, value.length()))), :1475 (stop condition), :354 (withMaxLength javadoc), :596-603 (getMaxLength javadoc), :100 (DEFAULT_MAX_LENGTH = 10000); a Lucene clone origin/main a95c754ee003, origin/branch_10x, origin/branch_10_6, origin/branch_10_5: the same two cut lines at :1447 and :1464
- The finding in 30 seconds
lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:100, (at 645d4fe14a20) :354, :596-603, :696-709, :958, :1253-1273 (:1268-1273), :1382-1411 (:1387, :1395, :1409-1411), :1438-1466 (:1446-1447, :1450, :1463-1464), :1468-1479 (:1475)lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/FieldHighlighter.java:164-166, (at 645d4fe14a20) :186; DefaultPassageFormatter.java:101, :108-138
- Why it looks unintended
lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:354, (at 645d4fe14a20) :596-603; DefaultPassageFormatter.java:101lucene/CHANGES.txt:1175 (at 645d4fe14a20) (10.5.0 Bug Fixes), :1215-1217 (GITHUB#15899, GITHUB#15900); :13320 (4.5.0 Bug Fixes), :13362-13364 (LUCENE-5191)lucene/highlighter/src/test/org/apache/lucene/search/uhighlight/TestUnifiedHighlighter.java:194-223 (at 645d4fe14a20) (testFormatWithMatchExceedingContentLength*)lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/TruncateTokenFilter.java:34-37, (at 645d4fe14a20) :53-54, :61-67; TruncateTokenFilterFactory.java:32-37, :93-97github.com/apache/lucene #15900, comment by uschindler, 2026-04-02T22:29:57Z (read with the GitHub API on 2026-10-29)
- Suggested fix
lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:1409-1411 (at 645d4fe14a20) (newLimitedStoredFieldsVisitor)
- History
a Lucene clone: git show origin/main (645d4fe14a20), origin/branch_10x (657014b3c579), origin/branch_10_6 (4ae946e5a9b9), releases/lucene/10.5.2: UnifiedHighlighter.java:1447, :1464
- TestUnifiedHighlighterMaxLengthSurrogatePair.java (JUnit test):
repro/LFV-775/src/org/apache/lucene/search/uhighlight/TestUnifiedHighlighterMaxLengthSurrogatePair.java(65 lines)
Made in parallel with this doc from the code at main 645d4fe14a20 and the executed runs; every value drawn should come from the executed runs and the source at that commit.
assets/LFV-775/bug.png(478 KB)