HTMLStripCharFilter has special start-tag rules for <script>, <style> and <br>; after a script or style start tag it drops everything up to the matching end tag. Since 10.5.0 these rules also accept a longer name, such as scripts, and the scanner prefers them because they match one character more than the ordinary element rule.
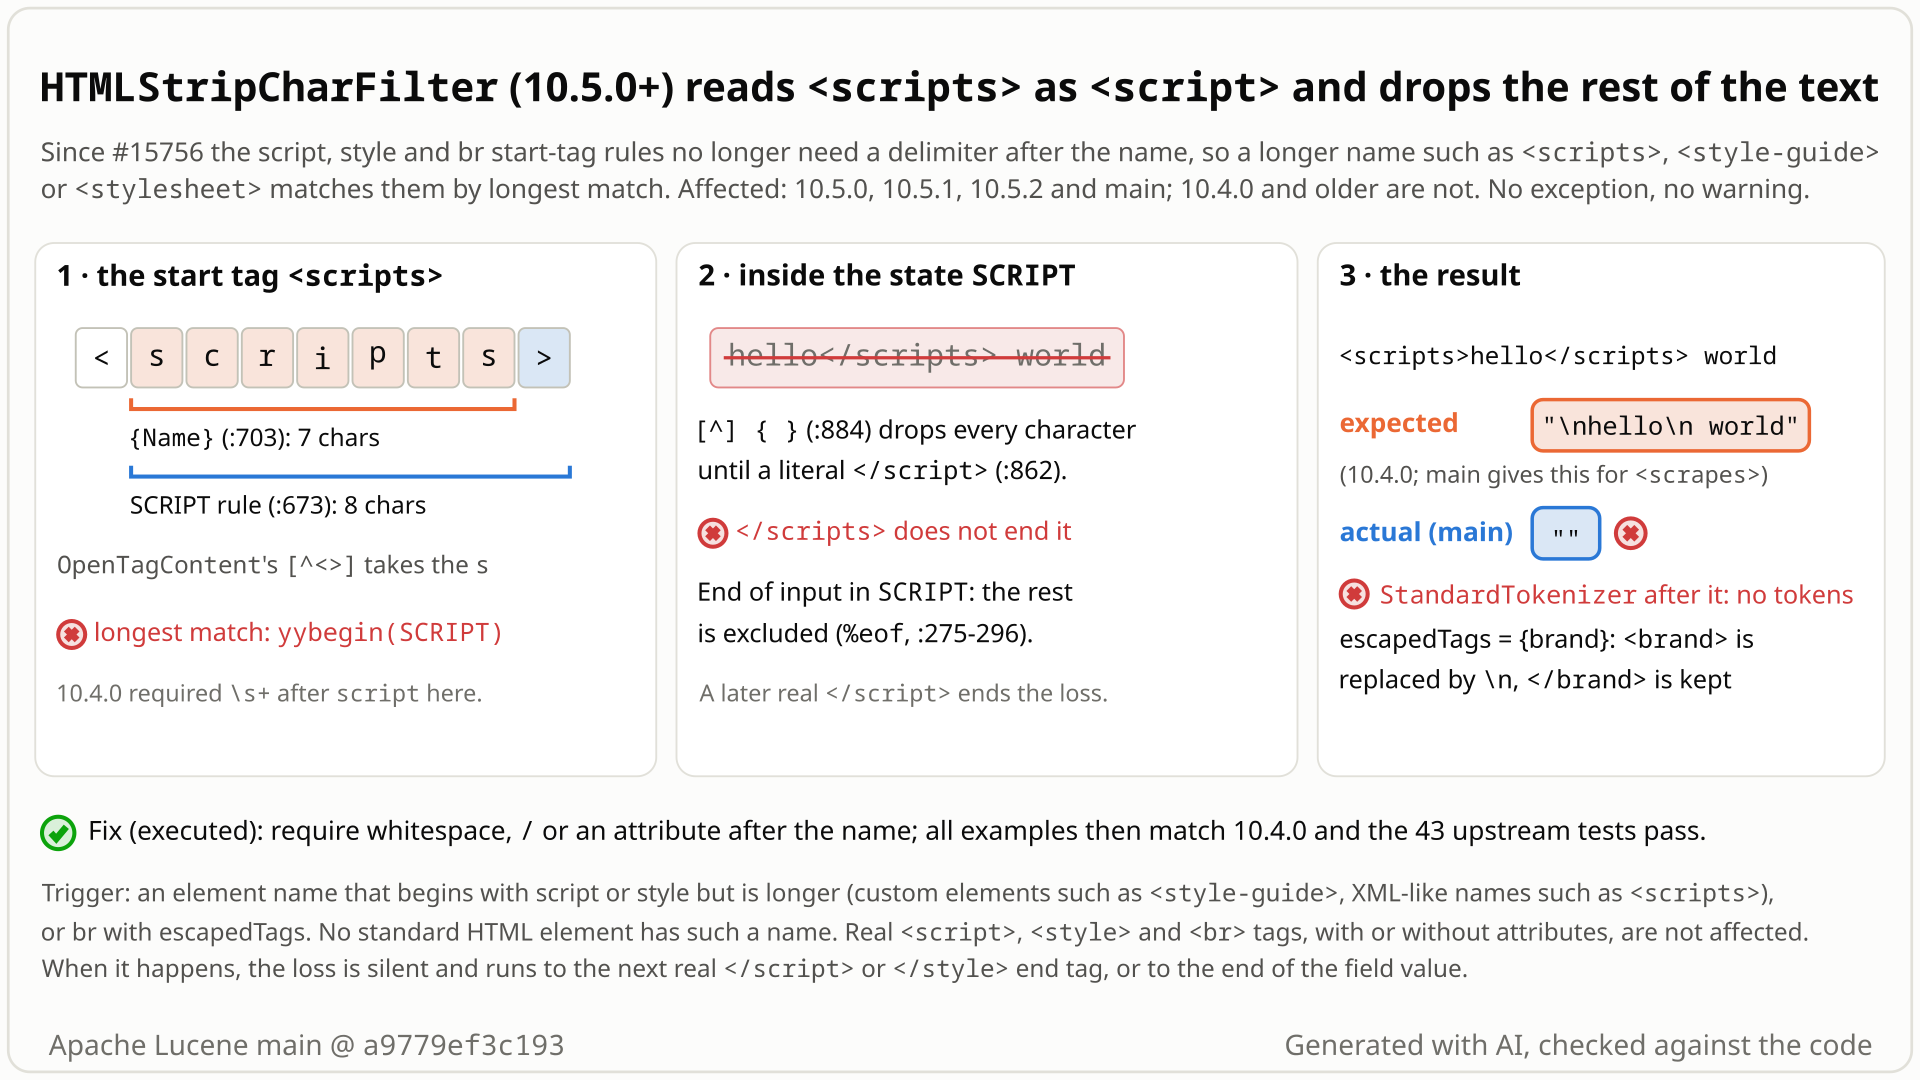
<scripts> cell by cell: the ordinary element rule matches 7 characters, the script rule 8 and wins; the script state then drops hello</scripts> world, so main outputs an empty string instead of \nhello\n world. Select the still to open it at full size. Generated with AI, checked against the code.- Strip
<scripts>hello</scripts> worldwithHTMLStripCharFilterat default settings.scriptsis just an element name, likescrapes. - You expect
\nhello\n world: both tags become newlines and both words stay. Lucene 10.4.0 gives exactly that, and main gives it for<scrapes>hello</scrapes> world. - You get an empty string, with no error. The script rule no longer checks that the name ends after
script, soscripts>matches it, one character longer than the ordinary element rule'sscripts. The longer match wins, and everything up to the next</script>end tag is dropped: here, the rest of the input. - Real pages lose more: in
<p>Intro</p><script-editor lang="js">Edit me</script-editor><p>Body text</p>onlyIntrosurvives, 4 of 5 words lost. WithescapedTags={brand},<brand>Acme</brand>comes out as\nAcme</brand>: the start tag is stripped althoughbrandis escaped.
Applications that strip HTML with HTMLStripCharFilter (directly, via the htmlStrip factory, or a downstream html_strip filter) on 10.5.0 to 10.6.0 (10.6.0 by reading) or main, at default settings. The trigger is rare: custom elements like <style-guide>, XML-like names like <stylesheet>. But the loss is silent and runs to the next real </script> or </style>, or to the end of the field.
Mechanism, terms and numbers899 words
HTMLStripCharFilter has dedicated start-tag rules for br, script and style (HTMLStripCharFilter.jflex:658, :673, :682). After a script or style start tag the scanner drops every character up to the next </script> or </style> end tag, or to the end of the input. Until 10.4.0 these rules required whitespace (or = for br) after the name. #15756, the fix for #15754 (attribute values ending in =), moved that whitespace into the attribute macros and dropped it from the three rules, so the text after the name may now start with any character except < and > (or with a server-side include). <scripts> then matches the script rule with one character more than the generic element rule, and JFlex's longest-match rule picks it: <scripts>hello</scripts> world strips to an empty string instead of \nhello\n world, a tokenizer after the filter emits no token, and no exception is raised. Custom elements such as <style-guide> or <script-editor> and XML-like names such as <stylesheet> or <styleUrl> lose the text the same way; with escapedTags, names that begin with br (<brand>, <bridge>) are escaped or stripped against the configured set. Released in 10.5.0 to 10.6.0 (10.6.0 by reading) and on main. The fix requires a delimiter after the name again (whitespace, / or an attribute); with it, all of :lucene:analysis:common:test passes (1,914 tests, 18 skipped, 0 failures).
HTMLStripCharFilter: aCharFilterinlucene/analysis/commonthat removes HTML markup and decodes character references before tokenization. Its scanner is generated by JFlex fromHTMLStripCharFilter.jflex. An unknown element's start and end tags are each replaced by a newline and its text is kept; the content of<script>and<style>elements is removed.- Longest match: JFlex picks the rule that consumes the most input. When two rules can match a start tag, the longer match wins.
escapedTags: an optional constructor argument; "Tags in this set (both start and end tags) will not be filtered out."
- The three rules (
HTMLStripCharFilter.jflex:658,:673,:682, right after<):
   \s* [bB][rR] ( "="\s* {OpenTagContent} | {OpenTagContent} )? \s* "/"? ">"
   \s* [sS][cC][rR][iI][pP][tT] ( {OpenTagContent} )? \s*  ">"      -> yybegin(SCRIPT)
\s* [sS][tT][yY][lL][eE] ( {OpenTagContent} )? \s* ">" -> yybegin(STYLE)OpenTagContent(:115) is( {EventAttribute} | [^<>] | {ServerSideInclude} | {OpenTagAttribute} )*. Its[^<>]alternative matches any character except<and>, letters included, so nothing has to separatescriptfrom what follows.- For
<scripts>two rules compete: the generic{Name}rule (:703-711) matchesscripts(7 characters), the SCRIPT rule matchesscript+s+>(8). The longer match wins and the scanner enters the SCRIPT state. - In SCRIPT (
:860-885) only<!--and the end tag</script>(:862: the exact name, whitespace allowed) are special; every other character is skipped (:884),</scripts>included. At the end of the input the rest is excluded (:275-296). STYLE (:887-912) is the same with</style>. - The
brvariant:<brand>matches the BR rule (6 characters) instead of{Name}(5).escapedTagsis checked by exact name:BR,SCRIPTandSTYLEbecome flags (:181-197), other names are looked up only by the generic{InlineElment}and{Name}rules (:591-608,:694-711); the BR, SCRIPT and STYLE rules check only their flags. So with{brand}the start tag is replaced by a newline while</brand>is kept; with{br},<bridge>is kept; with{script},<scripted>is echoed and the rest dropped. WithoutescapedTagsthe BR variant is invisible: both rules emit a newline. - The end-tag rules match only the exact names:
</br>(:576),</script>(:862),</style>(:889). - Until 10.4.0 the three rules were
( \s+ {OpenTagContent} )?(script, style) and( ( "="\s* | \s+ ) {OpenTagContent} )?(br), unchanged since the 2012 JFlex rewrite. #15756 added a leading\s+toEventAttributeandOpenTagAttribute(:113-114) and removed it from these rules, which also removed the only thing that ended the tag name.
| input | escapedTags | main, 10.5.2 | 10.4.0 (expected) |
|---|---|---|---|
<scrapes>hello</scrapes> world (control) | - | \nhello\n world | \nhello\n world |
<scripts>hello</scripts> world | - | empty | \nhello\n world |
<style-guide>hello</style-guide> world | - | empty | \nhello\n world |
<stylesheet>hello</stylesheet> world | - | empty; a tokenizer after it emits no token | \nhello\n world |
<scripting>alpha</scripting> beta <script>f()</script> gamma | - | \n gamma | \nalpha\n beta \n gamma |
<p>Intro</p><script-editor lang="js">Edit me</script-editor><p>Body text</p> | - | \nIntro\n | \nIntro\n\nEdit me\n\nBody text\n |
I love <scripted hut> so much | - | I love | I love \n so much |
I love <pizza hut> so much (control) | - | I love \n so much | I love \n so much |
<brand>Acme</brand> | {brand} | \nAcme</brand> | <brand>Acme</brand> |
x<bridge>alpha</bridge>y | {br} | x<bridge>alpha\ny | x\nalpha\ny |
x<scripted>alpha</scripted>y | {script} | x<scripted> | x\nalpha\ny |
Not affected: real <script>, <style> and <br> tags with or without attributes, and the controls with other names (<scrapes>, <stale-guide>, <bland>, <pizza hut>), executed; from the grammar, any name that does not begin with these words goes through the generic rules as before. A KML document loses everything after <styleUrl> in the same way. Output strings: the PrefixProbe on main and 10.4.0 and the fact check's own probe on main, 10.5.2 and 10.4.0 (10.5.0 and 10.5.1 have the same grammar as 10.5.2; there only the standalone JUnit was run). The token result: the standalone JUnit with a StandardTokenizer and the fact-check probe.
Exposure and likelihood248 words
- Who is exposed. Users of
HTMLStripCharFilterdirectly, through thehtmlStripSPI factory (HTMLStripCharFilterFactory.java:42, e.g. in aCustomAnalyzer), or through a downstreamhtml_stripchar filter built on it. No Lucene analyzer adds it by default: opt-in, but a stock component; the script/style variant needs no setting. - What it takes. A start tag whose name begins with
scriptorstyleand goes on with a name character: hyphenated custom elements (<style-guide>,<script-editor>,<style-switcher>), XML-like names (<scripts>,<styles>,<stylesheet>, KML's<styleUrl>), or angle-bracket placeholders in plain text (<scripted hut>). No standard HTML element has such a name, so pages that use only standard elements are not hit, but valid custom-element markup is; how often these shapes occur in real content was not measured. Thebrvariant needsescapedTags. - What the damage looks like. Text after the tag is missing from the char-filter output and so from the index, up to the next real
</script>or</style>end tag, or to the end of the field value if none follows. No exception, with assertions on or off; whatever came before the tag is indexed normally, so the document looks fine. - Scale. Pure scanner logic, deterministic and independent of index size.
- Versions. 10.5.0, 10.5.1, 10.5.2, 10.6.0 (by reading) and main; 10.4.0 and older are not affected.
- How likely. Rare: the trigger is an unusual element name, and no report was found since 10.5.0 shipped (tag commit dated 2026-06-19).
The test shows that HTMLStripCharFilter (since 10.5.0, #15756) takes a start tag whose name only begins with script (<scripts>) for a <script> tag and drops everything after it up to a </script> that never comes.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.charfilter;

import java.io.StringReader;
import java.io.StringWriter;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestHTMLStripScriptPrefixName extends LuceneTestCase {

  public void testElementNameStartingWithScript() throws Exception {
    StringWriter out = new StringWriter();
    try (HTMLStripCharFilter f =
        new HTMLStripCharFilter(new StringReader("<scripts>hello</scripts> world"))) {
      f.transferTo(out);
    }
    // <scripts> is not <script>: expected "\nhello\n world" (as in 10.4.0), actual "" (all dropped)
    assertEquals("\nhello\n world", out.toString());
  }
}
# in a copy of this finding's repro folder (repro/LFV-780/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.charfilter.TestHTMLStripScriptPrefixName
- Expected vs actual
- Expected
"<scripts>hello</scripts> world"to strip to"\nhello\n world"(what 10.4.0 gives, and what main gives for any other name); actual""(expected:<[\nhello\n world]> but was:<[]>), with-eaand-da.
More files, environment, full output34 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: expected:<[
hello
 world]> but was:<[]>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.analysis.charfilter.TestHTMLStripScriptPrefixName.testElementNameStartingWithScript(TestHTMLStripScriptPrefixName.java:32)- Until 10.4.0 the script/style/br start-tag rules required whitespace after the name; #15756, fixing values ending in
=, dropped it without mentioning tag names. - Their end-tag rules match only the exact names; other unknown names keep their text (
<scrapes>). escapedTags: "Tags in this set (both start and end tags) will not be filtered out." With{brand},<brand>is.
The full argument353 words
- The design required a delimiter. From the 2012 JFlex rewrite (LUCENE-3690) through 10.4.0 the rules were
( \s+ {OpenTagContent} )?(script, style) and( ( "="\s* | \s+ ) {OpenTagContent} )?(br); 9.12.3, 10.0.0 and 10.4.0 pass the test. - #15756 was about something else. Its title, body, commit message, 4 comments, 2 reviews, CHANGES entry ("GITHUB#15754: Fix HTMLStripCharFilter to prevent tags from incorrectly consuming subsequent HTML when an attribute value ends with an equals sign.",
CHANGES.txt:1160-1161, 10.5.0 Bug Fixes) and its four tests are all about attribute values ending in=. Dropping\s+from the rules was the mechanical counterpart of moving it into the attribute macros. - The grammar's own handling of every other name. An unknown element goes through
{Name}: its tags become newlines and its text is kept. The end-tag rules for these three names match only the exact names (HTMLStripCharFilter.jflex:576,:862,:889). escapedTags. "Tags in this set (both start and end tags) will not be filtered out." (HTMLStripCharFilter.jflex:176-177).- Unknown tags keep their text. In LUCENE-5943 (apache/lucene#7005, closed "Not A Problem" in 2014) the reporter's
I love <pizza hut> so muchcame out as the tokensi,love,so,much: only the tag was removed. The filter's original author (sarowe) replied that angle brackets mark tags, which the filter strips, and confirmed with a test thatI love <pizza hut>strips toI love \n.I love <pizza hut> so muchstill strips toI love \n so muchon main, butI love <scripted hut> so muchnow losesso much. - HTML. In the HTML tokenizer a tag name ends only at whitespace,
/or>, so<scripts>is ascriptselement, not a script element. The oracle here is the grammar's own{Name}handling and 10.4.0, not WHATWG equivalence. - No test pins the prefix behaviour. No upstream test has a start tag named script, style or br followed by a name character; the existing ones (
<script attr= bare>,<style type=...>,<BR class='whatever'>) all have whitespace after the name.
The devil's-advocate check159 words
The strongest case for "intended": (a) the class only "attempts to strip out HTML constructs" (HTMLStripCharFilter.jflex:31), so it is best effort; (b) #15756 was reviewed and merged, so the new rules could be deliberate; (c) such element names are not standard HTML; (d) dropping too much is safer than letting script text through.
Why it fails: (a) best effort does not explain a behaviour change on markup the grammar handled the same way for 14 years; (b) nothing in #15756 discusses tag names; (c) the grammar accepts any XML-style name through {Name}, hyphenated custom elements are valid HTML element names, and LUCENE-5943 shows the intended handling of unknown tags; (d) the script and style states exist to remove script and style content, and a real <script> still matches as before; what is lost here is ordinary text, often the rest of the field. The escapedTags promise is broken outright. Every verifier rated the intended-behaviour case weak.
Recommended A. Require a delimiter after the name again, also accepting /
Require a delimiter after the name again in the three rules: whitespace, / or an attribute (a new AfterTagName macro), then regenerate the scanner. Validated: the new tests pass, all of :lucene:analysis:common:test passes (1,914 tests, 18 skipped, 0 failures) and check passes; <script/> and > inside attribute values keep main's behaviour.
+// Content after the BR, SCRIPT or STYLE tag name: it must start at a tag-name delimiter
+// (whitespace or '/', or an attribute, which starts with whitespace), so that a longer name
+// such as "scripts" or "brand" is not taken for one of these tags.
+AfterTagName = ( \s | "/" | {EventAttribute} | {OpenTagAttribute} ) {OpenTagContent}
...
-  \s* [bB][rR] ( "="\s* {OpenTagContent} | {OpenTagContent} )? \s* "/"? ">" {
+  \s* [bB][rR] ( "="\s* {OpenTagContent} | {AfterTagName} )? \s* "/"? ">" {
-  \s* [sS][cC][rR][iI][pP][tT] ( {OpenTagContent} )? \s*  ">" {
+  \s* [sS][cC][rR][iI][pP][tT] ( {AfterTagName} )? \s*  ">" {
-  \s* [sS][tT][yY][lL][eE] ( {OpenTagContent} )? \s* ">" {
+  \s* [sS][tT][yY][lL][eE] ( {AfterTagName} )? \s* ">" {
All options and trade-offs3 options · 704 words
Two grammar options were applied in a scratch worktree of a9779ef3c193, each with the scanner regenerated by ./gradlew :lucene:analysis:common:regenerateHTMLStripCharFilter (JFlex 1.9.1; it also updates the checksum file), and run against TestHTMLStripCharFilter (with the five new tests) and TestHTMLStripCharFilterFactory, assertions on and off.
A. Require a delimiter after the name again, also accepting / (validated by the checks) (recommended)
Add a macro AfterTagName = ( \s | "/" | {EventAttribute} | {OpenTagAttribute} ) {OpenTagContent} and use it instead of the bare {OpenTagContent} in the BR, SCRIPT and STYLE start-tag rules (HTMLStripCharFilter.jflex:658, :673, :682); keep the BR rule's "="\s* {OpenTagContent} alternative. Then regenerate HTMLStripCharFilter.java. Longer names then fall through to the generic {Name} rule like every other element.
+// Content after the BR, SCRIPT or STYLE tag name: it must start at a tag-name delimiter
+// (whitespace or '/', or an attribute, which starts with whitespace), so that a longer name
+// such as "scripts" or "brand" is not taken for one of these tags.
+AfterTagName = ( \s | "/" | {EventAttribute} | {OpenTagAttribute} ) {OpenTagContent}
...
-  \s* [bB][rR] ( "="\s* {OpenTagContent} | {OpenTagContent} )? \s* "/"? ">" {
+  \s* [bB][rR] ( "="\s* {OpenTagContent} | {AfterTagName} )? \s* "/"? ">" {
-  \s* [sS][cC][rR][iI][pP][tT] ( {OpenTagContent} )? \s*  ">" {
+  \s* [sS][cC][rR][iI][pP][tT] ( {AfterTagName} )? \s*  ">" {
-  \s* [sS][tT][yY][lL][eE] ( {OpenTagContent} )? \s* ">" {
+  \s* [sS][tT][yY][lL][eE] ( {AfterTagName} )? \s* ">" {
Trade-offs
- Keeps #15756's other change on purpose:
<script/>starts a script element (as in HTML, where/does not close a script element; 10.4.0 kept the text after it). So it is "restore the delimiter after the name, also accepting/", not a revert. - Real tags with attributes,
<br/>and a>inside a quoted attribute value behave as on main (probe); the BR rule's=alternative is unchanged. - The hunt's bounded-exhaustive harness with this fix: 0 mismatches in 655,889,580 runs (every sequence of up to 4 of 102 items: 64 base, 14 attribute and 24 prefix-name items; not independently re-run). Over all 551,880 strings of up to 4 of the harness's 27 symbols it changes main's output on 200 inputs (escapedTags off) and 298 (on), every one of them with
<script,<styleor<brdirectly followed by a non-delimiter (re-run by the fact check). Bounded evidence, not a proof.
What the checks validated
- The five new tests pass;
TestHTMLStripCharFilter(41 tests) andTestHTMLStripCharFilterFactory(7) pass with assertions on and off: 48 tests, 0 failures (stock: 4 failures). - All of
:lucene:analysis:common:testwith assertions on: 339 classes, 1,914 tests, 18 skipped, 0 failures, 0 errors. :lucene:analysis:common:check -x testpasses (generated-source checksum checks,checkGoogleJavaFormat,ecjLint,forbiddenApis).- The scanner regenerated by the build is byte-identical to the finder's (428,370 bytes; stock 428,378).
- A public-API probe with this scanner gives 10.4.0's output for every prefix input and main's output for every real-tag input (
<script/>,<br title="a>b">, an escaped script tag with>in an attribute).
( \s+ {OpenTagContent} )? for script and style, ( ( "="\s* | \s+ ) {OpenTagContent} )? for br: exactly the reverse of #15756's three rule edits.
Trade-offs
Smallest diff, but not 10.4.0's behaviour: #15756 also moved the leading \s+ into the attribute macros, so the rule's own \s+ eats the space an attribute needs, and a > inside a quoted value ends the tag. It also brings back 10.4.0's handling of <script/>. Not recommended.
What the checks validated
- The four prefix tests pass, and so do the 36 existing
TestHTMLStripCharFiltertests and the 7 factory tests; the guardtestScriptStyleAndBrTagsStillMatchfails with assertions on and off (48 tests, 1 failed):a<script/>f();</script>bgivesa\nf();\nb. - The probe shows a regression the existing tests miss:
one<br title="a>b">twogivesone\nb">two(main and 10.4.0:one\ntwo), and withescapedTags={script}the start tag<script title="a>b">is echoed as<script title="a>.
Route these names through the generic {Name} rule and switch state in its action by exact name, as escapedTags already does.
Trade-offs
A larger restructuring of the grammar; not prototyped.
Downstream html_strip char filters built on this class would drop the same text once they ship a Lucene 10.5.x release (inferred from the code; not run on a downstream product).
While writing a bounded-exhaustive checker for the HTML scanner (every sequence of up to 4 well-formed constructs, with exact expected output and offsets), the finder read the script/style/br start-tag rules, suspected the missing delimiter and added prefix-name probes. The stock jar failed thousands of runs at 2 constructs; the finder bisected it to #15756.
The method in full195 words
Method: bounded-exhaustive translation validation of the scanner (registry tier semi-formal: a hypothesis formed while modelling, then witnessed by the tool).
- The harness runs every sequence of up to 4 of 64 well-formed constructs, with 3
escapedTagsconfigurations and whole and 1-character Readers, on the stock jar, and compares the exact output and the per-character source offsets with values written from the grammar's documented replacement policy. On those items: 0 mismatches. - While writing the item table, the finder read the BR, SCRIPT and STYLE start-tag rules and added 8 prefix names (
brx,scripts,stylesheet,style-x,script-x,scriptx,styles,brand), each as a start tag, an end tag and a start tag with an attribute: 24 probe items, 88 in all. The stock main jar fails 3,960 to 5,152 runs already at up to 2 items, depending on the configuration; the fixed scanner fails 0 at up to 3. - The finder bisected the behaviour to #15756 (10.4.0 passes, 10.5.0 fails), ran a differential of 10.4.0 vs main vs the fixed grammar over all 551,880 strings of up to 4 symbols, and wrote the public-API JUnit and the fix.
No prior report found (searched 2026-10-27, re-checked): GitHub issues and PRs, including every apache/lucene item updated since March 2026 and all 409 open PRs, JIRA, the Lucene and Solr lists, downstream projects and the web. #15756 and #15754 introduced it but never mention tag names.
Searches6 searches
No report was found of start tags whose name only begins with script, style or br being handled as those tags, in Lucene or downstream.
| Where | When | How | Found |
|---|---|---|---|
| scripted prior-report search | 2026-10-27 | 81 queries: 30 GitHub issue/PR, 6 commit, 5 downstream, 32 mailing-list (dev@, java-user@, issues@, commits@), 8 JIRA; plus the finder's earlier 45-query run | 233 distinct hits, 0 high overlap; no report |
| GitHub (manual) | 2026-10-27 | 50 searches over apache/lucene, elastic/elasticsearch, opensearch-project/OpenSearch, apache/solr, apache/lucenenet and all of GitHub (tag names, prefixes, symptoms) | no report |
| apache/lucene, full enumeration | 2026-10-27 | every issue and PR updated since 2026-03-01 (1,314 items); the changed files of all 409 open PRs | only #15754 and #15756 concern HTML stripping; only #13157 (test-only) and #16911 (deletes branch_10x) touch HTMLStrip files |
| JIRA, mailing lists, web | 2026-10-27 | 10 JQL queries over LUCENE and SOLR; 35 queries over the Lucene and Solr lists; 7 web queries | no report; SOLR-10337 is unrelated (Tika-side) |
| Related items (read in full) | 2026-10-27 | #15756 (body, comments, reviews), #15754, #11724, #11556, #13157, #4764 (LUCENE-3690), OpenSearch #20554 and #20575 | attribute-value shapes only; none mentions tag names |
| GitHub re-check | 2026-10-27 | read-only gh search: newest apache/lucene issues and PRs naming HTMLStripCharFilter; 'html strip script', 'HTMLStrip stylesheet', 'htmlStrip tag name' | nothing newer than #15754 / #15756; no hits |
Introduced by #15756 (merged 2026-03-03, the fix for #15754) and first released in 10.5.0; 10.5.1, 10.5.2, 10.6.0 (by reading) and main are affected, 10.4.0 and older are not. Swapping only the generated scanner flips the result both ways. Not fixed upstream.
Versions tested5 rows
Introduced by #15756 "Fix HTMLStripCharFilter dropping content after =''>" (by Seungmin123, approved and merged by msfroh; fixes #15754): main 02014a6245d (2026-03-03), branch_10x backport b2640a889aa. git tag --contains b2640a889aa gives exactly 10.5.0, 10.5.1, 10.5.2 and 10.6.0. The three rule lines blame to the 2012 JFlex rewrite (LUCENE-3690, f3a363708ff) before it. Upstream main a95c754ee00 (2026-10-26) has the same grammar and scanner as a9779ef3c193; branch_10_5, branch_10_6 and branch_10x carry the 10.5.2 blobs; #15756 is still the last change to the grammar on every branch.
Releases before 9.12.3 were not executed; they have the pre-#15756 rules. Not run on x86 (pure scanner logic).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the five new tests: 4 fail through gradle (assertions on and off); the standalone JUnit 4 of 4 fail |
| 10.5.2, 10.5.1, 10.5.0 | affected | standalone JUnit 4 of 4 fail (10.5.0 and 10.5.2 with assertions on and off) |
| 10.4.0, 10.0.0, 9.12.3 | not affected | standalone JUnit 4 of 4 pass |
| 10.5.0, 10.5.2 and main with the scanner from before #15756 | bisect | pass 4 of 4 |
10.4.0 with the scanner of b2640a889aa (#15756) | bisect | fail 4 of 4 |
An independent reproducer with its own names, an intended-behaviour devil's advocate, an adjudication and a credibility audit each re-ran it and confirmed it. Reviews by a reviewer from another model family (OpenAI GPT-5.6, reading only) agreed on the root cause; one gave a procedural "not real" because it could not run Java.
Checks and verdicts382 words
Each check ran or re-ran a public-API test on the stock main jars; the run records are in the sources. All cross-model reviews were reading-only, so an executing cross-model review is still open. The three hunt reviews read main at ea57360912ed, whose HTMLStripCharFilter grammar, scanner, factory and both test classes are byte-identical to a9779ef3c193's (same git blobs). Every executed check agrees.
| Check | Verdict | What it found |
|---|---|---|
| Cross-model refute review | not real (low), procedural | An independent reviewer from another model family (OpenAI GPT-5.6), reading only: it could not run its own test, called its verdict "not a substantive source-level refutation", agreed on the root cause and rated the intended-behaviour case weak. A separate run re-ran the repro: 4 of 4 fail. Its suggested names (<scriptlet>, <stylebook>, escaped <breadcrumb>) were then run and behave as claimed. |
| Independent reproducer | real | Own 9-test JUnit with its own names (scripture, styles, style-box, scripting, scriptorium, brief, bridge, scripted) and controls: 8 of 9 fail on main with assertions on and off, 10.5.2 and 10.5.0; 9 of 9 pass on 10.4.0, 9.12.3 and with the fix. |
| Cross-model root-cause review | real (medium) | The same reviewer with a root-cause lens, reading only: root cause agreed, inputs in contract, intended case weak; a separate run re-ran the repro (main and 10.5.0 fail, 10.4.0 passes) and a 14-input probe on main, 10.4.0 and the fixed scanner. |
| Intended-behaviour devil's advocate | real | Built the strongest "intended" case and rejected it; probes with <script-editor>, KML <styleUrl> and I love <scripted hut>. |
| Adjudication | confirmed (high) | Re-ran the independent reproduction's test (main: 8 of 9 fail; 10.4.0: 9 of 9 pass) and the finder's (4 of 4 fail). |
| Credibility audit | keep | New seed and an own probe on main vs 10.4.0: every prefix shape loses text on main, none on 10.4.0; real script/style tags unchanged. |
| This doc's validation | reproduces; fix A validated | Gradle on a9779ef3c193: the five new tests fail 4 of 5 on stock and pass with fix A, assertions on and off; fix A passes the module's tests (1,914, 18 skipped, 0 failures) and check; fix B fails the guard test. A final run with the delivered test file gave the same results. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 419 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,366 words
- Registry title
- HTMLStripCharFilter (since 10.5.0) treats a start tag whose name only begins with script, style or br (<scripts>, <style-guide>, <stylesheet>, <brand>) as a script, style or br tag, so it silently drops all text after it up to the next </script> or </style> (often to the end of the value) and misapplies escapedTags to such names
- Area
- analysis / HTMLStripCharFilter (JFlex grammar: the BR, SCRIPT and STYLE start-tag rules of the LEFT_ANGLE_BRACKET state; also the 'htmlStrip' char filter SPI)
- Priority
- Medium, rank 128: A released 10.5.0 HTMLStripCharFilter regression that silently drops text at default settings after tags like <style-guide>, which is worse than LFV-317 and LFV-290 but rarer than LFV-311, so it is second in that group.
- Impact class
- silent wrong results
- Impact note
- Applications on 10.5.0 to 10.6.0 (10.6.0 by reading) or main that strip HTML with HTMLStripCharFilter (directly, through the 'htmlStrip' factory, or through a downstream html_strip char filter; no Lucene analyzer adds it by default), at default settings and at any index size, lose from the char-filter output, and so from the index, all text after a start tag whose name begins with 'script' or 'style' but is longer (hyphenated custom elements such as <style-guide> or <script-editor>, XML-like names such as <scripts>, <stylesheet> or KML's <styleUrl>), up to the next literal </script> or </style> or the end of the field value, with no exception; when escapedTags is set, a start tag such as <brand> is filtered although 'brand' is escaped (or kept when only 'br' is escaped), so start and end tags no longer match.
- Summary
- You strip '<scripts>hello</scripts> world' (or '<style-guide>hello</style-guide> world') with HTMLStripCharFilter and expect '\nhello\n world', which is what Lucene 10.4.0 gives and what main gives for the same shape with any other name, such as '<scrapes>'. Since 10.5.0 the output is empty: the start-tag rules for script and style no longer require a delimiter after the name, so the longer name is taken for a <script> or <style> tag and everything up to the next literal </script> or </style>, here the end of the input, is dropped (for '<stylesheet>hello</stylesheet> world' a StandardTokenizer after the filter emits no token at all). With escapedTags={brand}, '<brand>Acme</brand>' likewise comes out as '\nAcme</brand>' instead of unchanged.
- Introduced
- 02014a6245d329ae93898f281b52eb3203d3b343 (main; apache/lucene#15756 "Fix HTMLStripCharFilter dropping content after =''>" by GitHub Seungmin123, approved and merged by GitHub msfroh; it fixed #15754, an attribute value ending in '=') and its branch_10x backport b2640a889aa2de9882591e8ebaf4720ea6ce197c, first released in 10.5.0 [read: git log and git blame of HTMLStripCharFilter.jflex in the full-history clone: the BR, SCRIPT and STYLE rule lines (658, 673, 682) come from 02014a6245d, and before it they were unchanged since f3a363708ff (LUCENE-3690, the 2012 JFlex rewrite by GitHub sarowe); exec: swapping only the generated HTMLStripCharFilter.java between its pre- and post-#15756 versions flips the finder's JUnit both ways (10.5.0, 10.5.2 and main pass with the old scanner, 10.4.0 fails with the new one)] (2026-03-03 (merged 2026-03-03T19:17:27Z, author date 2026-03-04 +0900; branch_10x backport committed 2026-03-03))
- First affected version
- 10.5.0 [exec] (10.4.0 is the last unaffected release [exec])
- Affected versions
- 10.5.0, 10.5.1, 10.5.2, 10.6.0 (by reading) and main a9779ef3c193. [exec] the finder's JUnit (4 tests) fails 4 of 4 on 10.5.0 (-ea and -da), 10.5.1 (-ea), 10.5.2 (-ea and -da) and main (-ea and -da), and passes 4 of 4 on 9.12.3, 10.0.0 and 10.4.0 (-ea; 10.4.0 also -da); the independent reproduction's JUnit fails 8 of 9 on main, 10.5.0 and 10.5.2 and passes 9 of 9 on 10.4.0 and 9.12.3. [read] the branch_10_6 head (contained in 10.6.0) and the unreleased branch_10_5 and branch_10x heads (fetched 2026-10-24) carry the same grammar and scanner blobs as 10.5.2; 9.12.3 to 10.4.0 share the pre-#15756 grammar; releases before 9.12.3 were not executed but are unaffected by code (the three rules required a delimiter after the name from LUCENE-3690 in 2012 until #15756). Not run on x86 (pure scanner logic). Not fixed upstream: upstream main a95c754ee00 (2026-10-26) has the same grammar and scanner blobs, f7bcc0abd816 (prior-art search time) the same grammar, and #15756 is still the last change to HTMLStripCharFilter.jflex on main, branch_10x, branch_10_5 and branch_10_6.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check, code reading
- Upstream and prior reports
- none found (searched 2026-10-27, read-only; the prior-report record): the scripted prior-report search (81 queries: 30 GitHub issue/PR, 6 commit, 5 downstream, 32 mailing-list over dev@, java-user@, issues@ and commits@, 8 JIRA; 233 distinct hits, 0 high overlap) plus the finder's earlier 45-query run, 50 direct GitHub searches over apache/lucene, elastic/elasticsearch, opensearch-project/OpenSearch, apache/solr, apache/lucenenet and all of GitHub, an enumeration of all 1,314 apache/lucene issues and PRs updated since 2026-03-01 (only #15754 and #15756 concern HTML stripping), a changed-file scan of all 409 open apache/lucene PRs (only #13157, test-only, and #16911, which deletes branch_10x, touch HTMLStrip files), the commit history of HTMLStripCharFilter.jflex on main, branch_10x, branch_10_5 and branch_10_6, 10 JIRA queries over LUCENE and SOLR, 35 mailing-list queries over the Lucene and Solr lists, and 7 web queries. Not fixed upstream: #15756 is still the last change to the grammar on every branch. Nearest items, none a report of this bug: #15756 / #15754 (the introducing change and the issue it fixed; the whole thread is about attribute values ending in '=' and never mentions tag names), #11724 / #11556 and OpenSearch#20554 / #20575 (attribute-value shapes), #13157 (open, test-only), LUCENE-3690 / #4764 (grammar design), #6825, #6802, #6796, #4986, #14089, SOLR-10337, elasticsearch#151959 and #15543 (unrelated). Gaps: GitHub search is phrase-like, so a report that never names the class or html_strip would be missed; vendor forums were covered only by general web search; two web queries were throttled and retried; 'not found' is the best available evidence, not proof.
- Lucene commit tested
- main
a9779ef3c193(2026-10-26) through gradle in a scratch worktree: five newTestHTMLStripCharFiltermethods plusTestHTMLStripCharFilterFactorywith assertions on and off (stock: 4 of 5 new methods fail; fix A: all pass), fix A with all of:lucene:analysis:common:testand:lucene:analysis:common:check -x test, fix B with the two suites, each scanner regenerated by the build's own task; the worktree was removed afterwards. A public-API probe on main, 10.4.0 and the two fixed scanners. The hunt's standalone JUnit on the Maven Central jars 9.12.3, 10.0.0, 10.4.0, 10.5.0, 10.5.1 and 10.5.2 and on main, with commit-level scanner swaps at #15756; the independent checkers' tests and probes on main, 10.5.2, 10.5.0, 10.4.0 and 9.12.3.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilter.jflex :31 (class javadoc 'attempts to strip out HTML constructs'), :113-115 (EventAttribute, OpenTagAttribute with leading \s+; OpenTagContent with the [^<>] alternative), :149-154 (replacement characters), :176-177 (escapedTags javadoc 'Tags in this set (both start and end tags) will not be filtered out.'), :181-197 (br/script/style escaping by exact name), :275-296 (%eof Exclude branch for SCRIPT and STYLE), :658, :673, :682 (BR, SCRIPT and STYLE start-tag rules), :703-711 ({Name} rule), :862-912 (SCRIPT and STYLE states; exact-name end-tag rules)
- The finding in 30 seconds
a Lucene main checkout (a9779ef3c193) lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilter.jflex:69, :112-115, :149-150, :176-177, :181-197, :275-296, :576, :591-608, :658, :673, :682, :694-711, :860-912
- Who is affected
a Lucene main checkout (a9779ef3c193) lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilterFactory.java:42 (SPI name htmlStrip)
- Why it looks unintended
a Lucene main checkout (a9779ef3c193) lucene/CHANGES.txt:1158-1161 (10.5.0 Bug Fixes, GITHUB#15754)a Lucene main checkout (a9779ef3c193) lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilter.jflex:31, :176-177, :576, :862, :889a Lucene main checkout (a9779ef3c193) lucene/analysis/common/src/test/org/apache/lucene/analysis/charfilter/TestHTMLStripCharFilter.java:413-466 (existing script/style/br tests)apache/lucene#7005 (LUCENE-5943, read-only): the reporter's description (tokens i, love, so, much) and sarowe's testTrailingTag (`I love <pizza hut>` -> `I love \n`)
- History
a Lucene clone release tags (git tag --contains b2640a889aa)
- TestHTMLStripScriptPrefixName.java (JUnit test):
repro/LFV-780/src/org/apache/lucene/analysis/charfilter/TestHTMLStripScriptPrefixName.java(34 lines)
Summary card (bug.png), every element checked against the grammar at a9779ef3c193 and executed runs; see the diagram notes.
assets/LFV-780/bug.png(419 KB)