A doc-values field such as price = 42 holds a value per document but no searchable terms. IndexWriter records it as not indexed; MemoryIndex claims it is indexed with positions.
MemoryIndexindexes one document in memory so you can run queries against it. Its reader looks like a one-document index segment.- Each field has a
FieldInfo. Its index options say whether terms were indexed:NONEfor a doc value, point, vector or stored-only field;DOCS_AND_FREQS_AND_POSITIONSfor text with positions. Only indexed fields have norms. IndexWriter.addIndexes(CodecReader...)copies readers into an index;SlowCodecReaderWrapper.wrapadapts any reader. Since 9.0.0 the writer first checks every field'sFieldInfoagainst the schema the index already has.
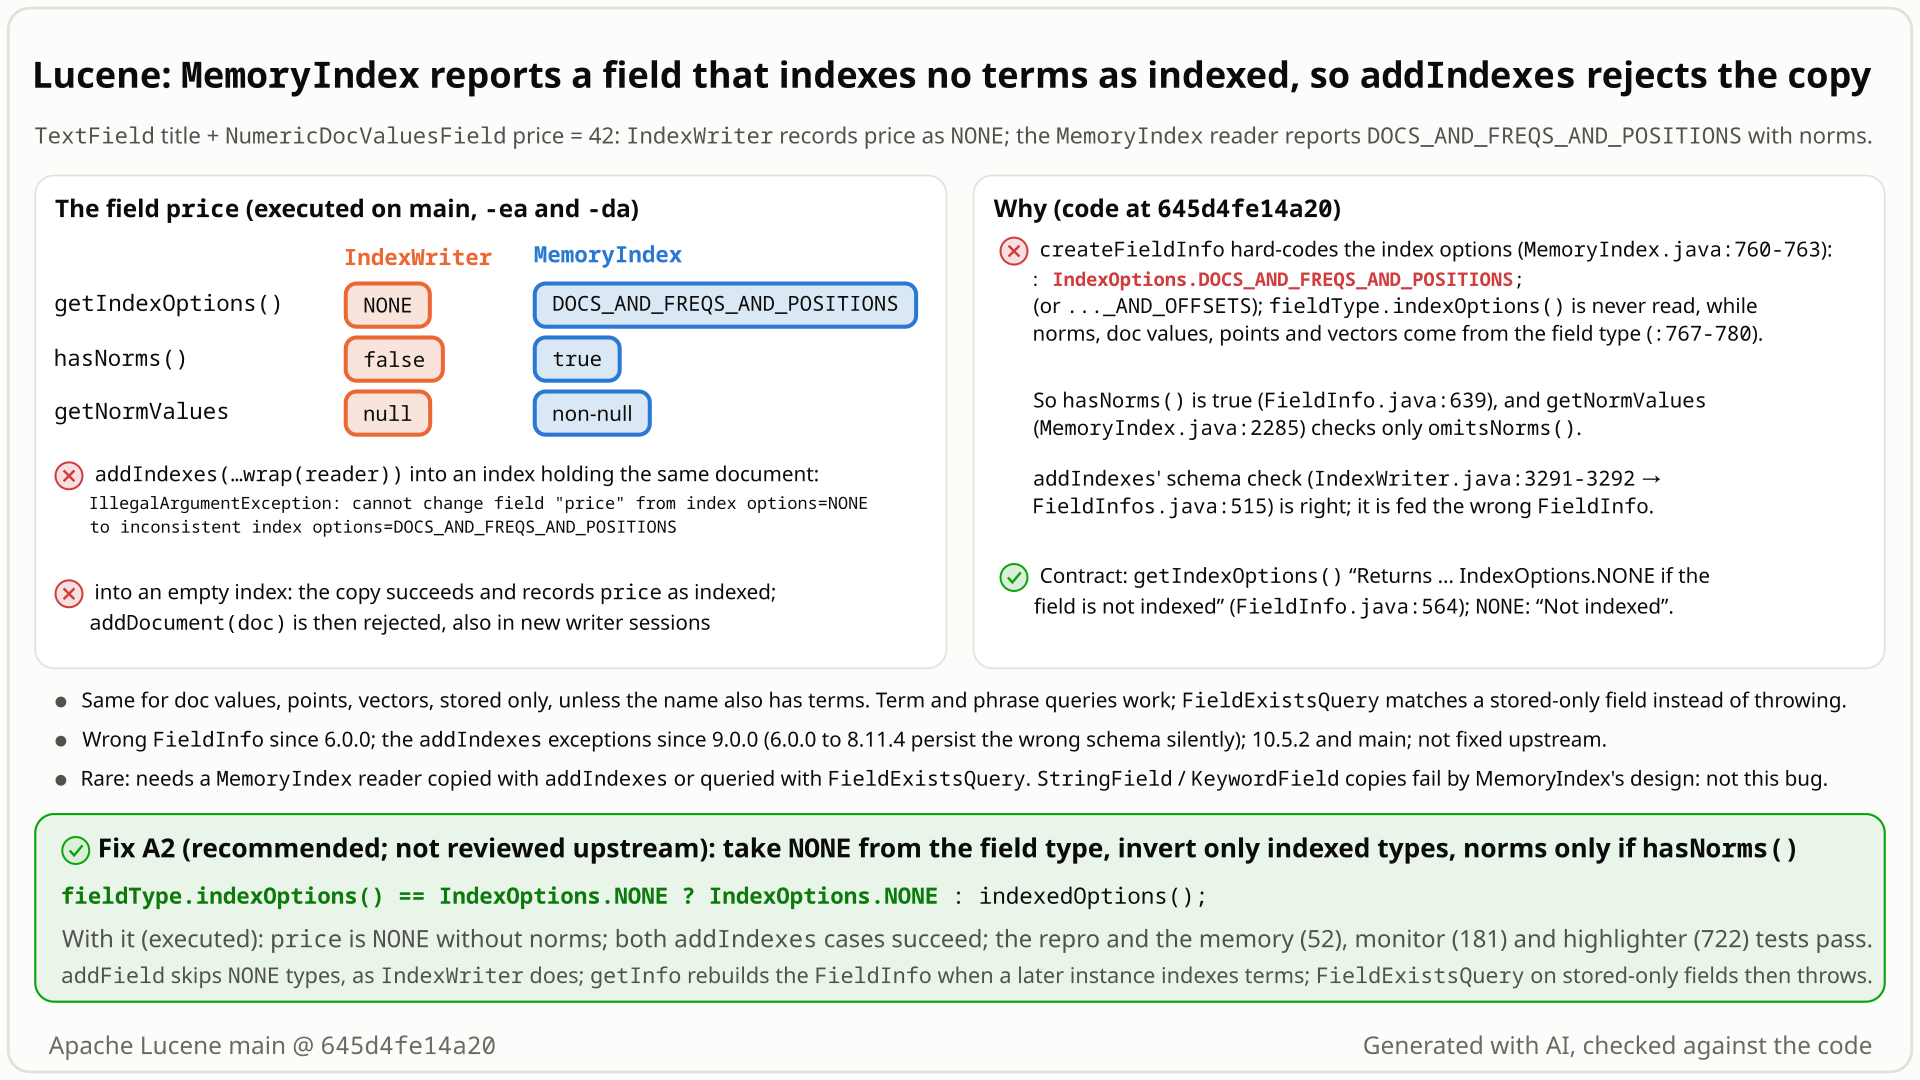
price field as IndexWriter records it (NONE, no norms) and as MemoryIndex reports it (positions, norms), and the two addIndexes failures that follow. Select the still to open it at full size. Generated with AI, checked against the code.- Build a
MemoryIndexfrom one document: aTextFieldtitleandNumericDocValuesField("price", 42).priceis only a doc value (for sorting or facets), so MemoryIndex stores no term for it. - Ask the reader how
priceis indexed. You expect whatIndexWriterrecords for the same document:NONE, no norms. You getDOCS_AND_FREQS_AND_POSITIONSwith norms, andFieldInfos.getIndexedFieldslists[price, title]instead of[title]. - On 9.0.0 or later, copy the reader with
addIndexes(SlowCodecReaderWrapper.wrap(reader))into an index that already holds this document. You expect 2 documents; you getIllegalArgumentException: cannot change field "price" from index options=NONE to inconsistent index options=DOCS_AND_FREQS_AND_POSITIONS. - Copy it into an empty index instead: the copy succeeds but records
priceas indexed, so a lateraddDocumentof the same document throws the reverse message, also after reopening the writer. 6.x to 8.x accept both steps silently. - Why:
MemoryIndexhard-codes positions as the index options of every field name and never reads the field type's ownindexOptions(). Doc-values, point, vector and stored-only fields are all affected; search on the MemoryIndex is not.
Applications that copy a MemoryIndex reader into a real index with addIndexes(SlowCodecReaderWrapper.wrap(reader)), or rely on its FieldInfos, for documents with doc-values, point, vector or stored-only fields. Default settings; one field is enough. Search on the MemoryIndex is unaffected. StringField/KeywordField documents and MemoryIndex(storeOffsets=true) fail that copy anyway, by design.
Mechanism, terms and numbers783 words
MemoryIndex accepts fields that index no terms: doc values, points, vectors and stored-only values. For each such field name (when no instance of the name indexes terms), its reader builds a FieldInfo whose index options are hard-coded to DOCS_AND_FREQS_AND_POSITIONS (..._AND_OFFSETS with storeOffsets), so hasNorms() is true and getNormValues returns a norms iterator, although the field type says NONE, MemoryIndex stores no term, and IndexWriter records NONE with no norms for the same document. FieldInfo#getIndexOptions promises NONE "if the field is not indexed".
Search on the MemoryIndex is unaffected; the wrong metadata shows when the reader is copied into an index with IndexWriter.addIndexes(SlowCodecReaderWrapper.wrap(reader)). On 9.0.0 and later, next to a natively indexed copy of the document the writer's schema check throws, and into an empty index the copy succeeds but persists the wrong schema, after which ordinary addDocument calls with that field are rejected, in later writer sessions too, until the copied documents are deleted before they are merged with other documents and a new writer is opened, or the index is rebuilt. FieldExistsQuery on a stored-only or point-only field also matches on a MemoryIndex where a real segment throws.
The metadata has been wrong since 6.0.0, when MemoryIndex started accepting fields without terms; the exceptions appear from 9.0.0, when the writer's strict schema checks arrived. A fix in MemoryIndex (take NONE from the field type, switch to positions when a later instance of the name indexes terms, serve norms only when hasNorms(), and, as IndexWriter does, invert only fields whose type indexes something) passes the repro and the lucene/memory, lucene/monitor and lucene/highlighter test suites.
- Accepting the field.
addField(IndexableField, Analyzer)callsgetInfo(field.name(), field.fieldType())first (MemoryIndex.java:622), so every field gets aFieldInfo. A null token stream withindexOptions() == NONEstores no term (:636-645); only the doc value, point, stored value or vector is kept (:647-679). - One FieldInfo per name.
getInfobuilds theFieldInfofrom the first instance of a name (:739-744); later instances only add point dimensions and the doc-values type (:745-755). - The hard-coded options (
createFieldInfo,:759-783):
   IndexOptions indexOptions =
       storeOffsets
           ? IndexOptions.DOCS_AND_FREQS_AND_POSITIONS_AND_OFFSETS
           : IndexOptions.DOCS_AND_FREQS_AND_POSITIONS;
fieldType.indexOptions() is never read. The other field-type settings come from the field type (term vectors, omitNorms, doc values, skip index, points, vectors: :767-768, :771-772, :775-780); payloads follow the MemoryIndex instance (:769), and the ordinal, doc-values generation, attributes (always empty) and the last two flags are not taken from it (:766, :773-774, :781-782).
- Norms follow.
FieldInfo#hasNormsisindexOptions != NONE && omitNorms == false(FieldInfo.java:637-640), andgetNormValuesreturns norms unlessomitsNorms()(MemoryIndex.java:2283-2289): a field with no postings gets a norm. - The writer's check is correct.
addIndexes(CodecReader...)verifies each sourceFieldInfobefore copying (IndexWriter.java:3288-3294->FieldInfos.java:401-409,:511-515->FieldInfo.java:276-288).SlowCodecReaderWrapper"Wraps arbitrary readers for merging" (SlowCodecReaderWrapper.java:38), and the MemoryIndex reader reportsVersion.LATESTmetadata (MemoryIndex.java:2292-2294), so the copy reaches the schema check, which is fed the wrongFieldInfo.
field f | MemoryIndex | IndexWriter |
|---|---|---|
NumericDocValuesField | POSITIONS, norms, in getIndexedFields | NONE, no norms |
StoredField (int) | POSITIONS, norms, in getIndexedFields; FieldExistsQuery counts 1 | NONE, no norms; FieldExistsQuery throws IllegalStateException |
IntPoint | POSITIONS, norms, in getIndexedFields; FieldExistsQuery counts 1 | NONE, no norms; FieldExistsQuery throws |
IntField, KnnFloatVectorField | POSITIONS, norms, in getIndexedFields | NONE, no norms |
TextField (control) | POSITIONS, norms | POSITIONS, norms |
terms("f") is null on both sides for every non-indexed kind. The hunt's matrix found the same for all five doc-values types (numeric, sorted and sorted-numeric also with a skip index), IntPoint 1D and 2D, LongField, float and byte vectors and StoredField string, int and binary; the other eight reader kinds it tested showed no exception and no mismatch (only an informational FieldInfo difference on the soft-deletes reader's own soft-deletes field). IntField comes from the devil's-advocate verifier's probe.
The FieldInfo is per field name, not per added instance. A name that also has an instance that indexes terms really has terms and is reported correctly: a TextField and a NumericDocValuesField both named f, in either order, give DOCS_AND_FREQS_AND_POSITIONS with norms in both readers. Only a name whose instances all index nothing gets the wrong metadata.
- Into an index holding the same document:
IllegalArgumentException: cannot change field "price" from index options=NONE to inconsistent index options=DOCS_AND_FREQS_AND_POSITIONS. - Into an empty index, then
addDocumentof the same document in a new writer:IllegalArgumentException: cannot change field "price" from index options=DOCS_AND_FREQS_AND_POSITIONS to inconsistent index options=NONE.
Exposure and likelihood521 words
- Who is exposed. Applications that build a MemoryIndex from ordinary
Documents with doc-values, point, vector or stored-only fields and then copy its reader into a persistent index withaddIndexes(SlowCodecReaderWrapper.wrap(reader)), read itsFieldInfos(getIndexOptions,hasNorms,getNormValues,FieldInfos.getIndexedFields), or runFieldExistsQueryon a stored-only or point-only field against it. DefaultIndexWriterConfig, codec and field classes; the one-field repro is enough, and no dependence on document size is apparent from the code. - Effect. On 9.0.0 and later, a clean
IllegalArgumentExceptionwhen the target already holds the field natively. Into an empty target, a committed segment that records the field as indexed with positions and norms; after it, ordinaryaddDocumentcalls with that field are rejected, in this and later writer sessions. That lasts until the copied documents are deleted before they are merged with other documents and a new writer is opened, or the index is rebuilt: deleting them in the same writer session does not help, and once they have been merged with other documents the wrong schema stays after deleting them andforceMerge. Not data corruption: the persisted segment is self-consistent andCheckIndex(level 3) is clean after copying this bug's documents (theCheckIndexfailures in the hunt's matrix come from term-vector fields, hunt row LFV-788). On 6.0.0 to 8.11.4 both steps are accepted silently and the wrong schema is persisted.FieldExistsQueryon a stored-only or point-only field counts 1 on the MemoryIndex where a real segment throwsIllegalStateException(it never matches a document without the field). - Scale. One field in one document suffices. In the hunt's matrix of 1,024 one- and two-field documents, copying a default
MemoryIndexinto an index holding the same document failed on a non-indexed field for 663 of them, in each merge mode (578 withMemoryIndex(true, true), where some fail first on a text field's offsets). - Limits to state plainly. The same copy also fails, by MemoryIndex's deliberate design and unchanged by the fix, for
StringFieldandKeywordField(every indexed field gets positions, soDOCSbecomesDOCS_AND_FREQS_AND_POSITIONS) and for every document of aMemoryIndex(storeOffsets=true)(text fields get offsets). The executed clean case is the defaultMemoryIndex(false, false)with positional text fields (the verifier ran only(false, false)and(true, true)); this bug blocks such documents when they also carry doc values, points, vectors or stored-only fields. So the strong claim is the reader'sFieldInfo/norms contract; theaddIndexesfailures are a limited consequence (the devil's-advocate verifier rates the reader defect high confidence and theaddIndexesframing medium). - Likelihood: rare. Every MemoryIndex with such a field name has the wrong metadata for it, but it shows only through these compositions. No matching public report was identified in the documented searches, although the code has been this way since 6.0.0 (2016).
- In-tree consumers.
lucene/monitormatches a single document through aMemoryIndex(true, true)(DocumentBatch.java:107-113) and a batch of several documents through anIndexWriter(:55-62,:71-74). Its presearcher walks the reader'sFieldInfosbut skips fields whoseterms()is null (TermFilteredPresearcher.java:103-108), so the wrong index options do not change which queries it selects.
One JUnit test in lucene/memory, public API only: a MemoryIndex from one NumericDocValuesField("price", 42), then the index options of price. It fails on main with assertions on and off, and on the 10.6.0 and 10.5.2 release jars.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index.memory;

import java.util.List;
import org.apache.lucene.analysis.standard.StandardAnalyzer;
import org.apache.lucene.document.NumericDocValuesField;
import org.apache.lucene.index.FieldInfo;
import org.apache.lucene.index.IndexOptions;
import org.apache.lucene.index.LeafReader;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestMemoryIndexDocValuesOnlyFieldInfo extends LuceneTestCase {

  public void testDocValuesOnlyFieldIsNotIndexed() {
    MemoryIndex mi =
        MemoryIndex.fromDocument(
            List.of(new NumericDocValuesField("price", 42)), new StandardAnalyzer());
    LeafReader reader = mi.createSearcher().getIndexReader().leaves().get(0).reader();
    FieldInfo fi = reader.getFieldInfos().fieldInfo("price");
    // Expected NONE, as IndexWriter records for this field; actual DOCS_AND_FREQS_AND_POSITIONS
    assertEquals("index options of \"price\"", IndexOptions.NONE, fi.getIndexOptions());
  }
}
cp $REPRO/TestMemoryIndexDocValuesOnlyFieldInfo.java $LUCENE/lucene/memory/src/test/org/apache/lucene/index/memory/
cd $LUCENE && ./gradlew :lucene:memory:test --tests org.apache.lucene.index.memory.TestMemoryIndexDocValuesOnlyFieldInfo -Ptests.seed=DEADBEEF -Ptests.asserts=true
# also with -Ptests.asserts=false
- Expected
priceis reported asIndexOptions.NONE, asIndexWriterrecords it.- Observed
AssertionError: index options of "price" expected:<NONE> but was:<DOCS_AND_FREQS_AND_POSITIONS>, with assertions on and off.
More files, environment, full output214 words
The test sits in the MemoryIndex package by convention; it uses no package-private access. Nothing random reaches the code path: it failed with every seed tried (DEADBEEF through gradle with assertions on and off; DEADBEEF, 5EED1234, 5EED3003 and 5EED3004 on a standalone runner with -ea and -da).
Suggested regression test: this same test, for example as a method of TestMemoryIndex.
The addIndexes consequence is not part of the repro. Adding a TextField title to the document and copying the reader with addIndexes(SlowCodecReaderWrapper.wrap(reader)) into an index that holds the same document throws cannot change field "price" from index options=NONE to inconsistent index options=DOCS_AND_FREQS_AND_POSITIONS, and copying into an empty index makes a later addDocument of the same document throw the reverse message (main 645d4fe14a20 and 10.6.0).
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); also the 10.6.0 and 10.5.2 release jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 (the only platform run; the code path is pure Java) |
TestMemoryIndexDocValuesOnlyFieldInfo > testDocValuesOnlyFieldIsNotIndexed FAILED
    java.lang.AssertionError: index options of "price" expected:<NONE> but was:<DOCS_AND_FREQS_AND_POSITIONS>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:5261ED1D894D8F3B]:0)
        at junit@4.13.2/org.junit.Assert.fail(Assert.java:89)
        at junit@4.13.2/org.junit.Assert.failNotEquals(Assert.java:835)
        at junit@4.13.2/org.junit.Assert.assertEquals(Assert.java:120)
        at org.apache.lucene.index.memory.TestMemoryIndexDocValuesOnlyFieldInfo.testDocValuesOnlyFieldIsNotIndexed(TestMemoryIndexDocValuesOnlyFieldInfo.java:36)
:lucene:memory:test (FAILURE): 1 test, 1  failure

# the same with -Ptests.asserts=false, on the standalone runner with -ea and -da,
# and on the 10.6.0 and 10.5.2 release jars; with the recommended fix: passesFieldInfo#getIndexOptionspromises "IndexOptions.NONE if the field is not indexed"; the field type saysNONE, MemoryIndex stores no term, andIndexWriterrecordsNONE.createFieldInfoalready takes norms, term vectors, doc values, points and vectors from the field type; the hard-coded options predate MemoryIndex accepting fields without terms (6.0.0).- With the fix, no
lucene/memory,lucene/monitororlucene/highlightertest fails.
The full argument350 words
- Contract.
FieldInfo#getIndexOptions: "Returns IndexOptions for the field, or IndexOptions.NONE if the field is not indexed" (FieldInfo.java:564);IndexOptions.NONE: "Not indexed" (IndexOptions.java:29);hasNorms: "Returns true if this field actually has any norms" (FieldInfo.java:637);FieldInfos.getIndexedFields: "fields that have a terms index" (FieldInfos.java:240);LeafReader#getNormValues: "or null if no NumericDocValues were indexed" (LeafReader.java:202-206). - The other field-type settings already follow the field type.
createFieldInfocopies term vectors, omitNorms, doc values, skip index, points and vectors from theFieldType(MemoryIndex.java:767-768,:771-772,:775-780); payloads follow the MemoryIndex instance flag (:769), and the ordinal, doc-values generation, attributes (always empty) and the soft-deletes and parent flags are not field-type settings (:766,:773-774,:781-782). LUCENE-7679 (#8730) moved the code there to re-use as many FieldType settings as possible and kept only the index options as they were. - History. The expression comes from LUCENE-4515 (
59476c30cf3, 2012), when every MemoryIndex field had a token stream: up to 5.5.x MemoryIndex rejected doc-values fields and failed on stored-only fields (null token stream); point fields did not exist before 6.0.0. LUCENE-7091 (#8147, doc values) and LUCENE-7093 (#8149, points), both in 6.0.0, started accepting fields without terms and gave them the same options; neither discussion mentions index options. Stored-only fields were accepted from 6.0.0 only as a side effect of their null token stream; MemoryIndex has kept stored values only since PR #11999 (first release 9.5.0), so before 9.5.0 such a field added only the wrongFieldInfoand no value. - Precedent. Wrong MemoryIndex
FieldInfobits were fixed as bugs before: LUCENE-6402 (#7462, "MemoryIndex should pass TestUtil.checkReader", the term-vector bit) and LUCENE-7679 (#8730, omitNorms). In PR #907 (LUCENE-10357, closed unmerged) GitHub user jpountz wrote that MemoryIndex should return nullTermsonly when the field does not exist or its index options are NONE. - No upstream test failed with the fix. With fix A2 (and, in the first brief, with fix A) the
lucene/memory,lucene/monitorandlucene/highlightersuites pass; this shows only that no tested code depends on the current value.
The devil's-advocate check155 words
Strongest case (the verifiers and the adjudication): MemoryIndex deliberately uses one set of index options per instance. Every indexed field gets positions, keyword fields get fake ones (#12139), and TestMemoryIndex#testKeywordWithoutTokenStream asserts freq and positions for DOCS and DOCS_AND_FREQS field types. MemoryIndex is a single-document search helper that never promised IndexWriter-identical FieldInfos or support as an addIndexes source; FieldInfo APIs are expert; and an indexed field without terms is legal ("ghost fields", LUCENE-10357).
Why it fails: that design covers fields that do index terms, for which MemoryIndex really stores (fake) positions, so their postings match their FieldInfo. For a field whose type says NONE, MemoryIndex stores nothing, and the FieldInfo constructor already normalizes non-indexed fields ("for non-indexed fields, leave defaults", FieldInfo.java:110-114), so reporting NONE does not clash with per-instance payloads. Ghost fields come from merges that drop every value of a field that was indexed; they do not make a never-indexed field indexed.
Recommended A2: report NONE when the field type indexes nothing, and index terms only when it does
In MemoryIndex: report IndexOptions.NONE when the field type indexes nothing, switch to the usual positions options when a later instance of the name does index terms, serve norms only when hasNorms(), and, like IndexWriter, index terms only for fields whose type is not NONE (one file). The repro and the lucene/memory, lucene/monitor and lucene/highlighter suites pass.
// addField(IndexableField, Analyzer): like IndexWriter, invert only fields whose type indexes something
if (field.fieldType().indexOptions() != IndexOptions.NONE) {
  ... // the existing token-stream / binary-value block; its "else if (... subsumes(DOCS))" becomes "else"
}
// createFieldInfo:
IndexOptions indexOptions =
    fieldType.indexOptions() == IndexOptions.NONE ? IndexOptions.NONE : indexedOptions();
// getInfo: rebuild the FieldInfo with indexedOptions() when a name first added without
// terms gets an instance that indexes terms (FieldInfo's index options are final)
// getNormValues:
if (info == null || info.fieldInfo.hasNorms() == false) {
  return null;
}
All options and trade-offs6 options · 1,095 words
The recommended fix is the finder's three-part sketch plus one guard in addField, applied to 645d4fe14a20 in a scratch worktree and run through gradle. The sketch alone, two partial variants and two alternatives are listed with why they fall short.
A2: report NONE when the field type indexes nothing, and index terms only when it does (validated by the checks) (recommended)
Four small changes in MemoryIndex.java (one file, +56/-24, most of it the re-indented addField block): createFieldInfo uses IndexOptions.NONE when fieldType.indexOptions() is NONE, else the old expression (now indexedOptions()); getInfo rebuilds the FieldInfo (its index options are final) with indexedOptions() and that instance's storeTermVectors/omitNorms when a name first added without terms gets an instance that indexes terms (Info.fieldInfo is not final, :1223, so it can be replaced); getNormValues returns null unless fieldInfo.hasNorms(); and addField(IndexableField, Analyzer) runs its existing term-storing block (:624-645) only when the field type's index options are not NONE, as IndexWriter does (IndexingChain.java:1481). The inner else if (... subsumes(IndexOptions.DOCS)) becomes else.
// addField(IndexableField, Analyzer): like IndexWriter, invert only fields whose type indexes something
if (field.fieldType().indexOptions() != IndexOptions.NONE) {
  ... // the existing token-stream / binary-value block; its "else if (... subsumes(DOCS))" becomes "else"
}
// createFieldInfo:
IndexOptions indexOptions =
    fieldType.indexOptions() == IndexOptions.NONE ? IndexOptions.NONE : indexedOptions();
// getInfo: rebuild the FieldInfo with indexedOptions() when a name first added without
// terms gets an instance that indexes terms (FieldInfo's index options are final)
// getNormValues:
if (info == null || info.fieldInfo.hasNorms() == false) {
  return null;
}
Trade-offs
- All parts are needed:
createFieldInfoalone would report a name first added as a doc value and then as aTextFieldasNONEalthough it has terms, becausegetInfobuilds theFieldInfoonce; norms must followhasNorms(); and without theaddFieldguard a custom field whose type saysNONEbut whose token stream emits terms would be reportedNONEwhile its terms stay searchable (option A). - Keeps MemoryIndex's deliberate design for fields that index terms (positions everywhere, offsets with
storeOffsets), soStringField/KeywordFieldandstoreOffsetscopies still fail as before. - Behaviour change:
FieldExistsQueryon a stored-only or point-only MemoryIndex field throwsIllegalStateException, as on a real segment, instead of matching (executed with A2 forStoredFieldandIntPointwith assertions on, and with fix A). - Behaviour change: a custom field whose type says
NONEbut whose token stream emits terms is no longer searchable in a MemoryIndex. It never was in anIndexWriterindex, andlucene/monitormatches a single document with a MemoryIndex and several with anIndexWriter(DocumentBatch.java:55-62,:71-74,:107-113), so the two batch kinds then agree. Stock field classes never produce such a field (Field.java:466-468). A2 does more than drop the terms: its guard sits before the token-stream call, soaddFieldno longer callstokenStream()for any field whose type saysNONE, asIndexWriter(IndexingChain.java:1481). A customIndexableFieldwhosetokenStream()has side effects (validation that throws, resources it opens or closes) no longer sees them run in a MemoryIndex; whether anyone relies on that is unknown. - Test gap: the custom-field case is shown only by standalone probes; neither the suggested regression test nor any gradle suite exercises it. Proposing A2 rather than A likely needs a focused test of a custom
NONEfield with a token stream, and agreement that such a field should not be searchable. - The
getInfopart also takes omitNorms from the first instance that indexes terms, which overlaps the first-instance case left by #8730 (LUCENE-7679).
What the checks validated
- Gradle, fresh scratch worktree of
645d4fe14a20, seed DEADBEEF: stock + test fails; with A2 the whole:lucene:memory:testpasses, 4 suites, 52 tests (the repro,TestMemoryIndex30,TestMemoryIndexAgainstDirectory16,TestSlicedIntBlockPool5), 0 failures, with assertions on and off;lucene/monitor(32 suites, 181 tests, 1 skipped) andlucene/highlighter(34 suites, 722 tests) pass with assertions on;:lucene:memory:check -x testpasses (google-java-format, ecjLint, forbiddenApis). - Standalone runner with the A2 class shadowed: the repro passes; the finder's four tests pass (both
addIndexesdirections succeed); a field-name probe matchesIndexWriterin all four cases, including the customNONEfield with a token stream (NONE, no norms, no terms, 0 matches). - Not run: the full Lucene test suite, nightly tests, benchmarks.
The first three parts of A2 only (one file, +33/-4): createFieldInfo takes NONE from the field type, getInfo upgrades on the first instance that indexes terms, getNormValues follows hasNorms().
Trade-offs
- Smaller and enough for every stock field class.
- Gap:
addFieldstores the terms of any non-null token stream whateverfieldType.indexOptions()says (MemoryIndex.java:636-637), whileIndexWriterinverts a field only when its index options are notNONE(IndexingChain.java:1481). For a customIndexableFieldwhose type saysNONEand whosetokenStreamreturns tokens (executed):IndexWriterreportsNONEand no terms; stock MemoryIndex reports positions, norms and searchable terms; with fix A MemoryIndex reportsNONEwithout norms but still serves the terms (terms("f")non-null, aTermQuerymatches), so its reader disagrees with itself. A2 closes this.
What the checks validated
- In the first brief (gradle, scratch worktree of
645d4fe14a20): the wholelucene/memorysuite, 52 tests, assertions on and off;lucene/monitor181 tests (1 skipped) andlucene/highlighter722 tests, 0 failures;:lucene:memory:check -x testpasses; the finder's four tests pass on the standalone runner. - In the hunt (standalone runner,
a9779ef3c193): the finder's 4 tests, the independent reproduction's 8 tests, the cross-model reviewers' own tests and the intended-behaviour check's probe pass with it.
Use NONE when the field type indexes nothing, nothing else.
Trade-offs
Mis-reports a name whose first instance has no terms and a later one has (read from getInfo, not run); leaves the norms keyed on omitsNorms().
Return null unless hasNorms().
Trade-offs
Removes nothing as long as the index options stay hard-coded (hasNorms() stays true); the addIndexes failures remain (read, not run).
Full IndexWriter parity, also for fields that index terms.
Trade-offs
Would also fix the StringField/KeywordField copies, but contradicts MemoryIndex's deliberate positions-for-every-indexed-field design that TestMemoryIndex#testKeywordWithoutTokenStream asserts and #12139 built on (read, not run).
Say in the javadoc that the reader is not an addIndexes source and its metadata is approximate.
Trade-offs
Leaves the FieldInfo#getIndexOptions contract broken for every consumer of the reader.
A product that copies MemoryIndex readers into its own indexes can, after one copy into an empty index (9.0.0 and later), be unable to add documents with that field, also in later writer sessions; the trigger is the application's own schema, not field values.
A bounded-exhaustive differential check copied every one- and two-field document built from 32 field kinds, from 10 kinds of reader, into indexes with addIndexes and compared the result with ordinary indexing. Only the two MemoryIndex readers failed, on every field kind that indexes no terms; the case was then reduced to a one-method JUnit test.
The method in full190 words
Method: semi-formal (bounded-exhaustive translation validation of the real jar), a hunt unit, 2026-10-27. The harness copied 32 field kinds as single-field documents and all 992 ordered pairs (1,024 documents) from 10 reader kinds (SegmentReader, one with a deleted document, MemoryIndex default and with offsets and payloads, ParallelLeafReader, FilterLeafReader, an ExitableDirectoryReader leaf, a SoftDeletesDirectoryReaderWrapper leaf, SortingCodecReader, FilterCodecReader), with a plain and a reordering merge policy, into three targets (empty then a native addDocument and forceMerge, holding the same document, holding it with the fields reversed). Oracles: no exception, equal content dumps, CheckIndex with slow checks. 20,480 cases and 123,410 checks with -ea on a9779ef3c193; replicated with 36 field kinds and a deliberately broken mutant reader with -da (28,512 cases, 174,514 checks; the mutant was caught).
Exceptions came only from the two MemoryIndex kinds. Besides this bug, the matrix also surfaced two related, already known MemoryIndex FieldInfo problems at the same code (term vectors without the FieldInfo flag, #7462 family, and settings taken from the first instance of a name, #8730), tracked as separate hunt rows (LFV-788 and LFV-342). The unit started from an executed lead of an earlier unit.
No prior report found (GitHub issues, PRs and commits of Lucene and three downstream projects, open PRs, mailing lists, the JIRA archive, the web; refreshed 2026-10-30). Closest: #8730 (LUCENE-7679), about omitNorms only.
Searches7 searches
Context, not reports: #8730 / LUCENE-7679 wrote today's createFieldInfo and kept the hard-coded options (a strict reading of its title could make this "known"; the adjudication and the prior-art search judged it new and the registry keeps "new"; the second cross-model fact check would count it as known for that reason); #8147 and #8149 added doc-values and point fields without discussing index options; PR #11999 (stored fields; GitHub user uschindler noted that merging a MemoryIndex into a conventional index goes through the LeafReader interface); PR #13633 (vectors); PR #907 (ghost fields, closed unmerged; jpountz's remark that MemoryIndex should return null Terms only if the field does not exist or its index options are NONE); #8447 and #8735 (open: immutability, per-field payloads); #7462 / LUCENE-6402 (the term-vector bit). Search limits: keyword search only; closed unmerged PRs that change MemoryIndex.java without naming it were not listed by file; one Stack Overflow question was seen by title only.
| Where | When | How | Found |
|---|---|---|---|
| GitHub (apache/lucene issues, PRs, commits; Elasticsearch, OpenSearch, Solr) | 2026-10-27 | two scripted prior-report searches (96 queries: 32 issue/PR, 3 commit, 4 downstream, 40 mailing-list, 8 JIRA-archive, 9 web) and 11 manual searches; the finder's 45 executed queries (6 web queries pending) and the devil's advocate's 40 earlier queries | no report; 29 logged hits, all about something else |
| Open apache/lucene PRs and file history | 2026-10-27 | changed files of all 409 open PRs; git log of MemoryIndex.java (-S DOCS_AND_FREQS_AND_POSITIONS, -S IndexOptions.NONE) | 17 open PRs touch the memory module or FieldInfo files; none changes the index options in createFieldInfo |
| Mailing lists, JIRA archive, web | 2026-10-27 | dev@, java-user@, issues@, commits@; LUCENE-7091, LUCENE-7093, LUCENE-7679, LUCENE-6402, LUCENE-10357 read | no report; a 2022 java-user@ thread documents addIndexes(SlowCodecReaderWrapper.wrap(...)) as a copy pattern |
| Refresh | 2026-10-30 | upstream head and MemoryIndex.java history; open PRs mentioning MemoryIndex; issue and PR searches for MemoryIndex with IndexOptions, addIndexes, FieldInfo, norms, SlowCodecReaderWrapper, inconsistent, FieldExistsQuery, createFieldInfo | no new item; no open PR mentions MemoryIndex; the file last changed with #16383 (2026-07-27) |
| Refresh | 2026-10-30 | upstream main head and MemoryIndex.java history; open PRs mentioning MemoryIndex; issues and PRs mentioning MemoryIndex updated since 2026-10-27 | no new item; MemoryIndex.java last changed with #16383 (2026-07-27) |
| Refresh | 2026-10-30 | upstream main head and MemoryIndex.java history; open PRs mentioning MemoryIndex (the issue searches hit the API rate limit) | no new item; upstream main 2f424fd428da; MemoryIndex.java unchanged since #16383 |
| Refresh (second-round fact check) | 2026-10-30 | issues and PRs mentioning MemoryIndex updated since 2026-10-27; MemoryIndex with addIndexes and createFieldInfo; upstream main head | no issue and no PR mentioning MemoryIndex updated since 2026-10-27; upstream main still 2f424fd428da |
Since 6.0.0 (LUCENE-7091, cf3eea264066, 2016, then points in LUCENE-7093); exceptions since 9.0.0, when the writer's strict schema checks (LUCENE-9334) arrived; unfixed on main and in 10.6.0.
Versions tested7 rows
LUCENE-7091 "Added doc values support to memory index" (GitHub issue #8147, a JIRA patch, no PR; Martijn van Groningen) is cf3eea264066 on main (committed 2016-03-15), 559432fcdcd8 on branch_6x and bd0803fd41c6 on branch_6_0, the one in 6.0.0. LUCENE-7093 (#8149, points, fe58313de027 on branch_6_0) widened it in the same release. The hard-coded expression itself is from LUCENE-4515 (59476c30cf3, 2012), correct while every MemoryIndex field had terms: up to 5.5.x MemoryIndex rejected doc-values fields and failed on stored-only fields, and point fields did not exist before 6.0.0. Stored values have been kept only since PR #11999 (first release 9.5.0; 89cfaa37720 on branch_9x, 66127f6e696 on main); before that a stored-only field added only the wrong FieldInfo. LUCENE-7679 (cecc44c731b in 6.5.0, 6696eafaae18 on main) moved it into createFieldInfo unchanged. LUCENE-9334 (d03662c48bfc, PR #11, 2021-04-14, 9.0.0) added the strict per-field schema checks that now reject the copy; they are correct. All 83 release tags from 6.0.0 to 10.5.2 contain the expression (read); the version table is from executed probes.
| Version or commit | Verdict | Result |
|---|---|---|
| 5.5.0, 5.5.5 | API absent | MemoryIndex rejects doc-values fields and fails on stored-only fields; point fields do not exist before 6.0.0 |
| 6.0.0, 6.0.1, 6.1.0, 6.4.2, 6.5.0, 6.6.6, 7.7.3, 8.11.4 | silent | wrong FieldInfo (positions, norms); the copy and the later addDocument are accepted and the wrong schema is persisted |
| 9.0.0, 9.1.0, 9.12.3, 10.5.2 | affected | wrong FieldInfo, and both addIndexes scenarios throw |
10.6.0 (4ae946e5a9b) | affected | the repro fails; the finder's test fails 3 of 4 (both addIndexes messages) |
main 645d4fe14a20 | affected | the repro fails (gradle; standalone runner with assertions on and off) |
upstream main 2f424fd428da | read | same code: MemoryIndex.java last changed by #16383 (2026-07-27), read 2026-10-30 |
with the fix (main 645d4fe14a20) | not affected | with fix A2 (recommended) or fix A: the repro passes, and so do the lucene/memory, lucene/monitor and lucene/highlighter suites |
The finder, cross-model reviews (OpenAI GPT-5.6, with code execution), more verifiers, an adjudication and a credibility audit rate it real; this doc's runs reproduced it on main, 10.6.0 and 10.5.2 and validated the fix.
Checks and verdicts441 words
Every check ran a repro of its own or re-ran one on stock jars. The hunt and its reviews ran on main a9779ef3c193 (the cross-model reviews' records name ea57360912ed); MemoryIndex, FieldInfo, FieldInfos and IndexWriter are identical there, and MemoryIndex.java is identical at 645d4fe14a20.
| Check | Verdict | What it found |
|---|---|---|
| finder (a hunt unit) | candidate | Bounded-exhaustive copy matrix (20,480 cases, replicated with 28,512 and a caught mutant): exceptions only for the MemoryIndex kinds. Public-API JUnit fails 3 of 4 on main, 10.5.2, 9.12.3, 9.1.0; passes with the fix. |
| cross-model review, refute lens (OpenAI GPT-5.6) | real, high | Own doc-values-only test fails 9 of 12 (-ea) and 6 of 8 (-da); indexed-text control passes; 12 of 12 with the fix; intended-behaviour argument weak. |
| Independent reproducer | real | Own 8-test JUnit fails 6 of 8 on main, 10.5.2 and 9.12.3 (doc-values, stored and point fields; both copy directions); controls pass; 8 of 8 with the fix. |
| Cross-model review, intended lens (OpenAI GPT-5.6) | real, high | Own binary-doc-values tests: the same on main, 10.5.2 and 9.12.3; wrong metadata without an exception on 8.11.4; upstream memory tests pass with the fix. |
| Devil's advocate | real; addIndexes framing limited | Found the FieldExistsQuery symptom and the StringField/KeywordField/storeOffsets limits; with the fix all five non-indexed kinds match IndexWriter. |
| adjudication | confirmed, high | Re-ran the independent reproduction's test with a new seed (6 of 8 fail, -ea and -da; 8 of 8 with the fix) and the finder's (3 of 4 fail, -da). |
| credibility audit | keep | Re-ran the finder's test with a fresh seed on main: 3 of 4 fail; class and score kept; reach caveats. |
| fact checks, two rounds (Claude; OpenAI GPT-5.6), and the diagram checks | errors and overclaims found, all fixed but one novelty call | Round 1: the persistence clause, the 5.5.x wording, the per-name scope, version qualifiers and the custom-field edge case, which fix A2 now closes. Round 2: the registry status, the matrix citation, the "not affected" scope, the clean-copy case, a storeDocValues citation, A2's skipped tokenStream() call and its test gap, and the diagrams now show A2. The reviewer's view that #8730 makes the bug "known" is left to the registry, which keeps "new". |
| this doc's runs | reproduced, fix validated | The one-method test on main through gradle and on the standalone runner (assertions on and off), and on 10.6.0 and 10.5.2; the finder's test on main and 10.6.0; fix A2 (and, in the first brief, fix A) with the memory suite and its in-tree consumers; the field-name probe with the fix. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 515 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,611 words
- Registry title
- MemoryIndex reports a field that indexes no terms (doc values, points, vectors or stored only) as indexed with positions and norms, so IndexWriter.addIndexes(SlowCodecReaderWrapper.wrap(reader)) fails next to the same document, or records the wrong schema in an empty index, after which the writer rejects that document
- Area
- memory / MemoryIndex reader FieldInfos (index options and norms of fields that index no terms); seen through the IndexWriter.addIndexes(CodecReader...) schema check and FieldExistsQuery
- Priority
- Low, rank 602: MemoryIndex reporting term-less fields as indexed mostly fails loudly at addIndexes and needs a rare composition to persist a wrong schema.
- Impact class
- crash
- Impact note
- Applications that put an ordinary Document with a field that indexes no terms (NumericDocValuesField and the other doc-values fields, IntPoint, the point and doc-values parts of IntField or LongField, KnnFloatVectorField, StoredField) into a MemoryIndex and copy its reader into a persistent index with IndexWriter.addIndexes(SlowCodecReaderWrapper.wrap(reader)) get IllegalArgumentException 'cannot change field ... inconsistent index options' when the target already holds that field as indexed natively, or, into an empty index, a committed segment that records the field as indexed with positions and norms, after which every ordinary addDocument with that field is rejected, also in later writer sessions, until the index is rebuilt; default IndexWriterConfig, codec and field classes, any scale, exceptions on 9.0.0 to 10.6.0 and main (6.0.0 to 8.11.4 accept the copy and silently persist the wrong schema); the wrong reader metadata is present for every such field in every MemoryIndex, but term and phrase queries are unaffected, and the only other in-tree symptom found is FieldExistsQuery matching a stored-only or point-only field where a real segment throws its documented IllegalStateException.
- Summary
- You build a MemoryIndex from a Document with a TextField title and a NumericDocValuesField price=42 (or a StoredField, IntPoint or vector field) and read its FieldInfo for price, or copy the reader into an index with IndexWriter.addIndexes(SlowCodecReaderWrapper.wrap(reader)), and expect what IndexWriter records for the same document: price is not indexed (IndexOptions.NONE, no norms), so the copy fits next to natively indexed copies of the document. Instead MemoryIndex reports price as DOCS_AND_FREQS_AND_POSITIONS with norms although it holds no terms for it, so addIndexes into an index holding the same document throws 'cannot change field "price" from index options=NONE to inconsistent index options=DOCS_AND_FREQS_AND_POSITIONS'. A copy into an empty index succeeds but records price as indexed, and addDocument of the same document then throws the reverse message, also in a new writer session.
- Introduced
- cf3eea264066 on main (LUCENE-7091 'Added doc values support to memory index', a JIRA patch, now GitHub issue #8147, no PR; backports 559432fcdcd8 on branch_6x and bd0803fd41c6 on branch_6_0, the one in 6.0.0), widened in the same release by LUCENE-7093 (#8149, point values, fe58313de027 on branch_6_0) [read: history clone; exec: 5.5.0 and 5.5.5 reject these field types, 6.0.0 has the bug]. Before it every MemoryIndex field had a token stream, so the hard-coded 'storeOffsets ? DOCS_AND_FREQS_AND_POSITIONS_AND_OFFSETS : DOCS_AND_FREQS_AND_POSITIONS' (from LUCENE-4515, 59476c30cf3, 2012) was accurate; LUCENE-7091 accepted fields without a token stream and gave them the same options. LUCENE-7679 (6696eafaae18; cecc44c731b in 6.5.0) moved the expression into createFieldInfo unchanged, LUCENE-9570 (7f8b7ffbcad2) only reformatted it. The visible exceptions come from the correct strict schema checks of LUCENE-9334 (d03662c48bfc, PR #11, 9.0.0), which are fed the wrong FieldInfo (2016-03-15 (committed; authored 2016-03-09); the addIndexes exceptions appear with LUCENE-9334, 2021-04-14)
- First affected version
- 6.0.0 [exec] (wrong reader-side FieldInfo; the finder and judge said 6.1, corrected by the version-history runs: LUCENE-7091 and LUCENE-7093 are in 6.0.0); the addIndexes exceptions first in 9.0.0 [exec]
- Affected versions
- Reader-side defect in every release from 6.0.0 to 10.6.0 (10.6.0 [exec] on the release jars, in the doc) and on main a9779ef3c193. [exec] the version-portable history probe (doc-values-only and stored-only index options, norms, both addIndexes scenarios) on 6.0.0, 6.0.1, 6.1.0, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.5.2 and main, and the finder's probe on 6.4.2 and 6.5.0; the finder's JUnit fails on 9.1.0, 9.12.3, 10.5.2 and main (-ea and -da on main); the independent reproduction's JUnit on main (-ea and -da), 10.5.2 and 9.12.3. addIndexes exceptions on 9.0.0 to 10.6.0 and main [exec]; 6.0.0 to 8.11.4 accept the copy and the later addDocument without an error and persist the wrong FieldInfo [exec]. Not affected: 5.5.0 and 5.5.5, where MemoryIndex rejects doc-values, point and stored-only fields [exec]. [read] the releases between the executed points: all 83 release tags from 6.0.0 to 10.5.2 contain the hard-coded expression and none reads fieldType.indexOptions() when building the FieldInfo. Unfixed: upstream main f7bcc0abd81 (2026-10-27) has no change under lucene/memory, and no open apache/lucene PR changes createFieldInfo's index options. Not checked: unreleased branches past 10.6.0, x86
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (searched 2026-10-27, read-only; the prior-report record, verdict new, confidence medium-high): two scripted prior-report searches (96 queries: 32 GitHub issue/PR, 3 commit, 4 downstream, 40 mailing-list over dev@, java-user@, issues@ and commits@, 8 JIRA archive, 9 web), 11 manual GitHub searches (apache/lucene, Elasticsearch, OpenSearch, Solr), the changed files of all 409 open apache/lucene PRs, the git history of MemoryIndex.java, and the finder's (51 queries) and the intended-behaviour check's (40) earlier runs. Related, not reports of this bug: #8730 / LUCENE-7679 (closed, fixed in 6.5.0; generic title 'MemoryIndex.addField() ignores some FieldType settings', but body, comments, fix and test are only about omitNorms of indexed fields and scores; it wrote createFieldInfo and kept the hard-coded index options; the known overlap of LFV-342), #8147 / LUCENE-7091 and #8149 / LUCENE-7093 (added doc-values and point fields to MemoryIndex; index options never discussed), PR #907 / #11393 (LUCENE-10357 ghost fields, closed unmerged; GitHub jpountz wrote there that MemoryIndex should return null Terms only if the field does not exist or does not index terms, indexOptions == NONE), PR #11999 (stored fields; GitHub uschindler: merging a MemoryIndex into a conventional index goes through the LeafReader interface), PR #13633 (vectors), #8735 / LUCENE-7684 and #8447 / LUCENE-7394 (open; per-field payloads and offsets), #7462 / LUCENE-6402 (FieldInfo term-vector bit, 2015). Not fixed: upstream main f7bcc0abd81 (2026-10-27) unchanged under lucene/memory; no open PR changes createFieldInfo's index options. Gaps: Stack Overflow question 78129318 read by title only; closed unmerged PRs that touch MemoryIndex.java without naming it were not enumerated
- Lucene commit tested
- main
645d4fe14a20(11.0.0-SNAPSHOT, commit of 2026-10-28) in scratch worktrees through gradle: the repro test stock (assertions on and off); with fix A2 (recommended) the wholelucene/memorysuite (assertions on and off), thelucene/monitorandlucene/highlightersuites and:lucene:memory:check -x test; the same with fix A in the first brief. On the standalone runner: the repro (-ea,-da), the finder's four-test class and a field-name probe, stock and with the fix. Release jars 10.6.0 (4ae946e5a9b) and 10.5.2. The hunt and its reviews ran on maina9779ef3c193, whereMemoryIndex.javais the same, and the history probe on release jars from 5.5.0 to 10.5.2. Upstream main2f424fd428dawas read on 2026-10-30. Only Linux aarch64 and OpenJDK 25.0.3 were run.
- Finding record
lucene/memory/src/java/org/apache/lucene/index/memory/MemoryIndex.java:759-783 (at a9779ef3c193) (createFieldInfo: indexOptions = storeOffsets ? DOCS_AND_FREQS_AND_POSITIONS_AND_OFFSETS : DOCS_AND_FREQS_AND_POSITIONS, while term vectors, omitNorms, doc values, skip index, points and vectors come from the FieldType), :732-757 (getInfo: the FieldInfo is built from the first instance of a name), :2283-2289 (getNormValues: norms unless fieldInfo.omitsNorms())lucene/core/src/java/org/apache/lucene/index/FieldInfo.java:564 (at a9779ef3c193) ('Returns IndexOptions for the field, or IndexOptions.NONE if the field is not indexed'), :637-640 (hasNorms 'Returns true if this field actually has any norms' = indexOptions != NONE && !omitNorms), :279 (verifySameIndexOptions); IndexOptions.java ('NONE: Not indexed'); FieldInfos.java:240 (getIndexedFields), :406, :515 (verifyFieldInfo / verifySameSchema)lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:3289-3294 (at a9779ef3c193) (addIndexes(CodecReader...) checks every source FieldInfo against the writer's schema); SlowCodecReaderWrapper.java:37-41 ('Wraps arbitrary readers for merging'); search/FieldExistsQuery.java:291 ('FieldExistsQuery requires that the field indexes doc values, norms or vectors')a Lucene main checkout: git diff ea57360912ed a9779ef3c193 touches none of lucene/memory, FieldInfo.java, FieldInfos.java or IndexWriter.java (SlowCodecReaderWrapper.java gains only a vector-access overload)
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/memory/src/java/org/apache/lucene/index/memory/MemoryIndex.java:620-680 (addField(IndexableField, Analyzer)), :732-757 (getInfo), :759-783 (createFieldInfo), :2283-2289 (getNormValues), :2292-2294 (getMetaData)a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/FieldInfo.java:110-114, :276-288, :564, :637-640a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/FieldInfos.java:401-409, :511-515; index/IndexWriter.java:3275, :3288-3294; index/SlowCodecReaderWrapper.java:38a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/document/Field.java:466-468 (tokenStream is null for NONE)
- Who is affected
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/FieldExistsQuery.java:38-41 (class javadoc; it does not mention the exception), :156, :211, :258, :290-291a Lucene main checkout (645d4fe14a20) lucene/monitor/src/java/org/apache/lucene/monitor/DocumentBatch.java:55-62, :71-74, :107-113; lucene/monitor/src/java/org/apache/lucene/monitor/TermFilteredPresearcher.java:103-108
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/FieldInfo.java:110-114, :564, :637-640; index/IndexOptions.java:29; index/FieldInfos.java:240; index/LeafReader.java:202-206a Lucene main checkout (645d4fe14a20) lucene/memory/src/java/org/apache/lucene/index/memory/MemoryIndex.java:759-783a Lucene main checkout (645d4fe14a20) lucene/memory/src/test/org/apache/lucene/index/memory/TestMemoryIndex.java:1093-1176 (testKeywordWithoutTokenStream)a Lucene main checkout (645d4fe14a20) lucene/memory/src/java/org/apache/lucene/index/memory/MemoryIndex.java:421, :475, :743, :766-782; lucene/core/src/java/org/apache/lucene/index/IndexableFieldType.java:121
- Suggested fix
a Lucene main checkout (645d4fe14a20) lucene/memory/src/java/org/apache/lucene/index/memory/MemoryIndex.java:620-680 (addField; term block :624-645, :636-637), :732-757 (getInfo builds the FieldInfo once), :1223 (Info.fieldInfo is not final), :2283-2289 (getNormValues)a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:1481; lucene/core/src/java/org/apache/lucene/document/Field.java:466-468; lucene/core/src/java/org/apache/lucene/index/FieldInfo.java:637-640a Lucene main checkout (645d4fe14a20) lucene/memory/src/test/org/apache/lucene/index/memory/TestMemoryIndex.java:1093-1176 (testKeywordWithoutTokenStream)a Lucene main checkout (645d4fe14a20) lucene/monitor/src/java/org/apache/lucene/monitor/DocumentBatch.java:55-62, :71-74, :107-113a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:1477-1489, :1950, :1981 (IndexWriter calls tokenStream only inside invert, which runs only for index options other than NONE)
- TestMemoryIndexDocValuesOnlyFieldInfo.java (lucene/memory test, one method):
repro/LFV-785/src/org/apache/lucene/index/memory/TestMemoryIndexDocValuesOnlyFieldInfo.java(38 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and the executed repro runs.
assets/LFV-785/bug.png(515 KB)