Lucene counts the first 1,000 hits of a top-n search exactly (the first n, if n is larger). After that it tells the scorer the n-th best score so far, and the scorer skips documents that cannot beat it. A search sorted by relevance through TopFieldCollector is meant to do the same, and did until 8.6.3.
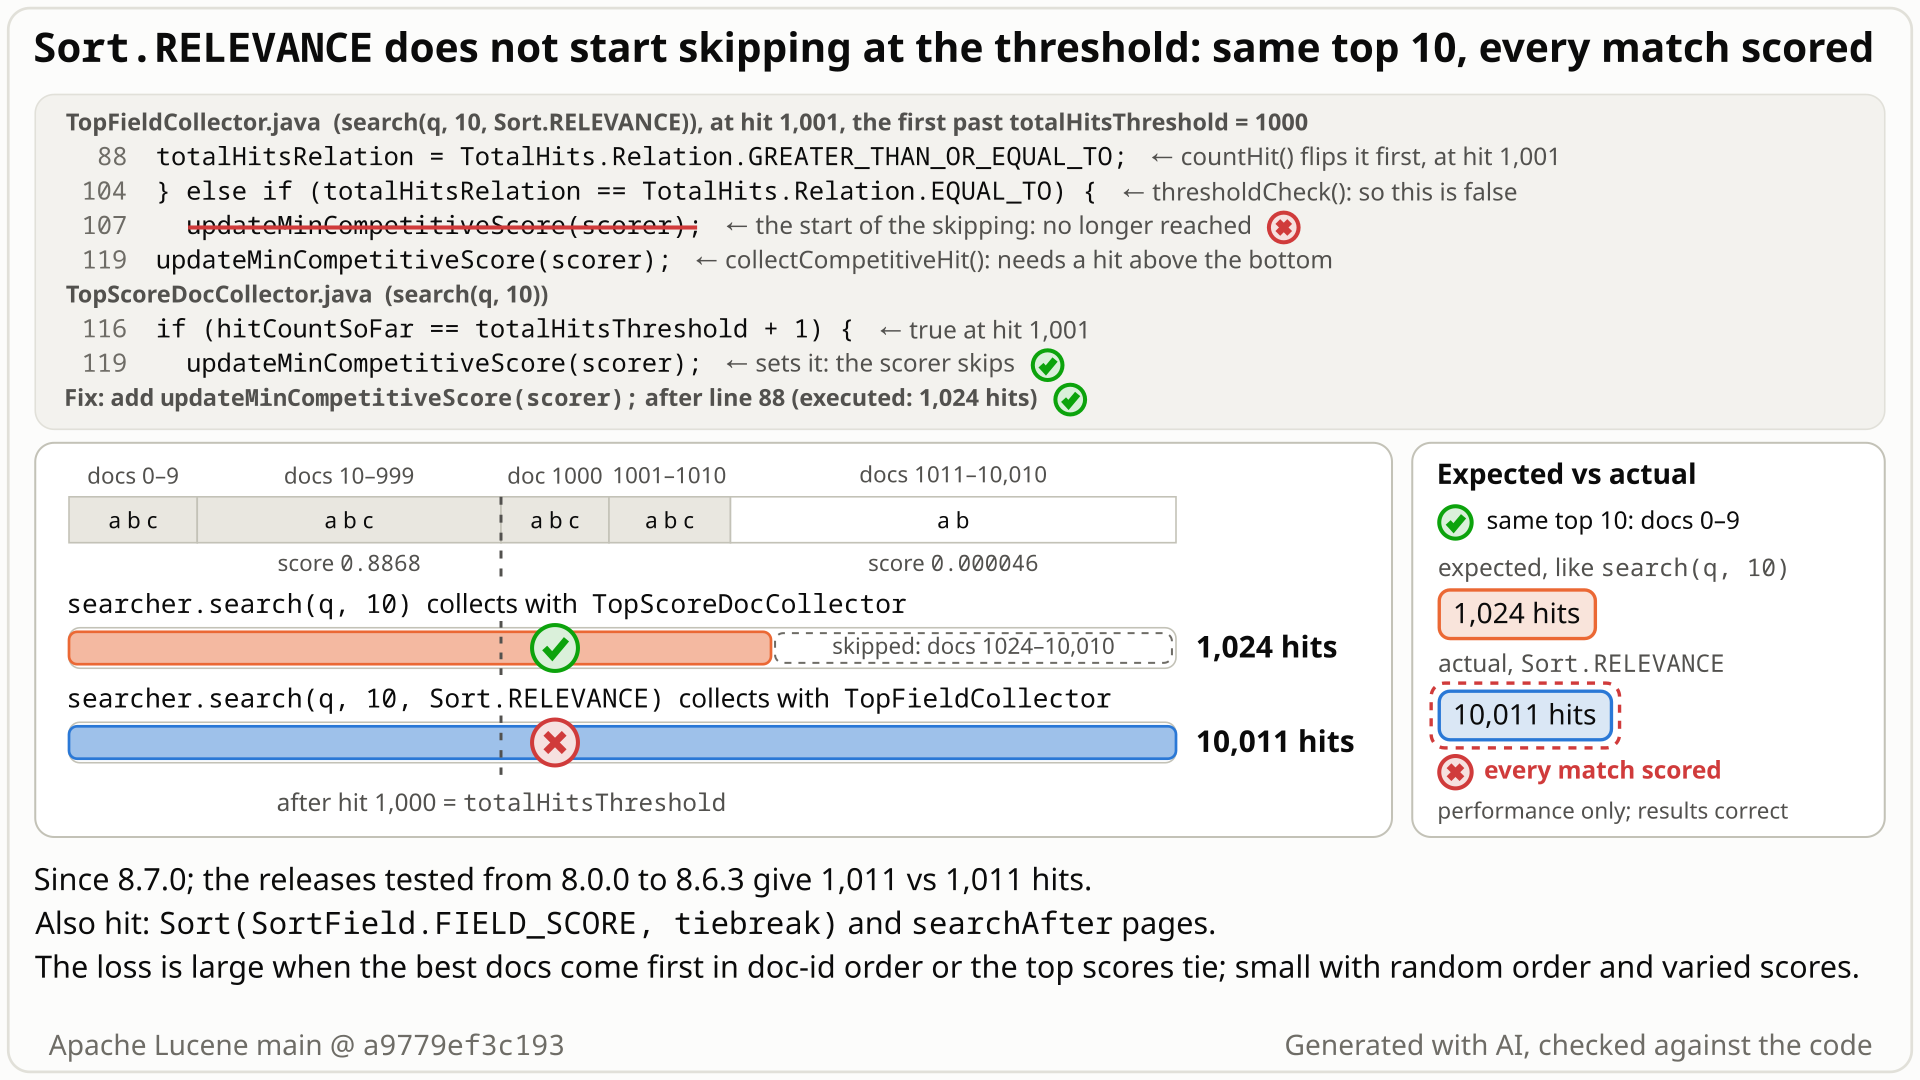
search(q, 10) passes 0.887 to the scorer, while the relevance sort flips its hit count first and never passes it. Same top 10, almost ten times the hits. Select the still to open it at full size. Generated with AI, checked against the code.- Index 10,011 documents: docs 0-1,010 contain "a b c" (score 0.887), the rest "a b" (score 0.00005). Search
a OR b OR cfor the top 10. search(q, 10)returns docs 0-9. On hit 1,001 it tells the scorer that only scores above 0.887 can still make the top 10; the scorer skips the rest, and the search stops after 1,024 hits.- You expect
search(q, 10, Sort.RELEVANCE), orSort(FIELD_SCORE, id)for paging that stays stable across index changes, to do the same, as Lucene 8.6.3 does: 1,011 hits for both. - Instead it returns the same docs 0-9 but scores all 10,011 matches. On hit 1,001 it first marks the hit count as "at least"; the call that would pass 0.887 to the scorer runs only while the count is still exact, so it never runs.
- Skipping then waits for a later hit that beats the 10th. Here none does, so nothing is skipped, and later segments would start with no minimum either. On a 200k-document index sorted by a static rank: 183,669 hits instead of 1,060.
Anyone sorting by relevance through TopFieldCollector with default settings: search(q, n, Sort.RELEVANCE), and searchAfter paging with Sort(FIELD_SCORE, tiebreak), which has no unsorted equivalent. The loss is large when no later hit beats the n-th best: best documents first (an index sorted by rank) or n tied top scores; random order with varied scores loses about 1.1-1.3x.
Mechanism, terms and numbers703 words
IndexSearcher#search(query, n) counts hits exactly up to 1,000 (or up to n when n is larger) and then passes the n-th best score to the scorer through Scorable#setMinCompetitiveScore, so the scorer can skip documents that cannot make the top n. A search sorted by relevance through TopFieldCollector (Sort.RELEVANCE, or Sort(SortField.FIELD_SCORE, tiebreak), which deep paging uses for an order that stays stable across index changes) is meant to do the same: LUCENE-8507 added it in 8.0.0, and 8.0.0, 8.5.2, 8.6.0 and 8.6.3 do it. Since 8.7.0 it no longer happens on the hit that crosses the threshold. TopFieldCollector.countHit (TopFieldCollector.java:77-90 on main a9779ef3c193) first sets totalHitsRelation to GREATER_THAN_OR_EQUAL_TO, and the updateMinCompetitiveScore call in thresholdCheck that should follow is guarded by totalHitsRelation == EQUAL_TO (:104-107), so it can never take effect; the searchAfter branch (:276-282) is dead the same way. Skipping starts only when a later hit beats the queue bottom, and later segments start with no minimum either. With the best documents first in doc-id order, or n hits tied at the top score already in the queue at the crossing, the search scores every match: 10,011 hits instead of 1,024 in the repro, 183,669 instead of 1,060 on a 200k-document index sorted by a static rank. Results, their order and the TotalHits lower bound stay correct; no wall-clock time was measured. Introduced by LUCENE-9449 (99220677fe4, apache/lucene-solr#1725). The fix calls updateMinCompetitiveScore right after the flip and removes the two dead branches; it does not help when every score ties, an older gap.
- Total hits threshold:
IndexSearchercounts hits exactly up toTOTAL_HITS_THRESHOLD = 1000(IndexSearcher.java:100), or up to n when n is larger (both collectors useMath.max(1000, n):TopScoreDocCollectorManager.java:69,TopFieldCollector.java:337); past it the count may become a lower bound (TotalHits.Relation.GREATER_THAN_OR_EQUAL_TO, printed as1024+ hits). - Minimum competitive score: once the threshold is passed and the top-n queue is full, the collector calls
Scorable#setMinCompetitiveScore(bottom score); scorers inScoreMode.TOP_SCORESmay then skip documents that score lower (ScoreMode.java:28-32). - Relevance-first sort: a
Sortwhose first field is descending relevance:Sort.RELEVANCE,new Sort(), orSort(SortField.FIELD_SCORE, tiebreak).TopFieldCollectorthen usesScoreMode.TOP_SCORESand may set the minimum score (canSetMinScore,TopFieldCollector.java:342-347).IndexSearcher#search(Query, int, Sort)andsearchAfter(..., Sort)build it with the 1,000 threshold (IndexSearcher.java:677-679,:719-735).
- Every hit runs
countHit(), thenthresholdCheck(doc)(true for a non-competitive hit) orcollectCompetitiveHit(doc)(TopFieldCollector.java:203-213). - On hit 1,001,
countHitsetstotalHitsRelation = GREATER_THAN_OR_EQUAL_TOfor every non-exhaustive score mode,TOP_SCORESincluded (:83-89). thresholdCheckthen reaches} else if (totalHitsRelation == TotalHits.Relation.EQUAL_TO) { // we can start setting the min competitive score if the threshold is reached for the first time here. updateMinCompetitiveScore(scorer); }(:104-107). The relation is no longerEQUAL_TO; and before the thresholdupdateMinCompetitiveScoredoes nothing, because it needstotalHits > totalHitsThreshold(:381). So this call can never have an effect. The "Already collected on a previous page" branch ofPagingFieldCollectorhas the same guard (:276-282).- Per hit, only
collectCompetitiveHitandcollectAnyHitstill callupdateMinCompetitiveScore(:114-132): skipping waits for a hit that strictly beats the queue bottom. (setScoreralso calls it,:139, but only without a shared accumulator, andTopFieldCollectorManager.java:90creates one for every finite threshold.) - Later segments read only the shared
MaxScoreAccumulatorinsetScorer(:135-143;TopFieldCollectorManager.java:90creates it for every finite threshold). It is filled only by a successfulupdateMinCompetitiveScore(:388-390), so they start with no minimum too. TopScoreDocCollectormakes the call on that same hit:if (hitCountSoFar == totalHitsThreshold + 1) { ... updateMinCompetitiveScore(scorer); }(TopScoreDocCollector.java:116-120).
10,011 documents in one segment; docs 0-1,010 "a b c" score 0.8867903, docs 1,011-10,010 "a b" score 4.6311867E-5; a OR b OR c, top 10. TopScoreDocCollector calls setMinCompetitiveScore(0.88679034) at hit 1,001 (doc 1,000) and collects 1,024 hits. The relevance-sorted TopFieldCollector never calls it and collects all 10,011. Same top 10 (docs 0-9). With the fix it calls setMinCompetitiveScore(0.8867903) at hit 1,001 and collects 1,024. Sort(FIELD_SCORE, id) and searchAfter page 2 behave the same, with one segment or six.
Exposure and likelihood337 words
- Who is exposed. Default settings and stable entry points:
IndexSearcher#search(q, n, Sort.RELEVANCE)(ornew Sort()),search(q, n, sort, doDocScores),searchAfter(after, q, n, sort)withSort(FIELD_SCORE, tiebreak), and anyTopFieldCollectorManagerwhose first sort field is descending relevance. A tie-break field after the score keeps a deep-paging order stable across index changes (doc ids break ties only within one reader), and there is noTopScoreDocCollectorequivalent for it. - Not exposed.
search(q, n)/TopScoreDocCollector; sorts whose first field is not descending relevance; exhaustive counts (totalHitsThreshold = Integer.MAX_VALUE). - When the loss is large. When no hit after the threshold strictly beats the n-th best. That happens when the best documents come first in doc-id order (for example an index sorted by a static rank with
IndexWriterConfig#setIndexSort) or when the top scores tie and the queue already holds n of them at the crossing (short fields, single terms: an equal-score later hit loses the tie on doc id).
| setup | search(q, n) | relevance-first sort |
|---|---|---|
10,011 docs, best 1,011 first, a OR b OR c (1 or 6 segments) | 1,024 | 10,011 |
| same, good docs spread (every 7th doc, tied top scores) | 2,308 | 10,011 |
20,000 docs, one TermQuery, best first or random order | 1,001 | 20,000 |
200k docs sorted by a rank field, term + FeatureField boost | 1,060 | 183,669 |
| random text, random order, varied scores (4 queries; 1.06-1.29x per query) | 1,032-1,181 | 1,090-1,519 |
- Effect. Extra scoring work only. Top hits, their order and the
TotalHitslower bound stay correct, and the collector keeps only its fixed-size top-n queue (memory was not measured). The worst case is scoring and comparing every match, more than an exhaustive count of the same query, which need not score. All numbers are hits collected; no wall-clock time was measured. - How likely. Plausible: every relevance-first sorted search past the threshold runs the dead code, but the big loss needs one of the two data shapes above. No earlier report was found in 236 recorded searches, although the code has been there since 8.7.0 (2020).
The test shows that a relevance-first TopFieldCollector (Sort.RELEVANCE, numHits 1, totalHitsThreshold 1) never calls Scorable#setMinCompetitiveScore when the threshold is exceeded by a non-competitive hit, so skipping cannot start.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search;

import java.io.IOException;
import org.apache.lucene.document.Document;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestRelevanceSortMinCompetitiveScore extends LuceneTestCase {

  static class RecordingScorable extends Scorable {
    float score;
    float minCompetitiveScore;

    @Override
    public float score() {
      return score;
    }

    @Override
    public void setMinCompetitiveScore(float minScore) {
      minCompetitiveScore = minScore;
    }
  }

  public void testMinCompetitiveScoreSetOnceThresholdIsExceeded() throws IOException {
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
        w.addDocument(new Document());
        w.addDocument(new Document());
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        LeafCollector leaf =
            new TopFieldCollectorManager(Sort.RELEVANCE, 1, 1)
                .newCollector()
                .getLeafCollector(reader.leaves().get(0));
        RecordingScorable scorer = new RecordingScorable();
        leaf.setScorer(scorer);
        scorer.score = 2;
        leaf.collect(0);
        scorer.score = 1;
        leaf.collect(1);
        // 2 hits > totalHitsThreshold 1, queue full: expected min score >= 2 (bottom), actual 0
        assertTrue(
            "expected min competitive score >= 2, got " + scorer.minCompetitiveScore,
            scorer.minCompetitiveScore >= 2f);
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-791/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.TestRelevanceSortMinCompetitiveScore
- Expected vs actual
- Expected: after hits scored 2 and 1, a min competitive score >= 2 (the queue bottom, as TopScoreDocCollector does); actual (-ea and -da):
expected min competitive score >= 2, got 0.0.
More files, environment, full output37 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected min competitive score >= 2, got 0.0
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.assertTrue(Assert.java:42)
org.apache.lucene.search.TestRelevanceSortMinCompetitiveScore.testMinCompetitiveScoreSetOnceThresholdIsExceeded(TestRelevanceSortMinCompetitiveScore.java:63)- LUCENE-8507 (8.0.0) made a relevance-first
TopFieldCollectorset the minimum score at the threshold; the dead branch's comment still says so. TopScoreDocCollectorstill does it, as did the four releases tested from 8.0.0 to 8.6.3; LUCENE-9449 dropped it, by every sign by accident: its threads never mention relevance.- Skipping is optional: a performance regression, not a broken contract.
The full argument337 words
- Documented intent.
lucene/CHANGES.txt:6850-6851(LUCENE-8507, 8.0.0): "TopFieldCollector can now update the minimum competitive score if the primary sort is by relevancy and the total hit count is not required." Its commit947f82679afput the call on the non-competitive branch, already behind today'stotalHitsRelation == EQUAL_TOguard ("we just reached totalHitsThreshold, we can start setting the min competitive score now"; 8.0.0TopFieldCollector.java:143-146). The guard then meant "minimum score not set yet": in 8.0.0 onlyupdateMinCompetitiveScore(:331) and the index-sort early termination (:138) setGREATER_THAN_OR_EQUAL_TO. LUCENE-8992 (8.4.0, branch_8x commit1c23a3c14e7; the master commit93d135e79d7first shipped in 9.0.0) gave the twoPagingFieldCollectorbranches the same guard. A related promise, from an entry about field comparators that skip documents:CHANGES.txt:4864-4869(LUCENE-9280), a finite totalHitsThreshold "instructs Lucene to skip non-competitive documents whenever possible". - The code says so. The comment on the dead branch: "we can start setting the min competitive score if the threshold is reached for the first time here" (
TopFieldCollector.java:105-106). - The sibling does it.
TopScoreDocCollector.java:116-120callsupdateMinCompetitiveScoreon the non-competitive hit withhitCountSoFar == totalHitsThreshold + 1. - It stopped, by every sign as a side effect. 8.0.0, 8.5.2, 8.6.0 and 8.6.3 skip; 8.7.0 and later do not. The 8.7.0 source with only the new flip suppressed for relevance-first collectors skips again. LUCENE-9449 changed the flip from
filteringLeafComparator != null && ...(never true for a relevance comparator) toscoreMode.isExhaustive() == false && ..., after a review suggestion on #1725 to setGREATER_THAN_OR_EQUAL_TO"every time a TOP_SCORES collection reaches the total hits threshold"; no comment on #1725, #1856 or #10489 mentions relevance sorts. The relation change itself was deliberate; nothing in the record shows that losing the minimum-score start was. - Tests. No upstream test asserts the current behaviour.
TestTopFieldCollector#testSetMinCompetitiveScorecrosses the threshold on a competitive hit; its comment "Make sure we do not call setMinCompetitiveScore for non-competitive hits" (:303) comes from the LUCENE-8507 commit and checks that the setter is not called again. It passes with the fix.
The devil's-advocate check214 words
The strongest case for "works as designed": ScoreMode.TOP_SCORES only "optionally" allows skipping (ScoreMode.java:28-32); TopFieldCollector is @lucene.experimental (TopFieldCollector.java:35); Sort.RELEVANCE "returns the same results as calling IndexSearcher#search() without a sort criteria, only with slightly more overhead" (Sort.java:36-41); and the 8.7.0 CHANGES entry for LUCENE-9449 says "TopFieldCollector sets TotalHits.relation to GREATER_THAN_OR_EQUAL_TO, as soon as the requested total hits threshold is reached, even though in some cases no skipping optimization is applied and all hits are collected" (8.7.0 release lucene/CHANGES.txt:19-23; not in main's CHANGES).
Why it fails: the skipping is a documented feature built for exactly this path and lost as a side effect of LUCENE-9449; the entry point IndexSearcher#search(Query, int, Sort) is stable API; scoring every match (4x-170x the hits of search(q, n) in the probes where it happens) is not "slight", and Sort(FIELD_SCORE, tiebreak) has no alternative. The 8.7.0 note explains why the reported relation can be a lower bound when every hit was collected; it does not announce that relevance-first sorts stop setting the minimum score, and the code comment still says they set it. Verdict: not intended, as far as the record shows (the relation change was deliberate; losing the minimum-score start at the threshold appears to be its side effect); a performance regression with correct results.
Recommended Set the score where the flag is flipped, and drop the dead branches
In countHit, call updateMinCompetitiveScore(scorer) right after the relation flips to GREATER_THAN_OR_EQUAL_TO, and delete the two EQUAL_TO-guarded calls that can no longer fire (+3/-9 in TopFieldCollector.java). The test passes, every relevance-first sort in the repro counts 1,024 hits, and the org.apache.lucene.search tests (2,333) and :lucene:core:check pass. It does not help when every score ties, an older gap.
if (scoreMode.isExhaustive() == false
    && totalHitsRelation == TotalHits.Relation.EQUAL_TO
    && totalHits > totalHitsThreshold) {
  // for the first time hitsThreshold is reached, notify comparator about this
  comparator.setHitsThresholdReached();
  totalHitsRelation = TotalHits.Relation.GREATER_THAN_OR_EQUAL_TO;
  // and start setting the min competitive score (only has an effect when the primary sort is
  // by relevance and the queue is full)
  updateMinCompetitiveScore(scorer);
}
All options and trade-offs4 options · 839 words
One fix was built and validated through gradle; the finder's one-line variant was validated with the standalone runner; two alternatives were not built.
Set the score where the flag is flipped, and drop the dead branches (validated by the checks) (recommended)
In countHit, call updateMinCompetitiveScore(scorer) after totalHitsRelation = GREATER_THAN_OR_EQUAL_TO; remove the else if (totalHitsRelation == EQUAL_TO) branch of thresholdCheck (TopFieldCollector.java:104-107) and the EQUAL_TO block in the PagingFieldCollector "Already collected on a previous page" branch (:278-282). 1 file, +3/-9.
if (scoreMode.isExhaustive() == false
    && totalHitsRelation == TotalHits.Relation.EQUAL_TO
    && totalHits > totalHitsThreshold) {
  // for the first time hitsThreshold is reached, notify comparator about this
  comparator.setHitsThresholdReached();
  totalHitsRelation = TotalHits.Relation.GREATER_THAN_OR_EQUAL_TO;
  // and start setting the min competitive score (only has an effect when the primary sort is
  // by relevance and the queue is full)
  updateMinCompetitiveScore(scorer);
}
Trade-offs
updateMinCompetitiveScorereturns at once unless the sort is relevance-first with a finite threshold, the queue is full and the threshold is passed (TopFieldCollector.java:381), so field sorts are untouched; the flip runs at most once per collector, so this is at most one extra call per collector (none for a collector whose relation the shared accumulator flipped first). The call passes the queue bottom from before the current hit is compared; that loses nothing, because a competitive crossing hit callsupdateMinCompetitiveScoreagain with the new bottom (:119). The removed blocks can never have an effect in any score mode.- For
searchAfter, if the page's queue is not full at the crossing, the existing call incollectAnyHit(:128-131) sets the score when it fills (but see the deep-page limit below). The score is also accumulated, so later segments start with it. - It passes the bottom score itself, as the competitive-hit path does, not
Math.nextUpasTopScoreDocCollectordoes. That is needed when a tie-break follows the score; withSort.RELEVANCEalone and tied top scores it still scores more thansearch(q, n)(1,187 vs 1,001 hits in one probe). That gap predates this bug (the 8.6.3 source also passes the bottom score). When every score is equal, A does not help at all (20,000 docs with body "a",TermQuery body:a):search(q, 10)collects 1,001,Sort.RELEVANCEandSort(FIELD_SCORE, id)20,000 with or without A (fact-check probe). - In a concurrent search, a collector whose relation the shared accumulator already flipped skips
countHit's block; its own bottom score then waits for its next competitive hit, and the shared score it has can be low. In a fact-check probe (two segments, one per slice, 40 searches each way) stockSort.RELEVANCEcollected 10,011 every time; with A 1,024-4,096 in 39 of 40 (3,072 in 28) and 10,011 once, when that edge hit;search(q, 10)collected 1,024-2,184. The counts depend on thread timing. - A deep page whose queue fills with tied low scores is not helped either: on the repro's index, the page after hit 1,005 collects 10,011 with or without A, against 1,051 for
searchAfter(q, 10). The page queue fills at hit 1,015 with the low score that every later doc ties: the samenextUpgap. - No wall-clock benchmark was run. Open PR #16857 rewrites the same leaf collector.
What the checks validated
- Scratch worktree of
a9779ef3c193, gradle: the new test fails 2 of 2 on the stock tree and passes 2 of 2 with the fix, with assertions on and off. - With the fix: 11 sort and collector suites (
TestTopFieldCollector,TestTopFieldCollectorEarlyTermination,TestSortOptimization,TestSearchAfter,TestTopDocsCollector,TestSortRandom,TestTopDocsMerge,TestSort,TestElevationComparator,TestSortRescorer, the new test), 108 tests, 0 failures, assertions off; the wholeorg.apache.lucene.searchpackage, 215 suites, 2,333 tests, 0 failures, assertions on;:lucene:core:check -x testpasses. - Standalone runner: the new test passes 20 of 20 over 10 seeds; the plain repro counts 1,024 for both searches.
The finder's +3-line diff: the same added call, nothing removed.
Trade-offs
Same behaviour, and the smallest patch to review; leaves two branches that can never fire and a comment that is no longer true.
What the checks validated
With the standalone runner: the finder's repro 1,024 vs 1,024 and 103 tests in 9 sort and collector classes pass; the independent reproducer's collector and searcher tests pass, and the devil's advocate's static-rank probe gives the score-sorted counts.
Skip the countHit flip when canSetMinScore is true, so the EQUAL_TO-guarded call fires again.
Trade-offs
Restores the skipping on 8.7.0 (executed as a shadow of the 8.7.0 source), but reverts the relation change LUCENE-9449 made on purpose and touches the documented 8.7.0 relation behaviour. More change for the same result.
Replace both totalHitsRelation == EQUAL_TO guards with totalHits == totalHitsThreshold + 1.
Trade-offs
Works for the non-competitive crossing hit and also covers the concurrent edge above (seen once in 40 concurrent searches with A), but must be repeated at each branch. Not built.
Downstream code relies on this skipping for score-plus-tiebreak sorts (Solr's BlockMax WAND support, SOLR-13289, names sort=score desc, id asc); no downstream report of the gap was found.
Found while testing sorted search: debugging another candidate, the finder saw a relevance-sorted collector count all 100 matches where the unsorted one stopped at 11. Reading countHit, thresholdCheck and the history explained it, and a public-API repro on main and release jars confirmed it. The unit's metamorphic harness compares results only, so it could not flag it.
The method in full122 words
Method: non-formal (code reading and testing, hunt unit on sorted search, score modes and threshold invariance, 2026-10-27, main a9779ef3c193).
- The unit's primary method was a metamorphic threshold-invariance check on the real jars (about 305M checks): a sorted search with a small
totalHitsThresholdmust return the same hits and sort values as the exhaustive one. It compares results only, so it cannot see a performance-only defect. - While debugging the unit's other candidate (in
DrillSidewaysQuery), the finder sawTopFieldCollectorManager(Sort.RELEVANCE, 10, 10)count all 100 matches whereTopScoreDocCollectorManager(10, 10)stopped at 11. - Reading
countHitandthresholdCheckandgit logled to LUCENE-9449; a public-APImain()repro failed on main, 10.5.2, 9.12.3 and 8.7.0 and passed on 8.6.3 and with a one-line shadowed fix.
No prior report found: 236 read-only queries on 2026-10-27 over Lucene issues, PRs, review threads and commits, the Lucene and Solr lists, JIRA, downstream trackers and the web, re-checked for this doc. Open PR #16857 rewrites the same leaf collector and keeps the dead calls.
Searches6 searches
Related, not reports of this bug: #9553 (LUCENE-8507, the feature that regressed); #10489, apache/lucene-solr#1725 and #1856 (LUCENE-9449, the introducing change, no comment mentions relevance sorts); #16857 "Consolidate Sort pruning logic" (open, rewrites the leaf collector, keeps countHit and both dead calls); #13313 (a general remark by jpountz that clustered scores slow min-score convergence); an Elasticsearch forum thread (2025-05) on [_score, tiebreak] being slower than _score (about 3k matches, below the default 10,000 threshold there, so probably not this); a Solr users@ thread (2024-02) whose cause was put on edismax and boost functions. Downstream code relies on the feature: SOLR-13289 and Elasticsearch PR #160658. Gaps: keyword search cannot prove absence; private reports and chat are not searchable.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs, review threads and commits (apache/lucene, apache/lucene-solr) | 2026-10-27 | 83 issue/PR and 12 commit queries; the review threads of every PR that touched these lines; 3 code checks (the changed files of all open apache/lucene PRs, branch heads, the history clone) | no report; #16857 touches the same lines |
| Downstream trackers (Elasticsearch, OpenSearch, Solr) | 2026-10-27 | 22 queries | no report; SOLR-13289 and Elasticsearch #160658 rely on the feature |
| Mailing lists | 2026-10-27 | 84 queries over Lucene dev@, java-user@, issues@, commits@ and Solr users@, dev@, issues@ | no report; a Solr users@ thread (2024-02) with another cause |
| JIRA archive (LUCENE, SOLR) | 2026-10-27 | 21 queries | no report |
| Web | 2026-10-27 | 11 queries | an Elasticsearch forum thread (2025-05), probably not this bug |
| GitHub (re-check for this doc) | 2026-10-27 | 4 issue searches (TopFieldCollector min competitive score; relevance sort setMinCompetitiveScore; Sort.RELEVANCE slower skipping; totalHitsThreshold relevance sort) and open PRs "TopFieldCollector"; upstream main 20ced71c1e6e read | nothing new; the bug is still on upstream main |
Introduced in 8.7.0 by LUCENE-9449 (99220677fe4, #1725, 2020), which flipped the hit-count relation for every non-exhaustive score mode; the feature it disabled came with LUCENE-8507 in 8.0.0. Executed: 8.0.0, 8.5.2, 8.6.0 and 8.6.3 skip; all 8 releases run from 8.7.0 to 10.5.2, and main, do not.
Versions tested8 rows
Introduced by 99220677fe409bab5c4206dc31f186d0c4335280 on master, "LUCENE-9449 Skip docs with _doc sort and \"after\" (#1725)" (mayya-sharipova, merged 2020-09-08; migrated issue #10489), backported to branch_8x as 754216821001772a0890d7245765e2ffb3f917f2 (apache/lucene-solr#1856, 2020-09-17), first released in 8.7.0. It replaced the flip condition filteringLeafComparator != null && ... (never true for a relevance comparator) with scoreMode.isExhaustive() == false && .... Between 8.6.3 and 8.7.0 only that backport and 7b128492828 (LUCENE-9384, whose flip cannot fire for a relevance comparator) touched the file. No commit-level build was done.
The regressed feature: LUCENE-8507 (947f82679af, 2018, 8.0.0), whose call already had today's EQUAL_TO guard (8.0.0 TopFieldCollector.java:143); LUCENE-8992 (8.4.0, branch_8x 1c23a3c14e7; master 93d135e79d7, first in 9.0.0) gave the two PagingFieldCollector branches the same guard. Later commits on these lines (LUCENE-9599, LUCENE-10208, #13943, #14714, #15150, #16434) kept the dead calls; upstream main 20ced71c1e6e (2026-10-27) still has them.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the new JUnit 2 of 2 fail (gradle and the standalone runner, assertions on and off, 10 iterations); the plain repro 1024+ vs 10011+ |
| 10.5.2 | affected | the new JUnit 2 of 2 fail; the plain repro 1024+ vs 10011+; static-rank probe 183,669 vs 1,060 |
| 9.12.3, 10.0.0, 10.1.0 | affected | plain repro 1024+ vs 10011+ |
| 8.7.0, 8.8.2, 8.11.4, 9.0.0 | affected | plain repro 1011+ vs 10011+; the Sort(FIELD_SCORE, id) variant fails on 8.7.0 and 8.11.4 |
| 8.7.0 source, flip suppressed for relevance-first collectors | shadow | 1011+ vs 1011+ (the unmodified 8.7.0 source fails) |
| 8.0.0, 8.5.2, 8.6.0, 8.6.3 | not affected | 1011+ vs 1011+ |
| 7.7.3 | no feature | both searches count all 10,011 (no relevance-first min-score propagation before 8.0.0; a variant of the repro that reads 7.x's long totalHits) |
| main + recommended fix | fix | 1024+ for every sort and page 2; the new JUnit passes |
An independent reproducer, an intended-behaviour devil's advocate and reviews by another model family (OpenAI GPT-5.6, reading-only) agree on the root cause; the adjudication re-ran the repros and confirmed it with high confidence. This doc's new JUnit and the recommended fix were run through gradle on main.
Checks and verdicts390 words
The cross-model reviews were reading-only: they could not run Java. The refute-lens review returned a procedural "not real, low" while agreeing on the root cause; a separate re-run of the repro failed.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Plain main() repro fails on main (-ea, -da), 10.5.2, 9.12.3, 8.7.0; passes on 8.6.3 and with the one-line fix; 103 upstream tests pass with it. |
| cross-model review, refute lens | not real, low (procedural) | OpenAI GPT-5.6, reading-only, ran no Java ("not a substantive refutation"); agreed on the root cause. A separate run re-ran the repro: fails. |
| Independent reproducer | real | Own collector JUnit (setMinCompetitiveScore at hit 101 for TopScoreDocCollector, never for RELEVANCE or FIELD_SCORE + int) and searcher JUnit (20,000 vs 1,001) fail on main (-ea, -da), 10.5.2 and 9.12.3; 8.6.3 passes; both pass with the fix. |
| Cross-model review, intended lens | real, medium | Reading-only; a separate executed scope check: 6 segments and searchAfter page 2 scan fully too; the fix restores every count. |
| Intended-behaviour devil's advocate | real, high | Built and rejected the "as designed" case; static-rank probe 183,669 vs 1,060 on main and 10.5.2, equal on 8.6.3 and with the fix; later segments scan fully too. |
| adjudication | confirmed, high | Re-ran the finder's repro and both independent reproduction JUnits on main (-ea, -da): all fail; with the fix, the finder's repro and the independent reproduction's collector test pass (the independent reproduction's searcher test was not re-run with the fix). |
| this doc | confirmed | New two-test JUnit fails through gradle and the standalone runner on main and 10.5.2; the recommended fix validated through gradle. |
| fact check of this doc | real; 2 wording errors, fixed | Re-ran the gradle commands on a clean copy of a9779ef3c193 (2 of 2 fail, assertions on and off; with fix A 67 tests in 6 suites pass) and the standalone runner on main, 10.5.2, 8.6.3 and 8.7.0. The guard history and two ratio ranges were corrected. |
| cross-model fact check | real; 4 errors (fixed) | OpenAI GPT-5.6, reading-only, over raw command outputs and a probe run for it. Its errors, overclaims and missing caveats were fixed or answered; the limits of fix A (all ties, a deep page of tied low scores, concurrent search) come from that probe. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 452 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,450 words
- Registry title
- A relevance-first TopFieldCollector (Sort.RELEVANCE or Sort(FIELD_SCORE, tiebreak)) never sets the minimum competitive score when totalHitsThreshold is crossed, so skipping starts only if a later hit is competitive, and the search can score every match (performance regression since 8.7.0; results correct)
- Area
- search / sorting (TopFieldCollector, relevance-first sort: minimum competitive score at the totalHitsThreshold crossing)
- Priority
- Low, rank 364: Performance-only with correct results, and the large loss needs a rank-ordered index or tied top scores; search(q, n) without a sort is not affected.
- Impact class
- minor
- Impact note
- Performance only, with default settings: every relevance-first sorted search with a finite totalHitsThreshold (IndexSearcher#search(q, n, Sort.RELEVANCE), searchAfter paging with Sort(FIELD_SCORE, tiebreak), which has no TopScoreDocCollector alternative, or a TopFieldCollectorManager with FIELD_SCORE first) skips nothing until some hit after the threshold strictly beats the queue bottom, in that segment and in every later one, so when the best documents come first in doc-id order (an index sorted by a static rank) or the top scores tie it scores every match (measured 10,011 vs 1,024, 20,000 vs 1,001 and 183,669 vs 1,060 hits collected against search(q, n)), while with random doc order and varied scores the loss is small (about 1.1-1.3x hits per query); top hits, their order and the TotalHits lower bound stay correct, and no wall-clock time was measured.
- Summary
- You run IndexSearcher#search(query, 10, Sort.RELEVANCE), or a searchAfter page sorted by Sort(SortField.FIELD_SCORE, tiebreak), on a query with many matches, and expect it to start skipping non-competitive documents once 1,000 hits are counted, as search(query, 10) does and as LUCENE-8507 made relevance-first TopFieldCollector do from 8.0.0 to 8.6.3. Instead TopFieldCollector.countHit flips totalHitsRelation to GREATER_THAN_OR_EQUAL_TO on the hit that crosses the threshold, before thresholdCheck's EQUAL_TO-guarded updateMinCompetitiveScore call runs, so that call can never take effect and the minimum competitive score is set only when a later hit is competitive; with the best documents first, the relevance-sorted search scores all 10,011 matches where search(query, 10) stops at 1,024, with the same top 10. This is a regression from LUCENE-9449 (8.7.0); results are always correct.
- Introduced
- 99220677fe409bab5c4206dc31f186d0c4335280 on master (apache/lucene-solr#1725 'LUCENE-9449 Skip docs with _doc sort and "after"', by mayya-sharipova, merged 2020-09-08; issue LUCENE-9449, migrated as apache/lucene#10489), backported to branch_8x as 754216821001772a0890d7245765e2ffb3f917f2 (apache/lucene-solr#1856, 2020-09-17), the commit that shipped in 8.7.0. In countHit it replaced the relation flip condition 'filteringLeafComparator != null && ...' (never true for a RelevanceComparator) with 'scoreMode.isExhaustive() == false && ...', which is true for TOP_SCORES, following a review suggestion on #1725 to set GREATER_THAN_OR_EQUAL_TO whenever a TOP_SCORES collection reaches the threshold; this made the EQUAL_TO-guarded updateMinCompetitiveScore call on the threshold-crossing non-competitive hit dead (that call came with LUCENE-8507, 947f82679af, 8.0.0, and was reworked in 93d135e79d7, LUCENE-8992, 8.4.0) [read: git show 99220677fe4, 75421682100, 947f82679af, 93d135e79d7; only 7b128492828 (LUCENE-9384, which cannot flip the relation for a relevance comparator) and 75421682100 touched TopFieldCollector.java between 8.6.3 and 8.7.0] [exec: release bracketing 8.6.3 pass / 8.7.0 fail, and the 8.7.0 TopFieldCollector source shadowed with only the new flip suppressed for relevance-first collectors passes, while the unmodified 8.7.0 source fails; no commit-level build] (2020-09-08 (master); 2020-09-17 (branch_8x backport, released in 8.7.0))
- First affected version
- 8.7.0 [exec: the finder's repro and its Sort(FIELD_SCORE, id) variant fail, 1011+ vs 10011+; the independent reproduction's searcher-level test fails]. Not affected: 8.0.0 through 8.6.3 [exec 8.0.0, 8.5.2, 8.6.0, 8.6.3: 1011+ vs 1011+]. Before 8.0.0 the feature did not exist [exec 7.7.3: both searches count all 10,011 hits].
- Affected versions
- every release from 8.7.0 through 10.6.0 (10.6.0 by reading) and main a9779ef3c193. [exec] the finder's repro fails on 8.7.0, 8.8.2, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.1.0, 10.5.2 and main (-ea and -da; follow-up sweep, JDK 25, seed DEADBEEF), its Sort(FIELD_SCORE, id) variant on 8.7.0, 8.11.4, 9.12.3, 10.5.2 and main; the independent reproduction's searcher-level JUnit fails on 8.7.0, 9.12.3, 10.5.2 and main, its collector-level JUnit (needs TopFieldCollectorManager, 9.9+) on 9.12.3, 10.5.2 and main; the intended-behaviour check's static-rank probe on 10.5.2 and main. [read] git tag --contains: 99220677fe4 is in every tag 9.0.0-10.6.0 and 75421682100 in 8.7.0, 8.8.0 and 8.8.1 (the history clone has no 8.8.2-8.11.4 tags; 8.8.2 and 8.11.4 by execution). Main e1faeba08bd [exec 2026-11-02, -ea and -da], branch_11x da3ea39fa59 (same TopFieldCollector.java as main) and branch_10_6 91eaab4fb29 (same as 10.6.0) still have the flip and the guarded calls [read 2026-11-02]. Not affected [exec]: 8.0.0, 8.5.2, 8.6.0, 8.6.3; 7.7.3 has no relevance-first propagation at all.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (the prior-report record verdict new, searched 2026-10-27, read-only: 236 logged queries, 83 GitHub, 12 commits, 22 downstream, 84 mailing-list, 21 JIRA, 11 web and 3 code, over apache/lucene issues, PRs and commits, the review threads of every PR that touched these lines, the dev@, java-user@, issues@ and commits@ Lucene lists, the Solr users@, dev@ and issues@ lists, the LUCENE and SOLR JIRA archive, the Elasticsearch, OpenSearch and Solr trackers and the web, plus the changed-file lists of all 409 open apache/lucene PRs; the independent reproduction and the intended-behaviour check ran their own GitHub searches). Not fixed upstream: main e1faeba08bd [exec], branch_11x da3ea39fa59 and branch_10_6 91eaab4fb29 [read] keep the flip and the EQUAL_TO-guarded calls (2026-11-02; branch_10x was decommissioned by #16911). #16857 'Consolidate Sort pruning logic' (merged 2026-10-29 as 70a428b5ba9, branch_11x 203699279f5) rewrote TopFieldCollector's leaf collector but kept countHit and the guarded calls, so it neither reports nor fixes this. Related, not reports: #9553 (LUCENE-8507, the feature that regressed), #10489 and apache/lucene-solr#1725 (LUCENE-9449, the introducing change; none of its comments mention relevance sorts), #13313 (a general remark that clustered scores slow min-score convergence), an Elasticsearch forum thread (2025-05) on [_score, tiebreak] being slower than _score alone (about 3k matches, below the default 10,000 threshold, so probably not this bug) and a Solr users@ thread (2024-02, cause put on edismax and boost functions).
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-27) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off and 10 derived seeds; the 10.5.2 release jars. The finder's plainmain()repro on 8.0.0, 8.5.2, 8.6.0, 8.6.3, 8.7.0, 8.8.2, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.1.0, 10.5.2 and main (and on 7.7.3 a variant that reads 7.x'slong totalHits), plus an 8.7.0 shadow pair that changes only the new flip. The recommended fix was validated in the scratch worktree through gradle: the new test with assertions on and off, 11 sort and collector suites (108 tests) with assertions off, the wholeorg.apache.lucene.searchpackage (215 suites, 2,333 tests) with assertions on, and:lucene:core:check -x test.
- Finding record
lucene/core/src/java/org/apache/lucene/search/TopFieldCollector.java:35 (at a9779ef3c193) (@lucene.experimental), :77-90 (countHit: for every non-exhaustive score mode, totalHits > totalHitsThreshold flips totalHitsRelation to GREATER_THAN_OR_EQUAL_TO), :92-112 (thresholdCheck: 'else if (totalHitsRelation == EQUAL_TO) { // we can start setting the min competitive score if the threshold is reached for the first time here. updateMinCompetitiveScore(scorer); }' at :104-107), :135-142 (setScorer: with an accumulator only updateGlobalMinCompetitiveScore), :276-282 (PagingFieldCollector 'Already collected on a previous page' branch, same EQUAL_TO guard), :337-347 (relevance-first descending sort with a finite threshold: ScoreMode.TOP_SCORES and canSetMinScore), :380-393 (updateMinCompetitiveScore requires canSetMinScore, queueFull and totalHits > totalHitsThreshold)lucene/core/src/java/org/apache/lucene/search/TopFieldCollectorManager.java:90 (at a9779ef3c193) (a MaxScoreAccumulator for every finite threshold)lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:100 (at a9779ef3c193) (TOTAL_HITS_THRESHOLD = 1000), :677-679 (search(Query, int, Sort)), :719-735 (searchAfter builds TopFieldCollectorManager(sort, n, after, TOTAL_HITS_THRESHOLD))lucene/core/src/java/org/apache/lucene/search/TopScoreDocCollector.java:116-120 (at a9779ef3c193) (the unsorted collector calls updateMinCompetitiveScore on the non-competitive hit with hitCountSoFar == totalHitsThreshold + 1)lucene/core/src/java/org/apache/lucene/search/ScoreMode.java:28-32 (at a9779ef3c193) (TOP_SCORES: scorers 'will optionally allow skipping'); Sort.java:36-41 (Sort.RELEVANCE: same results 'only with slightly more overhead')lucene/CHANGES.txt:6850 (at a9779ef3c193) (LUCENE-8507: 'TopFieldCollector can now update the minimum competitive score if the primary sort is by relevancy and the total hit count is not required'), :4871 (LUCENE-9449)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/search/TopFieldCollector.java:77-90, (at a9779ef3c193) :92-112 (:104-107), :114-143, :203-213, :276-282, :342-347, :380-393lucene/core/src/java/org/apache/lucene/search/TopFieldCollectorManager.java:90; (at a9779ef3c193) IndexSearcher.java:100, :677-679, :719-735; ScoreMode.java:28-32; TopScoreDocCollector.java:113-120
- Who is affected
lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:677-679, (at a9779ef3c193) :691-693, :719-735; TopFieldCollector.java:342-354
- Why it looks unintended
lucene/CHANGES.txt:6850-6851, (at a9779ef3c193) :4864-4869lucene-history releases/lucene-solr/8.7.0:lucene/CHANGES.txt:19-23lucene/core/src/java/org/apache/lucene/search/TopFieldCollector.java:35, (at a9779ef3c193) :105-106; TopScoreDocCollector.java:116-120; ScoreMode.java:28-32; Sort.java:36-41lucene/core/src/test/org/apache/lucene/search/TestTopFieldCollector.java:269-328 (at a9779ef3c193) (:303)
- Suggested fix
lucene/core/src/java/org/apache/lucene/search/TopFieldCollector.java:122-132, (at a9779ef3c193) :363-393; TopScoreDocCollector.java:113-120
- TestRelevanceSortMinCompetitiveScore.java (JUnit test):
repro/LFV-791/src/org/apache/lucene/search/TestRelevanceSortMinCompetitiveScore.java(69 lines)
The PNG is the final summary card. It was made in parallel with this doc.
assets/LFV-791/bug.png(452 KB)