The document suggester stores each suggestion in an FST as its analyzed bytes, then the end byte 0x00, then one or more dedup bytes. SuggestField refuses U+0000 in the value you pass, but the analyzed form, which is what reaches the FST, is never checked.
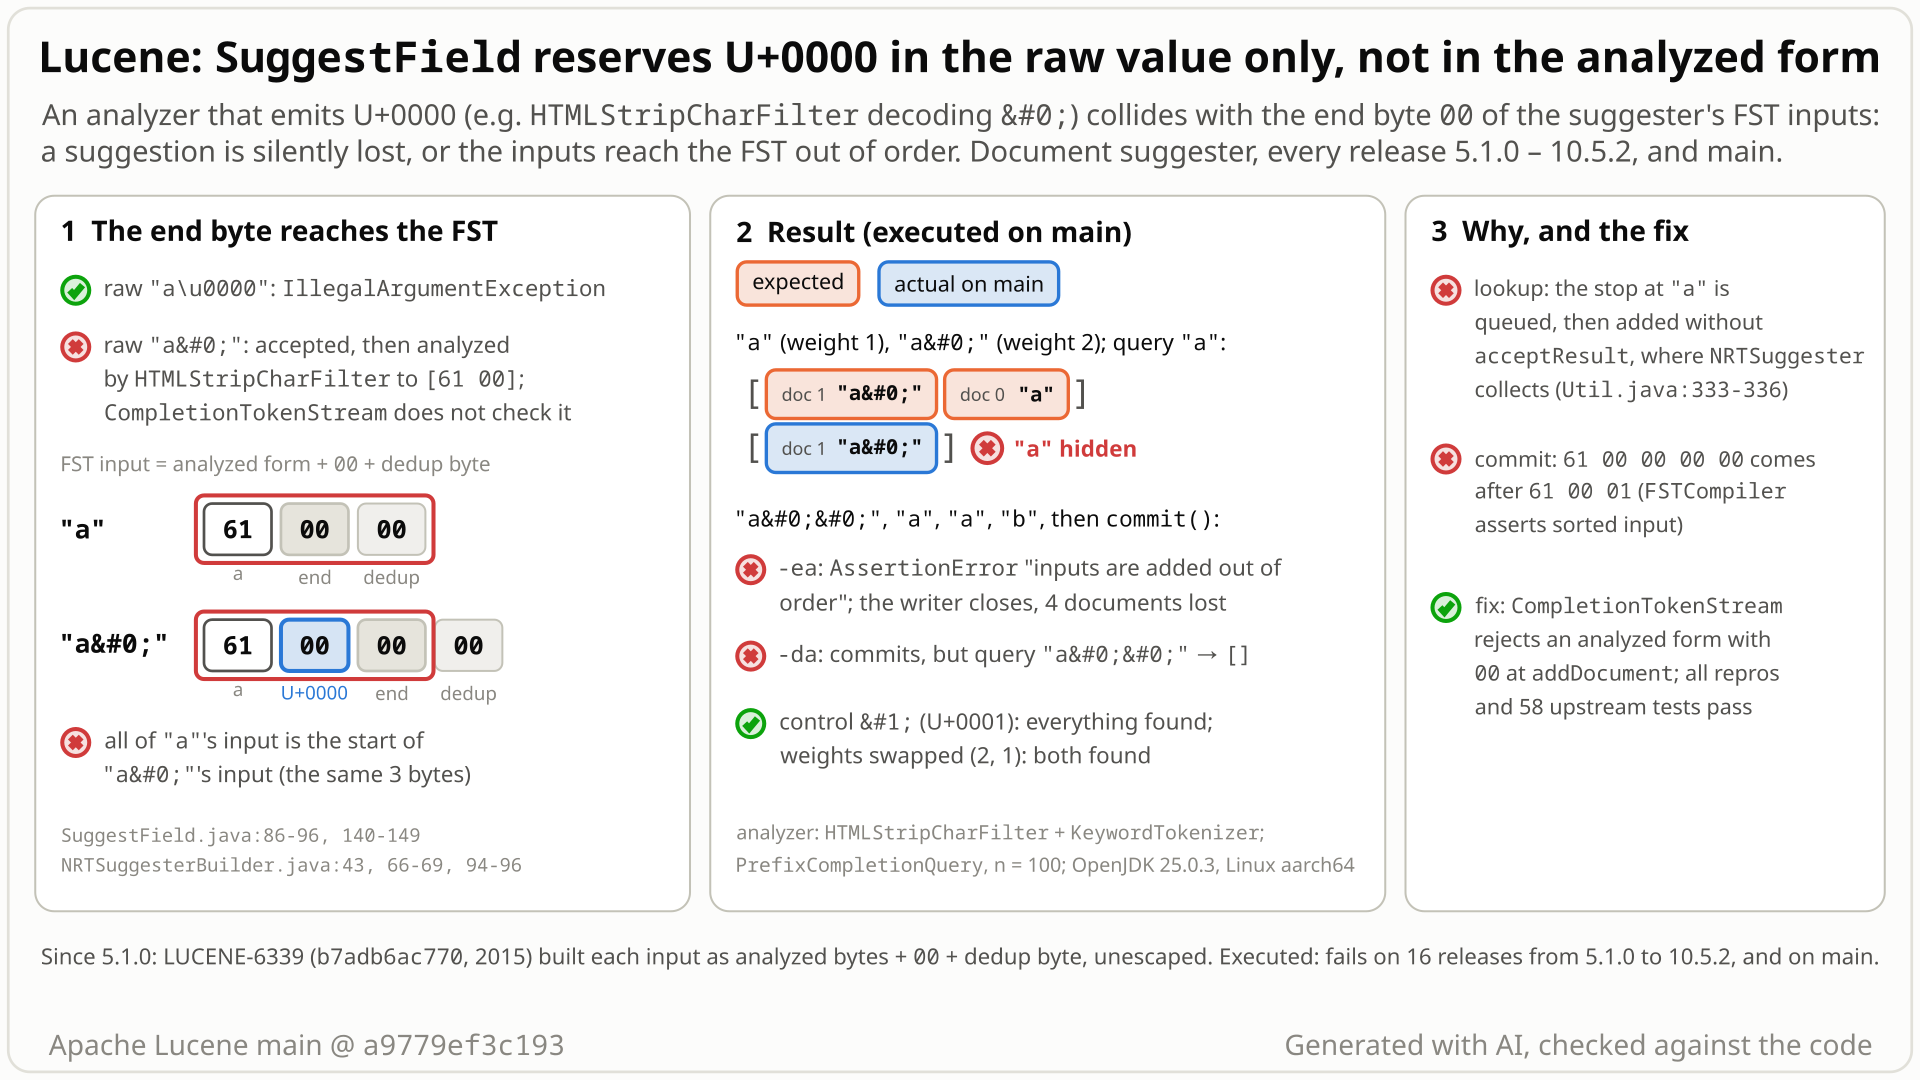
� becomes the FST's end byte so that a's input is the start of a�'s, what main returns, and why, with the fix. Select the still to open it at full size. Generated with AI, checked against the code.- You index suggestions with an analyzer
HTMLStripCharFilter+KeywordTokenizer: doc 0a(weight 1), doc 1a�(weight 2). Both values are accepted:SuggestFieldrejects a raw U+0000, anda�contains none. - You expect
PrefixCompletionQuery("a")with n = 100 to return both documents. Witha(U+0001) instead ofa�, it does. - Instead it returns only doc 1, with assertions on or off. The analyzer turned
�into U+0000, the end byte of every FST entry:ais stored as61 00 00,a+U+0000 as61 00 00 00. One entry is a prefix of the other, and the lookup drops the lower-weight one. - With
a��,a,a,b, the secondaentry (61 00 01) sorts after61 00 00 00 00. With assertions on,commit()throws "inputs are added out of order" and closes the IndexWriter: 4 buffered documents lost. With them off, a query fora��returns nothing, although a query forastill lists it. - It has been there since the document suggester arrived in 5.1.0 (2015): 16 releases up to 10.5.2 and main fail the same way, and 10.6.0 has the same code (by reading). A
MappingCharFilterrule that outputs U+0000 triggers it too.
Users of the opt-in document suggester whose analyzer can turn accepted text into U+0000: the stock HTMLStripCharFilter on � or �, or a char-filter mapping rule. In production, suggestions silently go missing, and a query ending in U+0000 can return extra ones; with assertions on, commit or merge closes the writer. Rare: misses need x and x+U+0000 in one segment.
Mechanism, terms and numbers1,138 words
The document (NRT) suggester stores every suggestion in an FST whose input is the analyzed form, then the end byte 0x00 (NRTSuggesterBuilder.END_BYTE), then one or more dedup bytes. Because 0x00 ends every entry, SuggestField reserves U+0000 and throws IllegalArgumentException for a value that contains it. It checks only the raw value, though; the analyzed form, which is what goes into the FST, is never checked, and the class javadoc invites "the usual Analyzers".
A stock char filter turns an accepted value into a reserved one: HTMLStripCharFilter decodes � to U+0000, and a MappingCharFilter rule can do the same. Then the input of a (61 00 00) is a prefix of the input of a+U+0000 (61 00 00 00), and a second entry for a (61 00 01) sorts after a+U+0000+U+0000 (61 00 00 00 00). In production (assertions off) suggestions silently disappear: with a (weight 1) and a� (weight 2) in one segment, a prefix query for a with n = 100 returns only the second document, and with a��, a, a, b a prefix query for a�� misses the first document (a query for a still lists it). With assertions on, the second case fails the commit with FSTCompiler's "inputs are added out of order" AssertionError, which closes the IndexWriter. The same analyzer with  (U+0001) indexes and finds everything. The bug came with the document suggester itself (5.1.0, 2015) and is in every release since; checking the analyzed form in CompletionTokenStream and throwing the same non-aborting IllegalArgumentException fixes these symptoms. The same in-band byte also gives a wrong extra hit on the query side, which that check does not remove: on main, a prefix query for a� also returns a.
- Document suggester:
SuggestField(orContextSuggestField) indexed with a completion postings format such asCompletion104PostingsFormat, queried withSuggestIndexSearcherand aCompletionQuerysuch asPrefixCompletionQuery. It is@lucene.experimentaland opt-in. - Analyzed form: the suggestion after the field's analyzer, concatenated by
ConcatenateGraphFilterinsideCompletionTokenStream. The FST is built from these bytes (UTF-8; U+0000 is the byte0x00). - FST input: analyzed bytes +
END_BYTE0x00("Marks end of the analyzed input and start of dedup byte",NRTSuggesterBuilder.java:42-43) + a dedup byte 0, 1, 2, ... per entry with that analyzed form (:66-69,:81-97). FST inputs must be added in increasing byte order.
- Only the raw value is checked. The constructor loops over the value (
SuggestField.java:86-96) and rejectsisReservedcharacters: U+001F, U+001E andNRTSuggesterBuilder.END_BYTEU+0000 (:140-149), as its javadoc promises (:75-76). - The analyzed form passes unchecked.
SuggestField.tokenStreamwraps the analyzer's stream inCompletionTokenStream(:103-120), whoseincrementTokenpasses theConcatenateGraphFilteroutput on unchanged (CompletionTokenStream.java:74-81).HTMLStripCharFilterhas already decoded�(or�) to U+0000: any code point up to 0x10FFFF except surrogates goes throughCharacter.toChars(HTMLStripCharFilter.jflex:494-514,:528-547). 0x00is the terminator, unescaped. At flushCompletionFieldsConsumercallsstartTermonce per analyzed term, in byte order, then one entry per document andfinishTerm(CompletionFieldsConsumer.java:195-227). Soawith one entry is61 00 00, with two entries61 00 00and61 00 01;a+U+0000 is61 00 00 00;a+U+0000+U+0000 is61 00 00 00 00. Without a0x00inside an analyzed form the inputs are prefix-free and increasing; with it, both properties break.- Out of order at flush.
a's second input61 00 01comes before61 00 00 00 00although it is larger.FSTCompiler.addasserts increasing order (FSTCompiler.java:854-855). With assertions on, theAssertionErrorescapes flush (NRTSuggesterBuilder.finishTerm:96<-CompletionFieldsConsumer:226<-IndexWriter.commit), a tragic event that closes the writer. With assertions off the FST is compiled from out-of-order inputs and a query fora��no longer returns that document. - A hidden suggestion at lookup.
61 00 00is now both the end ofaand a step on the way toa+U+0000.NRTSuggestercollects only in itsacceptResultoverride ofUtil.TopNSearcher(NRTSuggester.java:189-227; "we do not use it, instead collect at acceptResult",:254-255). When the higher-weighta+U+0000 wins at that node (weights are stored asInteger.MAX_VALUE - weight, lower is better,:329-334),a's final path is queued; when it is popped,TopNSearcheradds it to its own result list without callingacceptResult(Util.java:333-337). That branch is a separate weakness, reachable here only because the inputs stopped being prefix-free. - When it triggers. Some analyzed form in a segment must start with another analyzed form of the same segment followed by U+0000, such as
aanda+U+0000 (from the encoding). A lonex�with no plainxin the segment is indexed and found normally. Merges rebuild the FST from the merged terms, so a pair in two segments meets again at merge. The extra hit below needs only a query whose analyzed form ends in U+0000 and a suggestion equal to the text before it.
Analyzer HTMLStripCharFilter + KeywordTokenizer, one document per value with weight = position + 1, one segment, PrefixCompletionQuery with n = 100 for each value (gradle on main, seed DEADBEEF):
| documents | assertions off (production) | assertions on |
|---|---|---|
control: a, a | both found | both found |
a, a� | query a returns only doc 1: a hidden | same |
a��, a, a, b | commit works; query a�� misses doc 0 (got []) | commit throws inputs are added out of order lastInput=[61 0 1] vs input=[61 0 0 0 0]; writer closed, 4 buffered documents lost |
The hidden case needs the plain suggestion to have the lower weight: weights (1,2) and (1,10) lose a; (2,1), (5,5) and (10,1) do not (independent reproducer).
In the last case, with assertions off, a prefix query for a still lists doc 0; only the query for its own value misses it (diagram probe). Extra hits happen too, on the query side: with a (weight 2) and a� (weight 1), a prefix query for a� (analyzed 61 00) also returns a, which does not start with a+U+0000, because a's FST input 61 00 00 starts with the query bytes. The same happens with the fix in place, where only a is indexed (diagram probe, assertions on and off). It is the same class as the registered LFV-691 (RegexCompletionQuery's . matches the end byte), reached here through the query's own analyzed U+0000.
A MappingCharFilter rule ~ -> U+0000 hides a in the two-document case with assertions on and off, and fails the commit of a, a, a~ with assertions on; with them off that three-document case commits and finds all three (independent reproducer).
Exposure and likelihood494 words
- Who is hit. Users of the document suggester (
SuggestFieldorContextSuggestFieldwith a completion postings format; opt-in,@lucene.experimental) whose analysis chain can turn an accepted value into a form with U+0000. Stock components and plain document text suffice:HTMLStripCharFilterdecodes�and�; aMappingCharFilterorPatternReplaceCharFilterrule can output U+0000. Common text analyzers such asStandardAnalyzeradd no U+0000. Binary-term analyzers such asCollationKeyAnalyzerwrite raw collation-key bytes, which contain0x00by design (a JDK root-locale collation key forais00 53 00 00 00 01 00 00 00 01); how they behave in a suggest field today was not tested. - Silent in production. With assertions off nothing throws: a suggestion accepted at
addDocumentis just missing from the results of a query for its own value. The lost one can be the U+0000 document or an ordinary neighbour with a lower weight. A query whose analyzed form ends in U+0000 can also return suggestions that do not start with that form. - Loud with assertions. With
-ea(tests, development) the commit throws and closes theIndexWriter; every document added since the last commit is lost. A merge that brings such a pair together trips the same assertion, andIndexWriter.mergehandles any merge failure as a tragic event that closes the writer (IndexWriter.java:5109-5113); in the probe's four such merges,forceMergethree times reported the writer's unrecoverable error and once reported the merge exception whileisOpen()still returned true. Segments committed before are not lost. - Scale. Deterministic at any index size, given the colliding pair in one segment. In the hunt's bounded-exhaustive run over every list of 1-3 documents whose analyzed forms are 1-3 characters over {
a, U+0000} starting witha(399 lists): with assertions on, 12 flush failures (each closes the writer) and 68 lists with a missed suggestion; with them off, 0 and 71; 52 of the missed queries are for documents without U+0000; the U+0001 control has 0 and 0. An independent re-implementation in the fact check got the same counts and found the 12 failing flushes to be exactly the 12 lists predicted out of order. In a larger probe (2 to 600 copies ofawith weights 1..n, plus U+0000 forms with the highest weights, single and merged segments, assertions off) 76 of 78 runs lost U+0000 documents and none lost anadocument. These are counts over the probe's constructed cases, not a frequency estimate; in other layouts a plain document is the one hidden (the singleaabove, the 52 missed queries). No run threw, ran out of memory or took longer than the probe's 20 s limit per operation; allocation was not measured. - Likelihood. Rare: text with
�(or a mapping rule to U+0000) next to a suggestion equal to the text before it, plus a weight order or duplicate count that exposes it. No prior report was found in the recorded searches (2026-10-27; see Prior reports).
SuggestField "a" (weight 1) and "a�" (weight 2), analyzed by htmlStrip + keyword, both accepted; the analyzed U+0000 collides with the suggester's END_BYTE and hides the plain suggestion.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.suggest.document;

import java.util.Arrays;
import java.util.List;
import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.charfilter.HTMLStripCharFilterFactory;
import org.apache.lucene.analysis.core.KeywordTokenizerFactory;
import org.apache.lucene.analysis.custom.CustomAnalyzer;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.Term;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestSuggestFieldAnalyzedEndByte extends LuceneTestCase {

  public void testAnalyzedEndByteHidesOtherSuggestion() throws Exception {
    Analyzer analyzer =
        CustomAnalyzer.builder()
            .addCharFilter(HTMLStripCharFilterFactory.class)
            .withTokenizer(KeywordTokenizerFactory.class)
            .build();
    IndexWriterConfig iwc = new IndexWriterConfig(analyzer);
    iwc.setCodec(TestUtil.alwaysPostingsFormat(new Completion104PostingsFormat()));
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter writer = new IndexWriter(dir, iwc)) {
      writer.addDocument(List.of(new SuggestField("suggest", "a", 1)));
      writer.addDocument(List.of(new SuggestField("suggest", "a�", 2)));
      try (DirectoryReader reader = DirectoryReader.open(writer)) {
        TopSuggestDocs hits =
            new SuggestIndexSearcher(reader)
                .suggest(new PrefixCompletionQuery(analyzer, new Term("suggest", "a")), 10, false);
        // expected: both docs ("a�" weight 2, then "a" weight 1); actual: only doc 1, "a" is hidden
        assertEquals(List.of(1, 0), Arrays.stream(hits.scoreLookupDocs()).map(d -> d.doc).toList());
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-798/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/suggest/build/libs/lucene-suggest-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.suggest.document.TestSuggestFieldAnalyzedEndByte
- Expected vs actual
- Expected PrefixCompletionQuery "a" to return docs [1, 0]; actual [1] on main 645d4fe14a2 with -ea and -da.
More files, environment, full output35 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<[1, 0]> but was:<[1]>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:120)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.search.suggest.document.TestSuggestFieldAnalyzedEndByte.testAnalyzedEndByteHidesOtherSuggestion(TestSuggestFieldAnalyzedEndByte.java:53)- U+0000 is reserved because it ends every analyzed form in the FST; only analyzed bytes reach the FST, yet only the raw value is checked.
- The javadoc invites "the usual Analyzers" and nothing restricts their output;
ConcatenateGraphFilteralready escapes its own in-band separator. - With
everything works; #5600 fixed a 0-byte collision inAnalyzingSuggesteras a bug.
The full argument203 words
- The reservation exists for the FST. U+0000 is in
SuggestField.isReserved(SuggestField.java:140-149) because it isNRTSuggesterBuilder.END_BYTE, which "Marks end of the analyzed input" (NRTSuggesterBuilder.java:42-43). Only the analyzed bytes reach the FST, so a check on the raw value alone cannot keep the byte out. - Any analyzer is invited. "Besides the usual Analyzers, CompletionAnalyzer can be used" (
SuggestField.java:35-37). No javadoc, CHANGES or MIGRATE entry restricts analyzer output. - In-band markers are escaped elsewhere.
ConcatenateGraphFilterescapes its ownSEP_LABELinside tokens; nothing handlesEND_BYTE. - Tests cover the raw value only.
TestSuggestField#testReservedChars(TestSuggestField.java:101-124) buildsSuggestFields with raw reserved characters. No document-suggester test (suggest/document) uses an analyzer that emits U+0000; the only 0-byte analyzer test inlucene/suggestisTestAnalyzingSuggester#test0ByteKeys(TestAnalyzingSuggester.java:1204-1223), added by LUCENE-4534 (#5600) for theAnalyzingSuggester. - Precedent. #5600 / LUCENE-4534 (2012) fixed 0 bytes in
AnalyzingSuggester/WFST keys as a bug ("0 bytes are rare, they are 'allowed' but will cause exceptions"), withtest0ByteKeysas its regression test. - History. LUCENE-6339 (#7400) introduced the encoding; LUCENE-6459 (#7518) added the raw-value reservation of U+0000. Neither review discusses analyzer output.
- The control. The same analyzer and documents with
(U+0001) index and find every suggestion.
The devil's-advocate check221 words
The strongest case for "intended": the API is @lucene.experimental; the javadoc promises the IllegalArgumentException for the raw value only; the writer close needs assertions; HTML5 maps � to U+FFFD, so one could blame HTMLStripCharFilter; and NRTSuggester says "search admissibility is not guaranteed" (NRTSuggester.java:257).
Why it fails: experimental allows API changes, not a silent loss of other documents' suggestions; the production (assertions off) loss is the main symptom, not the writer close; a MappingCharFilter rule triggers the same defect, so the missing check is the bug whatever HTMLStripCharFilter should decode � to; and the admissibility notes tie misses to many deletions or a restrictive filter (:55-64, :280-290), while the repro has neither and asks for 100 hits out of 2-4 documents. Binary-term analyzers (collation keys) emit 0x00 by design; whether a suggest field should accept them is a decision for the fix, not an argument that the silent loss is intended. Two reading-only reviews by one model from another family (OpenAI GPT-5.6; neither ran code) rated the intended argument weak; a later fact check by the same family rated the strongest case moderate for the U+0000 suggestion's own miss and for the assertions-on writer close, and weak for the hidden neighbour. The devil's advocate found no intended or misuse argument that survives. Verdict: a defect.
Recommended Reject an analyzed form that contains END_BYTE, in CompletionTokenStream
Check the analyzed form in CompletionTokenStream.incrementToken and throw the same non-aborting IllegalArgumentException as for a raw U+0000 (+14 lines, one file). In a scratch worktree the repro then passes 3 of 3 with assertions on and off, the whole lucene/suggest module passes (240 tests), and a new TestSuggestField test fails before and passes after.
BytesRef analyzed = termAttr.getBytesRef(); // TermToBytesRefAttribute
for (int i = 0; i < analyzed.length; i++) {
  if (analyzed.bytes[analyzed.offset + i] == NRTSuggesterBuilder.END_BYTE) {
    throw new IllegalArgumentException(
        "analyzed form contains the reserved byte 0x"
            + Integer.toHexString(NRTSuggesterBuilder.END_BYTE)
            + " at position "
            + i);
  }
}
payloadAttr.setPayload(payload);
All options and trade-offs5 options · 858 words
The recommended fix was applied in a scratch worktree at a9779ef3c193 and run through gradle (seed DEADBEEF), and earlier shadowed onto the stock jars in the hunt. The other options were not run, except that the hunt shadowed a TopNSearcher change alone.
Reject an analyzed form that contains END_BYTE, in CompletionTokenStream (validated by the checks) (recommended)
In CompletionTokenStream.incrementToken, scan the term bytes of each concatenated form and throw IllegalArgumentException if one is NRTSuggesterBuilder.END_BYTE, as SuggestField does for the raw value. The exception is thrown during addDocument, so it is non-aborting: the document is rejected and the writer stays open. It covers ContextSuggestField too, whose contexts are part of the same bytes. It checks the index side only (see the trade-offs).
BytesRef analyzed = termAttr.getBytesRef(); // TermToBytesRefAttribute
for (int i = 0; i < analyzed.length; i++) {
  if (analyzed.bytes[analyzed.offset + i] == NRTSuggesterBuilder.END_BYTE) {
    throw new IllegalArgumentException(
        "analyzed form contains the reserved byte 0x"
            + Integer.toHexString(NRTSuggesterBuilder.END_BYTE)
            + " at position "
            + i);
  }
}
payloadAttr.setPayload(payload);
Trade-offs
- Behaviour change. It rejects every analyzed form with a
0x00, also a lonex�that works today, and any analyzer that emits0x00on purpose (for example binary or collation-key terms) can no longer feed a suggest field. It also rejects a raw context that contains U+0000, whichContextSuggestFieldaccepts today (its own check,ContextSuggestField.java:166-179, rejects only U+001D; not tested). Say so in a CHANGES entry; the javadoc ofSuggestFieldcould mention that the analyzed form is checked too. - Cost. One pass over the bytes of each suggestion at index time; nothing at search time. Not benchmarked.
- Existing indexes. The check runs only when a document is added. Merges copy the stored terms through
CompletionFieldsConsumer(CompletionFieldsConsumer.java:85-102,:195-226) without the token stream, so a segment written before the fix keeps its entries: suggestions stay missing, and with-eaa later merge can still trip the assertion. Only reindexing the affected documents removes them. - Query side not covered. A prefix query whose analyzed form ends in U+0000 still matches suggestions whose analyzed form is the query's without that last U+0000: with the fix, an index holding only
areturnsafor a query fora�(diagram probe, assertions on and off). Rejecting or escaping0x00in query analysis as well would close that; not run. The repro does not test it. LFV-691 needs a query-side fix forRegexCompletionQuerytoo; a shared change to the query automaton may cover both (not explored). - Message. It could also name the field, and the value as the raw-value message does.
- Add a regression test:
fix-with-test.diffaddsTestSuggestField#testReservedCharInAnalyzedForm.
What the checks validated
- Scratch worktree at
a9779ef3c193, gradle, seed DEADBEEF, 2026-10-28. Stock: the repro fails 2 of 3 with-Ptests.asserts=trueand with=false; the new regression testTestSuggestField#testReservedCharInAnalyzedFormfails ("Expected exception IllegalArgumentException but no exception was thrown"). - With the fix: the repro passes 3 of 3 and
TestSuggestField21 of 21 (with the new test), assertions on and off; the wholelucene/suggestmodule with the repro added, assertions on: 32 classes, 240 tests, 7 skipped, 0 failures (thesuggest.documentpackage: 62 tests);checkGoogleJavaFormat,ecjLintMain,ecjLintTest,forbiddenApisMainandforbiddenApisTestpass. - The stock gradle runs used the repro before an unused catch parameter was renamed to
_for the lint; the final file fails 2 of 3 on stock main (assertions on and off) and on 10.5.2 with a standalone runner, and passes 3 of 3 with the fix shadowed (seed 5EED0798). - Earlier, in the hunt (fix classes shadowed onto the stock jars): the finder's JUnit 3 of 3 and the independent reproducer's 5 of 5 pass with assertions on and off; the 58 upstream
suggest/documenttests pass; the bounded-exhaustive harness shows 0 flush failures and 0 misses. - Not run: a benchmark; other modules.
Like ConcatenateGraphFilter escapes SEP_LABEL: index an in-band 0x00 as an escape sequence and build every completion query's automaton the same way.
Trade-offs
Keeps such values indexable and findable and also covers the query-side extra hit, but touches the FST content and every CompletionQuery (prefix, regex, fuzzy, context), so it is a larger change with format implications. Not run.
HTML5 maps the character reference for code point 0 to U+FFFD.
Trade-offs
Removes one trigger only: a MappingCharFilter or PatternReplaceCharFilter rule still produces U+0000. It also changes the filter's output for every user. A possible separate hardening, not a fix of this bug. Not run.
TopNSearcher adds a queued END_LABEL path to its results without acceptResult (Util.java:333-337), which is how the lower-weight suggestion is lost.
Trade-offs
Partial: the hunt shadowed such a change alone, and the hidden-suggestion test passed but the out-of-order flush still failed (3 run, 1 failed). Worth its own issue; it does not stop 0x00 from reaching the FST.
A javadoc note on SuggestField and CompletionAnalyzer.
Trade-offs
Leaves the silent loss and the writer close in place for anyone who misses the note. Not recommended.
Not a Lucene security issue under its SECURITY.md, but downstream, where untrusted document text feeds a completion field through an HTML-decoding analyzer, one document containing � can lose its own suggestion and, in small segments, hide another document's.
A bounded-exhaustive differential check of the stock document suggester: every list of 1-3 suggestions whose analyzed forms mix a and U+0000, against "every accepted suggestion is found and commit succeeds" and an independent model of the FST input order, which predicted exactly the 12 failing flushes. It was then reduced to a public-API JUnit with HTMLStripCharFilter.
The method in full202 words
Method: bounded-exhaustive differential checking on the stock main jar (the hunt's "semi-formal" tier; no model checker, solver or prover).
- An earlier hunt over the completion suggester had seen the mechanism with a custom
MappingCharFilterrule, found no stock trigger and did not report it. A later unit that turns such stranded leads into public-API repros picked it up. - The harness indexed every list of 1-3 documents whose suggestion analyzes to a 1-3 character string over {
a, U+0000} starting witha(399 lists), with U+0001 as the control, and compared the jar with two oracles: an independent reference (every accepted document is found by a prefix query for its own value; commit succeeds) and an independent model ofNRTSuggesterBuilder's FST input order, which predicts exactly the 12 lists whose flush fails with assertions on (a count match in the hunt; the fact check's independent re-implementation confirmed the same set). - The finder then searched for a stock trigger, found
HTMLStripCharFilterdecoding�, and wrote the JUnit (2026-10-27). An independent reproducer, reading-only reviews by a model from another family (OpenAI GPT-5.6), an intended-behaviour devil's advocate, an adjudication, a history sweep, a prior-report search, a security screen and a credibility audit followed.
No prior report found (2026-10-27): two runs of the hunt's prior-report tool, 87 manual GitHub searches across Lucene and downstream engines, the changed files of all 409 open PRs, JIRA, the mailing lists and the web. Closest: #5600, the same kind of 0-byte bug in AnalyzingSuggester, fixed in 2012.
Searches3 searches
Verdict new: the recorded searches found no issue, PR, review comment, JIRA ticket, list thread, downstream issue or web page that reports this bug or its symptoms. Keyword search cannot prove absence: GitHub search reads only the first page per query and was partly rate-limited in one pass.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; downstream repos; dev@, java-user@, issues@, commits@; JIRA archive; the web | 2026-10-27 | two runs of the hunt's prior-report tool (24 and 16 GitHub queries plus commit, downstream, list, JIRA and web queries; 1,159 and 531 distinct hits) | no hit with high overlap |
| GitHub (apache/lucene, Elasticsearch, OpenSearch, Solr, GitHub-wide) | 2026-10-27 | 87 manual searches, including the stack-trace strings; the changed files of all 409 open apache/lucene PRs; issues and PRs created since 2026-10-25 | nothing about this bug; no open PR changes the check |
| Related threads (read in full) | 2026-10-27 | #7400, #7518, #9379, #9391, #10095, #4764, #6825; elastic/elasticsearch #48341, #48445, #82432, #3648; 11 JIRA queries | #5600 / LUCENE-4534 (0 bytes in AnalyzingSuggester keys, fixed 2012: same class, other suggester); elastic/elasticsearch#48341 (the raw-value check working as designed); #10095 (same assertion text, a user's own FST); #10038 (open: TopNSearcher with rejected completions, no 0x00) |
Introduced with the document suggester itself, LUCENE-6339 (b7adb6ac770, 2015-03-27), first released in 5.1.0. One portable probe fails on 16 releases from 5.1.0 to 10.5.2 and on main; 5.0.0 has no document suggester. Not a regression, and not fixed upstream.
Versions tested6 rows
Introduced by b7adb6ac770 (trunk, 2015-03-27, "LUCENE-6339: Added Near-real time Document Suggester via custom postings format", Areek Zillur; JIRA LUCENE-6339 = #7400; svn era, no PR) and its branch_5x backport 40e94c39ad3 (2015-03-28), first released in 5.1.0. It built each FST input as analyzed bytes + 0x00 + dedup byte(s) and escaped only the separator U+001F; git log -L on startTerm lists only this commit.
The contract came later. LUCENE-6459 (#7518, be4d58c7740, 2015-05-28, first in 5.3.0) added isReserved with U+0000 and the javadoc promise, for the raw value only. In 5.1.0-5.2.1 even a raw U+0000 is accepted and hides suggestions. LUCENE-8332 (7.4.0) moved the concatenation to ConcatenateGraphFilter, which still escapes only SEP_LABEL. CompletionTokenStream.java and NRTSuggesterBuilder.java on branch_10_6 are byte-identical to main (read).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | JUnit 2 of 3 fail through gradle and the runner, assertions on and off; the probe fails both scenarios |
| 9.12.3, 10.5.2 | affected | JUnit 2 of 3 fail; the probe fails with assertions on and off |
| 5.3.0 to 10.0.0 | affected | probe (assertions on): 5.3.0, 5.5.5, 6.0.0, 6.6.6, 7.3.1, 7.4.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 10.0.0 fail with the same failure text; 5.3.0 also with assertions off |
| 5.1.0, 5.2.0, 5.2.1 | wider | probe fails; a raw U+0000 is accepted too and hides suggestions (the raw check came in 5.3.0) |
| 5.0.0 | no API | no document suggester |
| main + fix | not affected | the JUnit, the independent reproducer's test, the exhaustive harness and the suggest module pass |
An independent reproducer and an intended-behaviour devil's advocate reproduced it with their own runs; reading-only reviews by a model from another family (OpenAI GPT-5.6) agreed on the root cause; an adjudication, an audit, this doc's gradle runs and fact checks confirmed it and validated the fix.
Checks and verdicts456 words
Every executing check ran a JUnit on stock main; every U+0001 control passed. The reviews from the other model family could not run code (separate runs re-ran the finder's test, which failed as expected).
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Exhaustive harness and FST-order model; JUnit fails 2 of 3 on main (on and off), 10.5.2 and 9.12.3; passes 3 of 3 with the fix; 58 upstream suggest/document tests pass with the fix. |
| independent reproducer | real | Own test from the claim: fails 3 of 5 (on) and 2 of 5 (off) on main, 10.5.2 and 9.12.3; found the weight condition and the MappingCharFilter trigger; passes 5 of 5 with the fix. |
| cross-model reviews (refute, intended) | not real (procedural); real (medium) | Both reviews were reading-only runs by the same model from another family (OpenAI GPT-5.6); neither ran code. The refute lens's "not real" rests only on the missing own execution; both agreed on the root cause, found the inputs legal and rated the intended argument weak. |
| intended-behaviour devil's advocate | real | Built the strongest "intended" case and showed why it fails; re-ran the JUnit on main (on and off) and 10.5.2: 2 of 3 fail. |
| adjudication | confirmed (high) | Re-ran both tests with a new seed, assertions on and off; cited the hunt's shadow run showing the TopNSearcher change alone leaves the flush case failing; duplicate of none. |
| security screen | not security-sensitive | Wrong or missing suggestions only; a probe with 2 to 600 duplicates saw no exception, out-of-memory error or operation over 20 s with assertions off (allocation not measured; extra hits not looked for); no guarantee SECURITY.md documents for untrusted input is broken. |
| credibility audit and re-runs | keep | The audit re-ran the JUnit on a clean main with a fresh seed (2 of 3 fail, on and off); the registration check's re-runs used two more seeds and the fix (3 of 3 pass); class and score unchanged. |
| this doc's gradle runs | reproduced; fix validated | Gradle on main in a scratch worktree, seed DEADBEEF: the repro fails 2 of 3 with assertions on and off; with the fix it passes, TestSuggestField with a new regression test passes 21 of 21, the whole lucene/suggest module (240 tests) has 0 failures, and the format, ECJ and forbidden-API checks pass. |
| fact checks of this doc | real; text corrected | An independent fact check re-ran the repro on main and 10.5.2 (assertions on and off), the doc's gradle commands and the fix, and re-implemented the 399-list run with the same counts. A reading-only fact check by a model from another family (OpenAI GPT-5.6) found the core claims sound. Their corrections are applied; the diagram check found no error. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 456 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,442 words
- Registry title
- The document suggester checks its reserved end byte U+0000 only in the raw SuggestField value, not in the analyzed form, so an analyzer that emits U+0000 (for example HTMLStripCharFilter decoding '�') hides another document's suggestion or its own and adds FST inputs out of order at flush (with assertions enabled the IndexWriter closes)
- Area
- suggest / document (NRT) suggester (SuggestField's raw-value reserved-character check vs. the analyzed form that CompletionTokenStream passes to NRTSuggesterBuilder's FST encoding)
- Priority
- Low, rank 272: Needs an analyzed U+0000 that collides with another suggestion's prefix form in the opt-in document suggester.
- Impact class
- silent wrong results
- Impact note
- Hits applications that use the opt-in document suggester (SuggestField with a completion postings format) whose analysis chain can turn an accepted value into a form that contains U+0000 (the stock HTMLStripCharFilter decodes '�' or '�' in document text; a MappingCharFilter or PatternReplaceCharFilter rule can do it too), and only in a segment that also holds a suggestion whose analyzed form equals the text before that U+0000 (for example 'a' next to 'a�'): in production (-da) the lower-weighted plain suggestion, or the U+0000 suggestion itself, is silently not returned for its own prefix, and with assertions enabled (-ea), once the shorter form has two or more entries, commit throws an AssertionError that closes the IndexWriter and loses the buffered documents; deterministic at any scale, in every release from 5.1.0 to 10.6.0 (10.6.0 by reading) and on main.
- Summary
- You index suggestions with SuggestField through an analyzer that decodes HTML character references (HTMLStripCharFilter + KeywordTokenizer), for example 'a' (weight 1) and 'a�' (weight 2), and expect a PrefixCompletionQuery 'a' with n=100 to return both documents, as it does with ''. Instead only the second document comes back; and with 'a��', 'a', 'a', 'b' the commit fails with an 'inputs are added out of order' AssertionError that closes the IndexWriter when assertions are enabled, while without assertions 'a��' is never found for its own value. SuggestField rejects U+0000, the byte that ends every entry in the suggester's FST, only in the raw value, so the analyzed form can still carry it and collide with that terminator.
- Introduced
- b7adb6ac7704a7e6364ee0d831bf77cf849f2090 (trunk, 'LUCENE-6339: Added Near-real time Document Suggester via custom postings format', by Areek Zillur; JIRA LUCENE-6339 = apache/lucene#7400; svn era, no pull request) and its branch_5x backport 40e94c39ad3b0f018ae9647b7d30bd0cfe341d86 (the commit in the 5.1.0 release): the commit that created the document suggester already built each FST input as analyzed bytes + END_BYTE 0x00 + dedup byte(s) (NRTSuggesterBuilder.startTerm/finishTerm) and passed the analyzed form on unchecked; the only in-band escaping it added was for the separator label U+001F [read: full-history clone, git log -L on NRTSuggesterBuilder.startTerm lists only this commit; exec: 5.0.0 has no document suggester, 5.1.0 fails]. The raw-value reservation of U+0000 came later with LUCENE-6459 (be4d58c7740 trunk / 380bb29f395 branch_5x, 2015-05-28, first in 5.3.0, apache/lucene#7518): it states the contract the bug breaks and narrowed it (a raw U+0000 is rejected from 5.3.0 on), but did not introduce the defect [exec: in 5.1.0-5.2.1 a raw U+0000 is accepted too and hides suggestions]. Not a regression. (2015-03-27 (trunk b7adb6ac770); 2015-03-28 (branch_5x 40e94c39ad3))
- First affected version
- 5.1.0 [exec: the version-portable history probe fails both scenarios with -ea and -da, U+0001 controls passing]; 5.0.0 is not affected because it has no document suggester [exec: API absent]
- Affected versions
- every release that has the document suggester: 5.1.0 to 10.5.2, 10.6.0 (by reading) and main a9779ef3c193 (unreleased 11.0) [exec: the history probe fails with byte-identical failure text on 5.1.0, 5.2.0, 5.2.1, 5.3.0, 5.5.5, 6.0.0, 6.6.6, 7.3.1, 7.4.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main with -ea, and with -da on 5.1.0, 5.3.0, 9.12.3, 10.5.2 and main; the finder's JUnit fails 2 of 3 on main (-ea, -da), 10.5.2 and 9.12.3; the independent reproduction's JUnit fails on main, 10.5.2 and 9.12.3 (-ea, -da)]; the releases in between by inference, the fix-site code being unchanged in substance [read]. 5.1.0-5.2.1 are wider: a raw U+0000 value is accepted too [exec]. branch_10_6 (head 2763db11b0a): CompletionTokenStream.java and NRTSuggesterBuilder.java byte-identical to main, SuggestField.java differs only in javadoc markup [read, not executed]. Not fixed upstream: main 20ced71c1e6e, branch_10x 657014b3c579 and branch_10_6 4ae946e5a9b9 have no commit on the fix-site files after a9779ef3c193, and no open PR changes the check [read, 2026-10-27]. Executed on Linux aarch64 with JDK 25 only.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (the prior-report record verdict new, searched 2026-10-27, read-only; the finder's, the independent reproduction's, the intended-behaviour check's and the adjudication's searches found nothing either): two scripted prior-report searches (24 and 16 GitHub issue/PR queries on apache/lucene plus commit, downstream, mailing-list over dev@, java-user@, issues@ and commits@, JIRA and web queries; 1159 and 531 distinct hits, none high overlap), 87 manual GitHub GraphQL searches over apache/lucene, Elasticsearch, OpenSearch, Solr and GitHub-wide, the file lists of all 409 open apache/lucene PRs, 11 JIRA queries, 6 web searches and the full discussions of #7400, #7518, #9379, #9391, #10095, #4764, #6825 and three downstream issues. Nearest items, none the same bug: #5600 / LUCENE-4534 (2012, fixed: 0 bytes in AnalyzingSuggester/WFST keys; same defect class in a different suggester that predates the document suggester, anchor of LFV-601), #7400 / LUCENE-6339 and #7518 / LUCENE-6459 (introduced the suggester and the raw-value check; their reviews never discuss analyzer output), elastic/elasticsearch#48341 (2019: a user hit the raw-value U+0000 rejection, which works as designed), #10095 (same assertion message from a user's own FST build, closed Invalid), #10038 / LUCENE-8995 (open, the TopNSearcher rejection path, no 0x00). Refresh (2026-10-27, read-only): apache/lucene PRs (#16905-#16923) and issues created since 2026-10-25 touch nothing in lucene/suggest. Not fixed upstream (main 20ced71c1e6e, branch_10x, branch_10_6). Gaps: GitHub search reads only the first page per query and was partly rate-limited in the adjudication's pass; list and JIRA search is keyword-based.
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26) through gradle in a scratch worktree, with assertions on and off (2026-10-28), and through the standalone JUnit runner (2026-10-27 and 2026-10-28, several seeds); the 10.5.2 and 9.12.3 release jars with the same JUnit; 17 releases from 5.0.0 to 10.5.2 plus main with one version-portable probe. The fix was validated in the scratch worktree: the repro,TestSuggestFieldwith a new regression test, the wholelucene/suggestmodule, and the format, ECJ and forbidden-API checks. Upstream main20ced71c1e6e,branch_10xandbranch_10_6have no later commit on the fix-site files (read, 2026-10-27).
- Finding record
lucene/suggest/src/java/org/apache/lucene/search/suggest/document/SuggestField.java:35-37 (at a9779ef3c193) (class javadoc: 'Besides the usual Analyzers, CompletionAnalyzer can be used'), :48 (@lucene.experimental), :75-76 (@throws IllegalArgumentException 'if value contains any reserved characters'), :86-96 (the check loops over the raw value only), :140-149 (isReserved: SEP_LABEL, HOLE_CHARACTER, NRTSuggesterBuilder.END_BYTE)lucene/suggest/src/java/org/apache/lucene/search/suggest/document/CompletionTokenStream.java:74-81 (at a9779ef3c193) (incrementToken passes the ConcatenateGraphFilter output on unchecked; fix site)lucene/suggest/src/java/org/apache/lucene/search/suggest/document/NRTSuggesterBuilder.java:42-43 (at a9779ef3c193) (END_BYTE = 0x0, 'Marks end of the analyzed input and start of dedup byte'), :66-69 (startTerm appends END_BYTE to the analyzed bytes, no escaping), :81-97 (finishTerm appends dedup byte(s) and calls fstCompiler.add at :96)lucene/suggest/src/java/org/apache/lucene/search/suggest/document/CompletionFieldsConsumer.java:197 (at a9779ef3c193) and :226 (startTerm/finishTerm once per analyzed term, terms in byte order)lucene/core/src/java/org/apache/lucene/util/fst/FSTCompiler.java:855 (at a9779ef3c193) (assert 'inputs are added out of order')lucene/core/src/java/org/apache/lucene/util/fst/Util.java:329-338 (at a9779ef3c193) (TopNSearcher adds a queued END_LABEL path to the results without acceptResult); lucene/suggest/src/java/org/apache/lucene/search/suggest/document/NRTSuggester.java:190 and :255 (NRTSuggester collects only in acceptResult)lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilter.jflex:493-550 (at a9779ef3c193) (numeric character references, including '�' and '�', are decoded with Character.toChars(codePoint))
- The finding in 30 seconds
lucene/suggest/src/java/org/apache/lucene/search/suggest/document/SuggestField.java:35-37, (at a9779ef3c193) 75-76, 86-96, 103-120, 140-149lucene/suggest/src/java/org/apache/lucene/search/suggest/document/CompletionTokenStream.java:74-81 (at a9779ef3c193)lucene/suggest/src/java/org/apache/lucene/search/suggest/document/NRTSuggesterBuilder.java:42-43, (at a9779ef3c193) 66-69, 81-97lucene/suggest/src/java/org/apache/lucene/search/suggest/document/CompletionFieldsConsumer.java:195-227 (at a9779ef3c193)lucene/suggest/src/java/org/apache/lucene/search/suggest/document/NRTSuggester.java:189-227, (at a9779ef3c193) 254-255, 329-334lucene/core/src/java/org/apache/lucene/util/fst/FSTCompiler.java:848-856; (at a9779ef3c193) Util.java:329-338lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilter.jflex:493-552 (at a9779ef3c193)
- Who is affected
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:2283-2301, (at a9779ef3c193) 5030-5055, 5084-5113, 6090-6106 (merge failure handling)
- Why it looks unintended
lucene/suggest/src/java/org/apache/lucene/search/suggest/document/SuggestField.java:35-37, (at a9779ef3c193) 48, 75-76, 140-149; NRTSuggesterBuilder.java:42-43; NRTSuggester.java:55-64, 257, 280-290lucene/suggest/src/test/org/apache/lucene/search/suggest/document/TestSuggestField.java:101-124 (at a9779ef3c193)lucene/suggest/src/test/org/apache/lucene/search/suggest/analyzing/TestAnalyzingSuggester.java:1204-1223 (at a9779ef3c193) (test0ByteKeys; commit 2537836d4ab, LUCENE-4534)
- Suggested fix
lucene/suggest/src/java/org/apache/lucene/search/suggest/document/CompletionFieldsConsumer.java:85-102, (at a9779ef3c193) 195-226; ContextSuggestField.java:79-103, 166-179
- TestSuggestFieldAnalyzedEndByte.java (JUnit test):
repro/LFV-798/src/org/apache/lucene/search/suggest/document/TestSuggestFieldAnalyzedEndByte.java(57 lines)
Made from an executed probe on main a9779ef3c193 (public API, the registry repro's analyzer and codec), with the FST inputs taken from an instrumented copy of NRTSuggesterBuilder that only adds print lines. The PNG is the final summary card.
assets/LFV-798/bug.png(456 KB)