With two or more terms, TermInSetQuery#visit reports "terms matching this automaton" and passes a supplier that builds the automaton on demand. The builder it uses refuses terms over 1000 bytes, although the query accepts and matches longer terms. Whoever asks for the automaton gets an exception instead.
- Highlighters walk a query with a
QueryVisitorto learn which terms it can match. - A query reports fixed terms with
consumeTerms, or a class of terms withconsumeTermsMatching, passing a supplier of an automaton that accepts the matching terms. - The UnifiedHighlighter with WEIGHT_MATCHES off (and MULTI_TERM_QUERY on, the default) calls that supplier and runs the automaton over the text; with WEIGHT_MATCHES on (the default since 9.0.0) it uses
Weight#matchesinstead.
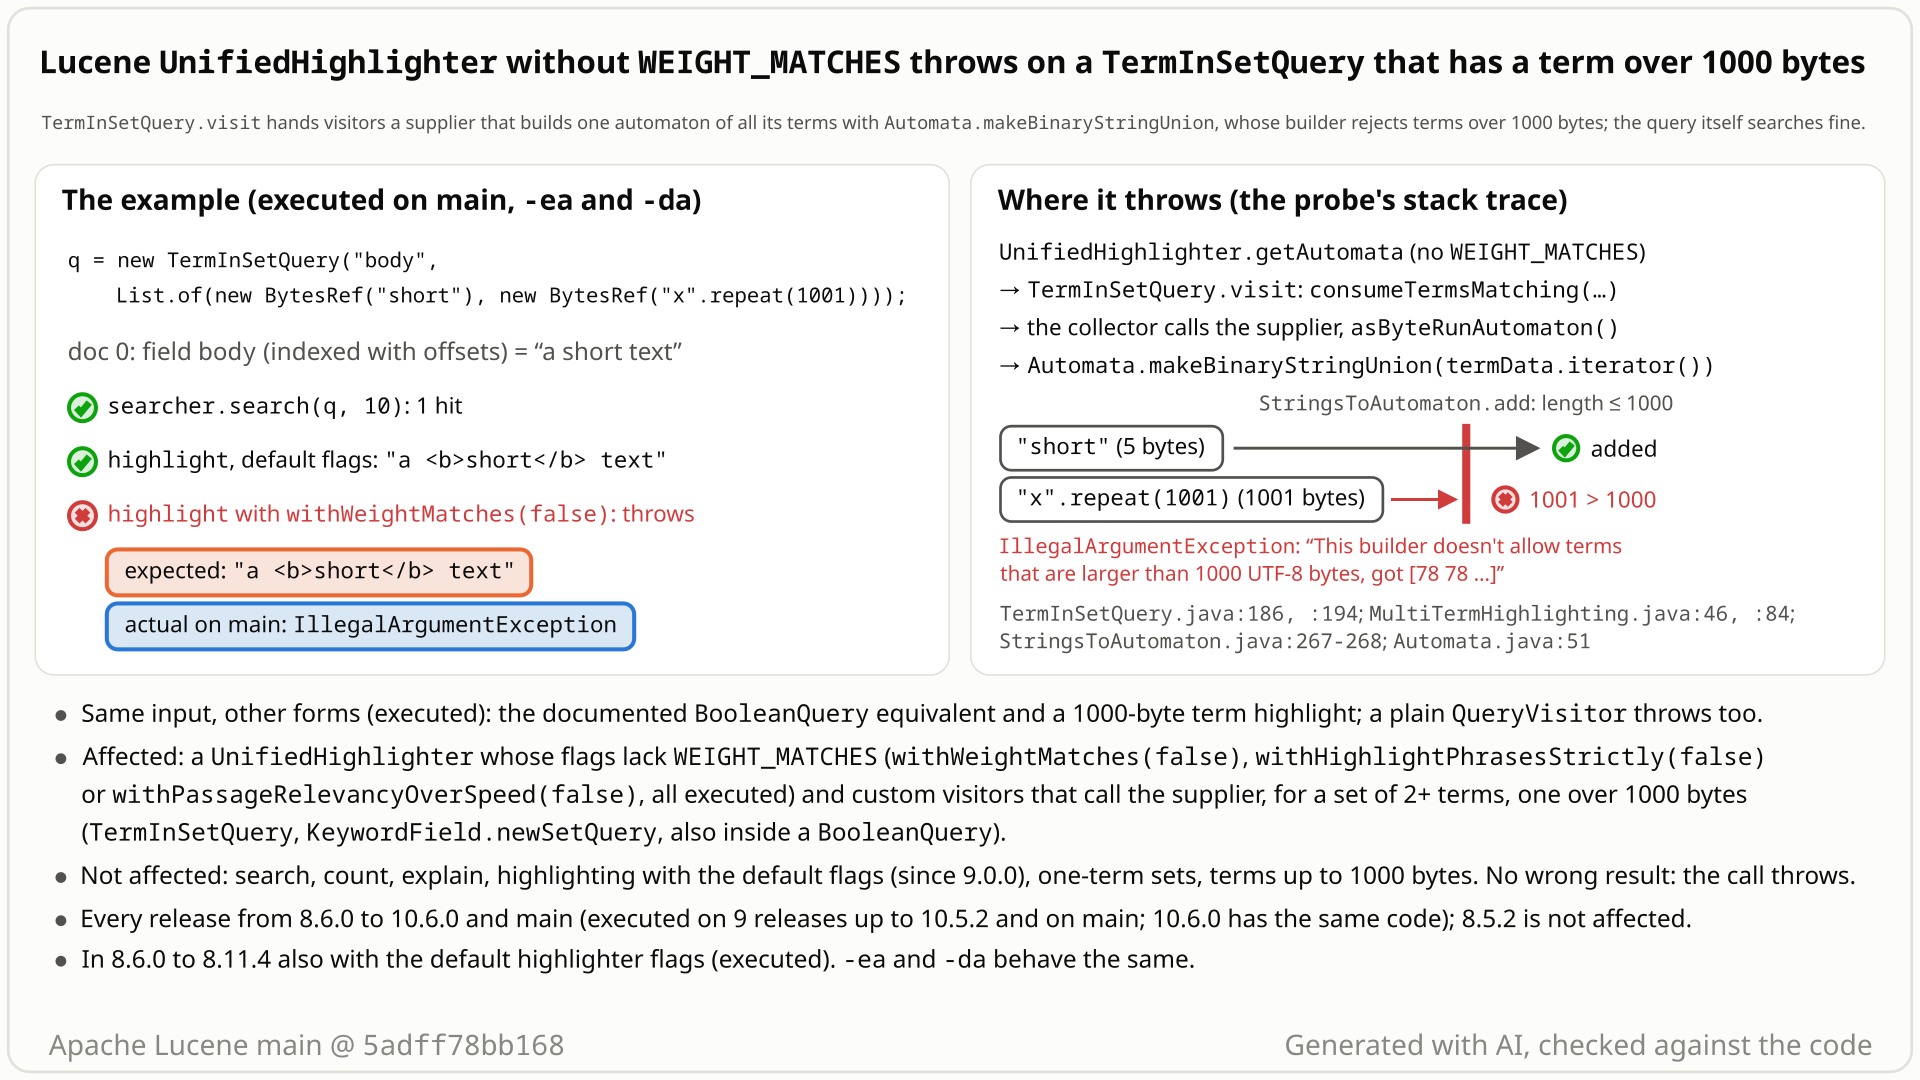
- Index one document whose field
bodyis "a short text", with offsets. Searchnew TermInSetQuery("body", ["short", "x" repeated 1001 times]): 1 hit, as expected. - Highlight it with
UnifiedHighlighter.builder(searcher, analyzer).withWeightMatches(false). You expecta <b>short</b> text, which is what the same two terms give as aBooleanQueryof SHOULDTermQuerys. - Instead
highlight()throwsIllegalArgumentException: This builder doesn't allow terms that are larger than 1000 UTF-8 bytes, with assertions on and off, on main and 10.6.0. With a 1000-byte term it works. - Why: for two or more terms,
TermInSetQuery#visitgives visitors a supplier that builds one automaton over all terms withAutomata.makeBinaryStringUnion. That builder refuses any term over 1000 bytes (a guard for its recursion), although the query itself accepts and matches longer terms. - The highlighter calls that supplier when WEIGHT_MATCHES is off (it is on by default since 9.0.0) and MULTI_TERM_QUERY is on (the default); any custom
QueryVisitorthat asks for the automaton fails the same way. Search itself is unaffected.
Applications that highlight a TermInSetQuery (also via KeywordField.newSetQuery or inside a BooleanQuery) with WEIGHT_MATCHES off and MULTI_TERM_QUERY on, or custom visitors that call the supplier, when one set term is over 1000 bytes. The whole highlight call fails; search is unaffected. Default highlighter flags are safe since 9.0.0. Rare. Priority Low.
Mechanism, terms and numbers441 words
For a set of two or more distinct terms, TermInSetQuery#visit reports its terms through QueryVisitor#consumeTermsMatching with a supplier that builds Automata.makeBinaryStringUnion over all terms. That builder rejects any term longer than Automata.MAX_STRING_UNION_TERM_LENGTH (1000 UTF-8 bytes), a guard for its recursive construction. TermInSetQuery itself accepts such terms and searches with them, so the supplier throws IllegalArgumentException for the query's own term set. The UnifiedHighlighter calls the supplier when WEIGHT_MATCHES is off and MULTI_TERM_QUERY is on (the default), that is after withWeightMatches, withHighlightPhrasesStrictly or withPassageRelevancyOverSpeed is set to false, so highlight() throws instead of returning snippets; custom visitors that call the supplier fail too. The documented equivalent, a ConstantScoreQuery over a BooleanQuery of SHOULD TermQuerys, highlights the same input. Search, count and default-flag highlighting are unaffected. It came with LUCENE-9349 (8.6.0; in 8.6.0-8.11.4 the default highlighter was affected too), is on main and in 10.6.0, and is not fixed upstream.
// TermInSetQuery.java at 5adff78bb168 (excerpt, "// :NNN" notes added)
public void visit(QueryVisitor visitor) {                               // :178
  ...
  if (termData.size() == 1) visitor.consumeTerms(this, new Term(field, ...));      // :182-184
  if (termData.size() > 1)  visitor.consumeTermsMatching(this, field, this::asByteRunAutomaton); // :185-187
}
private ByteRunAutomaton asByteRunAutomaton() {                         // :192
  Automaton a = Automata.makeBinaryStringUnion(termData.iterator());   // :194, every term
  return new ByteRunAutomaton(a, true);
}

// StringsToAutomaton.java
if (current.length > Automata.MAX_STRING_UNION_TERM_LENGTH) {         // :267
  throw new IllegalArgumentException("This builder doesn't allow terms that are larger than " ...);
}
// Automata.java:47-51: MAX_STRING_UNION_TERM_LENGTH = 1000, "to ensure the stack doesn't overflow
// while building, since our algorithm currently relies on recursion"UnifiedHighlighter.getHighlightComponentsextracts automata when WEIGHT_MATCHES is not in the flags (UnifiedHighlighter.java:1170-1172); WEIGHT_MATCHES is dropped whenwithWeightMatches,withHighlightPhrasesStrictlyorwithPassageRelevancyOverSpeedis false (:518-527).withHandleMultiTermQuery(false)drops it too, but it also removes MULTI_TERM_QUERY, so no automata are extracted and the supplier is not called (by reading).getAutomata(:1238-1251) visits the query only when MULTI_TERM_QUERY is in the flags (:1248-1250; on by default); for the two-term set,TermInSetQuery.visitcallsconsumeTermsMatching, and the highlighter's collector immediately callsautomaton.get()(MultiTermHighlighting.java:83-85).- The supplier runs
makeBinaryStringUnionover "short" and the 1001-byte term;StringsToAutomaton.addthrows for the long term before adding it (StringsToAutomaton.java:266-273). No stack overflow, only the exception, which ends the wholehighlight()call. - With default flags the supplier is never called: a
TermInSetQuerycounts as an unrecognized leaf under WEIGHT_MATCHES (UnifiedHighlighter.java:1185-1205), soWeight#matchesdoes the work.
Within the limit, an exhaustive check over a small enumerated corpus (3,280,539 term sets, 9,712,633,037 membership checks) found no mismatch between the supplier's automaton and the term set, which supports that the defect is the length limit only.
Exposure and likelihood216 words
- Who is hit. Code that highlights a
TermInSetQuerywith a UnifiedHighlighter whose flags lack WEIGHT_MATCHES but keep MULTI_TERM_QUERY (on by default), when the set has at least two distinct terms (duplicates are merged,TermInSetQuery.java:123-159) and one of them is over 1000 bytes. The query can come fromnew TermInSetQuery(...),KeywordField.newSetQueryor aBooleanQuerythat contains one; the set-query field must pass the field matcher (the highlighted field, or another field under an accept-all matcher). Custom or downstreamQueryVisitors that call theconsumeTermsMatchingsupplier fail the same way (by reading; a plain visitor that callssupplier.get()is executed). - Default vs opt-in. Since 9.0.0 (LUCENE-9431) the default highlighter is not affected;
withWeightMatches(false),withHighlightPhrasesStrictly(false)andwithPassageRelevancyOverSpeed(false)are documented, non-deprecated builder options. In 8.6.0-8.11.4 the default UnifiedHighlighter was affected. - Scale. None: one document and one 1001-byte value. The value does not have to be in the index, so one stray long id or URL in a user-supplied list is enough. The limit counts UTF-8 bytes, not characters.
- Effect. The whole
highlight()call throws, so no document gets snippets. No wrong result, hang, extra resource use or index change; search, count, explain andWeight#matchesof the same query work. - How likely. Rare: no report of this path was found in the more than six years since 8.6.0.
One JUnit test, one document, single thread: search the two-term set (1 hit), then highlight it with withWeightMatches(false). It must return a <b>short</b> text. It fails on main and 10.6.0 with assertions on and off, and passes with fix A.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.uhighlight;

import java.util.List;
import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.FieldType;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexOptions;
import org.apache.lucene.index.IndexReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.Query;
import org.apache.lucene.search.TermInSetQuery;
import org.apache.lucene.search.TopDocs;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.analysis.MockAnalyzer;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;

/**
 * A TermInSetQuery of "short" and a 1001-byte term finds the document, but a UnifiedHighlighter
 * without WEIGHT_MATCHES fails on it: TermInSetQuery#visit gives the highlighter an automaton
 * supplier that rejects terms longer than Automata.MAX_STRING_UNION_TERM_LENGTH (1000 bytes).
 */
public class TestTermInSetQueryLongTermHighlight extends LuceneTestCase {

  public void testHighlightWithoutWeightMatches() throws Exception {
    Analyzer analyzer = new MockAnalyzer(random());
    FieldType withOffsets = new FieldType(TextField.TYPE_STORED);
    withOffsets.setIndexOptions(IndexOptions.DOCS_AND_FREQS_AND_POSITIONS_AND_OFFSETS);
    try (Directory dir = newDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig(analyzer))) {
        Document doc = new Document();
        doc.add(new Field("body", "a short text", withOffsets));
        w.addDocument(doc);
      }
      try (IndexReader reader = DirectoryReader.open(dir)) {
        IndexSearcher searcher = new IndexSearcher(reader);
        Query query =
            new TermInSetQuery(
                "body", List.of(new BytesRef("short"), new BytesRef("x".repeat(1001))));
        TopDocs topDocs = searcher.search(query, 10);
        assertEquals(1, topDocs.scoreDocs.length); // the query itself works
        UnifiedHighlighter highlighter =
            UnifiedHighlighter.builder(searcher, analyzer).withWeightMatches(false).build();
        assertArrayEquals(
            new String[] {"a <b>short</b> text"}, highlighter.highlight("body", query, topDocs));
      }
    }
  }
}
cd $LUCENE
cp $REPRO/TestTermInSetQueryLongTermHighlight.java lucene/highlighter/src/test/org/apache/lucene/search/uhighlight/
./gradlew :lucene:highlighter:test --tests org.apache.lucene.search.uhighlight.TestTermInSetQueryLongTermHighlight -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same failure)
- Expected
- Search returns 1 hit and
highlight()returnsa <b>short</b> text. - Observed
- Search returns 1 hit, then
highlight()throwsIllegalArgumentException: This builder doesn't allow terms that are larger than 1000 UTF-8 bytes.
More files, environment, full output221 words
Public API only (TermInSetQuery, UnifiedHighlighter.builder); the package org.apache.lucene.search.uhighlight is only for locality, and the file belongs in lucene/highlighter/src/test/org/apache/lucene/search/uhighlight/. The test framework picks the directory and codec from the seed (gradle reported codec=Asserting(Lucene104)), which does not matter here: the exception comes from building the visitor's automaton. It passes :lucene:highlighter:checkGoogleJavaFormat, :lucene:highlighter:ecjLintTest and :lucene:highlighter:forbiddenApisTest. It does not compile before 9.1.0 (the builder API).
Regression test: this same test. It passes with fix A, with assertions on and off.
| lucene | main 5adff78bb168 (12.0.0-SNAPSHOT); the same test also fails on the 10.6.0, 9.12.3 and 9.6.0 release jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
# gradle, main 5adff78bb168, seed DEADBEEF, assertions on; -Ptests.asserts=false gives the same failure
TestTermInSetQueryLongTermHighlight > testHighlightWithoutWeightMatches FAILED
    java.lang.IllegalArgumentException: This builder doesn't allow terms that are larger than 1000 UTF-8 bytes, got [78 78 78 ... 78]
        at org.apache.lucene.util.automaton.StringsToAutomaton.add(StringsToAutomaton.java:268)
        at org.apache.lucene.util.automaton.StringsToAutomaton.build(StringsToAutomaton.java:260)
        at org.apache.lucene.util.automaton.Automata.makeBinaryStringUnion(Automata.java:688)
        at org.apache.lucene.search.TermInSetQuery.asByteRunAutomaton(TermInSetQuery.java:194)
        at org.apache.lucene.search.uhighlight.MultiTermHighlighting$AutomataCollector.consumeTermsMatching(MultiTermHighlighting.java:84)
        at org.apache.lucene.search.TermInSetQuery.visit(TermInSetQuery.java:186)
        at org.apache.lucene.search.uhighlight.MultiTermHighlighting.extractAutomata(MultiTermHighlighting.java:46)
        at org.apache.lucene.search.uhighlight.UnifiedHighlighter.getAutomata(UnifiedHighlighter.java:1249)
        at org.apache.lucene.search.uhighlight.UnifiedHighlighter.getHighlightComponents(UnifiedHighlighter.java:1172)
        ...
        at org.apache.lucene.search.uhighlight.UnifiedHighlighter.highlight(UnifiedHighlighter.java:748)
        at org.apache.lucene.search.uhighlight.TestTermInSetQueryLongTermHighlight.testHighlightWithoutWeightMatches(TestTermInSetQueryLongTermHighlight.java:66)

# [78 78 ... 78] is the 1001-byte term ("x" is 0x78), shortened here
# release jars, plain JUnit runner, seed DEADBEEF: 10.6.0 (assertions on and off) and 9.12.3: the same
# exception; 9.6.0: IllegalArgumentException: input automaton is too large: 1001 (Operations.isFinite)
# with fix A: BUILD SUCCESSFUL, assertions on and off- The visitor contract promises "a runnable automaton defining which terms match"; it cannot be built for the query's own terms.
- The javadoc calls the query equivalent to a
BooleanQueryof SHOULD clauses, which highlights the same input; an upstream test highlights a 1001-byteTermQuery. - #11808 met the same exception for long
TermQueryterms and filtered them instead.
The full argument221 words
- The contract.
QueryVisitor#consumeTermsMatching: "a supplier for a runnable automaton defining which terms match" (QueryVisitor.java:46).TermInSetQuery's class javadoc: it "behaves like a ConstantScoreQuery over a BooleanQuery containing only SHOULD clauses" (TermInSetQuery.java:42-45), and that form highlights the same input (the javadoc is about matching and scoring, so this is an observed control, not a documented highlighting promise).TermInSetQuery,KeywordField.newSetQuery,QueryVisitorandUnifiedHighlighter#highlightdocument no term-length limit;highlight()documents onlyIOExceptionand anIllegalArgumentExceptionfor a field without offsets (UnifiedHighlighter.java:743-746). The limit is documented only on the builder constant, whose javadoc namesmakeStringUnion(Iterable), not this query (Automata.java:47-50). - The tests.
TestTermInSetQuery.testVisitor(TestTermInSetQuery.java:508-550) asserts that the supplier's automaton accepts every term of the query, with short terms only.TestUnifiedHighlighter.testQueryWithLongTerm(TestUnifiedHighlighter.java:1766-1791) asserts that aBooleanQuerywith a 1001-byteTermQueryhighlights. No highlighter test uses aTermInSetQuery. - The history. #11808 (
188a78d7697, 2022) filters long terms on theMemoryIndexOffsetStrategypath (MemoryIndexOffsetStrategy.java:64-69); its commit message says "Rather than throwing a confusing exception, we can instead filter out the long terms".11436a848cb(2023) made a test helper fall back toOperations.unionfor a too-long term.asByteRunAutomatonhas no such guard. LUCENE-9349, which introduced the supplier, and #12320, which moved it to the string-union builder, do not discuss term length.
The devil's-advocate check134 words
The strongest case for "intended": consumeTermsMatching and Automata are @lucene.experimental; the builder limit is deliberate and tested (TestStringsToAutomaton.testLargeTerms); turning WEIGHT_MATCHES off selects the older automaton path; and #11808's commit message says "Very long terms are likely to be junk input in any case".
Why it fails: none of this is stated at TermInSetQuery, QueryVisitor or the highlighter; the query accepts and matches the term; the documented equivalent highlights; and #11808 answered the same exception on the TermQuery path by filtering, not by calling it intended. The cross-model reviewers rated the intended case moderate, the devil's-advocate check and the adjudication weak; every reviewer agreed on the root cause. A maintainer may still reasonably read it as a gap that #11808 left open (same highlighter, same exception, another path and fix site).
Recommended A: union over-long terms separately in asByteRunAutomaton (validated)
In TermInSetQuery#asByteRunAutomaton, build terms over 1000 bytes as single-string automata and union them with the string union, only when such a term exists (+24/-2). Validated: the repro passes with assertions on and off, and 27 core and 471 highlighter tests pass.
// in asByteRunAutomaton(): terms over the limit skip the string union
if (term.length <= Automata.MAX_STRING_UNION_TERM_LENGTH) {
  return term;                                   // to makeBinaryStringUnion
}
longTerms.add(Automata.makeBinary(term));
...
if (longTerms.isEmpty() == false) {
  longTerms.add(a);
  a = Operations.determinize(Operations.union(longTerms), Integer.MAX_VALUE);
}
return new ByteRunAutomaton(a, true);
All options and trade-offs3 options · 452 words
Option A is validated; B and C are alternatives a maintainer may prefer.
The diff is +24/-2 in TermInSetQuery.java only; makeBinaryStringUnion and StringsToAutomaton are unchanged. The terms still stream into makeBinaryStringUnion, through a wrapping iterator in asByteRunAutomaton that skips terms over the limit; those are built with Automata.makeBinary(term), and only when there is at least one, the string union and the long terms are combined with Operations.union and Operations.determinize(..., Integer.MAX_VALUE).
// in asByteRunAutomaton(): terms over the limit skip the string union
if (term.length <= Automata.MAX_STRING_UNION_TERM_LENGTH) {
  return term;                                   // to makeBinaryStringUnion
}
longTerms.add(Automata.makeBinary(term));
...
if (longTerms.isEmpty() == false) {
  longTerms.add(a);
  a = Operations.determinize(Operations.union(longTerms), Integer.MAX_VALUE);
}
return new ByteRunAutomaton(a, true);
Trade-offs
Sets without a long term take the old path unchanged. Sets with one get a non-minimal automaton with roughly one extra state per byte of each long term; the unbounded determinize limit is safe because the result has at most the union's states plus those (reasoned from the construction, not benchmarked). It does not remove the builder limit for other callers.
What the checks validated
Gradle in a scratch worktree of 5adff78bb168, seed DEADBEEF: the repro fails stock and passes with the fix, assertions on and off; the fix passes :lucene:core:checkGoogleJavaFormat, ecjLintMain and forbiddenApisMain; with the fix TestTermInSetQuery, TestQueryVisitor, TestKeywordField and a 3-test probe (a 32766-byte term with a short one, a set of only long terms, a 1000-byte term on the unchanged path; each checks accepted and rejected terms) pass (4 classes, 27 tests, 1 skipped, 0 failures), and the whole org.apache.lucene.search.uhighlight package passes (14 classes, 471 tests, 0 failures). Targeted suites, not a full build.
The highlighter cannot see inside the supplier, so it would have to special-case TermInSetQuery (for example via getBytesRefIterator()) or catch the exception.
Trade-offs
Fixes only the highlighter (other visitors still fail) and drops the long term from highlighting, as #11808 does.
Remove the recursion in the string-union builder so it accepts terms up to the index limit. Similar recursion limits on long legal input were lifted in #11813 (the recursive Operations.isFinite was taken out of production code on main and kept as a test utility) and #12286 (topoSort made iterative).
Trade-offs
Removes the cause for every caller (the #11808 filter and the test-helper workaround become unnecessary) but changes a core automaton builder. Note: the TODO above asByteRunAutomaton points at GH#12176; draft #12312 would build the same union in the constructor, where this limit would reject the query itself unless A or C lands first.
A service that highlights user-supplied value lists (ids, URLs) with WEIGHT_MATCHES off fails the whole highlight request when one value is over 1000 bytes; capping value length avoids it.
A semi-formal boundary-value matrix drove terms of 999, 1000, 1001, 4096 and 32766 bytes (ASCII and multi-byte UTF-8) through set queries and their consumers on the stock main jar. Every cell with a term over 1000 bytes and two or more terms threw from the visitor's supplier and from the highlighter without WEIGHT_MATCHES; search never threw.
The method in full194 words
Method: semi-formal (bounded boundary-value translation validation on the stock main jar).
- The matrix. Term byte length 999 / 1000 / 1001 / 4096 / 32766, in ASCII, 3-byte and 4-byte UTF-8; a
TermInSetQuerywith 1, 2 or 50 terms,KeywordField.newSetQueryand aBooleanQuerycontaining the set; each through search, count, explain,Weight#matches, a plainQueryVisitorthat calls the supplier, and the UnifiedHighlighter with default flags and with each of the three flags that drop WEIGHT_MATCHES; offsets from postings, term vectors and re-analysis. - Result. Every cell with a term over 1000 bytes and at least two terms threw
IllegalArgumentExceptionfrom the supplier and from the three non-WEIGHT_MATCHES highlighters; 999 and 1000 bytes never threw; search, count, explain and matches never threw. - The language within the limit. An exhaustive check of the supplier's automaton against the term set (3,280,539 sets, 9,712,633,037 membership checks, 0 mismatches; a deliberately broken reference was detected, so the check is not vacuous) showed that the defect is the limit only.
- The cause was then read from
TermInSetQueryandStringsToAutomaton, and a public-API JUnit reproduced it on main (assertions on and off) and on releases back to 9.1.0 (assertions on).
No report of this defect found (GitHub issues, PRs and commits incl. the JIRA archive, the Lucene lists, downstream trackers, the web; rechecked 2026-11-04). Related: #11808, which fixed the same exception for long TermQuery terms on another path, and #10696, another trigger of this supplier path before 9.7.0.
Searches4 searches
The recorded searches found no Lucene issue, PR, JIRA entry, list thread or commit, and nothing outside Lucene, that describes a TermInSetQuery#visit supplier that throws for a set term over 1000 bytes. Two items each touch it on one axis; two independent re-checks on 2026-11-03 found them related but about a different defect. Related items, none of them this defect:
- #11808 "Don't try to highlight very long terms" (PR, romseygeek, merged 2022, in 9.5.0; prompted by elastic/elasticsearch#46914 "Big term in a query breaks highlighting", 2019): the same builder exception for a long
TermQueryterm, fixed by filtering terms inMemoryIndexOffsetStrategy's extracted-terms automaton. It never mentionsTermInSetQueryorconsumeTermsMatching, and its fix does not reach the supplier path: a different defect at a different fix site. A maintainer may reasonably see this bug as a gap #11808 left open. - #10696 (LUCENE-9657, 2021, closed without a Lucene change): a terms filter with more than 288 values broke the UnifiedHighlighter with
TooComplexToDeterminizeException, very likely through this supplier as it was before #12320. Another trigger (term count) and another exception; #12320 (9.7.0) removed that failure. - Context: #9475 (LUCENE-8429, origin of the limit), #10389 (LUCENE-9349, the supplier), #12320, #11809 and #12284 (other recursion limits on long legal input, fixed as bugs), #13806 and #12310 (review remarks that this visitor method is heavy or "super trappy" because of its cost), #10649 (open, set-query terms not highlighted), drafts #12312 and #14350, commit
11436a848cb.
Keyword searches only; a report worded differently, or a private one, would not be found.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene incl. the JIRA archive, Elasticsearch, OpenSearch, Solr); dev@, java-user@, issues@, commits@; JIRA; web | 2026-10-27 | about 214 logged read-only queries, plus the changed files of all 409 open PRs and the history of the five fix-site files on main, branch_10x and branch_10_6 | only the related items above |
| same sources | 2026-11-03 | two independent same-defect re-checks | #11808 and #10696 related but a different defect; no report |
| GitHub, commits, downstream trackers, the four lists, JIRA, web | 2026-11-04 | prior-report tool, new spec in new wordings, 51 queries (206 distinct hits) | the closest hit is #12310 (a cost remark, not the limit); the others are the items above, the visitor's history (#10104, #10389, #13804, #13806) and highlighter or set-query items with other causes |
| apache/lucene items updated and open PRs created since 2026-10-26; upstream main file history | 2026-11-04 | searches for TermInSetQuery, StringsToAutomaton, makeBinaryStringUnion, consumeTermsMatching and UnifiedHighlighter; the open PRs' changed files; the commit history of the five files | nothing about this defect; #16975 (open) touches UnifiedHighlighter.java but only removes deprecated setters; no commit to the five files after 2026-07-31 |
Introduced by LUCENE-9349 (267d70b66b6, 2020-04-29, first in 8.6.0), which made visit hand out the automaton supplier; 8.5.2 passes. Since 9.0.0 the default highlighter is not affected; since 9.7.0 the limit is the string-union builder's. On main and in 10.6.0; not fixed upstream.
Versions tested7 rows
Introduced by 267d70b66b6 (main) and 4be69c8540b (branch_8x), "LUCENE-9349: TermInSetQuery should use consumeMatchingTerms in visit() (#1465)", romseygeek, 2020-04-29, first released in 8.6.0. Before it, visit passed the terms as a list and no automaton was built. Until 9.6.0 the supplier failed in Operations.isFinite (recursion cap 1000) with "input automaton is too large: 1001". LUCENE-9431 (2719cf6630e, 2021, 9.0.0) made WEIGHT_MATCHES the default, so since then only non-default flags reach it. #12320 (52ace7eb356, gsmiller, 2023-06-02, 9.7.0) moved the supplier to the string-union builder, whose 1000-byte limit dates from LUCENE-8429 (d78feb22361, 2018); 11436a848cb (2023, 9.9.0) reworded the message to "UTF-8 bytes". The boundary is 1000 bytes in every executed version. Upstream main has no commit to the involved files after 2026-07-31.
| Version or commit | Verdict | Result |
|---|---|---|
main 5adff78bb168 | affected | the minimal test fails through gradle and standalone runs, assertions on and off |
| 10.6.0 | affected | the minimal test fails on the release jars, assertions on and off |
| 9.7.0 to 10.5.2 | affected | fails with "... larger than 1000 UTF-8 bytes" ("characters" before 9.9.0); executed on 9.7.0, 9.12.3, 10.0.0 and 10.5.2 |
| 9.0.0 to 9.6.0 | affected | fails with "input automaton is too large: 1001" when WEIGHT_MATCHES is off; executed on 9.0.0, 9.1.0 and 9.6.0 |
| 8.6.0 to 8.11.4 | default flags too | fails with "input automaton is too large: 1001", also with the default highlighter; executed on 8.6.0 and 8.11.4 |
| 8.5.2 | not affected | a legacy-API variant of the test passes, assertions on and off (the minimal test does not compile before 9.1.0): visit reports the terms as a list. Older releases have no supplier path (by reading: the supplier came in 8.6.0, QueryVisitor in 8.1.0) |
fix A on 5adff78bb168 | not affected | the minimal test passes, assertions on and off; 27 core and 471 highlighter tests pass |
An independent reproducer, cross-model reviews (OpenAI GPT-5.6), a devil's-advocate check and the adjudication agreed on the root cause; the adjudication confirmed it with high confidence. A re-run on main on 2026-11-02 still reproduced it, and this doc's gradle runs validated fix A.
Checks and verdicts339 words
The earlier checks ran on main a9779ef3c193, where the involved files are identical to 5adff78bb168; this doc's runs used 5adff78bb168 and release jars.
| Check | Verdict | What it found |
|---|---|---|
| finder | found | Its two-test JUnit (a plain visitor that calls the supplier, and the highlighter without WEIGHT_MATCHES) fails 2 of 2 on main with assertions on and off, 40 of 40 over 20 iterations, and on 10.5.2, 9.12.3, 9.7.0, 9.6.0 and 9.1.0; it passes with the fix sketch. |
| cross-model review, refute lens (OpenAI GPT-5.6, reading only) | not real on procedure only (low) | Agreed with the root cause and found the inputs in contract; rated the intended case moderate. It could run no Java; a separate run re-ran the repro: 2 of 2 fail. |
| independent reproducer | real | Own 8-test JUnit: 4 fail on main (assertions on and off), 10.5.2 and 9.12.3 (plain supplier, KeywordField.newSetQuery, highlighter, another field under an accept-all matcher); 4 controls pass (search and count, the 1000-byte boundary, default flags). |
| cross-model review, intended lens (OpenAI GPT-5.6, reading only) | real (medium) | Intended case moderate. Executed checks around it: assertions off 2 of 2 fail, the fix 2 of 2 pass, and the BooleanQuery equivalent, the 1000-byte set and a single long term all highlight (3 of 3). |
| devil's-advocate check | real (high) | Answered eight works-as-designed arguments; on main and 10.5.2 the BooleanQuery form highlights and the set form throws. |
| adjudication | confirmed (high), priority Low | Re-ran the reproducer's test with a new seed (4 of 8 fail, controls pass, assertions on and off); with the fix 7 of 8 pass, the eighth being a test artifact (two supplier calls are correct for KeywordField.newSetQuery). |
| re-verification | still reproduces | Main e1faeba08bd, 2026-11-02: fails 2 of 2 with assertions on and off. |
| this doc | fails; fix A validated | The one-test repro fails on main and 10.6.0 (assertions on and off), 9.12.3 and 9.6.0, and passes with fix A; 27 core and 471 highlighter tests pass with the fix. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 479 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,404 words
- Registry title
- TermInSetQuery#visit gives QueryVisitor an automaton supplier that throws IllegalArgumentException when any term is longer than 1000 bytes, so UnifiedHighlighter without WEIGHT_MATCHES fails on such a query
- Area
- search / TermInSetQuery visitor (consumeTermsMatching automaton supplier over the util/automaton string-union builder's 1000-byte term limit), reached from highlighter / UnifiedHighlighter without WEIGHT_MATCHES
- Priority
- Low, rank 650: It needs WEIGHT_MATCHES turned off (or a custom visitor that calls the supplier) plus a set term over 1000 bytes and fails loudly while search stays correct, so this boundary-value crash closes the UnifiedHighlighter rare-input crash group after LFV-546.
- Impact class
- crash
- Impact note
- Applications that highlight with a UnifiedHighlighter whose flags lack WEIGHT_MATCHES (withWeightMatches(false), withHighlightPhrasesStrictly(false) or withPassageRelevancyOverSpeed(false); in 8.6.0-8.11.4 also the default highlighter), or that run a custom QueryVisitor that calls the consumeTermsMatching supplier, get an IllegalArgumentException instead of snippets (or an automaton) for a TermInSetQuery, a KeywordField.newSetQuery or a BooleanQuery containing one, as soon as the set has at least two terms and one of them is longer than 1000 bytes; default codec, no scale needed, -ea and -da; search, count, explain and default-flag highlighting are unaffected, and no wrong result, hang or index change was seen.
- Summary
- You search with a TermInSetQuery of the two terms 'short' and a 1001-byte term on a field indexed with offsets, get the hit, and highlight it with a UnifiedHighlighter built with withWeightMatches(false), expecting 'a <b>short</b> text', which is what the documented equivalent (a ConstantScoreQuery over a BooleanQuery of SHOULD TermQuery clauses) gives. Instead highlight() throws IllegalArgumentException 'This builder doesn't allow terms that are larger than 1000 UTF-8 bytes', and any QueryVisitor that asks the query for its automaton gets the same exception. For more than one term TermInSetQuery#visit hands visitors a supplier that builds Automata.makeBinaryStringUnion over all terms, and that builder rejects terms longer than Automata.MAX_STRING_UNION_TERM_LENGTH (1000 bytes, a guard for its recursive construction), although the query itself accepts such terms and searches with them.
- Introduced
- 267d70b66b6ac30db1d48f131b294512420f468c (master, first released in 9.0.0) and its branch_8x backport 4be69c8540b51f52355f9926cd84f3b3de985180 (first released in 8.6.0): 'LUCENE-9349: TermInSetQuery should use consumeMatchingTerms in visit() (#1465)' (apache/lucene-solr#1465, issue now apache/lucene#10389, author romseygeek), which switched TermInSetQuery.visit from consumeTerms(term list) to consumeTermsMatching(this::asByteRunAutomaton) for more than one term and introduced the Supplier signature; the supplier then failed in Operations.isFinite (recursion cap MAX_RECURSION_LEVEL = 1000, LUCENE-7914) through CompiledAutomaton [exec bound: 8.5.2 passes, 8.6.0 fails, -ea and -da; read: git log in the full-history clone]. GITHUB#12320 (52ace7eb3564 on main, 349b458e8895 on branch_9x, 2023-06-02, author gsmiller, first released in 9.7.0) moved the supplier to Automata.makeBinaryStringUnion, so since 9.7.0 the limit is the string-union builder's 1000-byte term limit from LUCENE-8429 (d78feb22361, 2018) [read]; the bug was kept, only the message changed. (2020-04-29 (LUCENE-9349, 267d70b66b6 and 4be69c8540b); mechanism change 2023-06-02 (#12320); builder limit 2018-07-27 (LUCENE-8429))
- First affected version
- 8.6.0 [exec, -ea and -da] (8.5.2 passes [exec, -ea and -da]: TermInSetQuery.visit still reported the term list and the supplier API did not exist); with the default UnifiedHighlighter in 8.6.0-8.11.4 [exec]; from 9.0.0 (LUCENE-9431, WEIGHT_MATCHES on by default) only with WEIGHT_MATCHES off or through a visitor that calls the supplier
- Affected versions
- every release from 8.6.0 to 10.6.0 and main (a9779ef3c193, 5adff78bb168) [exec: follow-up history sweep on 8.6.0, 8.11.4, 9.0.0, 9.1.0, 9.6.0, 9.7.0, 9.12.3, 10.0.0, 10.5.2 and main (fail 2 of 2 each; 8.6.0 also -da); finder on 10.5.2, 9.12.3, 9.7.0, 9.6.0 and 9.1.0; the independent reproduction on main (-ea, -da), 10.5.2 (-ea, -da) and 9.12.3; the intended-behaviour check on main and 10.5.2; read for the releases in between]. Message 'input automaton is too large: 1001' through 9.6.0, 'This builder doesn't allow terms that are larger than 1000 characters' from 9.7.0, '... 1000 UTF-8 bytes' since the 9.9.0 rewording; the boundary is 1000 bytes in every executed version (1000 passes, 1001 fails). branch_10_6 head 2763db11b0a has the same TermInSetQuery, StringsToAutomaton, QueryVisitor, MultiTermHighlighting and UnifiedHighlighter code as 10.5.2 [read], and the released 10.6.0 has it [exec, 2026-11-04: the one-test repro fails on the 10.6.0 jars with -ea and -da, and on main 5adff78bb168]. Not affected: 8.5.2 and older [exec 8.5.2]. Not fixed on main, branch_10x or branch_10_6.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- related items only, no report of this defect (searched 2026-10-27, read-only, re-checked 2026-11-03 in two independent passes: two scripted prior-report searches (50 GitHub issue/PR queries over apache/lucene, 6 commit, 4 downstream, 40 mailing-list queries over dev@, java-user@, issues@ and commits@, 8 JIRA and 12 web queries), 57 manual GitHub searches, the changed files of all 409 open apache/lucene PRs, the commit history of the five fix-site files on main, branch_10x and branch_10_6, 24 list, 6 JIRA and 7 web queries by hand): no issue, PR, commit, JIRA entry, list thread, downstream issue or web page reports that TermInSetQuery#visit's consumeTermsMatching supplier throws for a set query with a term over 1000 bytes. Two related items, each on one axis only: #11808 ('Don't try to highlight very long terms', romseygeek, merged 2022-09-24, released in 9.5.0, prompted by elastic/elasticsearch#46914 'Big term in a query breaks highlighting') fixed the same builder exception escaping the same UnifiedHighlighter for a long query term by filtering long terms on the MemoryIndexOffsetStrategy extracted-terms path only, and never mentions TermInSetQuery#visit; #10696 (LUCENE-9657, 2021, closed without a Lucene change) reported a terms filter with more than 288 values breaking the UnifiedHighlighter, very likely through the same supplier, with a different trigger (term count) and exception (TooComplexToDeterminizeException); #12320 (9.7.0) removed that failure and brought in the current 1000-byte one. Related, not the same: #9475 (LUCENE-8429, origin of the limit), #12320, #11809 and #12284 (other recursion-limit exceptions on long legal input, fixed as bugs), #13806 (a design remark that this supplier is heavy), #10649 (open: set-query terms not highlighted), draft #12312 (would build the same union in the TermInSetQuery constructor), draft #14350 (keeps the limit), commit 11436a848cb (a test helper that works around the limit), elastic/elasticsearch#156337 (a downstream visitor that calls these suppliers; no mention of the limit). Not fixed upstream: no change to these files on main (a9779ef3c193 plus the 4 newer commits), branch_10x or branch_10_6; no open PR changes asByteRunAutomaton or the limit. Re-check (2026-10-27, read-only gh): the apache/lucene PRs created since 2026-10-25 (#16905 to #16923, including #16913 and #16919) and issues (#16906 to #16922) do not touch TermInSetQuery, StringsToAutomaton, Automata or the highlighter; searches for TermInSetQuery, highlighter and StringsToAutomaton items updated since 2026-10-26 and for open PRs naming asByteRunAutomaton returned nothing.
- Lucene commit tested
- Lucene main
5adff78bb168(12.0.0-SNAPSHOT): the one-test repro through gradle in a scratch worktree, assertions on and off, without and with fix A, plus core and highlighter suites with fix A; standalone runs on main and on the release jars of 10.6.0 (assertions on and off), 9.12.3 and 9.6.0. Earlier checks ran on maina9779ef3c193(the involved files are identical) and on releases from 8.5.2 to 10.5.2. OpenJDK 25.0.3, Linux aarch64.
- Finding record
lucene/core/src/java/org/apache/lucene/search/TermInSetQuery.java:43-45 (class javadoc: behaves like a ConstantScoreQuery over a BooleanQuery of SHOULD clauses), :177-187 (visit), :189-201 (asByteRunAutomaton, makeBinaryStringUnion over every term)lucene/core/src/java/org/apache/lucene/util/automaton/StringsToAutomaton.java:266-272 (add rejects terms over MAX_STRING_UNION_TERM_LENGTH); Automata.java:44-51 (@lucene.experimental; MAX_STRING_UNION_TERM_LENGTH = 1000, 'to ensure the stack doesn't overflow while building')lucene/core/src/java/org/apache/lucene/search/QueryVisitor.java:40-51 (consumeTermsMatching: 'a supplier for a runnable automaton defining which terms match', @lucene.experimental)lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/MultiTermHighlighting.java:83-85 (AutomataCollector calls automaton.get()); UnifiedHighlighter.java:1163-1173 (getHighlightComponents extracts automata when WEIGHT_MATCHES is off) and :1245-1251 (getAutomata); MemoryIndexOffsetStrategy.java:62-70 (the #11808 long-term filter, on the extracted-terms path only)
- The finding in 30 seconds
lucene@5adff78bb168 lucene/core/src/java/org/apache/lucene/search/TermInSetQuery.java:177-201lucene@5adff78bb168 lucene/core/src/java/org/apache/lucene/util/automaton/StringsToAutomaton.java:266-273; lucene/core/src/java/org/apache/lucene/util/automaton/Automata.java:47-51lucene@5adff78bb168 lucene/core/src/java/org/apache/lucene/search/QueryVisitor.java:41-51lucene@5adff78bb168 lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:518-527, :1163-1183, :1185-1205, :1238-1251; lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/MultiTermHighlighting.java:54-56, :83-85
- Why it looks unintended
lucene@5adff78bb168 lucene/core/src/java/org/apache/lucene/search/QueryVisitor.java:41-51; lucene/core/src/java/org/apache/lucene/search/TermInSetQuery.java:42-57lucene@5adff78bb168 lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:734-747; lucene/core/src/java/org/apache/lucene/util/automaton/Automata.java:47-51lucene@5adff78bb168 lucene/core/src/test/org/apache/lucene/search/TestTermInSetQuery.java:508-550lucene@5adff78bb168 lucene/highlighter/src/test/org/apache/lucene/search/uhighlight/TestUnifiedHighlighter.java:1766-1791lucene@5adff78bb168 lucene/core/src/test/org/apache/lucene/util/automaton/TestStringsToAutomaton.java:95-109lucene@5adff78bb168 lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/MemoryIndexOffsetStrategy.java:62-71
- Suggested fix
lucene@5adff78bb168 lucene/core/src/java/org/apache/lucene/search/TermInSetQuery.java:190-191 (TODO, GH#12176)
- Diagrams
lucene@5adff78bb168 lucene/core/src/java/org/apache/lucene/search/TermInSetQuery.java:177-201; lucene/core/src/java/org/apache/lucene/util/automaton/StringsToAutomaton.java:266-273
- TestTermInSetQueryLongTermHighlight.java (one test, lucene/highlighter):
repro/LFV-808/TestTermInSetQueryLongTermHighlight.java(70 lines)
A picture of the repro, made in parallel with this doc from the code at 5adff78bb168 and the executed repro; the PNG is the summary still.
assets/LFV-808/bug.png(479 KB)