ASCIIFoldingFilter replaces each non-ASCII character using a table of 1,242 entries grouped by output: one block of case labels folds to G, another to g. Six entries sit in the block of the opposite case, although each line's own comment names the letter's real case.
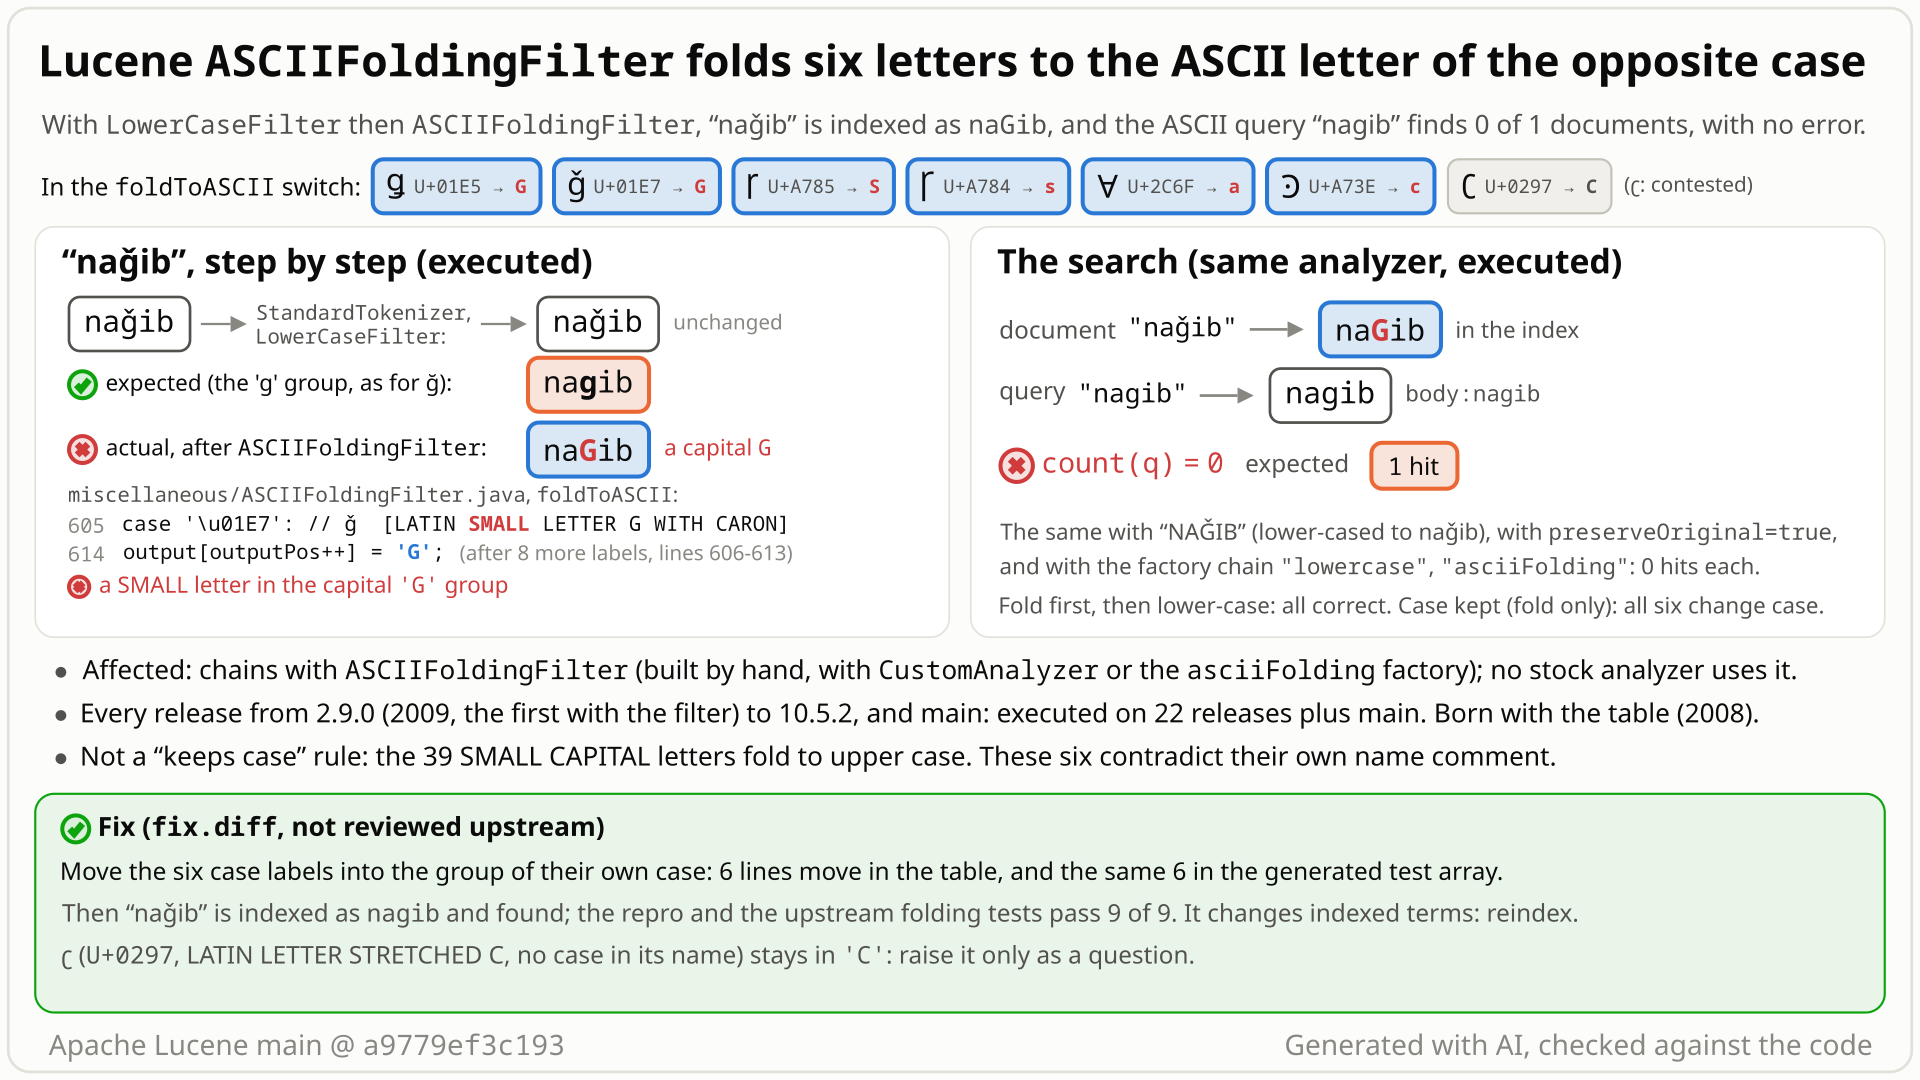
LowerCaseFilter and then ASCIIFoldingFilter: the small ǧ is listed in the capital G block of the fold table, so the index holds naGib and the query nagib gets 0 hits. Select the still to open it at full size. Generated with AI, checked against the code.- You analyze text with
LowerCaseFilterand thenASCIIFoldingFilter, at index and query time, and index the name "naǧib". ǧ is a small g with caron, used for example in Romani, Skolt Sami and Lakota and in romanized Arabic or Persian names. - You expect the term "nagib": the filter folds characters to "their ASCII equivalents", ǧ is a g plus a caron, and in the same chain "ağa" becomes "aga".
- The fold table lists ǧ among the letters that become a capital
G, so the term is "naGib". The query "nagib" finds 0 of 1 documents. "NAǦIB" is lower-cased to "naǧib" and becomes "naGib" too. - Six entries are placed like this, each against its own Unicode-name comment: ǥ, ǧ →
G; ꞅ →Sand Ꞅ →s(a swapped pair); Ɐ →a; Ꜿ →c. A field that keeps case gets all six wrong. - No error or warning, and
preserveOriginal=truedoes not help: it only adds the unfolded token. Folding first and lower-casing afterwards hides the bug.
Applications that add ASCIIFoldingFilter (opt-in; no Lucene analyzer includes it) after lower-casing, or in a field that keeps case, and index text with ǧ or ǥ (for example Romani, Skolt Sami, Lakota or romanized Arabic names) or a specialist letter. There the ASCII query term silently misses the folded term, in every release since 2.9.0.
Mechanism, terms and numbers770 words
ASCIIFoldingFilter converts non-ASCII characters "into their ASCII equivalents, if one exists". Its mapping table, the switch in foldToASCII with 1,242 case labels, groups the labels by output: one block for G, one for g, and so on. Six labels sit in the block of the opposite case: ǥ U+01E5 and ǧ U+01E7 fold to G, the insular s pair is swapped (small ꞅ U+A785 folds to S, capital Ꞅ U+A784 to s), capital Ɐ U+2C6F folds to a and capital Ꜿ U+A73E to c. Each of these lines carries a comment with the letter's Unicode name, which names the other case; the case partners of four of them (Ǥ, Ǧ, ɐ, ꜿ) sit in the right block, and the insular s pair is swapped. A chain that lower-cases and then folds therefore indexes "naǧib" as "naGib", and the lower-cased ASCII query "nagib" finds nothing, with no error. The entries have been in the table since it was added in 2008 and are in every release from 2.9.0 to 10.6.0 (10.6.0 by reading) and on main. A seventh entry, ʗ U+0297 LATIN LETTER STRETCHED C (folds to C), is contested and is raised only as a question.
- The fold table:
foldToASCII(char[], int, char[], int, int)(public static since 3.1, tagged@lucene.internal,ASCIIFoldingFilter.java:188-190, called by the filter at:153) is oneswitch (c)(:200). Each block lists case labels, each with a comment// <char> [UNICODE NAME], and then writes one output, for exampleoutput[outputPos++] = 'G'; break;. There are 1,242 case labels. - Case partner: the capital or small form of the same letter (Ǧ U+01E6 for ǧ U+01E7).
| letter | its own comment | line | sits in block | folds to | its case partner |
|---|---|---|---|---|---|
| ǥ U+01E5 | LATIN SMALL LETTER G WITH STROKE | :603 | G (:597-613) | G | Ǥ U+01E4 -> G (:602), correct |
| ǧ U+01E7 | LATIN SMALL LETTER G WITH CARON | :605 | G (:597-613) | G | Ǧ U+01E6 -> G (:604), correct (compare ğ U+011F -> g, :617) |
| ꞅ U+A785 | LATIN SMALL LETTER INSULAR S | :1216 | S (:1204-1217) | S | Ꞅ, also misplaced: the pair is swapped |
| Ꞅ U+A784 | LATIN CAPITAL LETTER INSULAR S | :1238 | s (:1220-1239) | s | ꞅ, also misplaced: the pair is swapped |
| Ɐ U+2C6F | LATIN CAPITAL LETTER TURNED A | :276 | a (:237-277) | a | ɐ U+0250 -> a (:253), correct, same block |
| Ꜿ U+A73E | LATIN CAPITAL LETTER REVERSED C WITH DOT | :395 | c (:384-397) | c | ꜿ U+A73F -> c (:396), correct, the next line |
| ʗ U+0297 (contested) | LATIN LETTER STRETCHED C (no case word) | :377 | C (:370-381) | C | none; next to ᴄ U+1D04 SMALL CAPITAL C -> C |
The other insular pairs are placed by case: Ꝺ/ꝺ (:419/:439), Ꝼ/ꝼ (:555/:566), Ᵹ/ᵹ (:611/:624), Ꞃ/ꞃ (:1171/:1195). Line numbers are at main a9779ef3c193.
- Lower-case, then fold: ǧ, ǥ and ꞅ come out as capitals; Ǧ and Ꞅ are lower-cased to ǧ and ꞅ first and then also come out as capitals. Ɐ and Ꜿ are lower-cased to ɐ and ꜿ, which fold correctly, so this order hides those two.
- Fold only (a field that keeps case, like the factory's own javadoc example,
WhitespaceTokenizerFactory+ASCIIFoldingFilterFactory): all six fold to the wrong case. - Fold, then lower-case: every result is correct, because the output is lower-cased afterwards.
On main, WhitespaceTokenizer + LowerCaseFilter + ASCIIFoldingFilter turns "naǧib NAǦIB aǥa ꞅet Ꞅet" into [naGib, naGib, aGa, Set, Set] instead of [nagib, nagib, aga, set, set]; an index of "ağa" and "naǧib" answers the query "aga" with 1 hit and "nagib" with 0. Without lower-casing, ǥ ǧ ꞅ Ꞅ Ɐ Ꜿ fold to G G S s a c instead of g g s S A C, while the controls ğ Ǧ ɐ ꜿ fold to g G a c. An exhaustive fold of all 65,536 BMP code units through the stock jar finds exactly these seven case violations among 891 mapped letters (a check of each letter's JDK case property against the case of its output; letters whose name contains SMALL CAPITAL excluded, see below); with the six-label fix only U+0297 remains, with the seven-label variant none.
- ẛ U+1E9B LATIN SMALL LETTER LONG S WITH DOT ABOVE folds to
f(:564); a committer already called it one of the "bugs in ASCIIFoldingFilter that should be fixed" in LUCENE-1343 (#2420, 2010), and it was never changed. - LFV-819: the ligature ſt U+FB05 has no entry at all, while its sibling st U+FB06 folds to
st.
Exposure and likelihood298 words
- Who is exposed. Analysis chains that use
ASCIIFoldingFilter: built by hand, withCustomAnalyzer, or through theasciiFoldingSPI factory; no analyzer shipped with Lucene includes it. The chain must either lower-case before folding or keep case in the folded field. Lucene's own javadoc shows the lower-case-then-fold order:TruncateTokenFilterFactoryrecommendsTurkishLowerCaseFilterFactoryfollowed byASCIIFoldingFilterFactoryfor diacritics-insensitive Turkish search (Turkish itself uses ğ, which folds correctly). Both orders occur: Lucene's ownTestCustomAnalyzerfolds first and lower-cases afterwards, the order that hides the bug in lower-cased fields, while on LUCENE-7525 (#8576) a committer wrote "So ASCIIFoldingFilter is in most analysis chains the very last filter!" - Which text. ǧ and ǥ have documented modern use, for example in Romani, Skolt Sami (ǥ, as in šiõǥǥ "good"), Lakota, Berber Latin, and scholarly romanization of Arabic, Persian and Pashto names (DIN 31635 uses ǧ), per the reference articles the hunt cited. The insular s pair, turned A and reversed C with dot are mainly specialist (medieval or phonetic) letters.
- Effect. Deterministic for every such token: in the affected chain the ASCII query term (
nagib) does not match the indexed term (naGib), so a search on that field misses the document; a query with the same non-ASCII letter still matches. No exception, no index damage, nothing in the logs.preserveOriginal=truekeeps the unfolded token next to the wrong one, which does not help an ASCII query. - How likely. Rare by accident, because these letters are rare in most corpora, but systematic in collections where they occur (transliterated names in scholarship, Sami or Romani text).
- Also affected. Code that calls the public static
foldToASCII(...)directly (from 3.1; it is tagged@lucene.internal, so not a supported API contract), and the copies of the table outside Lucene (see the downstream note).
The test shows that ASCIIFoldingFilter folds ǧ (U+01E7 LATIN SMALL LETTER G WITH CARON) to capital G: its table entry is in the 'G' group, not the 'g' group.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.miscellaneous;

import org.apache.lucene.tests.analysis.BaseTokenStreamTestCase;

public class TestASCIIFoldingOppositeCase extends BaseTokenStreamTestCase {

  public void testSmallGWithCaron() throws Exception {
    // expected: small g with caron (U+01E7) folds to small "g"; actual: capital "G"
    assertTokenStreamContents(
        new ASCIIFoldingFilter(whitespaceMockTokenizer("ǧ")), new String[] {"g"});
  }
}
# in a copy of this finding's repro folder (repro/LFV-818/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.miscellaneous.TestASCIIFoldingOppositeCase
- Expected vs actual
- Expected the token
g; actualG(-ea and -da).
More files, environment, full output38 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: term 0 expected:<[g]> but was:<[G]>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:262)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:513)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:598)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:622)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:689)
org.apache.lucene.analysis.miscellaneous.TestASCIIFoldingOppositeCase.testSmallGWithCaron(TestASCIIFoldingOppositeCase.java:25)- Each misplaced line's comment names the other case:
[LATIN SMALL LETTER G WITH CARON]sits in the capitalGblock. - Their partners follow case: Ǥ and Ǧ fold to
G, ğ tog, ɐ and ꜿ to lower case; the insular s pair is simply swapped. - The test asserting today's outputs was generated from the table by a script.
The full argument329 words
- The comments were the verification aid. In LUCENE-1390 (#2464) the contributor who added the Unicode-name comments wrote that the mappings were generated by script "and then moved things around to the appropriate places by hand. I guess this is one weakness of this patch: it's large enough that manual verification is tough. It's my hope that adding the Unicode character descriptions will allow for at least improved verifiability." Six of those descriptions name the case opposite to their block.
- Placement by case was the intent. A later patch revision in the same issue "moves all schwa characters to the 'A' or 'a' depending on their case", and an earlier one "fixes a couple of character mappings that were out of order in the mapped-to-capital-"B" section": hand-placement slips were already being fixed in review.
- The design rule gives the other answer. The stated rule was to "convert characters to those that look like them in ASCII"; a small ǧ looks like a small g, and capital Ɐ and Ꜿ look like capitals.
- Contract and tests. The class javadoc promises "their ASCII equivalents" and its one example keeps case ("'à' will be replaced by 'a'"); the hand-written
testLatin1Accentsasserts both cases ("À" -> "A", "à" -> "a"). ǧ's canonical decomposition is g + combining caron (NFD U+0067 U+030C). - The generated test is no evidence of intent.
testAllFoldingsasserts these outputs, but its comment says "The following Perl script generated the foldings[] array automatically from ASCIIFoldingFilter.java". - Precedent, and its limits. In LUCENE-1343 (#2420) a committer listed a self-inconsistent entry (U+1E9B) among the "bugs in ASCIIFoldingFilter that should be fixed", but that entry was never changed (ẛ still folds to
f,:564). No mapping in the table has changed since 2008 (it is identical at all 21 revisions of the file), so this would be the first table change. LUCENE-7468 (6.3.0, "Bug Fixes") changed the filter's output only underpreserveOriginal=true, where it stopped emitting a duplicate token: a limited precedent.
The devil's-advocate check299 words
The intended-behaviour checker built the strongest case for "intended": the javadoc has no case clause (its predecessor ISOLatin1AccentFilter said "The case will not be altered", and that sentence was not carried over); the table folds all 39 SMALL CAPITAL letters to upper case on purpose ("ᴄat" becomes Cat even after LowerCaseFilter, executed); the generated test has asserted these outputs for almost 18 years, and maintainers may treat it as a compatibility oracle; in LUCENE-1029 (#2105) participants objected to changing the older accent filter, one because it "would break indexes out there that use it", and a committer wrote that its functionality "shouldn't change in a way that wouldn't be b[a]ckward compatible"; and nobody reported these entries in almost 18 years.
Why it fails: the claim is not "case must be preserved" but six entries placed against their own names (and, for four of them, against their correctly placed partners). Small capitals are a uniform, deliberate choice under the look-alike rule; these six are isolated exceptions in blocks that otherwise follow case. The test was generated from the table. The back-compat objection was about deliberate semantics and argues for a CHANGES/MIGRATE note, not for intent, but it is a real cost: no table mapping has ever changed, so propose the fix for 11.0. The 2010 comparison with ICU folding could not see case errors because ICU folding lower-cases its output. Verdict: not intended for the six. The case survives only for ʗ U+0297. For a bug: Unicode gives it General Category Ll (a lower-case letter), which is why the case check flags it. For intent: its name, LATIN LETTER STRETCHED C, has no SMALL/CAPITAL, it has no case partner (upper-casing returns it unchanged), and C fits the look-alike rule like the small capitals. Raise it as a question only.
Recommended Move the six case labels into the block of their own case (and the same six entries of the generated test)
Move the six case labels into the block of their own case: six lines move in ASCIIFoldingFilter.java and the same six entries in the generated testAllFoldings array; ʗ U+0297 stays. The repro and all 1,912 tests of lucene/analysis/common pass. It changes indexed terms, so affected fields need reindexing.
           case '\u01E4': // Ǥ  [LATIN CAPITAL LETTER G WITH STROKE]
-          case '\u01E5': // ǥ  [LATIN SMALL LETTER G WITH STROKE]
           case '\u01E6': // Ǧ  [LATIN CAPITAL LETTER G WITH CARON]
-          case '\u01E7': // ǧ  [LATIN SMALL LETTER G WITH CARON]
 ...      (the rest of the 'G' block; output 'G')
           case '\u0123': // ģ  [LATIN SMALL LETTER G WITH CEDILLA]
+          case '\u01E5': // ǥ  [LATIN SMALL LETTER G WITH STROKE]
+          case '\u01E7': // ǧ  [LATIN SMALL LETTER G WITH CARON]
           case '\u01F5': // ǵ  [LATIN SMALL LETTER G WITH ACUTE]
 ...      (the same move for U+A785/U+A784 between 'S' and 's', U+2C6F to 'A', U+A73E to 'C',
 ...       and for the same six entries in TestASCIIFoldingFilter.testAllFoldings)
All options and trade-offs4 options · 861 words
One fix was applied in a scratch worktree at a9779ef3c193 and run through gradle (seed DEADBEEF), and the seven-label variant was run too; the documentation-only option and the workaround were not run.
Move the six case labels into the block of their own case (and the same six entries of the generated test) (validated by the checks) (recommended)
In ASCIIFoldingFilter.java, U+01E5 and U+01E7 move from the G block to the g block, U+A785 and U+A784 swap blocks, U+2C6F moves to A and U+A73E to C, each kept in code-point order inside its block. In TestASCIIFoldingFilter.testAllFoldings, the same six entries move between the same blocks of the generated array, which its comment says was generated from the table. The change is a pure permutation of existing lines: per file, six lines out and the same six lines in (24 changed lines in two files). U+0297 is left alone.
           case '\u01E4': // Ǥ  [LATIN CAPITAL LETTER G WITH STROKE]
-          case '\u01E5': // ǥ  [LATIN SMALL LETTER G WITH STROKE]
           case '\u01E6': // Ǧ  [LATIN CAPITAL LETTER G WITH CARON]
-          case '\u01E7': // ǧ  [LATIN SMALL LETTER G WITH CARON]
 ...      (the rest of the 'G' block; output 'G')
           case '\u0123': // ģ  [LATIN SMALL LETTER G WITH CEDILLA]
+          case '\u01E5': // ǥ  [LATIN SMALL LETTER G WITH STROKE]
+          case '\u01E7': // ǧ  [LATIN SMALL LETTER G WITH CARON]
           case '\u01F5': // ǵ  [LATIN SMALL LETTER G WITH ACUTE]
 ...      (the same move for U+A785/U+A784 between 'S' and 's', U+2C6F to 'A', U+A73E to 'C',
 ...       and for the same six entries in TestASCIIFoldingFilter.testAllFoldings)
Trade-offs
- Reindexing. Indexed terms change for text with these letters: documents indexed with the old table keep
naGib, new queries producenagib. Expect a back-compat reply: no mapping of this table has changed since 2008 (LUCENE-7468 in 6.3.0 changed only the duplicate token underpreserveOriginal), andtestAllFoldingshas asserted these outputs all along. Suggest the fix for 11.0 with a CHANGES entry and a MIGRATE.md note (reindex fields folded byASCIIFoldingFilterthat may contain ǥ, ǧ, ꞅ, Ꞅ, Ɐ or Ꜿ). A 10.x backport is the committers' call. - No API change. No performance effect is expected (the same switch, the same 1,242 labels and the same output lengths); not benchmarked.
- Copies of the table outside Lucene need the same change separately.
What the checks validated
- Stock main
a9779ef3c193(gradle, seed DEADBEEF): the repro fails 3 of 3 with assertions on and off;TestASCIIFoldingFilterandTestAsciiFoldingFilterFactorypass (6 tests). - With the fix: the repro and the two upstream suites pass with assertions on and off (9 tests, 0 failures each way, final test file); all of
:lucene:analysis:common:testwith the repro added passes (340 classes, 1,912 tests, 0 failures, 18 skipped);ecjLintMain,ecjLintTestandcheckGoogleJavaFormatpass for the module with the fix, and again for the final test file. - Run order, for the record: the module-wide run and the fix's lint run used the test before its class javadoc was reworded (a comment-only change); after the rewording, google-java-format left the file unchanged, and the stock and fixed repro runs above were repeated with it.
- The table change alone is not enough: with only
ASCIIFoldingFilter.javachanged, the unchanged upstreamTestASCIIFoldingFilterfails 1 of 5 (testAllFoldings), so the generated array must move too. - Through the classpath runner (fix shadowed onto the main jars): the repro passes 3 of 3 with
-eaand-da; the finder's broader JUnit then fails only on U+0297. - The fix, the fix with the repro as a new test file, and the seven-label variant all apply cleanly to a clean
a9779ef3c193tree.
The finder's original sketch: the same six moves plus U+0297 from the C block to the c block, in the table and in the generated test.
Trade-offs
ʗ (LATIN LETTER STRETCHED C) is General Category Ll in Unicode, but it has no case partner (upper-casing returns it unchanged) and no SMALL/CAPITAL in its name, so C may be intended under the look-alike rule, like the small capitals. Better raised as a question for the reviewers than bundled into the fix.
What the checks validated
- This doc's gradle run: the repro, the finder's JUnit,
TestASCIIFoldingFilterandTestAsciiFoldingFilterFactorypass (13 tests, 0 failures). - In the hunt, through the classpath runner: 10 tests, 0 failures, two seeds; the exhaustive check then reports 0 case violations.
Say in the javadoc that a few entries fold across case, and recommend folding before lower-casing.
Trade-offs
Not run. A reasonable choice for 10.x if committers do not want indexed terms to change in a minor release (it could pair with the fix in 11.0); on its own it leaves fields that keep case wrong and the six comments contradicting their blocks.
Put LowerCaseFilter after ASCIIFoldingFilter; that hides all six in lower-cased fields. A field that keeps case can use, for example, a MappingCharFilter override for these letters.
Trade-offs
Not run. Changes the analysis chain, so it also needs reindexing, and it does not help other users of the table.
The same table ships unchanged in copies outside Lucene, such as Solr's sample mapping-FoldToASCII.txt and ports of the filter in Lucene.NET and in JavaScript and Python packages, so their users get the same folds.
An exhaustive check folded all 65,536 BMP characters through the real jar and compared the case of every folded letter with Unicode data, leaving out small capitals, which fold to upper case on purpose. Exactly seven letters fold to the opposite case; six contradict their own name comment, and the seventh, ʗ, is contested.
The method in full240 words
Method: bounded-exhaustive checking of the stock jar against an exact reference (semi-formal tier), in a hunt unit that checked the ASCII folding table against the Unicode Character Database.
- A planning probe first folded every BMP code unit through the stock jar's public static
ASCIIFoldingFilter.foldToASCIIand flagged letters whose ASCII output has the opposite Unicode case. - The hunt then turned this into a proof by exhaustion over all 65,536 BMP code units on the stock jar, against JDK 25 Unicode data (NFKD, case properties, character names) and ICU4J 78.3 UTR#30 folding, with an independently parsed model of the source table that agrees with the jar on 65,536 of 65,536 code units. The case property (a mapped lower-case letter folds to lower-case ASCII and vice versa; letters whose name contains SMALL CAPITAL excluded as a uniform rule) has exactly 7 violations among 891 mapped letters, one more (U+0297) than the probe listed; with the seven-label fix, 0. This case check is a heuristic (the JDK case property of the letter against the case of a single-case output); that six of the seven sit opposite the case named in their own comments was then read from the source.
- The finding was reduced to a public-API JUnit and checked by an independent reproducer, an intended-behaviour devil's advocate, reading-only reviews by a model from another family (OpenAI GPT-5.6), an adjudication, a history, prior-report and security follow-up, and an audit. Found 2026-10-28 on main
a9779ef3c193.
No prior report found (2026-10-28): 156 queries over GitHub issues, PRs and commits, the Lucene and Solr lists, the JIRA archive, downstream trackers and the web, plus the changed files of all 411 open PRs. The issue that added the table never discusses these entries.
Searches5 searches
Verdict new: no report by anyone. Keyword search cannot prove absence; private trackers, non-indexed forums and private security reports cannot be searched. The nearest items are listed below; none of them is this bug.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene), Solr, Elasticsearch and other downstream repos; dev@, java-user@, issues@, commits@, solr-user@, general@; the JIRA archive; the web | 2026-10-28 | the hunt's prior-report tool (26 issue/PR, 4 commit, 4 downstream, 30 list, 6 JIRA and 6 web queries: class names, Unicode letter names, code points, insular, caron, stroke, uppercase/capital) | no report; nearest: #2464 (LUCENE-1390, added the table; none of the entries discussed), #2420 (LUCENE-1343, other entries such as U+1E9B, no case error) |
| apache/lucene, Lucene.NET, Solr, Elasticsearch, tantivy, the table's JavaScript port, and all of GitHub | 2026-10-28 | 30 own searches (27 issue and 3 PR searches) by Unicode letter name, hex code point and "uppercase/capital" | nothing on point; lance-format/lance#9565 and PR #9566 (open, 2026-09): a downstream port emits upper-case ASCII from lower-case-then-fold for caseless symbols such as ™ -> TM, deliberate output, a different cause and fix site |
| all 411 open apache/lucene PRs; PRs updated since 2026-10-25; issues created since 2026-10-24 | 2026-10-28 | changed-file lists; titles and files | none touches the folding table; the last commit to the file (#16063, 2026-05-15) only removes final modifiers |
| JIRA (LUCENE, SOLR, LUCENENET), Solr and Lucene.NET lists, Stack Exchange, forums; full comment threads of #2464, #2420, #3090, #8576, #6682 and #2655 | 2026-10-28 | 8 JQL and 30 list queries; the threads grepped for the code points, letter names and case words | no report |
| the finder's and the devil's advocate's searches | 2026-10-28 | 45 and 42 queries | no report |
Born with the table: 8660ccb303f6 (LUCENE-1390, 2008-12-06), first released in 2.9.0. The table is identical at every revision and release since; executed and failing on 22 releases from 2.9.0 to 10.5.2 and on main.
Versions tested5 rows
Introduced with the class by 8660ccb303f6 "LUCENE-1390: Added ASCIIFoldingFilter ..." (2008-12-06, SVN trunk r724053; CHANGES credit "Andi Vajda, Steven Rowe via Mark Miller"; the JIRA issue is now GitHub #2464, no PR). Not a regression: the final patch attachment in the JIRA archive has the identical table, and git blame -w -M -C (also ignoring the 2020 reformat) and git log -S per label give only this commit.
The parsed table (1,242 rows) is identical at all 21 revisions of the file and at all 136 release tags of the history clone that contain the commit; the branch_10x and branch_10_6 heads carry it too. 2.4.1 has no ASCIIFoldingFilter; its predecessor ISOLatin1AccentFilter did not map these letters. The last upstream commit to the file, c2825cfc4b2a (#16063, 2026-05-15), only removes final modifiers.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's JUnit fails 3 of 3 through gradle (assertions on and off) and the classpath runner (-ea, -da); passes with the fix |
| 10.5.2, 9.12.3 | affected | this doc's JUnit fails 3 of 3; the finder's and the reproducer's JUnits fail 4 of 4 |
| 9.1.0, 10.0.0 | affected | the finder's JUnit fails 4 of 4 |
| 2.9.0 to 9.0.0 (2.9.0, 2.9.4, 3.0.0, 3.0.3, 3.1.0, 3.6.2, 4.0.0, 4.10.4, 5.0.0, 5.5.5, 6.0.0, 6.2.1, 6.3.0, 6.6.6, 7.0.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0) | first release 2.9.0 | the JDK-only main() exits 1: the six entries fold to the opposite case, controls correct, the same fold hash over 63,345 BMP code units in every run |
| 2.4.1 | API absent | no ASCIIFoldingFilter (compile error); ISOLatin1AccentFilter does not map these letters |
An independent reproducer and an intended-behaviour devil's advocate reproduced it with their own tests, controls passing; reading-only reviews by a model from another family (OpenAI GPT-5.6) agreed on the root cause; an adjudication and an audit re-ran it with new seeds, and this doc's gradle runs reproduce it on a9779ef3c193.
Checks and verdicts319 words
Every executing check wrote or re-ran a repro on stock main, and every control passed. The cross-model reviews could not execute code on this host, so all execution evidence comes from the hunt's own runs.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Exhaustive BMP harness (7 case violations among 891 mapped letters, 0 with the fix), then the 4-test public-API JUnit: fails 4 of 4 on main (-ea, -da), 10.5.2 and 9.12.3; controls pass. |
| cross-model review, intended lens (OpenAI GPT-5.6, reading only) | real, medium | Root cause agrees; intended-behaviour argument moderate. Its objection that the generated testAllFoldings must change too was adopted. |
| independent reproducer | real | Own 4-test JUnit written from the claim: fails 4 of 4 on main (-ea, -da), 10.5.2 and 9.12.3; its own BMP scan finds the same seven among 868 single-letter folds of cased letters; the fix makes it pass. |
| cross-model review, refute lens (the cross-model review, OpenAI GPT-5.6, reading only) | not real, low (procedural) | Could not execute anything; its notes say this is not an affirmative refutation, its reading agrees with the root cause. The cross-model review AI tool's own runs fail 4 of 4 on main and 10.5.2 (-da). |
| intended-behaviour devil's advocate | real | High confidence for ǥ/ǧ and the insular s pair, medium for Ɐ/Ꜿ, U+0297 contested. Re-ran the repro (4 of 4 fail, -ea and -da) and its own main() on main, 10.5.2 and 9.12.3. |
| adjudication | confirmed, high | Re-ran the reproducer's JUnit (-ea) and the finder's (-da) with a new seed: 4 of 4 fail each. |
| audit | keep | Re-ran the finder's JUnit with -da and a new seed (4 of 4 fail) and a direct fold check on the main jars. |
| this doc's runs | reproduced; fix validated | Gradle in a clean worktree: the repro fails 3 of 3 on stock and passes with the six-label fix; lucene/analysis/common passes (1,912 tests). |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 476 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,346 words
- Registry title
- ASCIIFoldingFilter folds six letters to the ASCII letter of the opposite case (ǥ U+01E5 and ǧ U+01E7 to 'G', insular ꞅ U+A785 to 'S' and Ꞅ U+A784 to 's', Ɐ U+2C6F to 'a', Ꜿ U+A73E to 'c'; stretched ʗ U+0297 to 'C' is contested), so a LowerCaseFilter-then-ASCIIFoldingFilter chain indexes 'naǧib' as 'naGib' and the ASCII query 'nagib' finds nothing
- Area
- analysis-common / ASCIIFoldingFilter mapping table (foldToASCII switch)
- Priority
- Low, rank 301: The affected letters (mainly the Romani, Skolt Sami and Lakota letters ǧ and ǥ) are rare in most corpora, in an opt-in filter.
- Impact class
- silent wrong results
- Impact note
- Hits applications whose analysis chain uses ASCIIFoldingFilter (opt-in: no Lucene analyzer ships it; it is built by hand, through CustomAnalyzer or through the 'asciiFolding' SPI factory) either after LowerCaseFilter (misses for ǥ, ǧ and, through lower-casing, capital Ǧ, the insular s pair and ʗ) or in a folded field that keeps case (all seven letters), and whose text contains one of these letters, of which only ǧ and ǥ occur in real orthographies (Romani, Skolt Sami, Lakota, Berber Latin, romanized Arabic, Persian and Pashto); such documents are silently not found by ASCII-typed queries, from a single token, also with preserveOriginal=true, with no exception and no index damage, in every release since 2.9.0, while the fold-then-lowercase order hides all seven entries.
- Summary
- You index and search through a chain that lower-cases and then applies ASCIIFoldingFilter, documented to convert characters 'into their ASCII equivalents', and you type queries in plain ASCII. You expect 'naǧib' and 'NAǦIB' to be indexed as 'nagib', just as 'ağa' becomes 'aga'; instead six entries of the 1,242-entry folding table sit in the output group of the opposite case (ǥ and ǧ in 'G', ꞅ in 'S', Ꞅ in 's', Ɐ in 'a', Ꜿ in 'c', plus the contested ʗ in 'C'), so the term is 'naGib' and the query 'nagib' finds nothing. Each of the six lines carries a source comment that names the other case (for example [LATIN SMALL LETTER G WITH CARON] inside the 'G' group), and the fix is to move these case labels into the group of their own case.
- Introduced
- 8660ccb303f6 (LUCENE-1390 'Added ASCIIFoldingFilter ...', SVN trunk r724053, credited in CHANGES as 'Andi Vajda, Steven Rowe via Mark Miller'; JIRA issue migrated as #2464, no PR); born buggy, not a regression: the final patch attachment in the JIRA archive has the identical table, so the placements come from the contributed patch, whose author described it as Perl-generated from Unicode 5.1 UnicodeData.txt and then 'moved things around to the appropriate places by hand' [read: git blame -w -M -C on all seven lines (also ignoring the 2020 reformat 8ef6a0da568) and git log -S per case label give only this commit; the parsed table is identical (1,242 rows, digest 4b24fedc0e62) at all 21 main-line revisions of the file; exec: release level only, 2.4.1 has no ASCIIFoldingFilter (compile error) and 2.9.0, the first release with the class, fails] (2008-12-06 (author and committer date of 8660ccb303f6; LUCENE-1390 opened 2008-09-17, resolved 2008-12-06, fix version 2.9))
- First affected version
- 2.9.0 [exec] (first release with ASCIIFoldingFilter; 2.4.1, cut from the 2.4 branch, has no such class: compile error [exec]; its predecessor ISOLatin1AccentFilter did not map these letters [read])
- Affected versions
- every release from 2.9.0 to 10.5.2, 10.6.0 (by reading) and main a9779ef3c193 (the branch_10x and branch_10_6 heads carry the same table [read]). [exec] a JDK-only main() that drives the public TokenStream API by reflection fails with '6 of 6 letters fold to the ASCII letter of the opposite case' (U+0297 reported as 'C', not asserted; 9 same-case controls correct; the same BMP-wide fold digest b13b9b6ad318 in every run) on the 22 releases 2.9.0, 2.9.4, 3.0.0, 3.0.3, 3.1.0, 3.6.2, 4.0.0, 4.10.4, 5.0.0, 5.5.5, 6.0.0, 6.2.1, 6.3.0, 6.6.6, 7.0.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0 and 10.5.2 and on main with -ea and -da; the finder's JUnit fails 4 of 4 on 9.1.0, 9.12.3, 10.0.0, 10.5.2 and main (it needs the test framework of 9.1.0 or later); the independent reproduction's JUnit fails 4 of 4 on 9.12.3, 10.5.2 and main; all runs on JDK 25, Linux aarch64 only. [read] the same 1,242-row table at all 136 release tags of the history clone that contain the introducing commit; the public static foldToASCII(char[], int, char[], int, int) (LUCENE-2015, from 3.1) uses the same switch.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-28, follow-up prior-report record verdict new: 156 queries, among them a scripted prior-report search with 26 GitHub issue/PR, 4 commit, 4 downstream-repo, 30 mailing-list, 6 JIRA-archive and 6 web queries, 27 own GitHub issue searches in apache/lucene, the Lucene.NET, Solr, Elasticsearch, OpenSearch, tantivy and fold-to-ascii trackers and all of GitHub by Unicode letter name, hex code point and 'uppercase/capital', the file lists of all 411 open apache/lucene PRs, the 60 PRs updated since 2026-10-25, the issues created since 2026-10-24, 8 extra JIRA queries, 30 Solr and Lucene.NET list queries, Stack Exchange and forum searches, and all comments of #2464, #2420, #3090, #8576, #6682 and #2655 grepped for the code points, letter names and case words; plus the finder's 45 and the intended-behaviour check's 42 queries); nearest items, none of them this bug: #2464 (LUCENE-1390, the issue that added the table; none of the seven entries is mentioned), #2420 (LUCENE-1343, 2010: five disagreements with ICU folding, U+1E9B and four punctuation entries, no case error), lance-format/lance#9565 and PR #9566 (open, 2026-09, a downstream port: lower-case-then-fold emits uppercase for caseless symbols such as ™ -> TM, deliberate outputs, fixed there by folding first); re-checked 2026-10-28: no apache/lucene issue or PR created since 2026-10-26 touches ASCIIFolding or analysis/miscellaneous, upstream main is 20ced71c1e6e, and the last commit to the file is c2825cfc4b2a (#16063, author and committer date 2026-05-15, final modifiers only, table unchanged)
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26): this doc's JUnit through gradle in a clean worktree, stock and with the six-label fix, assertions on and off, plusTestASCIIFoldingFilter,TestAsciiFoldingFilterFactoryand all oflucene/analysis/common(1,912 tests) with the fix, and the seven-label variant (2026-10-28); through the hunt's classpath runner, the same JUnit on main (-ea,-da, fix shadowed), 10.5.2, 9.12.3 and 9.1.0. Hunt runs: a JDK-onlymain()on 22 releases from 2.9.0 to 10.5.2 and on main; the finder's JUnit on 9.1.0, 9.12.3, 10.0.0, 10.5.2 and main and the independent reproducer's on 9.12.3, 10.5.2 and main; an exhaustive fold of all 65,536 BMP code units on the main jar.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ASCIIFoldingFilter.java:26-32 (class javadoc), :72 (example), :276, :377, :395, :603, :605, :1216, :1238 (misplaced labels)lucene/analysis/common/src/test/org/apache/lucene/analysis/miscellaneous/TestASCIIFoldingFilter.java:150-151 (testAllFoldings array generated from ASCIIFoldingFilter.java by a Perl script)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ASCIIFoldingFilter.java:146-153, :190, :200, :237-278, :253, :276, :370-382, :377, :384-398, :395-396, :419, :439, :555, :566, :597-614, :602-605, :611, :617, :624, :1171, :1195, :1204-1218, :1216, :1220-1240, :1238lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ASCIIFoldingFilterFactory.java:26-32 (fold-only javadoc example)
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/TruncateTokenFilterFactory.java:39-50 (TurkishLowerCaseFilterFactory, then ASCIIFoldingFilterFactory)lucene/analysis/common/src/resources/META-INF/services/org.apache.lucene.analysis.TokenFilterFactory:70 (asciiFolding SPI); no non-test analyzer references the filter (grep of lucene/**/src/java)lucene/analysis/common/src/test/org/apache/lucene/analysis/custom/TestCustomAnalyzer.java:61-62, :134-135 (ASCIIFoldingFilterFactory before LowerCaseFilterFactory)lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ASCIIFoldingFilter.java:188 (@lucene.internal)
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ASCIIFoldingFilter.java:26-29 ("ASCII equivalents"), :72 ("'à' will be replaced by 'a'")lucene/analysis/common/src/test/org/apache/lucene/analysis/miscellaneous/TestASCIIFoldingFilter.java:48, :61, :97 (testLatin1Accents), :150-151 (Perl-generated foldings[]), :197lucene/CHANGES.txt:8809, :8824, :8835 (LUCENE-7468, 6.3.0, Bug Fixes); commit 28d187acd1e (LUCENE-7468: needToPreserve, duplicate token under preserveOriginal only)
- Suggested fix
lucene/CHANGES.txt:8835 (LUCENE-7468)
- TestASCIIFoldingOppositeCase.java (JUnit test):
repro/LFV-818/src/org/apache/lucene/analysis/miscellaneous/TestASCIIFoldingOppositeCase.java(28 lines)
Only the "c?" shown for ʗ in the table of all entries comes from the seven-label variant, as a question.
assets/LFV-818/bug.png(476 KB)