ASCIIFoldingFilter replaces each non-ASCII character using one big switch of case labels; a character without a label is copied unchanged. The table folds the Latin ligatures ff fi fl ffi ffl and st and the long s ſ, but has no label for ſt U+FB05, whose Unicode decomposition is "st" like st's.
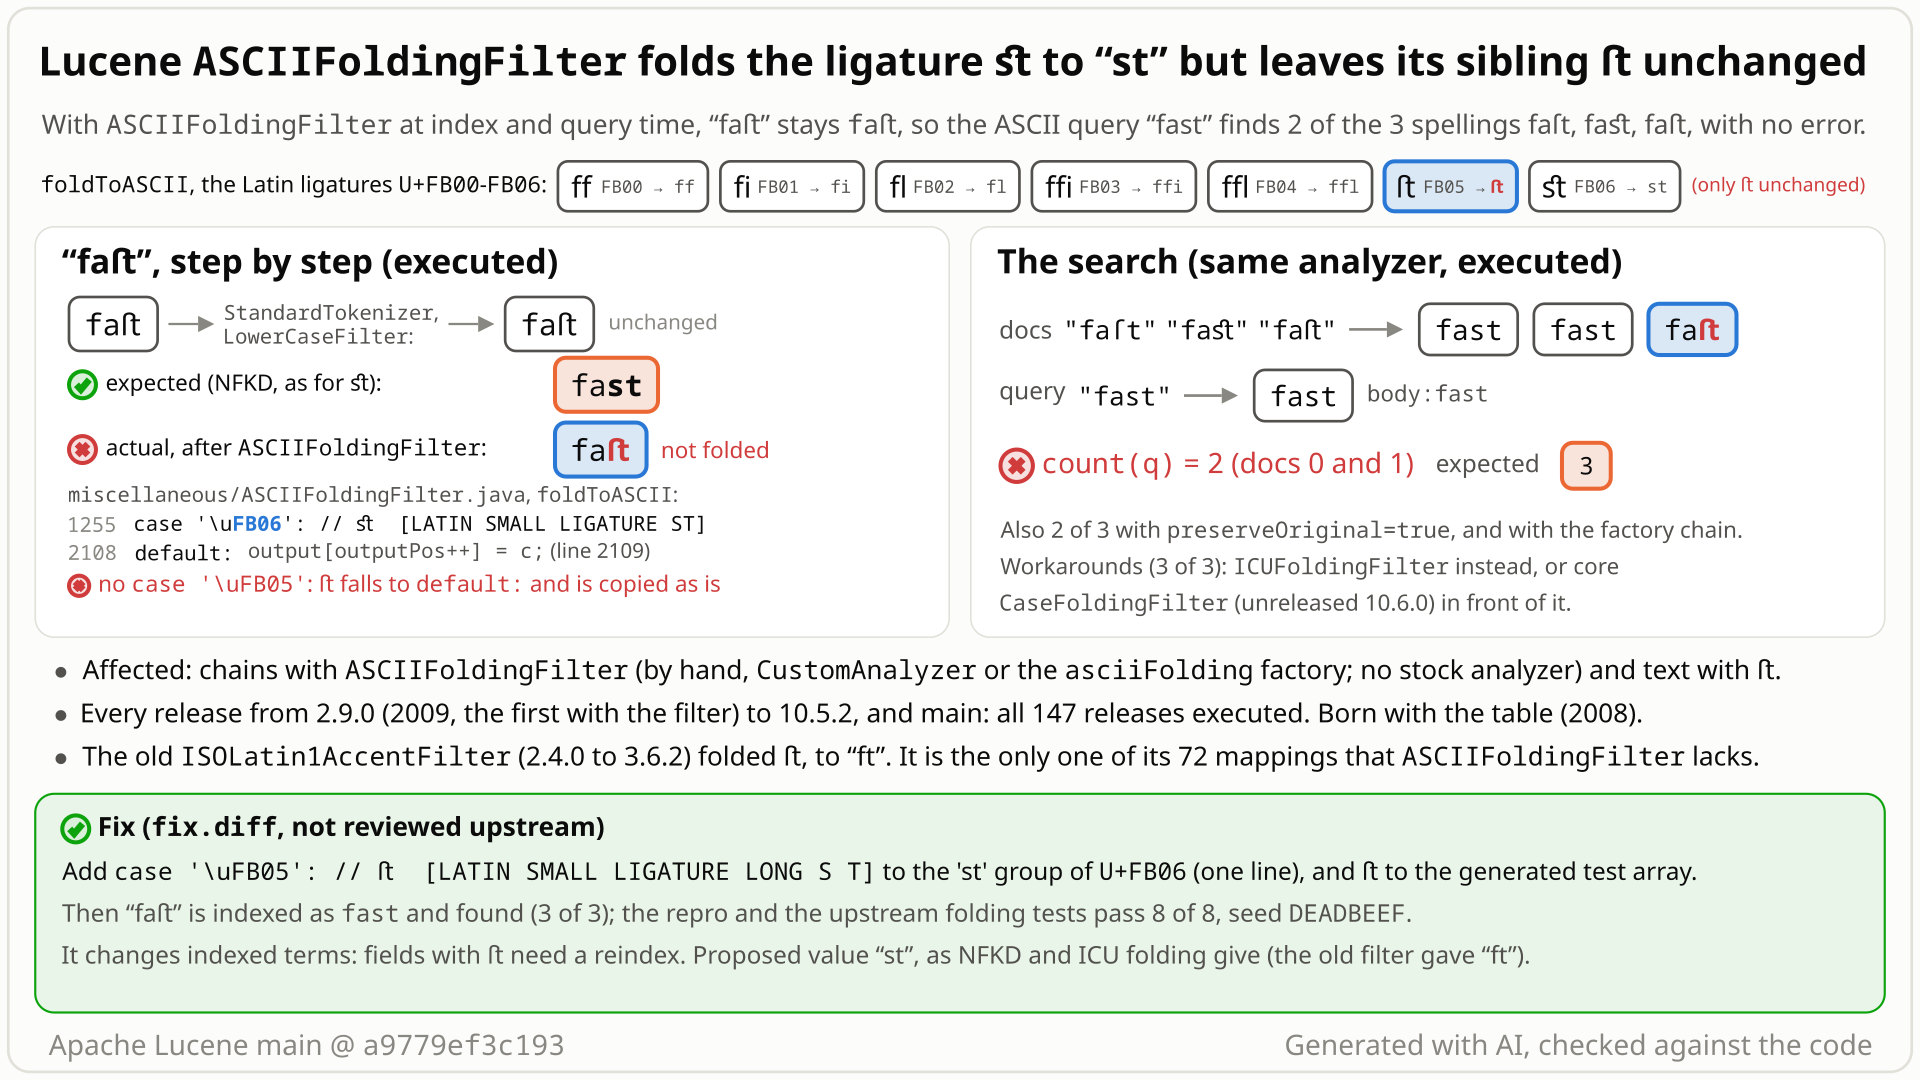
ASCIIFoldingFilter: faſt and fast become fast, while ſt has no case in the fold table and is copied as it is, so the index holds faſt and the query "fast" gets 2 of 3 hits. Select the still to open it at full size. Generated with AI, checked against the code.- You index three documents that spell "fast" three ways, "faſt" (long s ſ), "fast" (ligature st, U+FB06) and "faſt" (ligature ſt, U+FB05), with
StandardTokenizer,LowerCaseFilterandASCIIFoldingFilterat index and query time. A user types "fast". - You expect 3 hits: Unicode decomposes both ligatures to "st", and the filter already folds ſ to
sand st tost. - The fold table has a case for every Latin ligature from U+FB00 to U+FB06 except ſt, so ſt is copied unchanged: "faſt" and "fast" are indexed as
fast, "faſt" asfaſt. - The query "fast" finds 2 of 3 documents, with no error.
preserveOriginal=truealso gives 2 of 3: nothing was folded, so no extra token is added.
Applications that add ASCIIFoldingFilter (opt-in; no Lucene analyzer includes it) and whose text contains the precomposed ligature ſt, mostly transcriptions of early-modern printing or text extracted from documents set with historical ligatures. There every word with ſt is silently missed by ASCII queries, in every release since 2.9.0.
Mechanism, terms and numbers694 words
ASCIIFoldingFilter converts non-ASCII characters "into their ASCII equivalents, if one exists", and its javadoc lists the Alphabetic Presentation Forms block. Its table folds every Latin ligature of that block, ff fi fl ffi ffl (U+FB00-FB04) and st (U+FB06 to st), and the long s ſ (U+017F to s), but it has no case label for ſt U+FB05 LATIN SMALL LIGATURE LONG S T, whose Unicode compatibility decomposition (NFKD) is "st" like U+FB06's. ſt therefore falls to the default: branch and is copied unchanged: "faſt" is indexed as faſt, and the ASCII query "fast" finds the documents spelled "faſt" and "fast" but not "faſt", with no error. The table never had the entry (LUCENE-1390, 2008), so every release from 2.9.0 to 10.6.0 (10.6.0 by reading) and main is affected. For users of the filter it replaced it was an unnoticed regression: ISOLatin1AccentFilter folded U+FB05 (to ft), and U+FB05 is the only one of its 72 mappings that ASCIIFoldingFilter lacks. The fix is one case label plus the matching entry of the generated test; it changes indexed terms for text with ſt.
- The fold table:
foldToASCII(char[], int, char[], int, int)(public static, tagged@lucene.internal,ASCIIFoldingFilter.java:188-190) is oneswitch (c)(:200). Each block lists case labels, each with a comment// <char> [UNICODE NAME], and then writes the output characters.incrementToken()(:105) calls it throughfoldToASCII(char[], int)(:122,:146) for every token that has a character at or above U+0080. - NFKD: the Unicode compatibility decomposition. It turns st and ſt into "st" and ſ into "s" (the JDK's
java.text.Normalizer).
| char | Unicode name | line | folds to |
|---|---|---|---|
| ff U+FB00 | LATIN SMALL LIGATURE FF | :575 | ff |
| ffi U+FB03 | LATIN SMALL LIGATURE FFI | :579 | ffi |
| ffl U+FB04 | LATIN SMALL LIGATURE FFL | :584 | ffl |
| fi U+FB01 | LATIN SMALL LIGATURE FI | :589 | fi |
| fl U+FB02 | LATIN SMALL LIGATURE FL | :593 | fl |
| ſt U+FB05 | LATIN SMALL LIGATURE LONG S T | no case label | copied unchanged by default: (:2108-2109) |
| st U+FB06 | LATIN SMALL LIGATURE ST | :1255-1258 | st |
| ſ U+017F | LATIN SMALL LETTER LONG S | :1224 (output :1240) | s |
Line numbers are at main a9779ef3c193.
- With
StandardTokenizer,LowerCaseFilterandASCIIFoldingFilterat index and query time, "faſt" and "fast" are indexed asfastand "faſt" asfaſt. The query "fast" (body:fast) counts 2 of 3 documents; the query "faſt" still finds the third. preserveOriginal=trueadds the original token only when folding changed it (needToPreserve,:166). For "faſt" nothing changed, so the index still holds onlyfaſt, and "fast" again finds 2 of 3.- The
CustomAnalyzerchain "standard", "lowercase", "asciiFolding" gives the same 2 of 3.
An exhaustive fold of all 65,536 BMP code units through the stock jar took, in the 16 blocks the javadoc lists, every letter or digit whose NFKD (nonspacing marks removed) is ASCII: 631 code points, 583 folded, 48 not. 47 of the 48 have an explanation other than an oversight. 39 are whole classes the table never covers: 2 ordinal indicators (ª º) and 37 MODIFIER LETTER forms (the table has no ORDINAL or MODIFIER LETTER entry). 8 are subscripts U+2095-209C, added in Unicode 6.0 (2010), after the table was generated from "the Unicode 5.1 version of UnicodeData.txt" in 2008; the older subscripts U+2090-2094 are folded (:272, :273, :540, :1058, :1490). U+FB05 is the only gap that already existed when the table was made (Unicode 1.1, like U+FB06) and has a folded sibling of the same shape in its block. An independent scan of U+FB00-FB4F finds U+FB05 as the only unfolded letter there with an ASCII NFKD.
- LFV-818: six letters fold to the ASCII letter of the opposite case (for example ǧ to
G), and a seventh (ʗ U+0297 toC) is contested. - ẛ U+1E9B LATIN SMALL LETTER LONG S WITH DOT ABOVE folds to
f(:564); a committer listed it among the "bugs in ASCIIFoldingFilter that should be fixed" in LUCENE-1343 (#2420, 2010).
Exposure and likelihood231 words
- Who is exposed. Analysis chains that use
ASCIIFoldingFilter: built by hand, withCustomAnalyzer, or through theasciiFoldingSPI factory; no analyzer shipped with Lucene includes it. The text (documents or queries) must contain the precomposed ligature ſt U+FB05. - Which text. U+FB05 appears mainly in transcriptions and digitizations of early-modern long-s printing and in text extracted from documents set with historical ligatures. Ordinary text writes "st" with two letters or uses U+FB06.
- Effect. Deterministic for every token that contains ſt: the ASCII query term (
fast) does not match the indexed term (faſt), while the same word written with st or ſ is found. A query that itself contains ſt still matches. No exception, no index damage, nothing in the logs. - Settings. Assertions on or off make no difference, and
preserveOriginal=truedoes not help. - How likely. Rare: nobody has reported it in the 17 years since 2.9.0. But systematic in collections where the ligature occurs.
- Also affected. Code that calls the public static
foldToASCII(...)directly (tagged@lucene.internal, so not a supported contract), and the copies of the table outside Lucene (see the downstream note). - Workarounds today.
ICUFoldingFilterinstead ofASCIIFoldingFilter, or coreCaseFoldingFilter(new in 10.6.0; it maps U+FB05 to U+FB06) in front ofASCIIFoldingFilter: both find 3 of 3 on the example. Either changes the analysis chain, so it needs a reindex too.
The test shows that ASCIIFoldingFilter has no table entry for U+FB05 LATIN SMALL LIGATURE LONG S T, although it folds its sibling U+FB06 to "st", so "fa\uFB05" is not folded.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.miscellaneous;

import org.apache.lucene.tests.analysis.BaseTokenStreamTestCase;

public class TestASCIIFoldingLongSTLigature extends BaseTokenStreamTestCase {

  public void testLongSTLigatureFoldsToST() throws Exception {
    // expected: U+FB05 (NFKD "st") folds like its sibling U+FB06 to "fast"; actual: unchanged
    assertTokenStreamContents(
        new ASCIIFoldingFilter(whitespaceMockTokenizer("fa\uFB05")), new String[] {"fast"});
  }
}
# in a copy of this finding's repro folder (repro/LFV-819/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.miscellaneous.TestASCIIFoldingLongSTLigature
- Expected vs actual
- Expected the term "fast" (the proposed value "st" is the NFKD of U+FB05, not a promise of the current javadoc); actual: "fa\uFB05" unchanged (
term 0 expected:<fa[st]> but was:<fa[ſt]>), with-eaand-da.
More files, environment, full output38 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: term 0 expected:<fa[st]> but was:<fa[ſt]>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:262)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:513)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:598)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:622)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:689)
org.apache.lucene.analysis.miscellaneous.TestASCIIFoldingLongSTLigature.testLongSTLigatureFoldsToST(TestASCIIFoldingLongSTLigature.java:25)- The table's own rows say
st: ſ folds tos, st tost, and every other Latin ligature of the block is folded. - Unicode (NFKD), Lucene's ICU folding and core
SimpleCaseFoldingall treat ſt asst. - The filter it replaced as a documented superset,
ISOLatin1AccentFilter, folded ſt: the only one of its 72 mappings dropped.
The full argument482 words
- The table's own rows set the rule. It folds ſ U+017F to
s(:1224), st U+FB06 tost(:1255-1258) and every other Latin ligature of the block (:575-596). By its own standardstis a "reasonable ASCII alternative" for ſt, which is ſ + t. U+FB05 is the only hole among U+FB00-FB06. - Unicode and Lucene's other folding code agree on
st. NFKD(U+FB05) = NFKD(U+FB06) = "st" (JDKNormalizer, executed). Lucene's ICU folding data maps both to "st" (utr30/nfkc_cf.txt:3031,FB05..FB06>0073 0074), and coreSimpleCaseFoldingmaps U+FB05 to U+FB06 (:459-460). - A silent regression for users who migrated. LUCENE-1351 (2.4.0, filed under "Bug fixes": "ISOLatin1AccentFilter now cleans additional ligatures") added U+FB05 ->
fttoISOLatin1AccentFilter. Four months later LUCENE-1390 addedASCIIFoldingFilterand deprecated the old filter "in favor of ASCIIFoldingFilter which covers a superset of Latin 1"; from 2.9.0 to 3.6.2 the new javadoc said "The set of character conversions supported by this class is a superset of those supported by Lucene's ISOLatin1AccentFilter". The CHANGES entry on main still says the old filter "handles a subset of this filter", a contributor wrote in the issue: "This class includes all of ISOLatin1AccentFilter.", and in February 2011 a co-author repeated on the dev list that "ASCIIFoldingFilter provides a superset of it mappings". Of the old filter's 72 mappings, 71 are identical in the new table and U+FB05 is the only one missing; a scan of the 3.6.2 jars finds U+FB05 as the only character the old filter folds and the new one leaves unchanged. What migrating users lost was a match on "faft" (the old filter gaveft); the query "fast" has never matched "faſt" through either filter. The superset promise covered 2.9.0-3.6.2 only, so for current versions the case rests on the table's own consistency, not on a broken guarantee. - No record of a decision. The issue thread never mentions U+FB05, long s or ligatures; the final patch in the JIRA archive already lacks the entry; no test, CHANGES or MIGRATE entry, issue or list mail found says it was left out on purpose. No upstream test asserts that U+FB05 passes through (
testUnmodifiedLetterscovers only § ¦ ¤), andtestAllFoldingswas generated from the table by a Perl script (TestASCIIFoldingFilter.java:150-151), so it mirrors the table. The contributor called the table generated from UnicodeData.txt "and then moved things around to the appropriate places by hand. I guess this is one weakness of this patch: it's large enough that manual verification is tough." - Why it was left out is not recorded. One plausible mechanical cause (an inference, not documented): U+FB05's one-level decomposition is U+017F U+0074, which is not ASCII, while U+FB06's is U+0073 U+0074.
- What not to claim. The current javadoc does not promise this mapping: the superset sentence left together with
ISOLatin1AccentFilterin 4.0 (a58c26978f5, LUCENE-2781, 2010-11-30).
The devil's-advocate check318 words
The intended-behaviour checker built the strongest case for "intended": the javadoc says "only those characters with reasonable ASCII alternatives are converted", so the table is a curated selection with no completeness promise; the ICU module calls ICUFoldingFilter "a more thorough replacement for ASCIIFoldingFilter and LowerCaseFilter that applies the same ideas to many more languages", so gaps are expected and the remedy is to switch filters; the table has not changed since 2008 and any change alters indexed terms; and the contributor's rule, to "convert characters to those that look like them in ASCII", makes ſt ambiguous between ft (what it looks like, and what the old filter produced) and st (what it is).
Why it fails: the table already chose meaning over look for the long s (ſ, ẜ U+1E9C and ẝ U+1E9D fold to s) and folds st to st, so st is reasonable by its own standard, and NFKD, ICU folding and core case folding agree. Nothing indicates the omission was a choice: the 2.9.0-3.6.2 javadoc promised a superset of the old filter, which folded ſt, and U+FB05 is the only break. The ICU note says the ICU filter is broader, not that the table leaves a Latin presentation form of a block its javadoc lists out on purpose. The table is stable in practice (no mapping has changed since 2008, not even ẛ U+1E9B to f, called a bug in #2420 in 2010), but no freeze policy was found in the code, CHANGES, MIGRATE or the issue threads examined; back-compat is a real cost (a reindex note) and a likely review question, not evidence of intent. Verdict: the evidence favours an accidental omission; nothing found shows U+FB05 was left out on purpose. What survives is a priority argument (a committer may answer "use ICUFoldingFilter") and the ft versus st question: propose st and say plainly that the old filter gave ft.
Recommended Add U+FB05 to the U+FB06 'st' group (and the same entry to the generated test)
Add case '\uFB05' to the group that writes st for st (one line), and the same entry to the generated testAllFoldings array. The repro and all 1,912 tests of lucene/analysis/common pass, lint and format clean. It changes indexed terms, so fields with ſt need a reindex.
           case '\u00DF': // ß  [LATIN SMALL LETTER SHARP S]
             output[outputPos++] = 's';
             output[outputPos++] = 's';
             break;
+          case '\uFB05': // ſt  [LATIN SMALL LIGATURE LONG S T]
           case '\uFB06': // st  [LATIN SMALL LIGATURE ST]
             output[outputPos++] = 's';
             output[outputPos++] = 't';
             break;
 ...      (and in TestASCIIFoldingFilter.testAllFoldings: "ſt" // U+FB05 ... + "st" // U+FB06 ..., folded "st")
All options and trade-offs4 options · 632 words
One fix was applied in a scratch worktree at a9779ef3c193 and run through gradle (seed DEADBEEF), with the table line alone and with the generated-test entry; the alternatives were not run.
Add U+FB05 to the U+FB06 'st' group (and the same entry to the generated test) (validated by the checks) (recommended)
In ASCIIFoldingFilter.java, one new case label case '\uFB05': // ſt [LATIN SMALL LIGATURE LONG S T] right above the U+FB06 label, so both write s, t. In TestASCIIFoldingFilter.testAllFoldings, the generated array's st entry gains "ſt" next to "st" (the comment above the array says it was generated from the table by a Perl script). 2 files, +3/-1 lines.
           case '\u00DF': // ß  [LATIN SMALL LETTER SHARP S]
             output[outputPos++] = 's';
             output[outputPos++] = 's';
             break;
+          case '\uFB05': // ſt  [LATIN SMALL LIGATURE LONG S T]
           case '\uFB06': // st  [LATIN SMALL LIGATURE ST]
             output[outputPos++] = 's';
             output[outputPos++] = 't';
             break;
 ...      (and in TestASCIIFoldingFilter.testAllFoldings: "ſt" // U+FB05 ... + "st" // U+FB06 ..., folded "st")
Trade-offs
- Reindexing. Indexed terms change for text with ſt: documents indexed before the fix keep
faſt, new queries producefast. Suggest a CHANGES entry that says affected fields need a reindex; whether it goes to 10.x or only 11.0 is the committers' call. No mapping of this table has changed since 2008, so expect a back-compat question. - The value.
stmatches NFKD, the ICU folding data, coreSimpleCaseFoldingand the table's own ſ and st rows; the oldISOLatin1AccentFilterproducedft. - No API change. No performance effect is expected (one more label in the same switch, a two-character output like U+FB06's, within the 4 x length buffer); not benchmarked.
- Copies of the table outside Lucene need the same line separately.
What the checks validated
- Stock main
a9779ef3c193(gradle, seed DEADBEEF): the repro fails 2 of 3 with assertions on and off;TestASCIIFoldingFilterandTestAsciiFoldingFilterFactorypass (6 tests). - Table line only: the repro passes 3 of 3 with assertions on and off, and the two upstream suites pass (6 tests).
testAllFoldingschecks only the entries it lists, so it does not fail without the test change; the test change adds coverage for the new entry. - Full fix: the repro passes 3 of 3 with assertions on and off; the two upstream suites pass (6 tests); all of
:lucene:analysis:common:testwith the repro added passes (1,912 tests, 0 failures, 18 skipped);ecjLintMain,ecjLintTestandcheckGoogleJavaFormatpass for the module, and the repro needed no reformatting. - Through the classpath runner (fix shadowed onto the main jars): the repro passes 3 of 3 with
-eaand-da. In the hunt, the finder's and the independent reproducer's JUnits pass with the fix (2 of 2, 6 of 6), and the finder's JUnit plus the two upstream suites pass 8 of 8 with both parts. - The fix, the table line alone, and the fix with the repro as a new test file all apply cleanly to a clean
a9779ef3c193tree.
The same one-line change in a group that writes f, t.
Trade-offs
Not run. Fits the look-alike rule and restores the old filter's output exactly, but disagrees with Unicode and with every other Lucene folding component, and the query "fast" would still miss "faſt".
Say in the javadoc that U+FB05 is not folded.
Trade-offs
Not run. Avoids changing indexed terms, but leaves the hole and the search miss.
Use ICUFoldingFilter instead of ASCIIFoldingFilter, or put core CaseFoldingFilter (10.6.0 and later) in front of it; both give 3 of 3 on the example.
Trade-offs
Changes the analysis chain, so it also needs a reindex, and it does not help other users of the table.
The same table, without the U+FB05 entry, ships in copies outside Lucene, such as Solr's sample mapping-FoldToASCII.txt and ports of the filter in Lucene.NET and in JavaScript and Python packages, so their users get the same miss.
An exhaustive check folded all 65,536 BMP characters through the real jar and compared each with its Unicode decomposition, in the blocks the javadoc lists. Of 48 letters left unfolded although their decomposition is ASCII, 47 belong to classes the table never covers or were added to Unicode after the table; ſt is the only isolated gap.
The method in full255 words
Method: bounded-exhaustive checking of the stock jar against an exact reference (semi-formal tier), in a hunt unit that checked the ASCII folding table against the Unicode Character Database.
- A planning probe first folded every letter or digit of the 16 javadoc-listed blocks whose NFKD (nonspacing marks removed) is ASCII through the stock jar's public static
ASCIIFoldingFilter.foldToASCIIand listed the ones left unchanged. - The hunt then turned this into a proof by exhaustion over all 65,536 BMP code units on the stock jar, against JDK 25 NFKD, character names and Unicode ages and ICU4J 78.3 UTR#30 folding, with an independently parsed model of the source table that agrees with the jar on 65,536 of 65,536 code units. Its coverage property has 631 such code points, 583 folded and 48 not; U+FB05 is the only one of the 48 that is neither a class exclusion (2 ordinal indicators, 37 MODIFIER LETTER forms) nor added to Unicode after the table (8 subscripts U+2095-209C, Unicode 6.0, while the older subscripts U+2090-2094 are folded), and it has a folded sibling of the same shape in its block. This coverage property (P7) is one of several the harness checks; what the others flagged includes the separate table bugs listed under "Related entries in the same table".
- The finding was reduced to a public-API JUnit and checked by an independent reproducer, an intended-behaviour devil's advocate, reading-only reviews by a model from another family (OpenAI GPT-5.6), an adjudication, a history, prior-report and security follow-up, and an audit. Found 2026-10-28 on main
a9779ef3c193.
No prior report found (2026-10-28): 138 queries over GitHub issues, PRs and commits, the Lucene and Solr lists, the JIRA archive, ports and the web, plus the changed files of all 411 open PRs. The issue that added the table never mentions ſt.
Searches4 searches
Verdict new: no report by anyone. Keyword search cannot prove absence; private trackers, non-indexed forums and private security reports cannot be searched. The nearest items are listed below; none of them is this bug.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene), downstream repos; dev@, java-user@, issues@, commits@; the JIRA archive | 2026-10-28 | the hunt's prior-report tool: 53 queries (24 GitHub issue/PR, 3 commit, 2 downstream, 20 list, 4 JIRA), top 20 hits read with their comments | no report; nearest: #2464 (LUCENE-1390, added the table; U+FB05 not discussed), #2428 (LUCENE-1351, added U+FB05 -> ft to the old filter), #2420 (LUCENE-1343, five entries where ICU folding and the table disagree; U+FB05 is a gap, not a disagreement) |
| apache/lucene, Elasticsearch, OpenSearch, Solr, Lucene.NET | 2026-10-28 | 40 own searches (24 on apache/lucene: FB05, U+FB05, "long s", "st ligature", "LATIN SMALL LIGATURE", ligature, ASCIIFolding, ISOLatin1AccentFilter, mapping-FoldToASCII; 16 on the four downstream trackers) | nothing on point; apache/lucenenet#618 is a missing entry for a different character (U+01A6) in the .NET port |
| all 411 open apache/lucene PRs; the 18 closed since 2026-10-25; the file's history on main, branch_10_6 and branch_10x | 2026-10-28 | changed-file lists; commit history; git log -S uFB05 over the full history | no PR touches the table (only #16911, which deletes the branch_10x tree); no commit ever added or removed a U+FB05 case; the last commit to the file (#16063, 2026-05-15) only removes final modifiers |
| JIRA (LUCENE, SOLR); Lucene and Solr lists; 4 port repositories; the web | 2026-10-28 | 8 JQL, 29 list and 8 web queries; the 2011 dev@ thread "Should ASCIIFoldingFilter be deprecated?" read in full | no report |
Born with the table: 8660ccb303f6 (LUCENE-1390, 2008-12-06), first released in 2.9.0. All 147 releases from 2.9.0 to 10.5.2 were executed and fail, and so does main. The deprecated ISOLatin1AccentFilter folded ſt (to ft) until its removal in 4.0.
Versions tested6 rows
Introduced with the class by 8660ccb303f6 "LUCENE-1390: Added ASCIIFoldingFilter ..." (2008-12-06, SVN trunk r724053; CHANGES credit "Andi Vajda, Steven Rowe via Mark Miller"; the JIRA issue is now GitHub #2464, no PR). The table was born without U+FB05: the final patch in the JIRA archive already lacks it, git blame of the U+FB06 group and of U+FB00-FB04 gives only this commit, and git log --all -S uFB05 over the historical paths of the filter and its test returns nothing. All 136 release tags of the history clone that contain the commit have the U+FB06 case and no U+FB05 case.
Context. LUCENE-1351 (dd066edcf19, 2008-08-05, 2.4.0) had added U+FB05 -> ft to ISOLatin1AccentFilter; LUCENE-1390 deprecated that filter in favour of the new one; LUCENE-2781 (a58c26978f5, 2010-11-30, 4.0.0) removed it together with the superset sentence. So from 2.9.0 on, users who followed the deprecation lost the folding of U+FB05.
10.6.0 and main: the branch_10_6 head carries the same file as 10.5.2 and upstream main the same file as a9779ef3c193 (2026-10-28), so 10.6.0 (released 2026-10-29) ships it.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's JUnit fails 2 of 3 through gradle (assertions on and off) and the classpath runner (-ea, -da); passes with the fix |
| 10.5.2, 9.12.3 | affected | this doc's JUnit fails 2 of 3; the finder's fails 1 of 2 (-ea, -da), the reproducer's 4 of 6 |
| 10.0.0 | affected | the finder's JUnit fails 1 of 2 |
| 4.0.0 to 10.5.2 (130 releases) | affected | the JDK-only main() exits 1: foldToASCII("faſt") returns faſt, controls correct |
| 2.9.0 to 3.6.2 (17 releases) | first release 2.9.0 | the filter over KeywordTokenizer leaves "faſt" unchanged; the deprecated ISOLatin1AccentFilter in the same jar gives "faft" |
| 2.4.1 | API absent | no ASCIIFoldingFilter (compile error); ISOLatin1AccentFilter folds "faſt" to "faft" |
An independent reproducer and an intended-behaviour devil's advocate reproduced it with their own tests, controls passing; reading-only reviews by a model from another family (OpenAI GPT-5.6) agreed on the root cause; an adjudication and an audit re-ran it with new seeds, and this doc's gradle runs reproduce it and validate the fix.
Checks and verdicts374 words
Every executing check wrote or re-ran a repro on stock main, and every control passed. The cross-model reviews could not execute code on this host, so all execution evidence comes from the hunt's own runs.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Exhaustive BMP harness (631 code points, 48 unfolded, U+FB05 the only isolated gap), then a 2-test public-API JUnit: fails 1 of 2 on main (-ea, -da), 10.5.2 and 9.12.3; controls pass; the one-line fix passes. |
| cross-model review, intended lens (OpenAI GPT-5.6, reading only) | real, medium | Root cause agrees; intended-behaviour argument moderate, judged insufficient for U+FB05 (isolated hole, the table's own ſ and st rows, ICU data and core case folding). |
| independent reproducer | real | Own 6-test JUnit written from the claim: fails 4 of 6 on main (-ea, -da), 10.5.2 and 9.12.3; its own block scan reproduces 631/48; the fix makes it 6 of 6; found that U+FB05 is the only one of the old filter's 72 mappings that was dropped. |
| cross-model review, refute lens (the cross-model review, OpenAI GPT-5.6, reading only) | not real, low (procedural) | Could not execute anything; its notes call this "a rubric-required procedural not real, not a convincing technical refutation", and its reading agrees with the root cause. The cross-model review AI tool's own check reproduces on main (-ea, -da), also with preserveOriginal=true. |
| intended-behaviour devil's advocate | real, Low | Built the strongest intent case and showed why it fails; a scan of the 3.6.2 jars finds U+FB05 as the only break of the superset promise; re-ran the repro (1 of 2 fail, -ea and -da); its characterization test confirms both workarounds. |
| adjudication | confirmed, high | Re-ran the reproducer's JUnit with a new seed (4 of 6 fail, -ea and -da) and the finder's (1 of 2 fail). Recommends a Low bug, value st, and not claiming the current javadoc promises the mapping. |
| audit | keep | Re-ran the finder's JUnit with a new seed (1 of 2 fail) and re-checked the code and the history claim. |
| this doc's runs | reproduced; fix validated | Gradle in a clean worktree: the repro fails 2 of 3 on stock and passes with the fix; lucene/analysis/common passes (1,912 tests), lint and format clean. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 471 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,558 words
- Registry title
- ASCIIFoldingFilter folds the ligature st (U+FB06) to 'st' but has no entry for its sibling ſt (U+FB05 LATIN SMALL LIGATURE LONG S T, NFKD 'st'), so 'faſt' is indexed unchanged and the ASCII query 'fast' does not find it
- Area
- analysis-common / ASCIIFoldingFilter mapping table (foldToASCII switch)
- Priority
- Low, rank 511: ASCIIFoldingFilter is opt-in, the miss only affects relevance, and it involves one presentation-form ligature seen mostly in transcriptions of historical long-s printing, which matches the older-orthography profile of LFV-607.
- Impact class
- minor
- Impact note
- Relevance only, no error: applications whose analysis chain uses ASCIIFoldingFilter (opt-in: no Lucene analyzer ships it; it is added by hand, through CustomAnalyzer or through the 'asciiFolding' SPI factory) and whose documents or queries contain the precomposed ligature ſt U+FB05 index and query such tokens unfolded, so ASCII-typed queries silently miss them while the same word spelled with st U+FB06 or with long s ſ U+017F is found; no scale is needed, -ea and -da behave the same, preserveOriginal=true does not help, every release since 2.9.0 has it, ICUFoldingFilter used instead or core CaseFoldingFilter (new in 10.6.0) in front of ASCIIFoldingFilter avoid it today, and because a fix changes indexed terms, affected fields need reindexing after it.
- Summary
- You fold text with ASCIIFoldingFilter, whose javadoc says it converts characters 'into their ASCII equivalents, if one exists' and lists the Alphabetic Presentation Forms block, and you search in plain ASCII. You expect 'faſt' (with the long-s-t ligature U+FB05, whose NFKD is 'st') to be indexed as 'fast', just as 'fast' (U+FB06) and 'faſt' (long s U+017F) are; instead the table has cases for U+FB00-FB04 and U+FB06 but none for U+FB05, so the character passes through unchanged, the term stays 'faſt' and the query 'fast' finds nothing. The fix is one case label (U+FB05 added to the U+FB06 'st' group) plus the matching row of the generated testAllFoldings array.
- Introduced
- 8660ccb303f6 (LUCENE-1390 'Added ASCIIFoldingFilter ...', SVN trunk r724053, credited in CHANGES as 'Andi Vajda, Steven Rowe via Mark Miller'; JIRA issue migrated as #2464, no PR); the table was born without U+FB05 (the final patch in the JIRA archive already lacks it), and for users of the class it replaced it was a regression: ISOLatin1AccentFilter had folded U+FB05 (to 'ft') since LUCENE-1351 (dd066edcf19, 2008-08-05, first released in 2.4.0, filed under bug fixes), LUCENE-1390 deprecated that filter in favour of ASCIIFoldingFilter, whose 2.9.0-3.6.2 javadoc called its conversions 'a superset of' the old filter's, and U+FB05 is the only one of the old filter's 72 mappings that ASCIIFoldingFilter lacks [read: git blame of the U+FB06 group (:1255-1258) and the U+FB00-FB04 cases on main gives only this commit; git log --all -S uFB05 over the 5 historical paths of the filter and the 5 of its test returns nothing; all 136 release tags of the history clone that contain the commit have the U+FB06 case and no U+FB05 case; exec: 2.4.1 has no ASCIIFoldingFilter (compile error), 2.9.0 fails, and a BMP scan on the 3.6.2 jars finds U+FB05 as the only character that ISOLatin1AccentFilter folds and ASCIIFoldingFilter leaves unchanged] (2008-12-06 (author and committer date of 8660ccb303f6, 2008-12-06T23:25:42Z; LUCENE-1390 opened 2008-09-17, resolved 2008-12-06))
- First affected version
- 2.9.0 [exec] (first release with ASCIIFoldingFilter; 2.4.1, cut from the 2.4 branch, has no such class: compile error [exec]; in 2.4.x the then-current ISOLatin1AccentFilter folded U+FB05 to 'ft' [exec on 2.4.1])
- Affected versions
- every release from 2.9.0 to 10.5.2, 10.6.0 (by reading) and main a9779ef3c193. [exec] all 147 final lucene-core releases that Maven Central lists from 2.9.0 on fail (147 of 147, none skipped), with era-specific public-API main() repros: the filter over KeywordTokenizer for 2.9-3.6 and the public static foldToASCII, the table incrementToken uses, from 4.0 on; the finder's JUnit fails on 9.12.3, 10.0.0, 10.5.2 and main with -ea and on 9.12.3, 10.5.2 and main with -da (9.0.0: the test framework package does not exist yet, a harness limit); the independent reproduction's JUnit fails on 9.12.3, 10.5.2 and main; the intended-behaviour check's BMP scan fails on 3.6.2; all runs on JDK 25, Linux aarch64 only. [read] the 136 release tags of the history clone that contain the introducing commit (incl. 4.0.0-alpha/beta) have the U+FB06 case and no U+FB05 case; the upstream main head 20ced71c1e6 has the same file blob as a9779ef3c193 and the branch_10_6 head 4ae946e5a9b the same blob as 10.5.2, so 10.6.0 (released 2026-10-29) ships it.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-28, follow-up prior-report record verdict new: one scripted prior-report search with 53 non-web queries (24 GitHub issue/PR, 3 commit, 2 downstream, 20 mailing-list over dev@, java-user@, issues@ and commits@, 4 JIRA; top 20 hits enriched with their comments), 40 own gh searches (24 on apache/lucene incl. FB05, U+FB05, 'long s', 'st ligature', 'LATIN SMALL LIGATURE', ligature, ASCIIFolding, ISOLatin1AccentFilter, mapping-FoldToASCII; 16 on four downstream trackers), the changed-file lists of all 411 open apache/lucene PRs and of the 18 PRs closed since 2026-10-25, the commit history of ASCIIFoldingFilter.java on main, branch_10_6 and branch_10x, 8 JIRA queries (LUCENE and SOLR), 29 mailing-list queries incl. the Solr lists, 4 port repositories, 8 web searches and git log -S over the full history; plus the finder's, the independent reproduction's, the intended-behaviour check's and the adjudication's searches); nearest items, none of them this bug: #2464 (LUCENE-1390, added the table; nobody mentions U+FB05), #2428 (LUCENE-1351, added U+FB05 -> 'ft' to ISOLatin1AccentFilter), #2420 (LUCENE-1343, a 2010 list of five entries where ICU folding and ASCIIFoldingFilter both map a character and disagree; U+FB05 is a gap, not a disagreement), apache/lucenenet#618 (a missing entry for a different character, U+01A6, in the .NET port); re-checked 2026-10-28 (read-only gh): no issue or PR mentions FB05, no PR created since 2026-10-26 (#16907-#16926) matches ASCIIFolding, no open PR matches ASCIIFoldingFilter, no commit on main since 2026-10-26 touches analysis/common/.../miscellaneous, and the file's last upstream commit is c2825cfc4b2a (#16063, author and committer date 2026-05-15, 'final' modifiers only, table unchanged)
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26): this doc's JUnit through gradle in a clean worktree, stock, with the table line only and with the full fix, assertions on and off, plusTestASCIIFoldingFilter,TestAsciiFoldingFilterFactory, all oflucene/analysis/common(1,912 tests) and the module's lint and format checks with the fix (2026-10-28); through the hunt's classpath runner, the same JUnit on main (-ea,-da, fix shadowed), 10.5.2 and 9.12.3. Hunt runs: era-specificmain()programs on all 147 releases from 2.9.0 to 10.5.2 and on main; the finder's JUnit on 9.12.3, 10.0.0, 10.5.2 and main and the independent reproducer's on 9.12.3, 10.5.2 and main; a scan of the 3.6.2 jars againstISOLatin1AccentFilter; an exhaustive fold of all 65,536 BMP code units on the main jar.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ASCIIFoldingFilter.java:26-34 (at a9779ef3c193) (class javadoc: converts characters 'into their ASCII equivalents, if one exists'; 'only those characters with reasonable ASCII alternatives are converted'), :63-64 (Alphabetic Presentation Forms listed), :146-151 (output buffer sized 4 * length), :188 (@lucene.internal on the static foldToASCII overload), :575-596 (U+FB00-FB04), :1224 (U+017F -> 's'), :1255-1258 (U+FB06 -> 's','t'; no U+FB05 case anywhere), :2108-2109 (default branch copies the character)lucene/core/src/java/org/apache/lucene/util/SimpleCaseFolding.java:459-460 (at a9779ef3c193) (0xFB05 -> 0xFB06); lucene/core/src/java/org/apache/lucene/analysis/CaseFoldingFilter.java:27 (@since 10.6.0); lucene/CHANGES.txt:19528-19533 (LUCENE-1390 entry: ISOLatin1AccentFilter 'handles a subset of this filter'), :20119 (LUCENE-1351 'ISOLatin1AccentFilter now cleans additional ligatures', 2.4.0 bug fixes); lucene/analysis/common/src/test/org/apache/lucene/analysis/miscellaneous/TestASCIIFoldingFilter.java:150-151 (testAllFoldings generated from the table by a Perl script)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ASCIIFoldingFilter.java:105-131 (incrementToken), :146-157 (foldToASCII(char[], int), 4 x length buffer), :166-177 (needToPreserve), :188-200 (@lucene.internal static foldToASCII, switch), :575-596 (U+FB00-FB04), :1224 and :1240 (U+017F -> 's'), :1255-1258 (U+FB06 -> 's','t'), :2108-2109 (default copies the character); no case label for U+FB05 anywhere in the filelucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ASCIIFoldingFilter.java:272, :273, :540, :1058, :1490 (U+2090-2094 subscripts folded); no MODIFIER LETTER or ORDINAL entry
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ASCIIFoldingFilterFactory.java:35, :40 (SPI name asciiFolding); no non-test analyzer references the filter (grep of lucene/**/src/java: only javadoc in TruncateTokenFilterFactory, collation/package-info and the ICU overview, and the SPI provides list in module-info.java:210)lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ASCIIFoldingFilter.java:188 (@lucene.internal)lucene/core/src/java/org/apache/lucene/analysis/CaseFoldingFilter.java:27 (@since 10.6.0); lucene/core/src/java/org/apache/lucene/util/SimpleCaseFolding.java:459-460
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/ASCIIFoldingFilter.java:26-34 ("ASCII equivalents, if one exists"; "only those characters with reasonable ASCII alternatives"), :63-64 (Alphabetic Presentation Forms listed), :575-596, :1224, :1255-1258lucene/analysis/icu/src/data/utr30/nfkc_cf.txt:3031 (FB05..FB06>0073 0074); lucene/core/src/java/org/apache/lucene/util/SimpleCaseFolding.java:459-460 (0xFB05 -> 0xFB06); lucene/analysis/icu/src/java/overview.html:298-299 ('a more thorough replacement')lucene/CHANGES.txt:19528-19533 (LUCENE-1390: 'handles a subset of this filter'), :20119 (LUCENE-1351, 2.4.0 bug fixes)a Lucene clone releases/lucene/2.9.0: src/java/org/apache/lucene/analysis/ASCIIFoldingFilter.java (superset sentence), ISOLatin1AccentFilter.java:29-30 (deprecated 'in favor of ASCIIFoldingFilter which covers a superset of Latin 1'), :254-257 (U+FB05 -> 'f','t')lucene/analysis/common/src/test/org/apache/lucene/analysis/miscellaneous/TestASCIIFoldingFilter.java:137-148 (testUnmodifiedLetters), :150-151 (Perl-generated foldings[])
- Suggested fix
lucene/analysis/common/src/test/org/apache/lucene/analysis/miscellaneous/TestASCIIFoldingFilter.java:150-151 (Perl-generated foldings[]), :1171-1176 (the U+FB06 'st' entry)
- TestASCIIFoldingLongSTLigature.java (JUnit test):
repro/LFV-819/src/org/apache/lucene/analysis/miscellaneous/TestASCIIFoldingLongSTLigature.java(28 lines)
File names in the diagram's fix section: "fix.diff" and "test-fix.diff" are the hunt candidate's two parts (the table line, and the test row); this doc's full fix contains both, and its table-only fix is the table line alone.
assets/LFV-819/bug.png(471 KB)