The classic Highlighter rewrites parts of your query against a tiny index of the one document it highlights. Since 10.5.0 that breaks for exists clauses when the tiny index is built from term vectors.
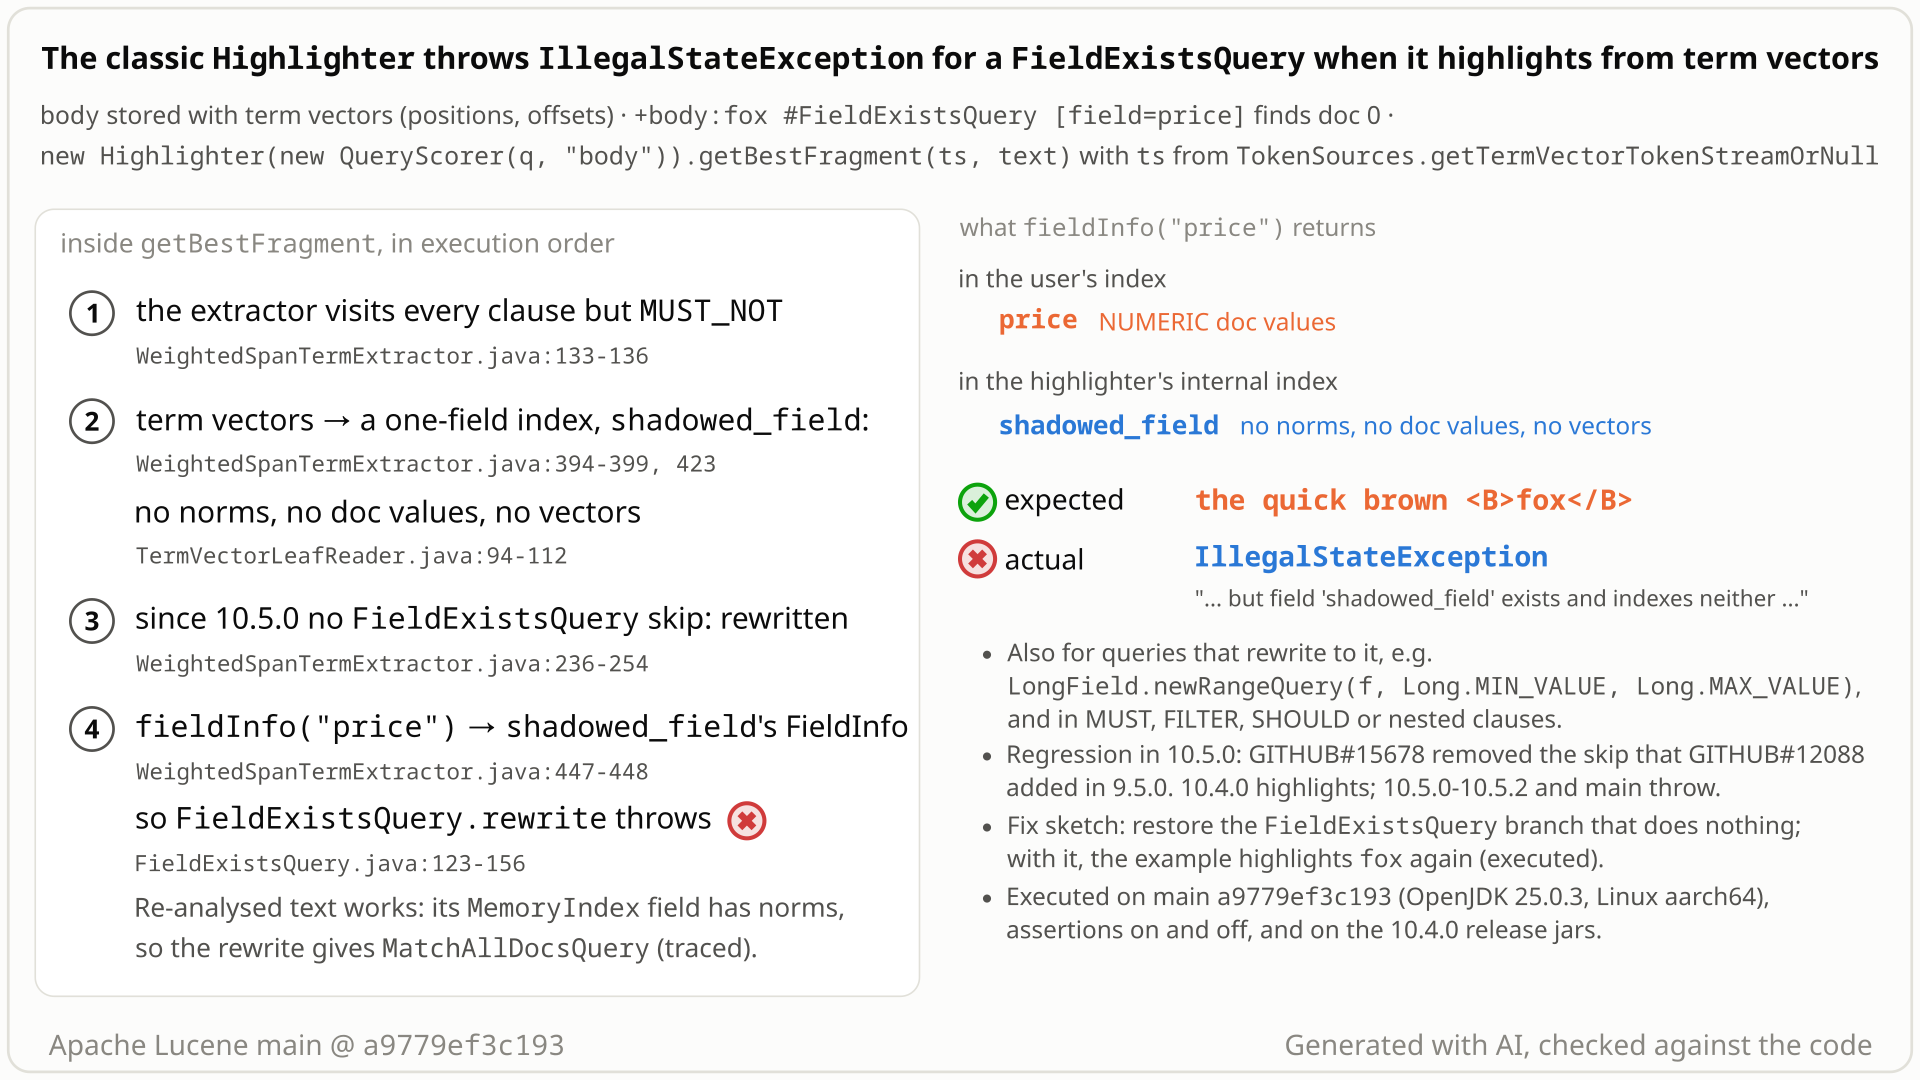
price with shadowed_field (no norms, no doc values), so getBestFragment throws instead of returning the highlight. Select the still to open it at full size. Generated with AI, checked against the code.- You index one document:
body= "the quick brown fox", stored with term vectors (positions and offsets), plus a doc-values fieldprice= 3. The query+body:fox #FieldExistsQuery(price)finds it: 1 hit. - You highlight the hit from its term vectors (
TokenSources.getTermVectorTokenStreamOrNull) withnew Highlighter(new QueryScorer(query, "body")). You expectthe quick brown <B>fox</B>, which 10.4.0 returns. - To find the words to mark, the highlighter rewrites each clause it has no special case for against a tiny one-field index built from the term vectors. Since 10.5.0 it no longer skips the exists clause, and that index describes every field,
priceincluded, as its own fieldshadowed_field: no norms, no doc values. - So
FieldExistsQueryrejects the field andgetBestFragmentthrowsIllegalStateException("... field 'shadowed_field' exists and indexes neither of these data structures"). Every hit fails, and so does the full-rangeLongField.newRangeQuery("size", Long.MIN_VALUE, Long.MAX_VALUE), which rewrites to the same query. - Re-analysing the text instead of reading term vectors still works: there the tiny index's field has norms, so the exists clause becomes match-all and is ignored.
Applications on 10.5.0 or later that highlight with the classic Highlighter and QueryScorer from term vectors with positions and offsets, when the highlighted query has an exists clause or a full-range numeric query on any field. Every hit fails. Search results, re-analysed text, offsets-only term vectors and the other highlighters are not affected.
Mechanism, terms and numbers584 words
The classic Highlighter with a QueryScorer finds the words to mark by rewriting the query's clauses against a tiny one-field index of the document being highlighted. When the token stream comes from term vectors with positions and offsets, that index is a TermVectorLeafReader, whose only field (shadowed_field) has no norms, doc values or vectors, and since #15678 (10.5.0) its getFieldInfos() returns that field for every name. #15678 also removed the FieldExistsQuery skip that #12088 (9.5.0) had added. So a FieldExistsQuery on any field, or a query that rewrites to one such as LongField.newRangeQuery(f, Long.MIN_VALUE, Long.MAX_VALUE), reaches FieldExistsQuery.rewrite, which throws IllegalStateException naming shadowed_field. The highlight call fails for every hit; 10.4.0 returns the quick brown <B>fox</B>. Search results, re-analysed text and offsets-only term vectors are not affected. Restoring the skip fixes it and passes all 732 tests of the highlighter module with the repro tests added.
- Classic Highlighter:
org.apache.lucene.search.highlight.Highlighterwith aQueryScorer. The scorer asksWeightedSpanTermExtractorwhich terms of the query occur in the token stream of the text. - Token stream from term vectors: instead of re-analysing the stored text,
TokenSourcescan rebuild the tokens from the document's term vectors (getTermVectorTokenStreamOrNull, orgetTokenStream(field, tvFields, text, analyzer, max), which prefers term vectors when they have offsets). This is the usual speed-up for this highlighter. - Internal reader: for queries it has no special case for (apart from spatial queries and multi-term queries it does not expand), the extractor calls
query.rewrite(...)on a one-document reader made from the token stream, then extracts terms from the result. With term vectors that have positions and offsets the reader is aTermVectorLeafReader; otherwise the text is indexed into aMemoryIndex. ADelegatingLeafReaderwraps it and answers every field name with its one field,shadowed_field. FieldExistsQuery: matches documents that have a value in a field, using norms, doc values or vectors. ItsrewritethrowsIllegalStateExceptionfor a field that exists but indexes none of them.
// WeightedSpanTermExtractor.extract
} else if (query instanceof MatchAllDocsQuery) {            // :236
  // nothing
                                                          // 9.5.0-10.4.0 had here:
                                                          //   } else if (query instanceof FieldExistsQuery) { // nothing
} else if (query instanceof FunctionScoreQuery) {           // :238
  ...
} else {
  final IndexReader reader = getLeafContext().reader();     // :247  the internal one-field reader
  rewritten = query.rewrite(new IndexSearcher(reader));     // :254  FieldExistsQuery.rewrite runs here

// getLeafContext(), :397-399: term vectors with positions AND offsets
internalReader = new TermVectorLeafReader(DelegatingLeafReader.FIELD_NAME, termVectorTerms);

// DelegatingLeafReader.getFieldInfos(), :442-451 (since #15678): every name gets the one FieldInfo
public FieldInfo fieldInfo(String fieldName) { return super.fieldInfo(DelegatingLeafReader.FIELD_NAME); }

// TermVectorLeafReader.java:93-112: omitNorms = true, DocValuesType.NONE, vector dimension 0
// FieldExistsQuery.java:156: no norms, no vectors, no doc values ->
throw new IllegalStateException(buildErrorMsg(fieldInfo));- A
BooleanQueryis walked clause by clause (prohibited clauses skipped), so MUST, FILTER and SHOULD clauses all reachextract. body:foxgives the termfox.FieldExistsQuery(price)has no branch since 10.5.0, so it is rewritten on the internal reader.- Asked for
price, the internal reader answers withshadowed_field, which on the term-vector path has no norms, doc values or vectors. The realpricehas numeric doc values. FieldExistsQuery.rewritethrows; the exception leavesHighlighter.getBestFragment.- On the
MemoryIndexpath the sameFieldInfohas norms,docCount1 equalsmaxDoc1, and the rewrite givesMatchAllDocsQuery, which the extractor ignores (traced).
The full-range LongField query gets there one step later: IndexSortSortedNumericDocValuesRangeQuery rewrites [Long.MIN_VALUE, Long.MAX_VALUE] to new FieldExistsQuery(field) (IndexSortSortedNumericDocValuesRangeQuery.java:131-133), which is extracted again (:259).
Exposure and likelihood425 words
- Who. Users of the classic
Highlighterwith aQueryScorerwho take token streams from term vectors with positions and offsets:TokenSources.getTermVectorTokenStreamOrNull, orTokenSources.getTokenStream(field, tvFields, text, analyzer, max)when the field has such vectors. Neither method is deprecated;TokenSourcesrecommends positions on the term vector, and the package javadoc presents term vectors as the faster way to highlight. - Trigger. Any clause of the highlighted query that is, or rewrites to, a
FieldExistsQuery, on any field: exists filters on doc-values, norms, vector, keyword or numeric fields and on the highlighted field itself; full-range numeric and unbounded sorted or sorted-set doc-values ranges, and the full-rangeLongFieldrange; anIndexOrDocValuesQuerywhose index side is an exists query (the extractor reads only that side); the same under ConstantScore, Boost, FunctionScore, DisjunctionMax or nested Boolean queries. MUST_NOT clauses are skipped by the extractor and do not trigger it. - Scale. The finder's matrix ran 7 document shapes x 3 text queries x about 130 query atoms x 5 occurrences (13,884 searchable queries) and highlighted every hit in 26 modes: 533,104 checks on main. 36 atoms throw this exception, all in the three
QueryScorerterm-vector modes and none in the UnifiedHighlighter or FastVectorHighlighter modes. (The matrix also records other, unrelated exceptions in some modes; they are not part of this report.) #16582 (10.6) makes ranges that cover every value of a field rewrite toFieldExistsQueryon the real index, but not on the highlighter's internal reader, which has no doc-values skipper: executed on main, such ranges still highlight from term vectors, and only the fullLong.MIN_VALUE..Long.MAX_VALUErange throws, as on 10.5.2. - Effect. One unchecked
IllegalStateExceptionper highlight call, so the request gets no highlights or an error. One document is enough, and no special settings are needed: it fails with the test framework's randomized directory and config (the repro) and with a plainIndexWriterConfig, the default codec and a plainIndexSearcher(the diagram probe); assertions on and off. Nothing is written and search results are correct. - Opt-in. Term vectors with positions and offsets are an index-time choice, and the classic Highlighter is the older highlighter (#16820, an open proposal, would deprecate it in 11.0; nothing is deprecated yet). No matching public report was found in the four months since 10.5.0.
- Workaround. Highlight with a query that has no exists or full-range clauses, or override the protected
QueryScorer.newTermExtractorto return aWeightedSpanTermExtractorwhose protectedisQueryUnsupportedalso returns true forFieldExistsQuery. Both givethe quick brown <B>fox</B>on main from a package outside Lucene, with assertions on and off.
A 3-test JUnit for lucene/highlighter on the public API (plus the test framework's LuceneTestCase and MockAnalyzer): one document, the test framework's randomized directory and config. Two tests fail on 10.5.0 and later with assertions on and off; the re-analysed control passes.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.highlight;

import org.apache.lucene.analysis.TokenStream;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.FieldType;
import org.apache.lucene.document.LongField;
import org.apache.lucene.document.NumericDocValuesField;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.Term;
import org.apache.lucene.search.BooleanClause.Occur;
import org.apache.lucene.search.BooleanQuery;
import org.apache.lucene.search.FieldExistsQuery;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.Query;
import org.apache.lucene.search.TermQuery;
import org.apache.lucene.search.TopDocs;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.analysis.MockAnalyzer;
import org.apache.lucene.tests.util.LuceneTestCase;

/**
 * Highlighting a hit of {@code +body:fox #FieldExistsQuery(price)} with the classic Highlighter
 * over the term-vector token stream of the hit throws IllegalStateException, while the same query
 * over a re-analysed token stream highlights "fox". GITHUB#12088 made the extractor skip
 * FieldExistsQuery ("Don't throw UOE when highlighting FieldExistsQuery").
 */
public class TestHighlightFieldExistsTermVectors extends LuceneTestCase {

  private static final String TEXT = "the quick brown fox";

  private static Query query() {
    return query(new FieldExistsQuery("price"));
  }

  private static Query query(Query filter) {
    return new BooleanQuery.Builder()
        .add(new TermQuery(new Term("body", "fox")), Occur.MUST)
        .add(filter, Occur.FILTER)
        .build();
  }

  private static Directory index() throws Exception {
    Directory dir = newDirectory();
    FieldType tv = new FieldType(TextField.TYPE_STORED);
    tv.setStoreTermVectors(true);
    tv.setStoreTermVectorPositions(true);
    tv.setStoreTermVectorOffsets(true);
    tv.freeze();
    try (IndexWriter w = new IndexWriter(dir, newIndexWriterConfig(new MockAnalyzer(random())))) {
      Document d = new Document();
      d.add(new Field("body", TEXT, tv));
      d.add(new NumericDocValuesField("price", 3));
      d.add(new LongField("size", 7, Field.Store.NO));
      w.addDocument(d);
    }
    return dir;
  }

  /** Fails on 10.5.0 and later: IllegalStateException from FieldExistsQuery.rewrite. */
  public void testTermVectorTokenStream() throws Exception {
    assertHighlightsFromTermVectors(query());
  }

  /**
   * Same failure for an open-ended range on a LongField (size:[* TO *]): it rewrites to
   * FieldExistsQuery before the extractor sees it.
   */
  public void testTermVectorTokenStreamOpenEndedLongRange() throws Exception {
    assertHighlightsFromTermVectors(
        query(LongField.newRangeQuery("size", Long.MIN_VALUE, Long.MAX_VALUE)));
  }

  private static void assertHighlightsFromTermVectors(Query q) throws Exception {
    try (Directory dir = index();
        DirectoryReader reader = DirectoryReader.open(dir)) {
      TopDocs td = new IndexSearcher(reader).search(q, 10);
      assertEquals(1, td.scoreDocs.length); // the document matches the query
      int doc = td.scoreDocs[0].doc;
      TokenStream ts =
          TokenSources.getTermVectorTokenStreamOrNull("body", reader.termVectors().get(doc), -1);
      assertNotNull(ts);
      Highlighter highlighter = new Highlighter(new QueryScorer(q, "body"));
      assertEquals("the quick brown <B>fox</B>", highlighter.getBestFragment(ts, TEXT));
    }
  }

  /** Control: the same query and document over a re-analysed token stream (passes). */
  public void testReanalysedTokenStream() throws Exception {
    Query q = query();
    TokenStream ts = new MockAnalyzer(random()).tokenStream("body", TEXT);
    Highlighter highlighter = new Highlighter(new QueryScorer(q, "body"));
    assertEquals("the quick brown <B>fox</B>", highlighter.getBestFragment(ts, TEXT));
  }
}
cp TestHighlightFieldExistsTermVectors.java $LUCENE/lucene/highlighter/src/test/org/apache/lucene/search/highlight/
cd $LUCENE
./gradlew :lucene:highlighter:test --tests org.apache.lucene.search.highlight.TestHighlightFieldExistsTermVectors -Ptests.seed=DEADBEEF
# assertions off (production-like): add -Ptests.asserts=false
- Expected
getBestFragmentreturnsthe quick brown <B>fox</B>, as on 10.4.0 and on main over re-analysed text.- Observed
IllegalStateException: FieldExistsQuery requires that the field indexes doc values, norms or vectors, but field 'shadowed_field' exists and indexes neither of these data structures; 2 of 3 tests fail.
More files, environment, full output2 more files (235 lines) · 1,344 words
TestHighlightFieldExistsTermVectors (package org.apache.lucene.search.highlight, public API only). One document: body stored with term vectors with positions and offsets, price as a NumericDocValuesField, size as a LongField. Each test first asserts that the query finds the document, then highlights it from its term vectors.
testTermVectorTokenStream:+body:fox #FieldExistsQuery(price); fails.testTermVectorTokenStreamOpenEndedLongRange: the full-rangeLongField.newRangeQuery("size", Long.MIN_VALUE, Long.MAX_VALUE)as the filter; fails (the method name says open-ended).testReanalysedTokenStream: the first query over re-analysed text; passes (control).
Two more tests are attached: the independent reproducer's (exists on a doc-values field, exists on the highlighted field, the full-range LongField range, two controls; 3 of 5 fail) and a variant test (exists on the highlighted field as a MUST clause, QueryScorer without a field, TokenSources.getTokenStream, offsets-only control; 1 of 2 fails). All three pass with the recommended fix.
In its own package verify.v1; it also runs in org.apache.lucene.search.highlight after changing only the package line. 3 of 5 fail on main; both controls pass.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package verify.v1;

import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.TokenStream;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.FieldType;
import org.apache.lucene.document.LongField;
import org.apache.lucene.document.NumericDocValuesField;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.Fields;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.Term;
import org.apache.lucene.search.BooleanClause;
import org.apache.lucene.search.BooleanQuery;
import org.apache.lucene.search.FieldExistsQuery;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.Query;
import org.apache.lucene.search.TermQuery;
import org.apache.lucene.search.highlight.Highlighter;
import org.apache.lucene.search.highlight.QueryScorer;
import org.apache.lucene.search.highlight.TokenSources;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.analysis.MockAnalyzer;
import org.apache.lucene.tests.analysis.MockTokenizer;
import org.apache.lucene.tests.util.LuceneTestCase;

/**
 * Independent check (public API only, own package): the classic Highlighter, fed a token stream
 * built from term vectors with positions and offsets, should highlight the matching term of a
 * query that also contains a FieldExistsQuery (or a query that rewrites to one), as it does for a
 * re-analysed token stream.
 */
public class TestFieldExistsTermVectorHighlight extends LuceneTestCase {

  private static final String TEXT = "the quick brown fox";
  private static final String EXPECTED = "the quick brown <B>fox</B>";

  private Directory dir;
  private DirectoryReader reader;
  private Analyzer analyzer;
  private int docId;

  @Override
  public void setUp() throws Exception {
    super.setUp();
    analyzer = new MockAnalyzer(random(), MockTokenizer.WHITESPACE, true);
    dir = newDirectory();
    FieldType tvType = new FieldType(TextField.TYPE_STORED);
    tvType.setStoreTermVectors(true);
    tvType.setStoreTermVectorPositions(true);
    tvType.setStoreTermVectorOffsets(true);
    tvType.freeze();
    try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig(analyzer))) {
      Document doc = new Document();
      doc.add(new Field("body", TEXT, tvType));
      doc.add(new NumericDocValuesField("dv", 7L));
      doc.add(new LongField("num", 42L, Field.Store.NO));
      w.addDocument(doc);
    }
    reader = DirectoryReader.open(dir);
    docId = new IndexSearcher(reader).search(new TermQuery(new Term("body", "fox")), 1).scoreDocs[0]
        .doc;
  }

  @Override
  public void tearDown() throws Exception {
    reader.close();
    dir.close();
    analyzer.close();
    super.tearDown();
  }

  private static Query foxAnd(Query filter) {
    return new BooleanQuery.Builder()
        .add(new TermQuery(new Term("body", "fox")), BooleanClause.Occur.MUST)
        .add(filter, BooleanClause.Occur.FILTER)
        .build();
  }

  private TokenStream termVectorStream() throws Exception {
    Fields tv = reader.termVectors().get(docId);
    TokenStream ts = TokenSources.getTermVectorTokenStreamOrNull("body", tv, -1);
    assertNotNull("term vectors with offsets expected", ts);
    return ts;
  }

  private void assertHighlights(Query query, TokenStream ts) throws Exception {
    // precondition: the document matches the query on the real index
    assertEquals(1, new IndexSearcher(reader).count(query));
    Highlighter highlighter = new Highlighter(new QueryScorer(query, "body"));
    String fragment;
    try {
      fragment = highlighter.getBestFragment(ts, TEXT);
    } catch (RuntimeException e) {
      throw new AssertionError("highlighting threw for query " + query + ": " + e, e);
    }
    assertEquals(EXPECTED, fragment);
  }

  /** Bug claim: FieldExistsQuery on a doc-values field, term-vector token stream. */
  public void testTermVectorStreamFieldExistsOnDocValuesField() throws Exception {
    assertHighlights(foxAnd(new FieldExistsQuery("dv")), termVectorStream());
  }

  /** Bug claim: FieldExistsQuery on the highlighted field itself (it has norms). */
  public void testTermVectorStreamFieldExistsOnHighlightedField() throws Exception {
    assertHighlights(foxAnd(new FieldExistsQuery("body")), termVectorStream());
  }

  /** Bug claim: an open-ended long range, which rewrites to a FieldExistsQuery. */
  public void testTermVectorStreamOpenEndedLongRange() throws Exception {
    assertHighlights(
        foxAnd(LongField.newRangeQuery("num", Long.MIN_VALUE, Long.MAX_VALUE)),
        termVectorStream());
  }

  /** Control: same FieldExistsQuery query, re-analysed token stream. */
  public void testControlReanalysedStreamFieldExists() throws Exception {
    assertHighlights(
        foxAnd(new FieldExistsQuery("dv")), analyzer.tokenStream("body", TEXT));
  }

  /** Control: term-vector token stream, query without FieldExistsQuery. */
  public void testControlTermVectorStreamPlainTerm() throws Exception {
    assertHighlights(new TermQuery(new Term("body", "fox")), termVectorStream());
  }
}
D=$LUCENE/lucene/highlighter/src/test/org/apache/lucene/search/highlight
sed 's/^package verify\.v1;/package org.apache.lucene.search.highlight;/' TestFieldExistsTermVectorHighlight.java > $D/TestFieldExistsTermVectorHighlight.java
cd $LUCENE
./gradlew :lucene:highlighter:test --tests org.apache.lucene.search.highlight.TestFieldExistsTermVectorHighlight -Ptests.seed=DEADBEEF
Exists on the highlighted field as a MUST clause through TokenSources.getTokenStream; 1 of 2 fails, the offsets-only control passes.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.highlight;

import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.TokenStream;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.FieldType;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.Fields;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.Term;
import org.apache.lucene.search.BooleanClause.Occur;
import org.apache.lucene.search.BooleanQuery;
import org.apache.lucene.search.FieldExistsQuery;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.Query;
import org.apache.lucene.search.TermQuery;
import org.apache.lucene.search.TopDocs;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.analysis.MockAnalyzer;
import org.apache.lucene.tests.util.LuceneTestCase;

/**
 * Variants: the FieldExistsQuery targets the highlighted field itself (which indexes norms), the
 * clause is MUST, the token stream comes from the non-deprecated TokenSources.getTokenStream
 * convenience (term vectors first, analysis as fallback), and QueryScorer has no field restriction.
 */
public class TestFieldExistsTermVectorVariants extends LuceneTestCase {

  private static final String TEXT = "the quick brown fox";

  private static String highlight(boolean positions) throws Exception {
    Analyzer analyzer = new MockAnalyzer(random());
    try (Directory dir = newDirectory()) {
      FieldType tv = new FieldType(TextField.TYPE_STORED);
      tv.setStoreTermVectors(true);
      tv.setStoreTermVectorPositions(positions);
      tv.setStoreTermVectorOffsets(true);
      tv.freeze();
      try (IndexWriter w = new IndexWriter(dir, newIndexWriterConfig(analyzer))) {
        Document d = new Document();
        d.add(new Field("body", TEXT, tv));
        w.addDocument(d);
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        Query q =
            new BooleanQuery.Builder()
                .add(new TermQuery(new Term("body", "fox")), Occur.MUST)
                .add(new FieldExistsQuery("body"), Occur.MUST)
                .build();
        TopDocs td = new IndexSearcher(reader).search(q, 10);
        assertEquals(1, td.scoreDocs.length);
        int doc = td.scoreDocs[0].doc;
        Fields tvFields = reader.termVectors().get(doc);
        String text = reader.storedFields().document(doc).get("body");
        TokenStream ts = TokenSources.getTokenStream("body", tvFields, text, analyzer, -1);
        Highlighter highlighter = new Highlighter(new QueryScorer(q));
        return highlighter.getBestFragment(ts, text);
      }
    }
  }

  /** Term vectors with positions and offsets: the TermVectorLeafReader path. */
  public void testTermVectorsWithPositionsAndOffsets() throws Exception {
    assertEquals("the quick brown <B>fox</B>", highlight(true));
  }

  /** Control: offsets without positions, so the extractor re-indexes into a MemoryIndex. */
  public void testTermVectorsWithOffsetsOnly() throws Exception {
    assertEquals("the quick brown <B>fox</B>", highlight(false));
  }
}
cp TestFieldExistsTermVectorVariants.java $LUCENE/lucene/highlighter/src/test/org/apache/lucene/search/highlight/
cd $LUCENE
./gradlew :lucene:highlighter:test --tests org.apache.lucene.search.highlight.TestFieldExistsTermVectorVariants -Ptests.seed=DEADBEEF
| lucene | main a9779ef3c193 (11.0.0-SNAPSHOT), 10.5.0, 10.5.1, 10.5.2 and branch_10_6 4ae946e5a9b (10.6.0-SNAPSHOT jars built from that checkout): fail; 9.12.3, 10.3.2, 10.4.0: pass (9.5.0: the 9.x-API port of the test passes) |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
cp TestHighlightFieldExistsTermVectors.java $LUCENE/lucene/highlighter/src/test/org/apache/lucene/search/highlight/
cd $LUCENE
./gradlew :lucene:highlighter:test --tests org.apache.lucene.search.highlight.TestHighlightFieldExistsTermVectors -Ptests.seed=DEADBEEF
# assertions off (production-like): add -Ptests.asserts=false
# gradle, main a9779ef3c193, assertions on, seed DEADBEEF (the same 2 of 3 with -Ptests.asserts=false); abridged and reordered: gradle prints the range failure first, with module prefixes, SeedInfo and test frames
TestHighlightFieldExistsTermVectors > testTermVectorTokenStream FAILED
    java.lang.IllegalStateException: FieldExistsQuery requires that the field indexes doc values, norms or vectors, but field 'shadowed_field' exists and indexes neither of these data structures
        at org.apache.lucene.search.FieldExistsQuery.rewrite(FieldExistsQuery.java:156)
        at org.apache.lucene.search.highlight.WeightedSpanTermExtractor.extract(WeightedSpanTermExtractor.java:254)
        at org.apache.lucene.search.highlight.WeightedSpanTermExtractor.extract(WeightedSpanTermExtractor.java:136)
        at org.apache.lucene.search.highlight.WeightedSpanTermExtractor.getWeightedSpanTerms(WeightedSpanTermExtractor.java:520)
        at org.apache.lucene.search.highlight.QueryScorer.initExtractor(QueryScorer.java:209)
        at org.apache.lucene.search.highlight.QueryScorer.init(QueryScorer.java:178)
        at org.apache.lucene.search.highlight.Highlighter.getBestTextFragments(Highlighter.java:175)
        at org.apache.lucene.search.highlight.Highlighter.getBestFragments(Highlighter.java:140)
        at org.apache.lucene.search.highlight.Highlighter.getBestFragment(Highlighter.java:98)

TestHighlightFieldExistsTermVectors > testTermVectorTokenStreamOpenEndedLongRange FAILED
    java.lang.IllegalStateException: (same message)
        at org.apache.lucene.search.FieldExistsQuery.rewrite(FieldExistsQuery.java:156)
        at org.apache.lucene.search.highlight.WeightedSpanTermExtractor.extract(WeightedSpanTermExtractor.java:254)
        at org.apache.lucene.search.highlight.WeightedSpanTermExtractor.extract(WeightedSpanTermExtractor.java:259)
        at org.apache.lucene.search.highlight.WeightedSpanTermExtractor.extract(WeightedSpanTermExtractor.java:136)
        ...

testReanalysedTokenStream: passed   (from the gradle test results)

# with the attached two tests: 10 tests, 6 failed (assertions on and off); every control passes
# 10.5.0 / 10.5.2: the same exception at FieldExistsQuery.java:155 <- WeightedSpanTermExtractor.java:255- #12088 (9.5.0) made the highlighter skip
FieldExistsQueryto "avoid throwing an exception"; #15678 promises such rewrites "will not throw exceptions during highlighting". - #15678 removed the skip, apparently expecting a clean rewrite; that holds only on the
MemoryIndexpath its tests use. - The real
pricehas doc values; the error names an internal field, and 10.4.0 highlights the same hit.
The full argument309 words
- #12088 (9.5.0), commit
fc7b937affe"Don't throw UOE when highlighting FieldExistsQuery": "This commit makes WeightedSpanTermExtractor aware of FieldExistsQuery, so that it can just ignore it and avoid throwing an exception." Its testTestHighlighter.testFieldExistsQuerystill exists. - #15678 (10.5.0), commit
a8b3d1a9481d: "This commit adds a more useful implementation, meaning that queries calling getFieldInfos() during rewrite will not throw exceptions during highlighting." Its PR body: the newFieldInfos"ensures that any current or future query types that rely on index schema metadata during rewrite can be handled gracefully by the highlighter". The issue it fixed, #15668, asked to end the "whack-a-mole" of query optimizations that break the highlighter. - Why the removal slipped through (our reading; the thread does not discuss term vectors). On #15678 the reviewer asked "maybe let's remove the special-casing for FieldExistsQuery as well?" and the author did. #15678's two tests and
testFieldExistsQuerytake theMemoryIndexpath, where the internal field has norms:testSortedNumericDocValuesRangeQueryandtestFieldExistsQueryuse aCannedTokenStream, andTestHighlightCustomQuery.testHighlightQueryRequiringMetadatare-analyses the text with aMockAnalyzer. No upstream test highlights aFieldExistsQueryfrom term vectors. - Correct usage. Public, non-deprecated APIs only; the document matches the query on the real index; the error names
shadowed_field, a field the user never created; it fires even for an exists clause on the highlighted field, which has norms. - The class javadoc leaves queries it does not support to subclasses: they may override
extractandextractUnknownQuery"to support additional, by default unsupported queries", and the defaultextractUnknownQuery, reached when a rewrite returns the query unchanged, does nothing. It does not promise that a rewrite cannot throw, so it is weaker support than the two commit messages. - Stability markers, both ways.
Highlighter,QueryScorer,WeightedSpanTermExtractorand the twoTokenSourcesmethods are public and not deprecated;TermVectorLeafReaderand theFieldInfoconstructor are@lucene.experimental, andTokenStreamFromTermVectoris@lucene.internal.
The devil's-advocate check154 words
Strongest case (a reviewer from another model family, OpenAI GPT-5.6, and an intended-behaviour checker): the classic Highlighter is a lexical term extractor that never promised to handle every query; FieldExistsQuery has no terms to highlight, and its exception is a deliberate fail-fast for a field without norms, doc values or vectors; the term-vector reader is a deliberately partial @lucene.experimental view; #15678 removed the special case on purpose; the #12088 CHANGES line names only UnsupportedOperationException; and #16820 proposes deprecating the classic Highlighter.
Why it fails: the fail-fast fires on the highlighter's own description of the schema, not on the caller's field (the real price has doc values); both commit messages state a no-exception intent for exactly this kind of rewrite; the removal was justified only for the path its tests covered; 10.4.0 behaves differently with the same code and query; and a proposed deprecation is not a decision. Both reviewers rated the argument weak.
Recommended A. Restore the FieldExistsQuery skip in WeightedSpanTermExtractor.extract (recommended)
Restore the skip that 10.5.0 removed: else if (query instanceof FieldExistsQuery) { // nothing } in WeightedSpanTermExtractor.extract (+4 lines with the import and a comment). The repro tests and all 722 other highlighter-module tests pass, with assertions on and off; it restores 10.4.0's handling of FieldExistsQuery.
+import org.apache.lucene.search.FieldExistsQuery;
 ...
     } else if (query instanceof MatchAllDocsQuery) {
       // nothing
+    } else if (query instanceof FieldExistsQuery) {
+      // nothing: it has no terms to highlight, and its rewrite reads FieldInfos that the internal
+      // reader cannot report faithfully (term vectors have no norms or doc values)
     } else if (query instanceof FunctionScoreQuery) {
All options and trade-offs5 options · 638 words
Fix A was built and run in a scratch worktree at a9779ef3c193 with the whole :lucene:highlighter:test task and the format and lint tasks; fix B with the same tests (assertions on). Fix C was run by the independent reproducer; the PR #16816 change was run as a shadow class; the workarounds were run on main from a package outside Lucene.
A. Restore the FieldExistsQuery skip in WeightedSpanTermExtractor.extract (recommended) (validated by the checks)
Put back the branch #12088 added and #15678 removed, right after the MatchAllDocsQuery branch.
+import org.apache.lucene.search.FieldExistsQuery;
 ...
     } else if (query instanceof MatchAllDocsQuery) {
       // nothing
+    } else if (query instanceof FieldExistsQuery) {
+      // nothing: it has no terms to highlight, and its rewrite reads FieldInfos that the internal
+      // reader cannot report faithfully (term vectors have no norms or doc values)
     } else if (query instanceof FunctionScoreQuery) {
Trade-offs
- Restores 10.4.0's handling of
FieldExistsQuery(main keeps #15678's workinggetFieldInfos()); oneinstanceofcheck per extracted query (not benchmarked). - Narrow: other rewrites can still read the misleading
FieldInfo. In the matrix it fixes 32 of the 36 throwing atoms; the other 4 are kNN queries with a filter or seed whose own rewrite runs a search on the internal reader, a related problem with a different fix that is better filed and cross-linked separately.
What the checks validated
- Gradle on
a9779ef3c193, seed DEADBEEF: the 3 + 5 + 2 repro tests pass, and:lucene:highlighter:testpasses with assertions on and off: 37 classes, 732 tests, 0 failures (722 upstream tests, e.g.TestHighlighter59,TestTokenSources8,TestUnifiedHighlighterTermVec6). checkGoogleJavaFormat,forbiddenApisMainandecjLintMainpass.- Earlier, with the standalone runner: the finder's, the independent reproducer's and the second reviewer's tests pass, and 81 upstream classic-highlighter tests.
Pass omitNorms = false in TermVectorLeafReader's FieldInfo; FieldExistsQuery.rewrite then takes its norms branch and no longer throws.
Trade-offs
- The reader then claims norms while
getNormValuesstill returnsnull. TermVectorLeafReaderis a public@lucene.experimentalclass, also used by the UnifiedHighlighter's term-vector strategy.- The exists clause is still evaluated on the shadowed field, not the named one.
What the checks validated
- Gradle on
a9779ef3c193, assertions on: all 732 tests pass. Not run with assertions off.
DelegatingLeafReader.getFieldInfos().fieldInfo(name) returns null for fields other than the highlighted one (the fix sketch of the related search-executing-rewrite report).
Trade-offs
Leaves FieldExistsQuery on the highlighted field itself failing: run by the independent reproducer on main, 1 of 5 still fails. Useful only together with A.
#16816 ("Rewrite special case AutomatonQueries", open; labelled Stale by the stale bot on 2026-10-28, last human activity 2026-10-13, merge conflicts) makes FieldExistsQuery.rewrite accept fields that index only terms.
Trade-offs
With its FieldExistsQuery.java as a shadow class the repro passes 3 of 3, so merging it would hide this bug on main by accident; 10.5.x and 10.6.x stay affected.
Until a fix ships: highlight with a query that has no exists or full-range clauses, or override the protected QueryScorer.newTermExtractor to return a WeightedSpanTermExtractor whose protected isQueryUnsupported also returns true for FieldExistsQuery.
new QueryScorer(query, "body") {
  @Override
  protected WeightedSpanTermExtractor newTermExtractor(String defaultField) {
    return new WeightedSpanTermExtractor(defaultField) {
      @Override
      protected boolean isQueryUnsupported(Class<? extends Query> clazz) {
        return clazz == FieldExistsQuery.class || super.isQueryUnsupported(clazz);
      }
    };
  }
}
Trade-offs
Application code only; it does not fix Lucene, and every application on the term-vector path needs it.
What the checks validated
- Main
a9779ef3c193, a test in a package outside Lucene, assertions on and off: both workarounds givethe quick brown <B>fox</B>for the exists filter (and the extractor override for the full-rangeLongFieldfilter); a stockQueryScorerthrows in the same test. 4 of 4 pass.
By code reading only, Solr's original highlighter gets term-vector token streams through the same TokenSources method; Solr is still on Lucene 10.4.0, so it is not affected yet.
Code reading, not a formal method: reading #15678's internal-reader change, a planning step wrote a small probe (term-vector highlighting plus an exists filter) that threw on main, and bisected it to 10.5.0. A hunt reduced it to a public-API JUnit and widened it with a 533,104-check matrix of query types and highlighter modes.
The method in full180 words
- First signal (non-formal). The hunt's planning analysis read the
DelegatingLeafReaderremap that #15678 added, prompted by downstream reports of its predecessorUnsupportedOperationException, and wrote a small probe: a term-vector field plus aFieldExistsQueryfilter. It threw on main and was bisected to 10.5.0 by release. - Reduction. A hunt unit on the classic and fast-vector highlighters turned it into the public-API JUnit of the repro and ran it on main and the release jars.
- Widening (bounded-exhaustive checking of the stock jars). A trigger model enumerated 11 token-stream cells (term-vector flag combinations, non-empty and empty text, the analysis path with and without caching and payloads) and checked "highlighting throws iff the internal reader is a TermVectorLeafReader" within them (holds, 0 violations). A matrix ran 7 document shapes x 3 text queries x about 130 query atoms x 5 occurrences and highlighted every hit in 26 modes: 533,104 checks on main (455,052, with a smaller atom set, on 10.5.2 and 10.4.0), grouped by throwing frame: 36 atoms throw this exception on main, only in the classic Highlighter's term-vector modes; 10.4.0 has none.
No report of this exact regression found (220 logged queries over GitHub, the Lucene and Solr lists, JIRA and the web, 2026-10-28). Nearest: #15678 (introduced it), #15668 and #12088 (the older exception), #7450 (the internal reader's missing getFieldInfos, open since 2015) and open PR #16816.
Searches5 searches
Novelty: known, by partial overlap with #7450 (LUCENE-6390). Every related report is about the older UnsupportedOperationException, which #15678 fixed; this regression is a side effect of that fix. #7450 (LUCENE-6390) is the long-open umbrella for the incomplete internal reader; it predates FieldExistsQuery and does not describe this exception, but someone else wrote there that "none of the query stack can use FieldInfos without breaking highlighting". The follow-up, the adjudication and the audit rated the bug new; the independent reproducer and the intended-behaviour checker left #7450 to the novelty decision; the cross-model fact check of this doc argues "known" under the hunt rule that partial overlap counts as known.
| Where | When | How | Found |
|---|---|---|---|
| GitHub apache/lucene issues, PRs and commits | 2026-10-28 | two scripted prior-report searches (class and method names; symptoms, the error text, the query types that rewrite to FieldExistsQuery) and 18 own searches, including shadowed_field | no report; nearest #15678, #15668, #12088, #7450 |
| Open and recent PRs | 2026-10-28 | the changed files of all 411 open apache/lucene PRs and the 15 closed since 2026-10-23; re-checked for PRs created since 2026-10-26 | #16816 is the only open PR touching FieldExistsQuery.rewrite (would mask the bug on main); none restores the skip |
| Downstream (apache/solr, Elasticsearch, OpenSearch) | 2026-10-28 | 12 own GitHub searches and the scripted prior-report search downstream legs; 3 searches across all of GitHub | only the older UnsupportedOperationException family (elastic/elasticsearch#92919, #99700, opensearch-project/OpenSearch#20496) |
| Mailing lists and JIRA | 2026-10-28 | 48 searches over Lucene dev@, java-user@, issues@ and Solr lists; 9 JIRA queries | only the #15668/#15678 notification mails; SOLR-18175 has the same message at query time, without highlighting |
| Web | 2026-10-28 | 7 searches | only the older exception |
Introduced by #15678 (a8b3d1a9481d on main, backport 7ddd1898b389, 2026-02-09), which removed the skip #12088 added in 9.5.0. First affected 10.5.0, last clean 10.4.0; a one-file bisect confirms it both ways. Not fixed upstream.
Versions tested7 rows
Introduced by #15678 "Fix Highlighter crash by implementing getFieldInfos in DelegatingLeafReader" (author sjs004, merged by romseygeek; fixes #15668): main a8b3d1a9481d, branch_10x 7ddd1898b389, author date 2026-02-09. It removed the FieldExistsQuery branch and made getFieldInfos() answer every name with the shadowed FieldInfo.
Older ingredients, harmless before: the norms-free FieldInfo of TermVectorLeafReader (LUCENE-6034, 5.0.0) and the exception branch of FieldExistsQuery.rewrite (LUCENE-10436, 9.2.0).
Not fixed upstream: main 20ced71c1e6e and branch_10_6 4ae946e5a9b9 still lack the skip (2026-10-28).
9.1.0 and older have no FieldExistsQuery (the 9.x test does not compile on 9.1.0; older releases read).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | 2 of 3 fail (gradle and runner, assertions on and off) |
branch_10_6 4ae946e5a9b (10.6.0, released 2026-10-29; 10.6.0-SNAPSHOT jars) | affected | 2 of 3 fail (jars built from a checkout of that commit) |
| 10.5.0, 10.5.1, 10.5.2 | affected | 2 of 3 fail |
| 10.4.0 + the #15678 file | bisect | 2 of 3 fail |
| 10.5.0 with the pre-#15678 file | bisect | 3 of 3 pass |
| 9.5.0, 9.12.3, 10.3.2, 10.4.0 | not affected | 3 of 3 pass (9.5.0: the same test on the 9.x API, 2 of 2); the releases in between read |
| 9.2.0, 9.4.2 | older bug | UnsupportedOperationException on every path, control included (fixed by #12088 in 9.5.0) |
The finder, an independent reproducer, reviews by OpenAI GPT-5.6 and an intended-behaviour checker each ran their own tests: all said real. An adjudication re-ran with a new seed and confirmed; a later audit kept it; this doc's gradle runs reproduced it and validated the fix; three checks of the doc itself found wording errors, all resolved.
Checks and verdicts496 words
Every check executed code on main, except the cross-model fact check of the doc, which read files only. The doc's fact checks found no error in the bug, its mechanism or its versions; their findings are resolved.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | JUnit 2 of 3 fail on main (-ea, -da), 10.5.0-10.5.2 and the branch_10_6 snapshot; pass on 10.4.0, 10.3.2, 9.12.3 and with the skip restored; trigger model and matrix. |
| refute review (OpenAI GPT-5.6) | real, high | Own JUnit fails on main with -ea and -da over 3 seeds; control passes; 10.4.0 passes, 10.5.2 fails; the fix passes. Intended argument weak. |
| independent reproducer | real | Own 5-test JUnit: 3 of 5 fail on main (-ea, -da; 15 of 25 over 5 iterations), 10.5.2 and 10.5.0; 0 of 5 on 10.4.0, 9.12.3 and with the fix. Found the highlighted-field case. |
| works-as-designed review (OpenAI GPT-5.6) | real, high | Built the strongest 'lexical extractor' case and rated it weak; own JUnit fails 1 of 2 on main and passes with the fix. |
| intended-behaviour checker | real, high | The CHANGES line, the deliberate removal, the fail-fast and the deprecation proposal all fail as defences; own variant fails on main and 10.5.2, passes on 10.4.0. |
| adjudication | confirmed, high | Re-ran the reproducer's JUnit with seed 1A2B3C4D: 3 of 5 fail with -ea and -da; both controls pass. Not a duplicate. |
| credibility audit | keep | Re-ran the finder's JUnit (2 of 3 fail), re-read the chain and the history. Its note that #16816 is active was wrong: the 2026-10-28 update is the stale bot (corrected by the fact check). |
| doc step (gradle) | reproduced; fix validated | Stock main: 6 of 10 repro tests fail with -ea and -da. Fix A: 732 of 732 module tests pass with -ea and -da, lint clean. Fix B: 732 pass with -ea. |
| Fact check of this doc (independent) | reproduced; 4 text errors, fixed | Ran section 7's gradle command verbatim (2 of 3 fail, assertions on and off), the two attached tests (4 of 7 fail), fix A on the whole module (732 pass), the harness on main, 10.3.2, 10.4.0 and 10.5.0-10.5.2, a public-API check and its own 12-test probe. Errors: #16816 is stale, not live; #16582 adds no trigger on the internal reader (executed); the matrix product; the source of #15678's test streams. All fixed. |
| Fact check of this doc (OpenAI GPT-5.6, read-only) | core finding holds; wording corrected | A reading-only review: 9 errors (1 high, 6 medium, 2 low), 8 overclaims and 4 missing caveats, none against the bug itself; intended-behaviour case moderate, but still a regression. Its high item, novelty "known" by partial overlap with #7450, is left to the registry; the rest were fixed or answered. |
| Diagram check | Every value, line number, stack frame and code excerpt matched; it ran its own probe showing that body:fox gives the weighted term fox from the query, not from a lookup in the internal index. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 478 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,328 words
- Registry title
- Classic Highlighter throws IllegalStateException for any query that contains a FieldExistsQuery (or a query that rewrites to one, such as an open-ended LongField range) when the token stream comes from term vectors with positions and offsets (regression in 10.5.0 from GITHUB#15678)
- Area
- highlighter / classic Highlighter (QueryScorer, WeightedSpanTermExtractor term-vector path)
- Priority
- Medium, rank 225: A released 10.5.0 regression where the classic Highlighter throws on every hit when term vectors are the source and the query contains an ordinary FieldExistsQuery or an open-ended range; the failure is loud and limited to the legacy term-vector path.
- Impact class
- crash
- Impact note
- Applications that highlight with the classic Highlighter and a QueryScorer from term vectors stored with positions and offsets (TokenSources.getTermVectorTokenStreamOrNull, or TokenSources.getTokenStream when the field has such vectors) get an IllegalStateException instead of highlights for every hit on 10.5.0-10.5.2, branch_10_6 (10.6.0) and main whenever the highlighted query contains a FieldExistsQuery on any field (in a MUST, FILTER, SHOULD or nested clause; MUST_NOT clauses are skipped) or a query that rewrites to one (LongField.newRangeQuery(f, Long.MIN_VALUE, Long.MAX_VALUE), full-range or open-ended doc-values slow ranges, IndexOrDocValuesQuery with a FieldExistsQuery side, and FieldExistsQuery under ConstantScore, Boost, FunctionScore or DisjunctionMax); default IndexWriterConfig, codec and searcher, -ea and -da, one document suffices; re-analysed token streams and offsets-only term vectors are not affected, search results are correct, and nothing is written to the index.
- Summary
- You store a text field with term vectors (positions and offsets), search with a query such as +body:fox plus a FieldExistsQuery filter on another field, and highlight the hit with the classic Highlighter from its term vectors; you expect 'the quick brown <B>fox</B>', which 10.4.0 and earlier return. Since 10.5.0 the call throws IllegalStateException 'FieldExistsQuery requires that the field indexes doc values, norms or vectors, but field 'shadowed_field' exists and indexes neither of these data structures', naming an internal field the user never created. The highlighter rewrites the query against its own one-field reader built from the term vectors, whose field info has no norms or doc values, and since GITHUB#15678 it no longer skips FieldExistsQuery as GITHUB#12088 had made it do.
- Introduced
- a8b3d1a9481d97c74c2fc06b15d5983288078e3b on main and 7ddd1898b3891c6cc8cf1a2edc513ab1ae3bfbac on branch_10x (GITHUB#15678 'Fix Highlighter crash by implementing getFieldInfos in DelegatingLeafReader', author Simranjeet Singh (GitHub sjs004), merged by romseygeek, fixing #15668): it made DelegatingLeafReader.getFieldInfos answer every field name with the shadowed field's FieldInfo and, on a reviewer's suggestion ('maybe let's remove the special-casing for FieldExistsQuery as well?'), removed the 'query instanceof FieldExistsQuery -> nothing' branch that GITHUB#12088 (fc7b937affe, 9.5.0) had added [exec: shadowing only the #15678 version of WeightedSpanTermExtractor.java onto 10.4.0 makes the repro fail 2 of 3; shadowing the pre-#15678 version onto 10.5.0 makes it pass 3 of 3]. Older ingredients, harmless before: TermVectorLeafReader's FieldInfo without norms, doc values or vectors (LUCENE-6034, 978aac31848, 5.0.0) and FieldExistsQuery.rewrite's IllegalStateException branch (LUCENE-10436, 91e29405d8e, 9.2.0) [read] (2026-02-09 (author date 2026-02-09T16:57:13Z on both commits; committed to main at 16:57:13Z and to branch_10x at 17:10:50Z))
- First affected version
- 10.5.0 [exec] (tagged 2026-06-25, the first release containing 7ddd1898b38; its CHANGES lists GITHUB#15668 under Bug Fixes); last unaffected 10.4.0 [exec] (cut from branch_10_4, which lacks the backport); the 9.x line never received #15678 (9.12.3 passes [exec])
- Affected versions
- 10.5.0, 10.5.1 and 10.5.2 [exec: the finder's JUnit fails 2 of 3, the control passes]; branch_10_6 head 4ae946e5a9b (10.6.0-SNAPSHOT jars, SHA-1-checked) [exec: fails 2 of 3], so the released 10.6.0 has it too; main a9779ef3c193 [exec, -ea and -da]; main 645d4fe14a2 [exec 2026-10-29, -ea and -da: 2 of 3 fail]; branch_10x 657014b3c579 and branch_10_5 e85bb7b2c86d [read: skip absent, getFieldInfos unchanged]. Not affected: 9.5.0-10.4.0 [exec on 9.5.0, 9.12.3, 10.3.2 and 10.4.0; read for the rest]. 9.2.0-9.4.2 fail differently, with the older UnsupportedOperationException on every token-stream path, the re-analysed control included (the GITHUB#12088 bug, fixed in 9.5.0) [exec on 9.2.0 and 9.4.2]; 9.1.0 and older have no FieldExistsQuery [exec: compile error]. Not fixed upstream.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading; also reached by exhaustive check
- Upstream and prior reports
- #7450 (LUCENE-6390, open since 2015; related design issue covering this failure class). Earlier: none found (2026-10-28, the prior-report record, verdict new: 220 logged queries and reads: two scripted prior-report searches over apache/lucene issues, PRs and commits, Solr, Elasticsearch and OpenSearch, the dev@, java-user@, issues@ and commits@ lists and the JIRA archive; 33 manual GitHub searches; 48 list searches; 9 JIRA queries; 7 web searches; the changed files of all 411 open apache/lucene PRs and of the 15 PRs closed since 2026-10-23; 18 items read in full; plus the finder's, the independent reproduction's, the intended-behaviour check's and the adjudication's searches). Re-checked 2026-10-28: no PR created since 2026-10-26 (#16907-#16926) touches lucene/highlighter or FieldExistsQuery; the newest commit on WeightedSpanTermExtractor.java is dbf0d1426f13 (#16056, author date 2026-05-14). Nearest items, none of them this bug: #15678 (the introducing PR; its tests use a CannedTokenStream, the MemoryIndex path), #15668 (the UnsupportedOperationException it fixed), #12088 (added the skip that #15678 removed), #7450 (LUCENE-6390, open since 2015: the internal reader did not implement getFieldInfos), open PR #16816 (stale; its FieldExistsQuery.rewrite change would hide the FieldExistsQuery form on main by accident, executed as a shadow class: 3 of 3 pass), #16582 (in 10.6.0; makes full-range sorted-numeric doc-values ranges rewrite to FieldExistsQuery, so more triggers). Not fixed upstream: main 645d4fe14a2 (re-run 2026-10-29) and branch_10_6 4ae946e5a9b9 still lack the skip.
- Lucene commit tested
- main
a9779ef3c193(gradle in a scratch worktree, assertions on and off; and the standalone JUnit runner with several seeds); the release jars 9.1.0, 9.2.0, 9.4.2, 9.5.0, 9.12.3, 10.3.2, 10.4.0, 10.5.0, 10.5.1 and 10.5.2 and 10.6.0-SNAPSHOT jars built from branch_10_64ae946e5a9b; a one-file shadow bisect of #15678 in both directions; fixes A and B ona9779ef3c193with the whole:lucene:highlighter:testtask. JDK 25.0.3, Linux aarch64.
- Finding record
lucene/highlighter/src/java/org/apache/lucene/search/highlight/WeightedSpanTermExtractor.java:236-263 (at a9779ef3c193) (extract: MatchAllDocsQuery and FunctionScoreQuery branches, no FieldExistsQuery branch; unknown queries rewritten with new IndexSearcher(getLeafContext().reader())), :388-400 (getLeafContext: a TokenStreamFromTermVector whose Terms have positions and offsets gets a TermVectorLeafReader), :442-451 (DelegatingLeafReader.getFieldInfos: fieldInfo(any name) returns the shadowed field's FieldInfo)lucene/highlighter/src/java/org/apache/lucene/search/highlight/TermVectorLeafReader.java:93-112 (at a9779ef3c193) (FieldInfo with omitNorms=true, DocValuesType.NONE, vector dimension 0)lucene/core/src/java/org/apache/lucene/search/FieldExistsQuery.java:125-157 (at a9779ef3c193) (rewrite: norms, then vectors, then doc values, else throw new IllegalStateException(buildErrorMsg))
- The finding in 30 seconds
lucene/highlighter/src/java/org/apache/lucene/search/highlight/WeightedSpanTermExtractor.java:129-138 (at a9779ef3c193) (BooleanQuery clauses), :236-262 (extract branches and rewrite), :389-430 (getLeafContext), :434-451 (DelegatingLeafReader, FIELD_NAME, getFieldInfos)lucene/highlighter/src/java/org/apache/lucene/search/highlight/TermVectorLeafReader.java:93-113 (at a9779ef3c193) (FieldInfo: omitNorms true, DocValuesType.NONE, vector dimension 0)lucene/core/src/java/org/apache/lucene/index/FieldInfo.java:78-96 (at a9779ef3c193) (constructor argument order)lucene/core/src/java/org/apache/lucene/search/FieldExistsQuery.java:116-157 (at a9779ef3c193) (rewrite, throw at :156), :290-293 (message)lucene/core/src/java/org/apache/lucene/search/IndexSortSortedNumericDocValuesRangeQuery.java:130-133 (at a9779ef3c193)lucene/highlighter/src/java/org/apache/lucene/search/highlight/TokenSources.java:40-92 (at a9779ef3c193) (getTokenStream, getTermVectorTokenStreamOrNull)
- Who is affected
lucene/highlighter/src/java/org/apache/lucene/search/highlight/TokenSources.java:29-92 (at a9779ef3c193) (class javadoc; getTokenStream prefers term vectors; positions recommended)lucene/highlighter/src/java/org/apache/lucene/search/highlight/package-info.java:29-82 (at a9779ef3c193) (term-vector example; 'Faster highlighting using Term vector support')lucene/highlighter/src/java/org/apache/lucene/search/highlight/WeightedSpanTermExtractor.java:133-138 (at a9779ef3c193) (prohibited clauses skipped)lucene/highlighter/src/java/org/apache/lucene/search/highlight/WeightedSpanTermExtractor.java:165-169 (at a9779ef3c193) (IndexOrDocValuesQuery: only the index side is extracted)
- Why it looks unintended
lucene/highlighter/src/test/org/apache/lucene/search/highlight/TestHighlighter.java:1445-1454, (at a9779ef3c193) 2230-2245 (CannedTokenStream tests)lucene/highlighter/src/java/org/apache/lucene/search/highlight/WeightedSpanTermExtractor.java:72-100 (at a9779ef3c193) (class javadoc), :260-261 (reached when the rewrite returns the query), :278-282 (extractUnknownQuery no-op)lucene/CHANGES.txt:1163-1164 (at a9779ef3c193) (GITHUB#15668 in 10.5.0), :3847-3848 (GITHUB#12088)lucene/highlighter/src/test/org/apache/lucene/search/highlight/custom/TestHighlightCustomQuery.java:100-140 (at a9779ef3c193) (testHighlightQueryRequiringMetadata, highlightField re-analyses with MockAnalyzer)lucene/highlighter/src/java/org/apache/lucene/search/highlight/TermVectorLeafReader.java:54 (at a9779ef3c193) (@lucene.experimental), TokenStreamFromTermVector.java:50 (@lucene.internal); lucene/core/src/java/org/apache/lucene/index/FieldInfo.java:73-78 (@lucene.experimental constructor)
- Suggested fix
lucene/highlighter/src/java/org/apache/lucene/search/highlight/TermVectorLeafReader.java:50-56 (at a9779ef3c193) (@lucene.experimental), :155-157 (getNormValues returns null)lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/TermVectorOffsetStrategy.java (at a9779ef3c193) (uses TermVectorLeafReader)
- History
a Lucene clone: git tag --contains 7ddd1898b389 = releases/lucene/10.5.0, 10.5.1, 10.5.2, 10.6.0; 10.4.0 lacks it
- TestHighlightFieldExistsTermVectors.java (highlighter, 3 tests):
repro/LFV-824/TestHighlightFieldExistsTermVectors.java(113 lines) - TestFieldExistsTermVectorHighlight.java (independent reproducer, 5 tests):
repro/LFV-824/TestFieldExistsTermVectorHighlight.java(146 lines) - TestFieldExistsTermVectorVariants.java (variant test, 2 tests):
repro/LFV-824/TestFieldExistsTermVectorVariants.java(89 lines)
A step-by-step picture of the repro's example, made in parallel with this doc from a traced run on main.
assets/LFV-824/bug.png(478 KB)