IndexWriter buffers a doc-values update as one term and one value. When it applies the update, it writes the value into a per-segment buffer once for every document the term matches. For binary values that buffer is a single Java byte[], whose length is an int and cannot reach 2^31 bytes.
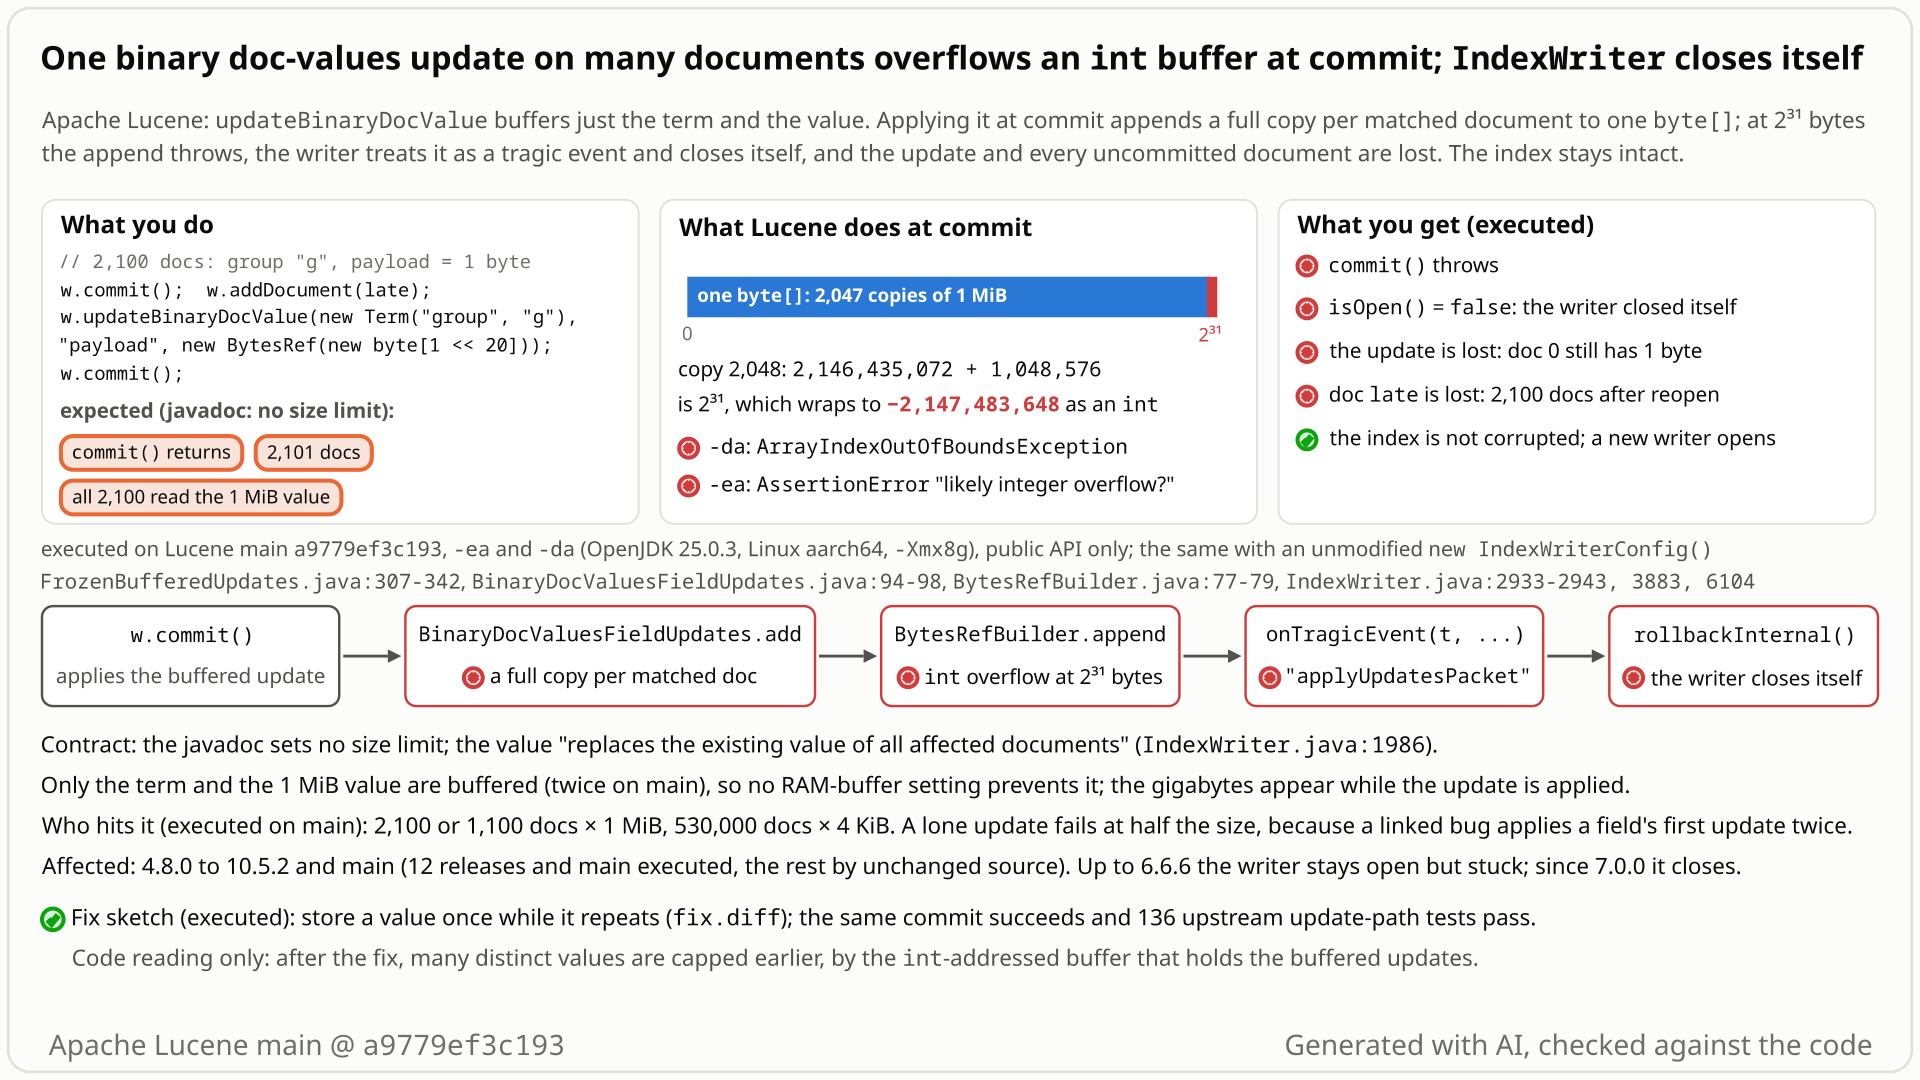
commit() each matched document appends another copy to one byte[], copy 2,048 would end at byte 2^31, the int length wraps, and the tragic handler closes the writer; with the fix the same commit succeeds. Select the still to open it at full size. Generated with AI, checked against the code.- Commit 2,100 documents that share the term
group:g(one segment), add one more document,late, and callupdateBinaryDocValue(new Term("group", "g"), "payload", value)once with a 1 MiB value. IndexWriter buffers only the term and that value, with no per-document copies. - You expect
commit()to give all 2,100 documents the new value and keeplate: about 2.2 GB of binary doc values, which a fixed build commits fine. - Instead, applying the update appends a full 1 MiB copy per matched document to one
byte[]. Copy 2,048 would end at byte 2^31, theintlength wraps to -2,147,483,648, andcommit()throwsArrayIndexOutOfBoundsException(with-ea, anAssertionError: "likely integer overflow?"). - The apply runs where every exception is tragic: IndexWriter closes itself, and the update and
lateare lost. The last commit stays readable and a new writer opens on it. - Since 7.7.0 a lone update is applied twice (a separate bug), so 1,100 documents x 1 MiB already fail. Ordinary sizes fail too: 530,000 documents x 4 KiB.
Applications that update a binary doc-values field by a term many documents share, such as a per-tenant or per-category blob, on the default configuration. It takes gigabytes of copies in one segment: 2,100 or 1,100 documents x 1 MiB, or 530,000 x 4 KiB. No RAM or heap setting prevents it, and uncommitted documents are lost.
Mechanism, terms and numbers660 words
IndexWriter.updateBinaryDocValue(term, field, value) buffers one term and one value (stored twice when it is the field's first update in the packet, on 7.7.0 and later). When the update is applied (at commit(), and by code reading also at a flush or NRT reopen that applies the packet), Lucene calls BinaryDocValuesFieldUpdates.add(doc, value) once for every document the term matches in a segment, and each call appends a full copy of the value to one int-sized byte[]. At 2^31 bytes the length wraps: ArrayIndexOutOfBoundsException (an AssertionError "likely integer overflow?" with assertions on). The apply runs inside an event that treats any Throwable as tragic, so IndexWriter closes itself and the update and every uncommitted document are lost; the last commit stays readable. 2,100 documents x 1 MiB fail, and so do 530,000 x 4 KiB; since 7.7.0 a lone update is applied twice (LFV-837), so 1,100 x 1 MiB fails too. With a one-method fix the same commit succeeds. Every tested release from 4.8.0 to 10.5.2 is affected, and so are main and, by reading, 10.6.0 (13 versions executed; the releases in between keep the same per-document append).
- Doc-values update:
updateBinaryDocValue(term, field, value)(alsoupdateDocValues(term, BinaryDocValuesField)) changes a binary doc-values field in place on every document that containsterm. IndexWriter buffers the request and applies it later, at a commit, flush or NRT reopen, by looking up the term in each segment. - Packet: the buffered updates that are applied together. Applying a packet builds one
BinaryDocValuesFieldUpdatesper field and segment, which records(doc, value)for every matched document before it is written out. - Tragic event: an error after which IndexWriter closes itself and discards everything not committed, because its internal state may be inconsistent.
FrozenBufferedUpdates.applyDocValuesUpdatescreates oneBinaryDocValuesFieldUpdatesper field and segment (FrozenBufferedUpdates.java:307-308) and, for each document the update's term matches, callsupdate.add(doc, binaryValue)with the sameBytesRef(:319, loop:336-345). The numeric path keeps one value for all documents in this case (SingleValueNumericDocValuesFieldUpdates,:288-295); the binary path does not.BinaryDocValuesFieldUpdates.addappends a full copy every time:offsets.set(index, values.length()); lengths.set(index, value.length); values.append(value);(BinaryDocValuesFieldUpdates.java:94-99), intovalues = new BytesRefBuilder()(:80), onebyte[].BytesRefBuilder.appendcomputes the new length asref.length + len, anint(BytesRefBuilder.java:77-80). With 2,047 copies of 1 MiB stored (2,146,435,072 bytes), copy 2,048 needs 2^31 bytes and the sum wraps to -2,147,483,648.ArrayUtil.growassertsminSize >= 0("likely integer overflow?",ArrayUtil.java:446); without assertions it returns the array unchanged andSystem.arraycopythrows (BytesRefBuilder.java:79). (1 MiB and 4 KiB divide 2^31; for lengths where a multiple lands betweenArrayUtil.MAX_ARRAY_LENGTHandInteger.MAX_VALUE, such as any length up to 16 bytes,ArrayUtil.oversizethrowsIllegalArgumentExceptioninstead,ArrayUtil.java:145-152, by code reading; the writer closes the same way.)- The apply runs as an event that catches any
Throwableand callsonTragicEvent(t, "applyUpdatesPacket")(IndexWriter.java:2935-2943).commit()first flushes the buffered documents to a new segment (:3809,:3819; here doclatebecomes segment_1, written but in no commit) and then applies the packet inprocessEvents(false)(:3821), as an executed infoStream probe shows.prepareCommitInternalthen closes the writer throughmaybeCloseOnTragicEvent()->rollbackInternal()(itsfinallyat:3883with assertions off; itscatch (Error)at:3879-3881with assertions on;:6098-6105), which drops segment_1too. - Nothing bounds the expansion: the per-segment updates are built privately during the apply and enter IndexWriter's RAM accounting only when published (
ReadersAndUpdates.java:153-161), and only the entry count has an explicit guard (DocValuesFieldUpdates.java:375-379).
By code reading the count that matters is the sum, over all binary updates of one field in one packet, of the documents each matches in one segment times its value length; only the one-update case was executed. Since 7.7.0 the first update of a field in a packet is applied twice (LFV-837), so a lone update fails at 2^30 bytes.
Exposure and likelihood329 words
- Who is hit. Callers of
updateBinaryDocValue,updateDocValues(term, BinaryDocValuesField)orsoftUpdateDocument(s)with a binary doc-values field (the last two by code reading), when the term matches many documents of one segment. - Default vs opt-in. Default
IndexWriterConfigand codec (executed). The tests useByteBuffersDirectory; anFSDirectoryvariant fails the same way (executed), since the overflow happens in a heap buffer, before the update is written. Binary doc-values updates are an optional but mainstream public API; no RAM-buffer or heap setting bounds the expansion. - Scale. 2,100 x 1 MiB; 1,100 x 1 MiB when the update is its field's first in the packet (any lone update, 7.7.0 and later); 530,000 x 4 KiB. Controls with 100 or 1,000 x 1 MiB and 200,000 x 4 KiB succeed. The failing apply needs about 4 GB of heap; with a 3 GB heap it ends in
OutOfMemoryErrorinstead, with the same close. The 530,000-document test forces one segment withforceMerge(1); in practice the trigger needs large segments and a term that many of their documents share. - Effect. Loud:
commit()throws and the writer is closed. The update and every acknowledged uncommitted document are lost; the last commit stays readable and a new writer opens on it (executed). Before 7.0.0 the writer stays open but stuck: a secondcommit()andclose()throw the same exception andlateis missing after reopening (executed on 4.8.0, 4.10.4, 5.5.5, 6.6.6); by code reading every later commit fails too andclose()rolls back. - No way to apply it. A bigger heap does not help, since the limit is the
intlength; only keeping documents matched per segment times value length, summed over the field's binary updates in one packet, under 2^31 bytes avoids it: fewer matched documents, a smaller value or fewer updates per packet (by code reading). - Likelihood. Rare: binary updates by a widely shared term are uncommon (most in-place updates are numeric or by primary key), and nobody has reported it since 4.8.0 (2014).
A JUnit test on the public API: 2,100 documents in one committed segment, one uncommitted document, one 1 MiB updateBinaryDocValue by the shared term, then commit(). Run it in lucene/core with an 8 GB test heap; it takes a few seconds.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import org.apache.lucene.document.BinaryDocValuesField;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.StringField;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;

/**
 * One {@link IndexWriter#updateBinaryDocValue} call whose term matches 2,100 documents of one
 * segment, with a 1 MiB value. Applying it keeps one copy of the value per matched document in a
 * single int-addressed buffer (BinaryDocValuesFieldUpdates), which overflows past 2^31 bytes; the
 * failure is handled as a tragic event and the writer closes.
 *
 * <p>Public API only. Needs a large heap (run with -Xmx8g): the failing path allocates about 4 GB.
 * Set -Dh321.numDocs=N to change the number of matched documents.
 */
public class TestBinaryDocValuesUpdateBufferOverflow extends LuceneTestCase {

  public void testBinaryUpdateMatchingManyDocsKeepsWriterOpen() throws Exception {
    final int numDocs = Integer.getInteger("h321.numDocs", 2100);
    final int valueLength = 1 << 20; // 1 MiB
    try (Directory dir = new ByteBuffersDirectory()) {
      IndexWriterConfig iwc = new IndexWriterConfig(null);
      iwc.setMergePolicy(NoMergePolicy.INSTANCE);
      IndexWriter w = new IndexWriter(dir, iwc);
      for (int i = 0; i < numDocs; i++) {
        Document doc = new Document();
        doc.add(new StringField("group", "g", Field.Store.NO));
        doc.add(new BinaryDocValuesField("payload", new BytesRef(new byte[] {(byte) i})));
        w.addDocument(doc);
      }
      w.commit(); // one segment with numDocs documents

      byte[] big = new byte[valueLength];
      for (int i = 0; i < big.length; i++) {
        big[i] = (byte) (i * 31 + 7);
      }
      // an unrelated document, acknowledged before the update and not yet committed
      Document late = new Document();
      late.add(new StringField("group", "late", Field.Store.NO));
      w.addDocument(late);
      w.updateBinaryDocValue(new Term("group", "g"), "payload", new BytesRef(big));
      Throwable failure = null;
      try {
        w.commit();
      } catch (Throwable t) {
        failure = t;
      }
      System.out.println(
          "numDocs="
              + numDocs
              + " commit failure: "
              + failure
              + "; writer open: "
              + w.isOpen()
              + "; tragic exception: "
              + w.getTragicException());
      if (w.isOpen() == false) {
        try (DirectoryReader r = DirectoryReader.open(dir)) {
          System.out.println(
              "after the close: committed docs="
                  + r.numDocs()
                  + ", acknowledged late doc present="
                  + (r.docFreq(new Term("group", "late")) > 0));
        }
      }
      assertNull("commit of an accepted binary doc-values update threw: " + failure, failure);
      assertTrue("IndexWriter closed itself", w.isOpen());
      try (DirectoryReader r = DirectoryReader.open(dir)) {
        BinaryDocValues bdv = MultiDocValues.getBinaryValues(r, "payload");
        assertEquals(numDocs + 1, r.numDocs());
        for (int d = 0; d < numDocs; d++) {
          assertTrue(bdv.advanceExact(d));
          assertEquals(new BytesRef(big), bdv.binaryValue());
        }
      }
      w.close();
    }
  }
}
cp $REPRO/org/apache/lucene/index/TestBinaryDocValuesUpdateBufferOverflow.java \
   $LUCENE/lucene/core/src/test/org/apache/lucene/index/
cd $LUCENE && ./gradlew :lucene:core:test --tests TestBinaryDocValuesUpdateBufferOverflow \
   -Ptests.heapsize=8g -Ptests.seed=DEADBEEF
# add -Ptests.asserts=false for the ArrayIndexOutOfBoundsException
# with a fix: -Ptests.heapsize=12g (the committed 2.2 GB live in the heap directory)
- Expected
commit()succeeds, the writer stays open, all 2,100 documents read the 1 MiB value andlateis committed.- Observed
commit()throwsAssertionError: size must be positive (got -2147483648): likely integer overflow?(ArrayIndexOutOfBoundsExceptionwith assertions off); the writer is closed andlateis lost.
More files, environment, full output3 more files (372 lines) · 2,188 words
The test uses ByteBuffersDirectory, new IndexWriterConfig(null) and NoMergePolicy so that the 2,100 documents stay in one segment; the independent reproducer's test (below) shows the same with a fully default new IndexWriterConfig(). Set -Dh321.numDocs=N (as -Ptests.jvmargs) to change the number of documents. The failing run allocates about 4 GB; with a 3 GB heap the same update ends in OutOfMemoryError, with the same close.
The other files: the independent reproducer's test (default config, a 100-document control, checks that a new writer opens), the devil's-advocate checker's 530,000 x 4 KiB test, and a small-heap unit test, which checks BinaryDocValuesFieldUpdates directly (it fails on stock main and passes with the fix). The verifier tests are not yet formatted with google-java-format.
On stock main: the 2,100-document test fails, the 100-document control passes; a new writer opens after the close.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import java.io.PrintWriter;
import java.io.StringWriter;
import java.util.Arrays;
import org.apache.lucene.document.BinaryDocValuesField;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.StringField;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.TermQuery;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;

/**
 * One call to {@link IndexWriter#updateBinaryDocValue(Term, String, BytesRef)} whose term matches
 * many documents of one segment. The javadoc documents no size limit and says the value replaces
 * the value of all affected documents. Expected: the commit succeeds, the writer stays open, the
 * acknowledged document added before the update is committed and every matched document reads
 * back the new value.
 *
 * <p>Heap: the failing run needs about 4 GB (the per-document copies of the value); run with
 * -Xmx8g. The control method needs far less.
 */
public class TestBinaryDvUpdateManyDocs extends LuceneTestCase {

  private static final int VALUE_LEN = 1 << 20; // 1 MiB

  /** 2,100 documents x 1 MiB = 2,100 MiB of updated values in one segment (> 2^31 bytes). */
  public void testUpdateMatchingManyDocs() throws Exception {
    runScenario(Integer.getInteger("v1.numDocs", 2100));
  }

  /** Control: the same scenario with 100 documents (100 MiB) must work on every version. */
  public void testControlFewDocs() throws Exception {
    runScenario(100);
  }

  private static void runScenario(int numDocs) throws Exception {
    byte[] big = new byte[VALUE_LEN];
    for (int i = 0; i < big.length; i++) {
      big[i] = (byte) (i * 31 + 7);
    }
    try (Directory dir = new ByteBuffersDirectory()) {
      IndexWriter w = new IndexWriter(dir, new IndexWriterConfig());
      for (int i = 0; i < numDocs; i++) {
        Document d = new Document();
        d.add(new StringField("id", "d" + i, Field.Store.NO));
        d.add(new StringField("group", "g", Field.Store.NO));
        d.add(new BinaryDocValuesField("bdv", new BytesRef(new byte[] {1})));
        w.addDocument(d);
      }
      w.commit();
      try (DirectoryReader r = DirectoryReader.open(dir)) {
        assertEquals("setup: one segment", 1, r.leaves().size());
        assertEquals(numDocs, r.numDocs());
      }

      // An unrelated, acknowledged but not yet committed document.
      Document late = new Document();
      late.add(new StringField("id", "late", Field.Store.NO));
      late.add(new BinaryDocValuesField("bdv", new BytesRef(new byte[] {2})));
      w.addDocument(late);

      // One update whose term matches all numDocs documents of the committed segment.
      w.updateBinaryDocValue(new Term("group", "g"), "bdv", new BytesRef(big));

      Throwable failure = null;
      try {
        w.commit();
      } catch (Throwable t) {
        failure = t;
      }
      boolean open = w.isOpen();
      Throwable tragic = w.getTragicException();
      if (open) {
        w.close();
      }

      int committedDocs;
      int lateHits;
      try (DirectoryReader r = DirectoryReader.open(dir)) {
        committedDocs = r.numDocs();
        lateHits = new IndexSearcher(r).count(new TermQuery(new Term("id", "late")));
        if (failure == null) {
          // spot-check updated values on a few matched documents
          for (LeafReaderContext ctx : r.leaves()) {
            BinaryDocValues bdv = ctx.reader().getBinaryDocValues("bdv");
            assertNotNull(bdv);
            int checked = 0;
            for (int doc = 0; doc < ctx.reader().maxDoc() && checked < 3; doc += 997) {
              assertTrue(bdv.advanceExact(doc));
              BytesRef v = bdv.binaryValue();
              if (v.length == VALUE_LEN) {
                assertTrue(
                    "value mismatch at doc " + doc,
                    Arrays.equals(big, 0, VALUE_LEN, v.bytes, v.offset, v.offset + v.length));
                checked++;
              }
            }
          }
        }
      }
      // A new writer on the same directory opens fine (the failure does not persist).
      boolean reopenedWriterOk;
      try (IndexWriter w2 = new IndexWriter(dir, new IndexWriterConfig())) {
        reopenedWriterOk = w2.isOpen();
      }

      String report =
          "numDocs="
              + numDocs
              + " valueLen="
              + VALUE_LEN
              + " product="
              + ((long) numDocs * VALUE_LEN)
              + " (2^31="
              + (1L << 31)
              + ")\n  commit failure: "
              + describe(failure)
              + "\n  writer open after commit: "
              + open
              + "\n  tragic exception: "
              + (tragic == null ? "null" : tragic.getClass().getName() + ": " + tragic.getMessage())
              + "\n  after reopen: committed docs="
              + committedDocs
              + ", late doc present="
              + (lateHits == 1)
              + ", new writer opens="
              + reopenedWriterOk;
      System.out.println("V1-REPORT " + report);

      assertNull("commit must not fail\n" + report, failure);
      assertTrue("writer must stay open\n" + report, open);
      assertNull("no tragic exception\n" + report, tragic);
      assertEquals("all docs incl. the late one committed\n" + report, numDocs + 1, committedDocs);
      assertEquals("late doc committed\n" + report, 1, lateHits);
    }
  }

  private static String describe(Throwable t) {
    if (t == null) {
      return "none";
    }
    StringWriter sw = new StringWriter();
    t.printStackTrace(new PrintWriter(sw));
    String[] lines = sw.toString().split("\n");
    StringBuilder sb = new StringBuilder();
    for (int i = 0; i < Math.min(14, lines.length); i++) {
      sb.append("\n      ").append(lines[i].trim());
    }
    return sb.toString();
  }
}
On stock main and 10.5.2: fails the same way; 200,000 documents pass.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import org.apache.lucene.document.BinaryDocValuesField;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.StringField;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;

/**
 * Reachability check with a moderate value size: one updateBinaryDocValue call with a 4 KiB value
 * whose term matches 530,000 documents of one segment (530,000 x 4,096 bytes > 2^31 - 1). Default
 * IndexWriterConfig (default merge policy, default RAM buffer). Expected per the javadoc: the update
 * is applied and the writer stays open.
 */
public class TestModerateValueBinaryUpdate extends LuceneTestCase {

  public void testModerateValueManyDocs() throws Exception {
    final int numDocs = Integer.getInteger("v3.numDocs", 530_000);
    final int valueLength = Integer.getInteger("v3.valueLength", 4096);
    try (Directory dir = new ByteBuffersDirectory()) {
      IndexWriter w = new IndexWriter(dir, new IndexWriterConfig(null));
      for (int i = 0; i < numDocs; i++) {
        Document doc = new Document();
        doc.add(new StringField("tenant", "t1", Field.Store.NO));
        doc.add(new BinaryDocValuesField("blob", new BytesRef(new byte[] {(byte) i})));
        w.addDocument(doc);
      }
      w.forceMerge(1);
      w.commit();
      int segs;
      try (DirectoryReader r = DirectoryReader.open(w)) {
        segs = r.leaves().size();
      }
      byte[] v = new byte[valueLength];
      for (int i = 0; i < v.length; i++) {
        v[i] = (byte) (i * 13 + 1);
      }
      w.updateBinaryDocValue(new Term("tenant", "t1"), "blob", new BytesRef(v));
      Throwable failure = null;
      try {
        w.commit();
      } catch (Throwable t) {
        failure = t;
      }
      System.out.println(
          "segments="
              + segs
              + " numDocs="
              + numDocs
              + " valueLength="
              + valueLength
              + " product="
              + ((long) numDocs * valueLength)
              + " failure="
              + failure
              + " writerOpen="
              + w.isOpen()
              + " tragic="
              + w.getTragicException());
      assertNull("commit after an accepted binary doc-values update threw: " + failure, failure);
      assertTrue("IndexWriter closed itself", w.isOpen());
      w.close();
    }
  }
}
10,000 documents get the same 1 KiB value; ramBytesUsed() must stay under a tenth of the 10,240,000 bytes of copies. Stock: fails (ramBytesUsed=11320434); with the fix: passes. A second, randomized test (runs of values, resets, a reused BytesRef) passes on both.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import org.apache.lucene.search.DocIdSetIterator;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;
import org.apache.lucene.util.BytesRefBuilder;

/**
 * Small-heap unit tests for BinaryDocValuesFieldUpdates: applying one buffered binary update adds
 * the same value for every document its term matches, so the value bytes kept must not grow with
 * the number of matched documents.
 */
public class TestBinaryDocValuesFieldUpdatesSharedValue extends LuceneTestCase {

  /** 10,000 documents get the same 1 KiB value: keeping 10,000 copies costs 10,240,000 bytes. */
  public void testSameValueOnManyDocsIsStoredOnce() {
    final int numDocs = 10_000;
    final byte[] bytes = new byte[1024];
    random().nextBytes(bytes);
    final BytesRef value = new BytesRef(bytes);
    BinaryDocValuesFieldUpdates updates = new BinaryDocValuesFieldUpdates(0, "f", numDocs);
    for (int doc = 0; doc < numDocs; doc++) {
      updates.add(doc, value);
    }
    updates.finish();
    long copies = (long) numDocs * bytes.length;
    assertTrue(
        "ramBytesUsed=" + updates.ramBytesUsed() + " for " + copies + " bytes of copies",
        updates.ramBytesUsed() < copies / 10);
    DocValuesFieldUpdates.Iterator it = updates.iterator();
    for (int doc = 0; doc < numDocs; doc++) {
      assertEquals(doc, it.nextDoc());
      assertTrue(it.hasValue());
      assertEquals(value, it.binaryValue());
    }
    assertEquals(DocIdSetIterator.NO_MORE_DOCS, it.nextDoc());
  }

  /**
   * Runs of different values (including empty ones), documents in random order and updated more
   * than once, resets, and a caller that reuses one BytesRef and overwrites its bytes between runs:
   * every document must read back its last value.
   */
  public void testRunsOfValuesReadBackLastValue() {
    final int maxDoc = 200;
    final byte[][] pool = new byte[5][];
    for (int i = 0; i < pool.length; i++) {
      pool[i] = new byte[i == 0 ? 0 : 1 + random().nextInt(40)];
      random().nextBytes(pool[i]);
    }
    for (int iter = 0; iter < 50; iter++) {
      BinaryDocValuesFieldUpdates updates = new BinaryDocValuesFieldUpdates(0, "f", maxDoc);
      byte[][] expected = new byte[maxDoc][]; // null: no entry
      boolean[] reset = new boolean[maxDoc];
      BytesRefBuilder reused = new BytesRefBuilder();
      int runs = 1 + random().nextInt(20);
      for (int run = 0; run < runs; run++) {
        if (random().nextInt(10) == 0) {
          int doc = random().nextInt(maxDoc);
          updates.reset(doc);
          expected[doc] = null;
          reset[doc] = true;
          continue;
        }
        byte[] v = pool[random().nextInt(pool.length)];
        BytesRef ref;
        if (random().nextBoolean()) {
          reused.copyBytes(v, 0, v.length); // same object, new bytes
          ref = reused.get();
        } else {
          byte[] padded = new byte[v.length + 3];
          System.arraycopy(v, 0, padded, 1, v.length);
          ref = new BytesRef(padded, 1, v.length);
        }
        int matches = 1 + random().nextInt(30);
        for (int m = 0; m < matches; m++) {
          int doc = random().nextInt(maxDoc);
          updates.add(doc, ref);
          expected[doc] = v;
          reset[doc] = false;
        }
      }
      updates.finish();
      DocValuesFieldUpdates.Iterator it = updates.iterator();
      for (int doc = 0; doc < maxDoc; doc++) {
        if (expected[doc] == null && reset[doc] == false) {
          continue;
        }
        assertEquals(doc, it.nextDoc());
        if (reset[doc]) {
          assertFalse("doc " + doc, it.hasValue());
        } else {
          assertTrue("doc " + doc, it.hasValue());
          assertEquals("doc " + doc, new BytesRef(expected[doc]), it.binaryValue());
        }
      }
      assertEquals(DocIdSetIterator.NO_MORE_DOCS, it.nextDoc());
    }
  }
}
| lucene | main a9779ef3c193 (11.0.0-SNAPSHOT), gradle, assertions on and off; also 12 releases from 4.8.0 to 10.5.2 (published jars) |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (a pure-Java code path) |
cp $REPRO/org/apache/lucene/index/TestBinaryDocValuesUpdateBufferOverflow.java \
   $LUCENE/lucene/core/src/test/org/apache/lucene/index/
cd $LUCENE && ./gradlew :lucene:core:test --tests TestBinaryDocValuesUpdateBufferOverflow \
   -Ptests.heapsize=8g -Ptests.seed=DEADBEEF
# add -Ptests.asserts=false for the ArrayIndexOutOfBoundsException
# with a fix: -Ptests.heapsize=12g (the committed 2.2 GB live in the heap directory)
# stock main a9779ef3c193, gradle, assertions on
TestBinaryDocValuesUpdateBufferOverflow > testBinaryUpdateMatchingManyDocsKeepsWriterOpen FAILED
    java.lang.AssertionError: commit of an accepted binary doc-values update threw: java.lang.AssertionError:
        size must be positive (got -2147483648): likely integer overflow? expected null, but was:<...>
  1> numDocs=2100 commit failure: java.lang.AssertionError: size must be positive (got -2147483648): likely integer overflow?;
     writer open: false; tragic exception: java.lang.AssertionError: size must be positive (got -2147483648): likely integer overflow?
  1> after the close: committed docs=2100, acknowledged late doc present=false

# the same with -Ptests.asserts=false
  1> numDocs=2100 commit failure: java.lang.ArrayIndexOutOfBoundsException: arraycopy: last destination index 2147483648
     out of bounds for byte[2147483631]; writer open: false; tragic exception: java.lang.ArrayIndexOutOfBoundsException: ...
  1> after the close: committed docs=2100, acknowledged late doc present=false

# the failed commit's stack (independent reproducer's test, same build, assertions on)
java.lang.AssertionError: size must be positive (got -2147483648): likely integer overflow?
    at org.apache.lucene.util.ArrayUtil.grow(ArrayUtil.java:446)
    at org.apache.lucene.util.BytesRefBuilder.grow(BytesRefBuilder.java:60)
    at org.apache.lucene.util.BytesRefBuilder.append(BytesRefBuilder.java:78)
    at org.apache.lucene.util.BytesRefBuilder.append(BytesRefBuilder.java:85)
    at org.apache.lucene.index.BinaryDocValuesFieldUpdates.add(BinaryDocValuesFieldUpdates.java:98)
    at org.apache.lucene.index.FrozenBufferedUpdates.lambda$applyDocValuesUpdates$2(FrozenBufferedUpdates.java:319)
    at org.apache.lucene.index.FrozenBufferedUpdates.applyDocValuesUpdates(FrozenBufferedUpdates.java:342)
    at org.apache.lucene.index.FrozenBufferedUpdates.applyDocValuesUpdates(FrozenBufferedUpdates.java:205)
    at org.apache.lucene.index.FrozenBufferedUpdates.apply(FrozenBufferedUpdates.java:173)
    at org.apache.lucene.index.IndexWriter.forceApply(IndexWriter.java:6592)
    at org.apache.lucene.index.IndexWriter.tryApply(IndexWriter.java:6494)
    at org.apache.lucene.index.IndexWriter.lambda$publishFrozenUpdates$0(IndexWriter.java:2939)
  writer open after commit: false
  after reopen: committed docs=2100, late doc present=false, new writer opens=true

# with the fix (same worktree): the test passes with assertions on and off (3.2 s, 12 GB test heap)- The javadoc sets no size limit and "replaces the existing value of all affected documents"; a fixed build commits the 2.2 GB update.
- Lucene's own check calls it a "likely integer overflow?"; the entry count has a guard, the byte length none.
- A numeric value shared by a packet's updates is stored once (LUCENE-8593); binary values never are.
The full argument236 words
- Contract.
updateBinaryDocValue(IndexWriter.java:1981-1995): "NOTE: this method currently replaces the existing value of all affected documents with the new value", with@param term the term to identify the document(s) to be updated; no size limit.updateDocValues(:2059-2063): "Each field update is applied to the set of documents that are associated with the Term to the same value." - A legal result. The indexing-time
BinaryDocValuesWriterstores values inPagedBytesand allows each value up toArrayUtil.MAX_ARRAY_LENGTH(BinaryDocValuesWriter.java:40-45, 61, 81-83); with the fix the same 2.2 GB update commits in one segment and all values read back (executed). - Lucene's own check flags it.
ArrayUtil.grow: "size must be positive (got -2147483648): likely integer overflow?" (ArrayUtil.java:446). The entry count has an explicit guard, "cannot support more than Integer.MAX_VALUE doc/value entries" (DocValuesFieldUpdates.java:375-379); the byte length has none. - History. The per-document append came with the feature (LUCENE-5513, #6576, 2014); in that issue @shaie, who implemented it, notes that the update "makes all affected documents identical", and no comment discusses the size of the in-heap buffer the apply builds. LUCENE-8593 (
b4e1fe4393b, 2018) gave the numeric path a single-value specialisation; the binary path never got one. - Tests and precedent. No test, javadoc, CHANGES or MIGRATE entry accepts the failure. #8589 (LUCENE-7538), an 800 MB stored field whose
intoverflow closed the writer, was fixed by rejecting the input with a clear error.
The devil's-advocate check236 words
The strongest intended-behaviour case, built by a dedicated checker: "the limits on IndexWriter are 2GB" (a maintainer on #15330), and IndexWriterConfig documents another sub-2 GB limit, the per-thread RAM hard limit (IndexWriterConfig.java:373-385); BinaryDocValuesField says values "are stored directly with no sharing" (BinaryDocValuesField.java:26-28); the class is @lucene.experimental; the writer closing after a failed apply is an intended fail-safe since LUCENE-7868; and the IndexWriter class NOTE ("if you hit an Error ... IndexWriter will close itself", IndexWriter.java:162-165) covers the AssertionError of an -ea run and the OutOfMemoryError of a small heap.
Why it fails: the #15330 remark is about an indexing buffer that the RAM settings bound, and the per-thread limit is a setting checked with a clear error, while here one 1 MiB value is buffered and the 2 GiB appear at apply time with no check; "no sharing" is storage advice, and only NUMERIC, SORTED_NUMERIC and BINARY fields can be updated (IndexWriter.java:2106-2124), so BINARY is the only updatable byte type; the experimental tag is on the internal class, not on updateBinaryDocValue; the close is intended, which is why the overflow, not the close, is the defect; the class NOTE explains the close for Errors but sets no limit on the update, and with assertions off (the production default) and an 8 GB heap the failure is an ArrayIndexOutOfBoundsException, which no document covers. Verdict: not intended.
Recommended Keep one copy of a repeated value (validated)
In BinaryDocValuesFieldUpdates.add, append the value only when it differs from the last appended one and point the document at the stored copy (+20/-2 lines). Validated with gradle: the repros pass with and without assertions, and 221 tests in 16 classes pass. For many distinct values, the int-addressed buffer of the buffered updates is the earlier limit (code reading).
All options and trade-offs3 options · 832 words
One fix was built and validated in a clean scratch worktree at a9779ef3c193 (removed afterwards); it is the finder's sketch with java.util.Arrays imported. Fixing the separate bug LFV-837 alone only restores the 2 GiB threshold. Workaround today (by code reading, not executed): keep each packet under the limit, for example by splitting the term into parts and committing after each part, or keep the shared value in a separate document. Both have limits: splitting needs an indexed term the application can partition, and a separate document changes the application's data model.
In BinaryDocValuesFieldUpdates.add (:94-99), remember the offset and length of the last appended value; when the new value has the same bytes, point the document's offset at that copy instead of appending again. One update's documents arrive consecutively with the same value (FrozenBufferedUpdates.java:336-345), including the duplicate pass of LFV-837, so each update is stored once.
  // plus: import java.util.Arrays;
  private int lastOffset = -1;
  private int lastLength = -1;

  @Override
  public synchronized void add(int doc, BytesRef value) {
    int index = add(doc);
    if (value.length != lastLength
        || Arrays.equals(values.bytes(), lastOffset, lastOffset + lastLength,
                value.bytes, value.offset, value.offset + value.length) == false) {
      lastOffset = values.length();
      lastLength = value.length;
      values.append(value);
    }
    offsets.set(index, lastOffset);
    lengths.set(index, value.length);
  }
Trade-offs
- Also removes the heap blow-up: one 1 MiB copy instead of 2.2 GB while applying, and the published update's
ramBytesUsed()(:135-143) no longer counts N copies. - Compares with the stored copy, not the caller's
BytesRef, so a reused or re-filledBytesRefis safe;swap()moves offsets and lengths together (:101-112), so shared offsets survive the sort infinish(). - Distinct values (by code reading): with the fix one apply buffer holds at most one copy per buffered update of the field, so no more value bytes than the packet buffered for that field, and those already sit in an
int-addressed structure (FieldUpdatesBuffer.byteValues, aBytesRefArraywithintoffsets over aByteBlockPoolthat advances withMath.addExact;FieldUpdatesBuffer.java:87, 111, 207-210,BytesRefArray.java:34-36, 64-72,ByteBlockPool.java:187-199). So about 2 GiB of distinct values for one field in one packet reaches that buffering limit at the same scale, before any apply; buffering that much takes a RAM buffer above 2 GB or flushing by document count only (FlushByRamOrCountsPolicy.java:34-52). The merge carry-over path (IndexWriter.java:4640-4687) also fills the buffer document by document, where the fix only shares a copy between consecutive equal values; not analysed further. - Cost: one byte comparison per matched document, the size of the copy it replaces, inside the
synchronizedadd(), so it lengthens the locked section; no performance or concurrency benchmark was run. A cheaper first check (same array, offset and length as the last call) is possible but untested. - The end-to-end test needs 8-12 GB of heap (at most a
@Monstertest, likeTest2BBinaryDocValues); the small-heap unit testTestBinaryDocValuesFieldUpdatesSharedValuesuits CI.
What the checks validated
- Stock, gradle, seed
DEADBEEF: the finder's test fails with assertions on and off; the new unit test fails (ramBytesUsed=11320434 for 10240000 bytes of copies); the verifiers' 2,100-document and 530,000 x 4 KiB tests fail, the 100-document control passes. - With the fix: the finder's test passes with assertions on and off (12 GB test heap); the verifiers' tests and both new unit tests pass.
- With the fix: 16 classes, 221 tests, 5 skipped, 0 failures:
TestBinaryDocValuesUpdates,TestNumericDocValuesUpdates,TestMixedDocValuesUpdates,TestSortedNumericDocValuesUpdates,TestDocValuesFieldUpdates,TestFieldUpdatesBuffer,TestBufferedUpdates,TestFrozenBufferedUpdates,TestIncrementalDocValuesUpdates,TestSoftDeletesRetentionMergePolicy,TestSoftDeletesDirectoryReaderWrapper,TestIndexWriterExceptions,TestDocValuesIndexing,TestAtomicUpdate,TestRollingUpdatesand the new unit test. checkGoogleJavaFormat,ecjLintMain,ecjLintTest,forbiddenApisMain,forbiddenApisTestonlucene/core: clean for the changed file, the finder's test and the new unit test (only the verifier tests need reformatting).- Earlier, the finder shadowed the same change onto the stock jars: the repro passes and 136 tests in 10 doc-values-update classes pass.
Store the values as BinaryDocValuesWriter does, in PagedBytes with long offsets.
Trade-offs
Still holds one copy per document (2.2 GB for the repro) while applying, and the iterator (:35-71, one BytesRef and int offsets) has to change. On its own it moves the limit to the heap; for many distinct values it would only matter if the buffering structure were made long-addressed too (by code reading). The first option alone fixes the executed failure.
Check the byte length in add and throw a descriptive exception, like the entry-count guard (DocValuesFieldUpdates.java:375-379).
Trade-offs
A guard inside add() still throws inside the apply event, so the writer still closes and the data is still lost; only the message improves. Rejecting the update cleanly would need a check outside the tragic event path, which is hard because the number of matched documents is known only during the apply, not when the update is buffered.
Not a Lucene security issue (the application controls the update); a service that lets its users trigger binary doc-values updates by a shared term should bound documents matched times value size until this is fixed.
While building a grid-based translation-validation check of the doc-values update buffers against a simple model (randomized values, 2,393,731 checks, no mismatch), the finder noticed that the value buffer is one int-sized array whose limit no small-scale check can reach. It then drove one public-API update to that limit, and the commit failed and closed the writer.
The method in full140 words
Method: semi-formal. In a hunt unit on packed, mutable and paged structures, the finder wrote a grid-based translation-validation harness (randomized operations and values) for the doc-values update buffers on the real jar: BinaryDocValuesFieldUpdates offsets, lengths and values checked against a TreeMap model, up to 4,097 updates per buffer and values up to 306 bytes, 2,393,731 checks, 0 mismatches.
- While modelling it, the finder noted that the value buffer is one
BytesRefBuilderwith anintlength, a bound no small-scale check can reach, and that applying one update callsaddonce per matched document with the same value. - The hypothesis was witnessed with a public-API JUnit on the stock main jar (2,100 documents x 1 MiB), then on 10.5.2, 9.12.3, 8.11.4, 8.0.0 and 7.6.0. No model checker or prover found the overflow itself; the model only pointed at the unchecked bound.
No prior report found (searched 2026-10-28 in GitHub issues, PRs and commits, the JIRA archive, the dev@, java-user@, issues@ and commits@ lists, downstream trackers and the web; re-checked the same day). Nearest: LUCENE-5248 (#6312) on the heap cost of updates matching many documents, and LUCENE-7538 (#8589), the same kind of overflow for stored fields.
Searches3 searches
Verdict new: no issue, PR, commit, list thread, JIRA entry or downstream report describes this overflow or the writer close, and nothing upstream fixes it. Other context: #6576 (LUCENE-5513, introducing), #6653 (LUCENE-5591, a performance remark on the same append), #7968 (LUCENE-6910, the entry-count guard), #15330, #16867 and elastic/elasticsearch#160939 (overflows of other IndexWriter buffers; on #15330 a maintainer wrote "the limits on IndexWriter are 2GB"), #16570 (removed a different, merge-time buffer), #8919 (LUCENE-7868, made apply failures tragic). Gaps: GitHub search caps results per query, the JIRA archive is frozen, private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; dev@, java-user@, issues@, commits@; JIRA archive; downstream repositories; web | 2026-10-28 | the hunt's prior-report tool, three runs of 63 queries (identifiers and symptoms; public API; history and memory amplification), e.g. BinaryDocValuesFieldUpdates, updateBinaryDocValue, "binary doc values update", BytesRefBuilder, applyUpdatesPacket, "likely integer overflow", 2GB, tragic | 780 hits, none the same bug; nearest #6312 / LUCENE-5248 and #8589 / LUCENE-7538 |
| GitHub-wide; apache/lucene, elastic/elasticsearch, opensearch-project/OpenSearch, apache/solr; JIRA (LUCENE, SOLR); open PRs; history | 2026-10-28 | about 60 manual GitHub searches, 12 JQL queries, 15 list queries, 18 web queries, the changed-file lists of all 411 open apache/lucene PRs (one, #16911, reaches the API's 3,000-file cap, so its list may be incomplete), git log -S/--grep on the five files involved | no report; no open PR touches BinaryDocValuesFieldUpdates or changes apply-failure handling |
| apache/lucene issues and PRs; the file's upstream commit list | 2026-10-28 (twice) | updateBinaryDocValue; BinaryDocValuesFieldUpdates (PRs); "binary doc values update overflow"; "likely integer overflow"; PRs updated since 2026-10-27, issues created since 2026-10-26, open PRs created since 2026-10-28 | nothing new; BinaryDocValuesFieldUpdates.java last changed upstream in #11923 (2022-11-15) |
Introduced with updateBinaryDocValue itself (LUCENE-5513, c5263086b4d / 019b0c879cb, 2014-03-18), first released in 4.8.0. Every release executed from 4.8.0 to 10.5.2, and main, fails; before 7.0.0 the writer stays open but stuck instead of closing, and from 7.7.0 a lone update fails at half the size.
Versions tested7 rows
Introduced by LUCENE-5513 (#6576), "add IndexWriter.updateBinaryDocValue", @shaie, 2014-03-18: c5263086b4d on trunk and 019b0c879cb on branch_4x (the copy in 4.8.0); committed from a JIRA patch, no pull request, reviewed in the issue by @mikemccand. That commit already appended one copy of the value per matched document to one int-addressed BytesRef; later edits of add() only reshaped it (LUCENE-5706, LUCENE-5864, LUCENE-7868, LUCENE-8282/8289, LUCENE-9570); the file's last upstream change, #11923, only added a cast in ramBytesUsed().
Two later changes altered the consequence, not the defect: LUCENE-7868 (#8919, 58105a203a1, 2017, 7.0.0) made an apply failure tragic, so the writer closes instead of staying open but stuck; LUCENE-8590 (#9636, 7.7.0) applies the first update of a field in a packet twice (the separate bug LFV-837), which halves the threshold.
Releases not executed contain the introducing commit by tag ancestry and keep the per-document append; the Git blob of BinaryDocValuesFieldUpdates.java is identical across 7.4.0-8.8.1 and across 9.12.3, 10.0.0-10.5.2 and main. 8.8.2-8.11.4 are not tagged in the history clone (8.11.4 ran from its published jars; 8.8.2-8.11.3 are inferred). Not fixed upstream as of 20ced71c1e6e (2026-10-27); branch_10x and branch_10_6 have the same file (read), and 10.6.0 was released from branch_10_6 (4ae946e5a9b) with the same blob, so it has the bug too.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | 2,100 x 1 MiB and 530,000 x 4 KiB fail, assertions on and off; 1,100 x 1 MiB fails; 1,000 x 1 MiB passes; writer closes |
| 10.5.2, 9.12.3, 8.11.4, 8.0.0 | affected | 2,100 x 1 MiB fails, writer closes; 10.5.2 also 530,000 x 4 KiB |
| 7.7.0, 7.7.3 | affected | 2,100 x 1 MiB fails; 7.7.0 also 1,100 x 1 MiB (first with LUCENE-8590) |
| 7.0.0, 7.6.0 | affected | 2,100 x 1 MiB fails, writer closes (7.0.0 first with LUCENE-7868); on 7.6.0, 2,000 and 1,100 x 1 MiB pass |
| 4.8.0, 4.10.4, 5.5.5, 6.6.6 | writer stuck | 2,100 x 1 MiB fails; the writer stays open, but a second commit and close() throw the same exception; the update and the uncommitted document are lost |
| 4.7.2 | not affected | no updateBinaryDocValue (the probe does not compile) |
fix, scratch worktree at a9779ef3c193 | not affected | 2,100 x 1 MiB and 530,000 x 4 KiB commit; 221 tests in 16 classes pass |
The finder, an independent reproducer, a devil's-advocate checker and an adjudication reproduced it on main with and without assertions; a cross-model review (OpenAI GPT-5.6) read the code and agreed but could not run Java. This doc re-ran it with gradle on main a9779ef3c193 and validated the fix.
Checks and verdicts337 words
All checks ran on main a9779ef3c193. Neither cross-model review could execute Java, so those verdicts rest on reading plus separate re-runs. After this doc was drafted, an independent fact check re-ran the repro, the fix and an FSDirectory variant, a cross-model fact check (reading only) reviewed every claim, and a diagram check ran CheckIndex after the close (clean); their corrections are in this version.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Public-API JUnit fails on main (on and off), 10.5.2 and 9.12.3; main() form fails on 8.11.4, 8.0.0 and 7.6.0; fix sketch shadowed: the commit succeeds and 136 doc-values-update tests pass. |
| cross-model review (refute lens) | not real (low), on procedure only | OpenAI GPT-5.6: no command could start; not a review. |
| independent reproducer | real | Own JUnit with a fully default config fails on main, 10.5.2 and 9.12.3; the 100-document control passes; 1,100 x 1 MiB fails; a new writer opens after the close. |
| cross-model review (intended lens) | real (medium) | OpenAI GPT-5.6, reading only: rated the intended-behaviour case weak and agreed on the root cause; a separate run re-ran the repro (fails) and a 1,000-document control (passes). |
| devil's advocate | real (medium-high) | Built eight intended-behaviour arguments and rebutted them; only the close itself is intended. Own test: 530,000 x 4 KiB fails on main and 10.5.2; 200,000 passes. |
| adjudication | confirmed (high) | Re-ran the reproducer's test on a clean main with assertions on and off: fails; the control passes. Crash, not security-sensitive. |
| security screen | not security-sensitive | The application controls the update; the failure is a detected exception and a writer close, outside SECURITY.md's in-scope cases. |
| registry re-runs and audit | still reproduces | The finder's test (assertions off) and the 530,000 x 4 KiB test (assertions on) fail on main with new seeds. |
| this doc's runs | reproduced; fix validated | Gradle in a scratch worktree: stock fails (on and off); with the fix the repros pass and 221 tests in 16 classes pass; lint clean for the fix. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 545 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,534 words
- Registry title
- A binary doc-values update whose term matches many documents copies its value once per matched document into one int-sized buffer when it is applied, so at 2^31 bytes in one segment (about 2^30 for the first update of a field in a packet) commit throws ArrayIndexOutOfBoundsException (AssertionError with -ea) and IndexWriter closes itself, losing the update and every uncommitted document (every release since 4.8.0)
- Area
- index / IndexWriter doc-values updates (BinaryDocValuesFieldUpdates value buffer, FrozenBufferedUpdates apply, applyUpdatesPacket tragic close)
- Priority
- Low, rank 286: Needs gigabyte-scale expansion of one binary doc-values update by a shared term, fails loudly and leaves the committed index intact.
- Impact class
- crash
- Impact note
- Applications that call updateBinaryDocValue, updateDocValues or softUpdateDocument(s) with a binary doc-values field, with the default configuration, are hit when the documents one buffered update matches in one segment times the value length reach 2^31 bytes (2^30 for the first update of its field in a packet, which is the case for a lone update, through the linked double-buffering bug), for example 1 MiB on 1,100 documents or 4 KiB on 530,000 documents [exec]: the commit (or flush or NRT open) that applies it throws, the writer closes itself and the update plus every acknowledged uncommitted document is lost, while the index is not corrupted and a new writer opens on the last commit [exec]; no RAM-buffer setting prevents it, because only the one value is buffered and the gigabytes arise at apply time.
- Summary
- You commit 2,100 documents that share the term group:g, add one more document, call updateBinaryDocValue(group:g, field, a 1 MiB value) once and commit; the javadoc sets no size limit and says the value replaces the value of all affected documents, and the resulting 2.1 GB of binary doc values is an index Lucene can hold (a build with the fix sketch commits it). Instead, applying the update appends a full copy of the value for every matched document to one int-addressed BytesRefBuilder, which overflows at 2^31 bytes: commit throws ArrayIndexOutOfBoundsException (with -ea, AssertionError 'size must be positive (got -2147483648): likely integer overflow?'), IndexWriter treats it as a tragic event and closes itself, and both the update and the extra uncommitted document are gone. On 7.7.0 and later a lone update fails at half that size (1,100 documents x 1 MiB) because of the linked bug that applies the first update of a field twice, and ordinary value sizes suffice too (530,000 documents x 4 KiB).
- Introduced
- c5263086b4da47ae0331678f1ec64dc1e7e3577b (trunk, svn r1578784) and its branch_4x backport 019b0c879cb (svn r1578790, the commit that shipped in 4.8.0), 'LUCENE-5513: add IndexWriter.updateBinaryDocValue' (committed from a JIRA patch, no GitHub PR; issue now apache/lucene#6576; author shaie, reviewed in the issue by mikemccand) [read: that commit already appended one full copy of the value per matched document to a single int-addressed BytesRef (offsets.set(size, values.length); values.append(val)), called once per matched document by BufferedUpdatesStream.applyDocValuesUpdates; git log -L on add() shows only reshaping edits since (LUCENE-5706, LUCENE-5864 BytesRef to BytesRefBuilder, LUCENE-7868, LUCENE-8282/8289, LUCENE-9570 reformat, #11923)] [exec: 4.7.2 lacks the API (compile error), 4.8.0 fails]. Two later changes altered the consequence, not the defect: 58105a203a1 (LUCENE-7868, #8919, 2017-06-21, 7.0.0) made an apply failure a tragic event, so the writer closes instead of staying open but stuck [exec boundary: 6.6.6 stuck, 7.0.0 closed]; b0e6a92ede3 / eaf840867fa (LUCENE-8590, #9636, 2018-12-04, 7.7.0) applies the first update of a field in a packet twice, halving the threshold [exec boundary: 1,100 x 1 MiB passes on 7.6.0, fails on 7.7.0] (2014-03-18 (author and commit date of c5263086b4d, 08:56 UTC, and 019b0c879cb, 09:25 UTC))
- First affected version
- 4.8.0 [exec] (the release that introduced updateBinaryDocValue; 4.7.2 has no such API [exec: compile error]); 4.8.0-6.6.6 leave the writer open but stuck (every later commit and close() throw, close() rolls back) [exec: 4.8.0, 4.10.4, 5.5.5, 6.6.6]; the writer closes itself from 7.0.0 [exec]
- Affected versions
- every release with binary doc-values updates, 4.8.0 through 10.6.0 (10.6.0 by reading), and main a9779ef3c193 [exec: the canonical 2,100 x 1 MiB scenario fails on 4.8.0, 4.10.4, 5.5.5, 6.6.6 (-da and -ea), 7.0.0, 7.6.0, 7.7.0, 7.7.3, 8.0.0, 8.11.4, 9.12.3, 10.5.2 and main (-ea and -da), in the finder's, the independent reproduction's, the adjudication's, the follow-up's and the registration check's runs; the intended-behaviour check's 530,000 x 4 KiB fails on main (-ea, -da) and 10.5.2]; the other releases by tag ancestry and an identical class blob across 7.4.0-8.8.1 and across 9.12.3, 10.0.0-10.5.2 and main [read]; 8.8.2-8.11.3 are not in the history clone and are inferred; not fixed upstream: upstream main 20ced71c1e6e, branch_10x and branch_10_6 have the same BinaryDocValuesFieldUpdates.java blob, last changed 2022-11-15 [read, 2026-10-28], so the released 10.6.0 has it too. All runs on aarch64 with JDK 25
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: code reading
- Upstream and prior reports
- none found (the prior-report record, verdict new, searched 2026-10-28, read-only): three scripted prior-report searches of 63 queries each over GitHub issues, PRs and commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web, plus about 60 manual GitHub searches, SOLR and LUCENE JQL, 18 web queries, the changed files of all 411 open apache/lucene PRs and the git history; also the finder's 51-query run and the intended-behaviour check's 24-query run; re-checked (2026-10-28: no PR after #16926, #16919 touches other classes, no issue since 2026-10-26 is related, BinaryDocValuesFieldUpdates.java last changed upstream 2022-11-15). No issue, PR, commit, list thread, JIRA entry or downstream report covers the overflow of this buffer or the writer close it causes. Nearest items, not this bug: #6312 (LUCENE-5248, 2013: an update resolving to millions of documents is accepted to cost a lot of RAM, before binary updates existed), #6576 (LUCENE-5513, introducing, no size discussion), #6653 (LUCENE-5591, a performance remark on the same append), #7968 (LUCENE-6910, entry-count guard only), #8589 (LUCENE-7538, the analogous stored-field overflow, fixed by rejecting the field), #16570 (merged 2026-09, a different merge-time buffer), #15330 and elastic/elasticsearch#160939 (ByteBlockPool overflows at buffering time) and #16867 (merged 2026-10-30 as 2813efa40a3 on main and cdfe8aa7829 on branch_11x, not on branch_10_6: caps the shared delete buffer at buffering time, changing only DocumentsWriterFlushControl and FlushByRamOrCountsPolicy; it does not touch BinaryDocValuesFieldUpdates or FrozenBufferedUpdates, and the repro still fails on main e1faeba08bd, -ea and -da), #8919 (LUCENE-7868, made the apply failure tragic).
- Lucene commit tested
- main
a9779ef3c193(2026-10-26) with gradle in a clean scratch worktree, stock and with the fix, assertions on and off (repros, 16 test classes, format and lint checks); the standalone JUnit runner on the built jars (finder, verifiers, judge and registry re-runs); published release jars 4.8.0, 4.10.4, 5.5.5, 6.6.6, 7.0.0, 7.6.0, 7.7.0, 7.7.3, 8.0.0, 8.11.4, 9.12.3 and 10.5.2 (follow-up history runs; 8.0.0 by the finder); 4.7.2 has no such API. The fact check also ran the repro withFSDirectory(fails the same way) and the diagram check ranCheckIndexafter the close (clean). Upstream main20ced71c1e6e(2026-10-27) has the sameBinaryDocValuesFieldUpdates.java(read). All runs on aarch64 with JDK 25.0.3.
- Finding record
lucene/core/src/java/org/apache/lucene/index/BinaryDocValuesFieldUpdates.java:63 (at a9779ef3c193) (Iterator.set: offset = (int) offsets.get(idx)), :80 (values = new BytesRefBuilder()), :94-99 (add(int, BytesRef): offsets.set(index, values.length()); lengths.set(index, value.length); values.append(value))lucene/core/src/java/org/apache/lucene/util/BytesRefBuilder.java:77-81 (at a9779ef3c193) (append: grow(ref.length + len) in int, then System.arraycopy) and util/ArrayUtil.java:445-449 (grow: assert minSize >= 0 'likely integer overflow?'; returns the array unchanged when minSize is negative)lucene/core/src/java/org/apache/lucene/index/FrozenBufferedUpdates.java:224-342 (at a9779ef3c193) (applyDocValuesUpdates: one BinaryDocValuesFieldUpdates per field and segment per packet, :305-309; :319 docIdConsumer = doc -> update.add(doc, binaryValue) for every matched document)lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:162-165 (at a9779ef3c193) (class NOTE: closes itself on an Error or a checkpoint disaster), :1981-1996 (updateBinaryDocValue javadoc: no size limit; 'replaces the existing value of all affected documents'), :2070 (updateDocValues), :2928-2946 (publishFrozenUpdates: catch (Throwable t) { w.onTragicEvent(t, "applyUpdatesPacket"); throw t; })lucene/core/src/java/org/apache/lucene/index/DocValuesFieldUpdates.java:375-379 (at a9779ef3c193) (explicit guard on the entry count only) and ReadersAndUpdates.java:153-161 (addDVUpdate: resolved updates enter the RAM accounting only when published)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/index/FrozenBufferedUpdates.java:224-360 (at a9779ef3c193) (288-295, 307-308, 319, 336-345, 351-357)lucene/core/src/java/org/apache/lucene/index/BinaryDocValuesFieldUpdates.java:63, (at a9779ef3c193) 80, 94-99lucene/core/src/java/org/apache/lucene/util/BytesRefBuilder.java:77-80; (at a9779ef3c193) util/ArrayUtil.java:445-449lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:2928-2946, (at a9779ef3c193) 3809, 3819, 3821, 3879-3884, 6090-6105; util/ArrayUtil.java:145-152lucene/core/src/java/org/apache/lucene/index/ReadersAndUpdates.java:153-161; (at a9779ef3c193) index/DocValuesFieldUpdates.java:375-379
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:162-165, (at a9779ef3c193) 1981-1996, 2059-2070, 2106-2124; index/IndexWriterConfig.java:373-385lucene/core/src/java/org/apache/lucene/index/BinaryDocValuesWriter.java:40-45, (at a9779ef3c193) 61, 81-83; util/ArrayUtil.java:446; index/DocValuesFieldUpdates.java:375-379lucene/core/src/java/org/apache/lucene/document/BinaryDocValuesField.java:26-28; (at a9779ef3c193) index/BinaryDocValuesFieldUpdates.java:31
- Suggested fix
lucene/core/src/java/org/apache/lucene/index/BinaryDocValuesFieldUpdates.java:35-71, (at a9779ef3c193) 94-99, 101-112, 135-143; index/FrozenBufferedUpdates.java:336-345; index/FieldUpdatesBuffer.java:87, 111, 207-210; util/BytesRefArray.java:34-36, 64-72; util/ByteBlockPool.java:187-199; index/FlushByRamOrCountsPolicy.java:34-52; index/IndexWriter.java:4640-4687; index/DocValuesFieldUpdates.java:375-379
- TestBinaryDocValuesUpdateBufferOverflow.java (lucene/core, 1 test):
repro/LFV-838/TestBinaryDocValuesUpdateBufferOverflow.java(100 lines) - TestBinaryDvUpdateManyDocs.java (default IndexWriterConfig; 2,100 docs and a 100-doc control):
repro/LFV-838/TestBinaryDvUpdateManyDocs.java(172 lines) - TestModerateValueBinaryUpdate.java (530,000 docs x 4 KiB):
repro/LFV-838/TestModerateValueBinaryUpdate.java(84 lines) - TestBinaryDocValuesFieldUpdatesSharedValue.java (small-heap unit test):
repro/LFV-838/TestBinaryDocValuesFieldUpdatesSharedValue.java(116 lines)
Made in parallel from the executed runs on main (the repro's 2,100 x 1 MiB scenario, the stack trace and the fixed run); the PNG is the summary frame.
assets/LFV-838/bug.png(545 KB)