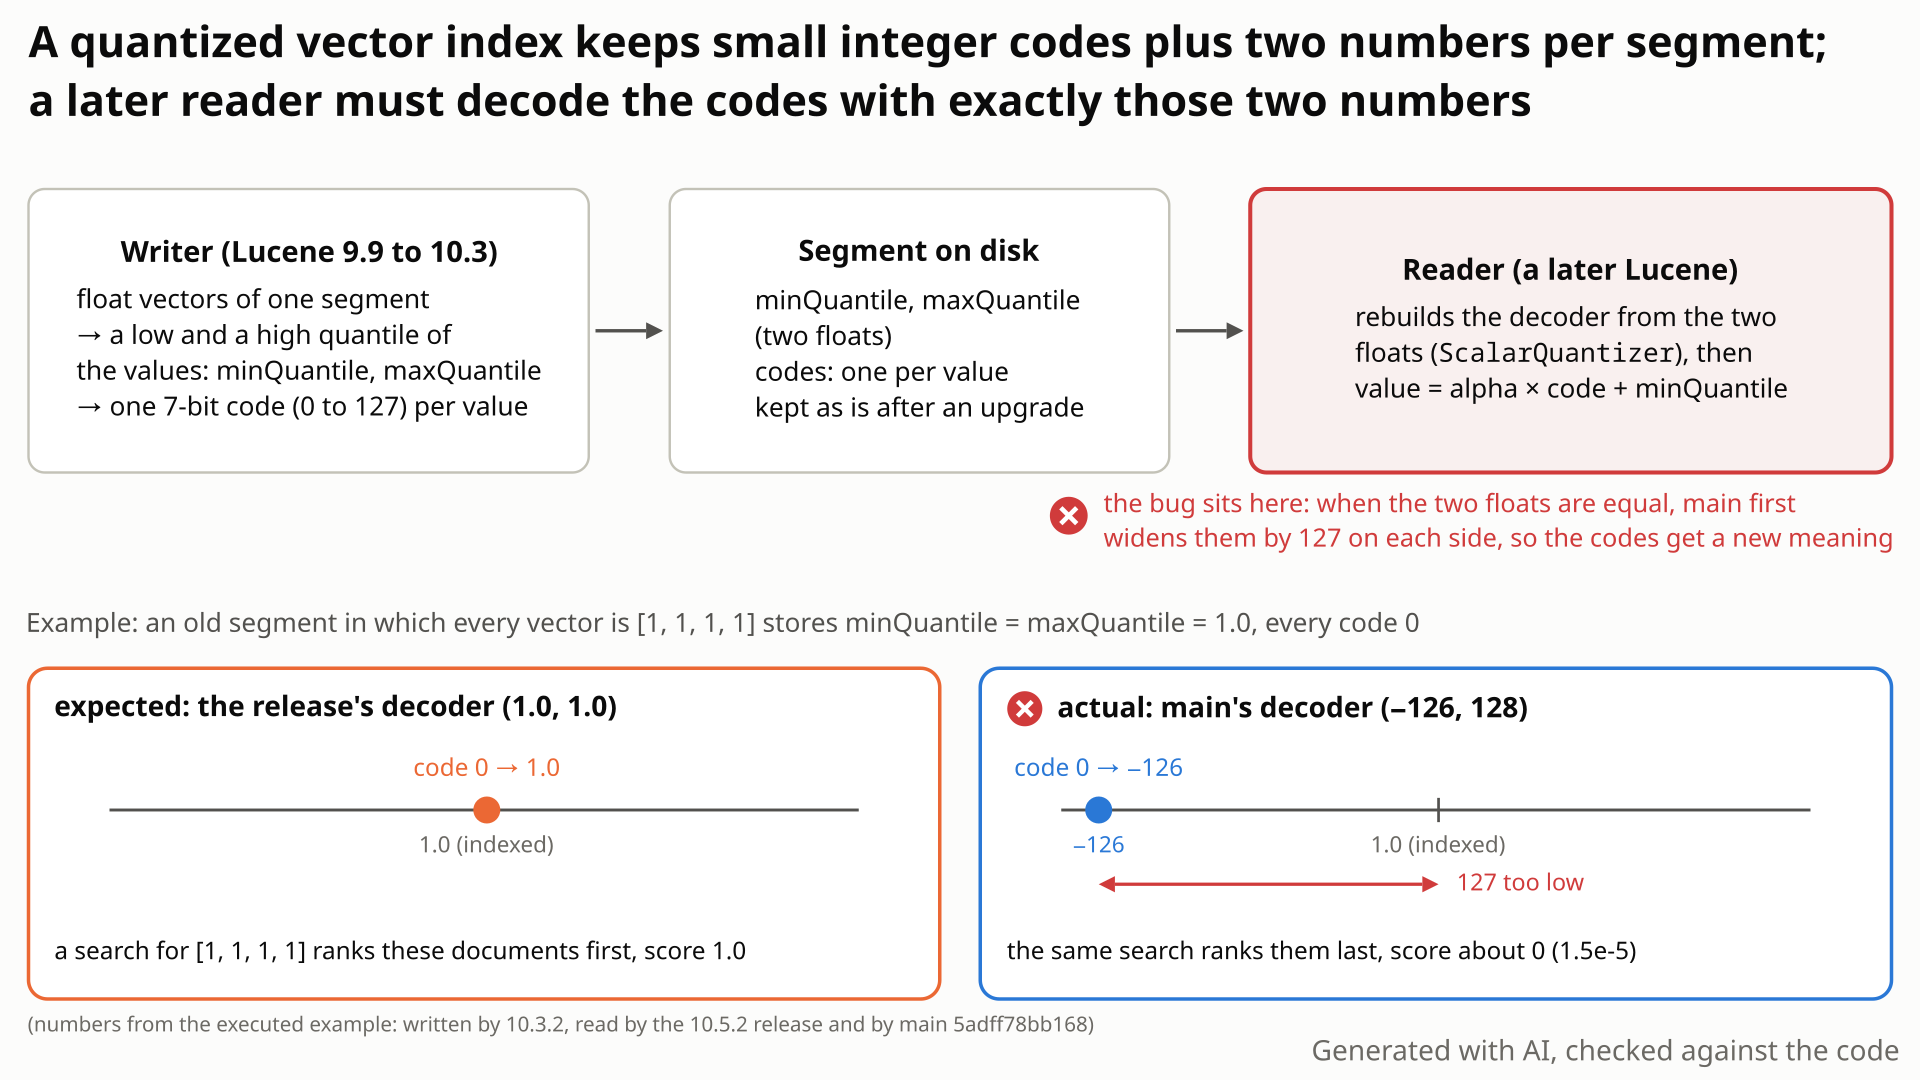
A segment's stored codes mean what that segment's stored quantiles say. Lucene 11 reads one kind of old segment with different quantiles.
- Scalar quantization stores each vector component as a small integer code (0 to 127 for int7) plus two numbers per segment, the lower and upper quantile. Code c means min + c × (max - min) / 127.
- If every component of every vector in a segment has the same value q, both quantiles are q (near-constant data can give equal quantiles too, because the writer clips the extreme values). The 9.9 to 10.3 writers then store every code as 0, which means q.
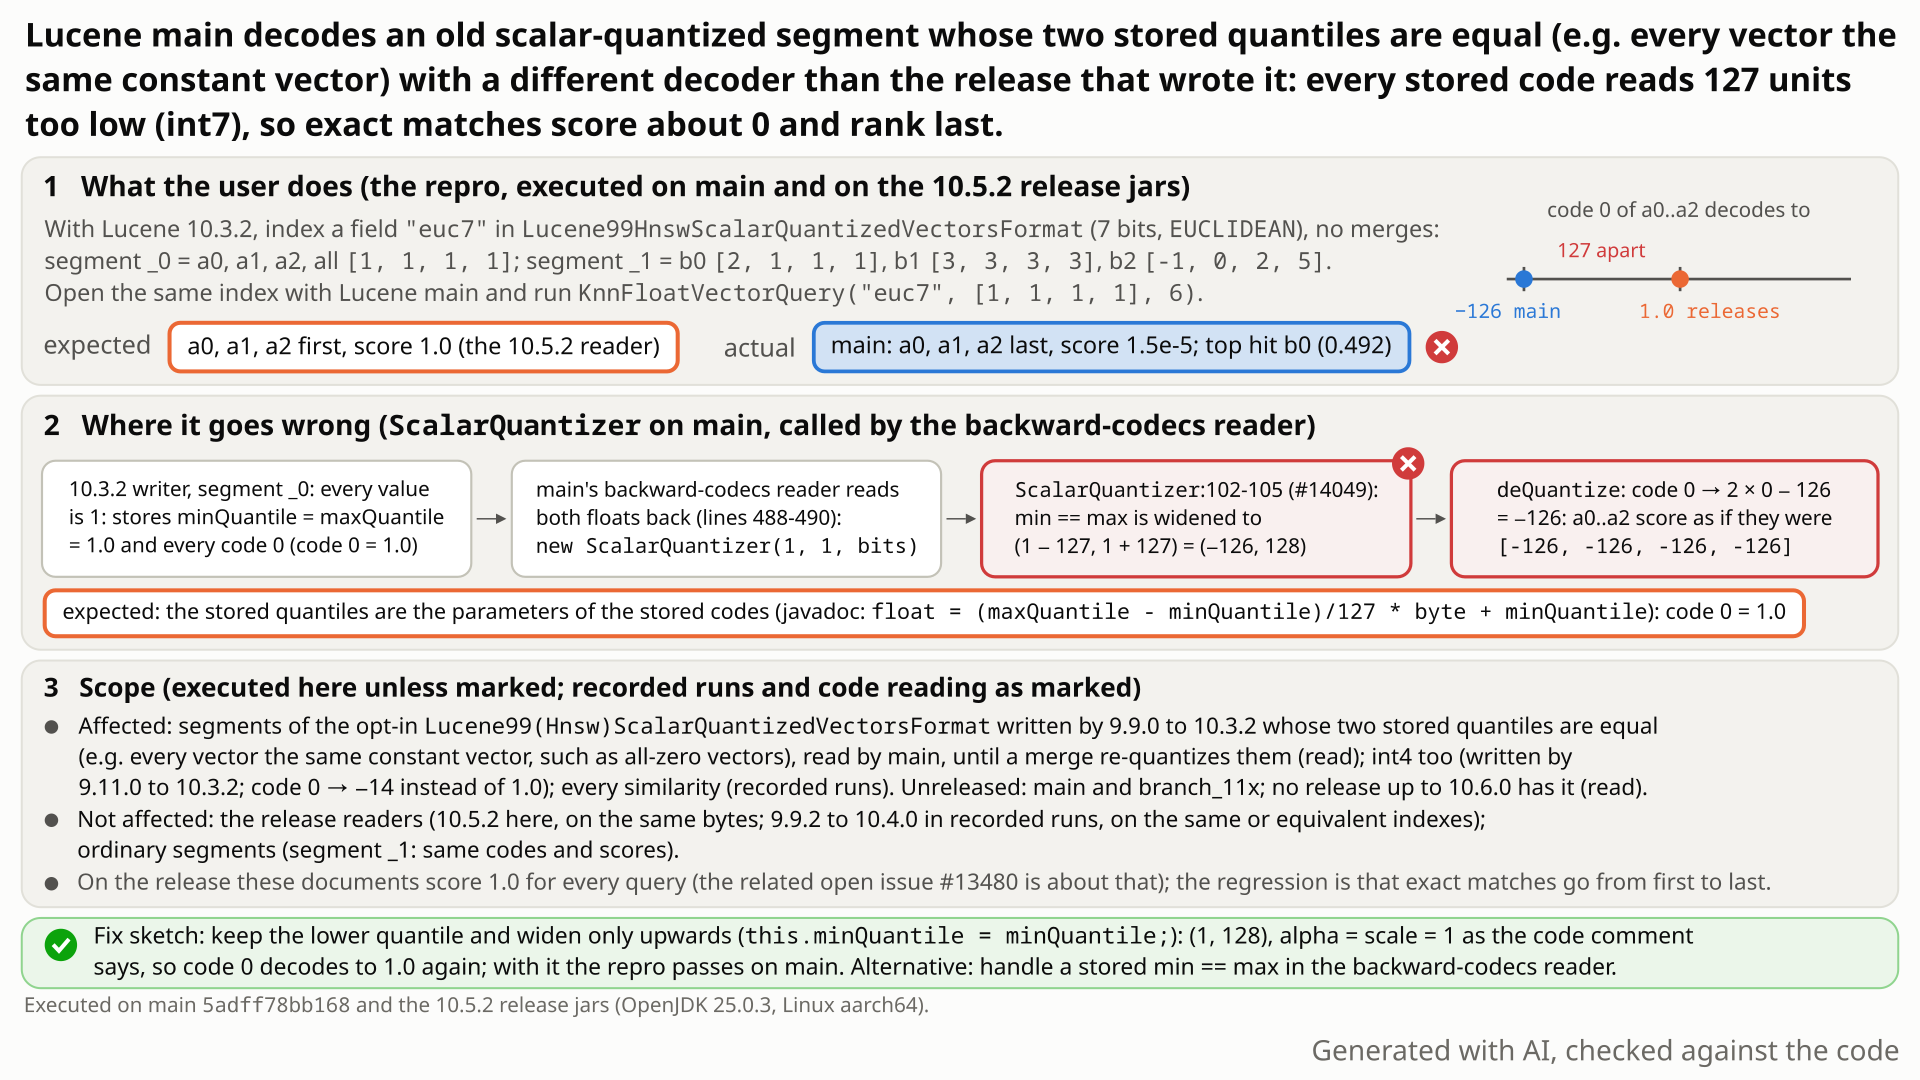
ScalarQuantizer constructor, which widens them to (-126, 128), so code 0 reads as -126 instead of 1.0 and the exact matches drop from first to last. Select the still to open it at full size. Generated with AI, checked against the code.- With Lucene 10.3.2 you index vectors with the opt-in
Lucene99HnswScalarQuantizedVectorsFormat(int7, EUCLIDEAN). One segment holds three documents whose vector is[1, 1, 1, 1]; another holds b0 =[2, 1, 1, 1]and two more. - Every value in the first segment is 1, so the writer stores both quantiles as 1 and every code as 0, which means 1.0. Lucene 10.3.2 and 10.6.0 search
[1, 1, 1, 1]and rank the three exact matches first with score 1.0, then b0 with 0.49. - You open the unchanged index with Lucene 11 and run the same query. You expect the same ranking.
- Instead the reader rebuilds the quantizer through a constructor that now widens equal quantiles to (1 - 127, 1 + 127) = (-126, 128). Code 0 now means -126, so the exact matches score 0.0000153 and rank last; b0 ranks first.
- No error. int4 fields are off by 15 instead of 127, and DOT_PRODUCT and COSINE exact matches score 0.0. Segments with ordinary vectors score as before, and a merge should clear it.
Users of the opt-in Lucene99 scalar-quantized formats (int7 written by 9.9.0-10.3.x, int4 by 9.11.0-10.3.x, any similarity) who open the index, unmerged, with Lucene 11. Only segments whose two stored quantiles are equal are hit, for example a segment of one constant vector or of all-zero placeholders; ordinary segments score exactly as before.
Mechanism, terms and numbers560 words
Lucene99(Hnsw)ScalarQuantizedVectorsFormat stores each vector as small integer codes plus two numbers per segment, the lower and upper quantile. When a segment's two stored quantiles are equal, for example because every vector of the field is the same constant vector, the 9.9-10.3 writers store (q, q) and every code as 0, which the documented formula decodes as q; every release reader (9.9.2 to 10.6.0 tested, on the same or equivalent indexes) does so. On Lucene 11 (main and branch_11x, unreleased) the backward-codecs reader rebuilds the quantizer through the public ScalarQuantizer constructor, which since #14049 widens equal quantiles to (q - 127, q + 127) (int4: q - 15, q + 15). Code 0 then decodes 127 (or 15) units too low, and exact and near matches in that segment score about 0 and rank last: 0.0000153 instead of 1.0 for [1, 1, 1, 1]. No error; ordinary segments are unaffected and a merge should clear it. Keeping the lower quantile in that branch fixes it.
- What the old writer stored. For a segment whose vectors are all
[1, 1, 1, 1], the 10.3.2 writer stores minQuantile = maxQuantile = 1.0 and every code 0. The documented decode,float = (maxQuantile - minQuantile)/127 * byte + minQuantile(ScalarQuantizer.java:51), gives 1.0. The release constructor has no special case: scale = 127/0 = +Infinity and alpha = 0. Each value is clamped to [1, 1], so its offset from minQuantile is 0 andMath.round(Infinity × 0)=Math.round(NaN)= 0: every code is 0. With alpha = 0 every EUCLIDEAN query scores these documents 1.0 (#13480). - Lucene 11 reads both floats back unchanged in
Lucene99ScalarQuantizedVectorsReader.FieldEntry.createand callsnew ScalarQuantizer(minQuantile, maxQuantile, bits)(:481-483,:488-490). - The constructor widens them. Since #14049,
if (minQuantile == maxQuantile)setsminQuantile - divisorandmaxQuantile + divisor, with divisor = 127 for 7 bits and 15 for 4 bits (ScalarQuantizer.java:101-105). For (1, 1) that is (-126, 128), alpha = 2 and scale = 0.5 (:110-111). The comment says this "leads to alpha = scale = 1" (:103). - Code 0 now means -126.
deQuantizecomputesalpha * code + minQuantile= 2 × 0 - 126 (:165-168). The scorer quantizes the query with the same parameters (Lucene99ScalarQuantizedVectorScorer.java:62-76):[1, 1, 1, 1]becomes codes 64 against stored codes 0, and the EUCLIDEAN score1 / (1 + squareDistance × alpha²)(:163-165) is 1 / (1 + 4 × 64² × 4) = 0.0000153. With the Panama provider,Lucene99MemorySegmentScalarQuantizedVectorScoreruses the same quantizer and multiplier, so the scores are identical. A query[-126, -126, -126, -126]scores those documents exactly 1.0.
| field (10.3.2 writer) | exact-match score, 10.3.2 and 10.6.0 | on Lucene 11 |
|---|---|---|
EUCLIDEAN int7, [1, 1, 1, 1] | 1.0, rank 1 | 0.0000153, rank 6 of 6 |
| MAXIMUM_INNER_PRODUCT int7 | 5.0 | 0.0000305 |
DOT_PRODUCT and COSINE int7, [0.5, 0.5, 0.5, 0.5] | 1.0 | 0.0 |
| EUCLIDEAN int4 (plain, packed, dynamic interval) | 1.0 | 0.000976 |
In every field the ordinary segment gets the same codes and scores on Lucene 11 as on its writer. On main this branch has no production writer behind it (the Lucene99 scalar-quantized writer is only in test sources since #15223, and no Lucene production code calls the public fromVectors factories), so its only production effect in Lucene is on segments written by releases.
Exposure and likelihood303 words
- Who is exposed. Users of the opt-in
Lucene99HnswScalarQuantizedVectorsFormatorLucene99ScalarQuantizedVectorsFormat(any similarity) whose index was written by the releases that write the format, int7 by 9.9.0-10.3.x and int4 by 9.11.0-10.3.x (int4 needs format version 1, added by #13197), and who open it with Lucene 11 without reindexing. CHANGES says that is supported: "Indexes created with 9.x remain fully supported in Lucene 11, no reindexing required" (GITHUB#16741). Not the default codec. - What it takes. A segment whose two stored quantiles are equal. The demonstrated case is a segment in which every vector of the field is identical: a constant vector (normalized, with equal components, for DOT_PRODUCT or COSINE), all-zero placeholder vectors, or a one-document segment with such a vector. One ordinary vector, or zeros mixed with 4-20% dense vectors, does not give equal quantiles. Near-constant data can: the quantile step clips the extreme values, so
[1, 1, 1, 1],[1, 1, 1, 1],[1, 1, 1, 5]at dimension 4 give (1, 1) on 10.3.2 and every code 0 (executed). No scale needed. A merge should clear it, since the legacy reader exposes the raw floats and the current writer re-quantizes them (code reading; no run merges such a segment). - What goes wrong. Silent wrong scores: exact and near matches in that segment drop from first to last. Same with assertions on and off, and with the Panama and the default vector provider.
- Honest scope. On the writing release these documents already score 1.0 for every EUCLIDEAN query (#13480), so Lucene 11 is not worse for every query: for all-zero placeholders, ranking them low is arguably closer to the truth. The clear harm needs identical (or near-constant) non-trivial vectors queried near them. Hence likelihood contrived and priority Low. No release has it yet; the patch is small but changes a public constructor.
One JUnit test, one method, public API: it unzips a two-segment index written by Lucene 10.3.2 and searches [1, 1, 1, 1]. It fails on main with assertions on and off and passes on the 10.3.2, 10.5.2 and 10.6.0 jars.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.backward_index;

import java.io.ByteArrayInputStream;
import java.nio.file.Path;
import java.util.Base64;
import java.util.Locale;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.KnnFloatVectorQuery;
import org.apache.lucene.search.ScoreDoc;
import org.apache.lucene.search.TopDocs;
import org.apache.lucene.store.Directory;
import org.apache.lucene.store.FSDirectory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

/**
 * INDEX_10_3_2 is a zip of an index written by Lucene 10.3.2 with
 * Lucene99HnswScalarQuantizedVectorsFormat (7 bits, default confidence interval): one EUCLIDEAN
 * field "euc7" with 4 dimensions, a stored "id", two segments, no merges.
 *
 * <ul>
 *   <li>segment _0: a0, a1, a2, each [1, 1, 1, 1], so the writer stored the quantiles (1, 1);
 *   <li>segment _1: b0 = [2, 1, 1, 1], b1 = [3, 3, 3, 3], b2 = [-1, 0, 2, 5].
 * </ul>
 *
 * <p>For the query [1, 1, 1, 1], a0..a2 are exact matches; Lucene 10.3.2 ranks them first with
 * score 1.0, b0 (distance 1) next with 0.49.
 */
public class TestOldUniformQuantizedSegment extends LuceneTestCase {

  static final String INDEX_10_3_2 =
      "UEsDBBQAAAAIAAAAZF0Z8/9/9wAAAL0CAAAGAAAAXzAuY2Zls7+eIy7uU5qcmpdqaeCcn1uQX5qX4ppXUpSZWswABF"
          + "/+XbOs2D7hyQwppydB9ZZMDPwsemkpFQYMEOAApQXiIWYYGhjHG+il5CcXQCX8sSooySw4AJUIwqEgV4IRIhGBVUFB"
          + "cW4BVEEGVAHIYSU30AT1obosLT3yisuDkxNzEosCSxPzSjKrUlPCUpNL8ouK3fKLchNLgIaWpVY4MEH0VZGnv/AAVP"
          + "8UqH4D0vTnpkUwQzTORvJV7g+o4FzyXJU8gwWibwn2wM5NcWCFSKwgz4LcF1D9G8j0duEMNojGLQhv5+UGsEM4MtBI"
          + "PaAx+QUDLN3sZMsEAFBLAwQUAAAACAAAAGRd5XRq7pYCAAB8CAAABgAAAF8wLmNmc7O/niMu4lOanJqXamngnJ9bkF"
          + "+al+KSWJLIAARf/l2zrNg+4ckMKacnQfWWTEAhe6B6MZh6t8zUnJRiz7yU1ArPlAqsOg5oTH7BAAXFUwsDQPqlIPoN"
          + "DYwD8otLMvPSi8OLMktSi1zyk7GZwQ1XHm+AbJzzg7UyYPcIO+XkJ2eHFKWmhqQW5ULcQ8ggBXOYMchGZnyyew9hgc"
          + "wVQjXXJTO5hJCx7CaJBomGiUbsTIysLHUMrKzIpi9LWrgVZK40Dv/7pmIPdmQLGNCAPxZf7FQ6OxVkjwwsnoJL8otS"
          + "UyCx5ZZYXAKNX0bM+OVjYGRgYWBiZAYDBgUGJoVEAzBpCCaNkO2x2a+4DWSPHNQeS4+84vKw1GSgbcVu+UW5iSWwqM"
          + "CwSQtZS3ByYk5iUWBpYl5JZlVqCooJ8QZMjIyMQFcxIdssY5T4FhFPGjDD8BmEy88kuAQ97LGloEeTp2jD3CULM9ot"
          + "J7EExSxcMU2CYxhBnoFammLAwgyk/kMBzC1QLrLz+qOMH8PDTRxLPoa6DDNpNDSwguzgAmJQOYAZGA4OcCZM0gwuwu"
          + "GEIRkBpRkZmZFd2Kxb2U8w/HAVUKRGZoM9KRglL+/ufQoLR7RygphsjJQ9MYoBsCGEDGgAZgpgDmVKNGBKNLJgcApC"
          + "C1Vkt0YdPSaKEp4Y+RRXrJOZHpPYwelRgDETKiCASCYK8GTCCFOOnkinfb76g+h8TWWn50jAsxI7PIEQkbHWT3E6DE"
          + "8PUKtNwPnKMy8tHxSdTBhZiokpMwVY1iIyLpNsQGoRWBMsRUCcqJcGpjjh8Y9LXXFpWlpmBaMByD8sqaXJ5oxIzv3P"
          + "JA/T5p2XhxIGUAs0iA0z3AbBXcDCiJIGjzxb8gyZz7Fv8REAUEsDBBQAAAAIAAAAZF1W9Qsl/AAAADwBAAAFAAAAXz"
          + "Auc2mzv54jLuxTmpyal2ppEJyanpuaV+KZl5bPAARf/l2zrNg+4ckMKacnQfWWTAxcQEFmIGYCYkZkDohm/M/BWZKZ"
          + "m1pckphbwGtobmlsbmpgYgACIlmJZYl6RaV5IHm9stSi4sz8PB4jUz0DPWNtS12fkGBusIqy1LyU/CL20LzsvPzyPK"
          + "b8YlafzLzSCvb8Yr3EouQM9kQQaWbCBeRDDYGp5csBewEmzGYINFnPiK04v7QoOZU1Lae0OIOZLd5ALzktlRVIFWdC"
          + "OMWM8nC/l+QXpaa4ZabmpBS75RflJpbo5eanpHI5uQaHxAcHuLq6MBzQmPyCAQpa56xZAgBQSwMEFAAAAAgAAABkXf"
          + "mG3an3AAAAvQIAAAYAAABfMS5jZmWzv54jLu5Tmpyal2pp4JyfW5BfmpfimldSlJlazAAEX/5ds6zYPuHJDCmnJ0H1"
          + "lmwM/Cx6aSkVBgwQ4AClBeIhZhgaGMcb6KXkJxdAJfyxKijJLDgAlQjCoSBXghEiEQFVALK3pAAqmIFVV0Fx7g00Bf"
          + "pQBZaWHnnF5cHJiTmJRYGliXklmVWpKWGpySX5RcVu+UW5iSVA/WWpFQ5MEH1V5OkvPADVPwWq34A0/blpEcwQjbOR"
          + "vJ37Ayo4lzxXJc9ggehbgj2wc1McWCESK8izIPcFVP8GMr1dOIMNonELwtt5uQHsEI4MNFIPaEx+AZVneL2EkQsAUE"
          + "sDBBQAAAAIAAAAZF184gBNsQIAAHwIAAAGAAAAXzEuY2Zzs7+eIy7iU5qcmpdqaeCcn1uQX5qX4pJYksgABF/+XbOs"
          + "2D7hyQwppydB9ZZsQCF7oHoxmHq3zNSclGLPvJTUCs+UCqw6DmhMfsEABVV1F7VA+qUg+g0NjAPyi0sy89KLw4syS1"
          + "KLXPKTsZnBDVceb4BsXKDkyuVg9wg75eQnZ4cUpaaGpBblQtxDyCAFc5gxyEYG585dDWGBzBVCNdclM7mEkLHsJkkG"
          + "SYZJRuxMjKwsdQysrCim1yd2gsyVgYVfcEl+UWoKJBTdEotLoOHOiBnufAyMDCwMTIzMYMCgwMCkkGQAJg3BpBGyPf"
          + "kzkvpB9kjjCGffVOzRi+wRBjTgjyW0ol6mpYHskYP6x9Ijr7g8LDUZ6Ktit/yi3MQSWFRg+EgLWUtwcmJOYlFgaWJe"
          + "SWZVagqKCfEGTIyMjEDfMyHb3DgvPBgRTxoww/AZhCtsSXBJqJaWFsjOeiCA2B5ajx4mpeqfbsHcJQsz2i0nsQTFLF"
          + "wxQIJjGEGegVqaYsDCDKT+QwHMLVAusvOOHFp3Ch5u4ljyMdRlmEmwoYEVZAcXEDMBMUYCYXBwgDNhkmZwEQ4nDMkI"
          + "KM3IyIzsQlPZVxUEww9XAUVC+EEdzcDQYI/AID8g44b9DHB1CxyQnclb8OgTLBzRyglishdSMYCRPcGGEDKgAZgpgC"
          + "UBU5IBU5KRBYNTEFqoIrv1vvSk4yjhiZFPccU6mekxiR2cHgUYM6ECAohkogBPJoww5eiJ1PFu1l6i8zWVnZ4jAc9K"
          + "7LC4dyAiY12+vPMFPD1ArTYB5yvPvLR8UHQyYWQpJqbMFGCZjsi4TLIBqUVgTbAUAXGiXhqY4oTHPy51xaVpaZkVjA"
          + "Yg/7CkliabMyI59z+TPEybd14eShhALdAgNsxwGwR3AQsjShq8e7dNCJlvckBjDQBQSwMEFAAAAAgAAABkXSYbOIj7"
          + "AAAAPAEAAAUAAABfMS5zabO/niMu7FOanJqXamkQnJqem5pX4pmXls8ABF/+XbOs2D7hyQwppydB9ZZsDFxAQWYgZg"
          + "JiRmQOiGb8z8FZkpmbWlySmFvAa2huaWxuamBiAAIiWYlliXpFpXkgeb2y1KLizPw8HiNTPQM9Y21LXZ+QYG6wirLU"
          + "vJT8IvbQvOy8/PI8pvxiVp/MvNIK9vxivcSi5Az2RBBpZsIF5EMNganlywF7ASbMZgg0Wc+IrTi/tCg5lTUtp7Q4g5"
          + "kt3lAvOa0YQqWyAqniTEZ5uN9L8otSU9wyU3NSit3yi3ITS/Ry81NSuZxcg0PigwNcXV0YDmhMfsEABQWKjnMAUEsD"
          + "BBQAAAAIAAAAZF3K1plcagAAAO4AAAAKAAAAc2VnbWVudHNfMrO/niPOUZyanpuaV1LMwMDA9eXfNcuK7ROezJByeh"
          + "JUb8nJaMTFzMTFAAHsTECCCSjAFG+AppCJ06c0OTUv1dDA+D8UgHT8RwMgMUY0rSxgs5niDdHE2cg3kgPi3gMak19A"
          + "nc7w51rtGgBQSwECFAMUAAAACAAAAGRdGfP/f/cAAAC9AgAABgAAAAAAAAAAAAAApIEAAAAAXzAuY2ZlUEsBAhQDFA"
          + "AAAAgAAABkXeV0au6WAgAAfAgAAAYAAAAAAAAAAAAAAKSBGwEAAF8wLmNmc1BLAQIUAxQAAAAIAAAAZF1W9Qsl/AAA"
          + "ADwBAAAFAAAAAAAAAAAAAACkgdUDAABfMC5zaVBLAQIUAxQAAAAIAAAAZF35ht2p9wAAAL0CAAAGAAAAAAAAAAAAAA"
          + "CkgfQEAABfMS5jZmVQSwECFAMUAAAACAAAAGRdfOIATbECAAB8CAAABgAAAAAAAAAAAAAApIEPBgAAXzEuY2ZzUEsB"
          + "AhQDFAAAAAgAAABkXSYbOIj7AAAAPAEAAAUAAAAAAAAAAAAAAKSB5AgAAF8xLnNpUEsBAhQDFAAAAAgAAABkXcrWmV"
          + "xqAAAA7gAAAAoAAAAAAAAAAAAAAKSBAgoAAHNlZ21lbnRzXzJQSwUGAAAAAAcABwBuAQAAlAoAAAAA";

  public void testExactMatchRanksFirst() throws Exception {
    Path path = createTempDir("old-sq-index");
    TestUtil.unzip(new ByteArrayInputStream(Base64.getDecoder().decode(INDEX_10_3_2)), path);
    try (Directory dir = FSDirectory.open(path);
        DirectoryReader reader = DirectoryReader.open(dir)) {
      IndexSearcher searcher = new IndexSearcher(reader);
      float[] query = {1f, 1f, 1f, 1f};
      TopDocs top = searcher.search(new KnnFloatVectorQuery("euc7", query, 6), 6);
      StringBuilder hits = new StringBuilder();
      for (ScoreDoc sd : top.scoreDocs) {
        String id = searcher.storedFields().document(sd.doc).get("id");
        hits.append(String.format(Locale.ROOT, " %s=%.6g", id, sd.score));
      }
      String first = searcher.storedFields().document(top.scoreDocs[0].doc).get("id");
      assertTrue("an exact match must rank first; hits:" + hits, first.startsWith("a"));
    }
  }
}
cd $LUCENE
cp $REPRO/org/apache/lucene/backward_index/TestOldUniformQuantizedSegment.java lucene/backward-codecs/src/test/org/apache/lucene/backward_index/
./gradlew :lucene:backward-codecs:test --tests org.apache.lucene.backward_index.TestOldUniformQuantizedSegment -Ptests.seed=DEADBEEF
# assertions off fails the same way: -Ptests.asserts=false
- Expected
- a0, a1, a2 (the exact matches) rank first with score 1.0; b0 follows with 0.492.
- Observed
- b0 ranks first (0.492); a0, a1, a2 score 0.0000153 and rank last.
More files, environment, full output255 words
The index is embedded as a base64 zip (47 lines). It was written through the public API of the 10.3.2 jar (regenerated 2026-11-04 with neutral segment diagnostics: java.vendor = OpenJDK, os.version = Unknown): the default Lucene99HnswScalarQuantizedVectorsFormat() (int7) for a 4-dimension EUCLIDEAN field euc7, a stored id, NoMergePolicy, compound files; a0, a1, a2 = [1, 1, 1, 1], commit; b0 = [2, 1, 1, 1], b1 = [3, 3, 3, 3], b2 = [-1, 0, 2, 5], commit. The test searches KnnFloatVectorQuery("euc7", [1, 1, 1, 1], 6) and asserts that an exact match ranks first; the message prints every hit with its score.
The same test is the suggested regression test; the index could also live as a .zip resource next to the int7_hnsw.*.zip files. It passes checkGoogleJavaFormat, ecjLintTest and forbiddenApisTest. The 9.12.3-written copy of the same index fails on main the same way.
| lucene | main 5adff78bb168 (12.0.0-SNAPSHOT): fails; 10.3.2, 10.5.2 and 10.6.0: pass |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
# gradle, main 5adff78bb168, seed DEADBEEF, -Ptests.asserts=true (the same with false)
TestOldUniformQuantizedSegment > testExactMatchRanksFirst FAILED
    java.lang.AssertionError: an exact match must rank first; hits: b0=0.492188 b2=0.124503 b1=0.0583900 a0=1.52586e-05 a1=1.52586e-05 a2=1.52586e-05
        at org.apache.lucene.backward_index.TestOldUniformQuantizedSegment.testExactMatchRanksFirst(TestOldUniformQuantizedSegment.java:111)
# the JUnit runner: the same failure on main with -ea and -da (Panama provider)
# 10.3.2, 10.5.2 and 10.6.0 jars on the same bytes: pass; hit list (10.3.2, 10.6.0) a0=1.00000 a1=1.00000 a2=1.00000 b0=0.492188 b2=0.124503 b1=0.0583900
# main with the recommended fix: pass, the same hit list as 10.6.0- The documented decode (
ScalarQuantizerjavadoc) gives 1.0 for code 0 with stored (1, 1), as every release reader does. - CHANGES says 9.x indexes "remain fully supported in Lucene 11"; #14049 fixed a divide-by-zero, and no comment there considers old stored codes.
- The branch's comment says "alpha = scale = 1"; the code gives 2 and 0.5.
The full argument273 words
- The stored quantiles are the parameters of the stored codes. The class javadoc formula (
ScalarQuantizer.java:50-51) gives 1.0 for code 0 with (1, 1). Every release reader from 9.9.2 to 10.6.0 (on the same or equivalent indexes), and main's own parent commita833887be67, compute that. - Lucene 11 states that 9.x indexes stay supported. CHANGES: "Indexes created with 9.x remain fully supported in Lucene 11, no reindexing required" (
CHANGES.txt:40-41). That is no promise of identical approximate scores for an experimental format; the point is that stored codes get a new meaning without notice. The #14049 entry describes a fix, "Fixes scalar quantization div-by-zero when all values are identical" (:342-343). No CHANGES or MIGRATE note mentions a decode change. - The code does not do what its comment says (
ScalarQuantizer.java:103). The #14049 discussion touches old indexes only in general: s1monw asked that the back-compat tests not be randomized, msokolov wondered whether a customized codec could end up "failing to be able to load an older index version" with no warning from those tests, and mccullocht later asked to backport the change tobranch_10x. No comment considers how the widening changes the decode of codes already stored in old equal-quantile segments. - Tests assert old int7 indexes keep their top hit.
TestInt7HnswBackwardsCompatibilitychecks the top kNN hit on the 9.10.0-10.6.0 indexes (:105-106after appending documents,:143-144intestReadOldIndices), but its vectors{0.2, -0.1, 0.1 + 0.1 * id}(:57,:134) never make the quantiles equal. - Precedent. #13867 (9.12 broke reading older Lucene99 scalar-quantized segments, fixed by #13874 and #13912) was treated as a back-compat bug.
The devil's-advocate check232 words
The case for "intended" (built by an intended-behaviour check and by a reviewer from another model family, OpenAI GPT-5.6, who rated it moderate): the formats are @lucene.experimental; quantization is lossy and kNN approximate ("it's unclear what kinds of guarantees we can make about score values under quantization", msokolov on #14049); the widening was a deliberate, approved choice; and these degenerate segments already score oddly on the writing release (#13480), so Lucene 11 only produces different wrong numbers.
Why it fails: loss and approximation describe quantization error, not a reader that reinterprets persisted codes. Re-quantizing the raw vector on main gives code 64, not the stored 0, and an exact match ends below every other document. The choice was made for new quantizers (when it merged, main still wrote this format, so its own segments stayed consistent); no comment in the discussion considers the decode of codes already stored in old equal-quantile segments, and the wrong comment suggests the effect on them was not analysed.
One point to state carefully: Lucene 11 is not worse for every query. Persisted codes decode with other parameters, so exact and near matches go from first to last; #13480 is the related writer-side case. A maintainer may still triage the two together, since both start from uniform vectors: #13480 is about the writer's own scores, this is a newer reader giving stored codes a new meaning.
Recommended Keep the lower quantile and widen upwards only (recommended)
Recommended: in the ScalarQuantizer constructor's min == max branch, keep minQuantile and widen upwards only. Code 0 then decodes to the stored quantile again, and alpha = scale = 1 as the comment says. Validated on 5adff78bb168: the repro passes with assertions on and off, and 27 backward-codecs and core suites (1,939 tests) pass.
if (minQuantile == maxQuantile) {
  // avoid divide-by-zero by widening upwards only (alpha = scale = 1). Keep minQuantile: older
  // segments store min == max with every code 0, so code 0 must still decode to minQuantile.
  this.minQuantile = minQuantile;
  this.maxQuantile = maxQuantile + divisor;
} else {
All options and trade-offs3 options · 528 words
Three options. A was built and tested; B and C were not run.
One line in ScalarQuantizer's constructor (ScalarQuantizer.java:104), plus the comment. For stored (q, q) the quantizer becomes (q, q + 127) (int4: q + 15), alpha = scale = 1, and code 0 decodes to q again.
if (minQuantile == maxQuantile) {
  // avoid divide-by-zero by widening upwards only (alpha = scale = 1). Keep minQuantile: older
  // segments store min == max with every code 0, so code 0 must still decode to minQuantile.
  this.minQuantile = minQuantile;
  this.maxQuantile = maxQuantile + divisor;
} else {
Trade-offs
- It changes the constructor for every caller with equal quantiles. On main that is only this reader in Lucene's production code, plus the test-only Lucene99 writer, the public factories
fromVectorsandfromVectorsAutoInterval(no production caller in Lucene), and any code outside Lucene that uses them or the public constructor. - Query values below q are clamped to q; there is no stored data below q.
- It restores the decode, not the writing release's query-independent 1.0 scores (that is #13480).
- One field shape stays imperfect: with a dynamic confidence interval (int4,
confidenceInterval = 0) the 10.3.2 writer itself stored (0, 0) for[1, 1, 1, 1], so even its own decode is 0.0. With the fix the exact match there scores 0.2 and ranks second behind b0 (0.67); only option C ranks it first.
What the checks validated
Scratch worktree at 5adff78bb168, gradle: the minimal test fails without the fix and passes with it, with -Ptests.asserts=true and false. With the fix, :lucene:backward-codecs:test for backward_index.*, backward_codecs.lucene99.* and backward_codecs.lucene102.*, plus :lucene:core:test for util.quantization.* and TestLucene104ScalarQuantizedVectorsFormat: 27 suites, 1,939 tests, 0 failures (141 skipped), with assertions on and off; among them TestInt7HnswBackwardsCompatibility (105), TestLucene99ScalarQuantizedVectorsFormat (61), TestLucene99HnswScalarQuantizedVectorsFormat (59) and TestScalarQuantizer (8). checkGoogleJavaFormat, ECJ lint and forbidden-apis pass; the EditorConfig lint did not run (its tool is not installed here). The JUnit runner with the fixed class: pass with -ea and -da, and the hit list equals 10.6.0's. Re-run 2026-11-04 with the regenerated fixture in a clean scratch worktree: the minimal test fails without the fix and passes with it, with assertions on and off, and the format, ECJ lint and forbidden-apis checks pass; the 27-suite run used the earlier copy of the fixture.
In Lucene99ScalarQuantizedVectorsReader.FieldEntry.create (:481-490), build new ScalarQuantizer(min, min + ((1 << bits) - 1), bits) when the stored quantiles are equal.
Trade-offs
Same effect on read as A and leaves the constructor alone. The wrong comment stays, and code outside Lucene that rebuilds quantizers from stored quantiles keeps the shift.
What the checks validated
Not run.
Give the reader a legacy quantizer with alpha = 0 for stored min == max, so old segments score bit-identically to their writer.
Trade-offs
Also keeps #13480's query-independent 1.0 scores, and ranks the dynamic-interval case first. Needs a new constructor or scorer path: the largest change.
What the checks validated
Not run.
Code outside Lucene that rebuilds a ScalarQuantizer from quantiles it stored earlier, through the public constructor, decodes equal-quantile data with the same shift on Lucene 11.
An SMT model (Z3, IEEE-754 single precision) compared the released ScalarQuantizer constructor with the current one for the same stored quantiles (q, q). In about 1 s the solver found q = 321, whose code 0 decodes to 321 on the release and to 194 on main. Indexes written by the 10.3.2 and 9.12.3 jars then reproduced it.
The method in full132 words
Method: formal, an SMT counterexample. A Z3 model in floating-point arithmetic (QF_FP, binary32, round to nearest even) encoded the release constructor and main's constructor applied to the same stored pair (q, q), and asked whether code 0 can decode differently. The query was satisfiable in 1.14 s: q = 321 decodes to 321 on the release and to 194 on main, with main's alpha = 2 (int4: 0 versus -15). The decodes agree again only for huge |q| (from about 2^31 for int7), where q ± divisor rounds back to q.
The model was then checked end to end: indexes written through the public API of the 10.3.2 and 9.12.3 jars, read on main by a JUnit test, gave the same shift, and the release readers on the same bytes did not.
New: no Lucene issue, PR, JIRA entry or list thread, and nothing outside Lucene, describes this defect (re-checked 2026-11-03 in two passes and again 2026-11-04). Related, about different defects: #13480 (uniform vectors score the same for every query on the writing release) and #14049, the change that added the widening.
Searches6 searches
Related items, each about a different defect:
- #13480 (open, benwtrent, 2024-06-11, 0 comments, unchanged since 2025-03-21), "Scalar quantization extreme edge case of uniform vector values": on the writing release, uniform vectors give equal quantiles and scores that ignore the query. It is about the release writer and scorer, predates #14049 by six months, and says nothing about a newer reader decoding stored codes differently. It is the related writer-side case; a maintainer may triage the two together.
- #14049 (merged 2024-12-09): the change that introduced the widening, as a divide-by-zero fix. Not a report.
- elastic/elasticsearch#109416 (2024-06-06): the downstream report behind #13480, release-side symptom only.
- #13867 (closed, fixed by #13874 and #13912): an earlier read-path back-compat break of older Lucene99 scalar-quantized segments, with another cause. Precedent only.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene), downstream repositories, the dev, java-user, issues and commits lists, the JIRA archive | 2026-10-28 | three spec runs of a prior-report search tool (153 queries) on identifiers, symptoms and the back-compat angle, plus 28 manual GitHub searches and 7 web queries | no report of this defect; #13480 and #13867 related |
| Open apache/lucene PRs | 2026-10-28 | the changed files of all 411 open PRs | none touches the equal-quantile handling |
| The same sources | 2026-11-04 | the same three specs re-run (135 queries): 349 hits, 278 distinct URLs | the closest are #13480, #13867, #13519, #13350, quantization feature and refactoring PRs, one list thread about a different Lucene99 fix |
| The same sources | 2026-11-04 | the same three specs again with every query fetched fresh (135 queries, none from the cache): 349 hits, 277 distinct URLs | the closest hits are all about other defects or features (#13480, #13867, #14049, #15223, recall and feature PRs, #16830); none about this defect |
| GitHub (apache/lucene) | 2026-11-04 | 6 searches for items updated since 2026-10-27; commits by path on both files; the state of #13480 | 0 results; no new commit on either file; #13480 unchanged |
| apache/lucene issues and PRs | 2026-11-04 | read-only listing of the 146 items updated since 2026-10-27 | quantization items #16979, #16830, #16829, #16790 are about other defects or performance; none about this defect |
Introduced on main by 6b0112cdee2 (#14049, merged 2024-12-09), which added the min == max widening. No release has it (release readers 9.9.2 to 10.6.0 read the same or equivalent segments correctly); main and branch_11x carry it, so 11.0.0 would be the first release. Affected data: int7 segments written by 9.9.0-10.3.2, int4 by 9.11.0-10.3.2.
Versions tested7 rows
Introduced by 6b0112cdee2 "Randomize KnnVector codec params in RandomCodec; addresses gh-14047" (#14049, by msokolov, merged 2024-12-09, main only). git log --all -S 'minQuantile == maxQuantile' lists only this commit. No release tag 9.9.0-10.6.0 and no branch_10_6 head has the branch; branch_10x was decommissioned (#16911). A branch_10x copy of the change was proposed in the #14049 review but never landed.
Affected data: segments written by the releases that write the format, int7 by 9.9.0-10.3.2 and int4 by 9.11.0-10.3.2 (#13197 added int4 in 9.11.0) (#15223 moved it to backward-codecs; 10.4.0 and later only read it). 10.x-written segments are read on main since the commit; 9.x-written ones by default since #16741 (2026-10-15).
| Version or commit | Verdict | Result |
|---|---|---|
main 5adff78bb168 (12.0.0-SNAPSHOT) | affected | exact matches 0.0000153, ranked last; gradle and the JUnit runner, -ea and -da; the 9.12.3-written copy fails too |
branch_11x 319bdb587ce (11.0.0, unreleased) | by reading | the same quantizer, reader and scorer files as main; not run |
main a9779ef3c193, ea57360912ed | affected | earlier runs: the same scores, with the Panama and the default provider |
6b0112cdee2 (#14049) vs its parent a833887be67 | bisect | the commit fails with the same scores; its parent passes (1.0, first) |
| 10.3.2, 10.5.2, 10.6.0 | not affected | this doc: pass on the test's bytes, a0..a2 1.0 and first (-ea and -da) |
| 9.9.2, 9.12.3, 10.0.0, 10.1.0, 10.3.2, 10.4.0, 10.5.2 | not affected | earlier runs: 10.3.2, 10.4.0 and 10.5.2 on the 10.3.2-written index; 9.9.2, 9.12.3, 10.0.0 and 10.1.0 on equivalent indexes written by 9.9.2, 9.12.3 or 10.0.0 (10.1 cannot open a 10.3 index): pass |
main 5adff78bb168 + recommended fix | not affected | pass; hit list equal to 10.6.0's |
An independent reproducer, two executed reviews by a model from another family (OpenAI GPT-5.6; refute and works-as-designed lenses), an intended-behaviour devil's advocate, an adjudication and a later re-check each re-ran it with their own tests or seeds: all say real. This doc re-ran it on 5adff78bb168.
Checks and verdicts335 words
The reviews and checks ran on main a9779ef3c193, except the works-as-designed review, which ran on ea57360912ed; the quantizer, reader and scorers of both are identical to 5adff78bb168, where this doc's runs are.
| Check | Verdict | What it found |
|---|---|---|
| finder | found | The SMT model, then a public-API JUnit with indexes written by the 10.3.2 and 9.12.3 jars: fails on main with -ea, -da and the default provider; passes on 10.5.2, 10.4.0, 10.3.2 and 9.12.3 and with the fix. |
| cross-model review, refute lens (OpenAI GPT-5.6, executed) | real (high) | Wrote its own writer and reader programs and 10.3.2 fixtures, reproduced it on main, agreed on root cause and fix; TestScalarQuantizer and a Lucene99 write-and-read test pass with the fix. |
| independent reproducer | real | Own fixture generators on the 10.3.2 and 9.12.3 jars and its own JUnit (int7 and int4): fails 4 of 4 on main, passes on four releases; main reports quantizer (-126, 128) for the stored (1, 1); main without the widening passes. |
| cross-model review, works-as-designed lens (OpenAI GPT-5.6, executed) | real (high); intended case moderate | Its own test fails on main and passes on 10.3.2, 10.5.2 and with the fix; a control on main's current quantized codec passes. |
| intended-behaviour devil's advocate | real (medium-high) | Built the "by design" case, read the whole #14049 discussion and found no document, test or discussion that intends the widened decode of old segments. |
| adjudication | confirmed (medium), Low | Re-ran the reproducer's test with a new seed: main fails, 10.5.2 and main without the widening pass. |
| later re-check | confirmed; likelihood lowered to contrived | Re-ran with a new seed (fails 2 of 2) and lowered the likelihood: the clear harm needs identical non-trivial vectors queried near them. |
| this doc | reproduced on 5adff78bb168 | The one-method test, with its embedded 10.3.2 index regenerated with neutral segment diagnostics, fails on main (gradle and the JUnit runner, assertions on and off), passes on 10.3.2, 10.5.2 and 10.6.0, and passes with the recommended fix. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 587 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,351 words
- Registry title
- On main, a 9.x/10.x int7/int4 scalar-quantized segment whose vectors are all identical (stored quantiles equal) is decoded with the min == max widening that #14049 added, not the quantizer that wrote it, so its vectors read 127 (int7) or 15 (int4) units lower in every dimension and exact matches score about 0 and rank last (unreleased, 11.0 only)
- Area
- codecs / legacy scalar-quantized vectors (util/quantization ScalarQuantizer, backward-codecs Lucene99ScalarQuantizedVectorsReader)
- Priority
- Low, rank 720: Low and placed right after LFV-221 with the other unreleased main-only silent-wrong-score rows, because an old opt-in Lucene99 scalar-quantized segment whose vectors are all identical ranks exact matches last on main, which is worse than LFV-221's near-tie drops, but the trigger is contrived, the format is legacy and a merge clears it.
- Impact class
- silent wrong results
- Impact note
- Applications that indexed an opt-in Lucene99(Hnsw)ScalarQuantizedVectorsFormat field (int7 or int4, any similarity) with 9.9.0-10.3.x and open the unchanged index with unreleased Lucene 11 (main) get silently wrong kNN scores for the documents of any segment in which every vector of that field is identical (for example only all-zero placeholder vectors, or one document with a constant vector): exact and near matches score about 0 and rank last, with no error, until a merge re-quantizes that segment from its raw floats; no scale is needed, and ordinary segments score bit-identically to the writing release [exec].
- Summary
- You index a field with the Lucene99 HNSW scalar-quantized format (int7, EUCLIDEAN) on 10.3.2 or 9.12.3, one segment holds only documents whose vector is [1,1,1,1], so the writer stores the quantiles (1, 1) and every code 0; you then open the unchanged index on main and search for [1,1,1,1]. Every release reader tested (9.9.2 to 10.6.0) decodes code 0 as 1.0, as the ScalarQuantizer formula for the stored quantiles says, and ranks those exact matches first with score 1.0. On main the reader rebuilds the quantizer through the min == max widening added by #14049, decodes those vectors as [-126,-126,-126,-126], and the exact matches score 1.5e-5 and rank last behind a document with half the similarity; int4 fields decode 15 units low, and DOT_PRODUCT and COSINE exact matches score 0.0.
- Introduced
- 6b0112cdee284cae9143402d7dd80fdaf4d22f93 (GITHUB#14049 'Randomize KnnVector codec params in RandomCodec; addresses gh-14047', author msokolov, main only, milestone 11.0.0): it added 'if (minQuantile == maxQuantile) { minQuantile - divisor; maxQuantile + divisor }' to the ScalarQuantizer constructor, which the Lucene99 reader (a47ba3369f4, #12729, and 07d3be59af8, #13197) also applies to the quantiles it reads from old segments [exec: main built at the parent a833887be67 passes, at 6b0112cdee2 fails with the same scores as a9779ef3c193; git log --all -S 'minQuantile == maxQuantile' lists only this commit] (2024-12-09 (author and commit date of 6b0112cdee2, 11:22:43 -0500; PR merged 2024-12-09T16:22:44Z))
- First affected version
- unreleased (main / 11.0.0-SNAPSHOT only: no release tag 9.9.0-10.6.0 and no head of branch_10x, branch_10_5 or branch_10_6 has the widening [read, 2026-10-24 heads; the 10.6.0 tag read and its jars executed 2026-11-04]; the first release that would ship it is 11.0.0)
- Affected versions
- main from 6b0112cdee2 (2024-12-09) through 5adff78bb168 [exec: 5adff78bb168 fails with -ea and -da (2026-11-04); the 6b0112cdee2 snapshot build fails; a9779ef3c193 fails with -ea and -da, with the Panama and the default vectorization provider; ea57360912ed fails]; upstream main 20ced71c1e6 has a byte-identical ScalarQuantizer.java [read, 2026-10-28]. Affected data: segments written by 9.9.0-10.3.2, the releases that write this format [exec writers: 9.9.2, 9.12.3, 10.0.0, 10.3.2]; 10.x-written segments are read on main since 6b0112cdee2, 9.x-written ones by default since #16741 (2026-10-15) [read; a 9.12.3-written index fails on a9779ef3c193 [exec]]. Not affected [exec]: the readers 9.9.2, 9.12.3, 10.0.0, 10.1.0, 10.3.2, 10.4.0 and 10.5.2 and the main snapshot a833887be67 pass on the same index bytes, and 10.6.0 passes on the test's regenerated copy of that index (2026-11-04, -ea and -da). A branch_10x backport of the ScalarQuantizer change was proposed in the #14049 review (2026-06-15, agreed 2026-07-10) but has not landed [read]. All runs on aarch64 with JDK 25
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- formal: Z3
- Upstream and prior reports
- related open issue #13480 (benwtrent, 2024-06-11, 0 comments) 'Scalar quantization extreme edge case of uniform vector values': uniform vectors give equal quantiles and query-independent scores on the writing release; it predates the main-only widening and does not describe a newer reader decoding stored equal-quantile codes differently. Introducing change #14049 (merged 2024-12-09, main only). No report of this defect itself (searched 2026-10-28, read-only: three scripted prior-report search specs with 153 queries over GitHub issues, PRs and commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists and the JIRA archive, 28 manual GitHub searches, 7 web queries, the changed files of all 411 open apache/lucene PRs, plus the finder's 51-query run; re-checked the same day: no PR #16907-#16926 touches the site, #13480 unchanged since 2025-03-21, upstream main 20ced71c1e6 has the same ScalarQuantizer.java). Downstream origin of #13480: elastic/elasticsearch#109416. Precedent: #13867 (a read-path back-compat break of older Lucene99 scalar-quantized segments, fixed by #13874 / #13912).
- Lucene commit tested
- main
5adff78bb168(run 2026-11-04): the one-method JUnit, with its embedded 10.3.2 index regenerated that day with neutral segment diagnostics, through gradle in a clean scratch worktree, stock and with the recommended fix, with assertions on and off, plus the format, ECJ lint and forbidden-apis checks; through the JUnit runner on main (-ea,-da, and with the fix) and on the released 10.3.2, 10.5.2 and 10.6.0 jars. With the earlier copy of the same index: 27 backward-codecs and core suites with the fix, and the 9.12.3-written copy of the index on main. Earlier checks ran on maina9779ef3c193andea57360912ed, whose quantizer, reader and scorers are identical, on the readers 9.9.2, 9.12.3, 10.0.0, 10.1.0, 10.3.2, 10.4.0 and 10.5.2 (same or equivalent indexes), and at the introducing commit and its parent.
- Finding record
lucene/core/src/java/org/apache/lucene/util/quantization/ScalarQuantizer.java:49-51 (at a9779ef3c193) (class javadoc: 'float = (maxQuantile - minQuantile)/127 * byte + minQuantile'), :102-109 (if (minQuantile == maxQuantile): minQuantile - divisor, maxQuantile + divisor; comment 'leads to alpha = scale = 1'), :110-111 (scale and alpha from the widened range: 0.5 and 2), :165-170 (deQuantize: alpha * code + minQuantile)lucene/backward-codecs/src/java/org/apache/lucene/backward_codecs/lucene99/Lucene99ScalarQuantizedVectorsReader.java:452 (at a9779ef3c193) (FieldEntry.create), :481-483 and :488-490 (new ScalarQuantizer(stored minQuantile, stored maxQuantile, bits))lucene/CHANGES.txt:9-10 (at a9779ef3c193) (GITHUB#16741: 'Indexes created with 9.x remain fully supported in Lucene 11'), :284-285 (GITHUB#14049: 'Fixes scalar quantization div-by-zero when all values are identical')upstream (read-only): apache/lucene#13480 body (gh issue view, 2026-10-28)
- The finding in 30 seconds
lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/util/quantization/ScalarQuantizer.java:50-51 (decode formula), :101-111 (min == max branch, scale, alpha), :103 (comment), :165-168 (deQuantize), :180-181 (getConstantMultiplier = alpha²)lucene main 5adff78bb168: lucene/backward-codecs/src/java/org/apache/lucene/backward_codecs/lucene99/Lucene99ScalarQuantizedVectorsReader.java:452, :481-483, :488-490 (FieldEntry.create)lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/codecs/lucene99/Lucene99ScalarQuantizedVectorScorer.java:62-76 (query quantized with the segment's quantizer), :163-165 (EUCLIDEAN score); lucene/core/src/java25/org/apache/lucene/internal/vectorization/PanamaVectorizationProvider.java:82-83, Lucene99MemorySegmentScalarQuantizedVectorScorer.java:112-113 (Panama path: same quantizer and multiplier)
- Who is affected
lucene main 5adff78bb168: lucene/CHANGES.txt:40-41 (GITHUB#16741)a Lucene clone: releases/lucene/9.9.0, 9.10.0, 9.11.0 Lucene99ScalarQuantizedVectorsFormat.java (VERSION_ADD_BITS and the bits check first in 9.11.0, #13197)
- Why it looks unintended
lucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/util/quantization/ScalarQuantizer.java:50-51, :103-111lucene main 5adff78bb168: lucene/CHANGES.txt:40-41, :342-343lucene main 5adff78bb168: lucene/backward-codecs/src/test/org/apache/lucene/backward_index/TestInt7HnswBackwardsCompatibility.java:57, :105-106, :134, :143-144lucene main 5adff78bb168: lucene/backward-codecs/src/java/org/apache/lucene/backward_codecs/lucene99/Lucene99HnswScalarQuantizedVectorsFormat.java:47, Lucene99ScalarQuantizedVectorsFormat.java:36 (@lucene.experimental)upstream (read-only): apache/lucene#14049 comments by s1monw and msokolov (2024-12-07) and the review thread at ScalarQuantizer.java:102 (mccullocht, 2026-06-15)
- History
a Lucene clone: releases/lucene/10.6.0, origin/branch_10_6, origin/branch_10x (48cf3f515d6, decommissioned), origin/branch_11x (319bdb587ce): ScalarQuantizer.java grep for the branchlucene main 5adff78bb168: lucene/core/src/java/org/apache/lucene/util/Version.java:305 (MIN_SUPPORTED_MAJOR = 9); lucene/CHANGES.txt:40-41, :342-343
- TestOldUniformQuantizedSegment.java (one test method; the 10.3.2 index as a base64 zip):
repro/LFV-841/TestOldUniformQuantizedSegment.java(113 lines)
Main's ranking appears only with main's executed scores. Every code line shown is checked against the sources of main 5adff78bb168 and the 10.3.2 tag, and every number against the executed runs.
assets/LFV-841/bug.png(587 KB)