WordDelimiterGraphFilter gives every character a type and splits a token at certain type changes. A types file overrides the type of the characters it lists. Adding one swaps the whole Latin-1 table for a second one that disagrees with the default on 8 characters; only the characters the file lists get its types.
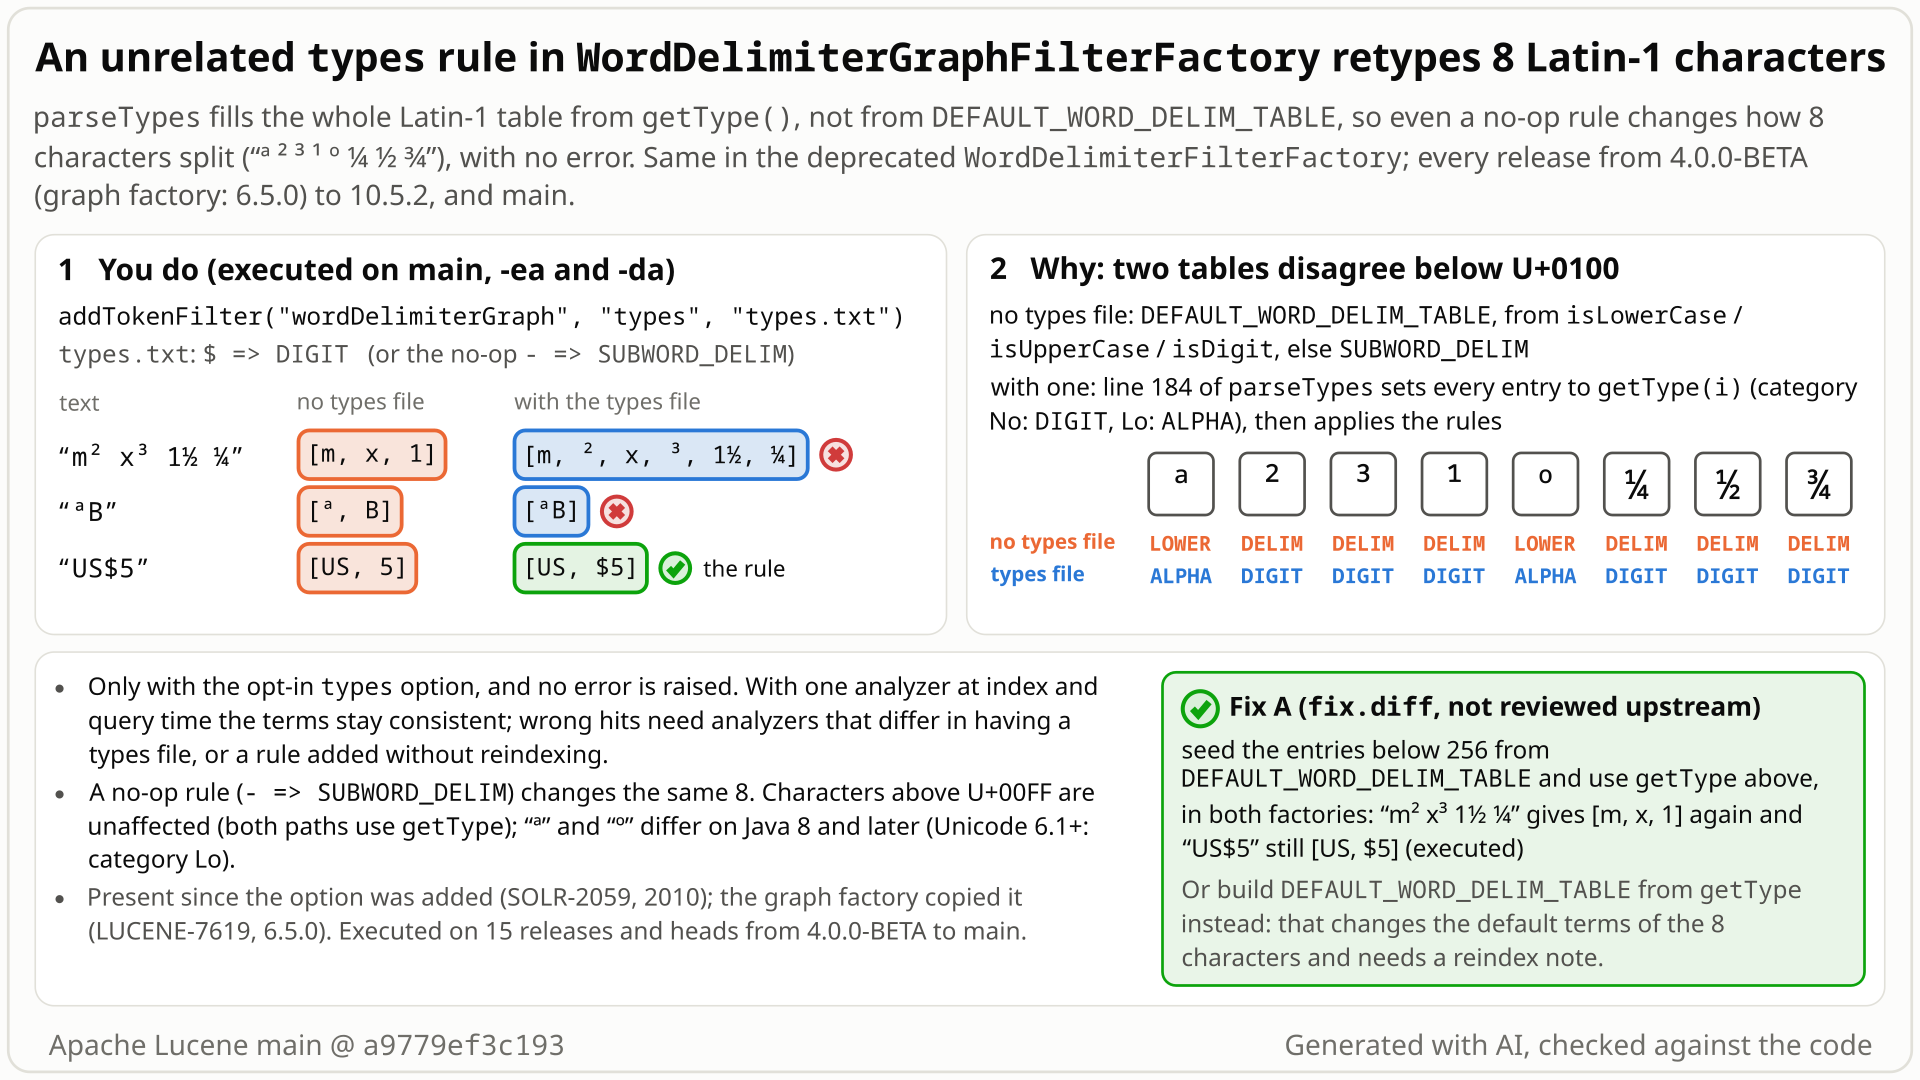
$ => DIGIT example: without a types file m² x³ 1½ ¼ gives [m, x, 1]; with it, parseTypes fills the 256 Latin-1 entries from getType(), the 8 entries on which that differs from the default table change, and the same text gives [m, ², x, ³, 1½, ¼]. Select the still to open it at full size. Generated with AI, checked against the code.- You give WordDelimiterGraphFilterFactory (whitespace tokenizer, default flags) a
typesfile with one rule,$ => DIGIT, so thatUS$5gives[US, $5]instead of[US, 5]. - You expect text without a
$to analyze as before:m² x³ 1½ ¼gives[m, x, 1], because by default ², ³, ½ and ¼ are delimiters. - Instead it gives
[m, ², x, ³, 1½, ¼]: ² and ³ become extra terms,1½stays whole, and the lone¼becomes a term. - Why: with a types file,
parseTypesfills all 256 Latin-1 entries fromgetType(), the Unicode category (WordDelimiterGraphFilterFactory.java:184), not from the default table built withisLowerCase,isUpperCaseandisDigit. The rules are applied after that, so only the characters the file lists get its types. The two tables disagree on exactly 8 characters: ¹ ² ³ ¼ ½ ¾ become digits, and ª º become caseless letters, soªBis no longer split. - Even the no-op rule
- => SUBWORD_DELIMdoes it:a-b m² 1½ ¼ ªBgoes from[a, b, m, 1, ª, B]to[a, b, m, ², 1½, ¼, ªB]. No error, in both factories, in all 15 releases and heads run from 4.0.0-BETA to main.
Only applications that set the opt-in types option (such as Solr's types="wdfftypes.txt"), for text with ¹ ² ³ ¼ ½ ¾ (m², 1½) or ª º before a capital. One analyzer for indexing and queries keeps terms consistent; hits go wrong only if index and query analyzers differ in having a types file, or a rule is added without reindexing.
Mechanism, terms and numbers790 words
WordDelimiterGraphFilter gives every character a type (lower-case, upper-case, digit or delimiter) and splits a token at type changes such as letter to digit or lower to upper case. Its factory, and the deprecated WordDelimiterFilterFactory, accept a types file whose rules override the type of single characters. Without the option, characters below U+0100 are looked up in DEFAULT_WORD_DELIM_TABLE, built from Character.isLowerCase, isUpperCase and isDigit. With the option, parseTypes fills every entry of a new table, including all 256 Latin-1 ones, from WordDelimiterIterator.getType(i), which maps the Unicode general category, and only then applies the rules (WordDelimiterGraphFilterFactory.java:179-186 on main a9779ef3c193). The two tables disagree on exactly 8 characters: ¹ ² ³ ¼ ½ ¾ are delimiters by default and digits in any types table that does not list them, and ª º are lower-case letters by default and caseless letters (ALPHA) in any types table that does not list them (on Java 8 and later). So a types file whose only rule is - => SUBWORD_DELIM, the type - already has, changes a-b m² 1½ ¼ ªB from [a, b, m, 1, ª, B] to [a, b, m, ², 1½, ¼, ªB], with no error. Only applications that set the opt-in option are hit; with one analyzer at index and query time the terms stay consistent. Every Lucene release from 4.0.0-BETA to 10.6.0 is affected (the graph factory from 6.5.0; 15 releases or heads run, the rest inferred from unchanged code), and seeding the Latin-1 entries from the default table fixes both factories without changing default tokenization.
- Character type:
LOWER,UPPER,ALPHA(= LOWER | UPPER),DIGIT,ALPHANUMorSUBWORD_DELIM(a delimiter). The filter splits a token at type changes such as letter to digit or lower to upper case, unless the two types share a bit or a flag turns that split off (isBreak,WordDelimiterIterator.java:227-245), and it drops delimiters. - Default table:
WordDelimiterIterator.DEFAULT_WORD_DELIM_TABLE, 256 entries for U+0000-U+00FF:LOWERifCharacter.isLowerCase, elseUPPERifisUpperCase, elseDIGITifisDigit, elseSUBWORD_DELIM(WordDelimiterIterator.java:88-105). Above U+00FF the filter callsgetType(:302-307). getType: a switch onCharacter.getType, the Unicode general category:OTHER_LETTER->ALPHA(:322-328),OTHER_NUMBER->DIGIT(:330-333) (:315-360).typesoption:types="wdfftypes.txt"names files of rules such as$ => DIGIT(the factory javadoc example,WordDelimiterGraphFilterFactory.java:62).
informreads the types files and callstypeTable = parseTypes(wlist)(WordDelimiterGraphFilterFactory.java:139-147).createpassestypeTable == null ? DEFAULT_WORD_DELIM_TABLE : typeTable(:155).parseTypes(:164-188) allocates a table of at least 256 entries ("ensure the table is always at least as big as DEFAULT_WORD_DELIM_TABLE for performance",:179), fills every entry withWordDelimiterIterator.getType(i)(:184), then writes the rules (:185-186).- Below U+0100,
getTypeand the default table disagree on 8 characters (exhaustive check):
| characters | Unicode category (JDK 25) | default table | in a types table that does not list them |
|---|---|---|---|
| ¹ ² ³ ¼ ½ ¾ (U+00B9, U+00B2, U+00B3, U+00BC-U+00BE) | No (other number); isDigit false | SUBWORD_DELIM | DIGIT |
| ª º (U+00AA, U+00BA) | Lo (other letter); isLowerCase true | LOWER | ALPHA |
- So the terms change. A trailing delimiter is dropped (
m²->[m],1½->[1], a lone¼-> nothing); as a digit,²is a new number part after a letter ([m, ²]) and½joins the digit before it ([1½]). Two characters whose types share a bit are never split (WordDelimiterIterator.java:228-230):ALPHAshares the upper-case bit withB, soªBstays one term, whileLOWERthenUPPERis a case change ([ª, B]). That is also why ª and º change only directly before an upper-case letter (1ªis[1, ª]andBªis unchanged either way). - The deprecated
WordDelimiterFilterFactoryhas the same code (WordDelimiterFilterFactory.java:151,:160-184).
| text | no types file | - => SUBWORD_DELIM (a no-op) | $ => DIGIT |
|---|---|---|---|
a-b m² 1½ ¼ ªB | [a, b, m, 1, ª, B] | [a, b, m, ², 1½, ¼, ªB] | - |
m² x³ 1½ ¼ | [m, x, 1] | [m, ², x, ³, 1½, ¼] | [m, ², x, ³, 1½, ¼] |
US$5 (the $ rule works) | [US, 5] | [US, 5] | [US, $5] |
x⁴, 1⅓ (above U+00FF) | [x, ⁴], [1⅓] | [x, ⁴], [1⅓] | [x, ⁴], [1⅓] |
With the no-op rule, an exhaustive sweep of U+0000-U+00FF (each character alone and between letters) finds exactly the 8 characters changed, in both factories. Code that builds the filter directly with DEFAULT_WORD_DELIM_TABLE plus its own entries is not affected; only the factory path is.
Exposure and likelihood234 words
- Who is hit. Users of WordDelimiterGraphFilterFactory or the deprecated WordDelimiterFilterFactory with a
typesfile that has any rule; only the characters the file lists keep the type it gives them. The option is off by default, and no built-in Lucene analyzer uses these filters. - What they get. Different terms for the same text, deterministic and silent, the same with assertions on and off:
m²gains the term²,1½is indexed as1½instead of1, a lone¼becomes a term,ªBis no longer split. Mostly an unannounced tokenization change when the first rule is added, even a rule unrelated to these characters. - Search results. With the same analyzer (with the types file) at index and query time, terms match either way. Missed or extra hits need analyzers that differ in having a types file (index with types:
1½->[1½]; query without:[1]), or a rule added without reindexing. - Which characters. Superscript one to three, the fractions ¼ ½ ¾ (on every JDK), and the ordinal indicators ª º (on Java 8 and later, whose Unicode data, 6.1 and later, makes them category Lo; on Java 5 to 7 they were Ll and unaffected; Lucene 6.0 and later require Java 8). Characters above U+00FF are not affected.
- Severity. Minor: opt-in configuration, uncommon characters, consistent terms in the usual setup; registry priority low. No prior report was found.
The test shows that a WordDelimiterGraphFilterFactory types file with the no-op rule '- => SUBWORD_DELIM' changes how the unlisted character ² is tokenized.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.miscellaneous;

import java.nio.file.Files;
import java.nio.file.Path;
import java.util.ArrayList;
import java.util.List;
import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.TokenStream;
import org.apache.lucene.analysis.custom.CustomAnalyzer;
import org.apache.lucene.analysis.tokenattributes.CharTermAttribute;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestWdgfTypesRuleKeepsOtherTypes extends LuceneTestCase {

  private static List<String> terms(Analyzer a, String text) throws Exception {
    List<String> out = new ArrayList<>();
    try (TokenStream ts = a.tokenStream("f", text)) {
      CharTermAttribute term = ts.addAttribute(CharTermAttribute.class);
      ts.reset();
      while (ts.incrementToken()) {
        out.add(term.toString());
      }
      ts.end();
    }
    return out;
  }

  public void testNoOpRuleKeepsSuperscriptTwo() throws Exception {
    Path dir = createTempDir();
    Files.writeString(dir.resolve("types.txt"), "- => SUBWORD_DELIM\n");
    try (Analyzer plain =
            CustomAnalyzer.builder()
                .withTokenizer("whitespace")
                .addTokenFilter("wordDelimiterGraph")
                .build();
        Analyzer typed =
            CustomAnalyzer.builder(dir)
                .withTokenizer("whitespace")
                .addTokenFilter("wordDelimiterGraph", "types", "types.txt")
                .build()) {
      // '-' already is SUBWORD_DELIM; expected [m] as without the file, actual [m, ²]
      assertEquals(terms(plain, "m²"), terms(typed, "m²"));
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-851/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.miscellaneous.TestWdgfTypesRuleKeepsOtherTypes
- Expected vs actual
- Expected: 'm²' gives [m], as without the types file. Actual (-ea and -da): [m, ²].
More files, environment, full output35 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<[m]> but was:<[m, ²]>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:120)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.analysis.miscellaneous.TestWdgfTypesRuleKeepsOtherTypes.testNoOpRuleKeepsSuperscriptTwo(TestWdgfTypesRuleKeepsOtherTypes.java:58)- A rule that restates a default (
- => SUBWORD_DELIM) still changes 8 other characters; nothing documents that. - The only code comment says the 256-entry table is there "for performance" (
WordDelimiterGraphFilterFactory.java:179). - The option's author called it a way to "customize the defaults" (SOLR-2059) and to adjust splitting "on a per-character basis" (SOLR-3102).
The full argument340 words
- No written contract either way. Lucene documents the option only as an attribute in the factory javadoc example (
WordDelimiterGraphFilterFactory.java:54-64), and no Lucene test sets it. The filter class javadoc says only that delimiters are "by default, all non alpha-numeric characters" (WordDelimiterGraphFilter.java:47,WordDelimiterFilter.java:40), which does not say whether ² or ½ count as numeric. So this is an inconsistency, not a broken documented promise. - The code comment. "ensure the table is always at least as big as DEFAULT_WORD_DELIM_TABLE for performance" (
WordDelimiterGraphFilterFactory.java:179;WordDelimiterFilterFactory.java:175): the full-size table is for speed, which implies the author treatedgetType(i)and the default table as interchangeable below 256. They are not, for 8 characters. - The author's description. SOLR-2059 (2010, added the option): "By default, WordDelimiterFilter assigns 'types' to each character (computed from Unicode Properties) ... I think you should be able to customize the defaults with a configuration file". Its CHANGES entry: it "allows you to customize how WordDelimiterFilter tokenizes text with a configuration file". SOLR-3102 (2012), the same author quoting the wiki: "In some cases you might want to adjust how WordDelimiterFilter splits on a per-character basis".
- A no-op rule.
- => SUBWORD_DELIMrestates the type-already has, and still changes 8 other characters. The SOLR-2059 test (testCustomTypes) checked a sentence of letters, digits andinterest-ratewhose only special characters were the mapped$ % . ,, plus U+200D; it has none of the 8 characters, and no test, CHANGES entry or discussion records a change of unlisted Latin-1 characters. - The ª º half came from Unicode data. In Unicode 4.0 to 6.0 (Java 5 to 7, the JDKs of 2010) ª and º are category Ll, so the two tables agreed on them; Unicode 6.1 made them Lo (Java 8 and later) while
isLowerCasestays true (unicode.org UnicodeData; no old JDK was run). The 6 number characters differed already in 2010. Lucene 6.0 and later require Java 8, so on every JDK they support, and so for the graph factory, all 8 differ.
The devil's-advocate check243 words
Strongest case: the types path is the consistent one. The Solr Reference Guide says "The default for any character without a customized mapping is computed from Unicode character properties" (the option's sample file says the same), which is what getType does; getType is already the filter's classifier above U+00FF; and by default the filter disagrees with itself (x² gives [x] but x⁴ gives [x, ⁴]; 1½ gives [1] but 1⅓ gives [1⅓]). Reviews from another model family (OpenAI GPT-5.6) rated this strong: one from the record alone, without reading the code (its verdict: not real, low confidence), and the read-only fact check of this doc, which still called the 8-character side effect a legitimate consistency defect, though not conclusively.
Our answer: the default table is computed from Unicode properties too (Lowercase, Uppercase, Nd), so that sentence does not pick a side. Whichever table is right, a rule for $, or a rule that changes nothing, that switches 8 other characters from one table to the other is hard to read as intended. We treat it as a consistency defect; maintainers may still prefer the complete getType table as the intended meaning, and that choice is fix B (change the default table, with a reindex note), not "no change". Every reviewer that read the code rated it real (the source-reading cross-model review had seen verifiers' verdicts; the adjudication's confidence is medium). Verdict: a consistency defect with a weak written contract.
Recommended A. Seed the Latin-1 entries from DEFAULT_WORD_DELIM_TABLE
Seed the Latin-1 entries of the custom table from DEFAULT_WORD_DELIM_TABLE instead of getType() in both factories' parseTypes, and compute getType only above U+00FF. Default tokenization does not change. Validated: the repro passes 4 of 4 with assertions on and off, and the lucene/analysis/common tests run 1,913 tests with 0 failures.
// parseTypes in both factories (WordDelimiterGraphFilterFactory.java:180-184); comment lines omitted
-    byte[] types =
-        new byte
-            [Math.max(
-                typeMap.lastKey() + 1, WordDelimiterIterator.DEFAULT_WORD_DELIM_TABLE.length)];
-    for (int i = 0; i < types.length; i++) types[i] = WordDelimiterIterator.getType(i);
+    byte[] defaults = WordDelimiterIterator.DEFAULT_WORD_DELIM_TABLE;
+    byte[] types = new byte[Math.max(typeMap.lastKey() + 1, defaults.length)];
+    System.arraycopy(defaults, 0, types, 0, defaults.length);
+    for (int i = defaults.length; i < types.length; i++) {
+      types[i] = WordDelimiterIterator.getType(i);
+    }
All options and trade-offs3 options · 670 words
Two fixes were applied in a scratch worktree at a9779ef3c193 and run through gradle, and shadowed onto the stock jars for every repro of the hunt. A keeps default tokenization; B changes it. C is not a fix.
Both factories' parseTypes, +18/-12 lines in total: copy the default table into the new one and compute getType only above it, then apply the rules as before. The same behaviour as the finder's fix (i < 256 ? DEFAULT_WORD_DELIM_TABLE[i] : getType(i)), written as a copy. The comment now says why the table starts from the defaults. Recommended if keeping default tokenization matters most.
// parseTypes in both factories (WordDelimiterGraphFilterFactory.java:180-184); comment lines omitted
-    byte[] types =
-        new byte
-            [Math.max(
-                typeMap.lastKey() + 1, WordDelimiterIterator.DEFAULT_WORD_DELIM_TABLE.length)];
-    for (int i = 0; i < types.length; i++) types[i] = WordDelimiterIterator.getType(i);
+    byte[] defaults = WordDelimiterIterator.DEFAULT_WORD_DELIM_TABLE;
+    byte[] types = new byte[Math.max(typeMap.lastKey() + 1, defaults.length)];
+    System.arraycopy(defaults, 0, types, 0, defaults.length);
+    for (int i = defaults.length; i < types.length; i++) {
+      types[i] = WordDelimiterIterator.getType(i);
+    }
Trade-offs
- A types file now changes exactly the characters it lists; default tokenization (no types file) does not change.
- Users who already have a types file see ¹ ² ³ ¼ ½ ¾ ª º go back to their default types, a one-time tokenization change for those characters that a CHANGES note should mention (reindex if they matter).
- No runtime cost: the table is built once per factory.
What the checks validated
- Stock main
a9779ef3c193, gradle: the repro fails 4 of 4 with assertions on and off. - With fix A, gradle: the repro passes 4 of 4 with assertions on and off; the whole
lucene/analysis/commontest task with assertions on, repro included, runs 340 classes, 1,913 tests, 0 failures, 18 skipped (among themTestWordDelimiterGraphFilter28,TestWordDelimiterFilter16 andTestCustomAnalyzer26 tests); with the test in placeecjLintMain,ecjLintTest,checkGoogleJavaFormatandforbiddenApisMainran and passed, andforbiddenApisTest, which had passed in the first fix A run, wasUP-TO-DATEin the final one. A first version withArrays.copyOffailedforbiddenApisMain("Prefer using ArrayUtil"), henceSystem.arraycopy. - With fix A shadowed onto the stock jars: the finder's test 2 of 2, the independent reproducer's 4 of 4, the cross-model reviewer's probe 3 of 3 and the audit's probe 2 of 2 pass.
- Not run: the full Lucene suite, a benchmark (the change only runs when a factory is initialized).
WordDelimiterIterator.java only: the static block becomes tab[i] = getType(i) for i < 256. Both paths then agree, and the default also matches how the filter treats characters above U+00FF (x² like x⁴, 1½ like 1⅓).
Trade-offs
- Changes default tokenization of the 8 characters for every user of the filter, with or without the factory (
DEFAULT_WORD_DELIM_TABLEis a public array, though of the@lucene.internalclassWordDelimiterIterator; after a Lucene upgrade also the downstream default paths):m²gains the term²,1½becomes one term,ªBis no longer split. Needs a reindex note in CHANGES and MIGRATE, so probably only for a major release. - Keeps the ª º behaviour tied to the JDK's Unicode data, as it already is above U+00FF.
What the checks validated
- Gradle: the repro passes 4 of 4 (assertions on), and the whole
lucene/analysis/commontest task runs 340 classes, 1,913 tests, 0 failures, 18 skipped, so no existing test pins the default tokenization of the 8 characters. Lint was not run. - Shadowed onto the stock jars: the independent reproducer's test, the reviewer's probe and the audit's probe pass; the finder's control fails as it must (it asserts 8 table disagreements, and B leaves 0).
Say in the factory javadoc that a types file switches every Latin-1 character it does not list to getType.
Trade-offs
Not a fix: a no-op rule would still change 8 other characters.
Elasticsearch's and OpenSearch's word_delimiter type_table settings build their tables with their own copy of this loop but use Lucene's WordDelimiterIterator (its default table without type_table, its getType in the loop; read, not run). Fix A would need separate downstream patches; fix B would reach them through a Lucene upgrade.
An exhaustive comparison of Lucene's analysis character tables: DEFAULT_WORD_DELIM_TABLE[c] against WordDelimiterIterator.getType(c) for every character below 256 gave exactly 8 disagreements. Reading parseTypes, which switches from one to the other, gave the hypothesis; a public-API JUnit through CustomAnalyzer then reproduced it on the stock jar.
The method in full182 words
Method: semi-formal (an exhaustive table comparison after code reading; no formal tool produced the first signal).
- A hunt unit on the apostrophe and hyphen character tables of Lucene's analysis filters, compared with Unicode, extracted the character tables from the stock main jar and compared them over all code points.
- While building that table model, reading
parseTypessuggested that the types path and the default path use different tables. The exhaustive comparisonDEFAULT_WORD_DELIM_TABLE[c]versusgetType(c)for every c < 256 found exactly 8 disagreements: U+00AA and U+00BA (LOWER versus ALPHA), U+00B2, U+00B3, U+00B9, U+00BC, U+00BD and U+00BE (SUBWORD_DELIM versus DIGIT). - A public-API JUnit through
CustomAnalyzer, with and without the types file$ => DIGIT, turned that into a failing test on the stock jar (2026-10-28, maina9779ef3c193). - Then checked by an independent reproducer, a reviewer-designed probe, an intended-behaviour devil's advocate, reviews by a model from another family (OpenAI GPT-5.6), an adjudication, a history and prior-report follow-up, a security screen and a credibility audit. This doc added the compact JUnit, the gradle runs and the validation of fixes A and B.
No prior report found (2026-10-28): 177 queries over GitHub, JIRA (LUCENE and SOLR), the Lucene and Solr lists, downstream repositories and the web, plus the changed files of all 411 open PRs. The closest items are SOLR-2059, which added the option, and downstream copies of parseTypes with other defects.
Searches4 searches
Verdict new: no report by anyone. The closest items are SOLR-2059 (added the option and the seeding; its 6 comments, the 2010 discussion plus the 3.1.0 bulk close, never mention the Latin-1 table), SOLR-3102 (documented the option), SOLR-1078 (2009, the getType switch), two downstream defects in copies of parseTypes, and #16918, which lists the deprecated factory for removal in 11.0. GitHub search cannot search the symbols ² ½ º reliably, private reports cannot be searched, and searches cannot prove absence.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; downstream repositories; dev@, java-user@, issues@ and commits@ lists; LUCENE JIRA; the web | 2026-10-28 | a scripted prior-report search, 51 queries | no report; 111 distinct hits, none with high overlap |
| apache/lucene, elastic/elasticsearch, opensearch-project/OpenSearch, apache/solr | 2026-10-28 | 45 manual searches (class names, types/type_table, superscript, fraction, ordinal, OTHER_NUMBER, isLowerCase, Character.getType, wdfftypes); file lists of all 411 open apache/lucene PRs and of the 50 closed or merged PRs updated since 2026-10-14 | no report; only #202 and #16911 touch the files, and both delete files outright; elastic/elasticsearch#2145 and opensearch-project/OpenSearch#6867 are other defects in downstream copies |
| ASF JIRA (SOLR and LUCENE), the solr-user@, solr-dev@, users@solr and dev@solr lists, the web | 2026-10-28 | 12 JQL queries, 8 related issues read with their comments, 56 list queries, 10 web queries | only the origin (SOLR-2059, SOLR-1078) and the documentation issue SOLR-3102 |
| apache/lucene PRs and issues (registration check) | 2026-10-28 | the 60 PRs updated since 2026-10-26 and the 6 issues opened since 2026-10-25 | nothing touches WordDelimiter code; #16918 lists the deprecated factory for removal |
Present since the option was added, SOLR-2059 (33cc5a041e81, 2010): first in Solr 3.1.0, in Lucene from 4.0.0-BETA; LUCENE-7619 copied it into WordDelimiterGraphFilterFactory (2017, 6.5.0). Affected on Solr 3.1.0 and on 15 Lucene releases or heads run, from 4.0.0-BETA to main. Not fixed upstream.
Versions tested8 rows
Introduced by 33cc5a041e81 "SOLR-2059: Add types attribute to WordDelimiterFilterFactory" (Robert Muir, 2010-08-28, SVN r990451; branch_3x 878a697766c0): it added parseTypes with the "for performance" comment and the getType(i) loop, and made getType public for it. Copied into WordDelimiterGraphFilterFactory by LUCENE-7619 (Mike McCandless, 2017-01-17; 637915b890d9, branch_6x 4e4ec082caa7). Later changes to these lines are formatting only. The two tables are older: the Latin-1 table dates from the first WordDelimiterFilter (148b4dbc923, 2006), the getType switch from SOLR-1078 (79414d2b726, 2009), which used it only above the table. SOLR-2059 is the first change that types U+0000-U+00FF with getType, so there is no regression window.
JDK dependence. The 6 number characters differ on every JDK. ª and º differ on Java 8 and later, whose Unicode data (6.1 and later) gives them category Lo (JDK 25: run); on Java 5 to 7 (Unicode 4.0 to 6.0) they were Ll and the tables agreed on them (unicode.org UnicodeData; no old JDK was run). Lucene 6.0 and later require Java 8, so there all 8 differ.
Upstream. Upstream main 20ced71c1e6e (2026-10-27) last changed the two factories in 378ca8d1bbf3 (2026-01-15, a javadoc tag); on upstream main c5ab3e57b9ba (2026-10-28) the two factories and WordDelimiterIterator.java are unchanged. #16918 lists the deprecated factory for removal in 11.0, which would leave the graph factory's copy.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the compact JUnit fails 4 of 4 through gradle, assertions on and off; the hunt's repros fail with -ea and -da |
branch_10_6 4ae946e5a9b9 | 10.6.0, released 2026-10-29 | the finder's JUnit fails; the hunt's probe shows both factories affected |
| 9.0.0, 9.12.3, 10.5.2 | affected | both factories; the compact JUnit fails 4 of 4 on 9.12.3 and 10.5.2 |
| 6.5.0, 6.6.6, 7.7.3, 8.11.4 | graph factory from 6.5.0 | both factories, the hunt's probe: 9 of 10 texts change, x⁴ unchanged |
| 4.0.0-BETA, 4.0.0, 4.4.0, 4.10.4, 5.0.0, 6.4.2 | first Lucene release 4.0.0-BETA | WordDelimiterFilterFactory affected; the graph factory does not exist yet |
| Solr 3.1.0 | as Solr code | the first release with the option: 9 of 10 texts change |
| Lucene 4.0.0-ALPHA, Solr 1.4.1 | no option | 4.0.0-ALPHA's Lucene jar has no factory (compile error); Solr 1.4.1 has no types option (jar inspection) |
| main + fix A | not affected | the compact JUnit passes 4 of 4; every other repro of the hunt passes |
An independent reproducer, an intended-behaviour devil's advocate, an adjudication and a credibility audit reproduced it with their own tests on main. Reviews by a model from another family (OpenAI GPT-5.6) ran no code; the one that could read the sources rated it real. This doc's gradle runs reproduce it and validate fix A.
Checks and verdicts393 words
Every executing check wrote or re-ran its own JUnit on stock main and found the same 8 characters; every control (the rule itself takes effect; characters above U+00FF unchanged) passed. No cross-model review executed code.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Exhaustive table comparison (8 disagreements), then the $ => DIGIT JUnit: fails 1 of 2 on main (-ea, -da), 10.5.2, 9.12.3 and branch_10_6; passes with the fix. |
| cross-model review, refute lens (OpenAI GPT-5.6) | not real, low (procedural) | Every sandboxed command failed: the reviewer read no source and ran no Java; it rated the intended argument weak. A separate re-run of the finder's JUnit failed as claimed. |
| independent reproducer | real | Own 4-test JUnit through the factory API: 3 fail, the control passes, on main (-ea, -da), 10.5.2 and 9.12.3; the no-op rule changes exactly the 8 characters in both factories; 4 of 4 pass with the fix. |
| cross-model review, intended lens (OpenAI GPT-5.6, 3 attempts) | uncertain / not real (low), then real (medium) | Two attempts could not read the checkout (uncertain; not real, rating the intended argument strong from the record alone). The third read the sources and returned real, but had seen the independent reproduction's and the intended-behaviour check's verdicts. Its designed probe (+ => DIGIT on z¹ q¾ ªB) fails 2 of 3 on main and passes with the fix. |
| intended-behaviour devil's advocate | real, low impact | Built the strongest intended case (the getType table matches the filter above U+00FF) and rejected it as a choice of fix; reproduced on main and 10.5.2; showed only the factory path is affected. |
| adjudication | confirmed, medium | Re-ran the independent reproduction's JUnit with -ea and -da (3 of 4 fail); class minor; security none. |
| credibility audit | keep | Re-ran the finder's JUnit (-ea) and an own no-op-rule probe in both factories (-da): a-b m² 1½ ¼ ªB Wi-Fi changes as claimed. |
| this doc | reproduced; fixes A and B validated | Compact 4-test JUnit: fails 4 of 4 through gradle on stock main (assertions on and off) and through the runner on 10.5.2 and 9.12.3; passes with fix A (analysis-common 1,913 tests, 0 failures; lint passes) and with fix B (1,913 tests, 0 failures); every hunt repro passes with fix A shadowed. Also ran the side probe of a comment-only types file. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 502 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,457 words
- Registry title
- WordDelimiterGraphFilterFactory's types option (and the deprecated WordDelimiterFilterFactory's) refills the whole Latin-1 type table from getType() instead of the filter's default table, so any rule, even one that restates a character's own type, silently changes how 8 other characters (¹ ² ³ ¼ ½ ¾ ª º) are tokenized
- Area
- analysis / WordDelimiterGraphFilterFactory and WordDelimiterFilterFactory types option (parseTypes) versus the default WordDelimiterIterator character-type table
- Priority
- Low, rank 446: An opt-in WordDelimiterGraphFilterFactory types file silently changes how 8 uncommon Latin-1 characters are tokenized, but index and query stay consistent when they share the analyzer, so it closes the minor analysis tokenization-quality rows after LFV-703.
- Impact class
- minor
- Impact note
- Only applications that set the opt-in types option of WordDelimiterGraphFilterFactory or the deprecated WordDelimiterFilterFactory (a types file, for example Solr's types="wdfftypes.txt") are hit, and only for text with superscript one to three, the fractions ¼ ½ ¾ or the ordinal indicators ª º: those characters are tokenized differently from the same chain without a types file ('m²' gives [m, ²] instead of [m], '1½' gives [1½] instead of [1], a lone '¼' gives [¼] instead of nothing, 'ªB' stays [ªB] instead of [ª, B]), with no error; when one analyzer is used at index and query time the terms stay consistent, so missed or extra hits need index and query analyzers that differ in having a types file, or a rule added without reindexing; tiny inputs, -ea and -da, every Lucene release from 4.0.0-BETA (WordDelimiterGraphFilterFactory from 6.5.0) to 10.6.0 and main.
- Summary
- You give WordDelimiterGraphFilterFactory a types file with one rule for a character that is not in your text (for example '$ => DIGIT', or even '- => SUBWORD_DELIM', which '-' already is) and expect every other character to keep the type it has without the option. Instead parseTypes fills all 256 Latin-1 entries from WordDelimiterIterator.getType() (the Unicode general category), while the table the filter uses without the option is built from Character.isLowerCase/isUpperCase/isDigit; the two disagree on exactly 8 characters, so 'm² x³ 1½ ¼' analyzes to [m, ², x, ³, 1½, ¼] instead of [m, x, 1] and 'ªB' is no longer split. Nothing reports an error; a small change that seeds the Latin-1 entries from the default table fixes both factories.
- Introduced
- 33cc5a041e8125a5ecf8e58c994fece4cfb03c7f (SOLR-2059 'Allow customizing how WordDelimiterFilter tokenizes text', SVN r990451 on trunk, by GitHub rmuir; SVN era, no GitHub PR) and its same-day branch_3x backport 878a697766c0 (r990456), which shipped in Solr 3.1.0: they add parseTypes with the comment 'ensure the table is always at least as big as DEFAULT_WORD_DELIM_TABLE for performance' and the loop 'types[i] = WordDelimiterIterator.getType(i)' over every entry, and make getType public for it [read: git history and blame of WordDelimiterFilterFactory.java:175-180 on main; exec: Solr 3.1.0 is affected, Solr 1.4.1 has no types option]. The WordDelimiterGraphFilterFactory copy came with LUCENE-7619 (apache/lucene#8670, by GitHub mikemccand): branch_6x 4e4ec082caa7, master 637915b890d9 [read: blame of WordDelimiterGraphFilterFactory.java:179-187; exec: 6.4.2 has no such factory, 6.5.0 is affected]. The two tables that disagree are older (Latin-1 table from the first WordDelimiterFilter, 148b4dbc923, 2006; the Character.getType switch with OTHER_NUMBER -> DIGIT and OTHER_LETTER -> ALPHA from SOLR-1078, 79414d2b726, 2009, used then only above the table); SOLR-2059 is the first change that types U+0000-U+00FF with getType. Later changes to these lines are formatting only (8ef6a0da5687 LUCENE-9570, 8ac26737913d LUCENE-10003). Not a regression: present since the option was added (2010-08-28 (SOLR-2059, author date 2010-08-28T21:25:44Z trunk, 22:01:10Z branch_3x); the WordDelimiterGraphFilterFactory copy 2017-01-17 (LUCENE-7619))
- First affected version
- Lucene 4.0.0-BETA [exec] (first Lucene artifact with WordDelimiterFilterFactory, moved from Solr into the analysis module; first GA release 4.0.0 [exec]; the 4.0.0-ALPHA Lucene jar has no factory, compile error [exec]); before that as Solr code from Solr 3.1.0 [exec]; WordDelimiterGraphFilterFactory from 6.5.0 [exec] (6.4.2 has no such factory [exec])
- Affected versions
- every Lucene release from 4.0.0-BETA to 10.5.2, the branch_10_6 head 4ae946e5a9b9 (10.6.0, released 2026-10-29) and main a9779ef3c193; Solr 3.1.0-3.6.2 as Solr code. [exec, follow-up history sweep, JDK 25.0.3 aarch64, rule '$ => DIGIT', 9 of 10 probe texts without '$' change] Solr 3.1.0; Lucene 4.0.0-BETA, 4.0.0, 4.4.0, 4.10.4, 5.0.0 and 6.4.2 (WordDelimiterFilterFactory; the graph factory is absent), 6.5.0, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.5.2, branch_10_6 4ae946e5a9b9 and main (-ea and -da) (both factories); the candidate JUnit fails on 9.12.3, 10.5.2, branch_10_6 and main (-ea and -da); the independent reproduction's JUnit fails on main (-ea and -da), 10.5.2 and 9.12.3. [read] the key lines are identical apart from formatting at 3.1, 4.0.0-beta, 6.5.0, 8.8.1, 9.12.3, 10.5.2 and main; releases between the executed ones are inferred from tag containment and unchanged code. Not affected: Solr 1.4.1 and earlier (no types option, jar inspection). Not fixed upstream: upstream main 20ced71c1e6e (2026-10-27) last changed the two factories in 378ca8d1bbf3 (2026-01-15, javadoc tag). JDK caveat: the 6 number characters differ on every JDK; ª and º differ only where the JDK's Unicode data gives them category Lo (JDK 25: yes; Unicode 3.2 data: Ll, so on 2010-era JDKs most likely only 6 characters differed; no old JDK was run)
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: code reading; also reached by exhaustive check
- Upstream and prior reports
- none found (2026-10-28; the prior-report record verdict new, 177 recorded queries: a scripted prior-report search over GitHub issues, PRs and commits, downstream repositories (elastic/elasticsearch, opensearch-project/OpenSearch, apache/solr), the dev@, java-user@, issues@ and commits@ lists, JIRA and the web; direct GitHub searches over apache/lucene and the three downstream repositories; JIRA JQL over the LUCENE and SOLR projects; the solr-user@, solr-dev@, users@solr and dev@solr lists; the changed files of all 411 open apache/lucene PRs and of the 50 closed or merged PRs updated since 2026-10-14 (no PR touches parseTypes or WordDelimiterIterator; #202 and #16911 only delete files wholesale); SOLR-2059, SOLR-3102, SOLR-1078, SOLR-1710, LUCENE-3410, LUCENE-8695, LUCENE-10097 and SOLR-11700 read with comments; 25 hits analysed, all same_bug false; the finder's, the independent reproduction's, the intended-behaviour check's and the adjudication's searches agree). Check (2026-10-28): none of the 60 apache/lucene PRs updated since 2026-10-26 touches WordDelimiter code; none of the 6 issues opened since 2026-10-25 reports it; #16918 (by GitHub javanna, 2026-10-27, 'Deprecations slated for removal in 11.0') lists WordDelimiterFilter/WordDelimiterFilterFactory for removal, which would delete one of the two copies on main but not WordDelimiterGraphFilterFactory (not a report of this bug). Not fixed upstream: upstream main 20ced71c1e6e last changed the two factories in 378ca8d1bbf3 (2026-01-15, javadoc tag). Closest items: SOLR-2059 (added the option and the getType seeding; its 5 comments never mention the Latin-1 table), SOLR-3102 (documentation of the option, 'adjust how WordDelimiterFilter splits on a per-character basis'), SOLR-1078 (2009, the getType switch, used only above the table); downstream elastic/elasticsearch#2145 and opensearch-project/OpenSearch#6867 are other defects in those products' own copies of parseTypes. Gaps: private reports to security@lucene.apache.org cannot be searched; GitHub search is token-based and cannot search for the symbols ² ½ º reliably; searches cannot prove absence
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26): the compact JUnit through gradle in a scratch worktree of that commit with only the test added, stock and with fixes A and B, assertions on and off for fix A, plus the wholelucene/analysis/commontest task and its lint checks with fix A and the test task with fix B; through the hunt's classpath runner, the same JUnit on main (-ea,-da), 10.5.2 and 9.12.3, and every repro of the hunt with each fix shadowed (2026-10-28). Hunt runs: Solr 3.1.0 and 15 Lucene releases or heads from 4.0.0-BETA to main, on OpenJDK 25.0.3, Linux aarch64.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilterFactory.java:50-67 (class javadoc; types example at :62), :135-147 (inform loads the types files), :155 (create uses DEFAULT_WORD_DELIM_TABLE without the option), :164-187 (parseTypes; comment :179; getType(i) loop :184) (read at a9779ef3c193)lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterFilterFactory.java:56 (@Deprecated), :151 (default table), :160-183 (same parseTypes; comment :175; getType(i) loop :180)lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterIterator.java:88-105 (DEFAULT_WORD_DELIM_TABLE from isLowerCase/isUpperCase/isDigit), :302-307 (charType falls back to getType above the table), :315-360 (getType; OTHER_LETTER -> ALPHA :324, OTHER_NUMBER -> DIGIT :332)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilterFactory.java (lines 51-68, 139-158, 164-188 at a9779ef3c193)lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterFilterFactory.java (lines 151, 160-184)lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterIterator.java (lines 29-41, 88-105, 227-245, 302-307, 315-360)
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilterFactory.java (lines 54-64, 179); lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterFilterFactory.java (line 175)lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilter.java (line 47), WordDelimiterFilter.java (line 40)
- TestWdgfTypesRuleKeepsOtherTypes.java (JUnit test):
repro/LFV-851/src/org/apache/lucene/analysis/miscellaneous/TestWdgfTypesRuleKeepsOtherTypes.java(61 lines)
assets/LFV-851/bug.png(502 KB)