QUERY mode joins a kana token with the letter the input method is still composing and romanizes the pair from the bundled table romaji_map.txt. For a small tsu plus a pending c, j, f or v the table has no row.
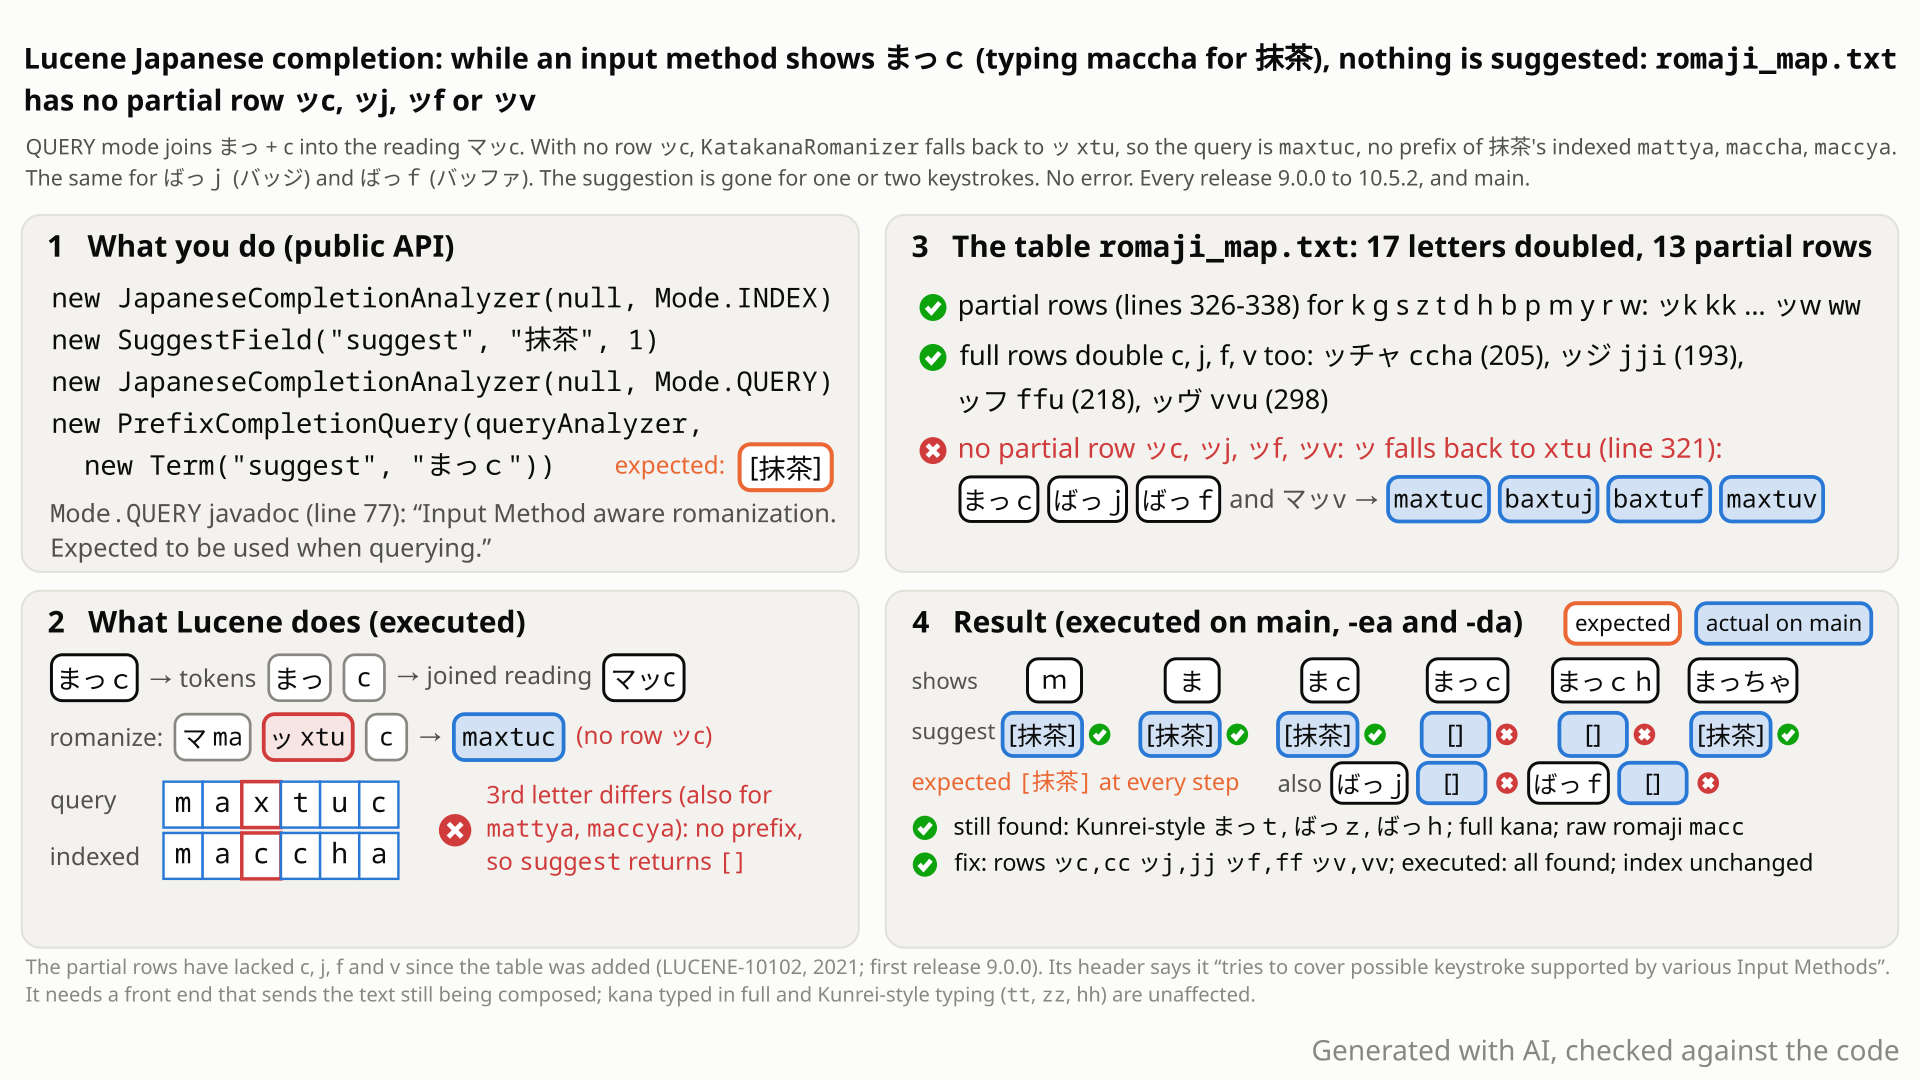
まっc is romanized to maxtuc, the table's partial-input rows ッk … ッw with no ッc, and the executed result. Select the still to open it at full size. Generated with AI, checked against the code.- You index 抹茶 (maccha), バッジ (bajji), スタッフ (sutaffu) and サッカー (sakkaa) as suggestions with
JapaneseCompletionAnalyzer, and send the text the input method is still composing to a QUERY-modePrefixCompletionQuery. - Typing
m-a-c-cshowsまっc. You expect 抹茶 to stay suggested, asさっk(typingsakk) keeps サッカー: QUERY mode joinsまっ+c, andmaccis a prefix of 抹茶's indexedmaccha. - Instead
まっcbecomesmaxtucand matches nothing; so doesまっch(maxtuch).まcone keystroke earlier andまっちゃtwo later do suggest 抹茶.ばっj(baxtuj) andすたっf(sutaxtuf) are the same. No error. - Why: the table's rows for a small tsu plus a pending letter,
ッk,kktoッw,ww, cover 13 letters. Its full small-tsu rows also double c, j, f and v (ッチャ,ttya,ccha,ccya,ッジ,zzi,jji,ッフ,hhu,ffu,ッヴ,vvu). Without aッcrow, ッ falls back toxtuand the letter is appended.
Applications using the opt-in JapaneseCompletionAnalyzer or JapaneseCompletionFilter in QUERY mode (search servers expose it as kuromoji_completion) whose front end sends in-progress input-method text. Users who type the Hepburn or wapuro way (cc, jj, ff, vv) lose all suggestions for one or two keystrokes. Kunrei typing and committed kana are unaffected; nothing throws.
Mechanism, terms and numbers663 words
Kuromoji's completion analyzer (JapaneseCompletionAnalyzer, JapaneseCompletionFilter) adds romaji tokens to each Japanese word so an autocomplete can match Latin-letter input. Its QUERY mode is documented as "Input Method aware romanization": when the input method still shows a small tsu plus a pending letter, as in さっk while typing sakkaa, it joins the two tokens and romanizes them (sakk), so サッカー stays suggested. The bundled table romaji_map.txt has such rows only for k, g, s, z, t, d, h, b, p, m, y, r and w, although its own full small-tsu rows also double c, j, f and v. So まっc (typing maccha), ばっj (bajji), すたっf (sutaffu) are romanized maxtuc, baxtuj, sutaxtuf and suggest nothing for one or two keystrokes. Every release from 9.0.0 to 10.6.0 and main; the fix is four table rows.
- Small tsu (っ / ッ): doubles the next consonant. 抹茶 is read マッチャ, ma-ccha.
- Composition text: a Japanese input method shows what you type before you commit it. Doubling a consonant shows a small tsu plus the still-pending letter:
s-a-k-kshowsさっk,m-a-c-cshowsまっc. The open-source Mozc input method's romaji table mapskk,cc,jj,ff,vv(and Hepburntch) this way. - QUERY mode:
JapaneseCompletionFilter.Mode.QUERY, "Input Method aware romanization. Expected to be used when querying." When a token with a reading (here the kanaまっ) is followed by a lowercase-letter token it joins them and romanizes the result: the code comment says "words that are in mid-IME composition are split into two tokens by JapaneseTokenizer; should be recovered when querying ... e.g.: "サッ" + "k" => "サッk"" (JapaneseCompletionFilter.java:180-193). A test assertsサッk→sakk. romaji_map.txt: each row maps a key to its romaji;KatakanaRomanizermatches the longest key first; at the first position no key matches it stops and appends the rest of the reading, unchanged, to what it has built so far. Rows:326-338cover a small tsu plus one pending letter:ッk,kkッg,ggッs,ssッz,zzッt,ttッd,ddッh,hhッb,bbッp,ppッm,mmッy,yyッr,rrッw,ww.
The full small-tsu rows double 17 letters; the partial rows cover 13. The missing four:
| letter | full rows that double it | composition | query romaji |
|---|---|---|---|
| k (control) | :168 ッカ,kka ... | さっk | sakk (prefix of サッカー's sakkaー) |
| c | :205-207 ッチャ,ttya,ccha,ccya ... | まっc, まっch | maxtuc, maxtuch |
| j | :193 ッジ,zzi,jji, :197-199 ッジャ,zzya,jja ... | ばっj | baxtuj |
| f | :218 ッフ,hhu,ffu, :292-295 ッファ,hhwa,ffa,... | すたっf, ばっf | sutaxtuf, baxtuf |
| v | :296-300 ッヴァ,vva,vvuxa ... ッヴ,vvu | マッv (table level) | maxtuv |
With no ッc row the longest match at ッ is the bare :321 ッ,xtu, and c matches no key, so it is appended (KatakanaRomanizer.java:162-167). On the index side the full ッチ, ッジ, ッフ and ッヴ rows take a single small tsu, so a kana reading yields xtu before c, j, f or v only after a doubled small tsu (ッッジ → xtujji; checked over all katakana strings up to length 4). No indexed spelling of 抹茶 starts with maxtuc, so the prefix query matches nothing.
Typing maccha: まc → mac suggests 抹茶; まっc → maxtuc and まっch → maxtuch suggest nothing; まっちゃ → [mattya, maccha, maccya] suggests 抹茶 again. Likewise ばっj → baxtuj (バッジ is [bazzi, bajji]), すたっf → sutaxtuf (スタッフ is [sutahhu, sutaffu]), じゃっj → [zyaxtuj, jaxtuj] (ジャッジ has jajji), きゃっc → kyaxtuc (キャッチャー). Kunrei typing keeps it: まっt → matt. Half-width まっc behaves the same.
The code follows the table: romanize() equals an independently coded longest-match model of the same table on 59,120,615 inputs (0 mismatches; a shortest-match mutant was caught). A sweep that checked 367,780 simulated composition states of 43,775 synthetic one- and two-unit words found failing tails only after っc, っf, っj, っv (and っh, which belongs to a sibling bug's malformed ッへ row).
Exposure and likelihood277 words
- Who. Applications that build Japanese autocomplete with
JapaneseCompletionAnalyzerorJapaneseCompletionFilterin QUERY mode (also through the analysis SPI asjapaneseCompletion; search servers built on Lucene expose it as akuromoji_completiontoken filter) and whose front end sends the text the input method is still composing, the use the feature was built for (#11140). Opt-in. - What triggers it. Ordinary typing of words with っち/っちゃ, っじ, っふ/っふぁ or っゔ the Hepburn or wapuro way: 抹茶
maccha, キャッチャーkyacchaa, バッジbajji, ブリッジburijji, スタッフsutaffu, バッファbaffa. Hepburnmatch...also passes throughまっch. How often users type this way was not measured. - How long. One keystroke (
っj,っf,っv) or two (っc, thenっch); the states before and after suggest normally. - Not hit. Kunrei typists (
tt,zz,hh), kana typed or committed in full, raw romaji queries (not joined to kana) and INDEX-mode tokens of kana readings. Nothing throws and the index is unchanged. - After a fix the new rows match only a small tsu directly followed by a Latin letter. QUERY mode builds that by joining tokens; INDEX mode romanizes each token's reading as it is, and a kana-only reading can never match the new keys. The index-side tokens of the 9 probed words are identical with and without the fix. One exception: a user-dictionary reading may contain Latin letters (readings are not checked), and an entry 試験 read
アッcis indexed asaxtucon main butaccwith the fix. So existing suggest fields need no reindexing unless a user dictionary has readings with a Latin letter after ッ.
The test shows that in QUERY mode JapaneseCompletionAnalyzer romanizes the mid-composition input 'まっc' (typing maccha for 抹茶) as maxtuc, because romaji_map.txt has small-tsu + pending-letter rows only for k..w, not c/j/f/v, so the completion prefix can never match.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.ja;

import java.util.ArrayList;
import java.util.List;
import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.TokenStream;
import org.apache.lucene.analysis.tokenattributes.CharTermAttribute;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestCompletionPendingLetterAfterSmallTsu extends LuceneTestCase {

  public void testMidCompositionMacc() throws Exception {
    List<String> terms = new ArrayList<>();
    try (Analyzer analyzer =
            new JapaneseCompletionAnalyzer(null, JapaneseCompletionFilter.Mode.QUERY);
        TokenStream ts = analyzer.tokenStream("f", "まっc")) {
      CharTermAttribute term = ts.addAttribute(CharTermAttribute.class);
      ts.reset();
      while (ts.incrementToken()) {
        terms.add(term.toString());
      }
      ts.end();
    }
    // expected "macc" (prefix of 抹茶's index-side "maccha", as "さっk" gives "sakk"); actual "maxtuc"
    assertTrue(
        "expected macc among the query-side tokens, actual: " + terms, terms.contains("macc"));
  }
}
# in a copy of this finding's repro folder (repro/LFV-854/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/analysis/kuromoji/build/libs/lucene-analysis-kuromoji-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.ja.TestCompletionPendingLetterAfterSmallTsu
# the module(s) analysis-kuromoji also need their third-party runtime jars
- Expected vs actual
- Expected
maccamong the query-side tokens (as 'さっk' givessakk); actual[まっc, maxtuc], with-eaand-da.
More files, environment, full output38 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected macc among the query-side tokens, actual: [まっc, maxtuc]
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.assertTrue(Assert.java:42)
org.apache.lucene.analysis.ja.TestCompletionPendingLetterAfterSmallTsu.testMidCompositionMacc(TestCompletionPendingLetterAfterSmallTsu.java:41)- The full small-tsu rows double 17 letters, the partial-input rows only 13; the missing four are exactly c, j, f, v.
- QUERY mode is "Input Method aware romanization" and joins a pending letter for this very state; a test pins
サッk→sakk. - In the introducing PR's review,
jjiwas added on request, but noッjpartial row.
The full argument299 words
- The table contradicts itself. Its full small-tsu rows double 17 letters, its partial-input rows cover 13, and the four missing (c, j, f, v) are the letters that no Kunrei-shiki or Nihon-shiki spelling uses (per a reference table of the three systems; modified Hepburn uses all four; the table itself does not label its spellings by system). The javadoc and the table header list "(modified) Hepburn-shiki, Kunrei-shiki (Nihon-shiki) and Wāpuro shiki" as supported (
JapaneseCompletionFilter.java:41-42,romaji_map.txt:3). - The state is handled on purpose.
Mode.QUERYis "Input Method aware romanization" (:77); the join exists for exactly this state (:184-188);TestJapaneseCompletionFilterassertsサッk→sakkandTestKatakanaRomanizerassertsコダッk→kodakk. - The design goal names it. #11140: "When querying, mid-IME composition strings will be sent to the search systems, and auto-complete systems should handle them (or, it may just ignore such inputs, but it hurts users' experience)."
- The
jjgap arose in review. In PR #297 a reviewer (GitHub johtani) asked: "Should we addjji? I usually usejajjiforジャッジ. What do you think?"; the author (GitHub mocobeta) answered "yes, of course" and addedjji/jja/jju/jjoto the full rows (review commitfc90e452474), but noッj,jjrow. The reviewer's ownjajjipasses throughじゃっj, which romanizes to[zyaxtuj, jaxtuj]and matches nothing. The c, f and v gaps were already in the PR's first commit, next to full rows withccha,ffuandvvu. - No documented or tested behaviour depends on it. For kana readings,
maxtuc,baxtuj,sutaxtufstart an indexed spelling only after a doubled small tsu. The javadoc's only example of an unsupported case is circumflex/macron long vowels; no comment, test, CHANGES or MIGRATE entry mentions the partial rows.
The devil's-advocate check172 words
The strongest case (the intended-behaviour checker and the cross-model review): the javadoc says the filter "does not strictly comply ... but tries to cover possible keystroke supported by various Input Methods" (best effort); the 13 partial rows are all Kunrei-shiki consonants (every one except n, which no full small-tsu row doubles), so they could be a deliberate Kunrei-only set; #11140 allows that a system "may just ignore such inputs"; only k is tested; the suggester classes are @lucene.experimental.
Why it fails: the same table accepts cc, jj, ff, vv in its full rows, so a Kunrei-only rule is not what the table does; jji was added on request without the matching partial row, which reads as an oversight; the "may just ignore" clause describes systems that ignore composition text altogether, while this filter handles it for 13 of the 17 letters; and the defect is in the kuromoji filter's tokens, not in the experimental suggester API. What remains is a labelling question (bug fix or improvement), not intent.
Recommended Add the four missing partial-input rows
Add four rows to romaji_map.txt after ッw,ww: ッc,cc, ッj,jj, ッf,ff, ッv,vv. Data only; for kana readings only query-side tokens change, so no reindexing should be needed (unless a user dictionary has readings with a Latin letter after ッ). The repro passes, and the whole kuromoji test task passes (197 tests, 0 failures) with assertions on and off.
--- a/lucene/analysis/kuromoji/src/resources/org/apache/lucene/analysis/ja/completion/romaji_map.txt
+++ b/lucene/analysis/kuromoji/src/resources/org/apache/lucene/analysis/ja/completion/romaji_map.txt
@@ -336,6 +336,10 @@
 ッy,yy
 ッr,rr
 ッw,ww
+ッc,cc
+ッj,jj
+ッf,ff
+ッv,vv

 # below are characters that should be kept but have no explicit romanization rules.
 # Chōonpu (Katakana-Hiragana Prolonged Sound Mark)
All options and trade-offs3 options · 512 words
The recommended option is a four-line edit of the bundled table, validated in a scratch worktree at a9779ef3c193 with the whole :lucene:analysis:kuromoji:test task plus the paste-ready test, assertions on and off. The two other options were not run.
With it, まっc → macc, まっch → macch, ばっj → bajj, ばっf → baff, すたっf → sutaff, じゃっj → [zyajj, jajj], きゃっc → kyacc, ぶりっj → burijj: each a prefix of an indexed spelling. さっk and まっt are unchanged.
--- a/lucene/analysis/kuromoji/src/resources/org/apache/lucene/analysis/ja/completion/romaji_map.txt
+++ b/lucene/analysis/kuromoji/src/resources/org/apache/lucene/analysis/ja/completion/romaji_map.txt
@@ -336,6 +336,10 @@
 ッy,yy
 ッr,rr
 ッw,ww
+ッc,cc
+ッj,jj
+ッf,ff
+ッv,vv

 # below are characters that should be kept but have no explicit romanization rules.
 # Chōonpu (Katakana-Hiragana Prolonged Sound Mark)
Trade-offs
- Each new row has one spelling, so it adds no romaji combinations (a separate expansion issue is untouched).
- For kana readings only query-side tokens change (the new keys contain a Latin letter); the index-side tokens of the 9 probed words are identical with and without the fix, so existing suggest fields should not need reindexing. A user-dictionary reading with a Latin letter after ッ does change (
アッc:axtucbefore,accafter), so such fields would need reindexing. - Where a full row lacks the doubled spelling, this fix alone does not bring the suggestion back: ッチ has only
tti(a sibling bug), so マッチ typedmacchistill misses atまっc(maccagainstmatti). The examples here fail for this root cause alone. - A PR could add one assertion per letter to
TestKatakanaRomanizer.testRomanizeWithAlphabets(likeコダッk→kodakk) and aまっccase toTestJapaneseCompletionFilter.testCompletionQuery(likeサッk).
What the checks validated
- Scratch worktree at
a9779ef3c193, gradle, seed DEADBEEF: the paste-ready test fails on stock main with assertions on and off (2 of 2); with this fix the whole:lucene:analysis:kuromoji:testtask passes, 31 classes, 197 tests, 0 failures (7 skipped, all in pre-existing module tests: TestExtendedMode 1, TestFactories 1, TestJapaneseNumberFilter 2, TestJapaneseTokenizer 3), with assertions on and off, including the completion suites TestJapaneseCompletionAnalyzer, TestJapaneseCompletionFilter, TestJapaneseCompletionFilterFactory and TestKatakanaRomanizer. - With the paste-ready test,
ecjLintTestandcheckGoogleJavaFormatof the module pass. - The repro runner with the fixed table first on the class path: the paste-ready test passes with assertions on and off, and the end-to-end suggester test passes with assertions off. Earlier, the independent reproducer's and the intended-behaviour checker's tests passed with the same four rows.
In the static initializer of KatakanaRomanizer (:44-84), add ッX → XX for every letter X that some full ッ row doubles.
Trade-offs
Self-maintaining if rows are added later, but it moves a table rule into code and changes behaviour that is now plain data; more than the defect needs. Not run.
Add "a small tsu followed by a pending c, j, f or v is not supported" to the javadoc's limitation (JapaneseCompletionFilter.java:44-48).
Trade-offs
No behaviour change; contradicts the table's own full rows. Not recommended.
Search servers that expose this filter as kuromoji_completion load the same table from the Lucene jar, so their Japanese autocomplete should show the same gap while composing (inferred from the code; not run on those servers).
Semi-formal. A table consistency check (partial-input rows must cover every letter the full small-tsu rows double) flagged c, f, j and v; a sweep of 367,780 simulated input-method states through the real query-side romanizer failed only after those four letters, plus a っh tail from a sibling bug. A public-API suggester test then reproduced the missing suggestions.
The method in full279 words
- Table laws. A model of the table's rules; law L2p (partial-input rows
ッ<letter>must cover every letter the full ッ rows double) flagged exactlyッc,ッf,ッj,ッv. - Translation validation (bounded-exhaustive). Part A:
romanize()equals an independent longest-match model of the table on all 1,830,854 inputs of length up to 3 and all 57,289,761 inputs of length 4 over the key katakana (0 mismatches; a shortest-match mutant was caught), so the code agrees with the table on those inputs and the fault is in the data. The same log then ends with an out-of-memory error in a later part that is not used here. - Composition sweep. Part C2 took all 43,775 one- and two-unit katakana words (up to 4 kana, no ン) and typed each index-side spelling that a model input method (the open-source Mozc romaji table) composes back to the word (5,643 word/spelling pairs that do not were skipped). Each composition state, romanized by the stock QUERY path, had to stay a prefix of an indexed spelling, checked up to the first failing state of each spelling: 367,780 states. The only failing tails:
っc918,っf1,993,っj1,075,っv1,687 word/spelling pairs, andっh463 (a sibling bug'sッへrow). With all table fixes: 0 of 432,288 checked states fail (8,344 pairs skipped). The two totals are not comparable: the fixed table has more spellings and the stock run stops each failing spelling early. - Reduction. A public-API JUnit with the document suggester on the stock main jars (2026-10-28), then this doc's kuromoji-only test.
- Tier. Semi-formal: the first signal came from a table self-consistency script, not from a solver's or model checker's own output.
No prior report found (as of 2026-10-28) in GitHub issues, PRs and commits, JIRA, the mailing lists, open PRs' changed files, downstream projects, code search and the web. Closest: the introducing PR #297, whose review added jji to the full ッジ row without a ッj partial row.
Searches4 searches
No report of this defect was found. The closest upstream text is the PR #297 review exchange about jji, which explains how the j gap arose but is not a report of it. The table's data rows have not changed since 9.0.0, and no open PR touches the file except #16911, which deletes branch_10x. Of 17 indexed copies of the table found by code search, none has a ッc,cc row.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene), downstream repositories, mailing lists (dev@, java-user@, issues@, commits@), JIRA archive, web | 2026-10-28 | the scripted prior-report search, 51 queries (95 hits, 0 high), plus a lists and JIRA variant (275 hits, every post-2021 thread title read) | only the introduction (LUCENE-10102 / #11140, #297) and unrelated items |
| GitHub, by hand (apache/lucene, downstream trackers, code search) | 2026-10-28 | English and Japanese queries (small tsu, IME composition, mid-IME, maccha, sokuon, 促音, ローマ字, romaji, kuromoji completion, JapaneseCompletionFilter, KatakanaRomanizer); 17 indexed copies of the table | #11140, #297, #12047 (header typos), #11399 (offsets), #16416 (buffering), #12885 (a different romanizer); no copy of the table has a ッc,cc row; two downstream ports copy the gap |
| Open and recent PRs | 2026-10-28 | the changed-file lists of all 411 open apache/lucene PRs (the 4 lists cut at 100 files were re-read through the REST files endpoint); PRs created since 2026-10-26; the 23 PRs updated on 2026-10-28 | none touches romaji_map.txt, KatakanaRomanizer or JapaneseCompletionFilter (#16911 deletes branch_10x; not a fix) |
| Web and forums (English and Japanese) | 2026-10-28 | romaji_map.txt, kuromoji_completion mid-composition, 促音 サジェスト | vendor documentation and how-to posts (one documents the サッ + k join as a feature); none mentions these rows. The author's 2020 gist precursor of the table has no partial rows at all |
In the table since the feature was added (4e86df96c03, #297, 2021-09-17; first released in 9.0.0); the four rows never existed. Fails on all 33 releases from 9.0.0 to 10.5.2, on 10.6.0 (branch_10_6 4ae946e5a9b) and on main.
Versions tested5 rows
Introduced with the feature: 4e86df96c03 "LUCENE-10102: Add JapaneseCompletionFilter for Input Method-aware auto-completion (#297)", 2021-09-17 (issue #11140), which created romaji_map.txt; git blame attributes :326-338 to it, and no commit in any branch ever had a ッc,, ッj,, ッf, or ッv, row. The PR's first commit dff3942eed5 (2021-09-13) already had the 13 partial rows next to ccha, ffu and vvu; review commit fc90e452474 added jji to the full rows only. The only later commit to the file, 4676a735c18 (#12047, 2023-01-02), fixed header comments.
Executed: all 33 releases from 9.0.0 to 10.5.2 and the branch_10_6 head 4ae946e5a9b (a hybrid run; its completion files are byte-identical to main) fail 7 of 7 defect checks with 0 of 7 controls failing (assertions on); main fails with assertions on and off. 8.10.1 and 8.11.x have no completion filter. No fix upstream.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | paste-ready test fails (gradle and runner, assertions on and off); the end-to-end and reproducer tests fail |
| 10.5.2, 9.12.3 | affected | paste-ready test fails with the same messages (published jars; 10.5.2 with assertions on and off) |
9.0.0 to 10.5.2 (33 releases), branch_10_6 4ae946e5a9b | affected | history probe: 7 of 7 defect checks fail, 0 of 7 controls fail, in every release |
| 8.10.1, 8.11.0, 8.11.4 | no API | no completion filter: the probe fails to compile on the missing completion classes |
| main + the 4-row fix | not affected | paste-ready and end-to-end tests pass; the whole kuromoji test task passes (197 tests) |
The finder, an independent reproducer, an intended-behaviour checker, the adjudication and a credibility audit all ran code and said real. A reviewer from another model family (OpenAI GPT-5.6) could not run code; on reading it agreed with the root cause. This doc's gradle runs confirm the repro and the fix.
Checks and verdicts344 words
Every verdict except the cross-model review's rests on executed runs on main a9779ef3c193. The cross-model review read the checkout at ea57360912ed, where the table is the same blob.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Table-law model (law L2p flags c, f, j, v), bounded-exhaustive check of the real romanizer and composition sweep; the end-to-end JUnit fails on main with assertions on and off and on 10.5.2; the 4-row fix passes. |
| independent reproducer | real, Low | Own public-API test with other words (キャッチャー, ブリッジ, スタッフ, 抹茶, v at table level): 3 of 3 fail on main (on and off), 10.5.2 (on and off) and 9.12.3, a main() variant fails on 9.0.0; controls pass; the suggestion is present one keystroke before and after; the 4-row fix passes, and 11 upstream completion tests pass with it. |
| intended-behaviour checker | real, high (low impact) | Built and rejected the best-effort, Kunrei-only, 'may just ignore such inputs' and 'only k is tested' readings; found the jji review exchange (じゃっj matches nothing); own test fails on main (on and off) and 10.5.2, passes with the fix. |
| refute review (OpenAI GPT-5.6) | not real, low (procedural) | Could not run any command, so it voted not real on procedure only; on reading: root cause agrees, inputs in contract, "Static evidence strongly favors the candidate"; rated the intended-behaviour case moderate. Its step re-ran the finder's test: fails on main (on and off) and 10.5.2; a stock-versus-fixed pair fails, then passes. |
| adjudication | confirmed, high; minor | Re-ran the reproducer's test on main with assertions on and off: 3 of 3 fail; with only the 4 rows: 0 of 3. |
| credibility audit | keep | Re-ran the finder's test on main with assertions off: fails, control passes; re-read the table rows and re-checked prior art. |
| this doc | reproduces; fix validated | Gradle in a scratch worktree: the paste-ready test fails on stock main with assertions on and off; the 4-row fix passes the whole kuromoji test task (197 tests) with assertions on and off, and lint. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 532 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,590 words
- Registry title
- Kuromoji completion suggester (JapaneseCompletionAnalyzer / JapaneseCompletionFilter, QUERY mode) suggests nothing while an input method shows a small tsu plus a pending c, j, f or v ('まっc' while typing maccha for 抹茶, 'ばっj' for bajji, 'すたっf' for sutaffu), because romaji_map.txt has the partial-input rows ッk..ッw but none for ッc, ッj, ッf or ッv, although its full rows double those letters (ッチャ ccha, ッジ jji, ッフ ffu, ッヴ vvu)
- Area
- analysis / kuromoji completion (JapaneseCompletionFilter QUERY-mode handling of mid-IME composition; the partial-input rows of romaji_map.txt, read by KatakanaRomanizer)
- Priority
- Low, rank 509: In the opt-in kuromoji completion QUERY mode, suggestions disappear for only one or two keystrokes while っc, っj, っf or っv is still being composed and nothing is wrong once the kana is complete.
- Impact class
- minor
- Impact note
- Applications that use the opt-in kuromoji JapaneseCompletionAnalyzer or JapaneseCompletionFilter in QUERY mode (default constructors once chosen; downstream search servers expose it as kuromoji_completion) and send the text an input method is still composing, the use the feature was built for (#11140), lose all suggestions for one keystroke (っj, っf, っv) or two (っc, then っch) whenever a user types a small tsu before ch, j, f or v the Hepburn or wapuro way (maccha 抹茶, bajji バッジ, sutaffu スタッフ, キャッチャー); the suggestions come back once the input method turns the pending letter into kana, kana typed in full and Kunrei-style typing (tt, zz, hh) are unaffected, nothing throws and the index is unchanged; every release from 9.0.0 to 10.5.2, branch_10_6 (10.6.0) and main.
- Summary
- You build Japanese autocomplete with JapaneseCompletionAnalyzer, whose QUERY mode is documented as 'Input Method aware romanization' and joins a kana token with a still-pending romaji letter ('サッ' + 'k' => 'サッk', so 'さっk' keeps suggesting サッカー), and expect the same while a user types 'maccha' and the input method shows 'まっc'. Instead 'まっc' is romanized 'maxtuc' and nothing is suggested, and the same happens for 'ばっj' (bajji, バッジ) and 'ばっf' (baffa, バッファ), because the bundled romaji_map.txt has partial-input rows (small tsu plus one pending letter) only for k, g, s, z, t, d, h, b, p, m, y, r and w, although its own full rows double c, j, f and v (ッチャ ccha, ッジ jji, ッフ ffu, ッヴ vvu). The suggestions return one or two keystrokes later, when the input method converts the pending letters to kana.
- Introduced
- 4e86df96c0385a7b552434d7e2a9bee69f18bd77 (LUCENE-10102 / issue #11140, PR #297, 'Add JapaneseCompletionFilter for Input Method-aware auto-completion', by GitHub mocobeta, co-authored by rmuir) [read: git blame of romaji_map.txt:326-338 and git log -L326,338 list only this commit; git log -S 'ッc,' / 'ッj,' / 'ッf,' / 'ッv,' over all refs finds no commit, so those rows never existed]. Inside the PR, its first commit dff3942eed5 (2021-09-13) already had the 13 partial rows ッk..ッw next to the full rows ッチャ ccha, ッフ ffu and ッヴ vvu, and review commit fc90e452474 (2021-09-17) added jji/jja/jju/jjo to the full ッジ rows at a reviewer's request without a ッj partial row [read via the GitHub API]. Present since the feature was written; not a regression. The only later commit to the file, 4676a735c18 (#12047, 2023), changed header comments only (2021-09-17 (author date 2021-09-17T13:37:12Z; merged 2021-09-17T13:37:13Z))
- First affected version
- 9.0.0 [exec] (the first release with JapaneseCompletionFilter; CHANGES lists LUCENE-10102 under 9.0.0 only; on 8.10.1, 8.11.0 and 8.11.4 [exec] the probe does not compile because the completion API is absent)
- Affected versions
- Every release from 9.0.0 to 10.5.2 (33 releases), the branch_10_6 head 4ae946e5a9b9 (10.6.0, released 2026-10-29) and main a9779ef3c193 [exec: the follow-up's portable history probe RomajiPartialRowsHistoryProbe fails 7 of 7 defect checks with 0 control failures on all 33 releases, on main -ea and -da, and on the branch_10_6 head (a hybrid run: the 10.5.2 kuromoji jar with the one changed production source, JapaneseCompletionFilter.java, shadowed from 4ae946e5a9b, because no 10.6 kuromoji jar is cached; the five completion files there are byte-identical to main); the finder's JUnit fails on main -ea and -da, 10.5.2, 9.12.3 and 9.1.0 (it does not compile on 9.0.0, whose test framework package differs); the independent reproduction's JUnit fails on main -ea and -da, 10.5.2 -ea and -da and 9.12.3, and the independent reproduction's main() variant on 9.0.0; the intended-behaviour check's JUnit fails on main -ea and -da and 10.5.2 -da] [read: the table ships as blob 4a803a469ad in 9.0.0-9.12.3 and 8136668e708 in 10.0.0-10.5.2, branch_10_6, branch_10x and main, with identical data rows]. Not applicable to 8.x and older (API absent). No fix exists upstream. All runs: JDK 25.0.3, Linux aarch64
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal; also reached by exhaustive check
- Upstream and prior reports
- none found (2026-10-28, read-only; the prior-report record, verdict new): a scripted prior-report search with 51 queries over apache/lucene issues, PRs and commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web (95 hits, 0 high), a lists and JIRA variant (275 hits, every post-2021 thread title read), manual GitHub searches in English and Japanese ('small tsu', 'IME composition', 'mid-IME', maccha, sokuon, 促音, ローマ字 ...), downstream trackers (Elasticsearch, OpenSearch, Solr, two ports), the changed files of all 411 open apache/lucene PRs, the commit history of the table with author and committer dates on main, branch_10x and branch_10_6, GitHub code search (17 indexed copies of the table, none has a 'ッc,cc' row), web and forum searches, and the review threads of #297, #11140 and #12047; the finder, the independent reproduction, the intended-behaviour check (36 queries) and the adjudication found nothing either. Re-check 2026-10-28: no apache/lucene issue or PR updated since 2026-10-26 matches 'romaji', none updated since 2026-10-27 matches 'kuromoji', 'JapaneseCompletionFilter' returns only #11399, #16416, #11140 and #297, none of the 15 PRs created since 2026-10-26 (#16907-#16926) concerns kuromoji, the table's commits on main are still only 4e86df96c03 (author date 2021-09-17) and 4676a735c18 (author date 2023-01-01), and no commit has touched lucene/analysis/kuromoji on main since 2026-10-20. Context, not reports: #11140 and #297 (the introduction, including the 'jji' review request), #12047 (header typos), #16416 (output buffering), #11399 (offsets, open), #12885 (a different romanizer), #16911 (deletes branch_10x; not a fix), downstream exposure and documentation items, the feature author's 2020 gist precursor (no partial rows at all) and two downstream ports that copy the gap. Update 2026-11-02: #16911 (open when searched) merged 2026-10-29 as 48cf3f515d6, which emptied branch_10x to a README tombstone (10.6 is the last 10.x minor; 10.x fixes go to branch_10_6); it fixes nothing here.
- Lucene commit tested
- main
a9779ef3c193(gradle in a scratch worktree, assertions on and off, and the standalone JUnit runner); the release jars 10.5.2 (assertions on and off) and 9.12.3 (this doc's test); all 33 releases from 9.0.0 to 10.5.2 and the branch_10_6 head4ae946e5a9b(the history probe, assertions on); the 4-row fix on main (gradle, the whole kuromoji test task, assertions on and off).
- Finding record
lucene/analysis/kuromoji/src/resources/org/apache/lucene/analysis/ja/completion/romaji_map.txt:3-5 (at a9779ef3c193) (header: 'covers romanization systems: modified Hepburn-shiki, Kunrei-shiki (Nihon-shiki), and Wāpuro shiki'; 'does not strictly comply ... but tries to cover possible keystroke supported by various Input Methods')lucene/analysis/kuromoji/src/resources/org/apache/lucene/analysis/ja/completion/romaji_map.txt:326-338 (at a9779ef3c193) (partial rows ッk,kk .. ッw,ww: k g s z t d h b p m y r w only), :321 (ッ,xtu fallback), :193 (ッジ,zzi,jji), :205 (ッチャ,ttya,ccha,ccya), :218 (ッフ,hhu,ffu), :292 (ッファ,hhwa,ffa,...), :296 (ッヴァ,vva,vvuxa), :298 (ッヴ,vvu); :185 (ッシ,ssi), :201 (ッチ,tti) for the coupling with the sibling sokuon row (grep -n, 2026-10-28)lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapaneseCompletionFilter.java:36-48 (at a9779ef3c193) (class javadoc: 'Main usage of this filter is Query Auto-Completion'; supported systems; best-effort wording; only Circumflex / Macron named as unsupported), :77 (Mode.QUERY 'Input Method aware romanization. Expected to be used when querying.'), :180-193 (QUERY mode joins a kana token with a following lowercase-alphabet token: 'words that are in mid-IME composition ... should be recovered when querying', e.g. "サッ" + "k" => "サッk")lucene/analysis/kuromoji/src/test/org/apache/lucene/analysis/ja/TestJapaneseCompletionFilter.java:215-216 (at a9779ef3c193) ('サッk' -> {'サッk', 'sakk'}); test/org/apache/lucene/analysis/ja/completion/TestKatakanaRomanizer.java:52 ('コダッk' -> 'kodakk')lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/completion/KatakanaRomanizer.java:103-165 (at a9779ef3c193) (romanize: greedy longest match over the table rows, unmatched remainder appended)
- The finding in 30 seconds
lucene/analysis/kuromoji/src/resources/org/apache/lucene/analysis/ja/completion/romaji_map.txt:3-5 (at a9779ef3c193) (header), :168-175, :193, :197-199, :205-207, :218, :292-295, :296-300, :307-312, :321 (ッ,xtu), :326-338 (partial rows)lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapaneseCompletionFilter.java:41-48 (at a9779ef3c193) (javadoc), :77 (Mode.QUERY), :180-193 (mid-composition join), :217-233 (generateOutputs)lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/completion/KatakanaRomanizer.java:44-65 (at a9779ef3c193) (table load), :103-169 (romanize; remnant appended :162-167)lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapaneseCompletionAnalyzer.java:48-59 (at a9779ef3c193) (JapaneseTokenizer, JapaneseCompletionFilter, LowerCaseFilter; CJKWidthCharFilter)lucene/analysis/kuromoji/src/test/org/apache/lucene/analysis/ja/TestJapaneseCompletionFilter.java:215-216 (at a9779ef3c193) (サッk -> サッk, sakk)row counts: a parse of romaji_map.txt at a9779ef3c193 with the loader's rules (full small-tsu rows double 17 letters; partial rows cover 13; missing c, f, j, v)
- Who is affected
lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapaneseCompletionFilterFactory.java:38 (at a9779ef3c193) (SPI name japaneseCompletion)lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapaneseCompletionFilter.java:179-210 (at a9779ef3c193) (the join happens only in QUERY mode)lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapaneseCompletionFilter.java:217-228 (at a9779ef3c193) (generateOutputs romanizes the reading in both modes)lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/dict/UserDictionary.java:95-131 (at a9779ef3c193) (readings are stored without a kana check)
- Why it looks unintended
lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapaneseCompletionFilter.java:41-48, (at a9779ef3c193) :77, :184-188lucene/analysis/kuromoji/src/resources/org/apache/lucene/analysis/ja/completion/romaji_map.txt:3-5, (at a9779ef3c193) :193, :205, :218, :298, :326-338lucene/analysis/kuromoji/src/test/org/apache/lucene/analysis/ja/TestJapaneseCompletionFilter.java:215-216; (at a9779ef3c193) test/org/apache/lucene/analysis/ja/completion/TestKatakanaRomanizer.java:51-52lucene/suggest/src/java/org/apache/lucene/search/suggest/document/CompletionAnalyzer.java:35, (at a9779ef3c193) SuggestField.java:48, PrefixCompletionQuery.java:39 (@lucene.experimental)
- Suggested fix
lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/completion/KatakanaRomanizer.java:44-84 (at a9779ef3c193) (static initializer)lucene/analysis/kuromoji/src/test/org/apache/lucene/analysis/ja/completion/TestKatakanaRomanizer.java:48-52; (at a9779ef3c193) test/org/apache/lucene/analysis/ja/TestJapaneseCompletionFilter.java:215-216
- TestCompletionPendingLetterAfterSmallTsu.java (JUnit test):
repro/LFV-854/src/org/apache/lucene/analysis/ja/TestCompletionPendingLetterAfterSmallTsu.java(44 lines)
The PNG is the summary card. Made in parallel with this doc.
assets/LFV-854/bug.png(532 KB)