ICUFoldingFilter folds with a compiled table, utr30.nrm, built from Lucene's DiacriticFolding.txt. A hand-written block of that file strips descenders and strokes from Cyrillic letters: җ to ж, қ to к, ҳ to х, ҹ to ч. One line, 04B7>04BC, sends ҷ to Ҽ (ABKHASIAN CHE) instead, and case folding then makes it ҽ.
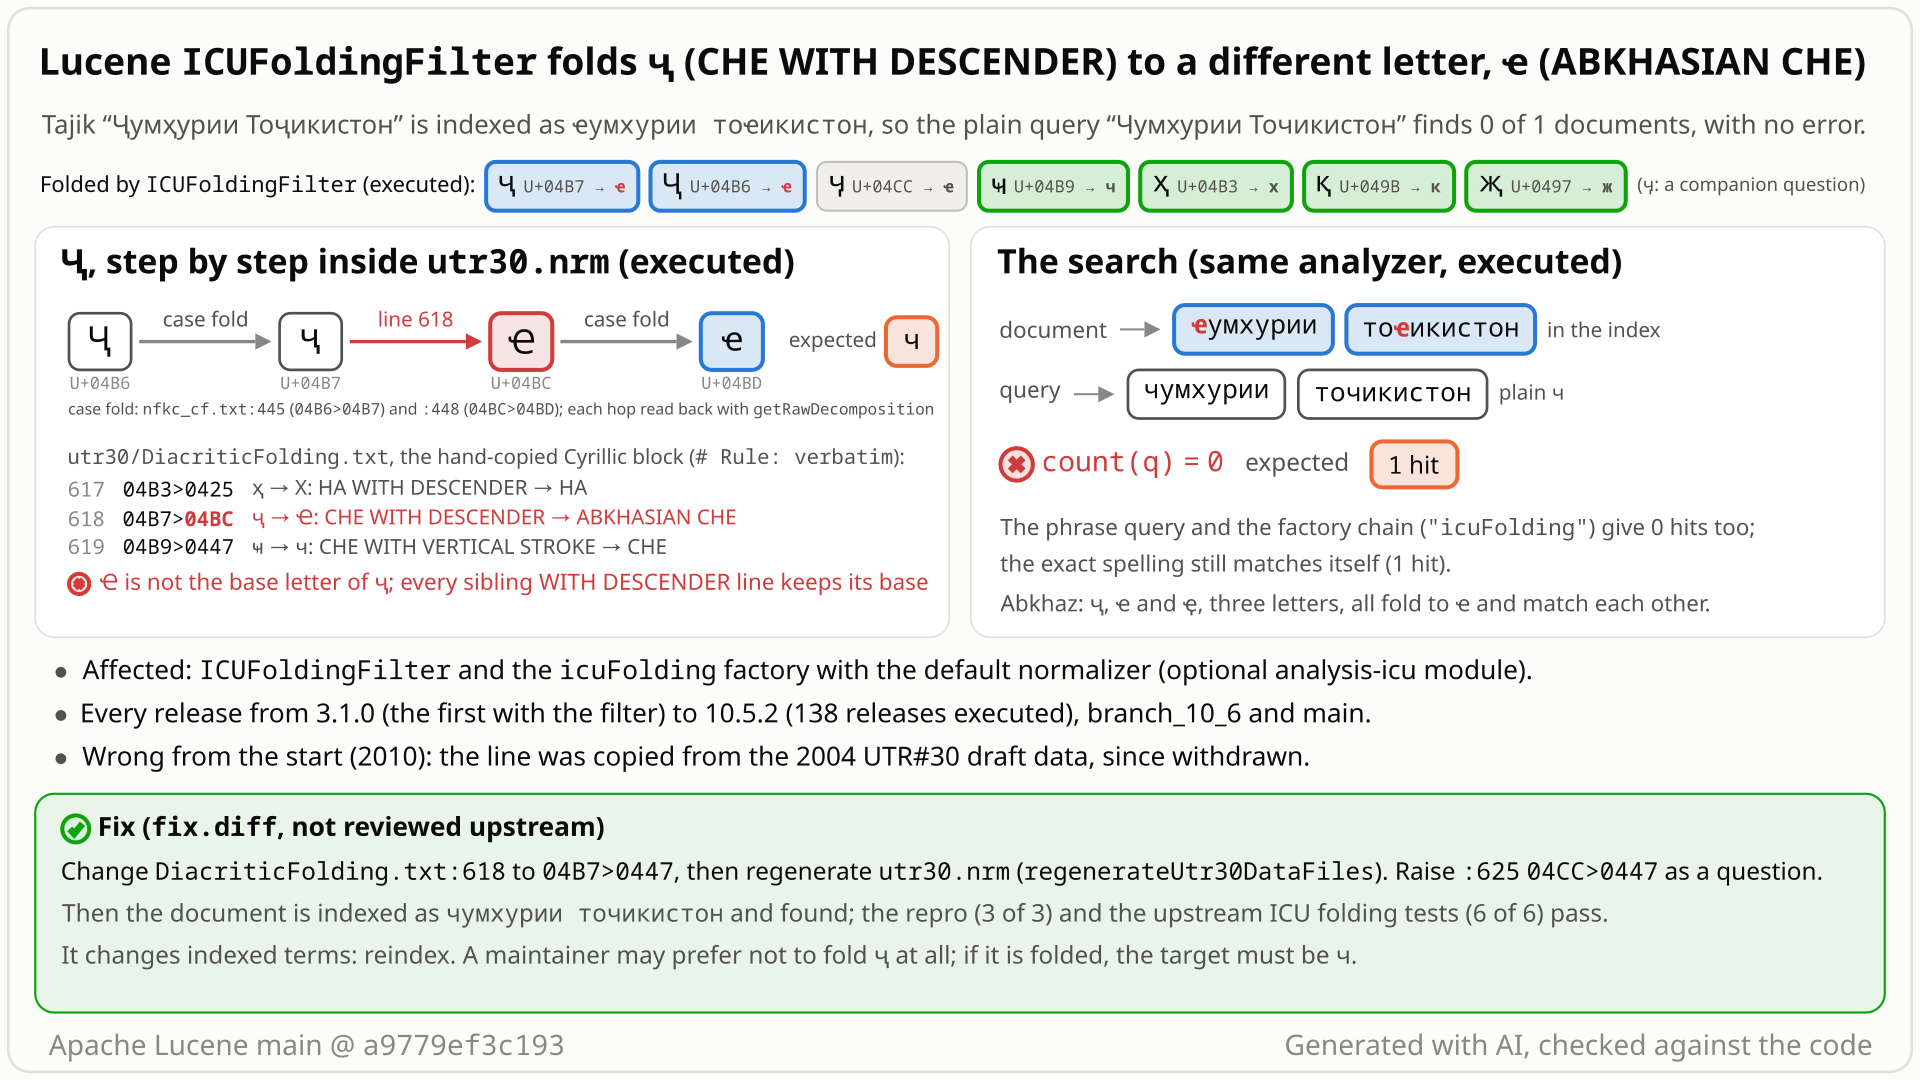
ICUFoldingFilter: the document's ҷ becomes ҽ while the query's plain ч stays ч, so the terms differ and the query finds nothing. Select the still to open it at full size. Generated with AI, checked against the code.- You add
ICUFoldingFilterwith its default settings to the analyzer, at index and query time, and index the Tajik phrase "Ҷумҳурии Тоҷикистон" (Republic of Tajikistan). ҷ is "che with descender", a letter of Tajik and Abkhaz. - You expect the plain-letter spelling "Чумхурии Точикистон" to find it: the filter removes descenders, and in the same phrase ҳ already folds to х, as қ folds to к and ҹ to ч.
- Instead the document is indexed as
ҽумхурии тоҽикистонand the query asчумхурии точикистон: 0 of 1 documents found. The one-word query "Точикистон" also finds 0. - The cause is one line of the folding table,
04B7>04BC: it maps ҷ to Ҽ (ABKHASIAN CHE), which case folding turns into ҽ. The next line,04B9>0447, maps ҹ to ч. - No error, and the exact spelling still finds itself. In Abkhaz, which writes ҷ and ҽ as two letters, the two now match each other.
Users of the optional analysis-icu ICUFoldingFilter (its default normalizer; no setting needed) who index Tajik or Abkhaz Cyrillic text. A query typed with plain ч misses every document that writes the word with ҷ, and in Abkhaz ҷ and ҽ match each other. Deterministic at any scale, silent, in every release since 3.1.0.
Mechanism, terms and numbers605 words
ICUFoldingFilter (module analysis-icu) folds text for search; its javadoc lists "Diacritic removal (including stroke, hook, descender)". Its data, utr30.nrm, is compiled from Lucene's own folding tables and ICU's NFKC data. One hand-copied line of DiacriticFolding.txt, 04B7>04BC, maps U+04B7 CYRILLIC SMALL LETTER CHE WITH DESCENDER (ҷ, a letter of Tajik and Abkhaz) to U+04BC CYRILLIC CAPITAL LETTER ABKHASIAN CHE, which case folding turns into ҽ U+04BD. Removing the descender gives ч U+0447, which is what every sibling WITH DESCENDER or WITH STROKE line of the same block does (җ to ж, қ to к, ҳ to х, ҹ to ч). So the Tajik phrase "Ҷумҳурии Тоҷикистон" is indexed as "ҽумхурии тоҽикистон", the query "Чумхурии Точикистон" (the same words with plain letters) becomes "чумхурии точикистон", and it finds 0 documents; in Abkhaz, which writes ҷ and ҽ as separate letters, the two fold to one term. There is no error, and the exact spelling still matches itself. The line was copied in 2010 from the 2004 draft data of UTR#30 (since withdrawn) and is in every release from 3.1.0 to 10.6.0 and on main. The fix is a one-line data change plus a regenerated utr30.nrm; it changes indexed terms for these letters.
ICUFoldingFilter(moduleanalysis-icu): a token filter for "search term folding". Its normalizerNORMALIZERloads the compiled data fileutr30.nrm(ICUFoldingFilter.java:69-77); the one-argument constructor uses it, and so doesICUFoldingFilterFactory(SPI nameicuFolding), directly or, with afilterargument, wrapped in aFilteredNormalizer2.utr30.nrm: compiled by the gradle taskregenerateUtr30DataFilesfromsrc/data/utr30/*.txtwith ICU'sgennorm2andicupkg. The task regenerates the rule-based parts of the tables and keeps the data lines after a# Rule: verbatimmarker as written, up to the next# Rule:line.- The Cyrillic verbatim block (
DiacriticFolding.txt:597-626), headed "Cyrillic script \"composed\" that do not further decompose, so decompose here", "These are from UTR#30 DiacriticFolding.txt", "Rule: verbatim". Each line issource>targetin hex.
| line | entry | letter | folds to |
|---|---|---|---|
| :607 | 0497>0436 | җ ZHE WITH DESCENDER | ж ZHE |
| :609 | 049B>043A | қ KA WITH DESCENDER | к KA |
| :612 | 04A3>043D | ң EN WITH DESCENDER | н EN |
| :614 | 04AB>0441 | ҫ ES WITH DESCENDER | с ES |
| :617 | 04B3>0425 | ҳ HA WITH DESCENDER | Х HA (case-folded to х) |
| :618 | 04B7>04BC | ҷ CHE WITH DESCENDER | Ҽ ABKHASIAN CHE (case-folded to ҽ) |
| :619 | 04B9>0447 | ҹ CHE WITH VERTICAL STROKE | ч CHE |
| :620 | 04BF>04BC | ҿ ABKHASIAN CHE WITH DESCENDER | Ҽ ABKHASIAN CHE (its own base letter) |
| :625 | 04CC>04BC | ӌ KHAKASSIAN CHE | Ҽ ABKHASIAN CHE (same origin; a companion question) |
The block has 26 data lines (:601-626), with the same mappings as the small-letter lines of the 2004 UTR#30 draft data file. 24 map to the base letter of the character's Unicode name (for :620 that base is ABKHASIAN CHE itself); only :618 and :625 map to a different letter, ABKHASIAN CHE.
Ҷ U+04B6 is case-folded to ҷ U+04B7; line 618 maps ҷ to Ҽ U+04BC; case folding maps Ҽ to ҽ U+04BD. getRawDecomposition(U+04B7) is U+04BC, and normalize gives U+04BD for Ҷ ҷ Ҽ ҽ Ҿ ҿ Ӌ ӌ alike, while Ч and ч give ч. U+04B7 has no NFKC decomposition, so the order in which gennorm2 reads the files (a separate bug, LFV-857) does not matter here.
Eight Cyrillic descender letters added to Unicode after the 2004 draft (GHE, PE, SHHA and EL WITH DESCENDER, small and capital) keep their descender (the capitals are only case-folded). That is a separate completeness gap with a different fix (missing lines, not a wrong one).
Exposure and likelihood197 words
- Who is exposed. Analysis chains with
ICUFoldingFilter: built by hand, withCustomAnalyzeror theicuFoldingSPI name, or through a downstream product that wraps the filter. No Lucene analyzer adds it by default. The default normalizer is enough; no option is involved. - Which text. Tajik and Abkhaz Cyrillic text: Unicode's NamesList marks U+04B7 "Abkhasian, Tajik". Tajik writes, for example, "Тоҷикистон" (Tajikistan).
- Effect. Deterministic for every token with ҷ/Ҷ, which folds to ҽ; what a search then gets wrong depends on the query: one typed with plain ч (for example on a keyboard layout without Tajik letters) does not match the indexed term, so the document is missed; in Abkhaz text a word with ҷ and the same word with ҽ become one term, so they match each other. No exception, no index damage, nothing in the logs; the exact spelling still matches itself.
- How likely. Rare for most indexes, because the text must be Tajik or Abkhaz, but systematic for a Tajik-language search application. No public report was found (see Prior reports), although the line has shipped since 3.1.0 (2011).
- Fixing it changes indexed terms: fields that contain ҷ/Ҷ need a reindex after the fix.
The test shows that ICUFoldingFilter folds the Tajik/Abkhaz letter CHE WITH DESCENDER "ҷ" (U+04B7) to the different letter ABKHASIAN CHE "ҽ" (U+04BD), not to CHE "ч" (U+0447) as every sibling WITH DESCENDER letter keeps its base letter.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.icu;

import org.apache.lucene.tests.analysis.BaseTokenStreamTestCase;

public class TestICUFoldingCheWithDescender extends BaseTokenStreamTestCase {

  public void testCheWithDescenderFoldsToChe() throws Exception {
    // expected: CHE WITH DESCENDER U+04B7 folds to CHE U+0447; actual: ABKHASIAN CHE U+04BD
    assertTokenStreamContents(
        new ICUFoldingFilter(whitespaceMockTokenizer("ҷ")), new String[] {"ч"});
  }
}
# in a copy of this finding's repro folder (repro/LFV-855/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/analysis/icu/build/libs/lucene-analysis-icu-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.icu.TestICUFoldingCheWithDescender
# the module(s) analysis-icu also need their third-party runtime jars
- Expected vs actual
- Expected
term 0 expected:<[ч]>; actualbut was:<[ҽ]>, with-eaand-da.
More files, environment, full output38 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: term 0 expected:<[ч]> but was:<[ҽ]>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:262)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:513)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:598)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:622)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:689)
org.apache.lucene.analysis.icu.TestICUFoldingCheWithDescender.testCheWithDescenderFoldsToChe(TestICUFoldingCheWithDescender.java:25)- The javadoc lists "Diacritic removal (including stroke, hook, descender)"; the block's own comment says "decompose here".
- The other WITH DESCENDER and WITH STROKE lines keep the base letter, such as
04B9>0447(ҹ to ч); ABKHASIAN CHE is a separate letter. - The 2004 draft it copies contradicts itself (Ҹ to Ҽ, ҹ to ч); Lucene already departs from it for Ҹ.
The full argument283 words
- Contract.
ICUFoldingFilter.java:33: "Diacritic removal (including stroke, hook, descender)". The module overview: search term folding "removes distinctions (such as accent marks) between similar characters". - The block's stated purpose. "Cyrillic script \"composed\" that do not further decompose, so decompose here" (
DiacriticFolding.txt:597). ABKHASIAN CHE is not a decomposition of CHE WITH DESCENDER: the Unicode name gives the base letter CHE, and the Unicode 1.0 names were "CHE WITH RIGHT DESCENDER" for U+04B7 and "IE HOOK" for U+04BD. - The siblings. Every other WITH DESCENDER or WITH STROKE line of the block keeps the base letter of the character's name, including CHE WITH VERTICAL STROKE (
:619, to ч) and ABKHASIAN CHE WITH DESCENDER (:620, to ABKHASIAN CHE); the only other line that sends a different letter to ABKHASIAN CHE is:625(KHAKASSIAN CHE, same origin). - The copied source is inconsistent and withdrawn. The UTR#30 draft data ("DRAFT 1 - 2004-07-14 ... Subject to change") maps capital Ҹ U+04B8 to ABKHASIAN CHE but small ҹ U+04B9 to CHE. Lucene copied only the small-letter lines, so it already folds Ҹ to ч, not to ҽ. The report defines diacritic removal as mapping to "related base characters", so that users can "search for words with accented characters in them by supplying the equivalent word spelled in base letters only"; the Unicode site lists the draft as withdrawn.
- No test or decision records it. No upstream test asserts any Cyrillic folding, and no javadoc, CHANGES or MIGRATE entry or issue discusses ҷ. LUCENE-1343 (#2420), which added the table, lists five intended differences from
ASCIIFoldingFilter, none Cyrillic. In LUCENE-10238 (#11274) the verbatim sections are called "basically hacks" and edited: maintained data, not a frozen copy.
The devil's-advocate check224 words
The strongest case for "intended": the block says "These are from UTR#30 DiacriticFolding.txt" and "Rule: verbatim", and line 618 has the same mapping as the draft (which maps both U+04B6 and U+04B7 to U+04BC). The javadoc names a category, not a promise per character; eight newer Cyrillic descender letters keep their descender. ҷ is a letter of its own in Tajik, so a maintainer may prefer not to fold it, and any change forces a reindex.
Why it fails: Lucene does not reproduce the draft anyway (it differs for Ҹ, and the draft maps a case pair to two different letters); the block's stated job is to decompose, and the target is a third letter that Abkhaz uses next to ҷ, which no reading of "descender removal" yields. "Do not fold ҷ" is a fair position. No current normative Unicode source mandates U+0447 (UTR#30 is a withdrawn draft), so do not claim one; ask the maintainers to choose between ч and not folding ҷ, since either removes the merge with ҽ. Reindexing is the normal cost of a change to this data; every ICU upgrade regenerates utr30.nrm. Framing note from the independent reproducer: a plain-ч query would also miss ҷ if ҷ were left unfolded, so the distinctive harm of today's line is the merge with ҽ and the break from its siblings.
Recommended Change line 618 to 04B7>0447 and regenerate utr30.nrm
Change line 618 of DiacriticFolding.txt to 04B7>0447 and regenerate utr30.nrm and its checksum file. Then ҷ and Ҷ fold to ч and no other code point changes; the repro passes, and analysis-icu runs 161 tests with 0 failures (10 skipped). Indexed terms change, so affected fields need reindexing.
--- a/lucene/analysis/icu/src/data/utr30/DiacriticFolding.txt
+++ b/lucene/analysis/icu/src/data/utr30/DiacriticFolding.txt
@@ -615,7 +615,7 @@
 04AD>0442
 04B1>04AF
 04B3>0425
-04B7>04BC
+04B7>0447
 04B9>0447
 04BF>04BC
 04C4>043A
(+ utr30.nrm regenerated, + the two new SHA-1 values in regenerateUtr30DataFiles.json)
All options and trade-offs4 options · 829 words
One fix and one variant were applied in a scratch worktree at a9779ef3c193 and run through gradle; the other options were not run.
One line of DiacriticFolding.txt changes. The binary utr30.nrm (61,776 bytes before and after) and the two SHA-1 values in src/generated/checksums/regenerateUtr30DataFiles.json follow from it: upstream, ./gradlew :lucene:analysis:icu:regenerateUtr30DataFiles produces both (the task runs GenerateUTR30DataFiles, downloads ICU's NFKC data files and compiles ICU4C 78.3). Here the file was rebuilt with only that task's last two steps (gennorm2 over the sorted *.txt, then icupkg -tb) and ICU4C 77.1, whose rebuild of the unchanged sources is byte-identical to the shipped file. An independent run of the full task, with only line 618 changed, produced a byte-identical utr30.nrm and the same two checksum lines. Add a test such as the repro's testCheWithDescenderFoldsToChe to TestICUFoldingFilter.
--- a/lucene/analysis/icu/src/data/utr30/DiacriticFolding.txt
+++ b/lucene/analysis/icu/src/data/utr30/DiacriticFolding.txt
@@ -615,7 +615,7 @@
 04AD>0442
 04B1>04AF
 04B3>0425
-04B7>04BC
+04B7>0447
 04B9>0447
 04BF>04BC
 04C4>043A
(+ utr30.nrm regenerated, + the two new SHA-1 values in regenerateUtr30DataFiles.json)
Trade-offs
- Reindexing. Indexed terms change for text with ҷ/Ҷ: documents indexed before the fix keep
тоҽикистон, new queries produceточикистон. Add a CHANGES entry (and, if the committers want, a MIGRATE note) thatICUFoldingFilteroutput changes for U+04B6/U+04B7 and affected fields need reindexing. Earlier changes to this data (ICU upgrades, LUCENE-3747, LUCENE-10238) shipped with plain CHANGES entries and no reindex note;MIGRATE.mdhas a precedent for an analysis change that asks users to reindex (Romanian analysis,lucene/MIGRATE.md:873). - No API change; no performance effect is expected (one mapping changes, the file size does not); not benchmarked.
- Copies outside Lucene need the same change separately: downstream copies of the text file, and Lucene.NET's compiled
utr30.nrm, which would have to be regenerated.
What the checks validated
- Stock main
a9779ef3c193(gradle, seed DEADBEEF): the repro fails 2 of 3 with assertions on and off;TestICUFoldingFilterandTestICUFoldingFilterFactorypass (6 tests); the generated-file checksum check passes. - With the fix: the repro passes 3 of 3 with assertions on and off; the two upstream suites pass (6 tests); all of
:lucene:analysis:icu:testwith the repro added passes (17 classes, 161 tests, 0 failures, 10 skipped);regenerateUtr30DataFilesChecksumCheckpasses with the updated checksum file;ecjLintTestpasses. - An exhaustive comparison of the stock and the fixed
utr30.nrmover all 1,112,064 non-surrogate code points, each normalized on its own, differs at exactly U+04B6 and U+04B7, which now fold to U+0447; an independent fact check repeated it with its own code and got the same 2 code points. - The fixed
utr30.nrmwas rebuilt from the patched sources withgennorm2andicupkg -tb; the same rebuild of the unchanged sources is byte-identical to the shipped file, and the full upstream task (ICU4C 78.3) with only line 618 changed gives a byte-identical fixed file (SHA-1 d14cf338...). checkGoogleJavaFormatflagged only the new test's line wrapping; the formatted test is the final repro file and was re-run: 2 of 3 fail on stock, 3 of 3 pass with the fix.- After the fact checks, the repro's comments were corrected ("selected sibling letters" instead of "every letter"; code unchanged): google-java-format and
ecjLintTestpass, it fails 2 of 3 on stock and passes 3 of 3 with the fix, assertions on and off, andfix-with-test.diffwas rebuilt fromfix.diffplus this file; it applies cleanly.
The finder's original sketch: the same change plus the neighbouring line with the same origin and the same target.
Trade-offs
Its Unicode 1.0 name was "CHE WITH LEFT DESCENDER", which points to ч, but its current name, KHAKASSIAN CHE, carries no diacritic, the 2004 draft grouped it with ABKHASIAN CHE, and no test asserts it. Treat it as a suspect companion mapping for maintainers to adjudication, not as part of the minimal fix or as a second bug.
What the checks validated
- With this variant: the repro passes 3 of 3 (assertions on),
TestICUFoldingFilterandTestICUFoldingFilterFactorypass (6 tests), and the checksum check passes. - Its
utr30.nrmis byte-identical to the hunt's rebuilt file, whose exhaustive comparison with the stock one differs at exactly U+04B6, U+04B7, U+04CB and U+04CC.
For maintainers who want ҷ to stay distinct. Not run.
Trade-offs
Removes the wrong merge with ҽ, but a query with plain ч still misses ҷ, and it departs from every sibling line of the block.
Map ҷ to ч and Ҷ to Ч before the filter (for example with a MappingCharFilter), or exclude them with the factory's filter argument (a UnicodeSet of the characters to fold). Not run.
Trade-offs
Both change indexed terms too, so they also need a reindex; with filter, the excluded letters are not case-folded either. The filter route only removes the merge with ҽ: a plain-ч query still misses, as with not folding ҷ; only the char-filter mapping fixes that.
Lucene.NET ships a compiled utr30.nrm that gives the same fold, and public copies of the file inside downstream plugins carry the same line, so their users get the same fold.
An exhaustive check compared, for each of the 1,467 Unicode letters named "<base> WITH ..." whose base letter exists, the filter's output with the fold of the base letter, 5 fold to a different base letter, and for 2 of them, CHE WITH DESCENDER (U+04B6/U+04B7), the wrong mapping comes from one of Lucene's hand-written lines.
The method in full243 words
Method: bounded-exhaustive translation validation of the folding data (semi-formal tier), in a hunt unit that checked the UTR#30 verbatim tables against Unicode character names and the compiled .nrm.
- An independent model of the source tables (gennorm2's precedence by sorted file name, recursive mapping, canonical reordering) agreed with the shipped
utr30.nrmand with gennorm2's own combined output on all 1,114,112 code points (0 mismatches); a mutation of lines 618 and 625 in the model was flagged at exactly the affected code points (U+04B7 and U+04CC in the raw mapping; U+04B6, U+04B7, U+04CB and U+04CC after recursion), and a gennorm2 rebuild of the unchanged sources is byte-identical to the shipped file. - A name oracle (ICU4J 78.3, Unicode 17) took the 1,467 letters named "<base> WITH ..." whose base letter exists: 1,050 fold to the base letter's fold, 355 are left unfolded, 57 give the base plus something, and 5 fold to a wrong base letter. Two of the five are U+04B6/U+04B7, from line 618; the other three (U+06C0 and two presentation forms) follow Unicode's own canonical decomposition of U+06C0 into U+06D5 plus hamza above (Lucene's line 637 then removes the hamza as a diacritic), not a wrong Lucene line.
- The finding was reduced to a public-API JUnit and checked by an independent reproducer, reading-only reviews by a model from another family (OpenAI GPT-5.6), an intended-behaviour devil's advocate, an adjudication, a history, prior-report and security follow-up, and an audit. Found 2026-10-28 on main
a9779ef3c193.
No prior report found (2026-10-28): 221 queries over GitHub issues, PRs, commits and code, the Lucene and Solr lists, JIRA, downstream trackers, the UTR#30 review feedback and the web, plus the changed files of 44 open PRs and of recently closed ones. The issue that added the line never discusses che.
Searches4 searches
Verdict new: no report by anyone. Keyword search cannot prove absence; private trackers and private reports cannot be searched. The nearest items are listed below; none of them is this bug.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene), Elasticsearch, OpenSearch and Solr trackers; dev@, java-user@, issues@, commits@; the JIRA archive; the web | 2026-10-28 | the hunt's prior-report tool, two runs (96 queries: class and file names, Tajik, Abkhasian, "che with descender", code points) | no report; nearest #2420 (LUCENE-1343, added the line), #9177 (LUCENE-8129, the filter option), #10052 |
| apache/lucene, apache/lucene-solr, Lucene.NET, ICU4N, Elasticsearch, OpenSearch, Solr, unicode-org/icu, and all of GitHub | 2026-10-28 | 43 own issue and PR searches (Tajik, Abkhaz, ҷ, U+04B7, 04BC, Khakassian, UTR#30) and 4 code searches | nothing on point; code search finds 92 files with 04B7>04BC (apache/lucene's own included) and none with 04B7>0447 or 04CC>0447 |
| the 411 open apache/lucene PRs (all listed, the file lists of 44 read); PRs closed or updated since 2026-10-20; PRs and issues created since 2026-10-26 | 2026-10-28 | changed-file lists; titles | none fixes the line; #16911 deletes the file only as part of retiring branch_10x |
| related threads read in full: #2420, #2464, #4820, #11274, #10806, #10122, #9177; the Lucene, Solr and Lucene.NET lists; JIRA (LUCENE, SOLR, LUCENENET); the public review feedback on the UTR#30 draft | 2026-10-28 | comments grepped for che and the code points; 49 list and 11 JIRA queries | no report; two 2014 list threads ask how to change an unnamed mapping in DiacriticFolding.txt |
Born with the filter: 3599d0c60b17 (LUCENE-1343, 2010-04-22), first released in 3.1.0, copied from the 2004 UTR#30 draft data. The line never changed; all 138 releases from 3.1.0 to 10.5.2, 10.6.0 (branch_10_6 4ae946e5a9b) and main fold ҷ to ҽ.
Versions tested5 rows
Introduced with the filter by 3599d0c60b17 "LUCENE-1343: Add ICUFoldingFilter, normalizes unicode text for search" (2010-04-22, svn trunk r936657; issue #2420, no PR), backported to branch_3x as 534809c2eae (2010-05-06), which shipped in 3.1.0. git blame -w -M -C gives every line of the Cyrillic block to 3599d0c60b17 except the marker # Rule: verbatim (5abc76ea4221, LUCENE-3747, 2012); git log -S '04B7>04BC' --all finds only the two adding commits and aad44bc6e36 (2021), which emptied the old branch_8x tree. Wrong from the start, so not a regression.
The 138 releases and main ship 14 distinct utr30.nrm builds (run here with 16 ICU4J versions, 4.6 to 78.3); on main the file has been regenerated about 20 times (git log --follow: creation plus 20 changes, the last for ICU 78.1), and every rebuild kept the verbatim line. The 3-test JUnit ran on the six refs below; every final release ran the one-token main() (3.1.0 and 3.2.0 with their republished ICU4J 4.6 jar); the 4.0.0 alpha and beta pre-releases were not run. Upstream main c5ab3e57b9b (fetched 2026-10-28) has no change under lucene/analysis/icu since a9779ef3c193, and the branch_10x head 657014b3c57 has the same line.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's JUnit fails 2 of 3 through gradle (assertions on and off); passes with the fix |
branch_10_6 head 4ae946e5a9b (10.6.0) | affected | the main() folds ҷ and Ҷ to ҽ; the JUnit fails |
| 9.1.0, 9.12.3, 10.0.0, 10.5.2 | affected | the JUnit fails 2 of 3 (10.5.2 with -ea and -da) |
| all 138 final releases 3.1.0 to 10.5.2 | first release 3.1.0 | the standalone main() folds ҷ and Ҷ to ҽ; all 8 control letters fold to their base letter |
| 3.0.3 and earlier | API absent | no ICUFoldingFilter (compile error on the ICU package and class only) |
An independent reproducer and an intended-behaviour devil's advocate reproduced it with their own runs, controls passing; reading-only reviews by a model from another family (OpenAI GPT-5.6) agreed on the root cause; an adjudication and an audit re-ran it, and this doc's gradle runs reproduce it and validate the fix.
Checks and verdicts429 words
Every executing check wrote or re-ran a repro on stock main, and every control passed. The cross-model reviews could not execute code on this host, so all execution evidence comes from the hunt's own runs.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Exhaustive translation validation and name oracle, then the 3-test JUnit: fails 2 of 3 on main (-ea, -da), 10.5.2 and 9.12.3; passes with the rebuilt table, as do the upstream folding tests (6 of 6). |
| independent reproducer | real | Own 5-test JUnit written from the claim: fails 3 of 5 on main (-ea, -da), 10.5.2 and 9.12.3; passes 5 of 5 with the rebuilt table. |
| cross-model reviews (OpenAI GPT-5.6, reading only) | intended lens: real, medium; refute lens: not real, low, procedural only | Root cause agrees, inputs in contract, intended argument moderate. The refute runs could start no command and say this is not evidence against the result. |
| cross-model adversarial review step | uncertain (procedural) | The reviewer could not execute; separate runs fail on main and 10.5.2, pass with the fix, and an exhaustive comparison of the two tables differs at exactly 4 code points (the two-line variant). |
| intended-behaviour devil's advocate | real, medium-high | Built the case for intent and rejected each point; added the Unicode 1.0 names. Re-ran the JUnit on main (-ea, -da) and 10.5.2: 2 of 3 fail. |
| adjudication | confirmed, medium | Re-ran the independent reproduction's JUnit with a new seed on main: 3 of 5 fail with -ea and -da, controls pass. Asks for the minimal patch and KHAKASSIAN CHE as a companion question. |
| audit | keep | Re-ran the JUnit (2 of 3 fail) and an independent probe of the normalizer on main. |
| this doc's runs | reproduced; fix validated | Gradle in a clean worktree: the repro fails 2 of 3 on stock (assertions on and off) and passes 3 of 3 with the one-line fix; lucene/analysis/icu runs 161 tests with 0 failures (10 skipped) with it, and the fixed table differs from the stock one at exactly 2 code points. |
| fact checks (an independent Claude check and an independent reviewer from another model family, OpenAI GPT-5.6) | bug confirmed; wording errors corrected | The Claude check re-ran the doc's command (2 of 3 fail), the fix (3 of 3 pass), the whole module, the full upstream regeneration task (byte-identical utr30.nrm) and an exhaustive comparison of its own; the cross-model check read the evidence. Both found the bug, the fix and the verdict right and listed wording errors (counts, scopes, a mislabelled diagram section), all corrected. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 482 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,384 words
- Registry title
- ICUFoldingFilter folds the Tajik/Abkhaz letter CHE WITH DESCENDER (ҷ U+04B7, Ҷ U+04B6) to the different letter ABKHASIAN CHE (ҽ U+04BD) instead of to CHE (ч U+0447), so Tajik text is not found by the same words typed with plain ч
- Area
- analysis / icu (ICUFoldingFilter UTR#30 folding data: the hand-written 'Rule: verbatim' Cyrillic block of DiacriticFolding.txt, compiled into utr30.nrm)
- Priority
- Low, rank 309: Only Tajik or Abkhaz text in the opt-in ICU folding filter is affected.
- Impact class
- silent wrong results
- Impact note
- Applications that use the optional analysis-icu ICUFoldingFilter or ICUFoldingFilterFactory (its default normalizer, no setting needed) and index Tajik or Abkhaz Cyrillic text silently miss documents with ҷ/Ҷ when the query spells the word with plain ч ('Чумхурии Точикистон' does not find 'Ҷумҳурии Тоҷикистон'), and in Abkhaz text the three separate letters ҷ, ҽ and ҿ match each other; the exact spelling still matches itself, nothing throws, no scale is needed, every release from 3.1.0 to 10.5.2, branch_10_6 (10.6.0) and main are affected, and a fix changes indexed terms, so affected fields need a reindex.
- Summary
- You index Tajik text such as 'Ҷумҳурии Тоҷикистон' with ICUFoldingFilter, whose javadoc lists 'Diacritic removal (including stroke, hook, descender)', and expect the same words typed without the Tajik letters, 'Чумхурии Точикистон', to find it, as they do for ҳ, қ and the other WITH DESCENDER letters. Instead the hand-copied line '04B7>04BC' in DiacriticFolding.txt maps CHE WITH DESCENDER to ABKHASIAN CHE, so ҷ and Ҷ are indexed as ҽ while the query's ч stays ч, and the query gets 0 hits. In Abkhaz, which uses ҷ, ҽ and ҿ as three separate letters, all three fold to ҽ and match each other.
- Introduced
- 3599d0c60b17e395b9cd3a3f745187a5d32bb8be (svn trunk r936657, 'LUCENE-1343: Add ICUFoldingFilter, normalizes unicode text for search', issue LUCENE-1343 = #2420, by GitHub rmuir; no PR), backported to branch_3x as 534809c2eae7addcd93ede794e1e42d72a87e105 (r941694, 'LUCENE-1343: backport'), the commit that shipped in 3.1.0 [read: the commit created DiacriticFolding.txt and utr30.nrm; git blame -w -M -C on main's file puts the whole Cyrillic block, including line 618 '04B7>04BC' and line 625 '04CC>04BC', on 3599d0c60b17, and only the marker line 599 '# Rule: verbatim' on the later 5abc76ea4221 (LUCENE-3747); git log -S '04B7>04BC' --all finds only the two adding commits and a branch_8x commit that deleted that branch's tree] [exec: 3.1.0, the first release with the API, already folds U+04B7 to U+04BD]. The line was copied, with the rest of the block ('These are from UTR#30 DiacriticFolding.txt'), from the 2004 UTR#30 draft data file (since withdrawn), which itself maps U+04B6/U+04B7 to U+04BC; wrong from the start, so not a regression (2010-04-22 (trunk author date 2010-04-22T08:47:49Z; branch_3x backport author date 2010-05-06T12:27:18Z))
- First affected version
- 3.1.0 [exec] (the first release with ICUFoldingFilter; 3.0.3 [exec]: API absent, the probe fails to compile on the ICU package and class only, and Maven Central has no lucene-icu 3.0.3 artifact)
- Affected versions
- every release from 3.1.0 to 10.5.2 (all 138 final releases on Maven Central: lucene-icu 3.1.0-3.6.2, lucene-analyzers-icu 4.0.0-8.11.4, lucene-analysis-icu 9.0.0-10.5.2), the branch_10_6 head 4ae946e5a9b (10.6.0, released 2026-10-29) and main a9779ef3c193 [exec: the follow-up's history harness folds U+04B7 and U+04B6 to U+04BD on every one, while all 8 control letters fold to their base letter (3.1.0 and 3.2.0 run with --allow-stale, because their lucene-icu depends on a republished ICU4J 4.6; branch_10_6 with its analysis-icu jar compiled from the branch sources); the candidate's JUnit fails 2 of 3 on 9.1.0, 9.12.3, 10.0.0, 10.5.2 (-ea and -da), branch_10_6 and main (-ea and -da); the independent reproduction's JUnit fails 3 of 5 on main (-ea, -da), 10.5.2 and 9.12.3; the intended-behaviour check and the cross-model review step reproduced on main and 10.5.2] [read: every release tag's DiacriticFolding.txt contains 04B7>04BC, each release jar's utr30.nrm has its tag's git blob, and 14 distinct utr30.nrm builds with 16 ICU4J versions (4.6 to 78.3) all fold the same way; upstream main 20ced71c1e6 has no analysis/icu change since a9779ef3c193; branch_10x head 657014b3c57 has the same line]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal; also reached by exhaustive check
- Upstream and prior reports
- none found (2026-10-28, read-only; the prior-report record, verdict new): 221 logged queries, among them two scripted prior-report searches (51 and 45 queries over GitHub apache/lucene issues and PRs, commits, the Elasticsearch, OpenSearch and Solr trackers, the dev, java-user, issues and commits lists, LUCENE JIRA and the web), 43 extra GitHub issue/PR queries (apache/lucene, apache/lucene-solr, apache/lucenenet, ICU4N, elastic/elasticsearch, opensearch-project/OpenSearch, apache/solr, unicode-org/icu, all of GitHub), 4 GitHub code searches (92 files carry '04B7>04BC', none carries '04B7>0447' or '04CC>0447'), 11 JIRA queries (SOLR, LUCENE, LUCENENET), 49 list queries and 9 web searches (English and Russian); the file lists of the open PRs (411 listed, 44 read) and of the 34 PRs closed or updated since 2026-10-20 (#16911 deletes the file only as part of retiring branch_10x). Nearest items, none about this mapping: #2420 (LUCENE-1343, the introducing issue; all 28 comments read), #4820 (LUCENE-3747) and #11274 (LUCENE-10238), maintenance of the verbatim sections, #9177 (LUCENE-8129, a UnicodeSet filter for letters not to fold), #10052, and 2014 java-user/solr-user threads about an unnamed DiacriticFolding mapping. Re-check 2026-10-28: none of the 15 apache/lucene PRs created since 2026-10-26 touches lucene/analysis/icu, and none of the issues created since then concerns ICU folding (listing only; the GitHub search API was rate-limited at that moment)
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26): this doc's JUnit through gradle in a clean worktree, stock and with the one-line fix (and the variant that also changes KHAKASSIAN CHE), assertions on and off, plusTestICUFoldingFilter,TestICUFoldingFilterFactory, all oflucene/analysis/icuand the generated-file checksum check with the fix (2026-10-28); an exhaustive comparison of the stock and the fixedutr30.nrmover all 1,112,064 non-surrogate code points. Hunt runs: the JUnit on 9.1.0, 9.12.3, 10.0.0, 10.5.2, branch_10_6 and main; a standalone Javamain()(each release's Lucene and ICU4J jars) on all 138 final releases from 3.1.0 to 10.5.2. After the fact checks: the repro, after a comment-only edit, again fails 2 of 3 on stock and passes 3 of 3 with the fix, assertions on and off; an independent run of the full upstreamregenerateUtr30DataFilestask with only line 618 changed gives the sameutr30.nrmas the fix.
- Finding record
lucene/analysis/icu/src/data/utr30/DiacriticFolding.txt:597-599 (at a9779ef3c193) (block comment '# Cyrillic script "composed" that do not further decompose, so decompose here', '# These are from UTR#30 DiacriticFolding.txt', '# Rule: verbatim'), :618 '04B7>04BC', :625 '04CC>04BC', :600-626 (siblings 0497>0436, 0499>0437, 049B>043A, 04A3>043D, 04AB>0441, 04AD>0442, 04B3>0425, 04B9>0447, 04BF>04BC)lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/ICUFoldingFilter.java:23-24 (at a9779ef3c193) ('applies search term folding to Unicode text, applying foldings from UTR#30 Character Foldings'), :33 ('Diacritic removal (including stroke, hook, descender)'), :66-76 (NORMALIZER loaded from the utr30.nrm class resource)lucene/analysis/icu/src/resources/org/apache/lucene/analysis/icu/utr30.nrm (at a9779ef3c193) (compiled data; byte-identical to a gennorm2 rebuild of the stock sources)
- The finding in 30 seconds
lucene/analysis/icu/src/data/utr30/DiacriticFolding.txt:597-626 (block comment :597-599; :607, :609, :612, :614, :617, :618, :619, :620, :625)lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/ICUFoldingFilter.java:22-33, :64-87 (javadoc; NORMALIZER from utr30.nrm; constructors)lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/ICUFoldingFilterFactory.java:40-58 (SPI name icuFolding; filter)lucene/analysis/icu/build.gradle:77-135 (regenerateUtr30DataFiles: GenerateUTR30DataFiles, gennorm2, icupkg -tb)lucene/analysis/icu/src/tools/java/org/apache/lucene/analysis/icu/GenerateUTR30DataFiles.java:75-78, :122-154 (verbatim lines kept until the next '# Rule:' line); DiacriticFolding.txt:27-33 (the file's own note)
- Who is affected
lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/ICUFoldingFilterFactory.java:43 (SPI name icuFolding); lucene/analysis/icu/src/resources/META-INF/services/org.apache.lucene.analysis.TokenFilterFactory (registration); no analyzer under lucene/analysis/icu/src/java uses the filter (grep)
- Why it looks unintended
lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/ICUFoldingFilter.java:33; lucene/analysis/icu/src/java/overview.html:284-293lucene/analysis/icu/src/data/utr30/DiacriticFolding.txt:597-599, :601-626
- Suggested fix
lucene/analysis/icu/build.gradle:77-135; lucene/analysis/icu/src/generated/checksums/regenerateUtr30DataFiles.json; help/regeneration.md:13-56 (checksum check)lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/ICUFoldingFilterFactory.java:51-58 (filter argument)lucene/CHANGES.txt:4457, :15241 (LUCENE-10238, LUCENE-3747 entries); lucene/MIGRATE.md:873 (Romanian analysis: 'you should reindex Romanian documents')
- TestICUFoldingCheWithDescender.java (JUnit test):
repro/LFV-855/src/org/apache/lucene/analysis/icu/TestICUFoldingCheWithDescender.java(28 lines)
It was made in parallel with this doc; every term, fold and hit count on screen comes from an executed probe on main a9779ef3c193, stock and with the fix.diff table (04B7>0447, rebuilt utr30.nrm) first on the classpath, and every code and data row is a line of the code at a9779ef3c193.
assets/LFV-855/bug.png(482 KB)