The Monitor splits a stored query into parts so it can pick candidate queries fast, then adds up the scores of the parts that match. The parts are kept in a Set, which holds each query once, so a part that occurs twice is run and counted once.
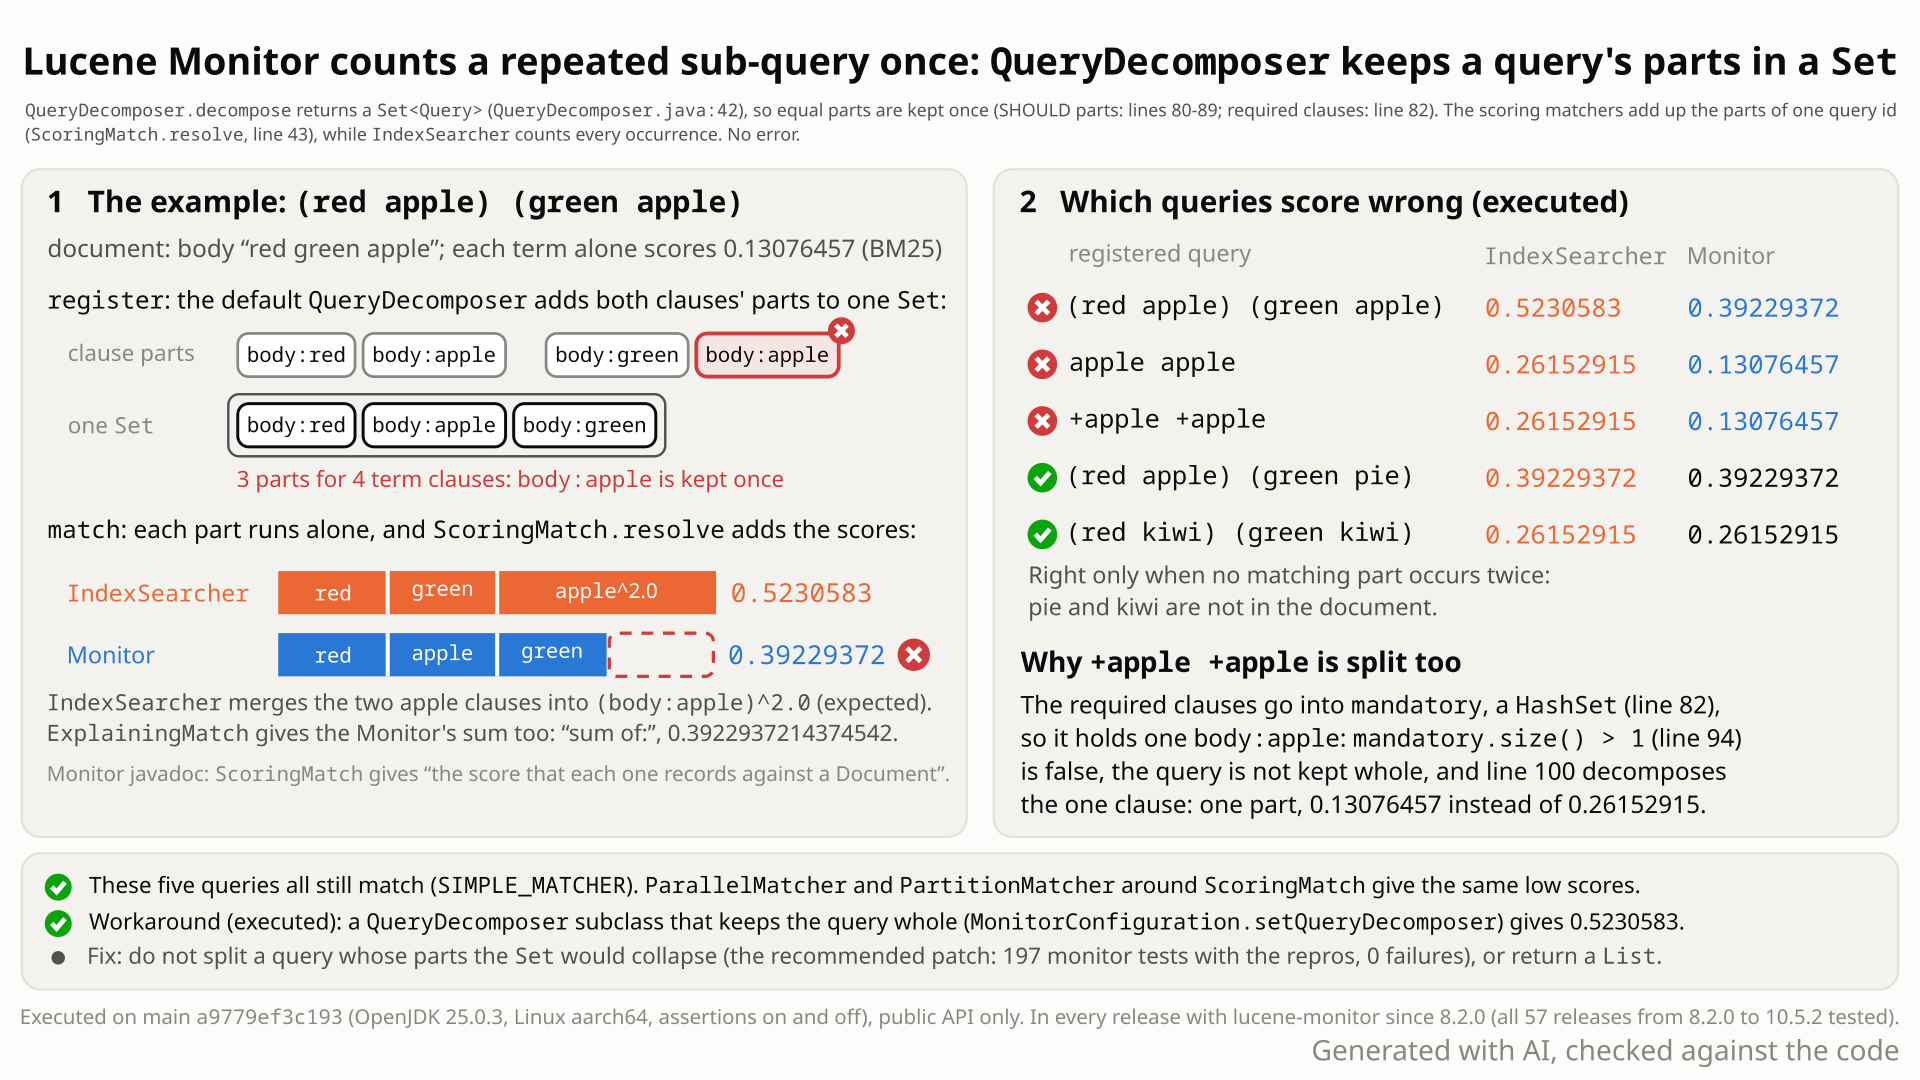
(red apple) (green apple) into the parts red, apple and green, so the Monitor adds 3 x 0.13076457 = 0.39229372, where IndexSearcher counts apple twice: 4 x 0.13076457 = 0.5230583. Select the still to open it at full size. Generated with AI, checked against the code.- Register
(red apple) (green apple)(classic QueryParser, field body) in a defaultMonitor, and match the document {body: "red green apple"} withScoringMatchand BM25. - On this document each word alone scores 0.13076457. The query names apple twice, so you expect 4 x 0.13076457 = 0.5230583, which is what IndexSearcher returns.
- You get 0.39229372 = 3 x 0.13076457: apple is counted once.
ExplainingMatchshows the same value as a "sum of:" green, apple and red.apple appleand+apple +appleget 0.13076457 instead of 0.26152915. No error. - Why: the default
QueryDecomposersplits the query into parts so the presearcher can pick candidates fast, and collects the parts in a Set: {red, apple, green}. The two apples are equal queries, so the Set keeps one, andScoringMatchadds up the scores of the parts that match. - Controls:
(red apple) (green pie), with no repeated part, gets 0.39229372 from both, and a decomposer that keeps the query whole gets 0.5230583. Whether each of these queries matches does not change.
Applications that use lucene-monitor and read scores through ScoringMatch (also via ParallelMatcher or PartitionMatcher) or ExplainingMatch, with a stored query that repeats a sub-query: a repeated word, overlapping expansions that share a term, or a repeated required clause that is the only distinct required clause (+apple +apple). Default configuration, any scale; for these shapes matching and highlighting are unaffected.
Mechanism, terms and numbers858 words
The Monitor (lucene-monitor) matches documents against stored queries. To select candidate queries quickly, its default QueryDecomposer splits a registered query into parts and collects them in a Set, which keeps equal queries once. When several parts of one query match a document, ScoringMatch and ExplainingMatch merge them by adding their scores. A BooleanQuery, however, counts a repeated clause at every occurrence. So when an equal sub-query occurs more than once among a registered query's decomposed SHOULD parts, or as a repeated required clause that is the only distinct required clause, with no SHOULD clause beside it, the Monitor reports, on every document on which that part matches, a score that counts the part once: (red apple) (green apple) on "red green apple" gets 0.39229372 instead of 0.5230583, and apple apple and +apple +apple get 0.13076457 instead of 0.26152915. The classic QueryParser builds all three from plain input. For these shapes, which queries match is unchanged. It is in every release since the module was imported (LUCENE-8766, 8.2.0). Keeping such a query whole in the decomposer (+25/-4 lines, one decomposer test added) fixes it, and the whole monitor module passes with that change.
- Monitor (lucene-monitor,
org.apache.lucene.monitor): stores queries and matches incoming documents against them. A matcher chosen permatchcall decides what is reported:SIMPLE_MATCHER(query ids),ScoringMatch(ids and scores),ExplainingMatch(ids and anExplanation),HighlightsMatch(matching terms). - QueryDecomposer: splits a registered query into parts that are indexed and run separately, so the presearcher can select only the parts whose terms occur in the document. Each part keeps the registered query's id.
decomposereturns aSet<Query>. - Repeated part: a sub-query that occurs more than once, compared with
Query.equals:applein(red apple) (green apple), a repeated termapple apple, or a repeated required clause+apple +apple.
QueryDecomposer.decomposereturns aSet<Query>(QueryDecomposer.java:42).decomposeBooleanadds the parts of every SHOULD clause to oneLinkedHashSet(:80,:89) and the MUST/FILTER clauses to aHashSet(:82,:85-86); the DisjunctionMaxQuery branch adds its disjuncts' parts to aLinkedHashSet(:46-52). Equal parts are kept once.- For
+apple +appletheHashSetholds one clause, so the keep-whole rule for more than one required clause (:94-95) does not fire, and the single required clause is decomposed (:99-101). QueryCacheEntry.decomposestores one entry per Set element under the parent's id (QueryCacheEntry.java:51-59), and the Monitor runs every part the presearcher selects on its own (Monitor.java:299).CandidateMatcher.addMatchmerges two matches of one id withresolve()(CandidateMatcher.java:75-85).ScoringMatch.resolvereturnsmatch1.getScore() + match2.getScore()(ScoringMatch.java:42-44);ExplainingMatch.resolvebuilds a "sum of:" explanation (ExplainingMatch.java:44-52).BooleanQuery.rewritemerges repeated SHOULD and MUST clauses "into a single clause with a combined boost" (BooleanQuery.java:438-455,:706-713): an unboosted repeat getssimilarity.computeQueryTermWeight(count)(:743-746), which iscountfor default BM25 and the base Similarity. So the query counts the repeat, and with default BM25 the Monitor's score is too low by the score of each extra occurrence of a part that matches (with BM25's optional k3 > 0 the loss is smaller, and with k3 = 0 there is none).
A plain Boolean disjunction whose parts are all distinct is scored right (a DisjunctionMaxQuery with tie below 1 and a FILTER-only required clause are mis-scored even without a repeat: those are two separate sibling bugs), and so is a repeated part that does not match the document (it scores 0 both ways). A repeated required clause next to another required clause or a SHOULD clause is kept whole by line 94 and scored right: +apple +apple +red and +apple +apple green both get 0.39229372 from IndexSearcher and from the Monitor, while nested (+apple +apple) red is mis-scored (0.26152915 instead of 0.39229372). For these shapes matching is unchanged: a collapsed part matches exactly where its copies do. The one exception found is +apple +apple with minimumNumberShouldMatch=1, which the collapse turns into the shape of a separately registered minimumShouldMatch bug, so the Monitor reports a match that IndexSearcher does not.
Document {body: "red green apple"}, BM25, IndexSearcher on a one-document index vs ScoringMatch with BM25. Each of red, green and apple alone scores s = 0.13076457 (≈ idf 0.2876821 x tf 0.45454544; BM25 computes it as a float expression, so the decimal product differs in the last digits).
| query | IndexSearcher | Monitor |
|---|---|---|
(red apple) (green apple) | 0.5230583 (4 x s) | 0.39229372 (3 x s) |
apple apple | 0.26152915 (2 x s) | 0.13076457 |
+apple +apple | 0.26152915 (2 x s) | 0.13076457 |
(red apple) (green pie) (no repeat) | 0.39229372 | 0.39229372 |
(red kiwi) (green kiwi) (repeat does not match) | 0.26152915 | 0.26152915 |
ExplainingMatch gives 0.3922937214374542 = "sum of:" green and "sum of:" (apple, red); ParallelMatcher and PartitionMatcher also report 0.39229372. IndexSearcher explains apple with "2.0 = boost" and rewrites the query to (body:apple)^2.0 body:green body:red. With ClassicSimilarity the shared-term case gives 1.5 instead of 2.0, and a a a under BM25 gives 0.13076457 instead of 0.39229375 (the whole query folds the weight 3 into BM25's float expression and rounds to 0.39229375; three summed parts give 0.39229372).
Exposure and likelihood283 words
- Who. lucene-monitor users with the default
QueryDecomposer(MonitorConfiguration.java:38) who read scores throughScoringMatch(directly or throughParallelMatcher/PartitionMatcher, which report the same values) orExplainingMatch, and register a query in which an equal sub-query occurs more than once among its decomposed SHOULD parts (a repeated word in user input,apple apple; overlapping expansions that share a term,(red apple) (green apple)), or a repeated required clause that is the only distinct required clause of its BooleanQuery, with no SHOULD clause beside it (+apple +apple, or nested,(+apple +apple) red).+apple +apple +redand+apple +apple greenare kept whole and scored right. - Default vs opt-in. The Monitor configuration and the decomposer are the defaults; lucene-monitor is an optional module, and the matcher is chosen per
matchcall (no default);ScoringMatchandExplainingMatchare two of the four documented matchers. The classic QueryParser builds all three shapes from plain strings. - Scale. None needed: one query and one document show it, deterministically, with assertions on and off.
- Effect. Too-low scores, and explanations that omit the repeat, which can mis-rank or mis-threshold stored queries against each other. For these shapes the set of matching queries is right (the one exception found,
+apple +applewith minimumNumberShouldMatch=1, is described in the bug section); nothing failed or was corrupted in any run, and the values look plausible. - How likely. Rare: it needs the scoring matchers and a stored query with a repeated part, which is uncommon within one query; the one public Monitor integration found (an open Solr pull request) defers the scoring matchers. The lack of reports since 2019 is weak evidence, because the wrong values look reasonable.
The test shows that Monitor's ScoringMatch scores the registered query (red apple) (green apple) on the document red green apple lower than IndexSearcher does, because QueryDecomposer's Set keeps the shared part apple once.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.monitor;

import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.core.WhitespaceAnalyzer;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.Term;
import org.apache.lucene.index.memory.MemoryIndex;
import org.apache.lucene.search.BooleanClause.Occur;
import org.apache.lucene.search.BooleanQuery;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.Query;
import org.apache.lucene.search.TermQuery;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestMonitorSharedSubqueryScore extends LuceneTestCase {

  private static Query or(String a, String b) {
    return new BooleanQuery.Builder()
        .add(new TermQuery(new Term("body", a)), Occur.SHOULD)
        .add(new TermQuery(new Term("body", b)), Occur.SHOULD)
        .build();
  }

  public void testSharedTermIsScoredAtEachOccurrence() throws Exception {
    Analyzer analyzer = new WhitespaceAnalyzer();
    Document doc = new Document();
    doc.add(new TextField("body", "red green apple", Field.Store.NO));
    Query query =
        new BooleanQuery.Builder()
            .add(or("red", "apple"), Occur.SHOULD)
            .add(or("green", "apple"), Occur.SHOULD)
            .build();
    IndexSearcher searcher = MemoryIndex.fromDocument(doc, analyzer).createSearcher();
    float expected = searcher.search(query, 1).scoreDocs[0].score;
    try (Monitor monitor = new Monitor(analyzer)) {
      monitor.register(new MonitorQuery("q", query));
      ScoringMatch match = monitor.match(doc, ScoringMatch.DEFAULT_MATCHER).matches("q");
      // expected IndexSearcher's 0.5230583; actual 0.39229372: the shared "apple" is scored once
      assertEquals(expected, match.getScore(), 1e-6f);
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-856/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/memory/build/libs/lucene-memory-$V.jar
CP=$CP:$LUCENE/lucene/monitor/build/libs/lucene-monitor-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.monitor.TestMonitorSharedSubqueryScore
- Expected vs actual
- Expected:
0.5230583(IndexSearcher's BM25 score of the same query on the same document). Actual:expected:<0.5230583> but was:<0.39229372>.
More files, environment, full output34 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<0.5230583> but was:<0.39229372>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:577)
       org.junit.Assert.assertEquals(Assert.java:701)
org.apache.lucene.monitor.TestMonitorSharedSubqueryScore.testSharedTermIsScoredAtEachOccurrence(TestMonitorSharedSubqueryScore.java:57)- The Monitor javadoc reports "the score that each one records against a Document"; nothing says a repeated part counts once.
- The port's own test expects the "sum of the scores" of the parts, which equals the whole query's score.
- Core BooleanQuery counts a repeated clause at every occurrence (LUCENE-7925); the Monitor contradicts it on plain QueryParser input.
The full argument320 words
- Monitor contract.
package-info.java:40-45:ScoringMatch.matchWithSimilarity"returns the set of matching queries, with the score that each one records against a Document";ExplainingMatchis "similar to ScoringMatch, but include the full Explanation". The natural reading is the query's own score. - Core contract.
BooleanQuery.deduplicateClausesmerges repeated queries "into a single clause with a combined boost" (BooleanQuery.java:706-713); core has counted repeated scoring clauses since LUCENE-7925 (#8974, 2017, "Collapse duplicate SHOULD or MUST clauses by summing up their boosts"), asserted byTestBooleanRewrites.testDeduplicateShouldClausesandtestDeduplicateMustClauses. The classic QueryParser'sapple appleis explained with "2.0 = boost" and rewritten to(body:apple)^2.0. - No distinct-parts semantic is documented.
QueryDecomposer's javadoc says only "Split a disjunction query into its constituent parts, so that they can be indexed and run separately";CandidateMatcher.resolvesays "combine them". No CHANGES or MIGRATE entry discusses it. - The only test that pins a score value.
ConcurrentMatcherTestBase.testMatchesAreDisambiguatedsays "We need to check that each query ends up with the sum of the scores for the 'test' and 'doc' parts" and asserts 1.4874471; an executed check showed that this is IndexSearcher's score for the whole query. The sum was meant to rebuild the query's own score, which it does for a plain Boolean disjunction whose parts are all distinct (the DisjunctionMaxQuery and FILTER sibling bugs aside). The test does not literally state equality with the whole query's score, and no upstream test has a query with a repeated part. - History. The predecessor library (Luwak) kept the parts in Lists and its
resolvekept the larger match, so a repeat could not change a score there. The 2019 import (LUCENE-8766) changed the parts to a Set andresolveto a sum in the same commit, and rewrote the shared test from "the score for the 'test' subquery, not the 'doc' subquery" to "the sum of the scores", with no recorded discussion. #14886 / #14885 (2025) discussed the Set only for its iteration order.
The devil's-advocate check181 words
The strongest works-as-designed case (the devil's advocate and the cross-model reviewer): decompose has returned Set<Query> in the public API since 8.2.0, so the parts are defined by uniqueness, and running an equal part twice would be wasted work; nothing literally promises that a Monitor score equals IndexSearcher's; the decomposer already misreports DisjunctionMaxQuery and FILTER scores, and Luwak's max never equalled a disjunction's score either, so Monitor scores could be called a heuristic; and a decomposer that never splits is a supported customization.
Why it fails: nothing documents a distinct-parts semantic, the package javadoc reads as the query's own score, and the port's own test treats the sum of the parts as the query's score. The Set is fine for matching; the defect is that the summing resolve assumes each part occurs once. Core deliberately keeps the weight of a repeat, and the Monitor contradicts it on queries built from plain QueryParser input. The other mis-scorings are separate bugs, and a workaround is not a contract. Verdict: not intended; a defect since the import. At worst upstream answers with a javadoc change.
Recommended Keep a query whole when a part or a required clause repeats (QueryDecomposer)
In QueryDecomposer, count the parts with multiplicity and keep a query whole when one of its parts or required clauses repeats (+25/-4 lines, plus one decomposer test). The whole monitor module passes (197 tests), the repros included, with assertions on and off, and its static checks pass.
int shouldParts = 0, mandatoryClauses = 0;
for (BooleanClause clause : q) {
  if (clause.occur() == MUST || clause.occur() == FILTER) {
    mandatory.add(clause.query());
    mandatoryClauses++;
  } else if (clause.occur() == MUST_NOT) exclusions.add(clause.query());
  else {
    Set<Query> decomposed = decompose(clause.query());
    shouldParts += decomposed.size();
    subqueries.addAll(decomposed);
  }
}
if (subqueries.size() < shouldParts || mandatory.size() < mandatoryClauses)
  return Collections.singleton(q);
All options and trade-offs6 options · 913 words
One fix was built and run in a scratch worktree at a9779ef3c193; it is the finder's fix, cleaned up and with a decomposer test, and is recommended. A broader change from the DisjunctionMaxQuery sibling's doc, which runs the registered query whole, also fixes this bug.
Keep a query whole when a part or a required clause repeats (QueryDecomposer) (validated by the checks) (recommended)
decomposeBoolean counts the SHOULD parts and the required clauses before they go into the Sets, and returns the query as a singleton when a Set is smaller than its count; the DisjunctionMaxQuery branch does the same for its disjuncts' parts. The new TestQueryDecomposer.testRepeatedPartsAreNotDecomposed asserts that hello hello, +hello +hello, (hello world) (goodbye world) and DisMax(f:t1, f:t1) stay whole. +25/-4 lines in QueryDecomposer.java, +12 in the test. The snippet below is condensed (the source spells out BooleanClause.Occur).
int shouldParts = 0, mandatoryClauses = 0;
for (BooleanClause clause : q) {
  if (clause.occur() == MUST || clause.occur() == FILTER) {
    mandatory.add(clause.query());
    mandatoryClauses++;
  } else if (clause.occur() == MUST_NOT) exclusions.add(clause.query());
  else {
    Set<Query> decomposed = decompose(clause.query());
    shouldParts += decomposed.size();
    subqueries.addAll(decomposed);
  }
}
if (subqueries.size() < shouldParts || mandatory.size() < mandatoryClauses)
  return Collections.singleton(q);
Trade-offs
- A query with a repeated part becomes one presearcher entry instead of one per distinct part, and runs whole whenever it is selected. The cost was not benchmarked. Decomposition happens at
register, before any matcher is chosen, so the change applies to every matcher,SIMPLE_MATCHERand highlighting included: for such queries the cache entries, the presearcher's selectivity andgetQueriesRun()change too. Matching is unchanged for the three repro shapes (the module's matching and presearcher tests pass, and a match-set probe agrees on every row with the fix). The public countsMonitor.getDisjunctCount()andQueryCacheStatsdrop for a query that had several distinct parts on stock, such as(red apple) (green apple)(3 entries become 1);apple apple,+apple +appleandDisMax(a, a)keep one entry. - Queries whose parts are all distinct decompose exactly as before (the 11 existing decomposer tests pass).
- The rule is conservative: it also keeps whole some repeats whose score the collapse does not change, such as
DisMax(a, a)with tie 0 or any repeat under BM25 with k3 = 0. No such case was compared. - Side effect:
+apple +applewithminimumNumberShouldMatch=1, where the collapse made the Monitor report a match that IndexSearcher does not, is now kept whole and agrees. The separately registered minimumShouldMatch bug (one distinct required clause) needs its own fix. - The DisjunctionMaxQuery sibling's fix edits the same DisjunctionMaxQuery branch, so the two patches conflict textually but combine logically; they were not run together.
What the checks validated
Gradle in a scratch worktree at a9779ef3c193, seed DEADBEEF: the whole :lucene:monitor:test with the 3 repro classes added, 35 classes, 197 tests, 0 failures, 1 skipped (a @Nightly test), with assertions on and off; all 12 repro tests that fail on stock pass. :lucene:monitor:check -x test with the fix and the primary test (google-java-format, ecj lint, forbidden APIs): BUILD SUCCESSFUL. The finder's original diff: 196 tests, 0 failures. The match-set probe with the fix: 15 of 15 rows agree.
Keep the split for the presearcher, run the registered query whole (Monitor, QueryCacheEntry) (validated by the checks)
From the DisjunctionMaxQuery sibling's doc: each QueryCacheEntry also keeps its parent MonitorQuery's query, and the Monitor runs that whole query once per query id when the presearcher selects any of its parts. +17/-3 lines in QueryCacheEntry.java and Monitor.java; written as a sketch.
Trade-offs
- Fixes this bug and both sibling decomposition bugs (DisjunctionMaxQuery summed, FILTER clause scored).
- It changes every matcher, not only the scoring ones;
getQueriesRun()no longer equals the number of queries executed; a large disjunction runs whole when one part is selected; every cache entry keeps a reference to its parent's query. Not benchmarked; a design change for maintainers to weigh.
What the checks validated
In the sibling's validation, with assertions on: this bug's finder test fails 3 of 4 on stock main and passes 4 of 4 with the change; the whole module with the sibling repros, 37 classes, 208 tests, 0 failures, 1 skipped. Not run with assertions off or through check.
Keep every occurrence as its own part, so the sum counts each one.
Trade-offs
An API change: decompose, decomposeBoolean and decomposeBoostQuery are public and overridable. It would also change the per-part cache ids that #14885 made stable across JVMs. Not run.
Wrap a part that occurs n times in a BoostQuery of n.
Trade-offs
Exact only for linear similarities: on main an unboosted repeat is weighted by Similarity.computeQueryTermWeight(n), which saturates for BM25 with k3 >= 0, and the decomposer does not know the Similarity, which the matcher chooses per match call. Not run.
A note in the package javadoc and on ScoringMatch / ExplainingMatch.
Trade-offs
A legitimate maintainer choice, but queries built from plain QueryParser input stay mis-scored. Not run.
A QueryDecomposer subclass whose decompose returns the query as a singleton (for every query, or only when a part repeats), set with new MonitorConfiguration().setQueryDecomposer(...). No Lucene change.
Trade-offs
Gives IndexSearcher's exact score (the independent reproducer's oracle, the devil's-advocate probe and this doc's control test); every application has to know about it.
For these shapes only scores change, not which queries match, so products that route or alert on Monitor matches are unaffected (one exception: +apple +apple with minimumNumberShouldMatch=1 gives a false match, in the shape of a separately registered bug); products that rank or threshold on ScoringMatch scores see too-low values for stored queries that repeat a sub-query.
The finder compared six Monitor matchers with IndexSearcher over every small query and document in a bounded space plus 3,000 random larger queries (6.5 million checks). The first signal was a a on document a: 0.13076457 instead of 0.26152915. Keeping a query whole when its parts collapse removed this mismatch family; a Z3 model confirmed the condition.
The method in full210 words
Method: bounded-exhaustive translation validation against a reference semantics (the hunt's "semi-formal" tier).
- The finder's harness ran six matchers (simple, scoring, explaining, highlighting, parallel, partition) on the stock decomposer, and three of them on six decomposer variants, against IndexSearcher on a one-document index: every depth-1 query (420) on 55 documents, every depth-2 query (7,685) on 19 documents, and 3,000 random depth-3 queries on 34 documents; 6,506,760 checks with assertions on and the same with them off.
- First signal (depth 1):
body:a body:aon the document "a", 0.13076457 instead of 0.26152915. The unit found it itself; the planning probe for this area had not. - Root attribution with public decomposer subclasses: the variant that keeps a query whole when its parts would collapse was the only single change that removed 252, 1,142 and 365 score-mismatch rows in the three tiers, for the scoring and the explaining matcher each; further rows were removed by it together with a sibling variant. The DisjunctionMaxQuery and FILTER variants explain the two sibling bugs and leave this repro failing.
- A Z3 model of the score algebra over the reals confirmed that a collapsed repeat keeps the score only when the repeated part does not match.
- The finder then wrote the public-API JUnit test, and independent checkers reproduced it.
No prior report found (75 tool queries and 20 targeted searches over GitHub issues and PRs, every open PR's file list, the mailing lists, the JIRA archive, the predecessor library's tracker, downstream projects and the web, 2026-10-28). The nearest item, #14885 (2025), touched the same Set only for its iteration order.
Searches3 searches
Registry verdict new: no report or discussion of this bug by anyone else was found. Nearest items, none a report: #14886 / #14885 (2025: the same Set, iteration order across JVMs only; the fix kept a Set), #14967 (an unmerged alternative ordering fix), #9811 / LUCENE-8766 and apache/lucene-solr#648 (the import that introduced the Set and the summing resolve; no discussion of either), #8974 / LUCENE-7925 (core's repeated-clause scoring, the reference behaviour), #7845 / LUCENE-6787 (core may drop only non-scoring duplicates), #13109 (matcher composition), #16350 (bulk scoring in the Monitor), apache/solr#2382 (a draft Monitor integration; its "deduplicate" is one result per query id), Luwak #64, #37, #78 and #175 (unrelated). Limits: keyword search only; GitHub full-text search may miss unusual wording and was rate-limited during the refresh; one web query was throttled; GitHub search does not index diffs (open PRs were checked by file list).
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; dev@, java-user@, issues@, commits@; LUCENE JIRA archive; downstream trackers; web | 2026-10-28 | a scripted prior-report search, two runs, 75 queries (QueryDecomposer duplicate clauses, monitor duplicate clause score, ScoringMatch, ExplainingMatch, monitor scoring, luwak duplicate, decomposer duplicate) | no report; 0 high-overlap hits |
| apache/lucene issues and PRs | 2026-10-28 | 20 targeted searches; recent issues and PRs (PRs created since 2026-10-25, issues created since 2026-10-20, monitor mentions updated since 2026-10-26); the file lists of all 411 open PRs and of the latest 150 closed PRs (closed 2026-09-04 to 2026-10-27); the upstream history of the three files on main, branch_10x and branch_10_6 | no report; #14886 / #14885 (ordering only); #12295 and #16847 touch the files cosmetically |
| Luwak (the predecessor library), Solr, Elasticsearch, OpenSearch | 2026-10-28 | score, duplicate and decompose searches; 7 Luwak threads read; apache/solr#2382 review threads | no report; Luwak kept the parts in Lists and the max in resolve |
In the code since the Monitor was imported from the Luwak library (LUCENE-8766, 251dbe7cea8 and the 8.x backport b8773d13ad8, 2019-06-13); first released in 8.2.0. The finder's test fails with identical values on all 57 releases from 8.2.0 to 10.5.2, on 10.6.0 (branch_10_6 4ae946e5a9b) and on main; 8.1.1 has no Monitor module.
Versions tested7 rows
Introduced by LUCENE-8766 "Add monitor subproject" (#9811; the import of the Luwak monitoring library), by @romseygeek, author date 2019-06-13: 251dbe7cea8126cb7ecadc921ba444c63d06c618 on the main line (in 9.0.0 and later) and b8773d13ad8e249a045862249bf476c30a444461 on branch_8x (byte-identical QueryDecomposer.java and ScoringMatch.java; first released in 8.2.0). git blame puts the Set declarations, the addAll calls and the required-clause logic on that commit, and both summing resolve bodies are in it; later edits keep the behaviour (reformatting, a presized set, record accessors, #14885 HashSet to LinkedHashSet for iteration order only, instanceof patterns). Luwak kept the parts in Lists and resolved by max (read, not executed). #15818 (main only) added the optional BM25 k3 saturation of repeated query terms; with default BM25 the reference value is unchanged. Upstream main c5ab3e57b9b (2026-10-28) and branch_10_6 have the same logic; nothing has fixed it.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the 3 repro classes fail through gradle (12 of 15), assertions on and off |
branch_10_6 head 4ae946e5a9b (10.6.0, released 2026-10-29) | affected | the finder's test fails 3 of 4 (monitor jar compiled from that commit) |
| 10.5.2, 9.12.3 | affected | the primary test fails 4 of 5; the finder's and the independent reproducer's tests fail |
| 8.2.0 to 10.5.2 (all 57 releases) | affected | the finder's test fails 3 of 4 with identical values, assertions off on each, on with 8 of them |
| 8.2.0 | first release | the finder's test fails 3 of 4, the independent reproducer's 5 of 6 |
| 8.1.1 | no module | lucene-monitor does not exist yet (no artifact; the test does not compile) |
the fix on a9779ef3c193 | not affected | the whole monitor module, repros included: 197 tests, 0 failures, assertions on and off |
An independent reproducer, the test of the AI tool that drove the cross-model review, a devil's-advocate probe and an adjudication all reproduced it on main with assertions on and off; the tests pass with the fix. The other-family reviewer itself could only read code and returned a procedural default.
Checks and verdicts346 words
Each check ran or read on its own; the registration check and a credibility audit re-ran the tests with fresh seeds, and this doc re-ran them through gradle on a9779ef3c193.
| Check | Verdict | What it found |
|---|---|---|
| finder (bounded-exhaustive comparison, Z3 algebra, JUnit) | candidate | JUnit fails 3 of 4 on main (-ea, -da), branch_10_6, 10.5.2, 9.12.3 and 8.11.4; passes with the finder's fix, and all 180 upstream monitor tests stay green; the sibling fixes leave it failing. |
| independent reproducer | real | Own test with two oracles that agree exactly (IndexSearcher, and the same Monitor with a decomposer that keeps every query whole); adds a QueryParser-built case and ExplainingMatch; the all-distinct control passes. Fails 5 of 6 on main (-ea and -da), 10.5.2 and 9.12.3 (-ea). |
| cross-model review, refute lens | not real, low (procedural); root cause agrees | An independent reviewer from another model family (OpenAI GPT-5.6) could only read code and called its verdict "procedural, not a substantive refutation"; inputs in contract. Its record names main ea57360912ed, where the monitor code is identical. The AI tool that drove the review wrote and ran its own test, which fails 4 of 5 on main: BM25 0.39229372 vs 0.5230583, ClassicSimilarity 1.5 vs 2.0, a a a 0.13076457 vs 0.39229375. |
| intended-behaviour devil's advocate | real | Built the works-as-designed case and rejected it: the port turned Luwak's max into a sum and rewrote the test to expect the sum of the parts; core counts repeats (LUCENE-7925). Its probe: the classic QueryParser builds all three shapes, IndexSearcher explains apple apple with boost 2.0, a keep-whole decomposer is exact, and SIMPLE_MATCHER still matches. |
| adjudication | confirmed, medium | Re-ran the independent reproducer's test with a new seed: 5 of 6 fail, the control passes. Medium because a maintainer may answer with a javadoc change. |
| this doc's gradle runs | stock fails, fix passes | Stock main: 12 of the 15 repro tests fail with assertions on and off, every control passes. The fix: the whole monitor module, 197 tests, 0 failures, on and off; static checks pass. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 566 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,610 words
- Registry title
- Lucene Monitor's QueryDecomposer collects a query's parts in a Set, so a sub-query that occurs more than once in a registered query (a repeated SHOULD or MUST clause, or a term shared by two nested disjunctions) is scored once by ScoringMatch and ExplainingMatch instead of once per occurrence
- Area
- monitor / query decomposition and match scoring (QueryDecomposer Set<Query> parts, ScoringMatch/ExplainingMatch resolve)
- Priority
- Low, rank 478: Monitor matches stay correct, and only the opt-in ScoringMatch and ExplainingMatch give scores and explanations that are too low, and only for stored queries that repeat a sub-query.
- Impact class
- silent wrong results
- Impact note
- Applications that use lucene-monitor with its default QueryDecomposer and read match scores through ScoringMatch (directly or through ParallelMatcher/PartitionMatcher) or ExplainingMatch get, for every registered query in which an equal sub-query occurs more than once among its decomposed parts or its required clauses ('apple apple', '+apple +apple', '(red apple) (green apple)': shapes the classic QueryParser builds from plain input), a score that counts the repeated part once (0.13076457 instead of 0.26152915 and 0.39229372 instead of 0.5230583 in the repro); which queries match is unchanged (SIMPLE_MATCHER agrees with IndexSearcher), no scale is needed, and it is in every release since 8.2.0.
- Summary
- You register a query such as '(red apple) (green apple)' or 'apple apple' in a Monitor and match the document 'red green apple' with ScoringMatch or ExplainingMatch, expecting the score the query itself gives that document, which is what IndexSearcher returns, because BooleanQuery counts a repeated clause at every occurrence (0.5230583 and 0.26152915). Instead the Monitor reports 0.39229372 and 0.13076457: the default QueryDecomposer collects the query's parts in a Set, which keeps equal parts once, and the scoring matchers add up the scores of the distinct parts, so the shared 'apple' is counted once. Which queries match is not affected; only the scores and explanations of such queries are too low.
- Introduced
- 251dbe7cea8126cb7ecadc921ba444c63d06c618 on the main line and b8773d13ad8e249a045862249bf476c30a444461 on branch_8x (its QueryDecomposer.java and ScoringMatch.java are byte-identical), both 'LUCENE-8766: Add monitor subproject' by romseygeek (JIRA LUCENE-8766, now GitHub #9811; review PR apache/lucene-solr#648, closed without a GitHub merge, code committed directly) [read: git blame -w -M -C on main a9779ef3c193 attributes the Set declarations, the addAll calls and the mandatory-clause logic of QueryDecomposer to 251dbe7cea8, and the summing resolve of ScoringMatch and ExplainingMatch is in the same commit; later edits are formatting, record accessors, instanceof patterns and #14885's HashSet to LinkedHashSet (iteration order only)]. Not a regression: present since the module's first release. Origin outside Lucene [read through the GitHub contents API, not executed]: Luwak's QueryDecomposer (flaxsearch/luwak master 7d78a434fe6) kept the parts in Lists (ArrayList/LinkedList) and its ScoringMatcher/ExplainingMatcher resolve kept the larger match, so a repeated part could not change a Luwak score; the port switched to a Set and to a summing resolve in the same commit (2019-06-13 (251dbe7cea8 and b8773d13ad8, author date 2019-06-13T09:40:57+01:00))
- First affected version
- 8.2.0 [exec] (first release with lucene-monitor; 8.1.1, the release before, has no lucene-monitor artifact on Maven Central (HTTP 404) and the repro does not compile without it, so no earlier release is unaffected: the API did not exist)
- Affected versions
- every release that ships lucene-monitor: all 57 published releases from 8.2.0 to 10.5.2, plus the branch_10_6 head 4ae946e5a9b (10.6.0, released 2026-10-29) and main a9779ef3c193. [exec] the finder's JUnit fails 3 of 4 with identical values (0.39229372 vs 0.5230583, 0.13076457 vs 0.26152915 twice; the all-distinct control passes) on each of the 57 releases with -da (follow-up sweep), with -ea on 8.2.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.2.2, 10.3.0 and 10.5.2, on branch_10_6 4ae946e5a9b (monitor jar compiled from the branch sources, the other jars cached branch jars) and on main (-ea and -da); the independent reproduction's JUnit fails 5 of 6 on main (-ea and -da), 10.5.2, 9.12.3 and 8.2.0; the intended-behaviour check ran the finder JUnit on main (-ea and -da) and 10.5.2. #14885 (HashSet to LinkedHashSet, first release 10.3.0) changes only the order: 10.2.2 and 10.3.0 fail identically. The IndexSearcher reference values are identical on all releases and on main. Not fixed: no upstream commit after 251dbe7cea8 changes the Set or the summing resolve (the newest commits touching QueryDecomposer.java are #16255 on main, 2026-06-14, typo tooling, and #14885 on branch_10_6), and no open PR changes them (2026-10-28).
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check; also reached by Z3
- Upstream and prior reports
- none found (2026-10-28, the prior-report record, verdict new: two scripted prior-report searches (51 queries over apache/lucene issues and PRs, commits, downstream trackers, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and 6 web searches; then list and JIRA queries for monitor scoring, Luwak duplicates and QueryDecomposer); 20 GitHub issue/PR searches on apache/lucene (QueryDecomposer, ScoringMatch, ExplainingMatch, matchWithSimilarity, 'duplicate clauses', 'Set<Query>', monitor score, monitor repeated, CandidateMatcher resolve and others); issues and PRs from the last 48 h; the apache/lucene-solr, apache/solr, flaxsearch/luwak, Elasticsearch and OpenSearch trackers; the file lists of all 411 open apache/lucene PRs and of the PRs closed 2026-09-04 to 2026-10-27; the upstream commit history of QueryDecomposer.java, ScoringMatch.java and ExplainingMatch.java on main, branch_10x and branch_10_6; the Luwak sources; the finder's, the independent reproduction's, the intended-behaviour check's and the adjudication's earlier searches found nothing either; refreshed 2026-10-28 with read-only calls: none of the 15 PRs and 6 issues created since 2026-10-26 (#16907-#16927) is about lucene/monitor, none of the newest 60 open PRs touches lucene/monitor/, the newest upstream commits touching QueryDecomposer.java are still #16255 on main and #14885 on branch_10_6 (upstream main head c5ab3e57b9b), and the newest commit under lucene/monitor on main is df6f71a3729 (author date 2026-09-25, formatting); GitHub full-text search was rate-limited at refresh time). Not fixed upstream. Related items, not reports of this bug: #14886 / #14885 (2025: the same Set, iteration order across JVMs only; the fix kept a Set, so equal parts still collapse), #14967 (alternative ordering fix, unmerged), #9811 / LUCENE-8766 and apache/lucene-solr#648 (the port; no discussion of the Set or of how part scores are combined), #8974 / LUCENE-7925 (core merges repeated SHOULD/MUST clauses by summing their boosts: the reference behaviour), #7845 / LUCENE-6787 (core may drop only non-scoring duplicates), #13109 (matcher composition), #16350 (bulk scoring in the monitor), apache/solr#2382 (draft Monitor integration; its 'deduplicate' is one result per query id; scoring matchers deferred), Luwak #64, #37, #78 and #175 (unrelated scoring, hashing and presearcher items)
- Lucene commit tested
- main
a9779ef3c193(gradle in a scratch worktree: the 3 repro classes on stock with assertions on and off; the fix on the whole monitor module with assertions on and off, and the module's static checks; the finder's original fix on the whole module; the repro runner: the finder's test, the independent reproducer's, the test written and run by the AI tool that drove the cross-model review (the other-family model ran no code), the devil's-advocate probe, the adjudication's, the security probe and the registry re-runs, several seeds, assertions on and off); the release jars of all 57 releases from 8.2.0 to 10.5.2 (the finder's test with assertions off; 8 of them also with assertions on; the primary test on 10.5.2 and 9.12.3) and 8.1.1 (no monitor module); branch_10_6 head4ae946e5a9b(monitor jar compiled from its sources). JDK 25.0.3, Linux aarch64.
- Finding record
lucene/monitor/src/java/org/apache/lucene/monitor/QueryDecomposer.java:30-33 (class javadoc 'Split a disjunction query into its constituent parts, so that they can be indexed and run separately'), :42 (decompose returns Set<Query>), :46-52 (DisjunctionMaxQuery disjuncts into a LinkedHashSet), :80 and :89 (SHOULD parts into one LinkedHashSet), :82 and :85-86 (MUST/FILTER clauses into a HashSet), :94-95 (kept whole only for more than one distinct required clause, or one plus SHOULD parts), :99-101 (a single distinct required clause is decomposed)lucene/monitor/src/java/org/apache/lucene/monitor/QueryCacheEntry.java:51-59 (one entry per Set element under the parent id), CandidateMatcher.java:75-85 (addMatch merges matches of one id through resolve) and :87-95 (resolve javadoc 'combine them')lucene/monitor/src/java/org/apache/lucene/monitor/ScoringMatch.java:42-44 (resolve returns match1.getScore() + match2.getScore()) and ExplainingMatch.java:44-52 (resolve builds a 'sum of:' Explanation)lucene/monitor/src/java/org/apache/lucene/monitor/package-info.java:40-45 (ScoringMatch 'returns the set of matching queries, with the score that each one records against a Document'; ExplainingMatch 'similar to ScoringMatch, but include the full Explanation') and MonitorConfiguration.java:38 (default QueryDecomposer), :111 (setQueryDecomposer)lucene/monitor/src/test/org/apache/lucene/monitor/ConcurrentMatcherTestBase.java:85-87 ('each query ends up with the sum of the scores for the 'test' and 'doc' parts', 1.4874471f)lucene/core/src/java/org/apache/lucene/search/BooleanQuery.java:438-455 (repeated SHOULD and MUST clauses are deduplicated into one clause with a combined weight) and :706-713 (deduplicateClauses javadoc: 'merging repeated queries into a single clause with a combined boost'; Similarity#computeQueryTermWeight for unweighted duplicates)
- The finding in 30 seconds
a Lucene main checkout lucene/monitor/src/java/org/apache/lucene/monitor/QueryDecomposer.java:30-101; QueryCacheEntry.java:51-59; Monitor.java:299; CandidateMatcher.java:75-95; ScoringMatch.java:36-44; ExplainingMatch.java:44-52; package-info.java:35-48a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/BooleanQuery.java:438-455, 706-758; similarities/BM25Similarity.java:131-136; similarities/Similarity.java:175-177
- Who is affected
a Lucene main checkout lucene/monitor/src/java/org/apache/lucene/monitor/MonitorConfiguration.java:38, 111; package-info.java:35-51
- Why it looks unintended
a Lucene main checkout lucene/monitor/src/java/org/apache/lucene/monitor/package-info.java:40-45; QueryDecomposer.java:30-33, 42; CandidateMatcher.java:87-95a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/BooleanQuery.java:438-455, 706-713; lucene/core/src/test/org/apache/lucene/search/TestBooleanRewrites.java:610-668a Lucene main checkout lucene/monitor/src/test/org/apache/lucene/monitor/ConcurrentMatcherTestBase.java:60-92; TestQueryDecomposer.java
- Suggested fix
a Lucene main checkout lucene/monitor/src/java/org/apache/lucene/monitor/Monitor.java:114-126, 258-260 (QueryCacheStats, getDisjunctCount: counts after decomposition); MonitorConfiguration.java:111a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/BooleanQuery.java:743-746; similarities/BM25Similarity.java:131-136a Lucene main checkout lucene/monitor/src/java/org/apache/lucene/monitor/MatchingQueries.java:92-93 (getQueriesRun); QueryCacheEntry.java:51-59 (one entry per Set element)
- TestMonitorSharedSubqueryScore.java (JUnit test):
repro/LFV-856/src/org/apache/lucene/monitor/TestMonitorSharedSubqueryScore.java(60 lines)
A step-by-step picture of the repro's example; the PNG is its summary still. Its fix panel shows the recommended patch.
assets/LFV-856/bug.png(566 KB)